Topics / #training
Training projects on GitHub
Mixed learning courses and machine learning training guides.
As of , the most-starred Training projects on GitHub are transformers (167.8K stars), yolov5 (58.2K stars) and DeepSpeed (43.2K stars). GitHub.Locker tracks 91 Training repositories with 1.5M stars combined. The fastest-growing on October 16 was airllm, with +159 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +159
airllm
lyogavin/airllm · ★ 39.1KAn open-source Python library that runs huge LLMs on tiny GPUs: a 70B model fits on a single 4GB card without quantization, distillation or pruning — even the 2.8T-parameter Kimi K3 runs in under 4GB.
 +47
ai-infra-book
bojieli/ai-infra-book · ★ 6.7KAn open-source book, 'Understanding AI Infra: Quantitative Analysis and System Design' by Bojie Li, that derives LLM inference and training system designs from hardware constraints and model architecture using quantitative, order-of-magnitude estimates.
 +42
transformers
huggingface/transformers · ★ 167.8KTransformers is Hugging Face's model-definition framework for state-of-the-art machine learning models across text, vision, audio, video, and multimodal tasks, usable for both inference and training.
 +37
tick-stock-panel
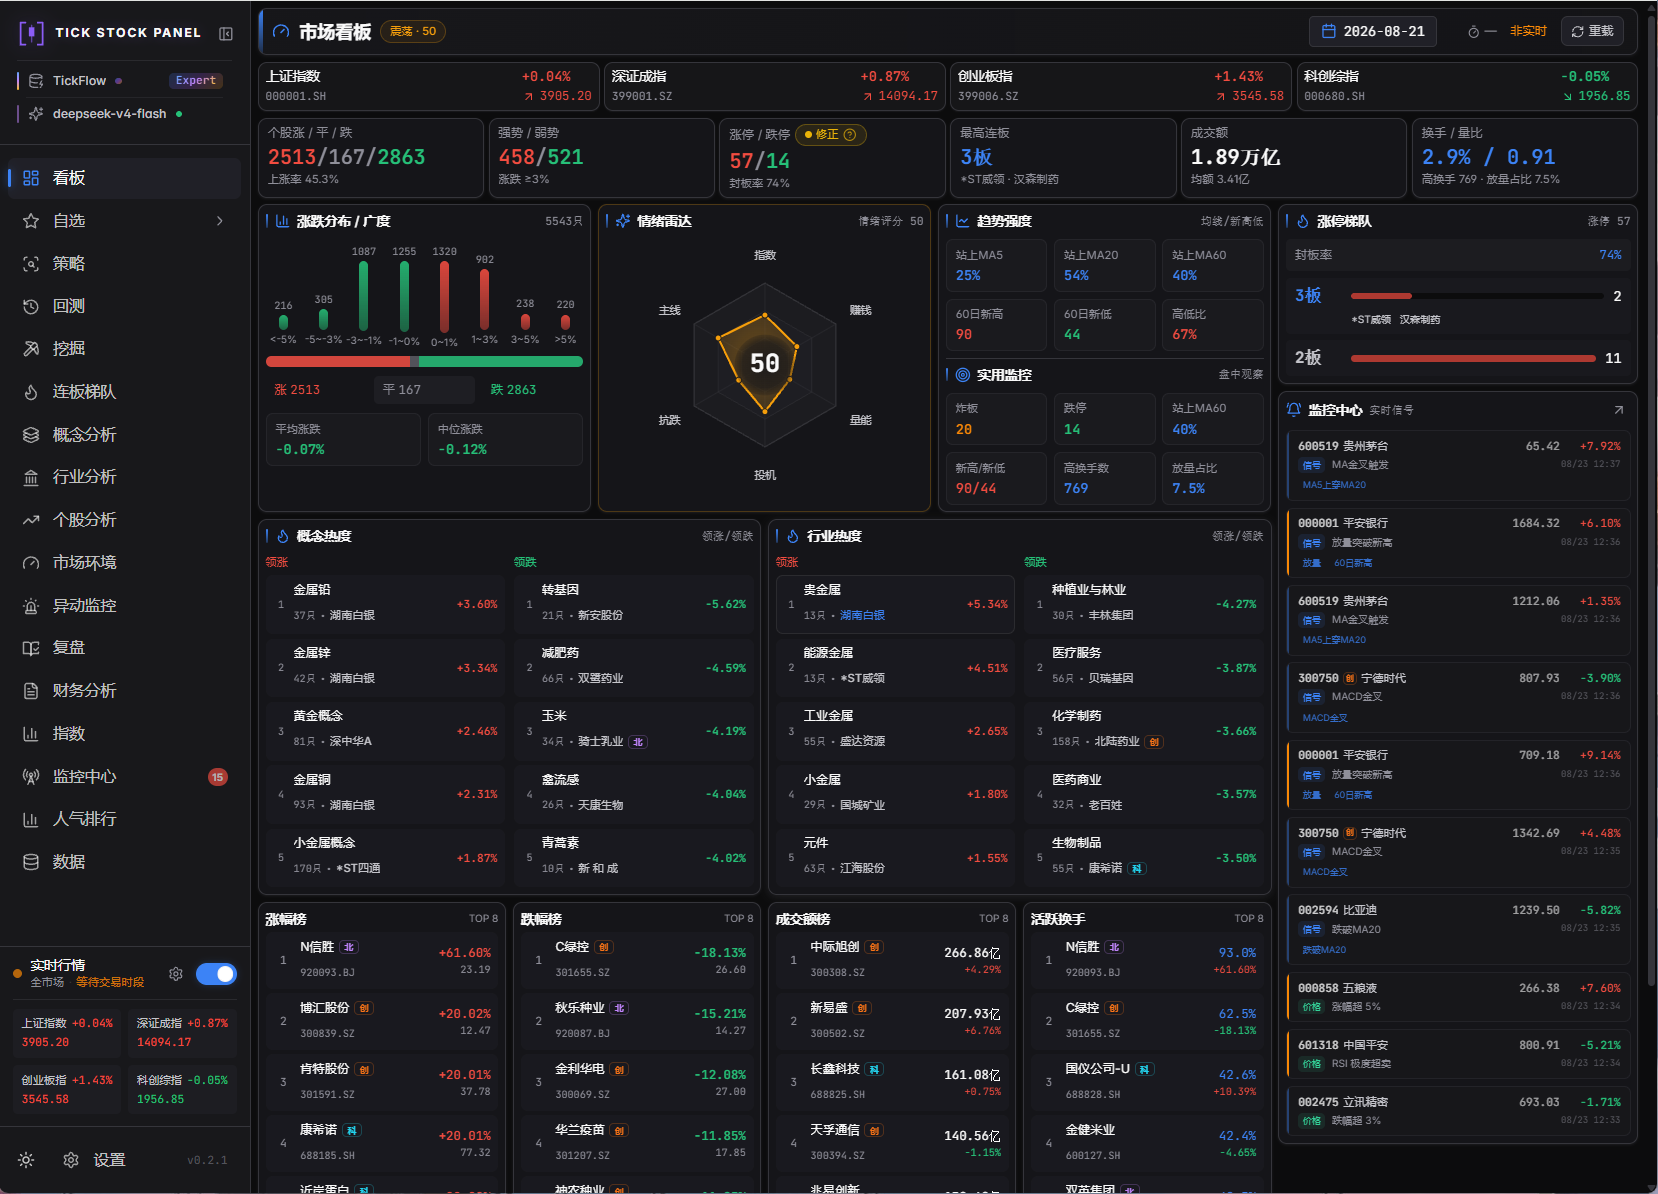
shy3130/tick-stock-panel · ★ 5.9KTSP is a self-hosted, zero-ops quantitative trading workbench for China's A-share stock market that combines stock screening, real-time anomaly monitoring, and strategy backtesting, with optional LLM-assisted analysis.
The all-time top
91 projects · by stars
- 167.8K#1 · huggingface/transformers
transformers
Transformers is Hugging Face's model-definition framework for state-of-the-art machine learning models across text, vision, audio, video, and multimodal tasks, usable for both inference and training.
- 58.2K
 #2 · ultralytics/yolov5
yolov5
YOLOv5 is a fast, accurate, and easy-to-use computer vision model from Ultralytics for object detection, instance segmentation, and image classification, built on PyTorch.
- 43.2K
#3 · deepspeedai/DeepSpeed
DeepSpeed
DeepSpeed is a deep learning optimization library that makes distributed training and inference of very large models easy, efficient and effective — it powered models like MT-530B and BLOOM.
- 4
ColossalAI
41.4Khpcaitech/ColossalAI · PythonColossal-AI is an open-source system for training and running large AI models more cheaply, faster and with less hardware, by providing a toolbox of parallelism and memory-optimization techniques.
- 5
airllm
39.1Klyogavin/airllm · Jupyter NotebookAn open-source Python library that runs huge LLMs on tiny GPUs: a 70B model fits on a single 4GB card without quantization, distillation or pruning — even the 2.8T-parameter Kimi K3 runs in under 4GB.
- 6
GFPGAN
37.7KTencentARC/GFPGAN · PythonGFPGAN is a practical algorithm for real-world blind face restoration: it rebuilds degraded or low-quality faces in photos using rich priors from a pretrained face GAN like StyleGAN2.
- 7

pytorch-image-models
37.2Khuggingface/pytorch-image-models · PythonPyTorch Image Models (timm) — the largest collection of PyTorch image encoders and backbones, shipped with pretrained weights plus train, eval, inference and export scripts.
- 8
diffusers
34.7Khuggingface/diffusers · PythonDiffusers is Hugging Face's Python library for state-of-the-art pretrained diffusion models that generate images, audio, and even 3D molecule structures, all in PyTorch.
- 9

spaCy
34Kexplosion/spaCy · PythonspaCy is a library for advanced Natural Language Processing in Python and Cython, designed from day one for real products. It ships pretrained pipelines and supports tokenization and training for 70+ languages.
- 10
comprehensive-rust
33.4Kgoogle/comprehensive-rust · RustComprehensive Rust is a multi-day Rust course developed by the Android team at Google, covering Rust from basic syntax to generics and error handling.
- 11
pytorch-lightning
31.4KLightning-AI/pytorch-lightning · PythonPyTorch Lightning is a deep learning framework for pretraining and finetuning AI models of any size, scaling from a single CPU to thousands of GPUs or TPUs without changing your model code.
- 12

llm.c
31.2Kkarpathy/llm.c · Cudallm.c is Karpathy's project for training large language models in raw C and CUDA, with no dependency on 245MB of PyTorch or 107MB of cPython. It currently focuses on pretraining GPT-2 and GPT-3-scale models, with train_gpt2.cu as the main CUDA training path.
- 13
tuning_playbook
30.4Kgoogle-research/tuning_playbookA free, in-depth guide from five Google Research Brain Team researchers (plus a Harvard co-author) on systematically maximizing the performance of deep learning models — the 'Deep Learning Tuning Playbook'.
- 14
stanford_alpaca
30.2Ktatsu-lab/stanford_alpaca · PythonStanford's official Alpaca repo: code and docs for training an instruction-following LLaMA model and generating its 52K instruction dataset. In preliminary human evaluation the 7B model behaved similarly to text-davinci-003.
- 15
Open-Sora
29.9Khpcaitech/Open-Sora · PythonOpen-Sora is an open-source initiative for efficiently producing high-quality video: it releases video generation models together with the tools, checkpoints and all training details.
- 16
h4cker
29.8KThe-Art-of-Hacking/h4cker · Jupyter NotebookA curated collection of thousands of cybersecurity resources — references, scripts, tools, code, labs, and training material — maintained by Omar Santos as a companion to his books, video courses, and live training.
- 17

cs249r_book
29Kharvard-edge/cs249r_book · PythonAn open textbook and full curriculum on Machine Learning Systems — AI engineering — from Harvard's CS249r course: four volumes covering foundations, scaling, agentic AI, and physical AI, plus labs, projects, and instructor materials.
- 18

mlx
28.8Kml-explore/mlx · C++MLX is an array framework for machine learning on Apple silicon, built by Apple's machine learning research team.
- 19

Mask_RCNN
25.6Kmatterport/Mask_RCNN · PythonAn implementation of the Mask R-CNN model on Python 3, Keras and TensorFlow that generates bounding boxes and a segmentation mask for each object instance in an image, built on a Feature Pyramid Network and a ResNet101 backbone.
- 20
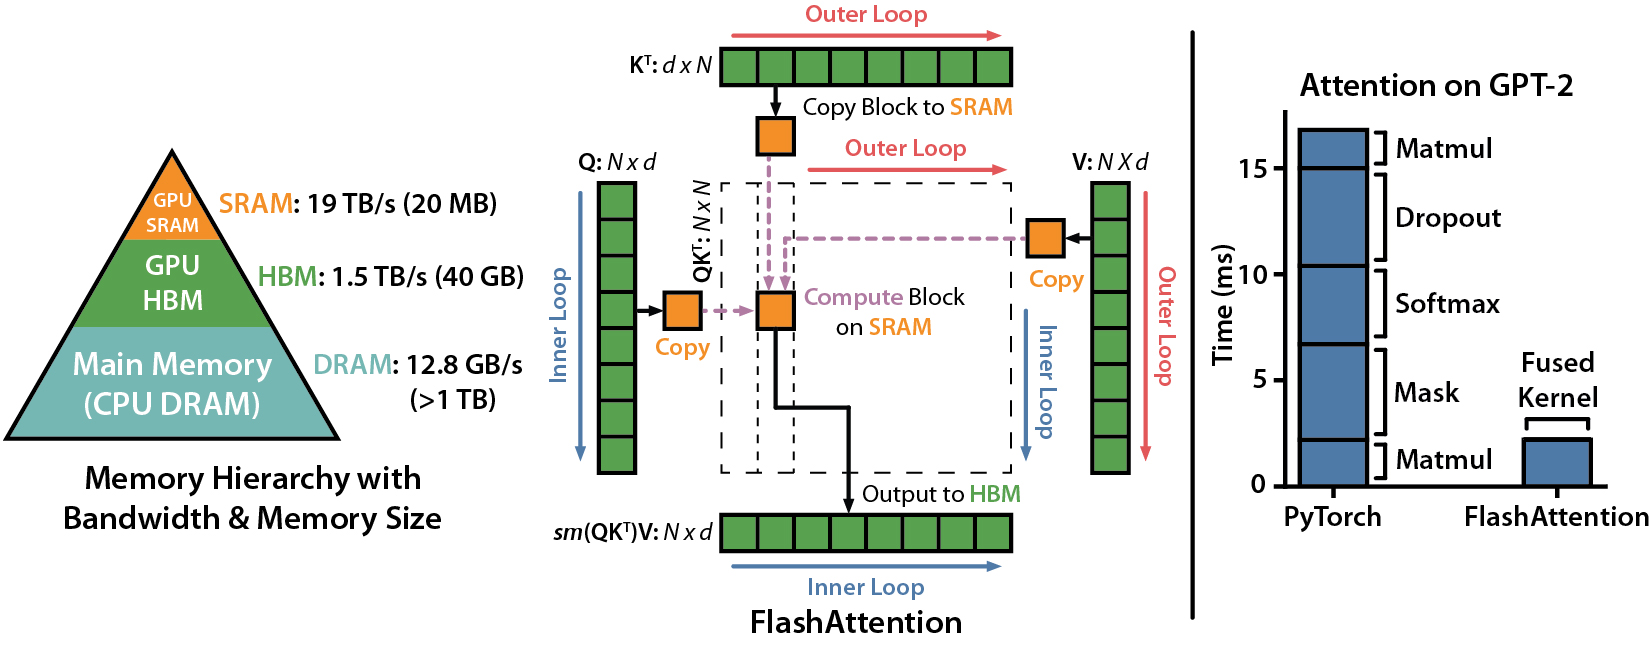
flash-attention
25.1KDao-AILab/flash-attention · PythonThe official implementation of FlashAttention and FlashAttention-2 — GPU kernels that compute exact attention faster and with less memory than standard PyTorch attention.
- 21
LLaVA
25.1Khaotian-liu/LLaVA · PythonLLaVA is an open-source large multimodal chatbot: a vision-language model you can show images to and talk with, built by visual instruction tuning toward GPT-4V-level capabilities (NeurIPS 2023 Oral).
- 22
Paddle
24.1KPaddlePaddle/Paddle · C++PaddlePaddle is an open-source deep learning platform — China's first independently developed one, open-sourced since 2016 — spanning a core framework, model libraries, end-to-end dev kits and service platforms.
- 23
onnxruntime
22.1Kmicrosoft/onnxruntime · C++ONNX Runtime is a cross-platform, high performance ML accelerator for inference and training. It runs models from PyTorch, TensorFlow/Keras and classical ML libraries like scikit-learn, LightGBM and XGBoost.
- 24
FinGPT
21.4KAI4Finance-Foundation/FinGPT · Jupyter NotebookFinGPT is AI4Finance Foundation's open-source project for financial large language models: trained models are released on HuggingFace, with code for RAG, fine-tuning pipelines and benchmarks built around them.
- 25
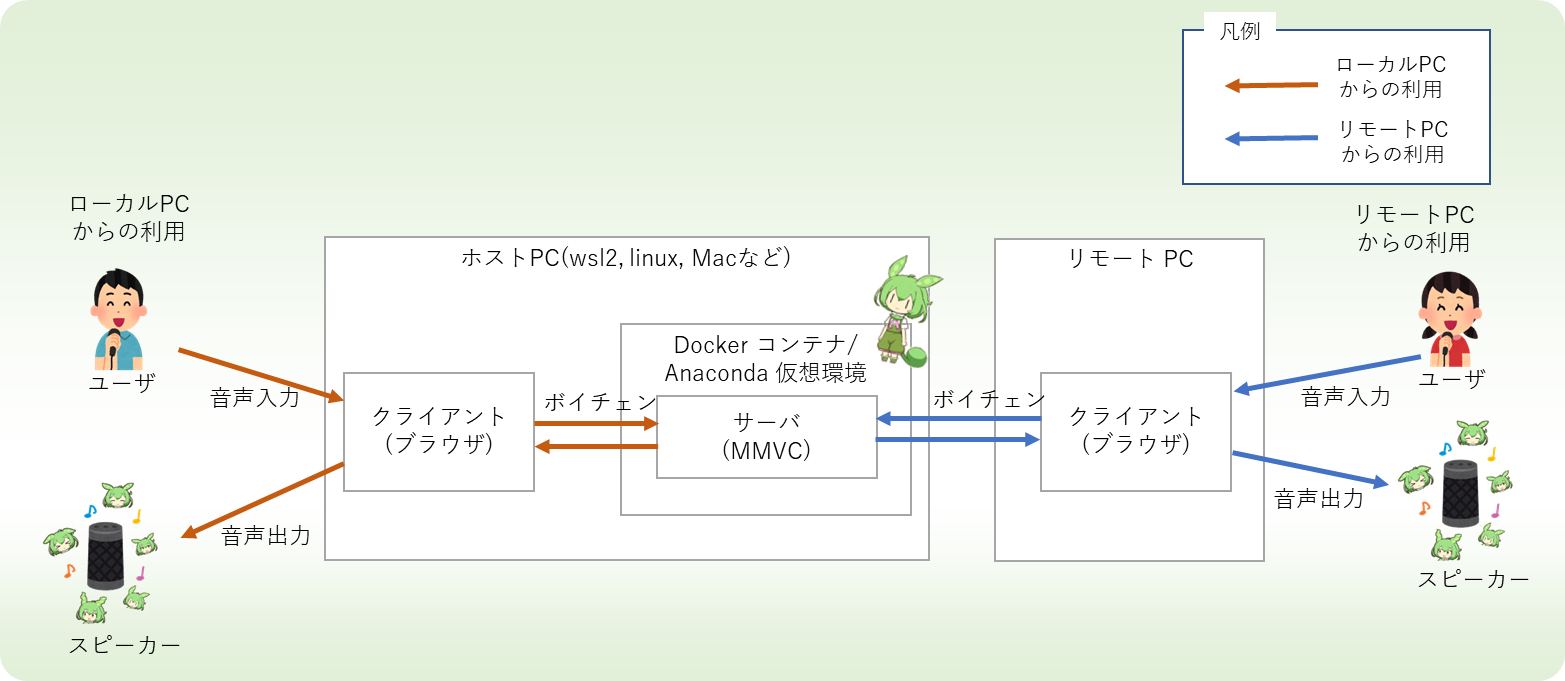
voice-changer
21.2Kw-okada/voice-changer · PythonIt's VCClient, a real-time AI voice changer: it converts your microphone input on the fly so you can speak live with a different voice.
- 26

jstraining
20Kruanyf/jstrainingTraining materials for a JavaScript full-stack bootcamp: they teach the basics needed to build both the front end and back end of a simple web application.
- 27
olmocr
19.8Kallenai/olmocr · PythonolmOCR is a toolkit that converts PDFs, PNGs, and JPEGs into clean Markdown or plain text with natural reading order, preserving equations, tables, and handwriting - built primarily to produce training datasets for LLMs.
- 28

ml-engineering
19.5Kstas00/ml-engineering · PythonAn open book on machine learning engineering: methodologies, tools and step-by-step instructions for training, fine-tuning and running inference on large language models and multi-modal (VLM) models, written by the engineer who led the BLOOM-176B training.
- 29

trl
19.5Khuggingface/trl · PythonTRL (Transformers Reinforcement Learning) is a Hugging Face library for post-training foundation models — fine-tuning them with techniques like SFT, GRPO and DPO on top of the Transformers stack.
- 30
sentence-transformers
19.2Khuggingface/sentence-transformers · PythonSentence Transformers is a framework for computing embeddings and using or training state-of-the-art embedding and reranker models, covering dense sentence embeddings, cross-encoder rerankers, sparse encoders, and multi-vector (ColBERT-style) encoders.
- 31

lila
18.8Klichess-org/lila · ScalaLichess (lila) is the free, adless and open source online chess server behind lichess.org, focused on realtime play and ease of use.
- 32
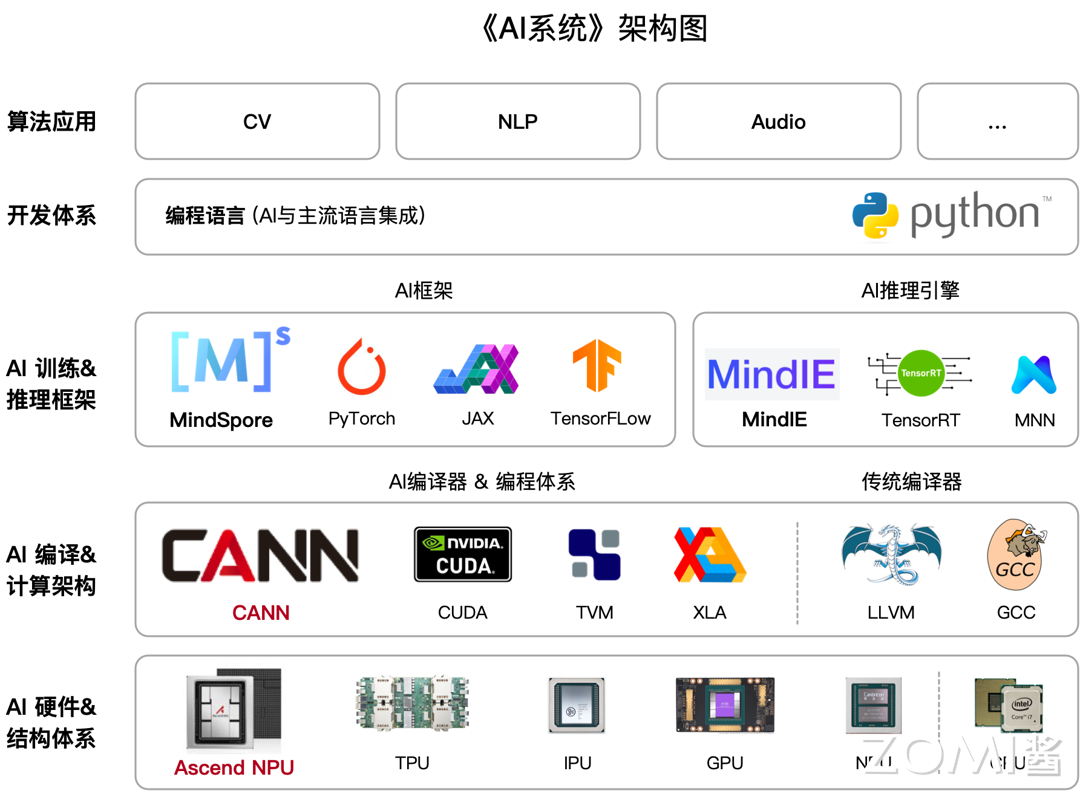
AISystem
18KInfrasys-AI/AISystem · Jupyter NotebookAISystem (AISys) is an open-source course covering the full AI stack: AI chip architecture, AI compilers, inference systems/engines, and training framework internals.
- 33
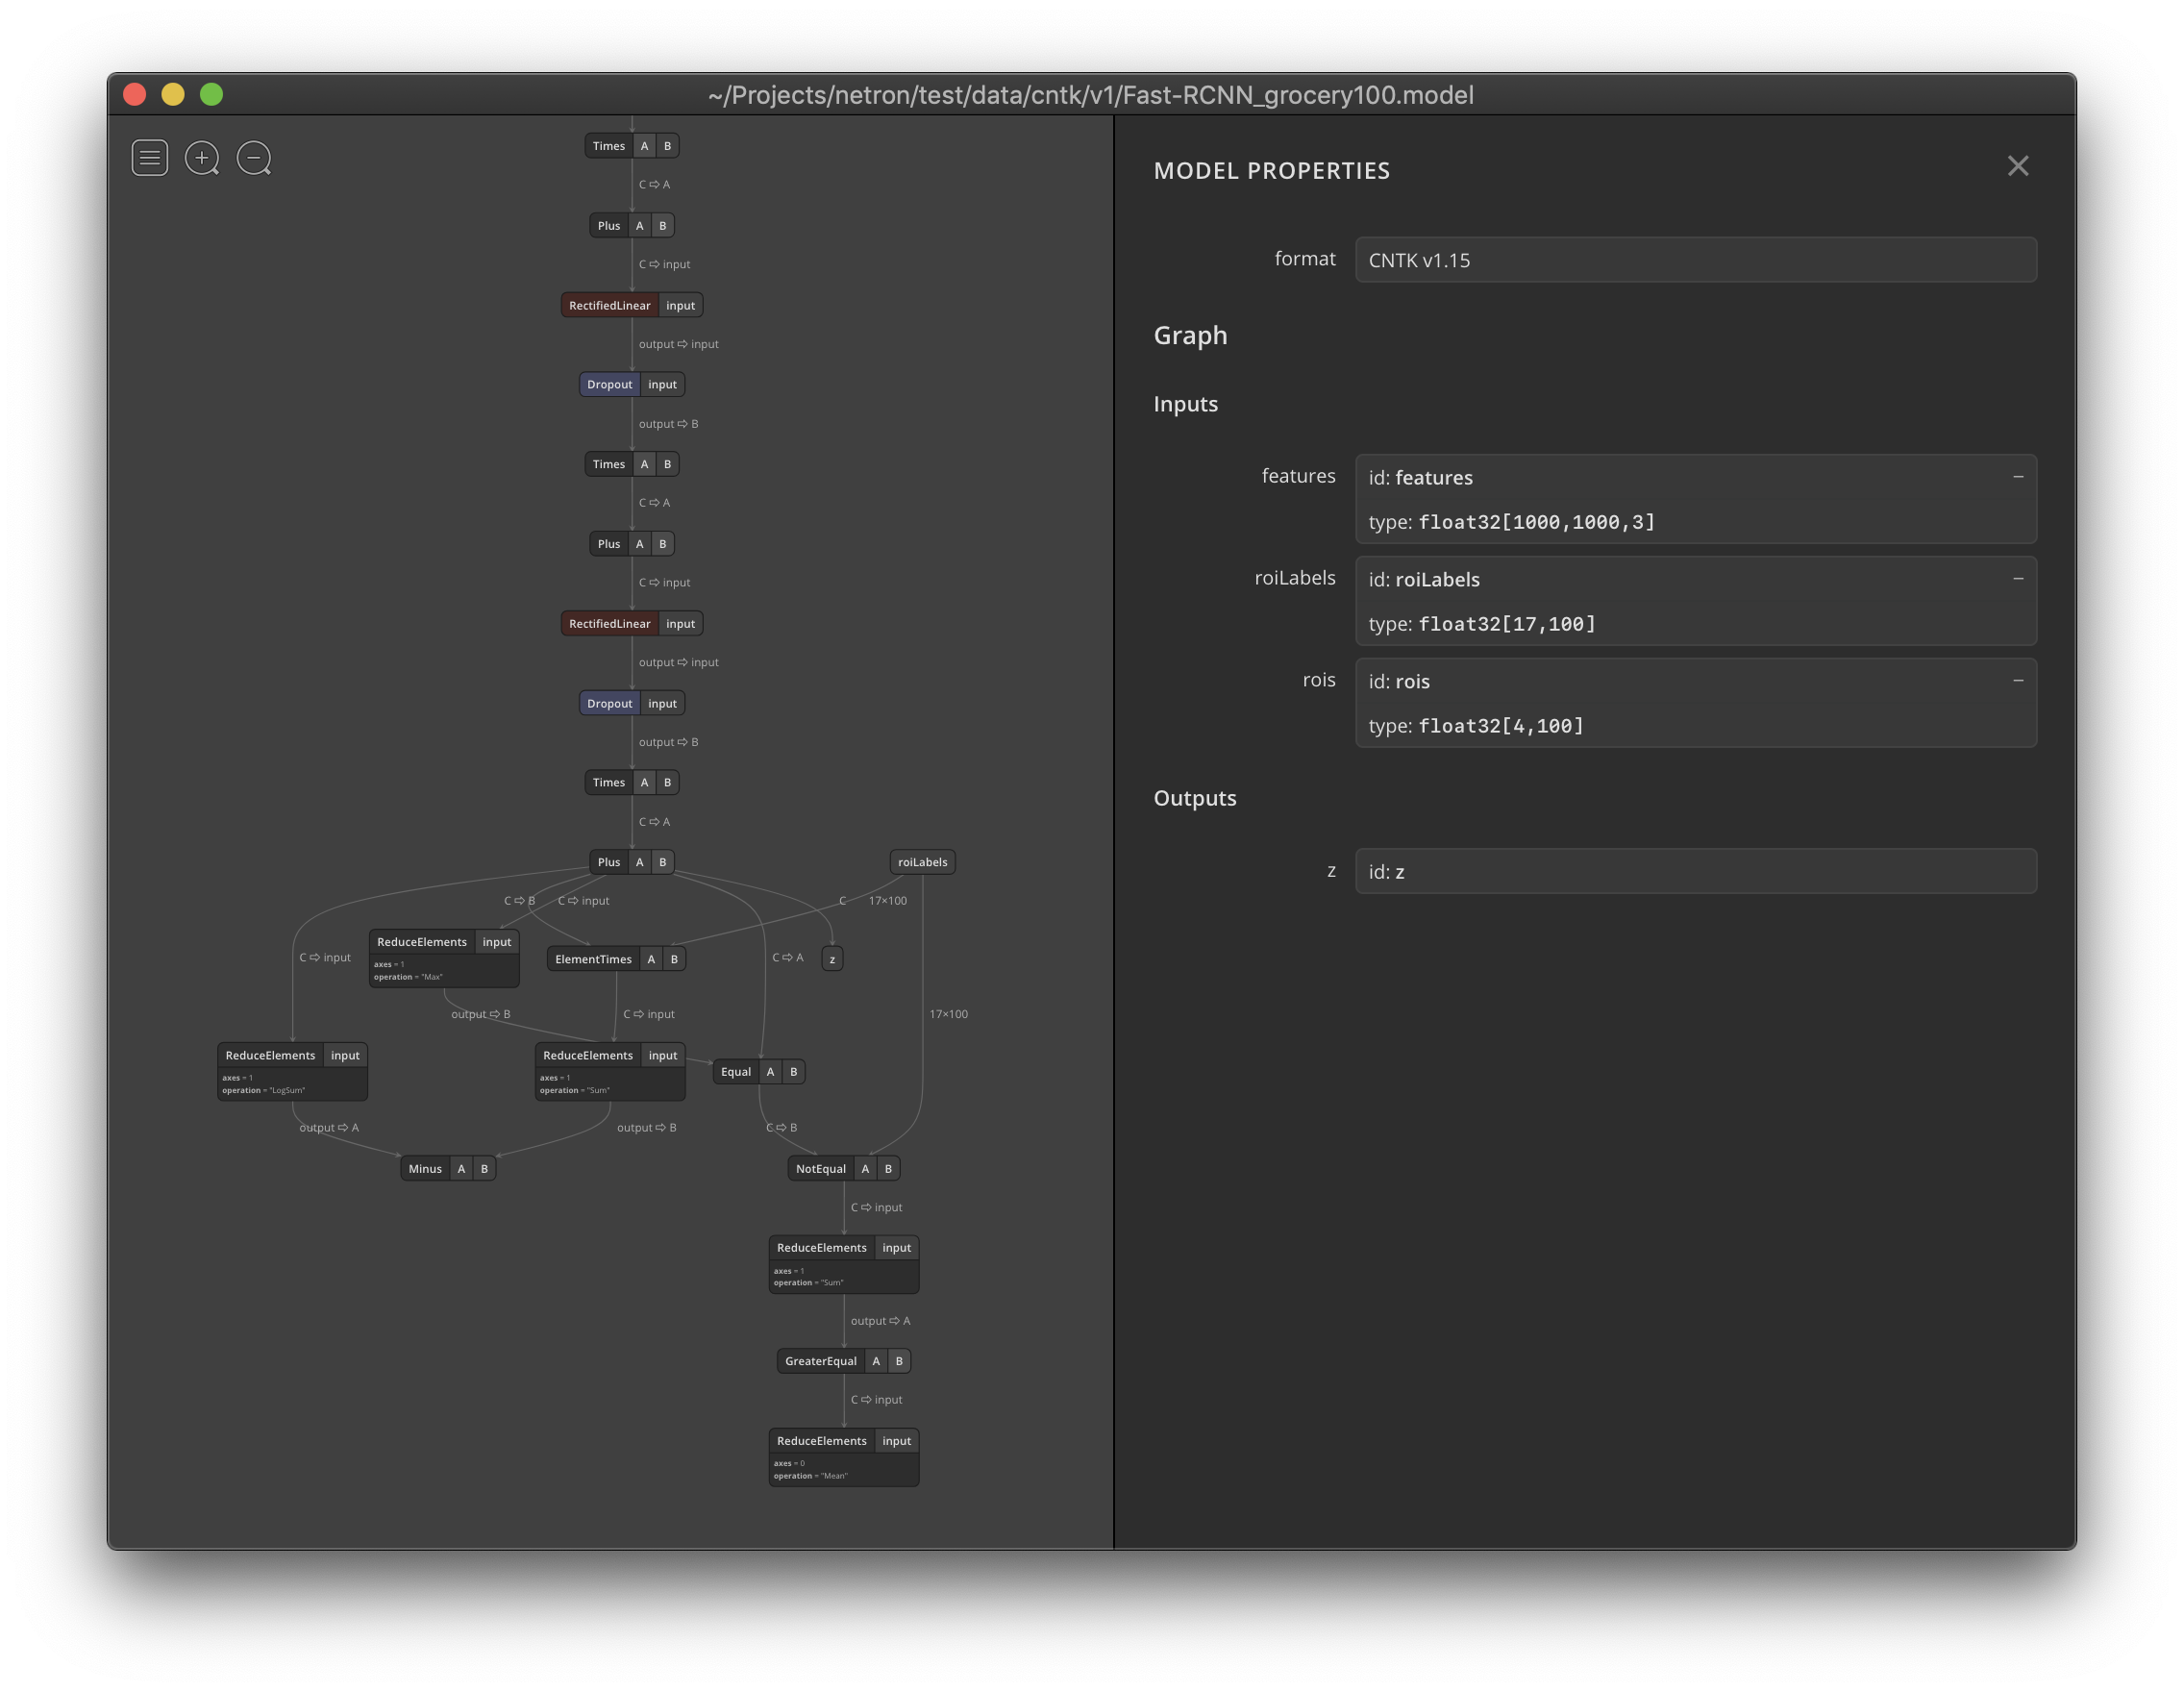
CNTK
17.6Kmicrosoft/CNTK · C++The Microsoft Cognitive Toolkit (CNTK) is an open-source deep-learning toolkit that describes neural networks as a series of computational steps in a directed graph.
- 34
burn
16.1Ktracel-ai/burn · RustBurn is a Rust tensor library and deep learning framework for both training and inference, so the same code takes a model from prototype to production on everything from GPU clusters to the browser.
- 35
ms-swift
15.9Kmodelscope/ms-swift · Pythonms-swift is the ModelScope community's fine-tuning and deployment framework for LLMs and multimodal models, covering training, inference, evaluation, quantization and deployment in one pipeline.
- 36

OpenMythos
14.9Kkyegomez/OpenMythos · PythonOpenMythos is an open-source, speculative PyTorch implementation that tries to reconstruct the internal architecture of Anthropic's Claude ('Mythos') purely from publicly available research papers, not from any leaked or official Anthropic code.
- 37
RWKV-LM
14.8KBlinkDL/RWKV-LM · PythonRWKV (pronounced 'RwaKuv') is an RNN architecture with transformer-level LLM performance that can also be trained in parallel like GPT. The current generation, RWKV-7 'Goose', is 100% attention-free, linear-time and constant-memory (no kv-cache).
- 38
stylegan
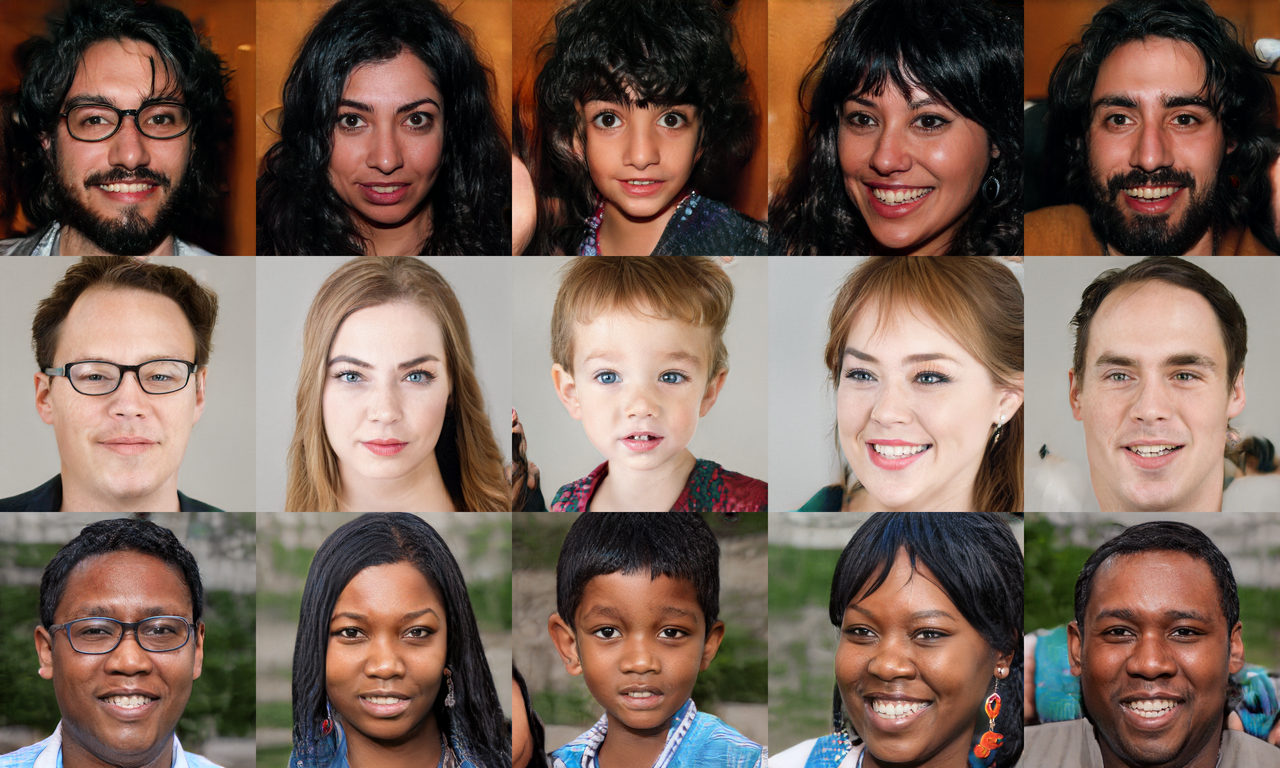
14.4KNVlabs/stylegan · PythonNVIDIA's official TensorFlow implementation of StyleGAN, a generative adversarial network that synthesizes photorealistic images — most famously 1024x1024 faces of people who don't exist — with intuitive control over attributes like pose and identity.
- 39

DVWA
13.9Kdigininja/DVWA · PHPDVWA (Damn Vulnerable Web Application) is a PHP/MariaDB web app that is deliberately full of security bugs, built as a legal practice target for security pros, students, and developers to learn web application security.
- 40

litgpt
13.7KLightning-AI/litgpt · PythonLitGPT is a collection of 20+ high-performance large language models (Llama, Gemma, Phi, Qwen, Mistral, Falcon, TinyLlama and more) implemented from scratch, with ready-made recipes to pretrain, finetune, evaluate and deploy them at scale.
- 41
DiffSynth-Studio
13.3Kmodelscope/DiffSynth-Studio · PythonDiffSynth-Studio is an open-source Diffusion model engine built and maintained by the ModelScope Community, covering image, video, and audio generation plus image quality metrics, with support for both inference and training.
- 42
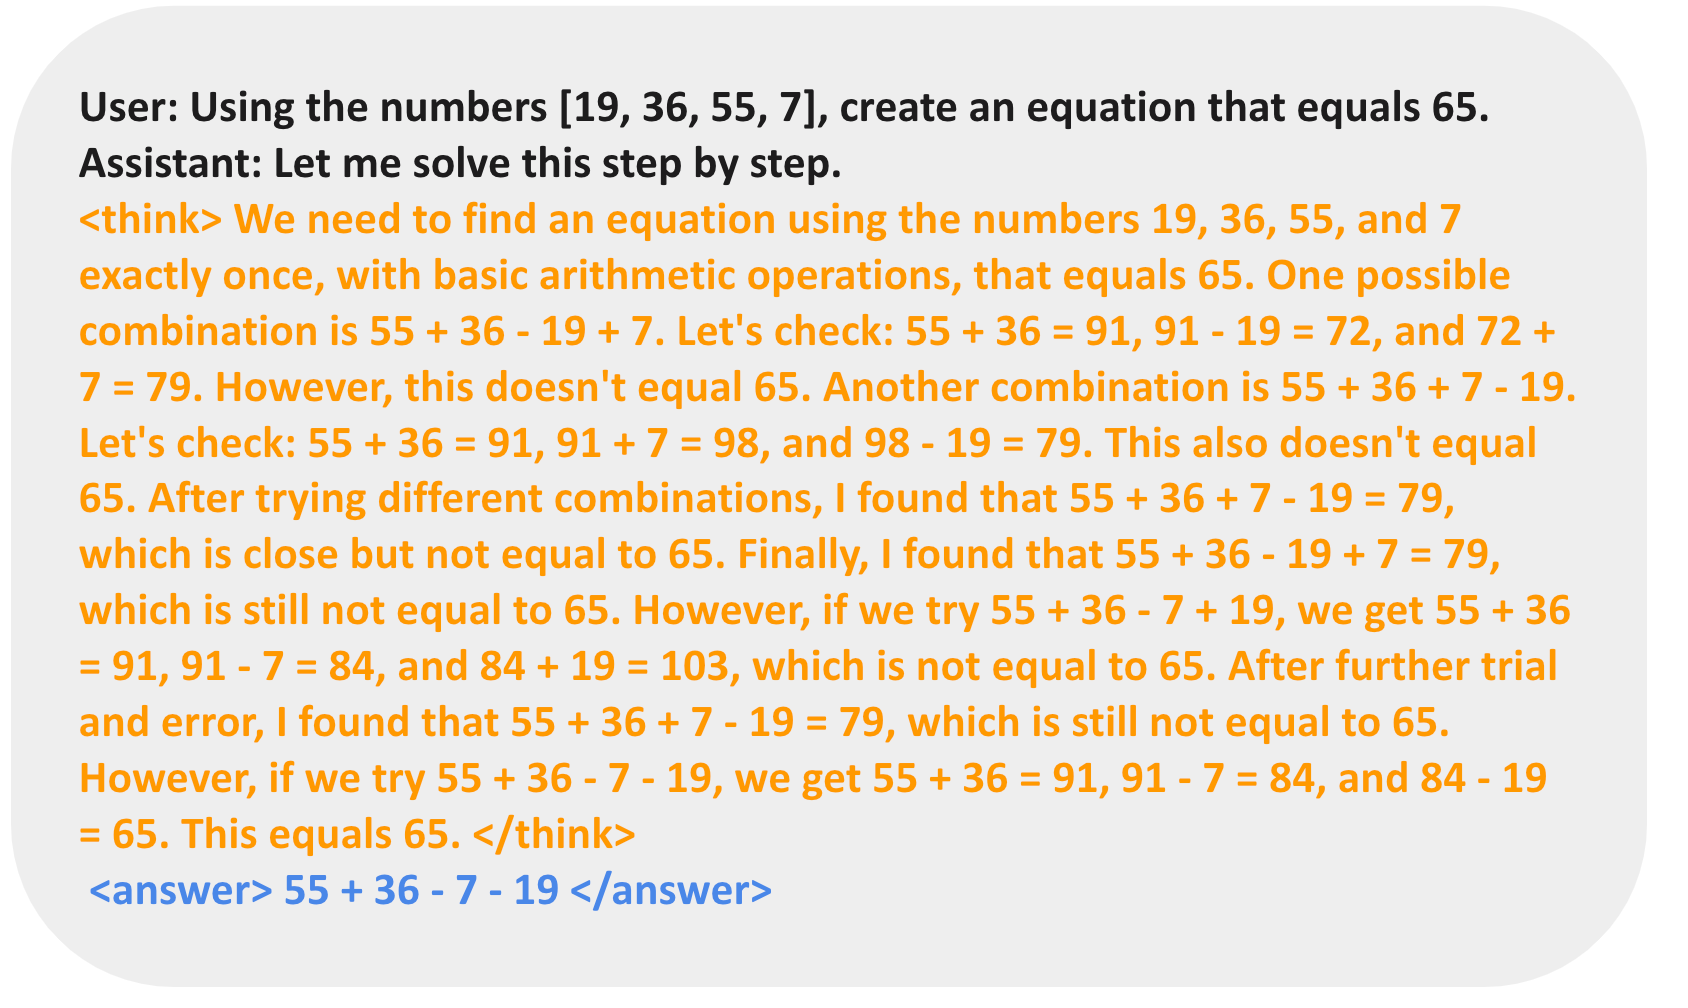
TinyZero
13.2KJiayi-Pan/TinyZero · PythonA minimal reproduction of DeepSeek R1-Zero: through reinforcement learning on countdown and multiplication tasks, a 3B base LM develops self-verification and search abilities all on its own.
- 43
Wav2Lip
13.2KRudrabha/Wav2Lip · PythonWav2Lip is the open-source code and pretrained models behind an ACM Multimedia 2020 paper: it lip-syncs any video to any target speech audio with high accuracy, for research, academic, and personal use.
- 44

kohya_ss
12.6Kbmaltais/kohya_ss · PythonKohya's GUI is a Gradio-based graphical interface (plus CLI) for Kohya's Stable Diffusion training scripts, letting you fine-tune diffusion models, train LoRA/LoHa/LoKr, Dreambooth, Textual Inversion, and full fine-tuning without hand-writing training commands.
- 45

axolotl
12.6Kaxolotl-ai-cloud/axolotl · PythonAxolotl is a free, open-source framework that streamlines post-training and fine-tuning of large language models — you describe your run in one YAML config and it drives the whole pipeline.
- 46

gotraining
12.2Kardanlabs/gotraining · GoTraining class material for Ardan Labs' Go courses - the commented example code and exercises used in classes that have taught Go to thousands of developers since 2014.
- 47
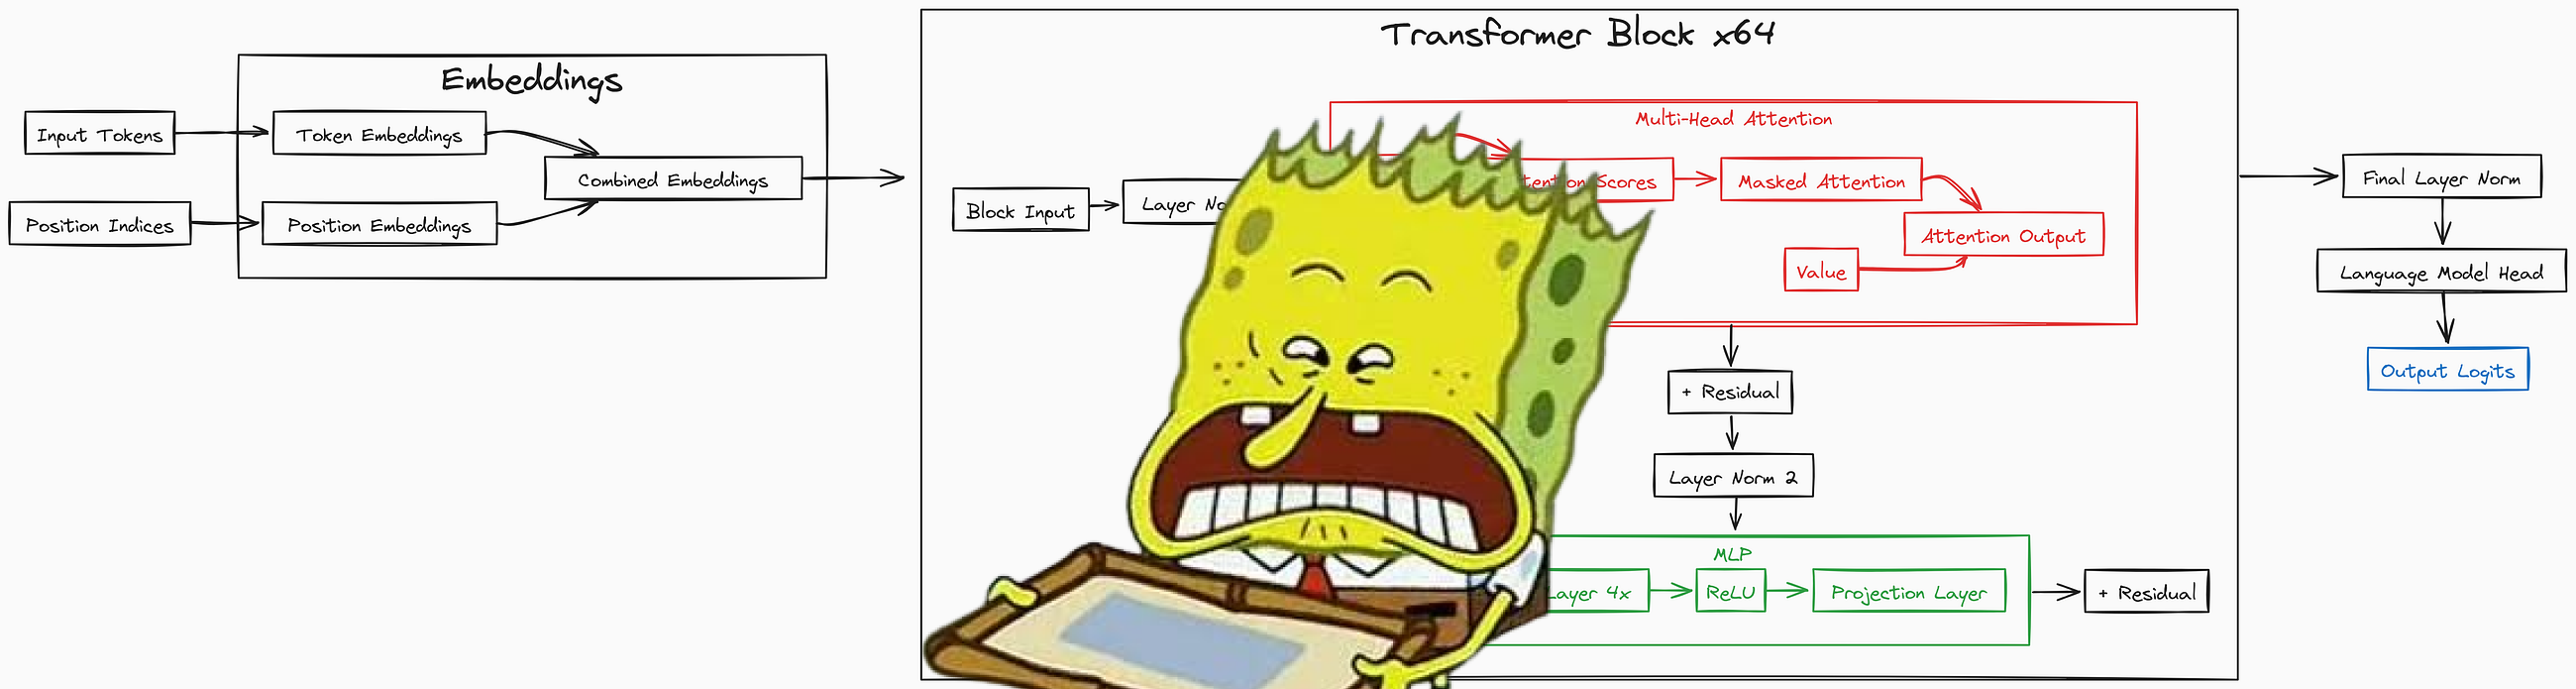
train-llm-from-scratch
12.2KFareedKhan-dev/train-llm-from-scratch · PythonA from-scratch tutorial and codebase for training your own LLM end to end: tokenizing raw text, pretraining a GPT-style Transformer, and then post-training it with SFT, a reward model, DPO/ORPO/KTO, PPO and GRPO into an aligned, reasoning-style assistant.
- 48
TRELLIS.2
12.1Kmicrosoft/TRELLIS.2 · PythonTRELLIS.2 is a 4-billion-parameter 3D generative model for high-fidelity image-to-3D generation, using a novel field-free sparse voxel representation (O-Voxel) to produce assets with complex topology and full PBR materials.
- 49

opensre
12KTracer-Cloud/opensre · PythonAn open-source framework for building AI SRE agents that resolve production incidents on your own infrastructure — and a training and evaluation environment for those agents.
- 50

speechbrain
11.9Kspeechbrain/speechbrain · PythonAn open-source, PyTorch-based toolkit for Conversational AI — the technology behind speech assistants and chatbots. It bundles training recipes and pretrained models for a wide range of speech and text processing tasks.
- 51
rerun
11.6Krerun-io/rerun · RustRerun is a data layer for physical AI: it logs, queries, visualizes and streams multimodal robotics data (images, point clouds, transforms, time series, video) so you can debug sensor pipelines and feed data into training.
- 52

True-Story-of-Pangu
11.5KHW-whistleblower/True-Story-of-PanguA long first-person exposé by a self-identified member of Huawei's Pangu LLM team at the Noah's Ark Lab, telling what he says really went on behind the model's development — including claims that some Pangu models were secretly continued-trained from Qwen and DeepSeek.
- 53
skills
11.2Khuggingface/skills · PythonThis repo provides modular 'Agent Skills' — SKILL.md definitions that teach AI coding agents (Claude Code, Codex, Gemini CLI, Cursor) how to do Hugging Face ML tasks like managing models/datasets, training, evaluation, and deploying to Spaces or SageMaker.
- 54

qlora
11Kartidoro/qlora · Jupyter NotebookQLoRA is a research method and code release for efficiently finetuning large quantized language models. It backpropagates gradients through a frozen 4-bit quantized model into small LoRA adapters, cutting memory use enough to finetune a 65B model on a single 48GB GPU while matching full 16-bit finetuning quality.
- 55

amazon-sagemaker-examples
11Kaws/amazon-sagemaker-examples · Jupyter NotebookA collection of official Jupyter notebooks from AWS that demonstrate how to build, train, and deploy machine learning models using Amazon SageMaker.
- 56
dopamine
10.9Kgoogle/dopamine · Jupyter NotebookDopamine is a research framework for fast prototyping of reinforcement learning algorithms — a deliberately small, easily grokked codebase meant for trying out speculative research ideas.
- 57
denoising-diffusion-pytorch
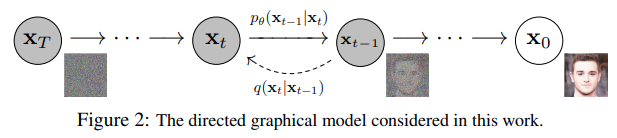
10.7Klucidrains/denoising-diffusion-pytorch · PythonA PyTorch implementation of the Denoising Diffusion Probabilistic Model (DDPM), a generative modeling approach the author positions as a possible rival to GANs.
- 58
YOLOX
10.7KMegvii-BaseDetection/YOLOX · PythonYOLOX is an object detector: an anchor-free version of YOLO with a simpler design but better performance, built to bridge the gap between research and industrial communities. The project says it outperforms YOLOv3-v5.
- 59
pyannote-audio
10.7Kpyannote/pyannote-audio · Jupyter NotebookAn open-source Python toolkit for speaker diarization - working out who spoke when in an audio recording. It is built on PyTorch and ships state-of-the-art pretrained models and pipelines.
- 60

yolov3
10.6Kultralytics/yolov3 · PythonUltralytics' PyTorch implementation of the YOLOv3 real-time object detector, packaging three model variants - YOLOv3, YOLOv3-SPP and YOLOv3-tiny - with training, validation, inference and multi-format export tooling.
- 61

cleanrl
10.6Kvwxyzjn/cleanrl · PythonCleanRL is a collection of high-quality single-file implementations of deep reinforcement learning algorithms (PPO, DQN, C51, SAC, DDPG, TD3, PPG and more), written to be read and tweaked rather than imported.
- 62

GolangTraining
10.5KGoesToEleven/GolangTraining · GoA collection of training materials and code examples for learning the Go (Golang) programming language, covering topics from the basics up through more advanced concepts.
- 63

TTS
10.2Kmozilla/TTS · Jupyter NotebookAn open-source deep learning library for text-to-speech: pretrained models, vocoders, a speaker encoder and dataset tools, already used in 20+ languages for products and research.
- 64

awesome-angular
10.1KPatrickJS/awesome-angular · HTMLA curated list of Angular resources: one GitHub README that collects the most interesting libraries, tools and learning material from across the Angular ecosystem.
- 65

reef
7.6KHuman-Agent-Society/reef · PythonReef is open-source infrastructure for continually self-improving agents. It wires together agent inference, feedback collection, learning, and versioned delivery so an agent keeps getting better from how you interact with it.
- 66

DeepSpec
7.2Kdeepseek-ai/DeepSpec · PythonDeepSpec is DeepSeek's full-stack Python codebase for training and evaluating draft models for speculative decoding — the technique where a small draft model accelerates a larger target LLM.
- 67
ai-infra-book
6.7Kbojieli/ai-infra-book · PythonAn open-source book, 'Understanding AI Infra: Quantitative Analysis and System Design' by Bojie Li, that derives LLM inference and training system designs from hardware constraints and model architecture using quantitative, order-of-magnitude estimates.
- 68
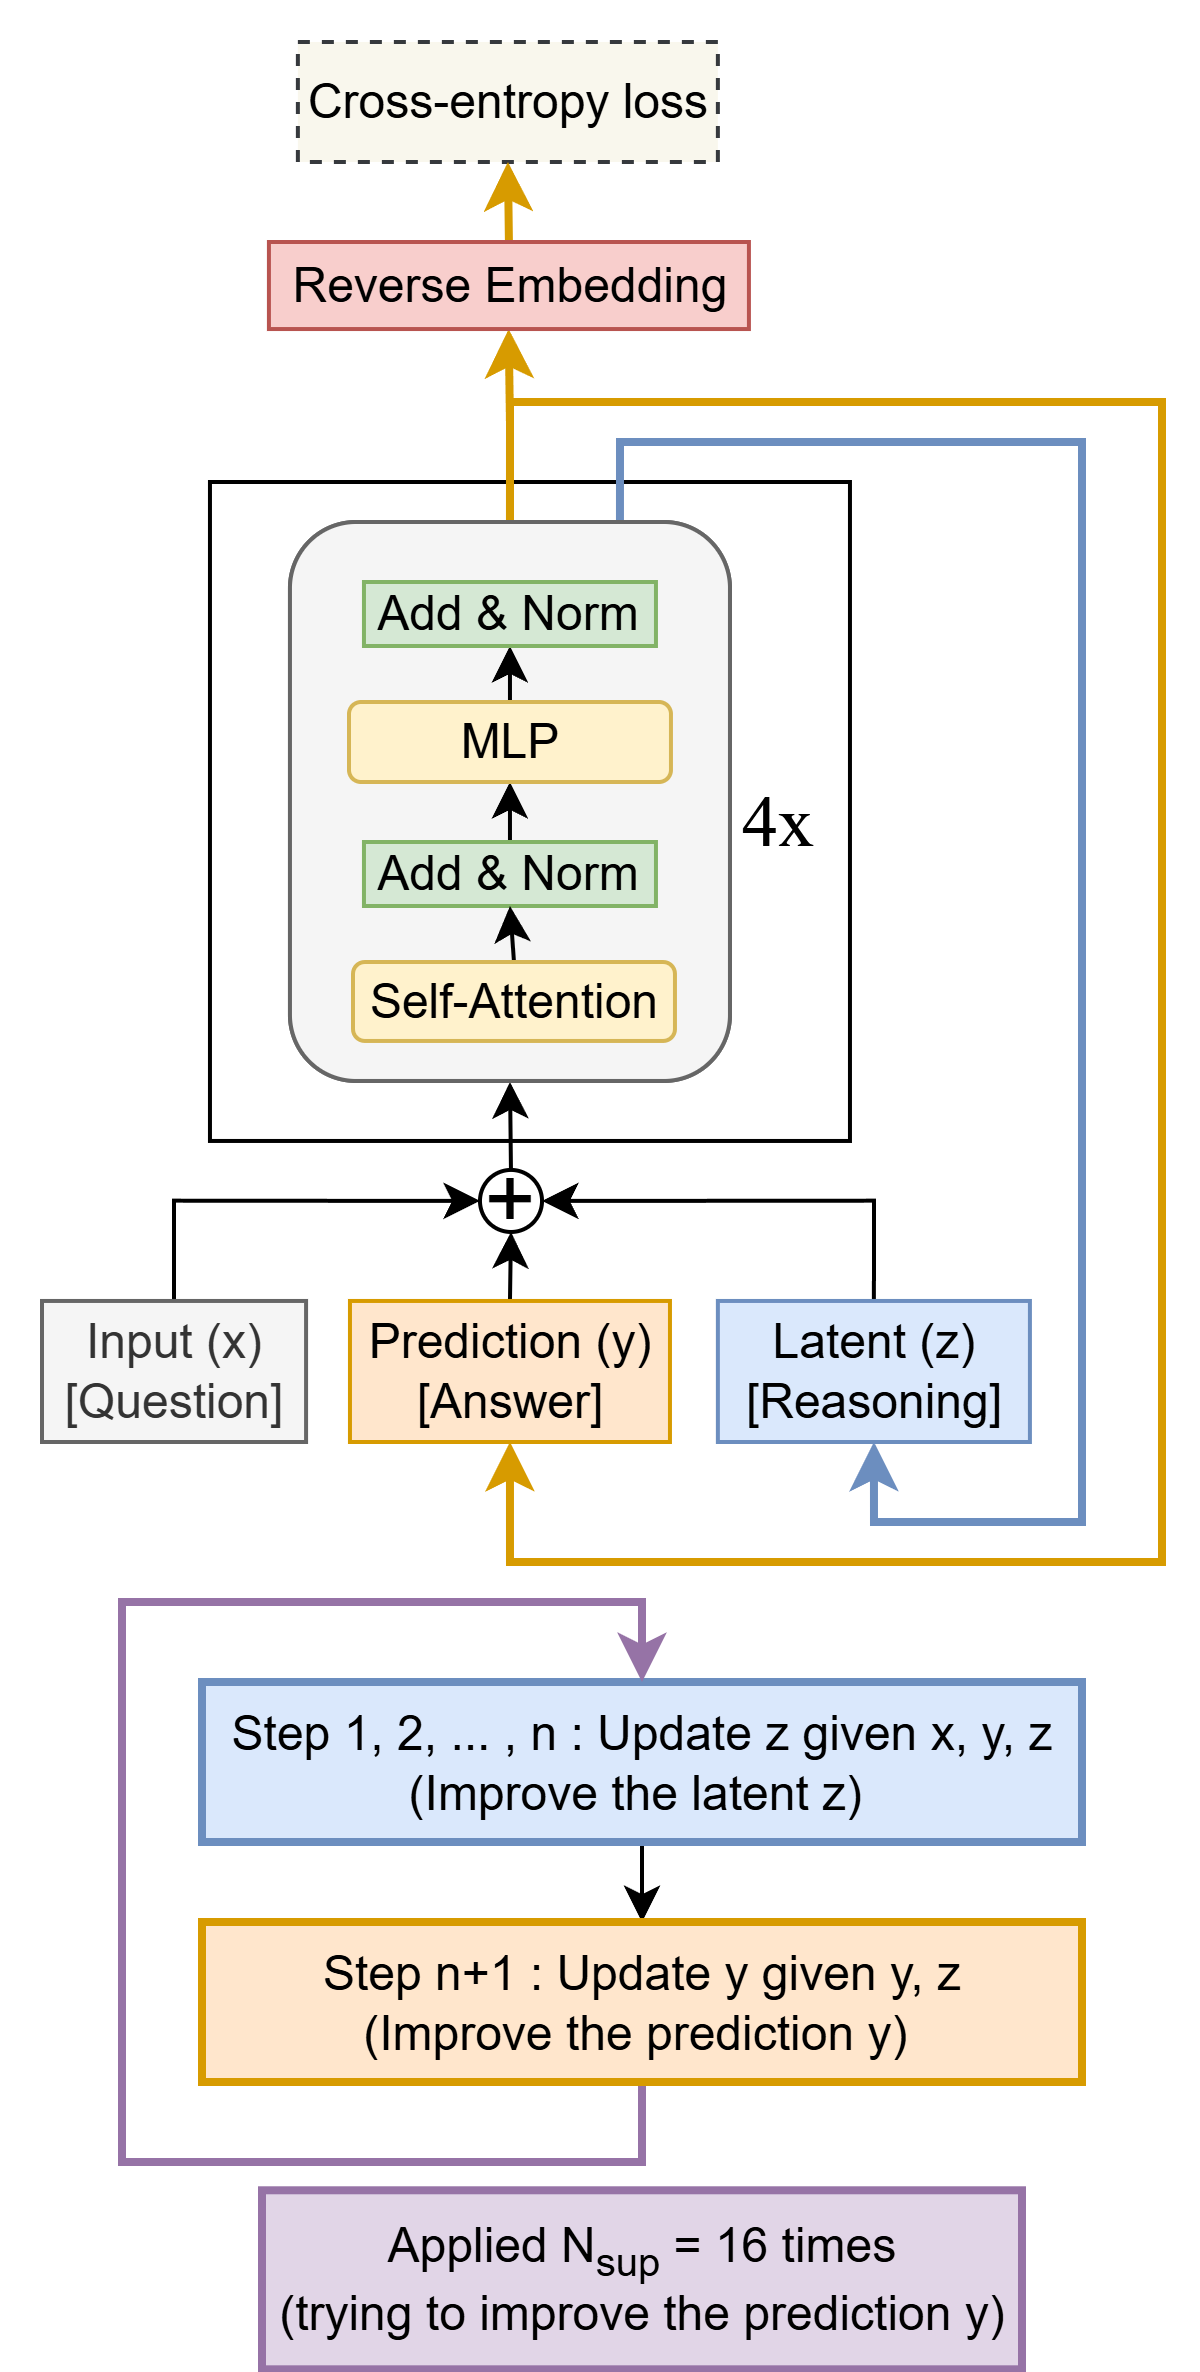
TinyRecursiveModels
6.6KSamsungSAILMontreal/TinyRecursiveModels · PythonThis is TRM (Tiny Recursive Model), the code behind the paper 'Less is More: Recursive Reasoning with Tiny Networks': a tiny 7M-parameter network that scores 45% on ARC-AGI-1 and 8% on ARC-AGI-2 through recursive reasoning.
- 69
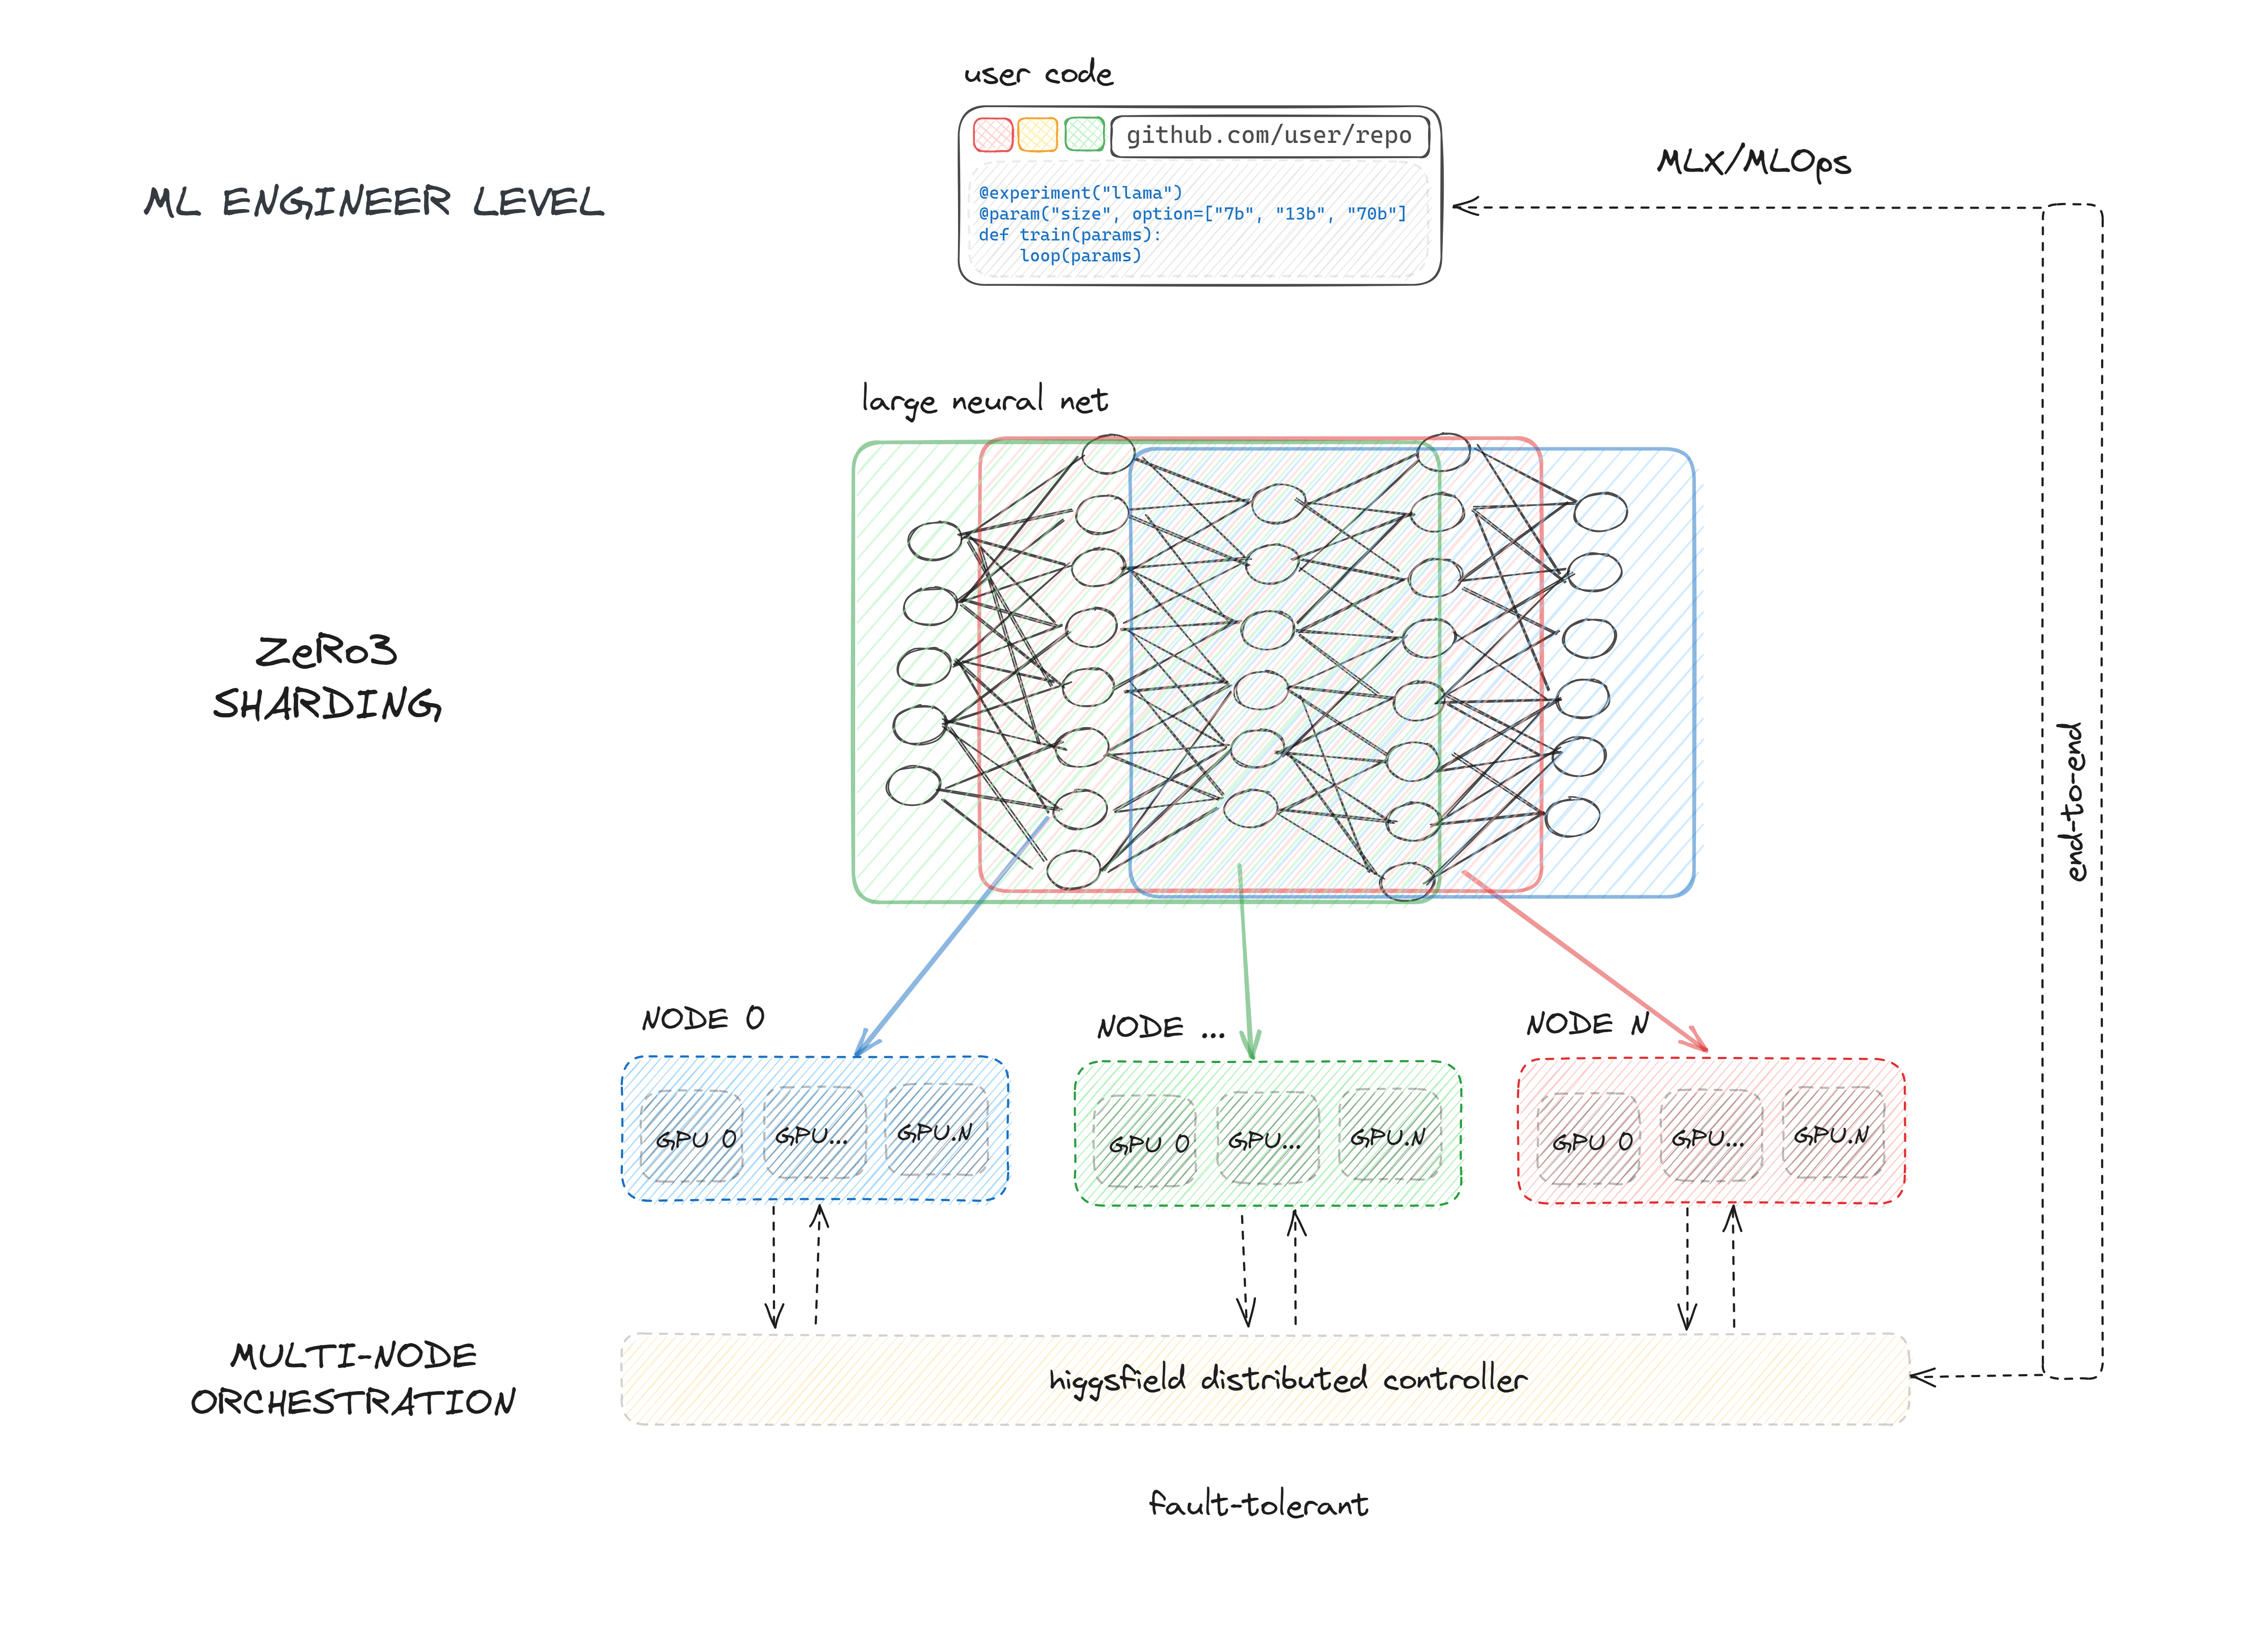
higgsfield
6.1Khiggsfield-ai/higgsfield · Jupyter NotebookHiggsfield is an open-source, fault-tolerant GPU orchestration system and machine learning framework for training huge models, from billions to trillions of parameters, such as LLMs.
- 70
tick-stock-panel
5.9Kshy3130/tick-stock-panel · PythonTSP is a self-hosted, zero-ops quantitative trading workbench for China's A-share stock market that combines stock screening, real-time anomaly monitoring, and strategy backtesting, with optional LLM-assisted analysis.
- 71

HunyuanVideo-1.5
4.6KTencent-Hunyuan/HunyuanVideo-1.5 · PythonHunyuanVideo-1.5 is a video generation model from Tencent that creates text-to-video and image-to-video clips, achieving top-tier quality with only 8.3B parameters so it runs on consumer-grade GPUs.
- 72
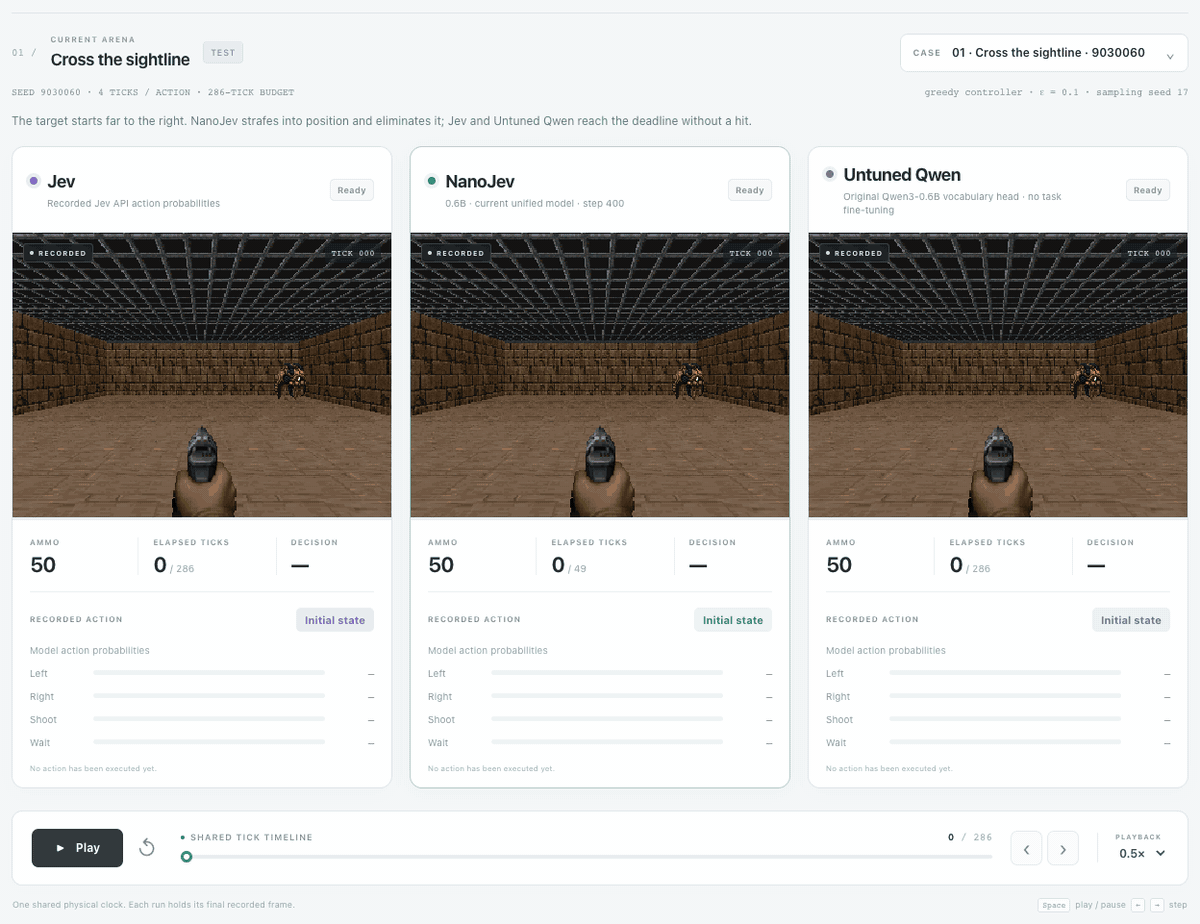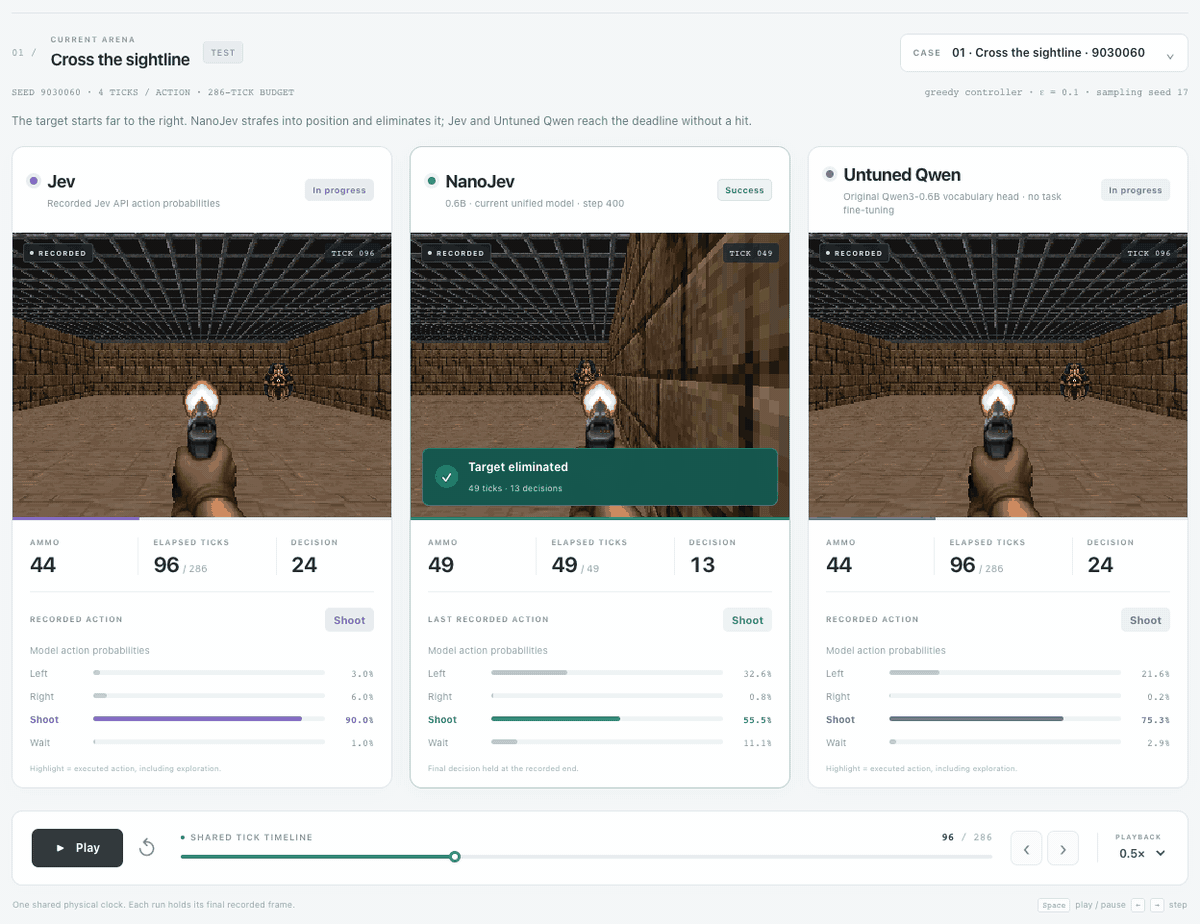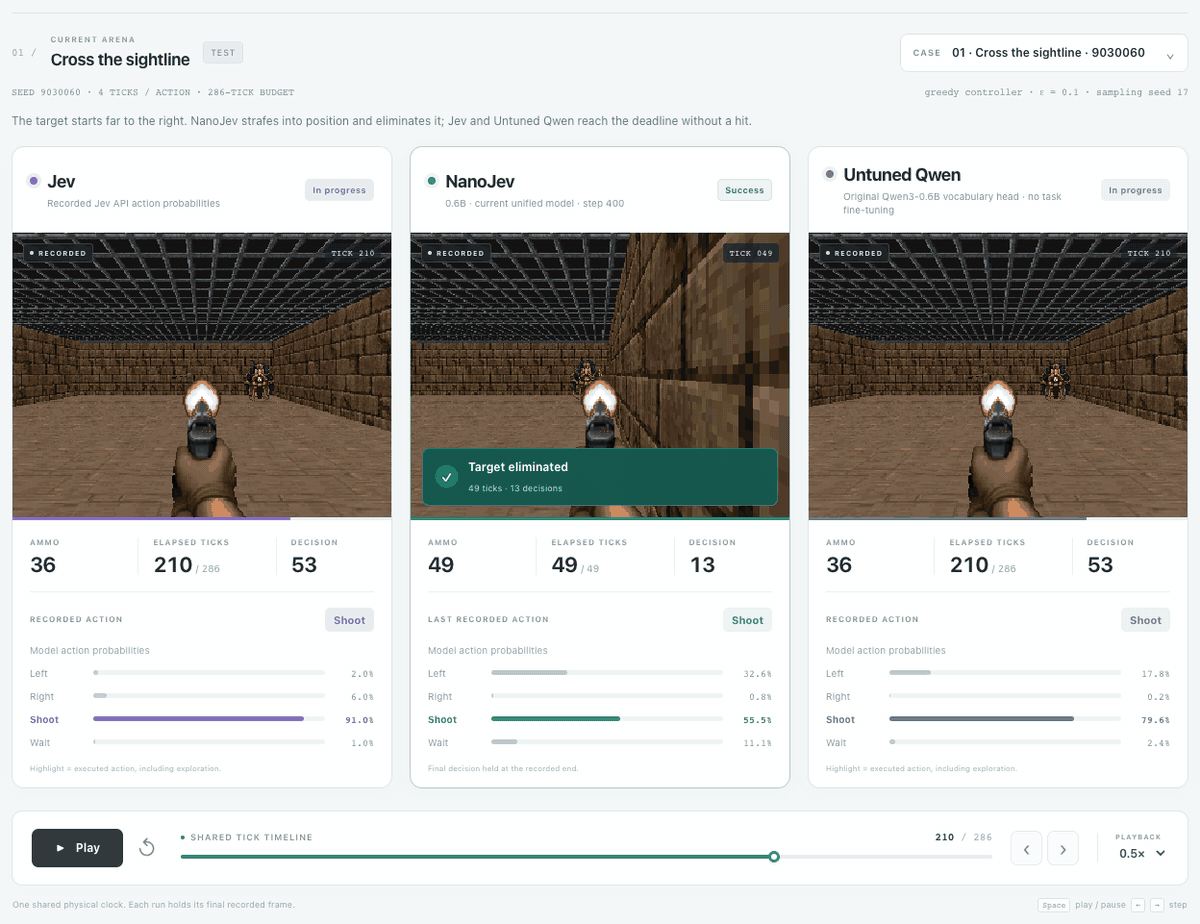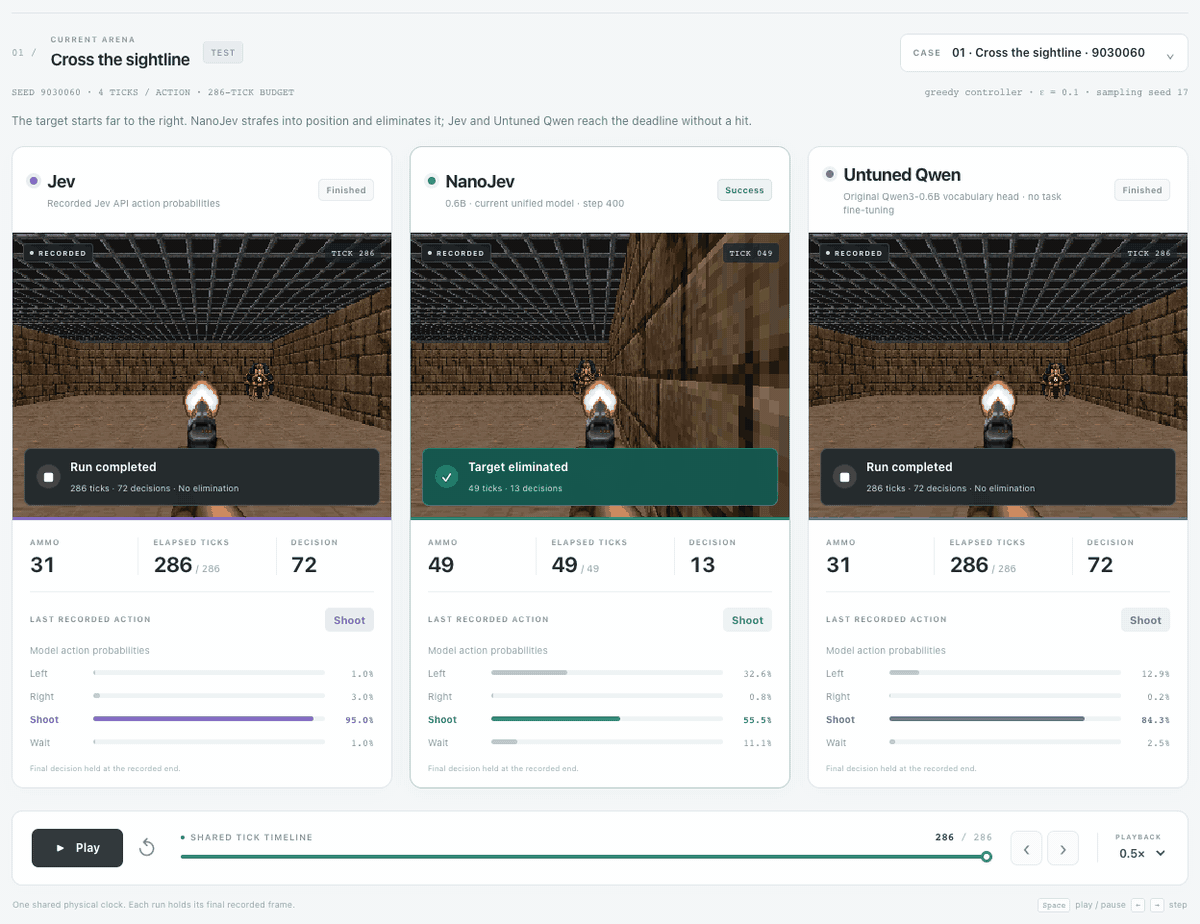
NanoJev
2.6KTianyuCodings/NanoJev · PythonA nano replica of Jev: a 0.6B-parameter parallel decision model that takes states and questions in and returns complete probability distributions — no output tokens are ever decoded.
- 73
jeff
1.5Kfirelex/jeff · PythonJeff is a family of small (0.8B-2B parameter) open-weight models fine-tuned from Qwen3.5 and Gemma 4 that act as fast 'System 1' decision-makers: you describe a situation and a list of options in plain text, and Jeff returns a calibrated probability for each option from a single forward pass, with no generated text to parse.
- 74
jevlike
1.4Kvinnylarouge/jevlike · PythonA small research model that reads a piece of text plus a list of options and returns a probability for each option in one pass, instead of writing an answer token by token.
- 75
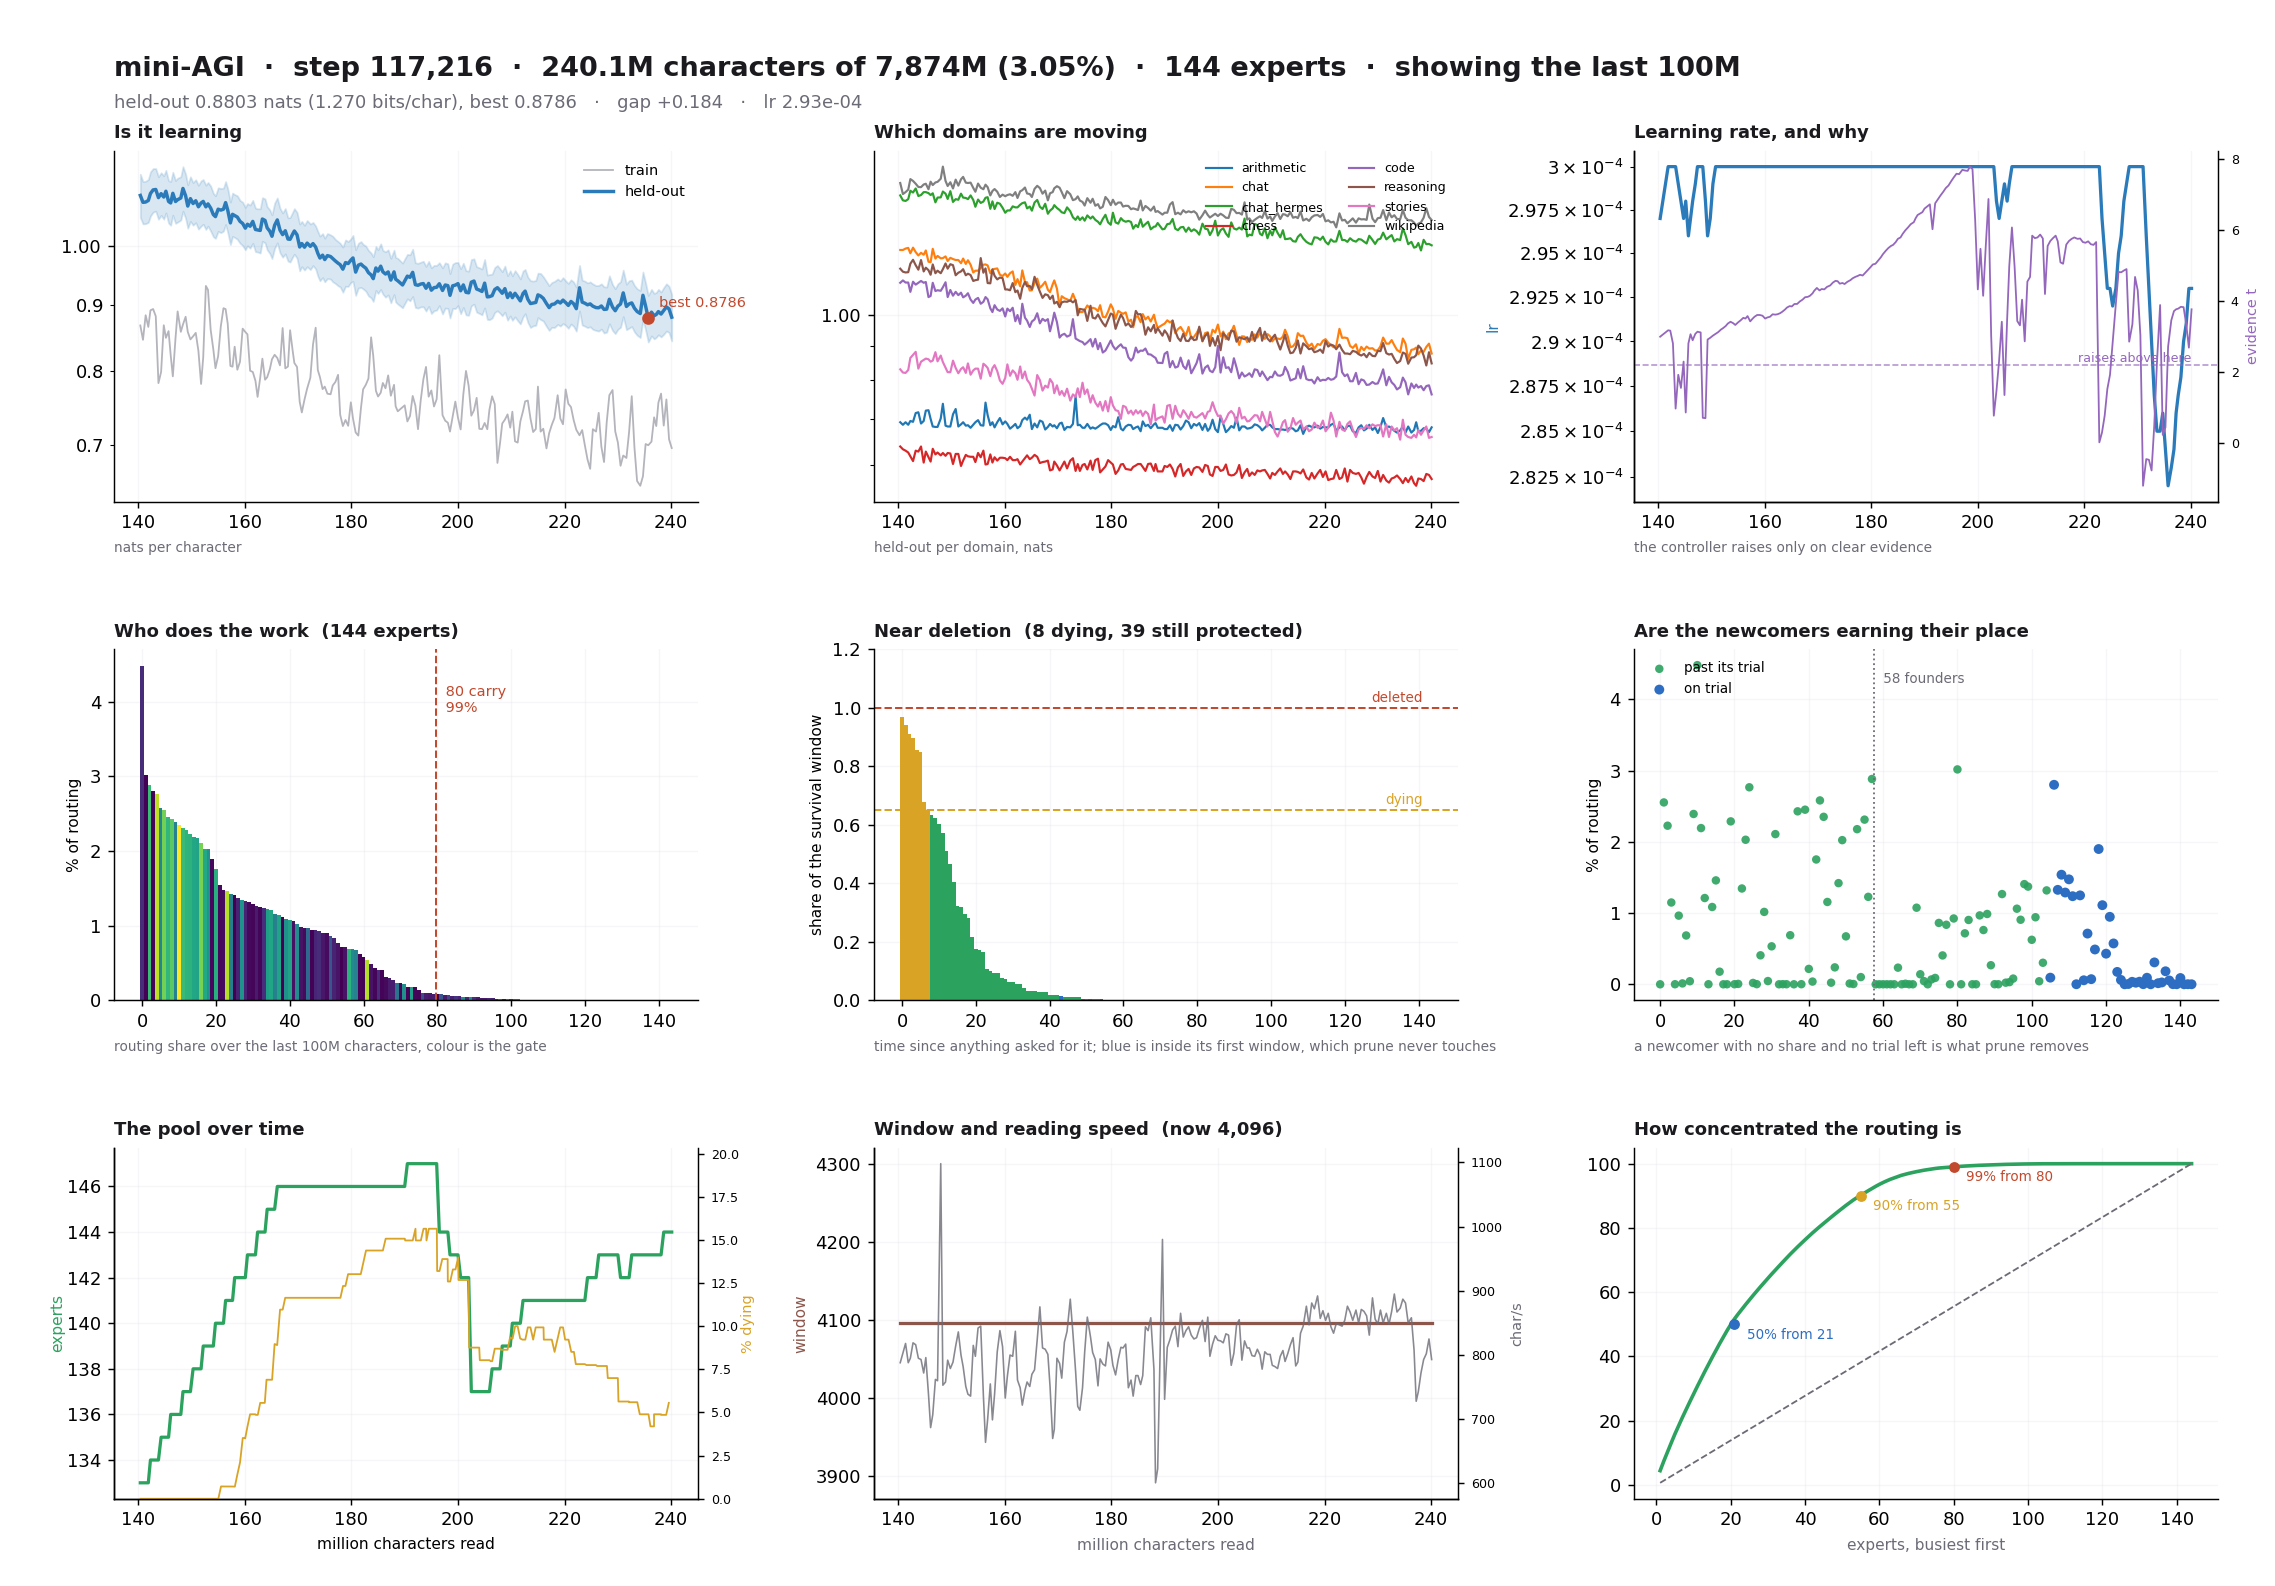
mini-AGI
1.2Kvolotat/mini-AGI · Pythonmini-AGI is a continual learning, byte-level language model that assembles its own architecture, trains from scratch on a single 8GB VRAM GPU, and keeps learning from everything it reads, without a separate fine-tuning phase.
- 76
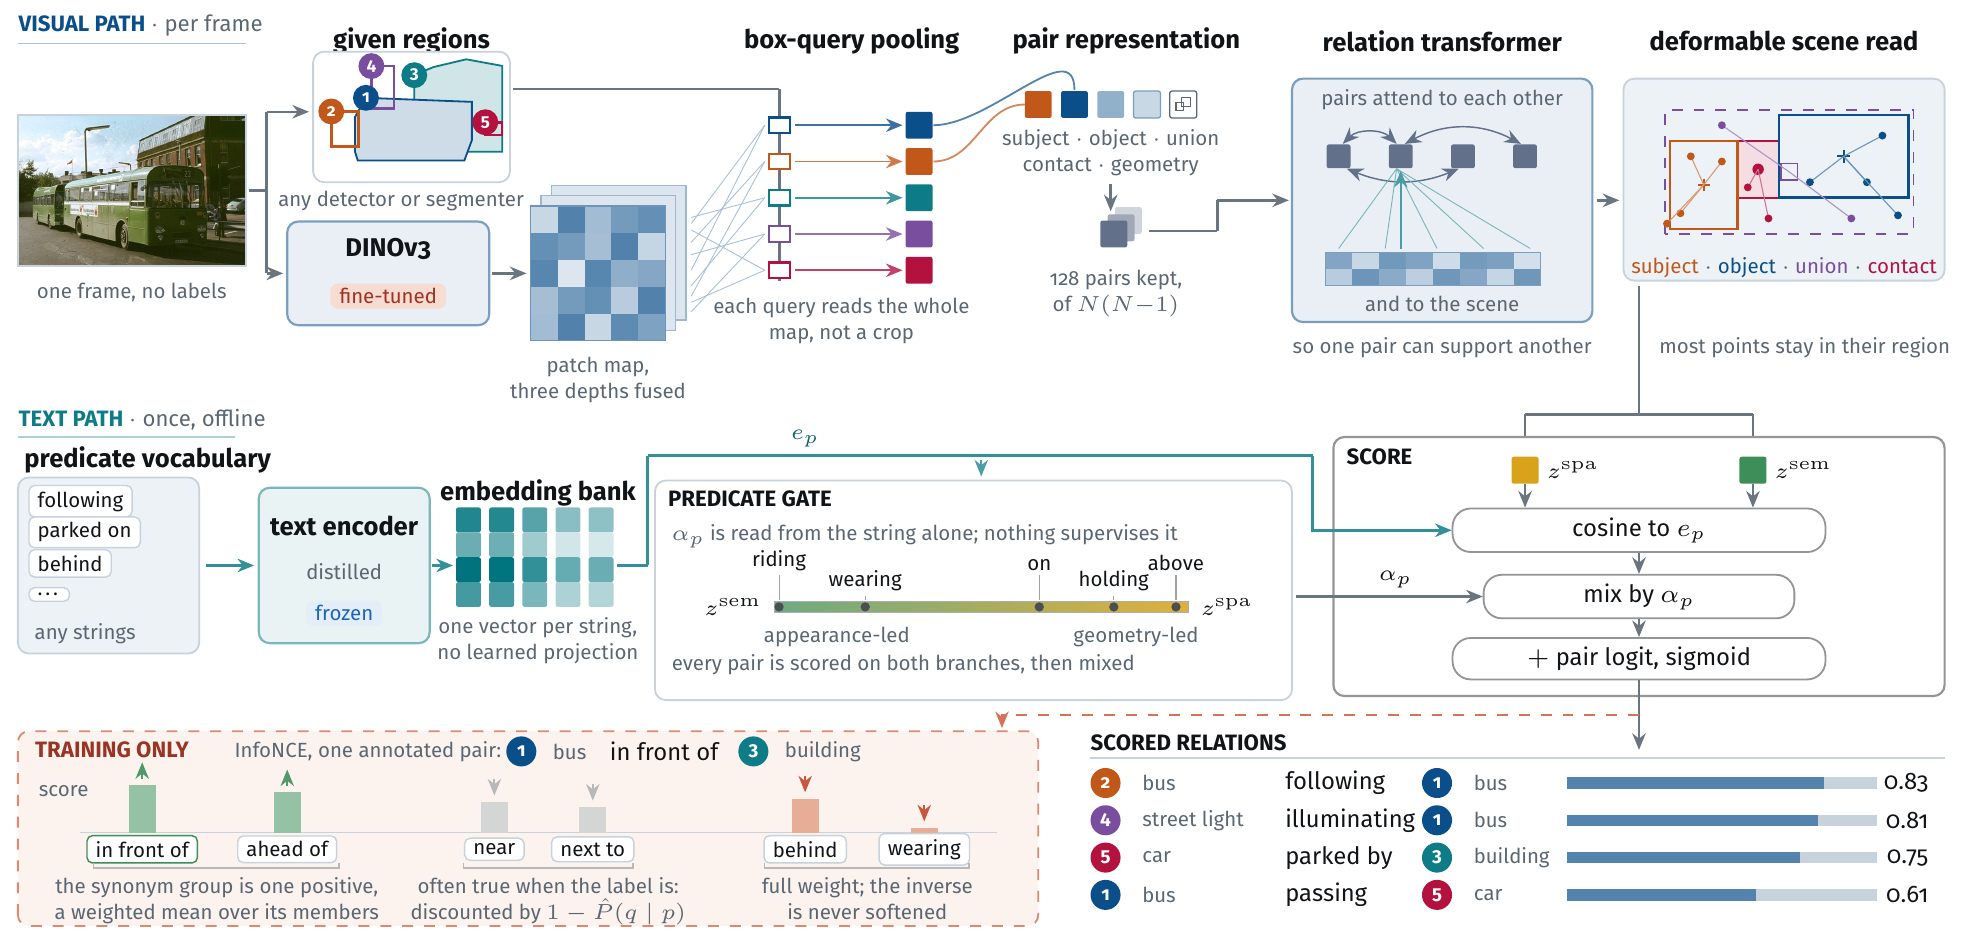
RelateAnything
1.1KMaelic/RelateAnything · PythonRelateAnything is a real-time, open-vocabulary relation prediction model: give it an image, object regions and the relations to look for, and it returns scored (subject, relation, object) triplets like person → riding → horse.
- 77
SolarWM
777Junchao-cs/SolarWM · PythonSolarWM is a fully open foundation for building interactive video world models, covering data preparation, scalable multi-backbone training, and long-horizon inference.
- 78
FluxVLA
748FluxVLA/FluxVLA · PythonFluxVLA is a full-stack engineering platform for embodied AI covering the whole loop from data to real-robot deployment for vision-language-action (VLA) models, built to lower the engineering barrier for VLA research and development.
- 79
context-language-models
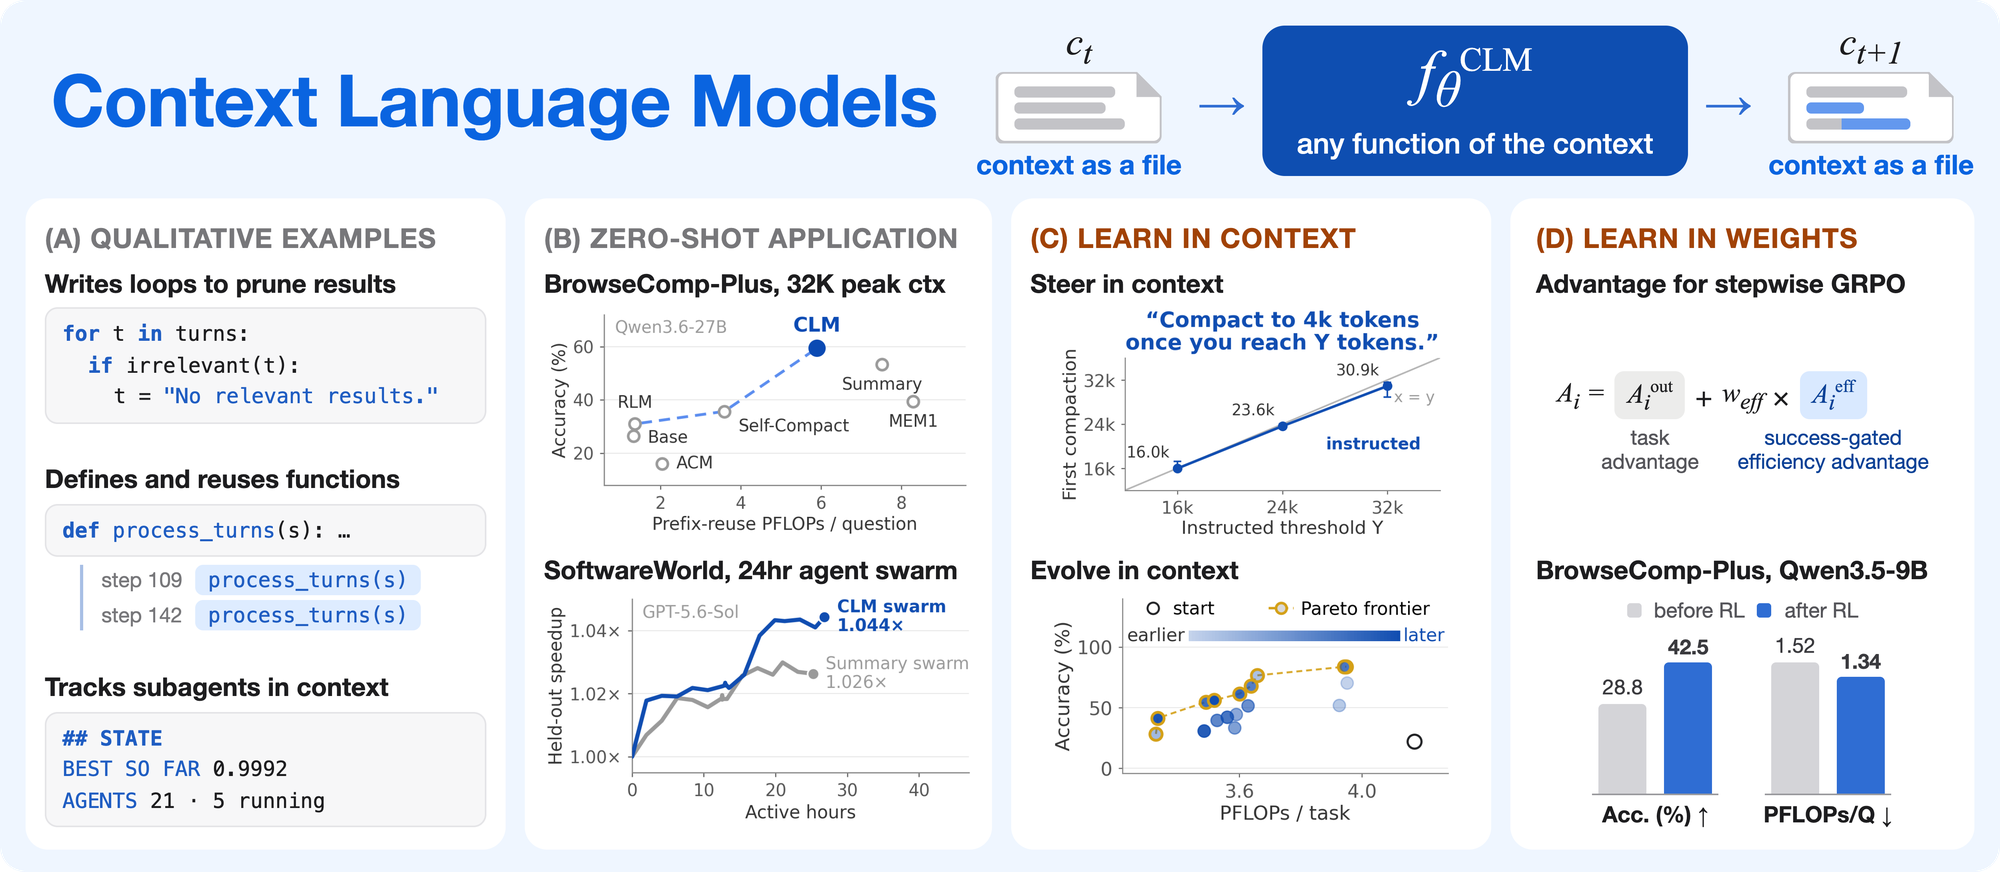
730facebookresearch/context-language-models · PythonThis is the official code release for 'Context Language Models (CLMs)', research from University of Washington, Meta Superintelligence Labs, MIT and Trillium Labs. CLMs are language models that natively manage their own context by treating it as a file they can freely edit, which naturally extends to multi-agent setups where each agent's context is its own file.
- 80
verl
716XiaomiMiMo/verl · Pythonverl is an open-source RL post-training framework for large language models, started by ByteDance Seed as the open-source version of the HybridFlow paper. This XiaomiMiMo fork adds agentic RL training code for MiMo, with reproduction code for five RL environments on top of verl 0.9.0.dev.
- 81
LoongForge
687baidu-baige/LoongForge · PythonAn open-source training framework from Baidu's Baige team for LLMs, VLMs, diffusion and embodied models, built for faster training and lower cost on NVIDIA GPUs and Kunlun XPUs.
- 82
Motus2
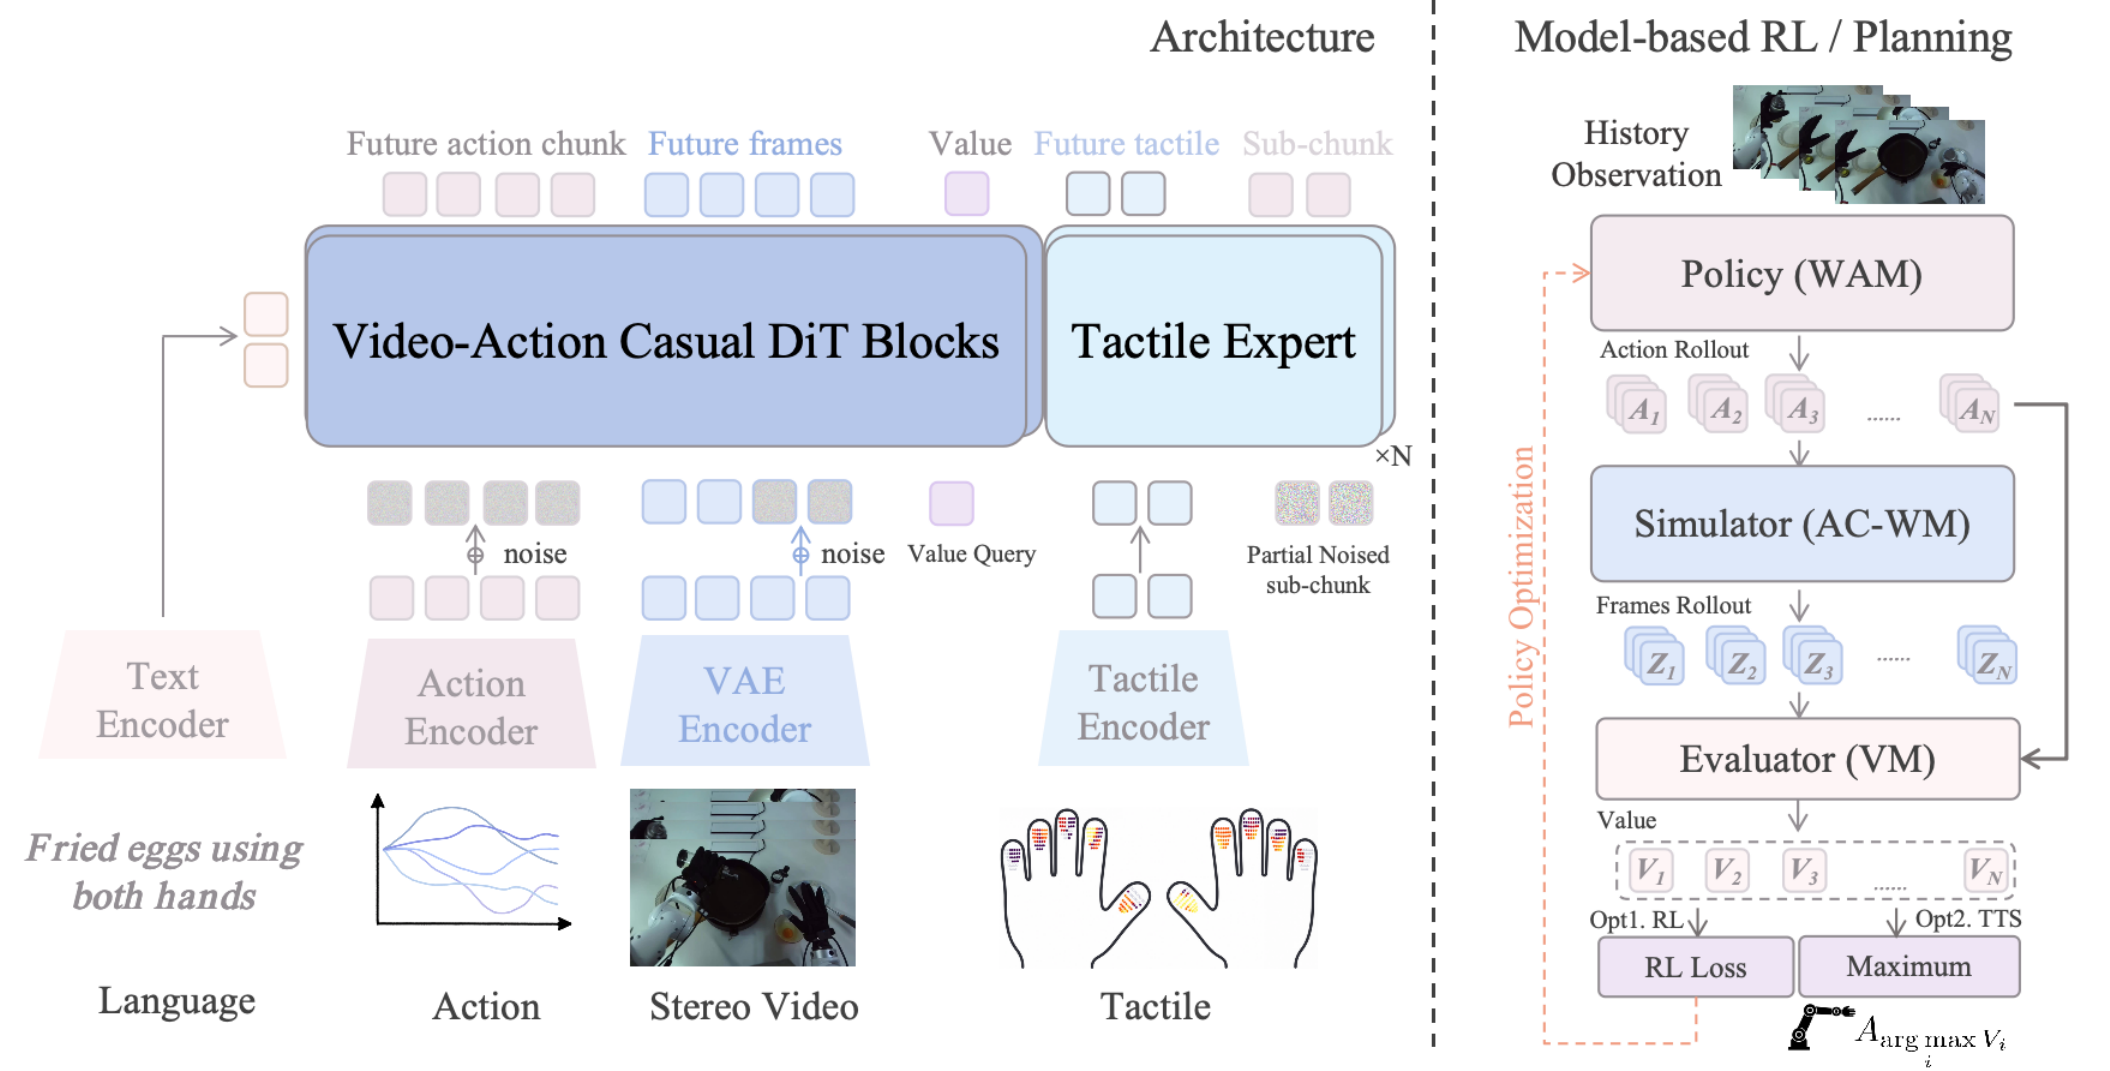
685shengshu-ai/Motus2Motus2 is a self-evolving general world model for dexterous robot manipulation. A single model with shared weights acts as a policy, a simulator, and an evaluator, coupling them into a closed decision-and-learning loop so the system can perceive, predict, act, and improve itself.
- 83
jeeves
425PostHog/jeeves · PythonJeeves is a reasoning-enhanced 'Jev-like' decision model built on Qwen3.5-9B with LoRA. It thinks through a reasoning chain before giving calibrated yes/no, multiple-choice, or rating answers, and ships with a diffusion drafter for faster inference.
- 84
EasyWAM
401OpenMOSS/EasyWAM · PythonEasyWAM is a unified research codebase for training, fine-tuning, and evaluating World Action Models (WAMs) — models that jointly predict future video and robot actions for embodied-AI and robotics research.
- 85
Meshy
387OpenBMB/Meshy · PythonMeshy is an open-source framework for running reinforcement learning (RL) training jobs where every role (inference, training, rollout) runs as an independent service, communicating through a shared TransferQueue data plane. It is built on SGLang and torchtitan.
- 86

H3-World
318Danzer1xxxxChan/H3-World · PythonH3-World is an interactive world model built on MiniMax-H3: give it one initial frame and it generates video you steer with keyboard actions, like driving a game world with your keys.
- 87
manaca-1b-base
249Instituto-IA-LNCC/manaca-1b-base · PythonAn open ~1.72B-parameter language model trained from scratch for Brazilian Portuguese. The repo holds the whole reproducible pipeline: Docker environment, corpus pipeline, tokenizer training, Megatron-LM pretraining, and a Portuguese benchmark suite.
- 88
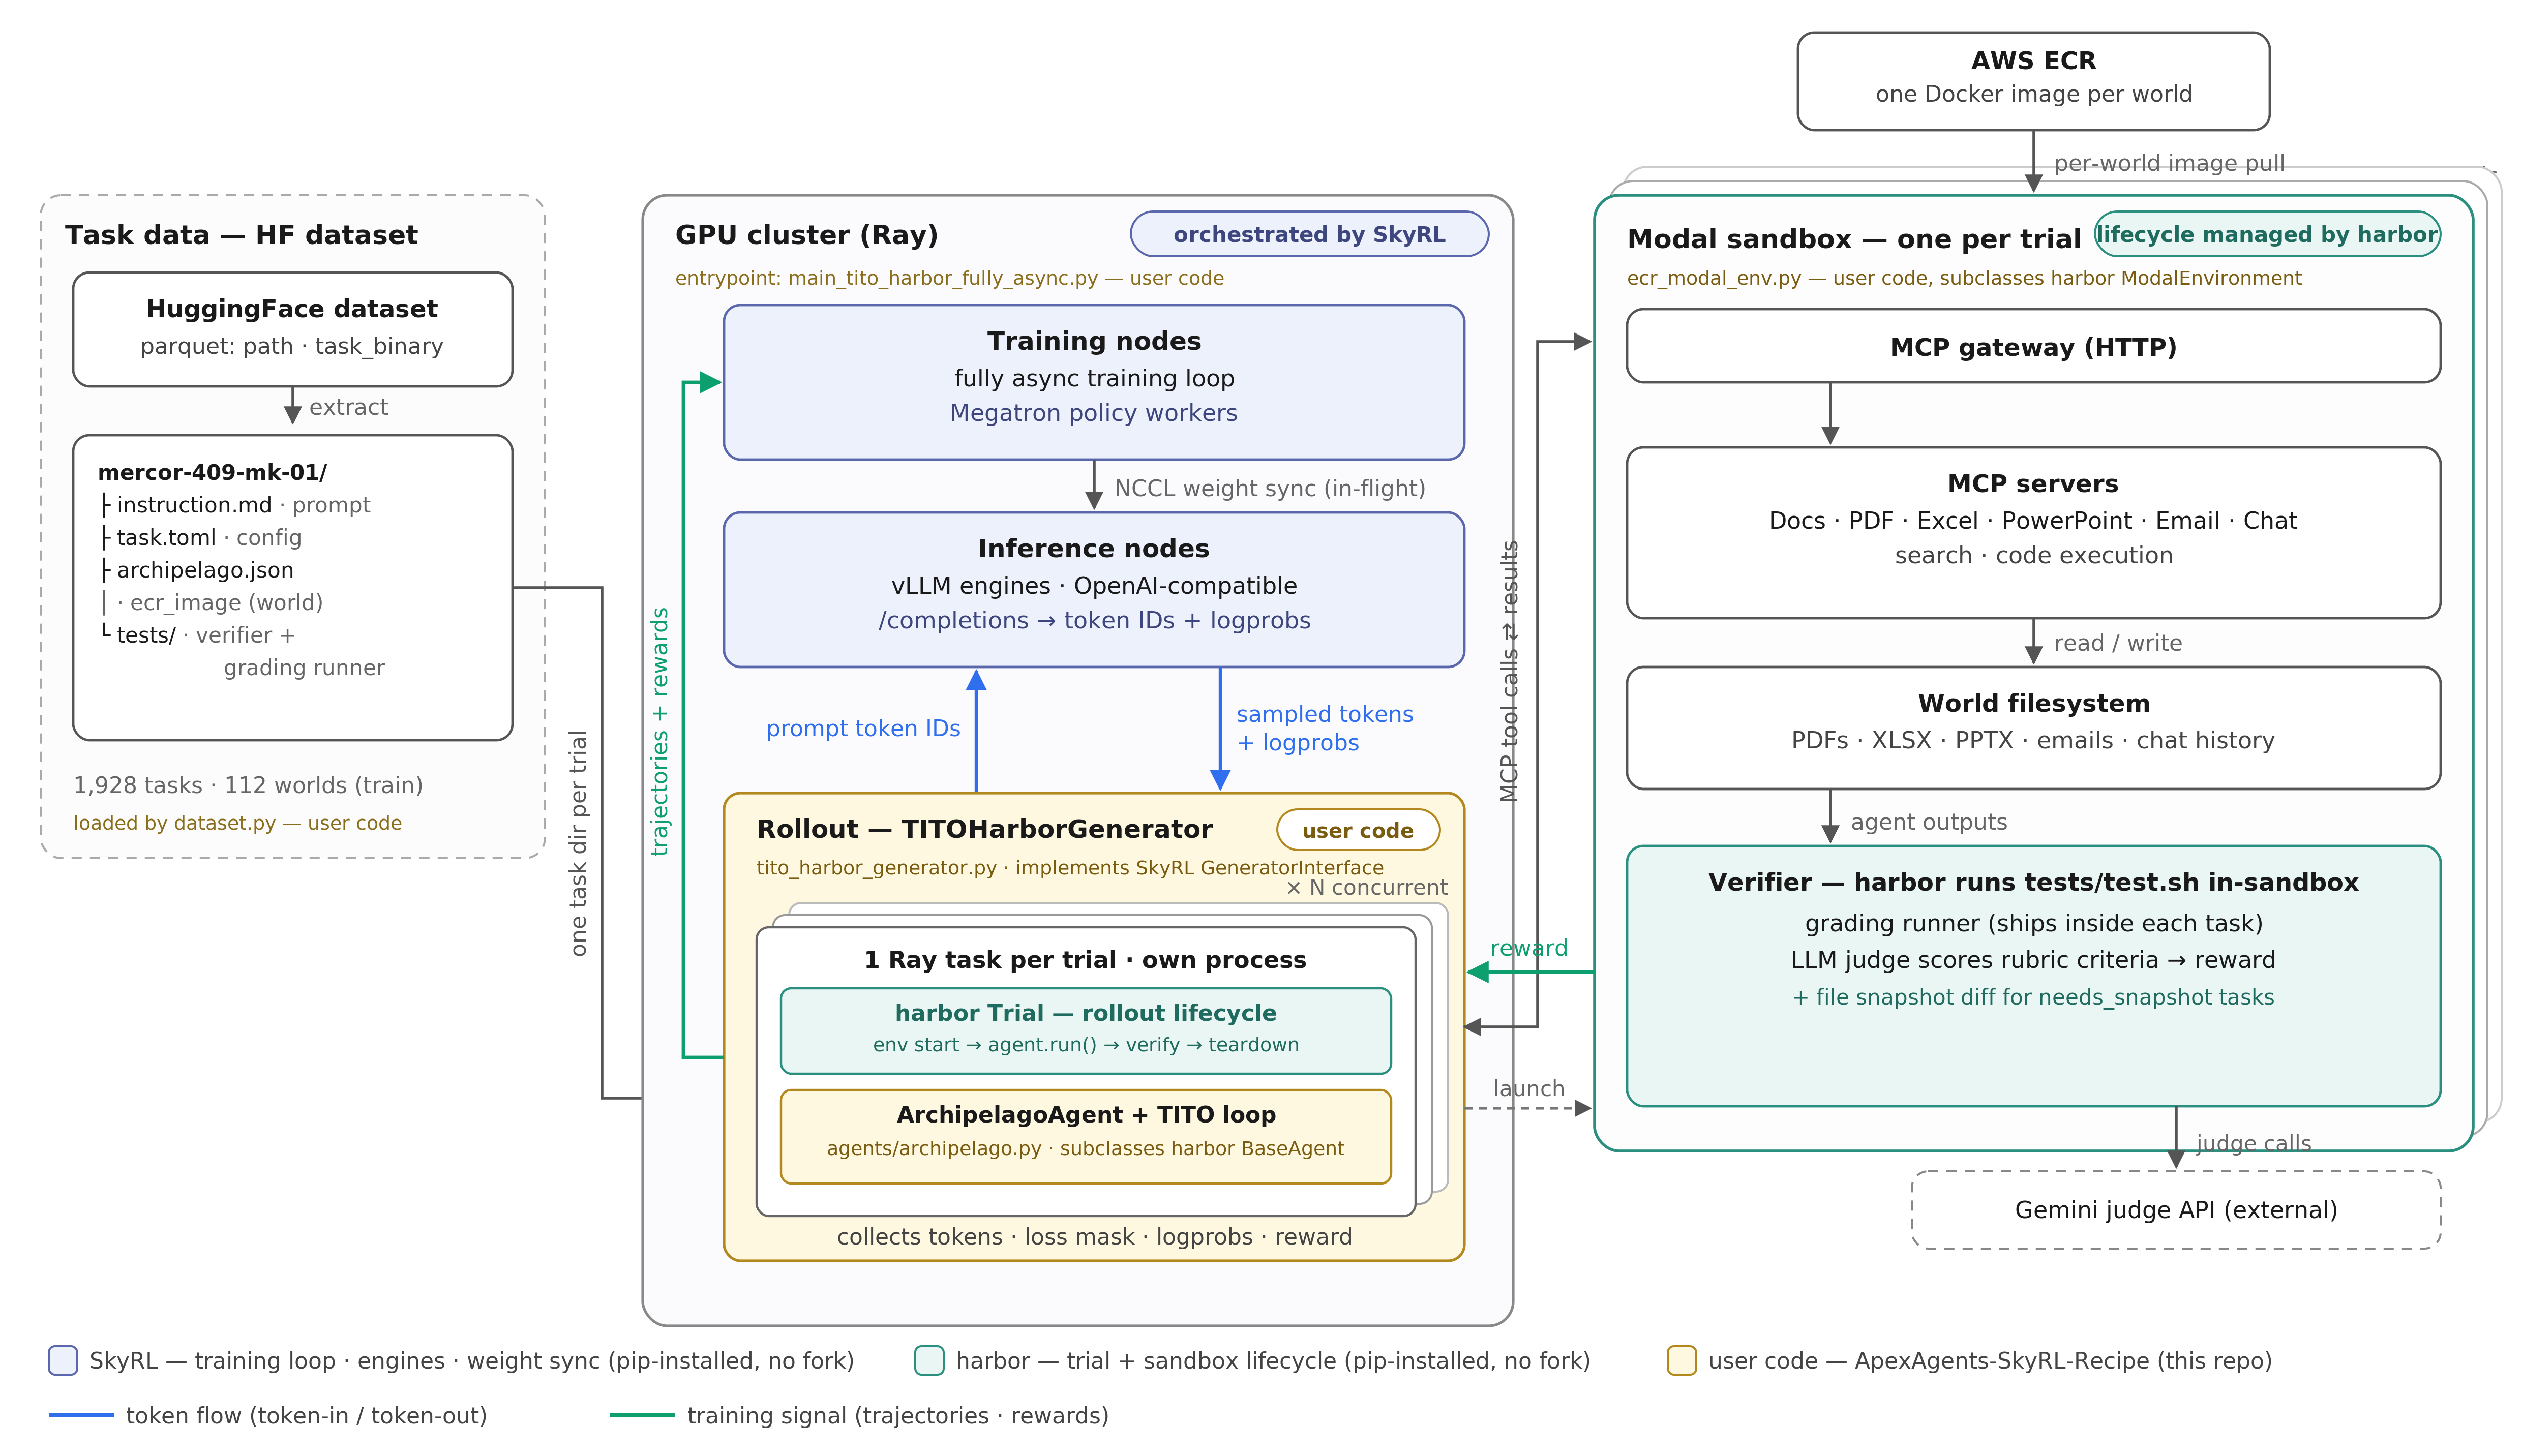
ApexAgents-SkyRL-Recipe
217Mercor-Intelligence/ApexAgents-SkyRL-Recipe · PythonIt's a complete, public recipe for RL-training knowledge-work agents on Mercor's APEX-Agents data, built on the open-source SkyRL training library and the open-source harbor sandbox/grading toolkit. It's the companion code for Mercor's 'Training Frontier Knowledge Work Agents' blogpost.
- 89
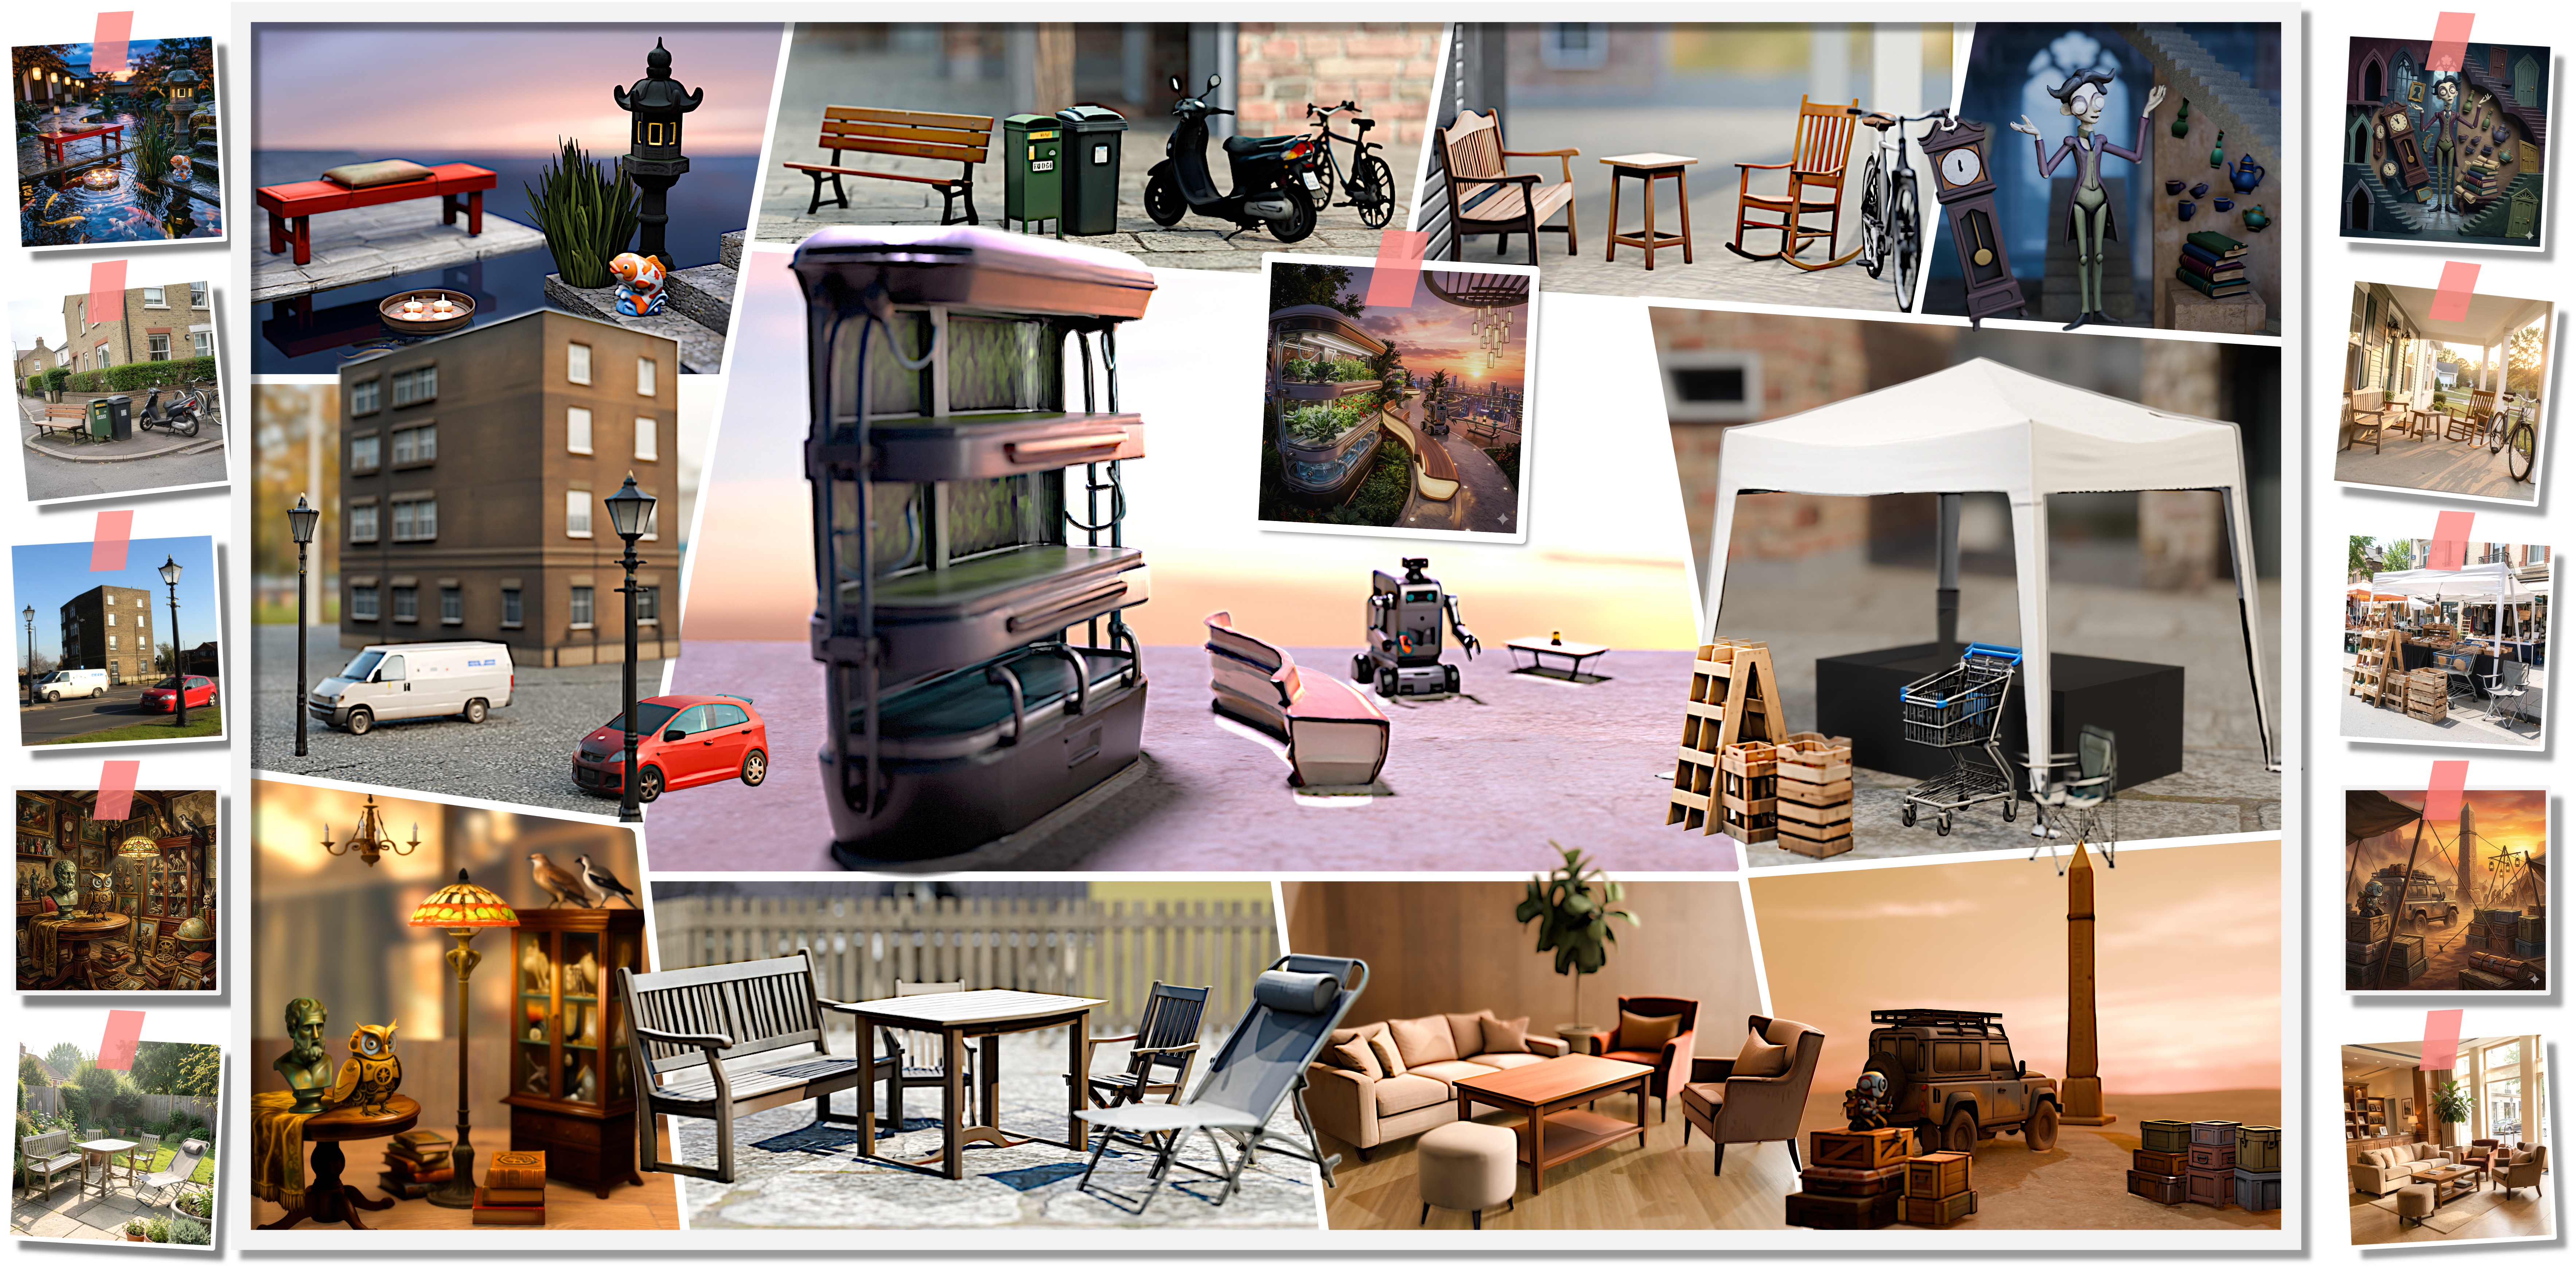
Mira-Scene
211VAST-AI-Research/Mira-Scene · PythonMira-Scene is a pipeline that reconstructs an editable 3D scene from a single image, combining interactive instance segmentation, depth estimation, canonical coordinate and voxel prediction, object mesh generation, scene assembly, and environment-map generation.
- 90
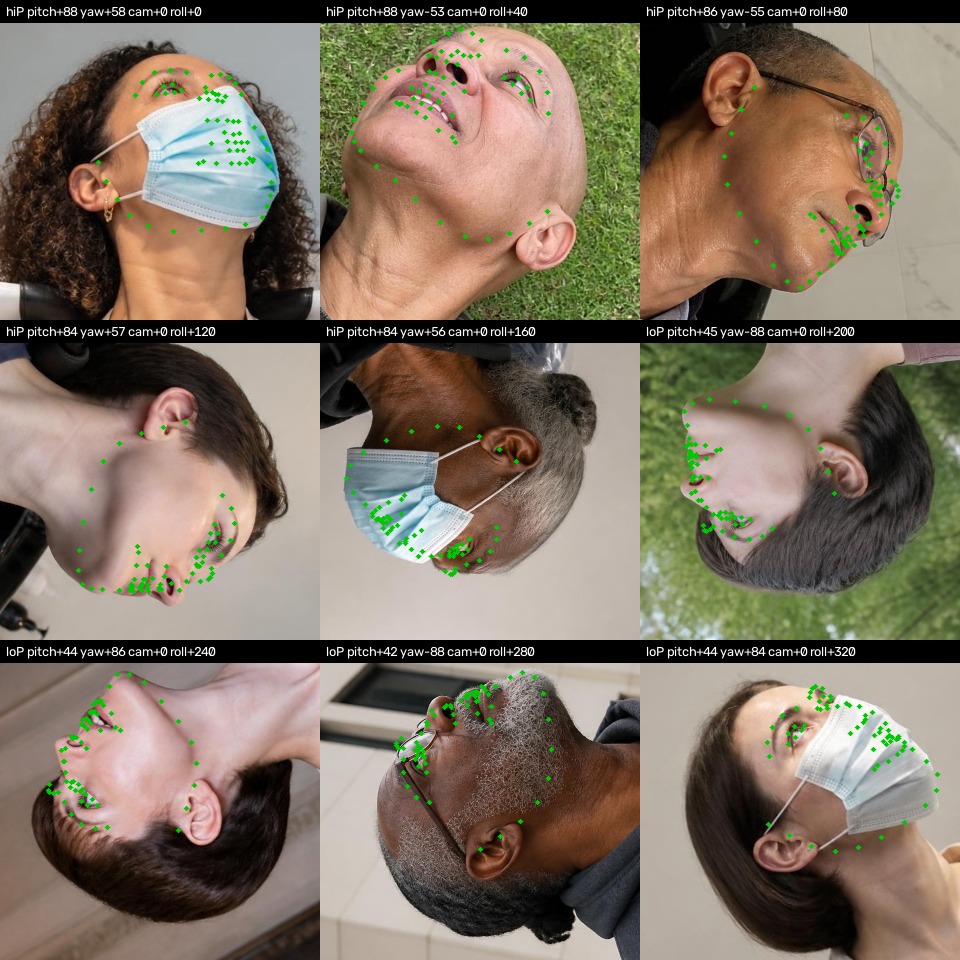
High-Angle_Robust_Fast_FaceAlignment
195PINTO0309/High-Angle_Robust_Fast_FaceAlignment · PythonHRFFA is a training, distillation and ONNX deployment pipeline for whole-head face alignment that stays robust at extreme head poses (looking up/down, full 360° roll, profile views) while being light enough for CPU inference.
- 91
Bud-Decision-Studio
110BudEcosystem/Bud-Decision-Studio · HTMLBud Decision Studio is a cross-platform desktop app and local serving system for 'decision models' (Jev-like 'System One' models): you give it a situation and typed questions, and it returns a calibrated probability for every allowed answer instead of generated text.

Related topics
Often tagged together
- deep-learning737
- python2,383
- machine-learning916
- gpu789
- ai1,955
- research764
- open-source5,666
- pytorch419
- cuda396
- inference327
- llm1,483
- huggingface362
- linux4,184
- fine-tuning185
- apache-2.01,434
- benchmark431
- nvidia328
- framework758
- computer-vision384
- docker1,660
- large-language-models213
- library1,587
- reinforcement-learning149
- transformer212