Topics / #a-stock
A-stock projects on GitHub
Quantitative data pipelines and daily analysis for Chinese A-share stock trading.
As of , the most-starred A-stock projects on GitHub are daily_stock_analysis (67.2K stars), UZI-Skill (7.4K stars) and tick-stock-panel (6.4K stars). GitHub.Locker tracks 5 A-stock repositories with 85.3K stars combined. The fastest-growing on October 27 was Vibe-Research, with +210 stars in a day.
Hot right now
Most stars gained in a day · Oct 27
 +210
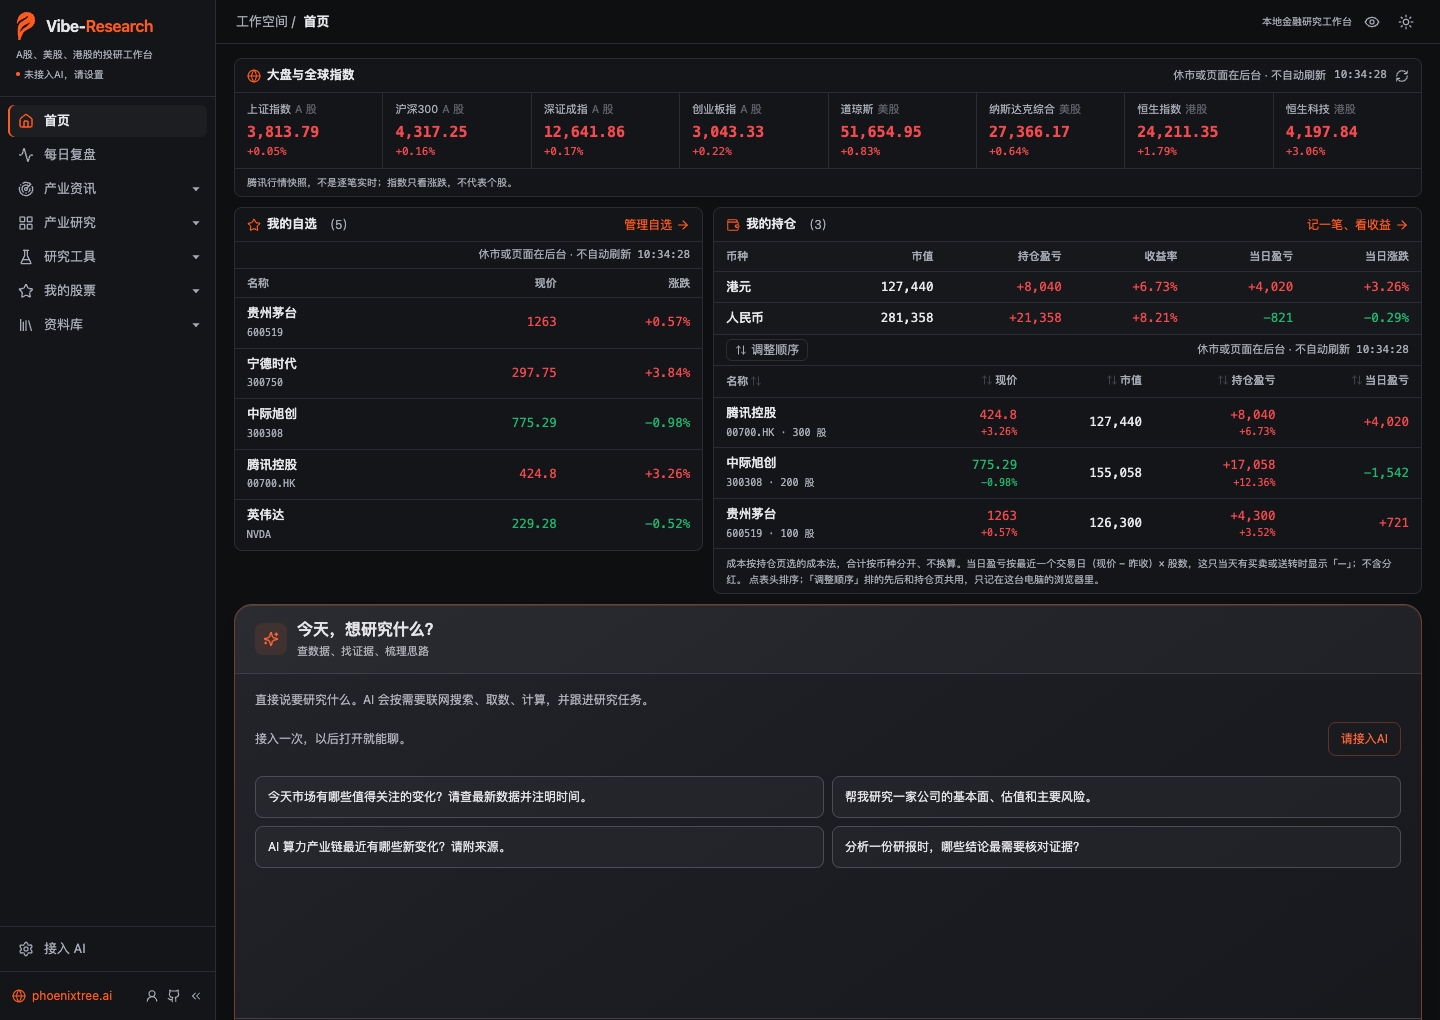
Vibe-Research
simonlin1212/Vibe-Research · ★ 3.4KVibe-Research:A 股、美股、港股的投研工作台 · 自选与持仓、每日复盘、产业资讯、产业研究、个股深挖、回测、研报库,168 个数据端点。支持 Claude Code、Codex、WorkBuddy 订阅或任意模型 API。 | A research workbench for China A-shares, US and HK stocks.
 +62
daily_stock_analysis
ZhuLinsen/daily_stock_analysis · ★ 67.2KAn AI-driven stock analysis system that pulls market data and news for A-share, Hong Kong, US, Japanese, Korean and Taiwanese stocks, then generates a daily AI decision report and pushes it to WeChat Work, Feishu, Telegram, Discord, Slack or email.
 +12
UZI-Skill
wbh604/UZI-Skill · ★ 7.4KA free skill that turns your AI coding agent into a personal stock analyst: give it a ticker and it pulls 22 dimensions of data, runs 22 institutional methods (DCF, comps, LBO), lets 66 investor personas vote, and outputs a ~600KB Bloomberg-style HTML report in 5-8 minutes. Covers A-shares, Hong Kong and US stocks.
 +9
CNEquity
rootSunc/CNEquity · ★ 890CNEquity is local data infrastructure for the Chinese A-share market: it organizes stock quotes, futures, fundamentals, corporate events and capital-flow data from multiple sources into a local Parquet data lake with incremental collection, resumable failures, quality audits and unified querying.
The all-time top
5 projects · by stars
- 67.2K#1 · ZhuLinsen/daily_stock_analysis
daily_stock_analysis
An AI-driven stock analysis system that pulls market data and news for A-share, Hong Kong, US, Japanese, Korean and Taiwanese stocks, then generates a daily AI decision report and pushes it to WeChat Work, Feishu, Telegram, Discord, Slack or email.
- 7.4K#2 · wbh604/UZI-Skill
UZI-Skill
A free skill that turns your AI coding agent into a personal stock analyst: give it a ticker and it pulls 22 dimensions of data, runs 22 institutional methods (DCF, comps, LBO), lets 66 investor personas vote, and outputs a ~600KB Bloomberg-style HTML report in 5-8 minutes. Covers A-shares, Hong Kong and US stocks.
- 6.4K
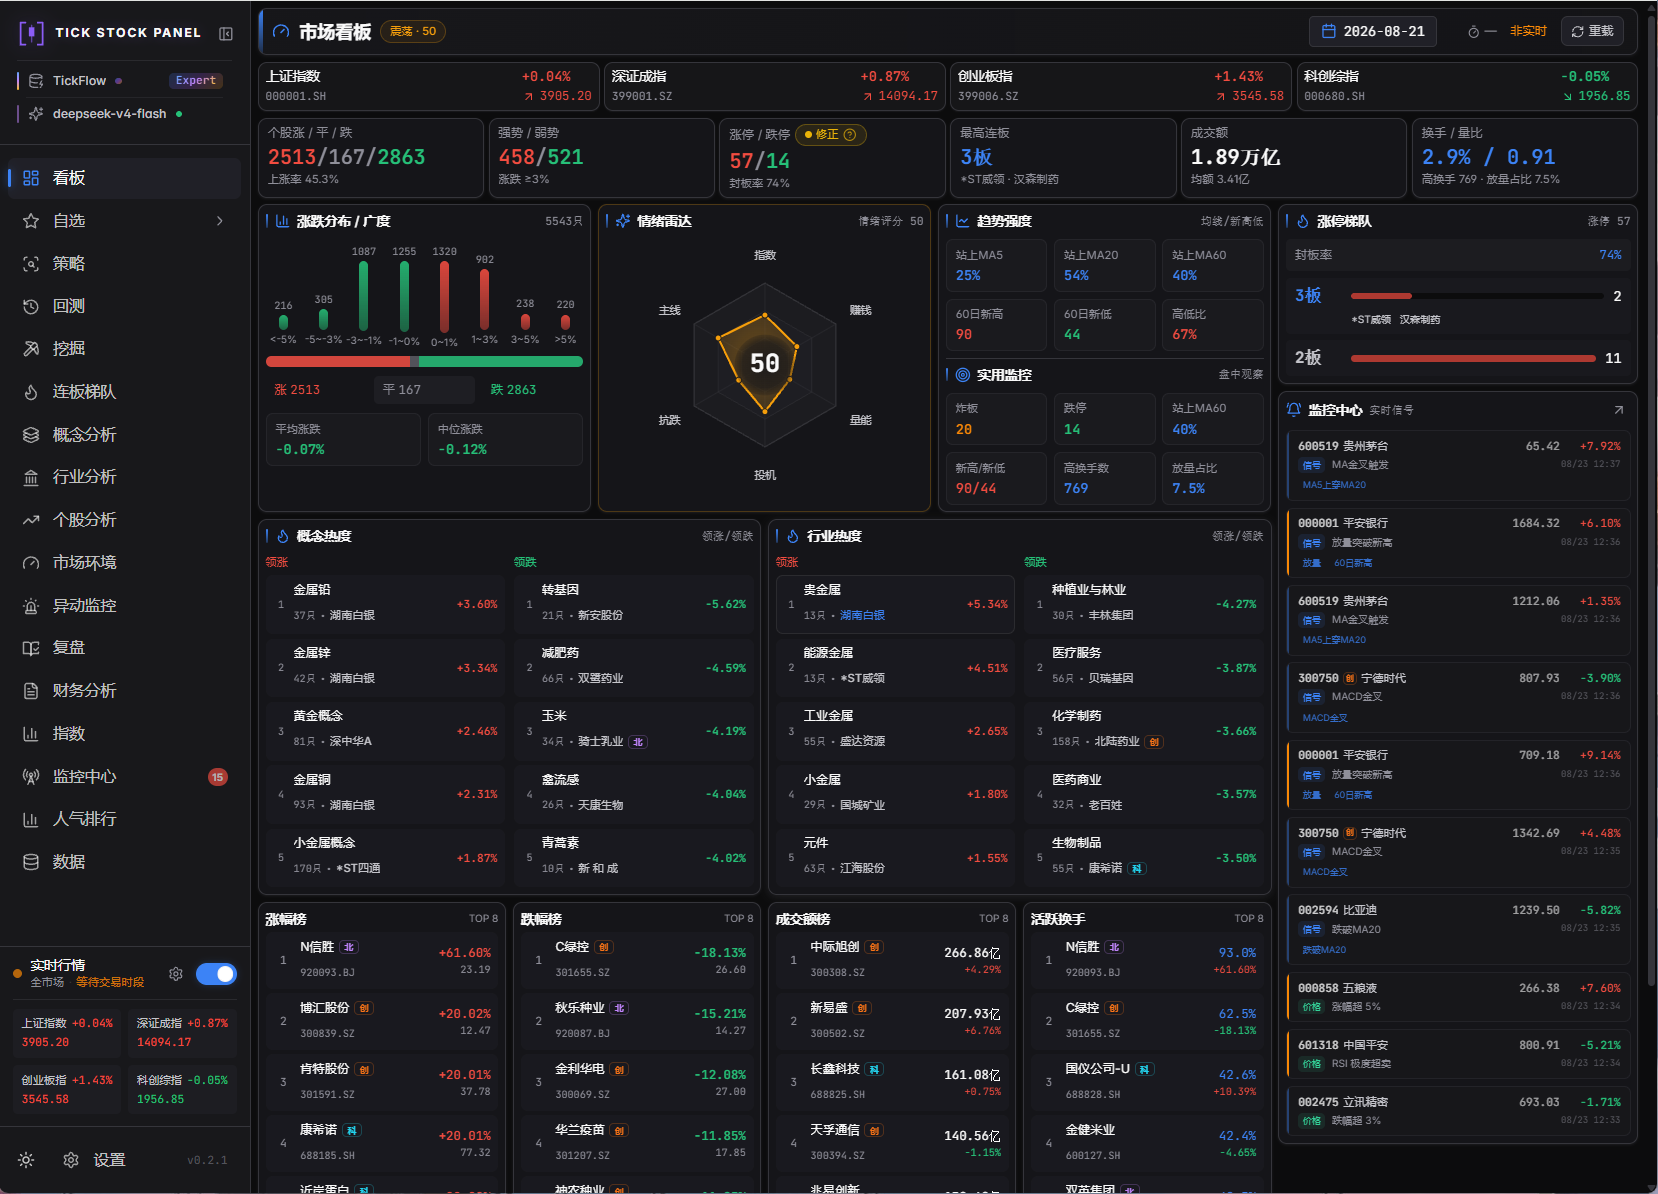 #3 · shy3130/tick-stock-panel
tick-stock-panel
TSP is a self-hosted, zero-ops quantitative trading workbench for China's A-share stock market that combines stock screening, real-time anomaly monitoring, and strategy backtesting, with optional LLM-assisted analysis.
- 4
Vibe-Research
3.4Ksimonlin1212/Vibe-Research · TypeScriptVibe-Research:A 股、美股、港股的投研工作台 · 自选与持仓、每日复盘、产业资讯、产业研究、个股深挖、回测、研报库,168 个数据端点。支持 Claude Code、Codex、WorkBuddy 订阅或任意模型 API。 | A research workbench for China A-shares, US and HK stocks.
- 5
CNEquity
890rootSunc/CNEquity · PythonCNEquity is local data infrastructure for the Chinese A-share market: it organizes stock quotes, futures, fundamentals, corporate events and capital-flow data from multiple sources into a local Parquet data lake with incremental collection, resumable failures, quality audits and unified querying.
Related topics
Often tagged together