Topics / #named-entity-recognition
Named-entity-recognition projects on GitHub
Extracting names, places and entities from text with NLP models.
As of , the most-starred Named-entity-recognition projects on GitHub are funNLP (83K stars), bert (40K stars) and HanLP (36.5K stars). GitHub.Locker tracks 12 Named-entity-recognition repositories with 294.8K stars combined. The fastest-growing on October 16 was funNLP, with +34 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +34
funNLP
fighting41love/funNLP · ★ 83KA huge curated collection of Chinese NLP resources: corpora, lexicons, tools, datasets and courses. The README calls it 'The Most Powerful NLP-Weapon Arsenal' — nearly the most complete Chinese NLP resource library.
 +17
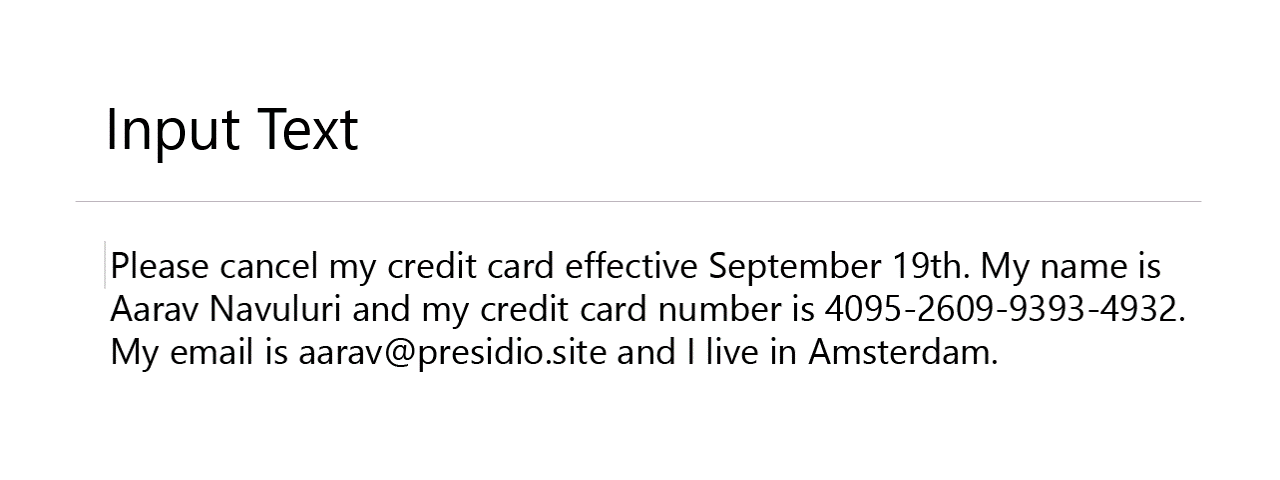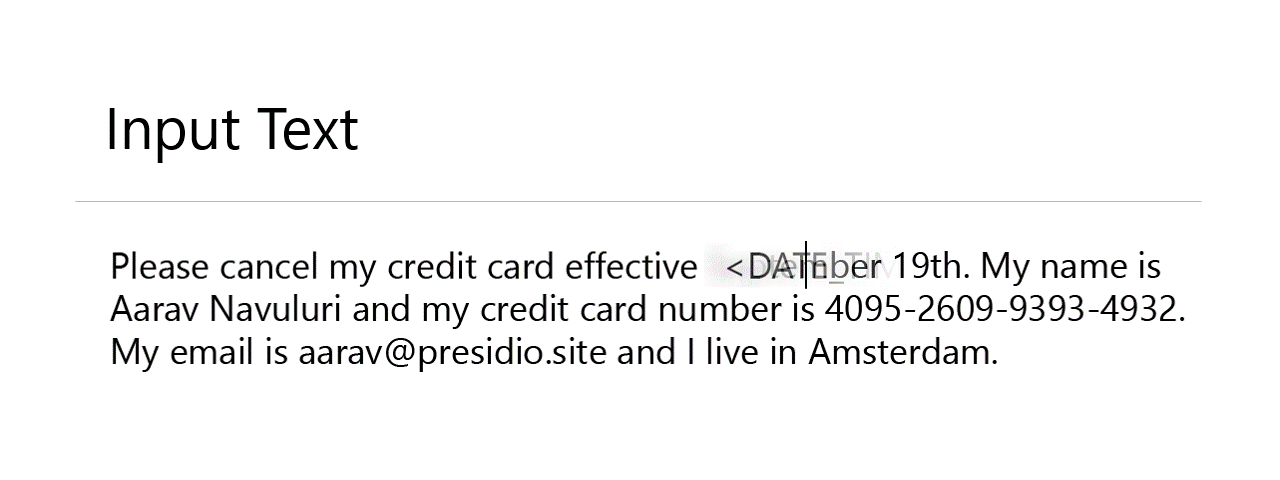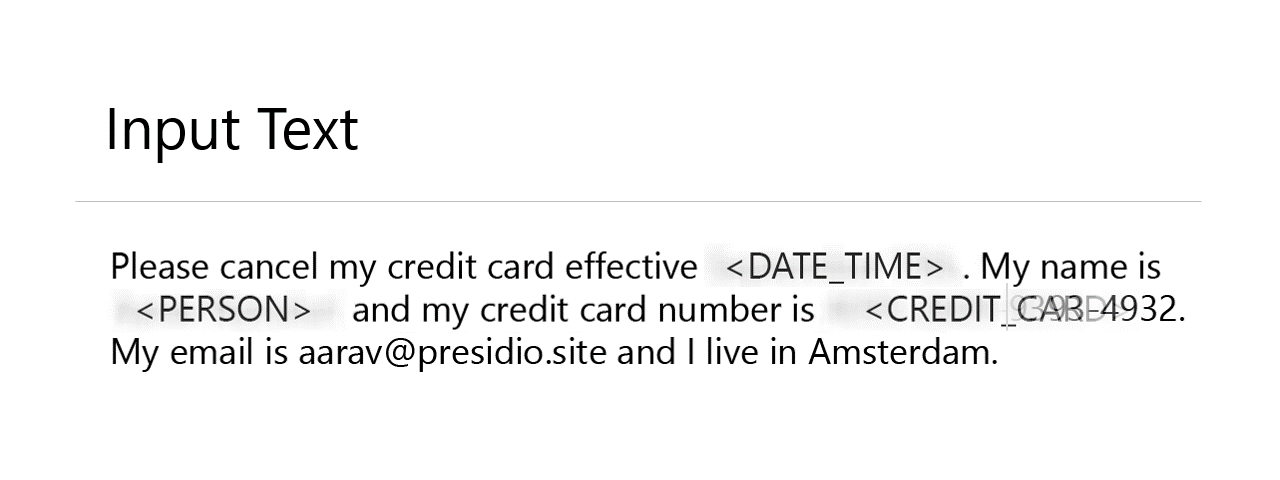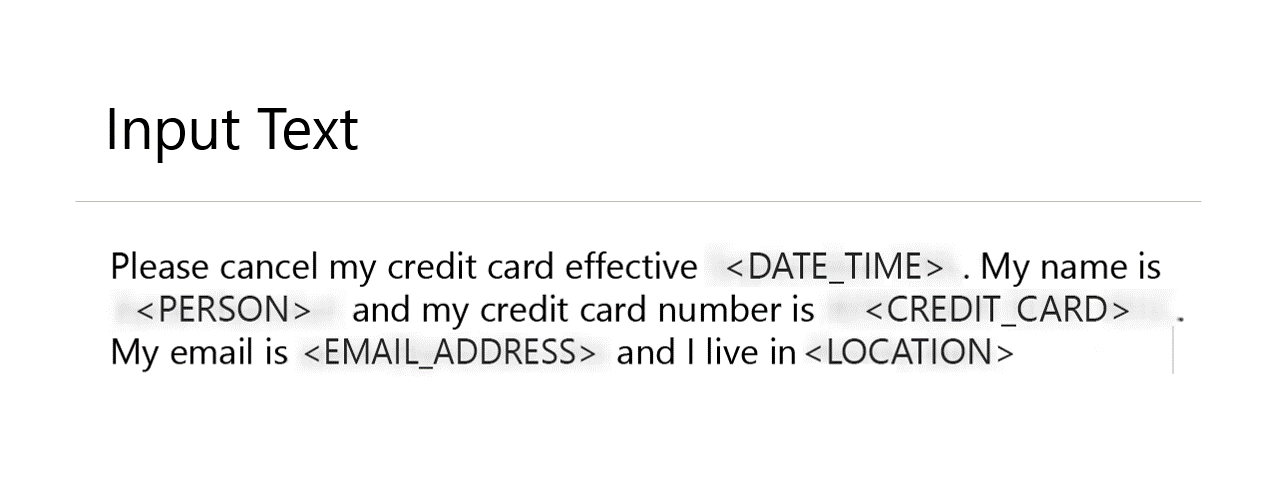
presidio
data-privacy-stack/presidio · ★ 11.4KAn open-source framework (SDK) that detects, redacts, masks and anonymizes sensitive data (PII) — names, credit card numbers, SSNs, phone numbers — in text, images and structured data.
 +3
HanLP
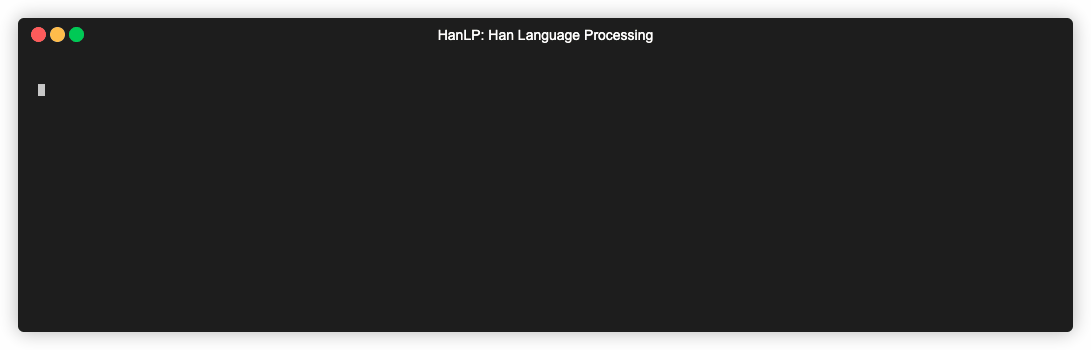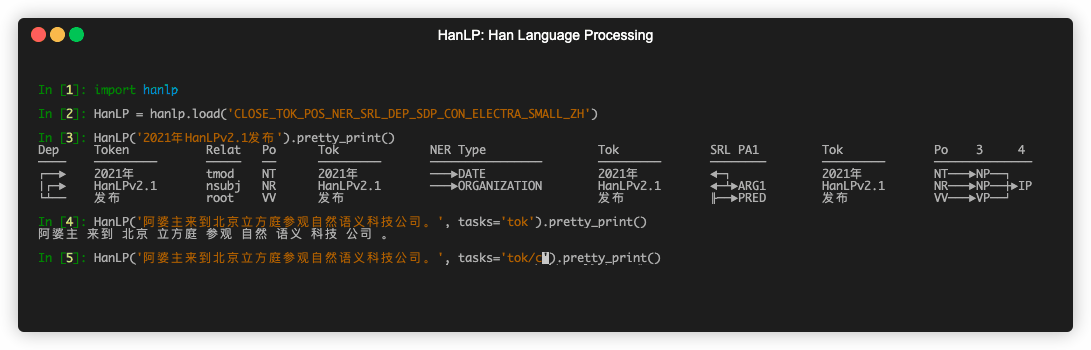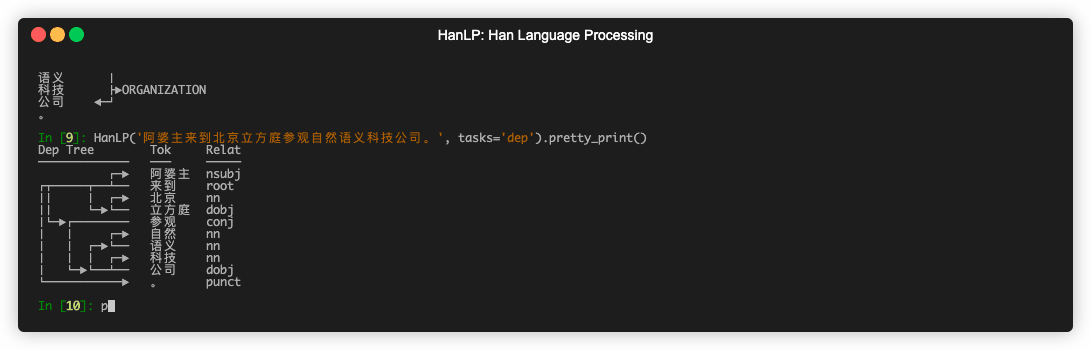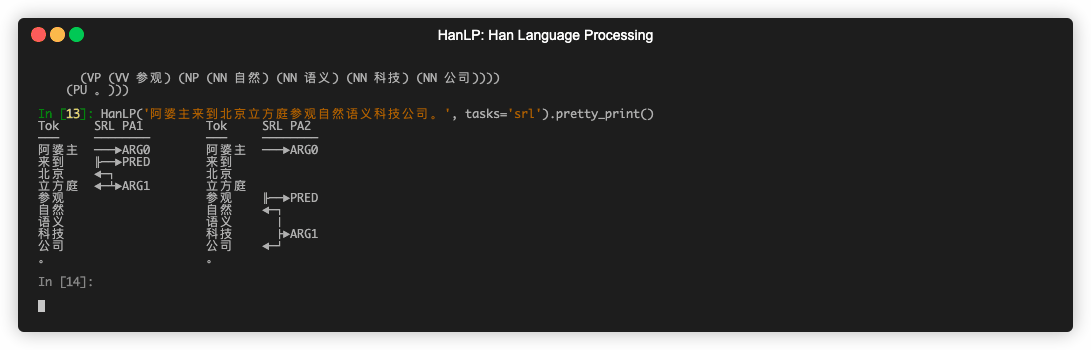
hankcs/HanLP · ★ 36.5KHanLP is a production-oriented, multilingual NLP toolkit built on dual PyTorch/TensorFlow 2.x engines, supporting 130 languages with ten joint tasks such as tokenization, POS tagging, NER, dependency and constituency parsing, semantic role labeling, and text classification.
 +3
awesome-nlp
keon/awesome-nlp · ★ 19.1KA curated list of resources dedicated to Natural Language Processing — research hubs, tutorials, courses, books, libraries, datasets, and task methods, collected as links with one-line descriptions.
The all-time top
12 projects · by stars
- 83K#1 · fighting41love/funNLP
funNLP
A huge curated collection of Chinese NLP resources: corpora, lexicons, tools, datasets and courses. The README calls it 'The Most Powerful NLP-Weapon Arsenal' — nearly the most complete Chinese NLP resource library.
- 40K
 #2 · google-research/bert
bert
Google's official TensorFlow implementation of BERT together with pre-trained checkpoints — a method for pre-training language representations that set state-of-the-art results on a wide range of NLP tasks, from SQuAD question answering to natural language inference.
- 36.5K#3 · hankcs/HanLP
HanLP
HanLP is a production-oriented, multilingual NLP toolkit built on dual PyTorch/TensorFlow 2.x engines, supporting 130 languages with ten joint tasks such as tokenization, POS tagging, NER, dependency and constituency parsing, semantic role labeling, and text classification.
- 4

spaCy
34Kexplosion/spaCy · PythonspaCy is a library for advanced Natural Language Processing in Python and Cython, designed from day one for real products. It ships pretrained pipelines and supports tokenization and training for 70+ languages.
- 5
NLP-progress
23Ksebastianruder/NLP-progress · PythonA curated, community-maintained document that tracks progress in Natural Language Processing: it lists the standard datasets and the current state-of-the-art results for most common NLP tasks across many languages.
- 6
awesome-nlp
19.1Kkeon/awesome-nlpA curated list of resources dedicated to Natural Language Processing — research hubs, tutorials, courses, books, libraries, datasets, and task methods, collected as links with one-line descriptions.
- 7
flair
14.4KflairNLP/flair · PythonFlair is a very simple framework for state-of-the-art natural language processing: a Python library for applying pre-trained NLP models to your text, developed by Humboldt University of Berlin and friends. The current release is version 0.15.1.
- 8
compromise
12.2Kspencermountain/compromise · JavaScriptCompromise is a lightweight JavaScript natural-language processing library that parses text into structured data: tokenizing words and sentences, tagging part-of-speech, and letting you query phrases like numbers, names, or dates.
- 9
presidio
11.4Kdata-privacy-stack/presidio · PythonAn open-source framework (SDK) that detects, redacts, masks and anonymizes sensitive data (PII) — names, credit card numbers, SSNs, phone numbers — in text, images and structured data.
- 10
doccano
10.8Kdoccano/doccano · PythonDoccano is an open-source text annotation tool that lets humans label data for machine learning tasks like text classification, sequence labeling, and sequence-to-sequence problems such as summarization or translation.
- 11

CoreNLP
10.1Kstanfordnlp/CoreNLP · JavaA Java suite of core NLP tools that takes raw human language text and returns linguistic analysis: tokenization, parts of speech, named entities, parsing, coreference, and sentiment.
- 12

privacy-preserving-control-plane
425gbenletoluwase/privacy-preserving-control-plane · JavaA Java control plane that bundles four coupled mechanisms for production ML pipelines: forecast-driven autoscaling, zero-shot PII redaction at the point of processing, governed model promotion, and drift/anomaly detection.
Related topics
Often tagged together
- nlp214
- machine-learning916
- natural-language-processing96
- python2,383
- deep-learning737
- library1,587
- mit3,312
- multilingual214
- open-source5,666
- research764
- sentiment-analysis16
- data-science231
- artificial-intelligence267
- cross-platform2,623
- dataset124
- embeddings135
- nlp-library7
- question-answering16
- text-classification12
- academic-research209
- ai1,955
- awesome-list495
- chinese1,159
- curated-list634