Topics / #comfyui
Comfyui projects on GitHub
Node-based interface for building image and video generation workflows with diffusion models.
As of , the most-starred Comfyui projects on GitHub are ComfyUI (137.9K stars), Pixelle-Video (29.1K stars) and Wan2.2 (18K stars). GitHub.Locker tracks 50 Comfyui repositories with 386.5K stars combined. The fastest-growing on October 16 was qwen21-nsfw-pose-skill, with +350 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +350
qwen21-nsfw-pose-skill
Arekejoker/qwen21-nsfw-pose-skill · ★ 2.5KA local recipe (agent skill) for generating NSFW and pose-controlled images with Qwen-Image 2.1, combining an author-level prompt formula, a mandatory NSFW LoRA, and a 136-pose 3D doll library for precise pose control.
ComfyUI
Comfy-Org/ComfyUI · ★ 137.9KComfyUI is a node-based graph interface for building and running diffusion model workflows: image, video, 3D, and audio generation, editing, and more, all without writing code.
 +151
universal-modder
rehan-remade/universal-modder · ★ 8.1KUniversal Modder gives Claude Code (and other AI coding agents) a set of Agent Skills, a CLI called 'um', and a fal MCP server so the agent can find, reverse-engineer, and mod almost any PC game you own, then generate art, 3D, audio, test the mod in-game, and record a showcase video.
 +45
YuE
multimodal-art-projection/YuE · ★ 12.1KYuE2 is an open-source music generation model: lyrics plus a style prompt become an editable melody-and-chord plan, then a complete song with vocals and accompaniment. It also does zero-shot covers and agent-driven editing.
The all-time top
50 projects · by stars
- 137.9K
#1 · Comfy-Org/ComfyUI
ComfyUI
ComfyUI is a node-based graph interface for building and running diffusion model workflows: image, video, 3D, and audio generation, editing, and more, all without writing code.
- 29.1K
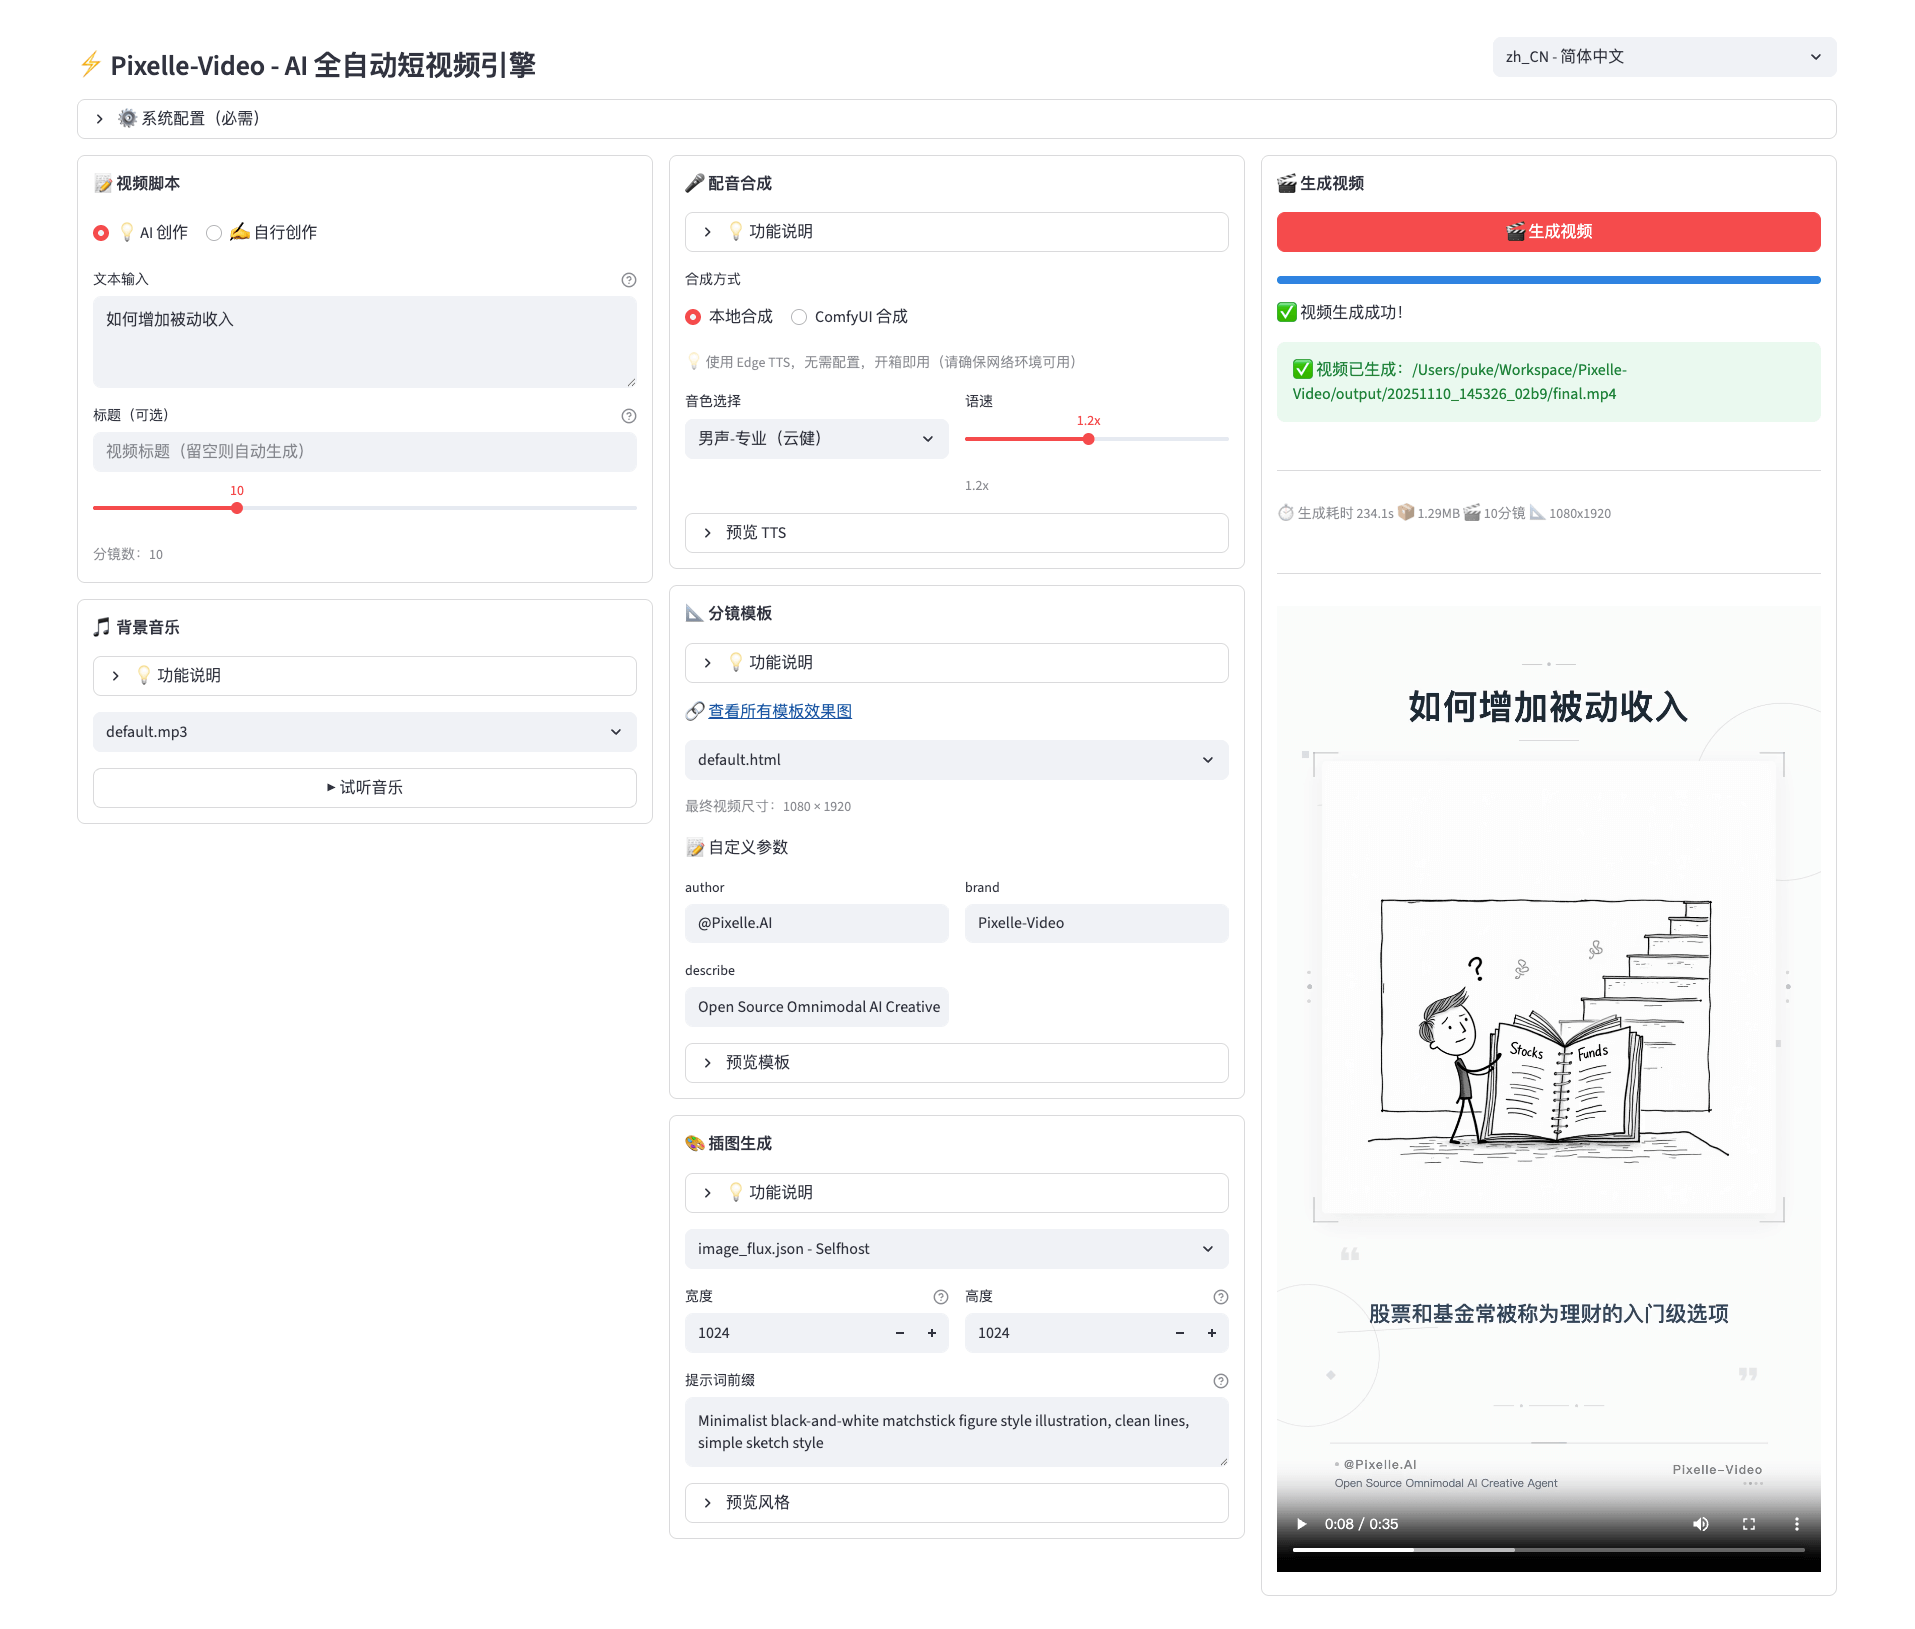 #2 · ATH-MaaS/Pixelle-Video
Pixelle-Video
Pixelle-Video is an open-source AI short-video engine: give it one topic and it automatically writes the script, generates AI images or video clips, synthesizes the voiceover, adds background music and assembles a finished video — no editing experience needed.
- 18K
 #3 · Wan-Video/Wan2.2
Wan2.2
An open-source family of large-scale video generation models: text-to-video, image-to-video, speech-to-video and character animation, with inference code and model weights released under Apache-2.0.
- 4
Wan2.1
17.2KWan-Video/Wan2.1 · PythonWan2.1 is an open suite of large-scale video generative models: it turns text or images into videos, and also covers video editing, text-to-image and video-to-audio tasks.
- 5
DiffSynth-Studio
13.3Kmodelscope/DiffSynth-Studio · PythonDiffSynth-Studio is an open-source Diffusion model engine built and maintained by the ModelScope Community, covering image, video, and audio generation plus image quality metrics, with support for both inference and training.
- 6
HunyuanVideo
12.6KTencent-Hunyuan/HunyuanVideo · PythonHunyuanVideo is Tencent's open-source video foundation model, a 13B+ parameter diffusion transformer that generates videos from text (and images) at quality the authors claim matches or beats closed-source competitors like Runway Gen-3 and Luma 1.6.
- 7

AnimateDiff
12.3Kguoyww/AnimateDiff · PythonAnimateDiff is the official implementation of a research method that turns personalized text-to-image Stable Diffusion models into animation (text-to-video) generators without any extra fine-tuning of those models.
- 8
YuE
12.1Kmultimodal-art-projection/YuE · PythonYuE2 is an open-source music generation model: lyrics plus a style prompt become an editable melody-and-chord plan, then a complete song with vocals and accompaniment. It also does zero-shot covers and agent-driven editing.
- 9
InstantID
12KinstantX-research/InstantID · PythonInstantID is a tuning-free method for identity-preserving image generation: a single reference photo of a face plus a text prompt is enough to create new images that keep the person's likeness, in seconds.
- 10

awesome-ai-painting
11.8Khua1995116/awesome-ai-paintingA curated Chinese-language collection of AI painting resources: platforms you can use today, tutorials, parameter and deployment guides, model lists and industry news, centered on Stable Diffusion and similar models.
- 11

LTX-Video
11.1KLightricks/LTX-Video · PythonLTX-Video is the official repo for Lightricks' DiT-based video generation model, which generates synchronized audio+video, supports text-to-video and image-to-video, keyframe conditioning, video extension, and video-to-video transformations.
- 12
PhotoMaker
10.1KTencentARC/PhotoMaker · Jupyter NotebookPhotoMaker is an AI tool from Tencent ARC (CVPR 2024) that generates new images of a specific person: you feed in a few reference photos of the face plus a text prompt, and it renders that identity in new scenes, poses, or styles.
- 13
LTX-2
9.8KLightricks/LTX-2 · PythonThe official Python package for LTX-2, Lightricks' audio-video foundation model: one DiT-based model that generates video with synchronized audio from text or an image, in several quality/speed modes.
- 14
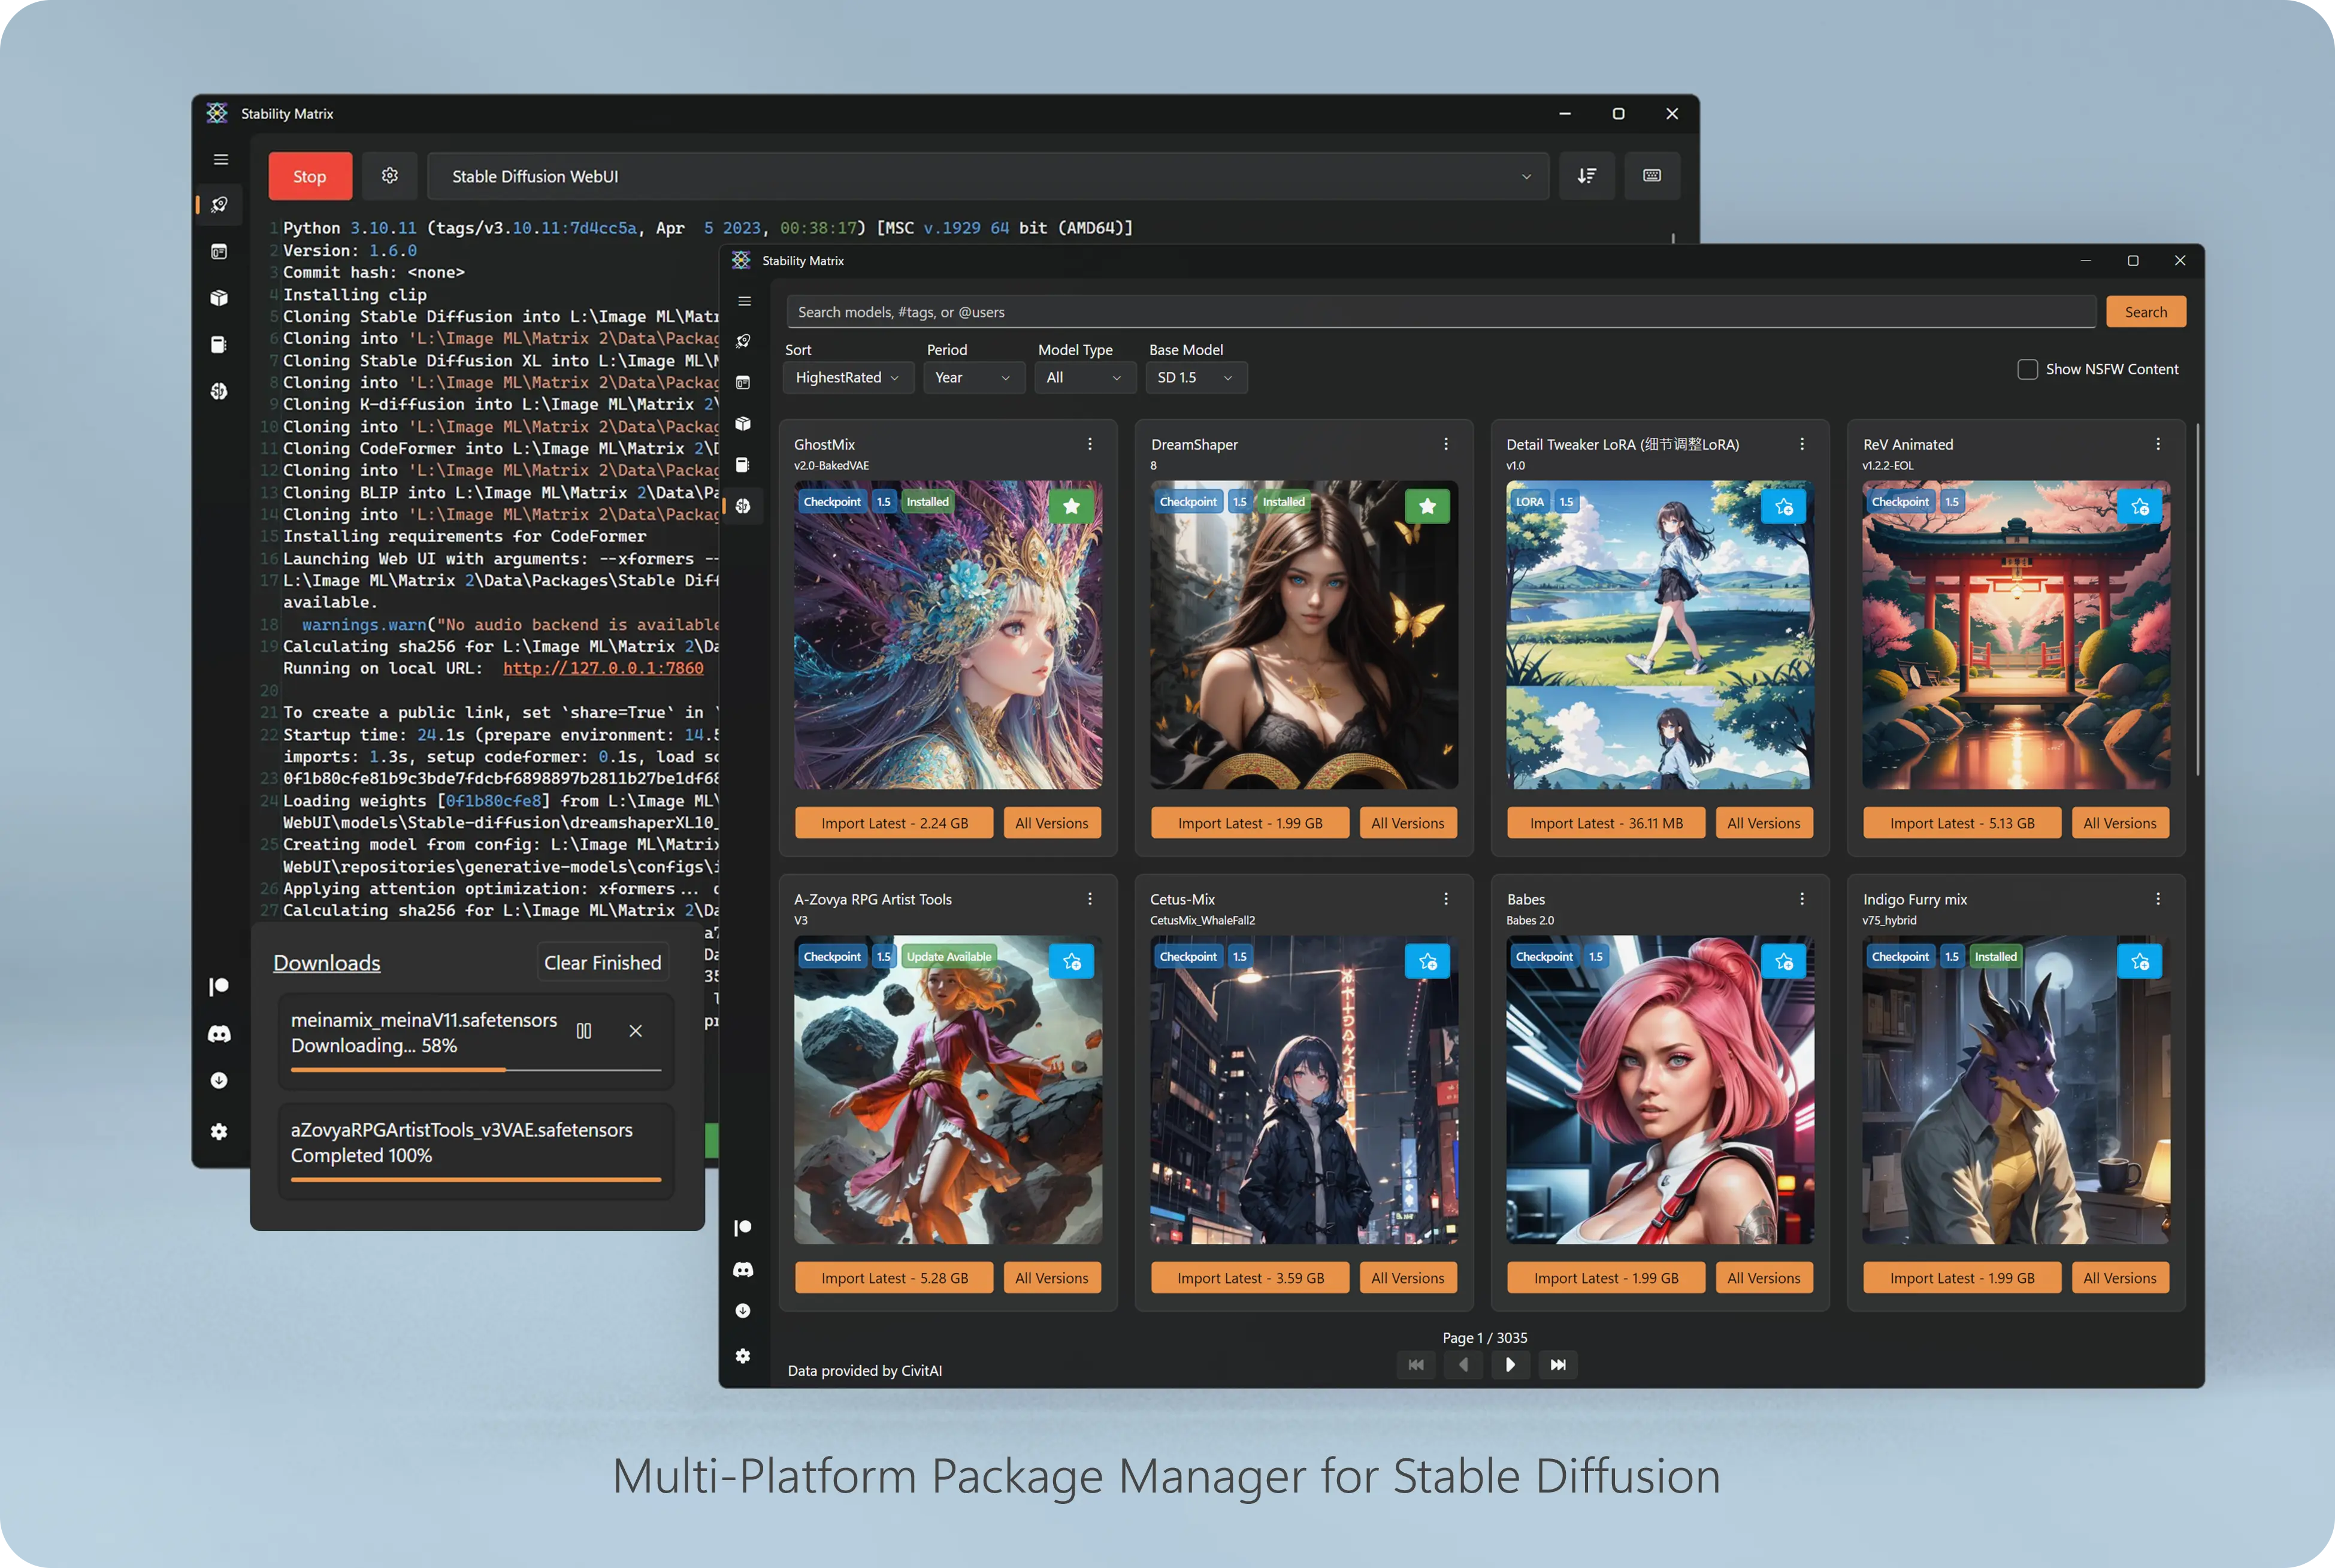
StabilityMatrix
8.9KLykosAI/StabilityMatrix · C#Stability Matrix is a multi-platform package manager and inference UI for Stable Diffusion, letting you install, update, and launch tools like Automatic1111, ComfyUI, Forge, Fooocus, InvokeAI, SwarmUI and others with one click.
- 15
universal-modder
8.1Krehan-remade/universal-modder · PythonUniversal Modder gives Claude Code (and other AI coding agents) a set of Agent Skills, a CLI called 'um', and a fal MCP server so the agent can find, reverse-engineer, and mod almost any PC game you own, then generate art, 3D, audio, test the mod in-game, and record a showcase video.
- 16
ODS
7.6KOsmantic/ODS · PythonODS (Osmantic Deployment System) turns your PC, Mac, or Linux box into a private AI server by installing and wiring together local LLM inference, a chat UI, agents, voice, RAG, image generation, and privacy tools in one go.
- 17
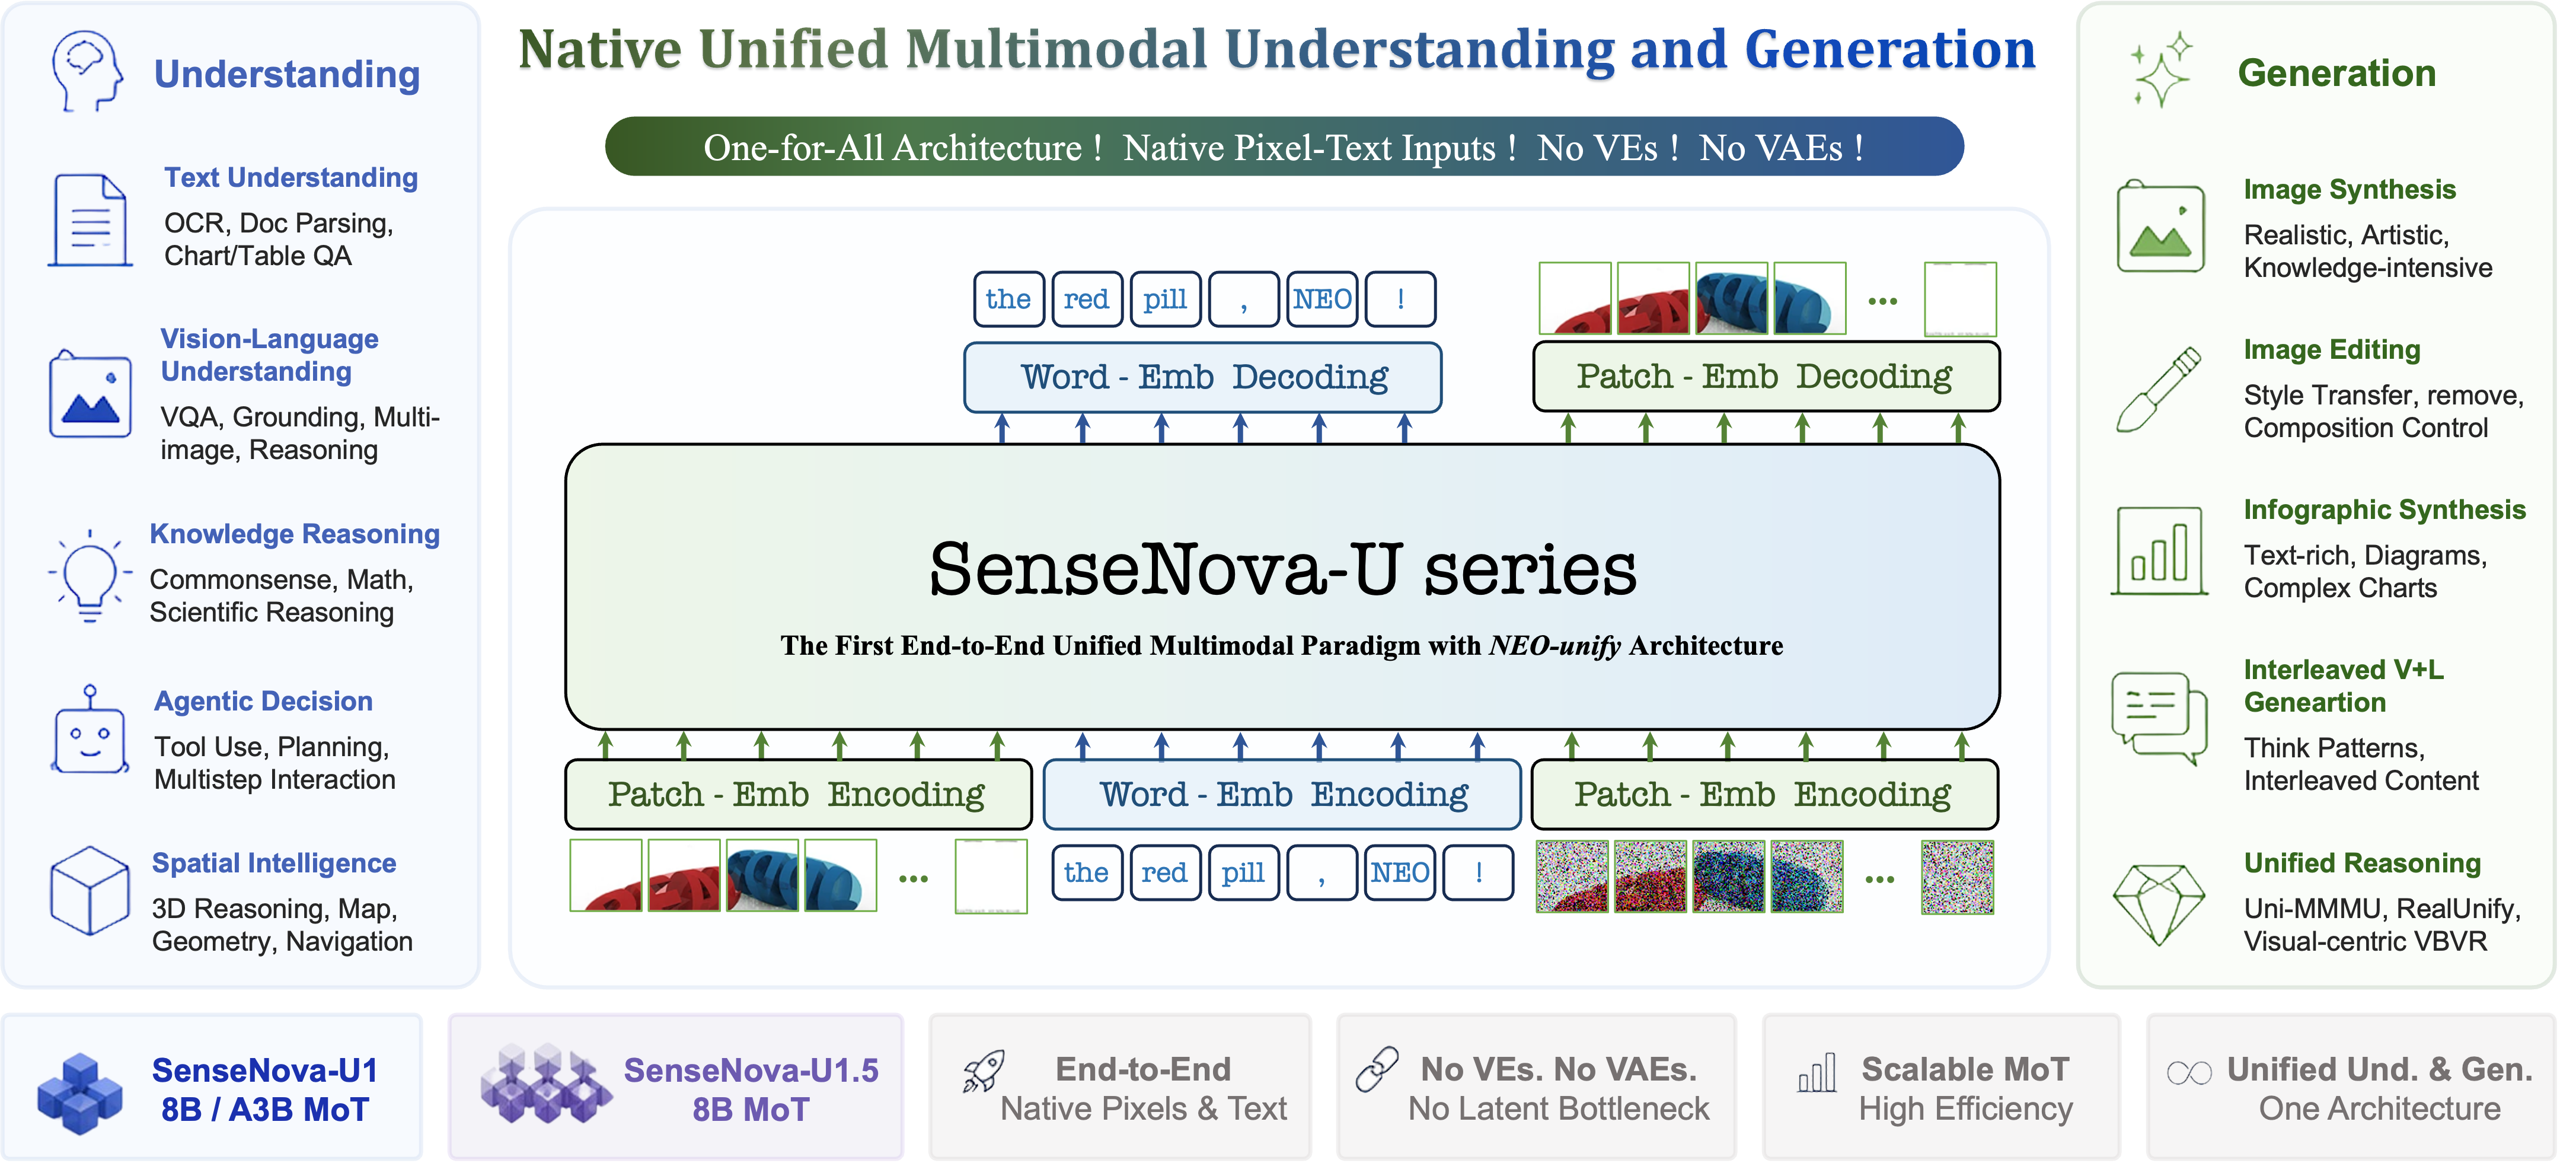
SenseNova-U1
6.9KOpenSenseNova/SenseNova-U1 · PythonOpen-source multimodal models that unify image understanding, reasoning and image generation in one architecture. The current release, SenseNova-U1.5-8B-MoT, creates and edits images up to native 4K.
- 18
remove-ai-watermarks
6Kwiltodelta/remove-ai-watermarks · PythonA Python library and CLI that removes visible and invisible AI watermarks and provenance metadata (SynthID, C2PA, EXIF, IPTC, XMP, and vendor marks like Gemini's sparkle) from images and videos you generated yourself.
- 19

LuxTTS
5.5Kysharma3501/LuxTTS · PythonLuxTTS is a lightweight text-to-speech model built on the ZipVoice architecture, designed for high-quality voice cloning and fast speech generation.
- 20
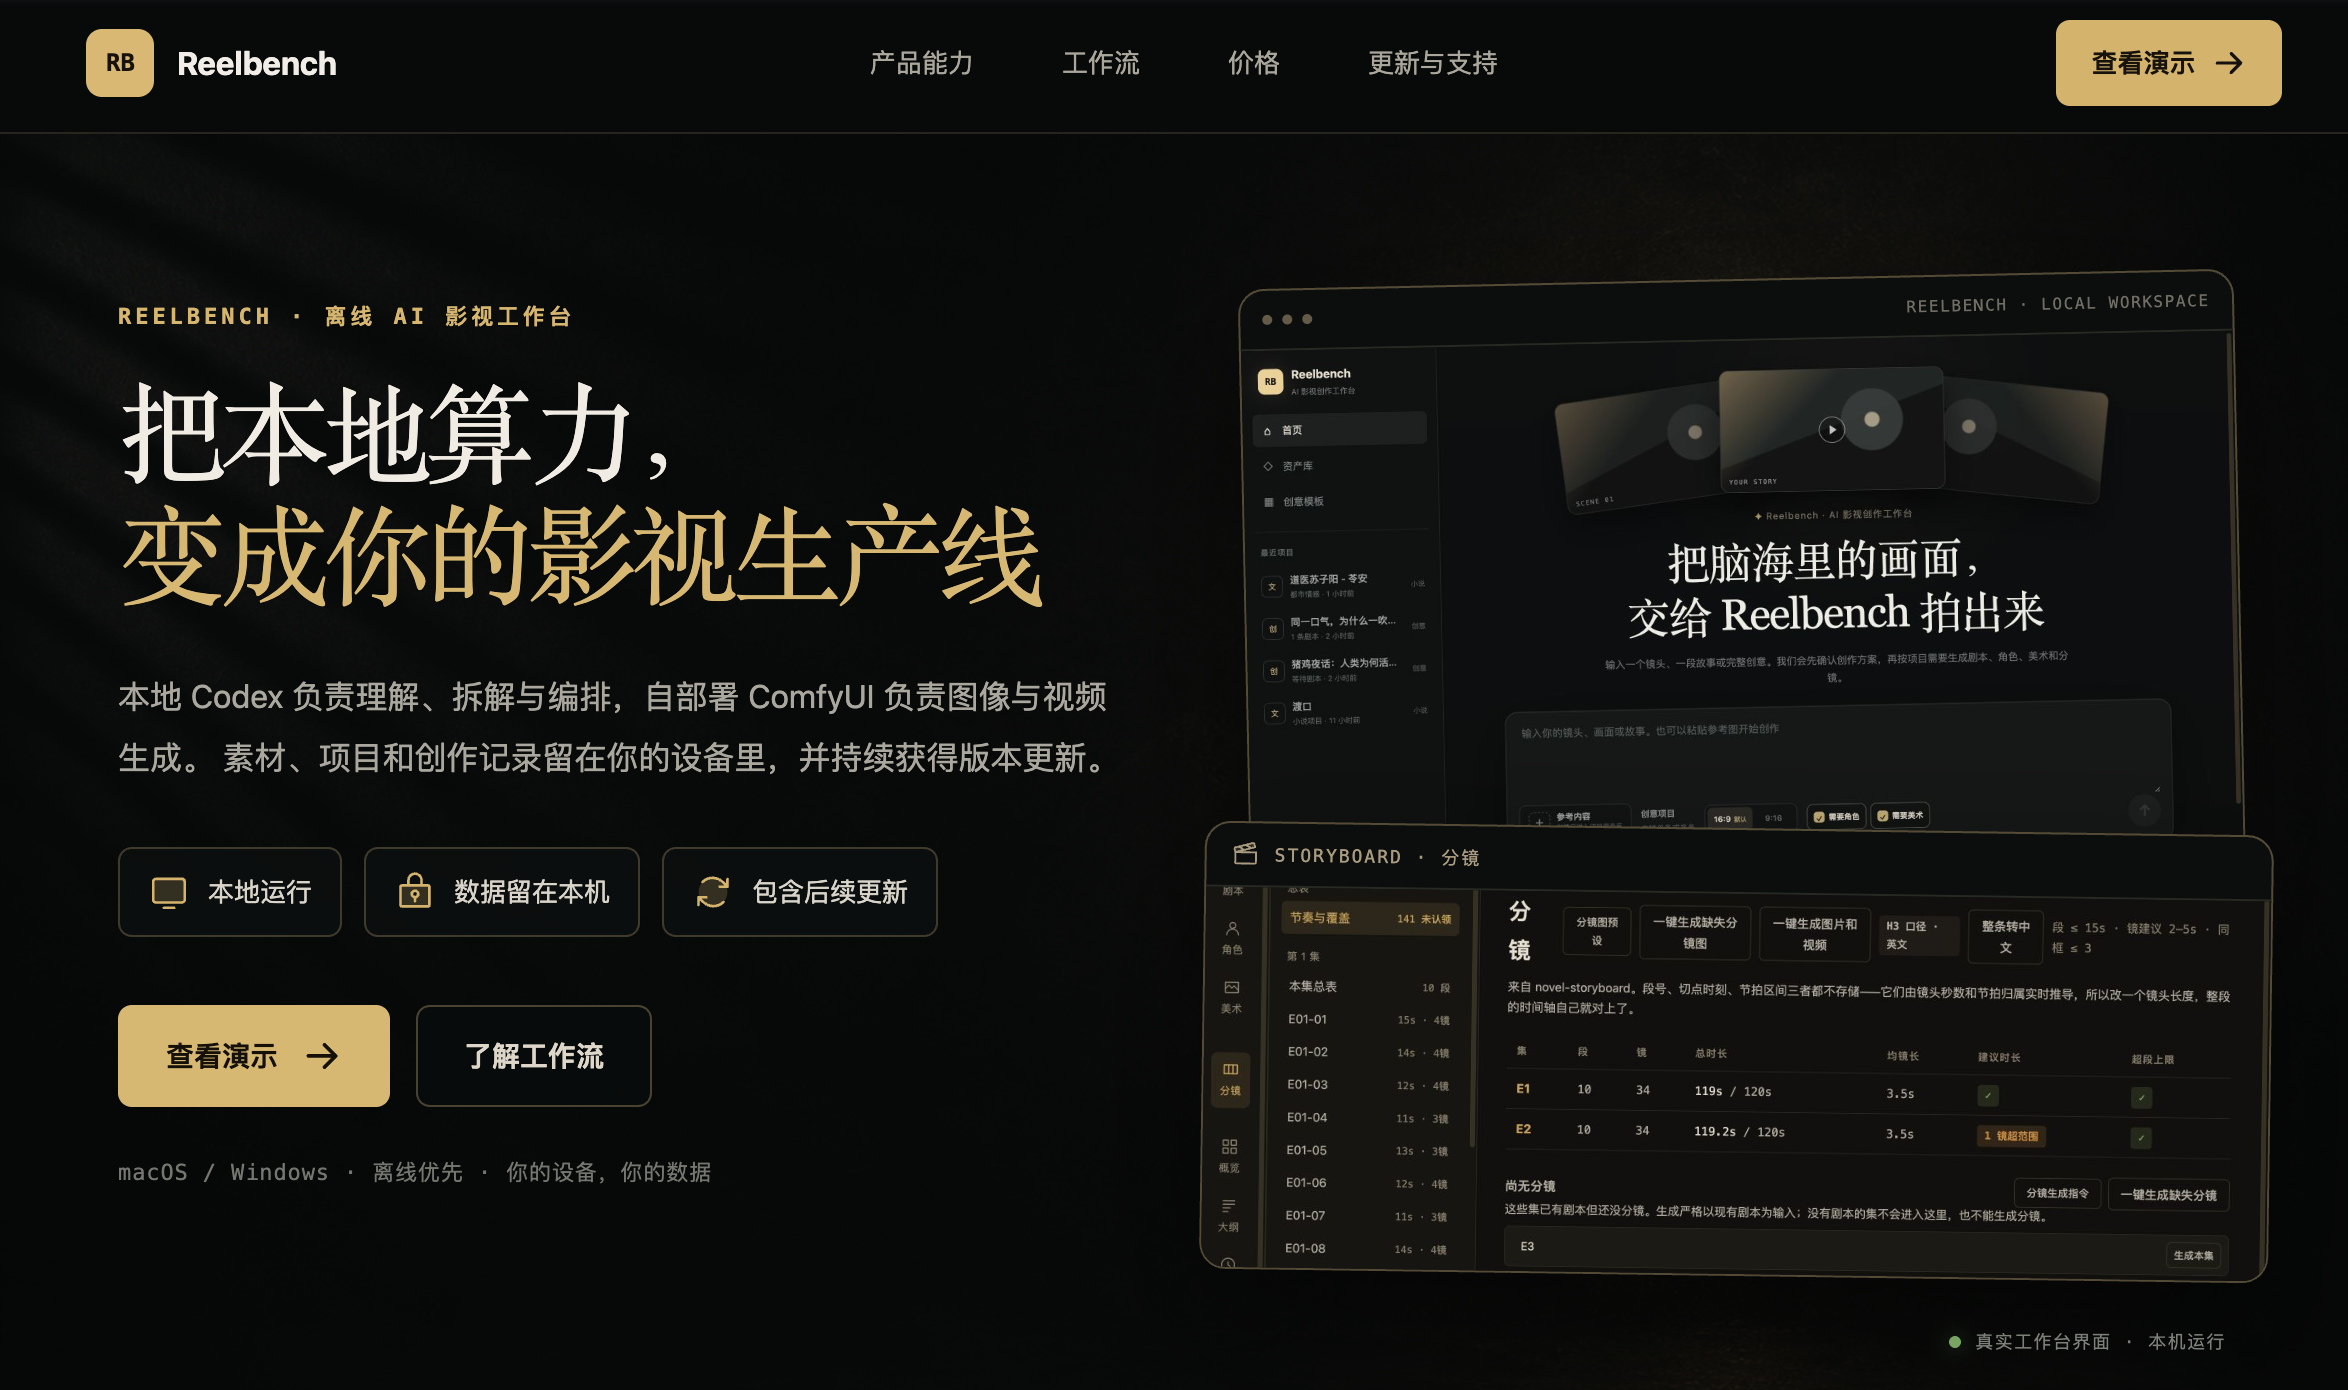
shuohao-skills
4.7Keternityspring/shuohao-skills · JavaScriptA collection of agent skills for producing AI short dramas from a novel: it breaks the novel into characters, builds an adaptation outline, generates art/prop bibles, writes the screenplay, and cuts the storyboard. It runs inside Claude Code or codex as a coding agent.
- 21

see-through
4.7Kshitagaki-lab/see-through · PythonIt is the open-source code for a SIGGRAPH 2026 paper: a framework that turns a single static anime illustration into a manipulatable 2.5D model by decomposing it into fully inpainted, semantically distinct layers with inferred drawing order.
- 22

HunyuanVideo-1.5
4.6KTencent-Hunyuan/HunyuanVideo-1.5 · PythonHunyuanVideo-1.5 is a video generation model from Tencent that creates text-to-video and image-to-video clips, achieving top-tier quality with only 8.3B parameters so it runs on consumer-grade GPUs.
- 23

PersonaLive
4KGVCLab/PersonaLive · PythonPersonaLive is a real-time, streamable diffusion framework that animates a single portrait image into an infinite-length talking video, designed for live-streaming use cases. It was accepted to CVPR 2026.
- 24

Stable-Diffusion
2.8KFurkanGozukara/Stable-Diffusion · Jupyter NotebookA huge, continuously updated collection of tutorial videos by Dr. Furkan Gozukara covering Stable Diffusion, SDXL, FLUX, SD3, LoRA training, DreamBooth, ControlNet, deepfakes, TTS, animation and more, with links to full YouTube walkthroughs for each topic.
- 25
qwen21-nsfw-pose-skill
2.5KArekejoker/qwen21-nsfw-pose-skill · PythonA local recipe (agent skill) for generating NSFW and pose-controlled images with Qwen-Image 2.1, combining an author-level prompt formula, a mandatory NSFW LoRA, and a 136-pose 3D doll library for precise pose control.
- 26
locally-uncensored
2.3KPurpleDoubleD/locally-uncensored · TypeScriptThis is an all-in-one local AI studio for your desktop that bundles chat, image and video generation, and a coding agent into a single free, open-source app for Windows and Linux.
- 27
FreeVideo
2KFlashML-org/FreeVideo · PythonFreeVideo is a local inference engine that lets you run the MiniMax H3 video generation model on your own consumer GPU instead of a cloud service, adapting its memory and compute strategy to your hardware.
- 28

AuK
1.5KTencent-Hunyuan/AuK · PythonAn open-source 1.5B-parameter foundation model from Tencent Hunyuan for speech generation and editing: zero-shot and instruct TTS, speech editing, enhancement, and source separation — all driven through one natural-language instruction interface.
- 29
ComfyUI-MiniMaxH3-TimelineDirector
647Songssx/ComfyUI-MiniMaxH3-TimelineDirector · PythonIt's an editable reference-media timeline UI for ComfyUI's native MiniMax H3 Reference-to-Video workflow, letting you arrange reference videos, images, audio, and Guides on one timeline to drive text-to-video, character replacement, motion transfer, digital humans, and long-form video generation.
- 30
mortiflix-oss
639GTKottman/mortiflix-oss · JavaScriptMortiflix is a self-hosted motion design studio where Claude makes a video step by step - brief, script, style frames, transition board, animatic, final - and you review and approve each stage before the next one starts.
- 31
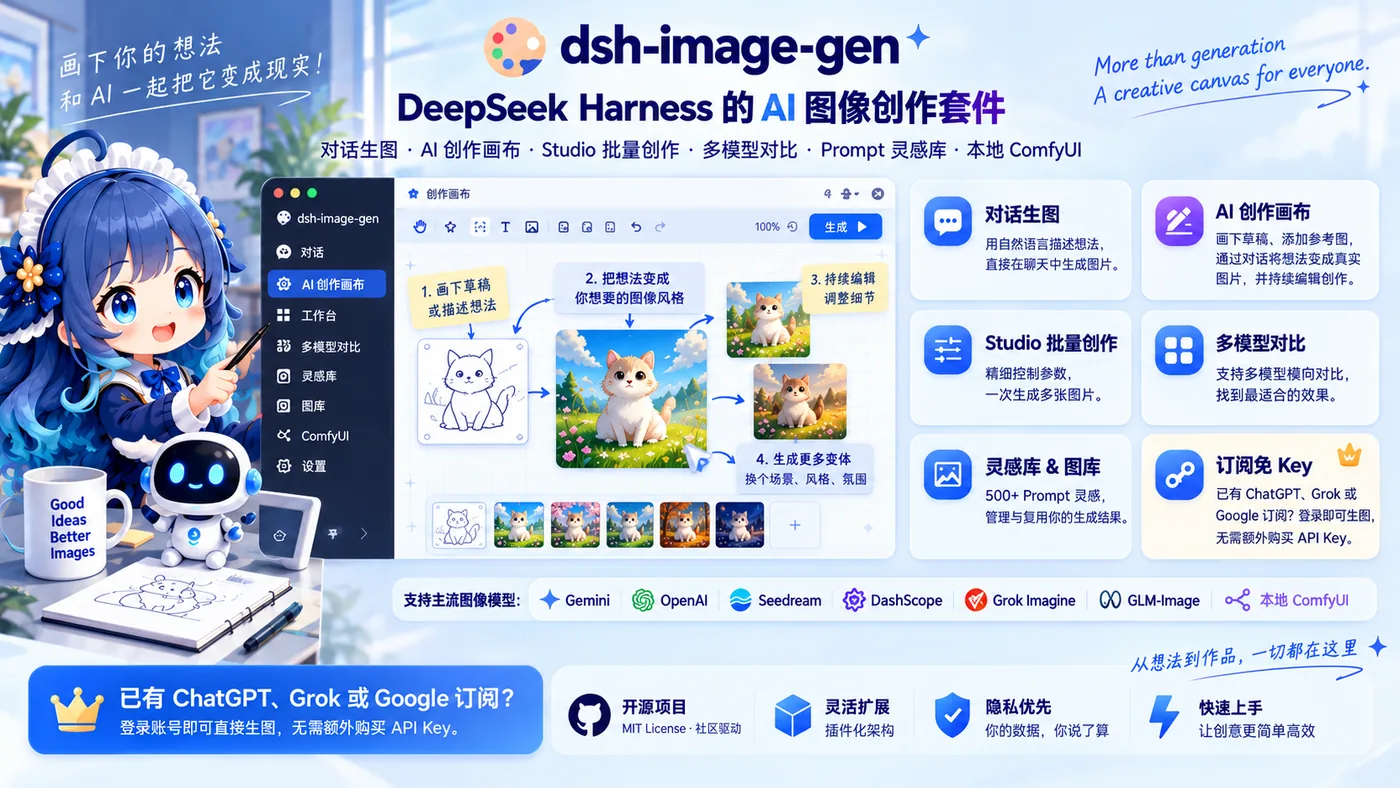
dsh-image-gen
619shanliuling/dsh-image-gen · TypeScriptdsh-image-gen is the native AI image creation plugin for DeepSeek Harness (DSH). It brings chat-based image generation and editing, a batch Studio, multi-model comparison, a library of 500+ prompts, a gallery manager, and local ComfyUI workflows directly into DSH conversations.
- 32
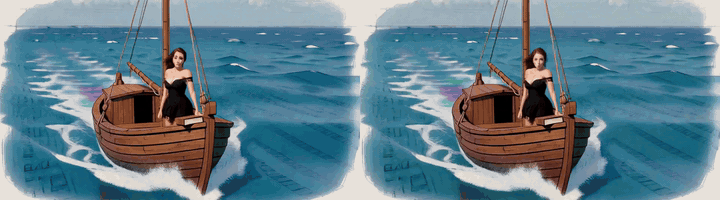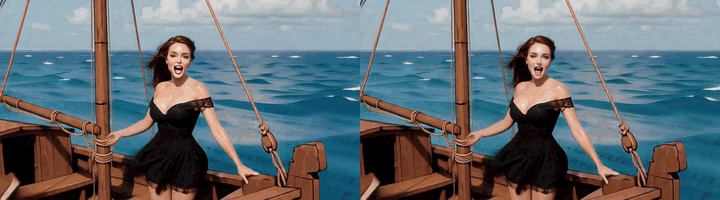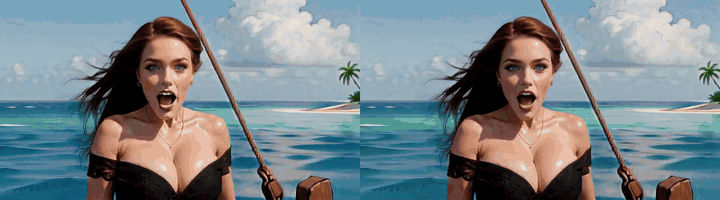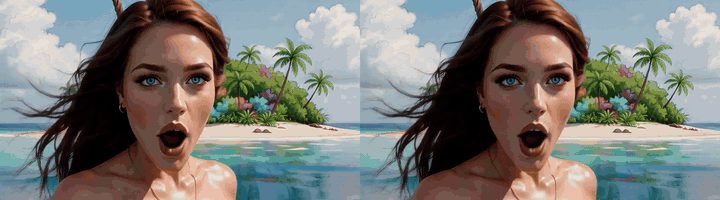
ComfyUI-H3-FaceRefine
516Carasibana/ComfyUI-H3-FaceRefine · PythonThis is a ComfyUI custom node pack that fixes small, blurry faces in MiniMax H3 generated video by tracking each face per frame, cropping it to fill a canvas, letting H3 re-render the crop in detail, and compositing the refined face back into the original video.
- 33
h3lite
459Rimagination/h3lite · PythonH3 Lite is a Codex/WorkBuddy AI agent skill that drives local MiniMax H3 video generation through ComfyUI, picking a hardware-aware route and producing videos with native audio from a description.
- 34
awesome-minimax-h3-integration
442MiniMax-AI/awesome-minimax-h3-integrationA community-maintained index of checkpoints, tools, and workflows for MiniMax H3, a video generation model that produces clips with native stereo audio from text, image, video, and audio inputs.
- 35

ComfyUI-MiniMaxH3Mod
441Luisacaotica/ComfyUI-MiniMaxH3Mod · PythonA ComfyUI custom node pack that adds 'RefMod' reference adapters for the MiniMax H3 model. It compresses reference images, videos or audio into small reusable .safetensors files that can be loaded and applied to influence generation without any training of the H3 model.
- 36
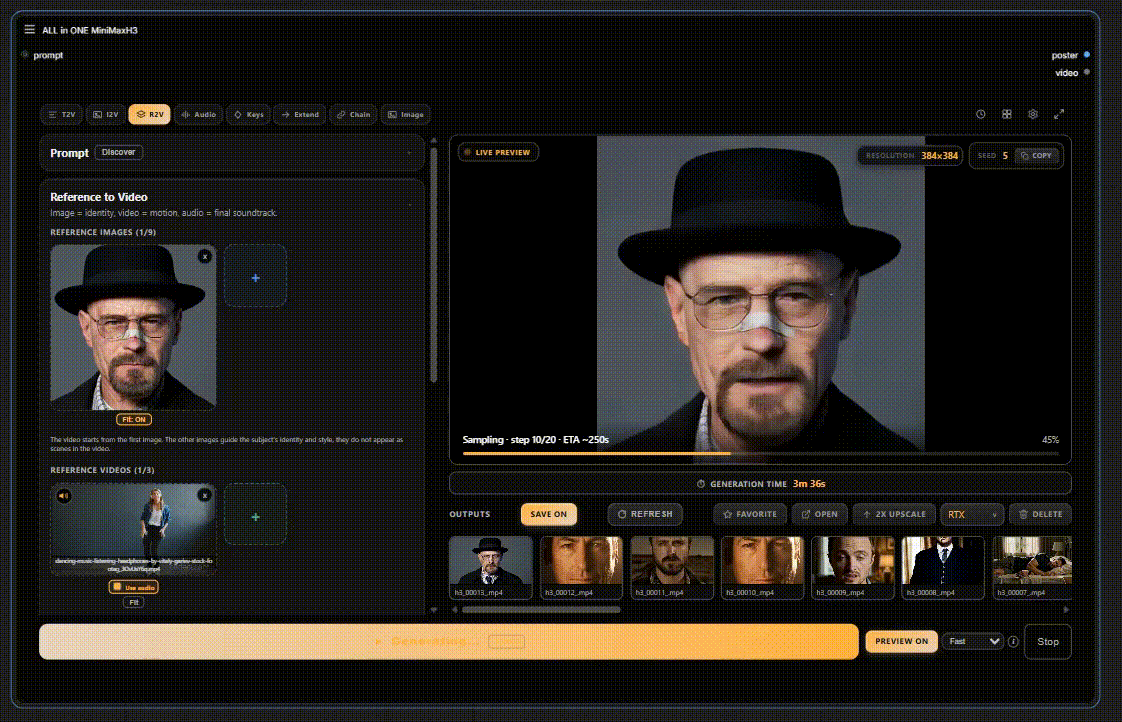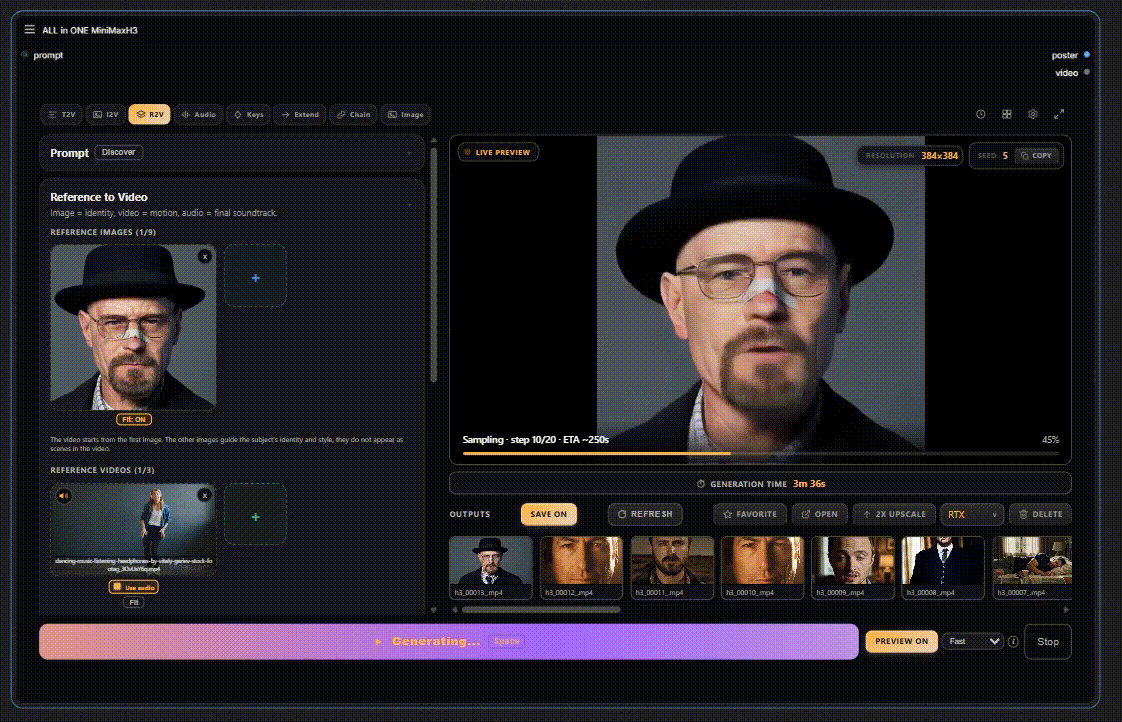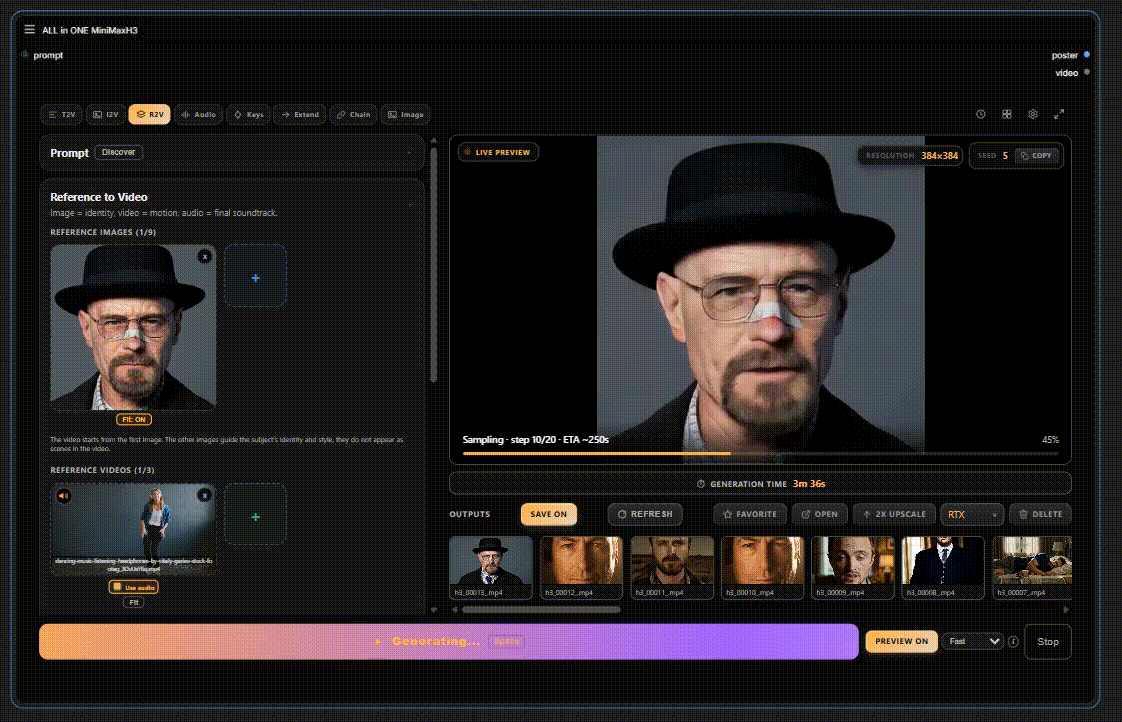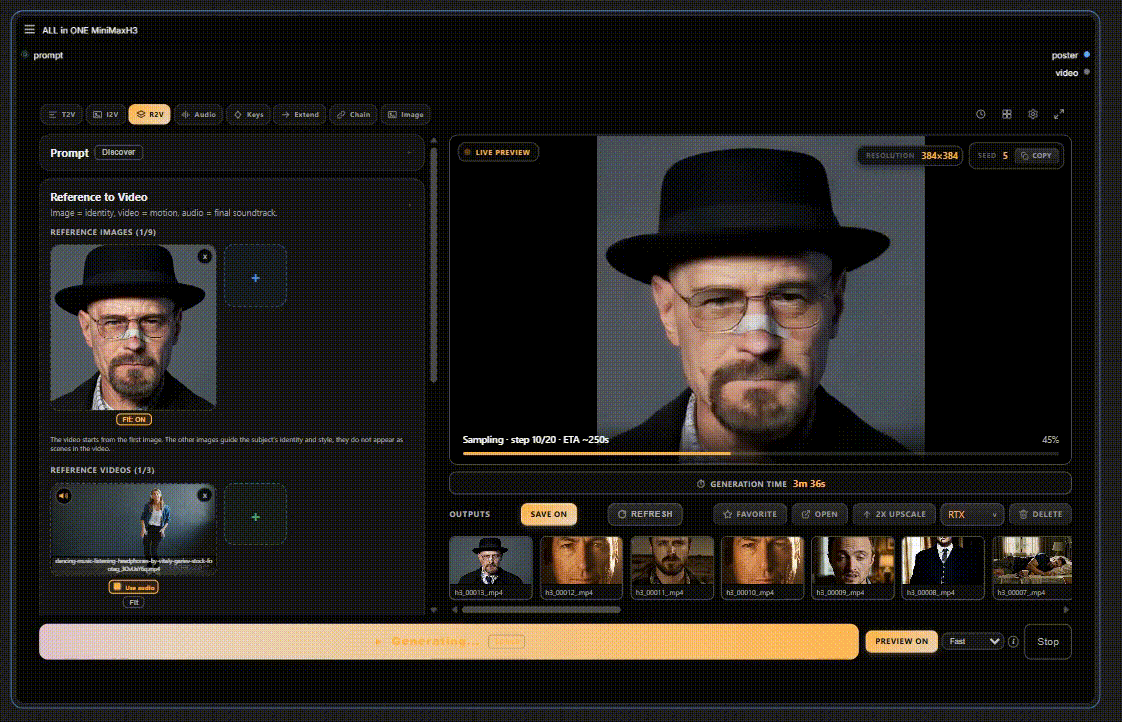
ComfyUI-ALLinONE-MinimaxH3
353LeonQ8/ComfyUI-ALLinONE-MinimaxH3 · JavaScriptA single custom node for ComfyUI that packs the whole MiniMax H3 video pipeline into one node — pick a mode, drop in your prompt or references, and hit Generate.
- 37
ComfyUI_MiniMax_H3_Extender
338tritant/ComfyUI_MiniMax_H3_Extender · PythonIt's a ComfyUI custom node for the MiniMax H3 video model: it chains multiple generated clips into one long sequence while preserving motion, visual and audio continuity across clip boundaries.
- 38
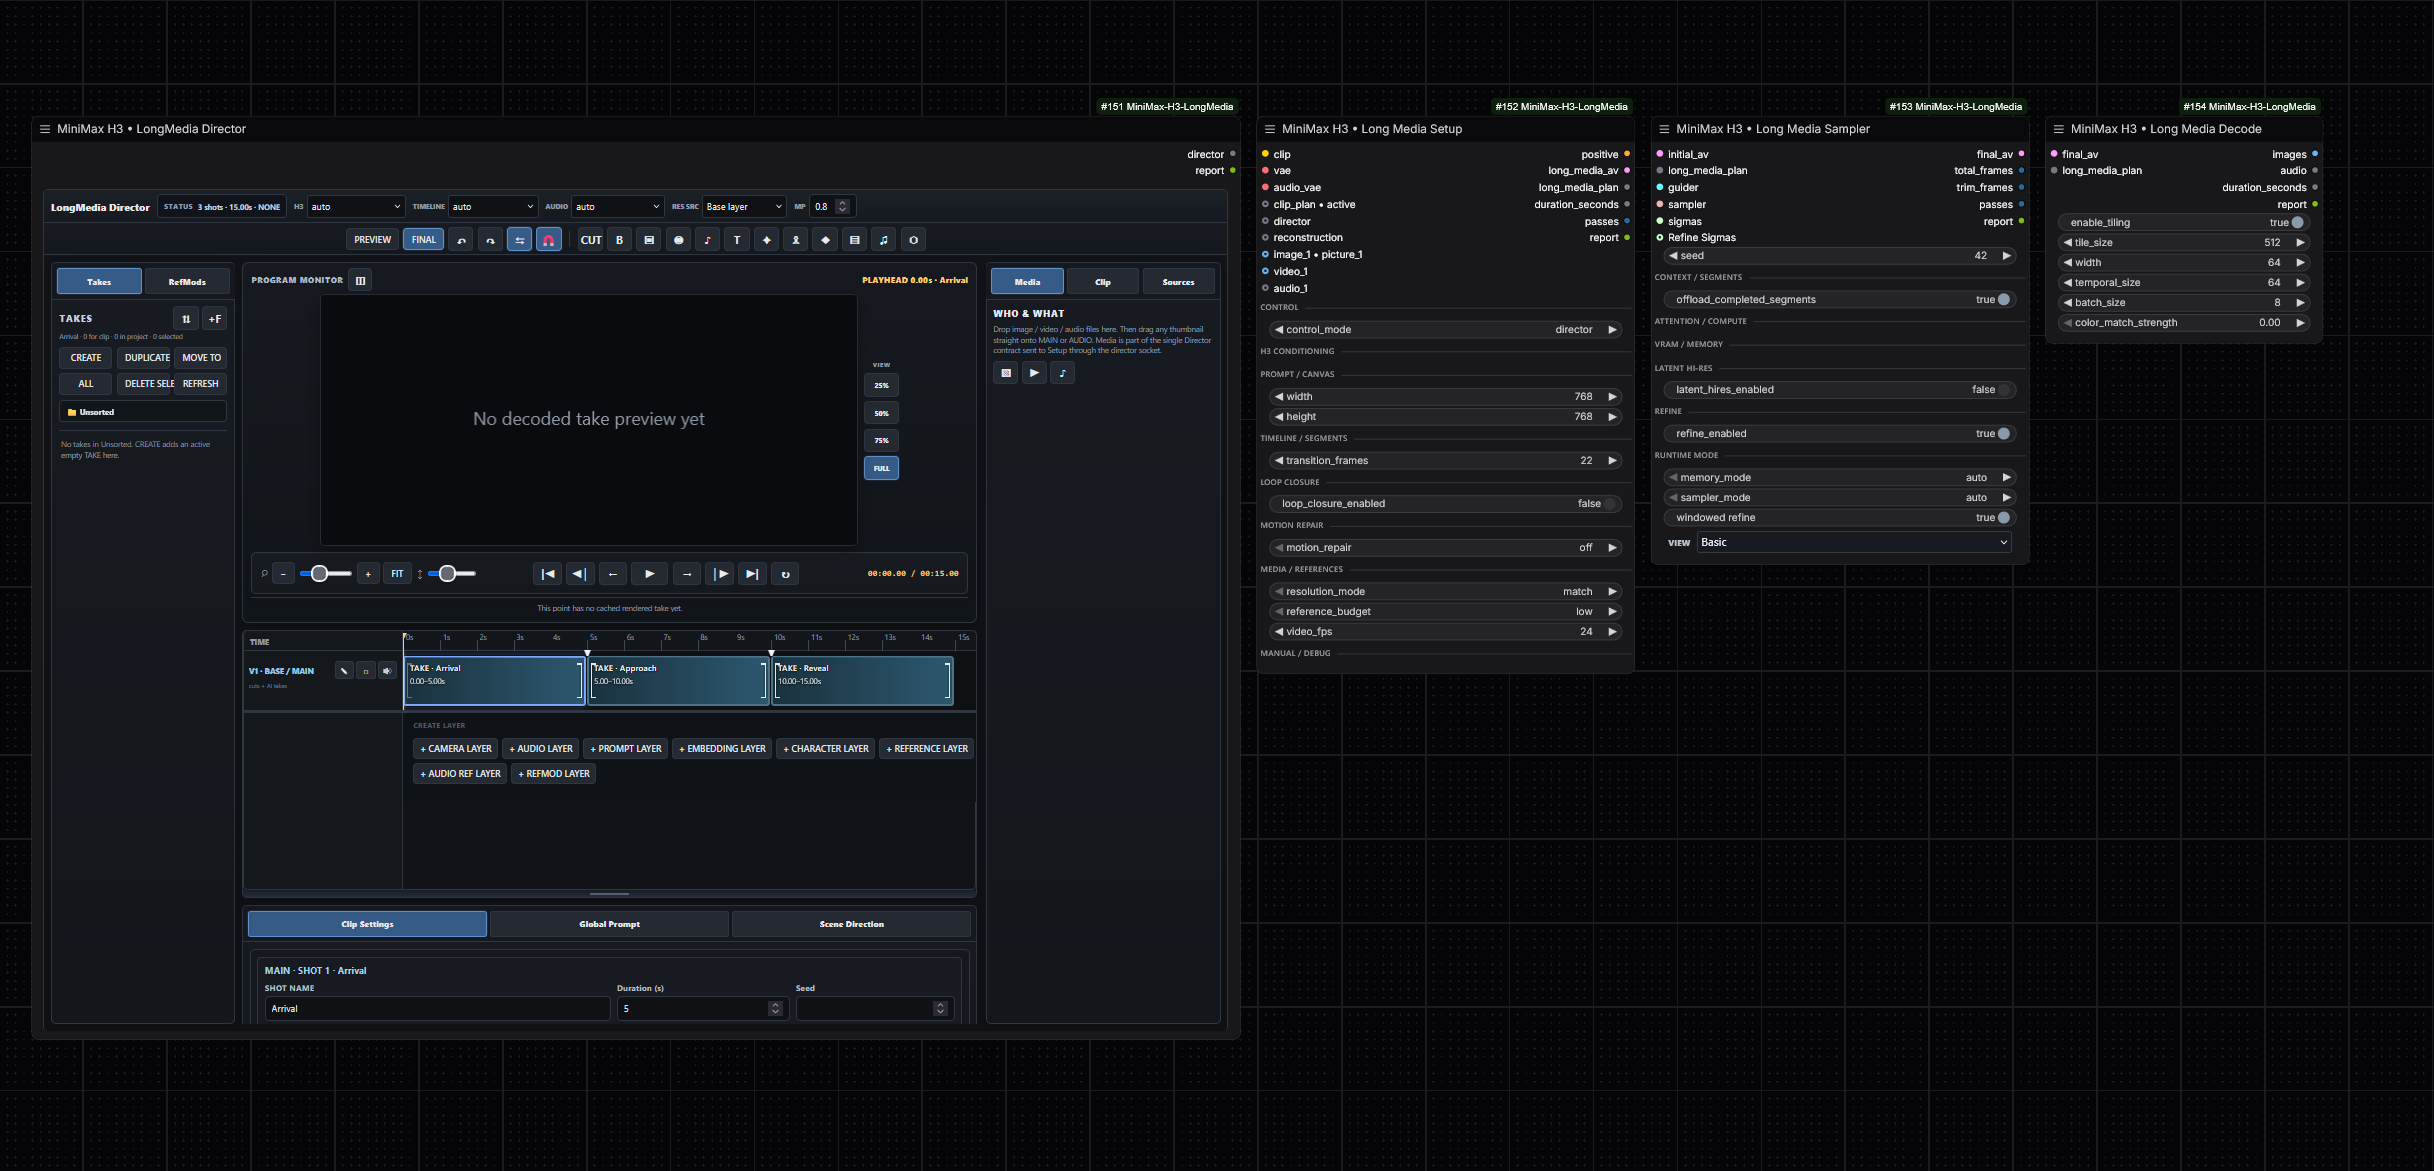
ComfyUI-MiniMax-H3-LongMedia
294vizart-vj/ComfyUI-MiniMax-H3-LongMedia · PythonA set of production-oriented custom nodes for ComfyUI that run MiniMax H3 for long-form video and audio generation: reference editing, MultiClip planning, camera direction, fixed segmentation, lip-sync and redubbing, latent hi-res refinement, and low-VRAM-safe execution.
- 39
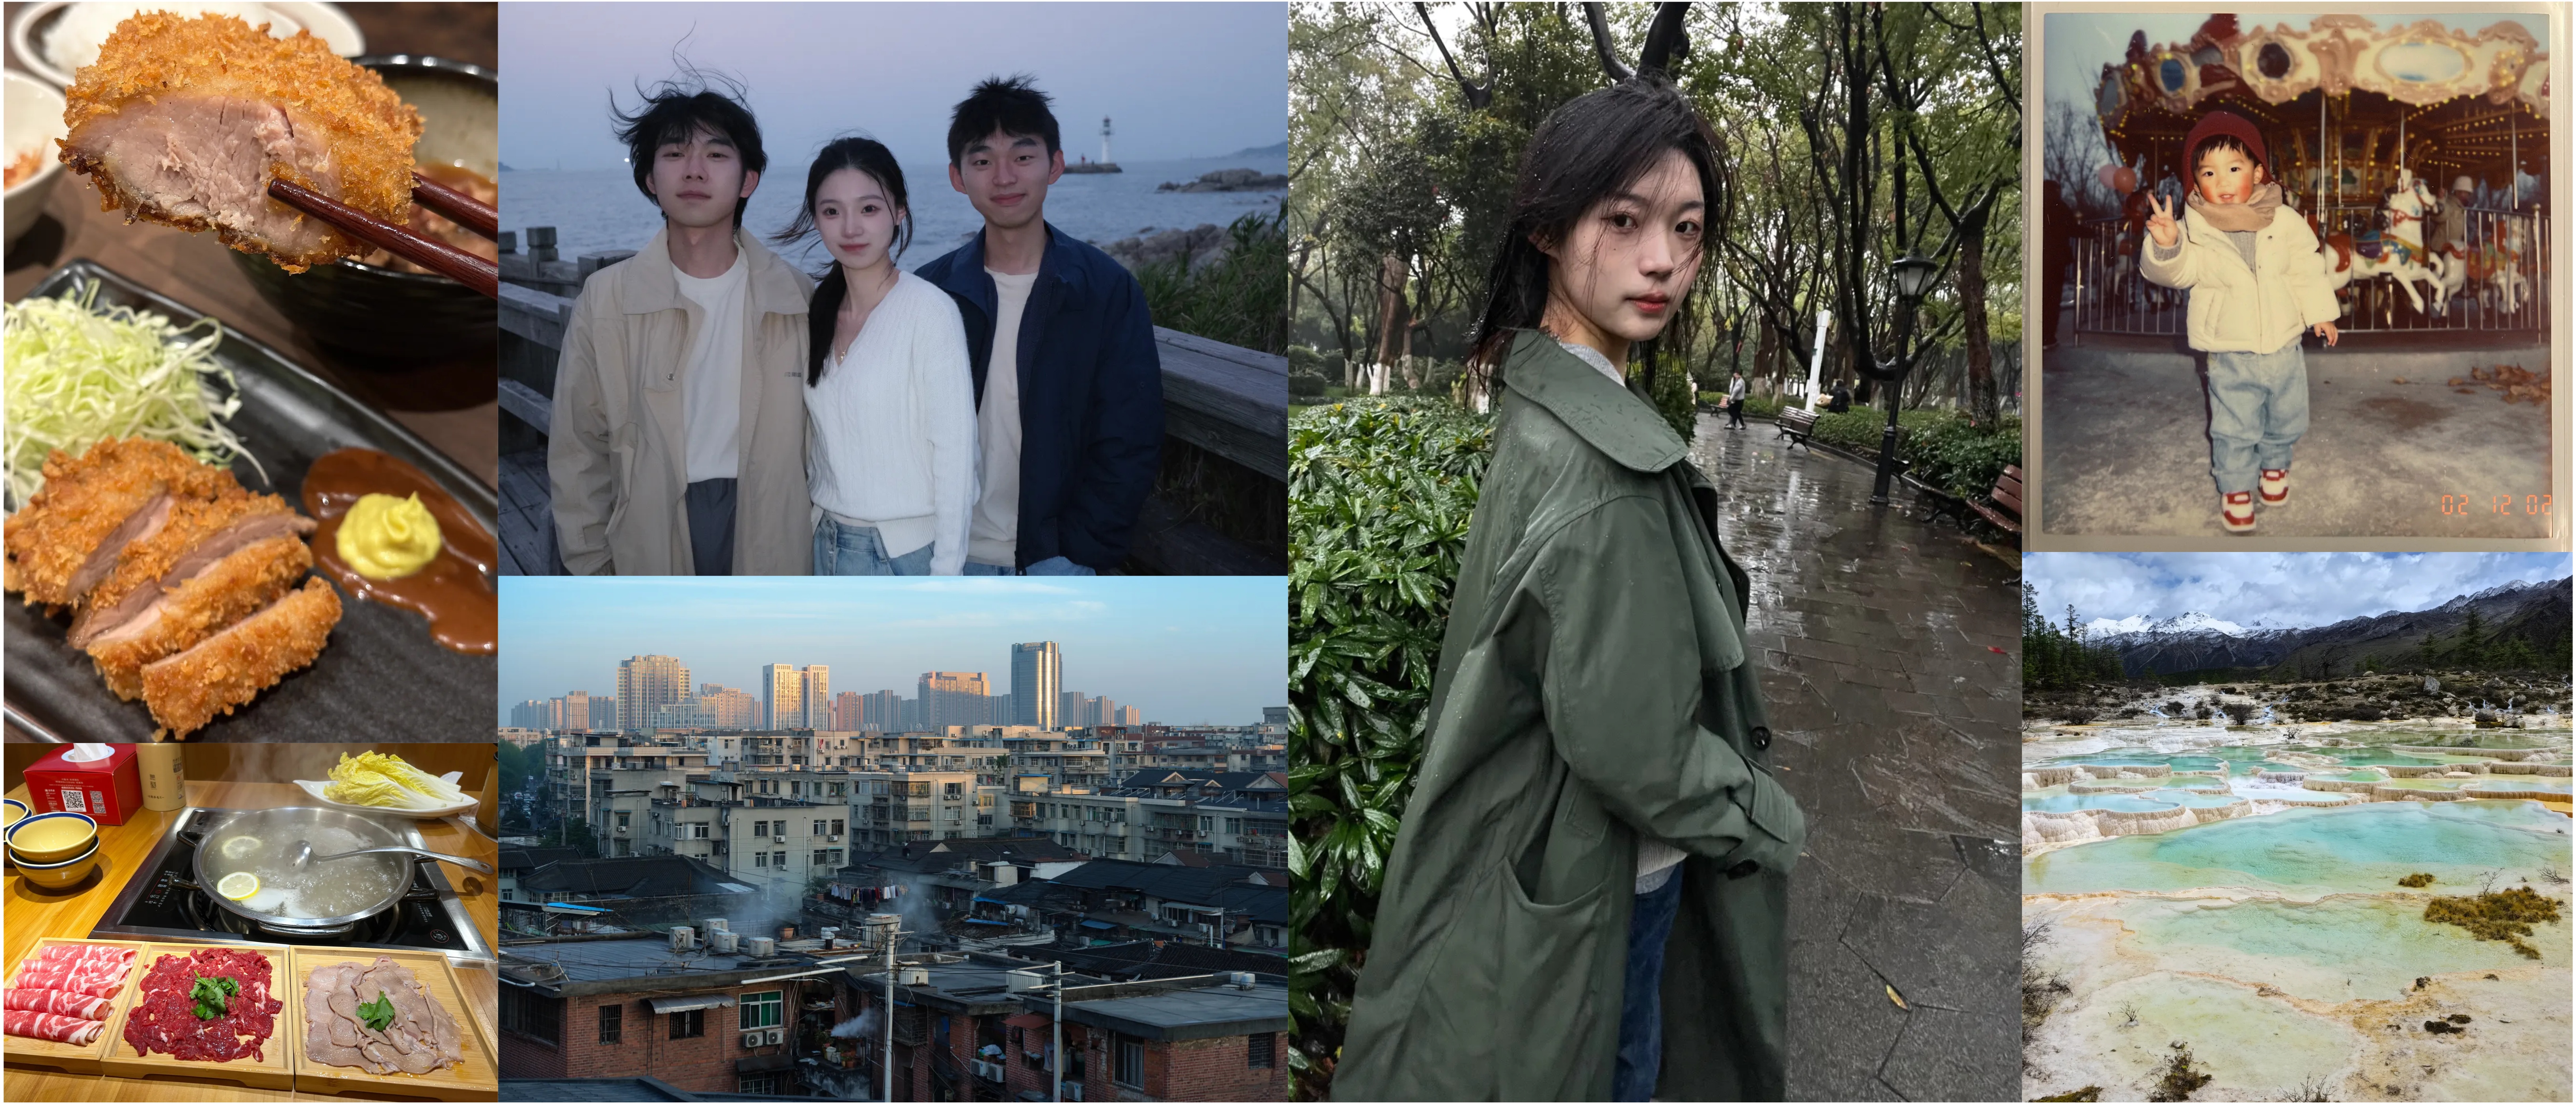
LLaDA-Image
261inclusionAI/LLaDA-Image · PythonLLaDA-Image is an open-source 6B-parameter unified model family for high-quality text-to-image generation and instruction-guided image editing, released as a 50-step Base model and a 4-step distilled Turbo model.
- 40
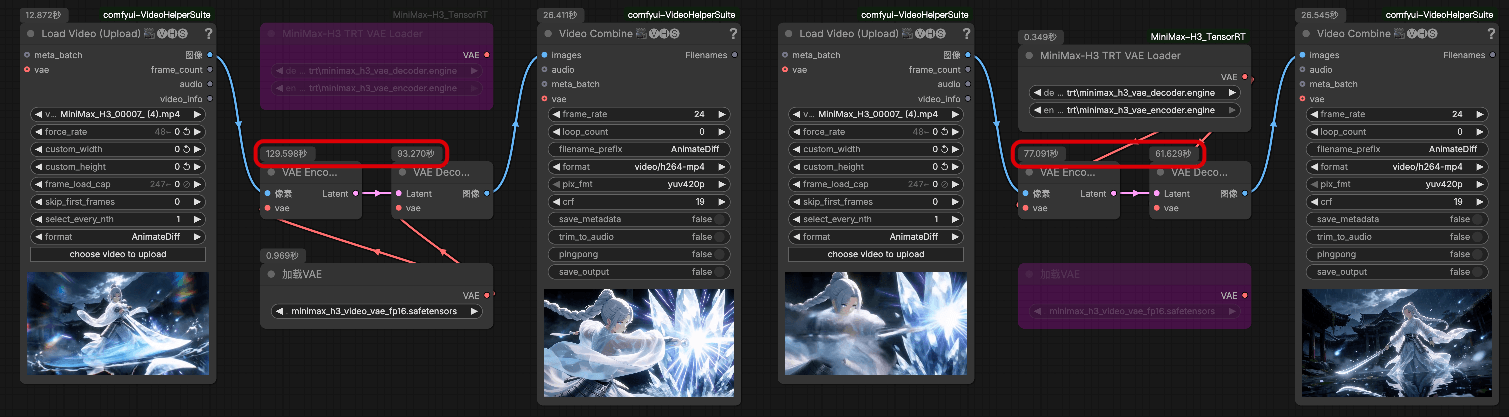
ComfyUI-H3VAE_TRT
254lihaoyun6/ComfyUI-H3VAE_TRT · PythonA ComfyUI custom node that runs the MiniMax-H3 VAE as a compiled TensorRT engine instead of the regular one, making it up to 1.7x faster.
- 41

vlo
247PxTicks/vlo · TypeScriptVlo is a free, open-source, local video editor with built-in AI features like automatic rotoscoping, audio stem separation, and beat detection, plus a live bridge to ComfyUI for running any generative AI workflow directly on the timeline.
- 42

ComfyUI-YCNodes-MiniMax-H3
243yichengup/ComfyUI-YCNodes-MiniMax-H3 · PythonThis is a ComfyUI custom node pack built specifically for the MiniMax H3 video model, adding 6 nodes for second-pass conditioning, timed prompt control, attention-field constraints, dynamic CFG scheduling, low-noise detail refinement and tiled sampling.
- 43
MiniMax-H3-Cloud
239Sac-Y/MiniMax-H3-Cloud · JavaScriptMiniMax H3 Cloud is a Codex plugin that generates MiniMax H3 videos using cloud GPUs (currently via the YunCloud/CompShare platform), handling instance selection, launching, ComfyUI workflow submission, MP4 download, and automatic shutdown.
- 44

Comfyui-MMH3-UltimateUpscale
236bbaudio-2025/Comfyui-MMH3-UltimateUpscale · PythonA ComfyUI custom node that upscales long, high-resolution MiniMax H3 AV video latents on VRAM-limited GPUs, using temporal chunking and spatial tiling inside a single node while keeping the audio track intact.
- 45

wenai
203Straniero44/wenaiwenai is a skill template for OpenClaw (and similar agent frameworks) that turns your AI agent into an immersive AI girlfriend companion, with daily greetings, roleplay scenes, generated images, and persistent memory of your relationship.
- 46
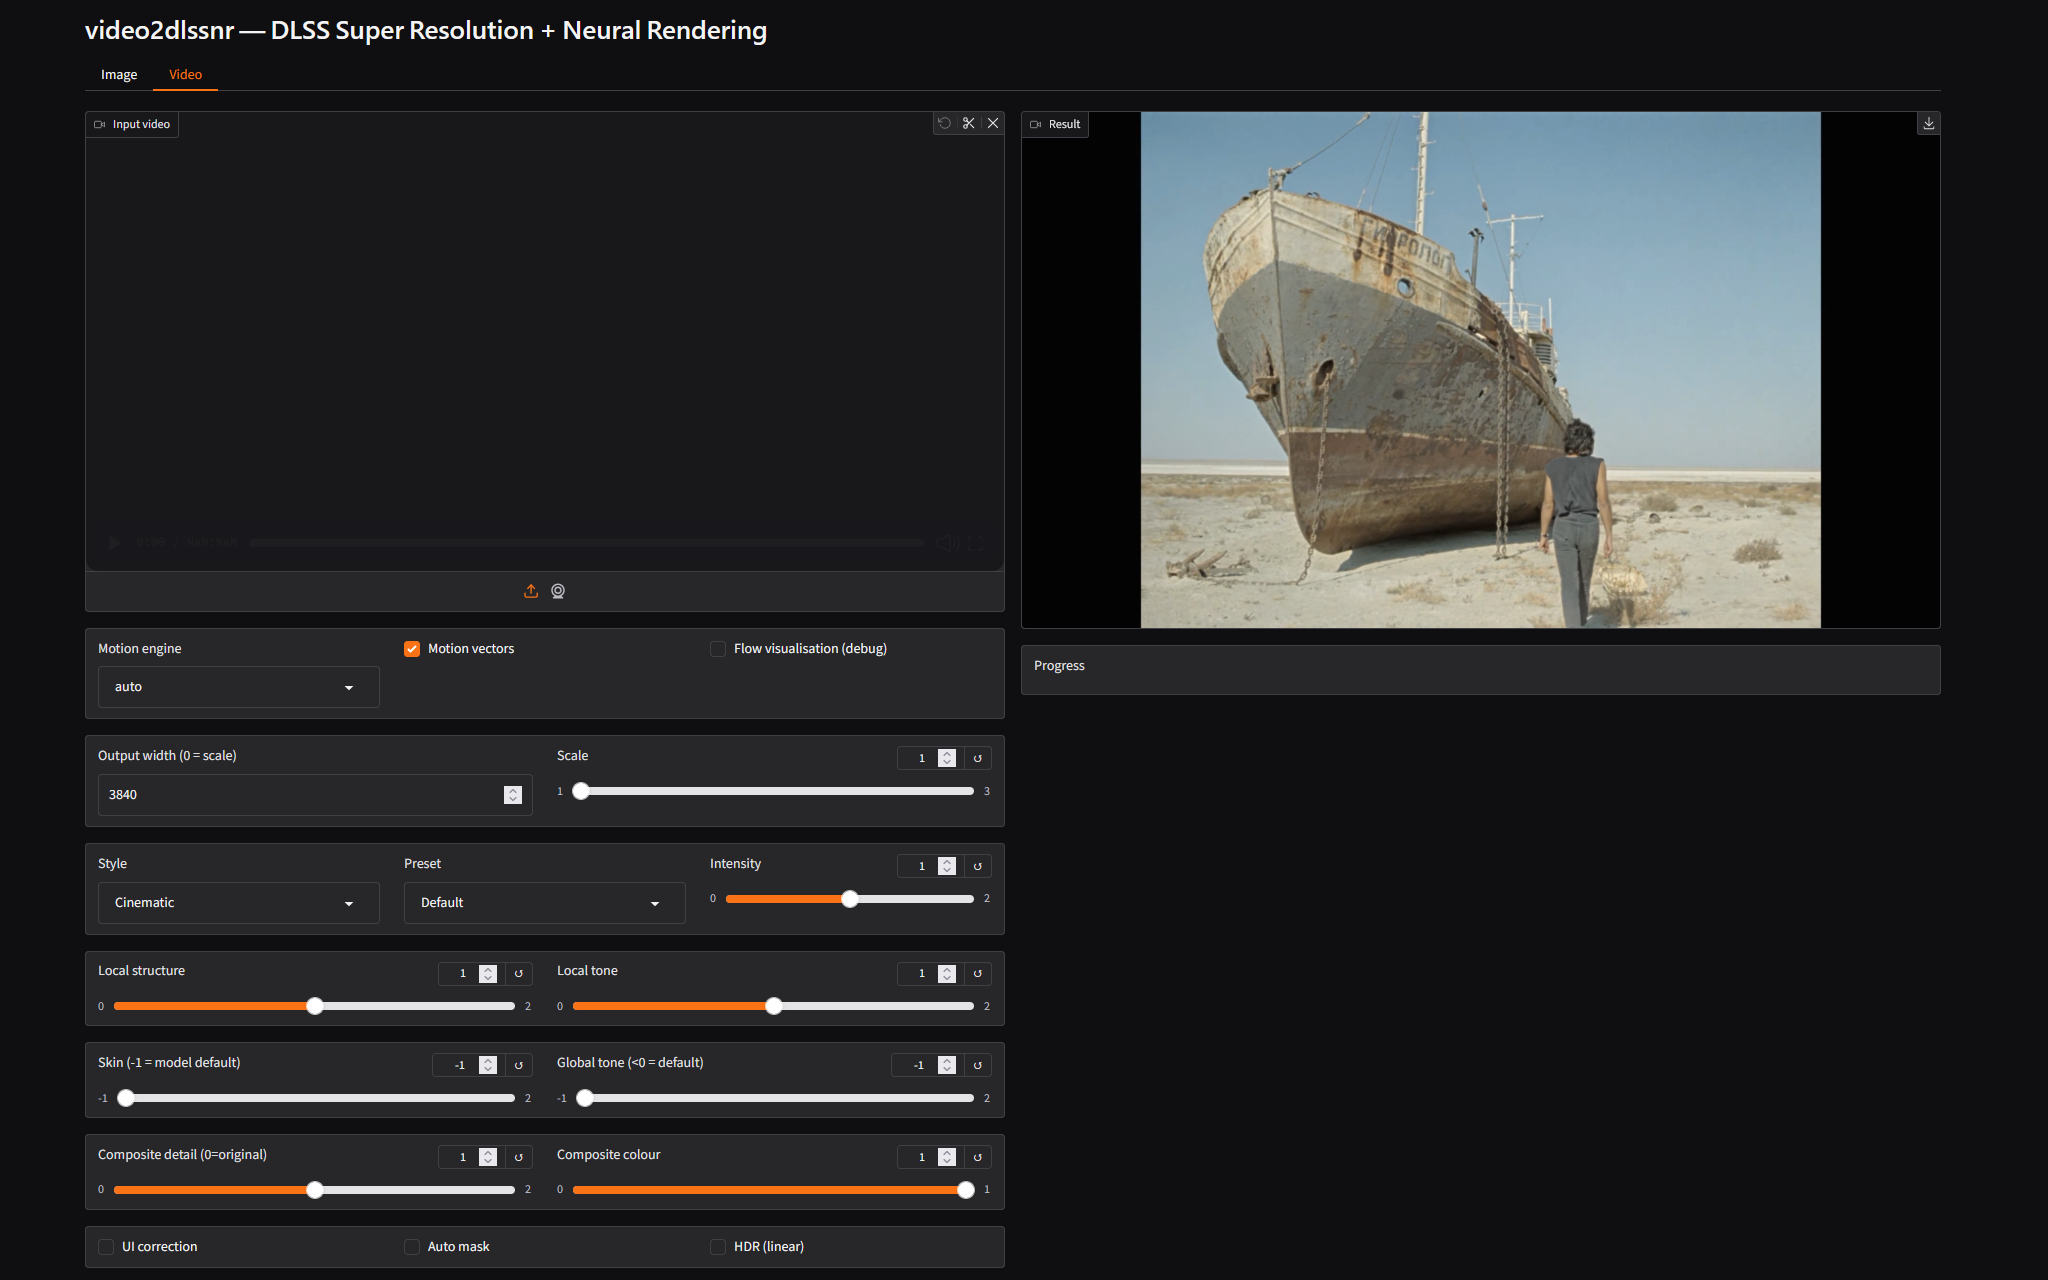
video2dlssnr
183DaniilSokolyuk/video2dlssnr · C++video2dlssnr brings NVIDIA's DLSS Super Resolution and Neural Rendering (DLSS 5, NGX feature 18) to arbitrary images and video on Windows, letting you upscale and enhance clips or stills the same way a game engine would, through a desktop UI, ComfyUI nodes, or a plain command-line tool.
- 47

short-drama-production
183suihe1/short-drama-production · JavaScriptThis is a production-control skill for Codex that turns AI short-drama video generation into a trackable, state-based pipeline covering outline, characters, art, script, directing, technical storyboards, MiniMax H3 shot jobs, voice assets, rough cuts and QC.
- 48
ComfyUI_MinimaxH3HybridLoader
180scottmudge/ComfyUI_MinimaxH3HybridLoader · PythonA custom ComfyUI node that loads a MiniMax H3 (audio+video DiT) checkpoint by merging selected tensor groups from a second 'overlay' checkpoint onto a 'base' checkpoint, producing a hybrid that ComfyUI treats exactly like a normal loaded model.
- 49

h3-storyboard-skill
178phileiny/h3-storyboard-skillIt is a Claude Code skill that teaches the agent how to turn a script into MiniMax H3 shot lists, covering shot breakdown, beat counting, and facial/body performance direction so the emotional acting actually renders on screen.
- 50
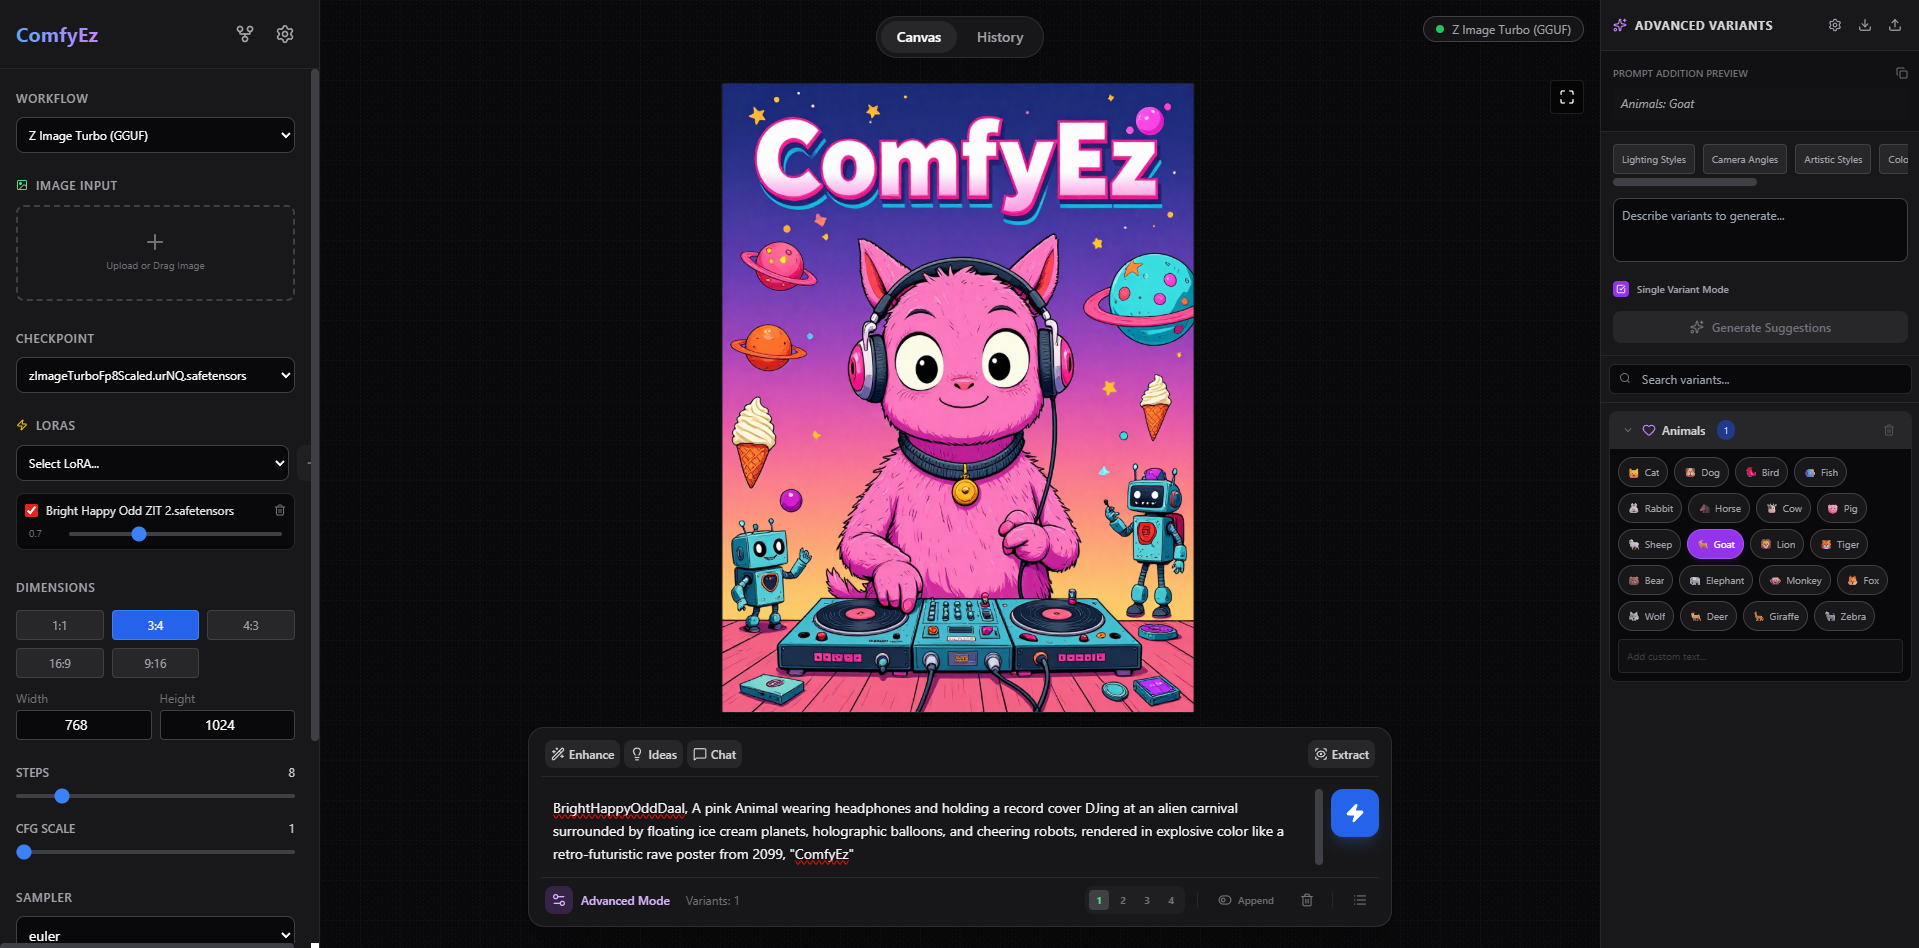
comfyEz
77amirrezasalimi/comfyEz · TypeScriptA web interface for a local ComfyUI instance: it wraps the node graph in a sleek Playground-style UI like commercial AI generators, adding LLM-powered prompt tools and a dedicated inpainting editor.
Related topics
Often tagged together
- gpu789
- python2,383
- linux4,184
- ai1,955
- windows3,403
- video-generation191
- generative-ai339
- macos3,544
- open-source5,666
- image-generation225
- diffusion-models80
- apache-2.01,434
- deep-learning737
- huggingface362
- inference327
- pytorch419
- text-to-video62
- text-to-image72
- cuda396
- machine-learning916
- chinese1,159
- image-to-video46
- lora87
- nvidia328