Topics / #vlm
Vlm projects on GitHub
Vision-language models that understand images together with text prompts.
As of , the most-starred Vlm projects on GitHub are transformers (167.8K stars), PaddleOCR (91.3K stars) and UI-TARS-desktop (39.3K stars). GitHub.Locker tracks 34 Vlm repositories with 575.9K stars combined. The fastest-growing on October 16 was tokenspeed, with +102 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +102
tokenspeed
lightseekorg/tokenspeed · ★ 2.7KTokenSpeed is a speed-of-light LLM inference engine designed for agentic workloads, with TensorRT-LLM-level performance and vLLM-level usability. The goal is to be the most performant inference engine for production agentic workloads.
 +62
PaddleOCR
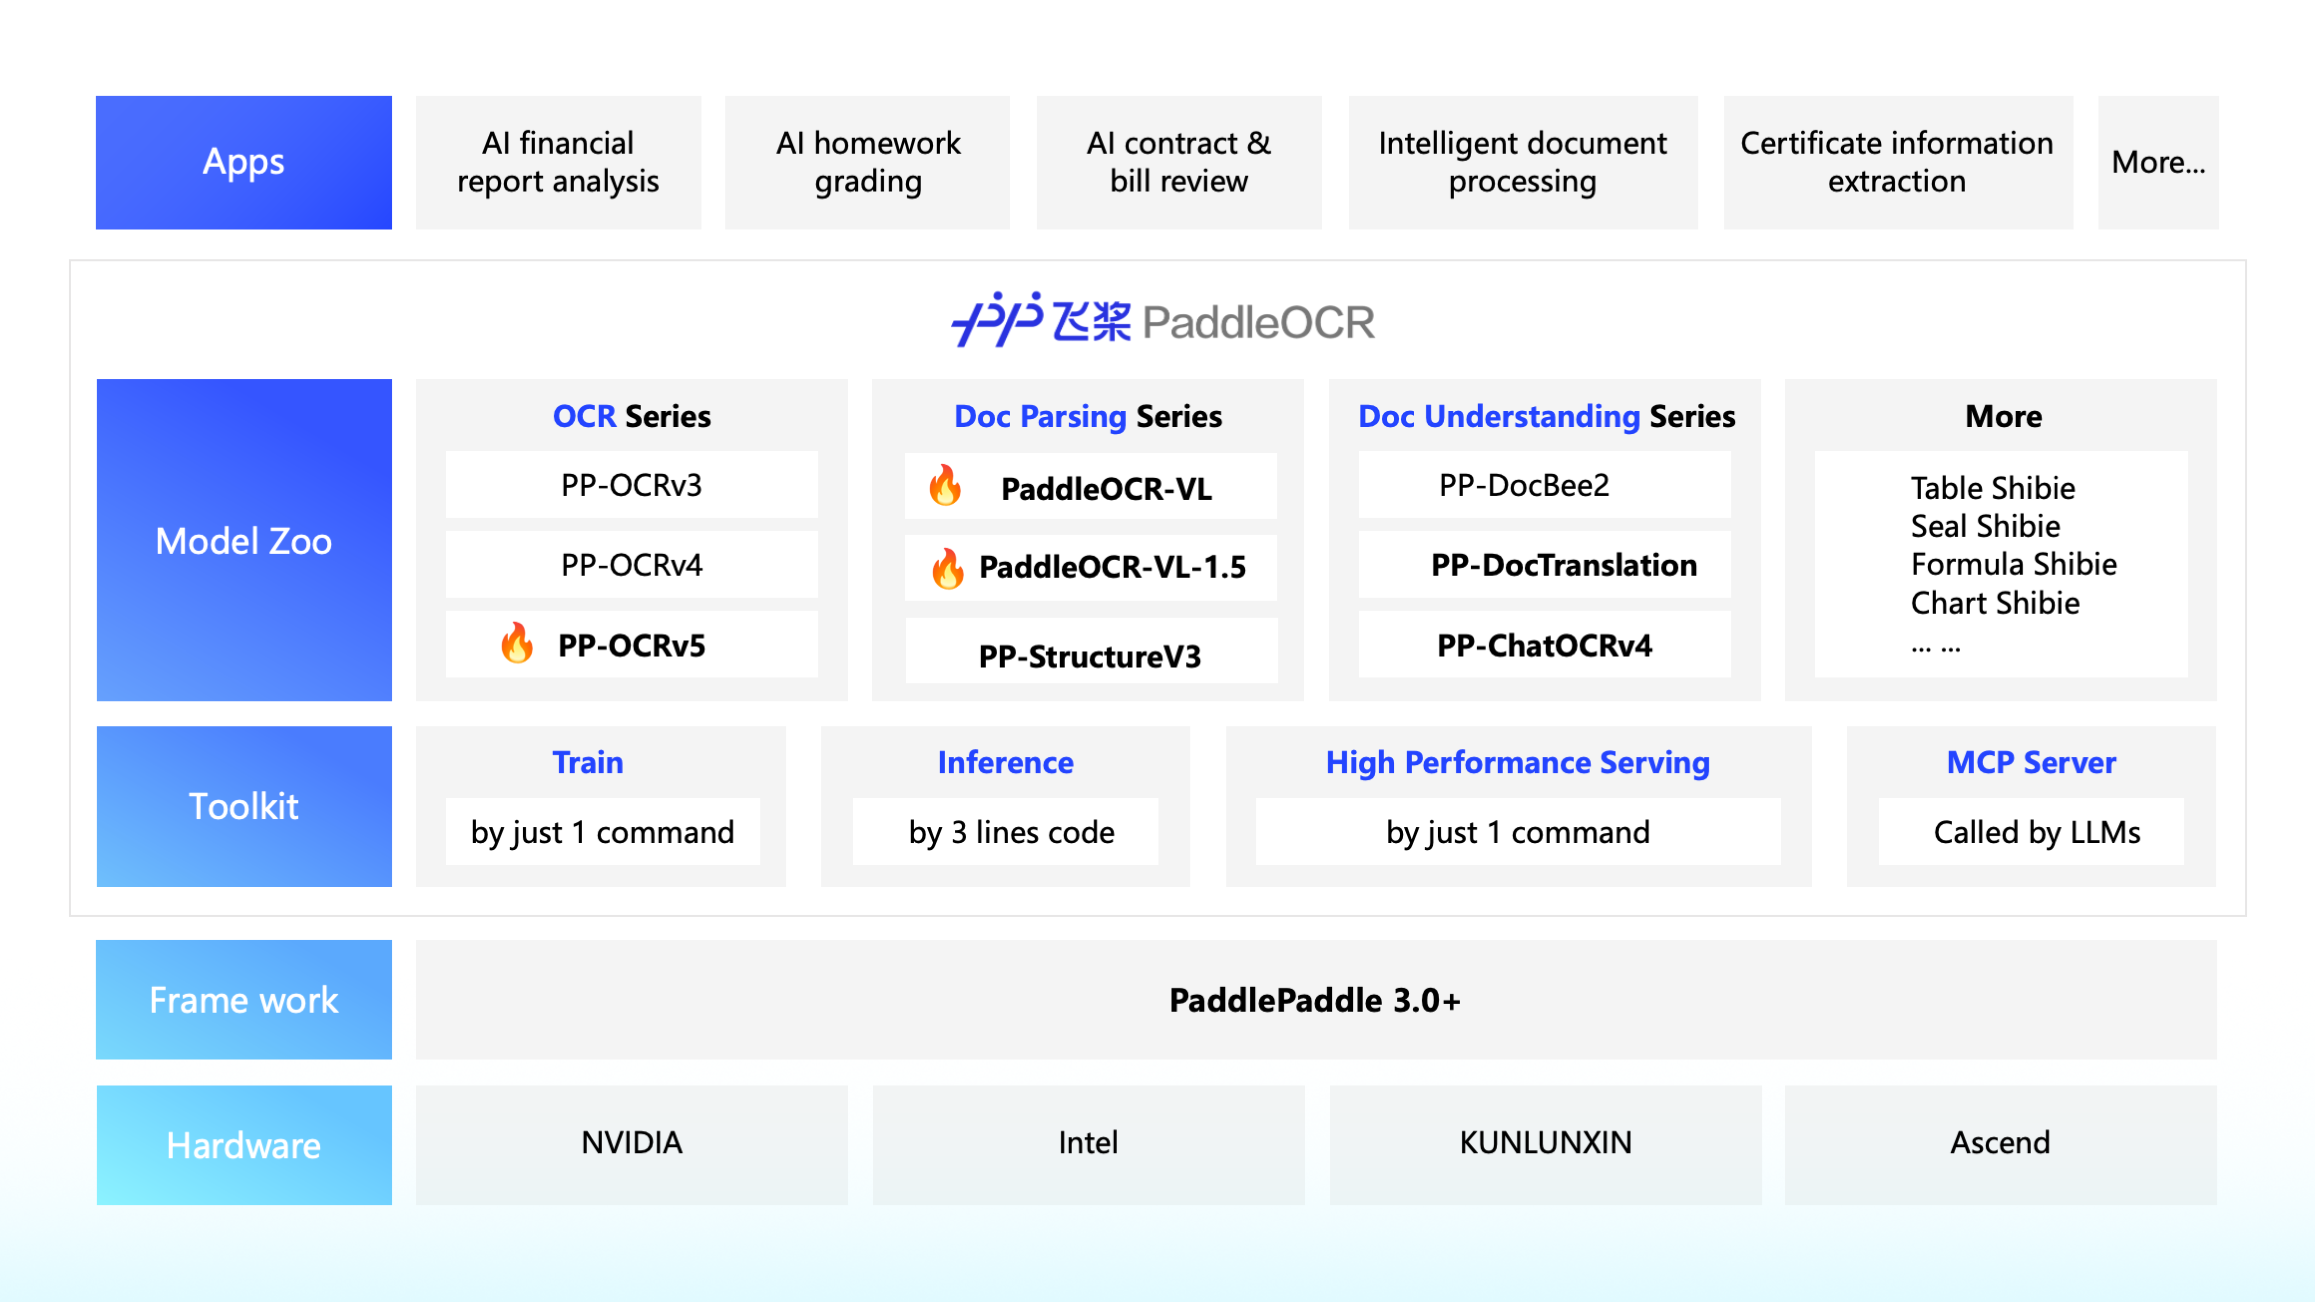
PaddlePaddle/PaddleOCR · ★ 91.3KPaddleOCR is an OCR and document AI toolkit that converts PDFs and images into structured, LLM-ready data (JSON or Markdown), supporting over 100 languages.
 +62
RAG-Anything
HKUDS/RAG-Anything · ★ 23.6KAn all-in-one multimodal RAG framework built on LightRAG: it ingests real-world documents that mix text, images, tables and equations, then answers queries across all content types through one pipeline instead of separate specialized tools.
 +60
EvoVLM
zzzz7788990213-ops/EvoVLM · ★ 319EvoVLM is a research project that runs LLM-guided, multi-objective evolutionary search over vision-language inference programs. It targets the accuracy-latency trade-off on scientific chart understanding while keeping model weights frozen.
The all-time top
34 projects · by stars
- 167.8K
 #1 · huggingface/transformers
transformers
Transformers is Hugging Face's model-definition framework for state-of-the-art machine learning models across text, vision, audio, video, and multimodal tasks, usable for both inference and training.
- 91.3K#2 · PaddlePaddle/PaddleOCR
PaddleOCR
PaddleOCR is an OCR and document AI toolkit that converts PDFs and images into structured, LLM-ready data (JSON or Markdown), supporting over 100 languages.
- 39.3K
 #3 · bytedance/UI-TARS-desktop
UI-TARS-desktop
TARS is an open-source multimodal AI agent stack from ByteDance that ships two projects: Agent TARS, a CLI/Web UI agent for terminal, browser and tool-use tasks, and UI-TARS Desktop, a native app that lets a vision-language model see your screen and control mouse/keyboard.
- 4
sglang
37.2Ksgl-project/sglang · PythonSGLang is a high-performance serving framework for large language models and multimodal models, built to deliver low-latency, high-throughput inference from a single GPU up to large distributed clusters.
- 5
MiniGPT-4
25.6KVision-CAIR/MiniGPT-4 · PythonThis is the open-sourced research code for MiniGPT-4 and MiniGPT-v2, two vision-language models that use a large language model as the interface for understanding and chatting about images.
- 6
verl
23.9Kverl-project/verl · Pythonverl is a flexible, efficient and production-ready reinforcement learning training library for LLMs, initiated by ByteDance's Seed team and maintained by the community. It is the open-source version of the HybridFlow paper (EuroSys 2025).
- 7
RAG-Anything
23.6KHKUDS/RAG-Anything · PythonAn all-in-one multimodal RAG framework built on LightRAG: it ingests real-world documents that mix text, images, tables and equations, then answers queries across all content types through one pipeline instead of separate specialized tools.
- 8

omlx
22.9Kjundot/omlx · PythonoMLX is a local LLM inference server for Apple Silicon Macs. It serves text LLMs, vision models, OCR, embeddings and rerankers with continuous batching and a tiered KV cache, managed from the macOS menu bar.
- 9
surya
21.5Kdatalab-to/surya · PythonSurya is Datalab's open-source document OCR system built around a 650M parameter model. It reads text from images and PDFs, and also does layout analysis, reading order, and table recognition.
- 10

ml-engineering
19.5Kstas00/ml-engineering · PythonAn open book on machine learning engineering: methodologies, tools and step-by-step instructions for training, fine-tuning and running inference on large language models and multi-modal (VLM) models, written by the engineer who led the BLOOM-176B training.
- 11
Embodied-AI-Guide
16.5KTianxingChen/Embodied-AI-GuideA free, encyclopedia-style Chinese knowledge base and resource index for embodied AI — robots that perceive and act in the physical world — maintained by the Lumina Embodied AI community. It is one of the most popular embodied-AI guides in China, with over 16,000 GitHub stars.
- 12
UI-TARS
11.6Kbytedance/UI-TARS · PythonUI-TARS is an open-source multimodal agent model built on a vision-language model that can operate GUIs directly — clicking, typing, scrolling, dragging — across desktop apps, mobile screens, browsers, and even video games like Minecraft, reasoning about its actions before taking them.
- 13
X-AnyLabeling
10.7KCVHub520/X-AnyLabeling · PythonA free cross-platform desktop app for AI-assisted annotation of text, image, video, and multimodal data — manual labeling tools plus built-in deep learning models that pre-label or batch-annotate, with multi-format export.
- 14
runanywhere-sdks
10.3KRunanywhereAI/runanywhere-sdks · C++A toolkit of eight SDKs over one C++ core that runs AI fully on-device — LLM chat, vision, speech, voice agents, RAG, and image generation — on phones, browsers, and desktops. Everything is private by default and works offline.
- 15

PixelRAG
10.3KStarTrail-org/PixelRAG · PythonAn open-source research codebase from Berkeley for pixel-native search: PixelRAG renders web pages, PDFs and images as screenshots and retrieves over the images directly, instead of parsing pages into text.
- 16
InternVL
10.2KOpenGVLab/InternVL · PythonA family of open-source multimodal chat models that understand images, video and text, positioned as an open alternative to GPT-4o. InternVL2.5-78B was the first open-source model to top 70% on the MMMU benchmark.
- 17
MiniMax-H3
10.1KMiniMax-AI/MiniMax-H3 · PythonMiniMax H3 is a general-purpose omni-modal generative system: it reads mixed text, image, video and audio input and generates video with native stereo audio, up to 2K resolution and 15 seconds per clip.
- 18
fara
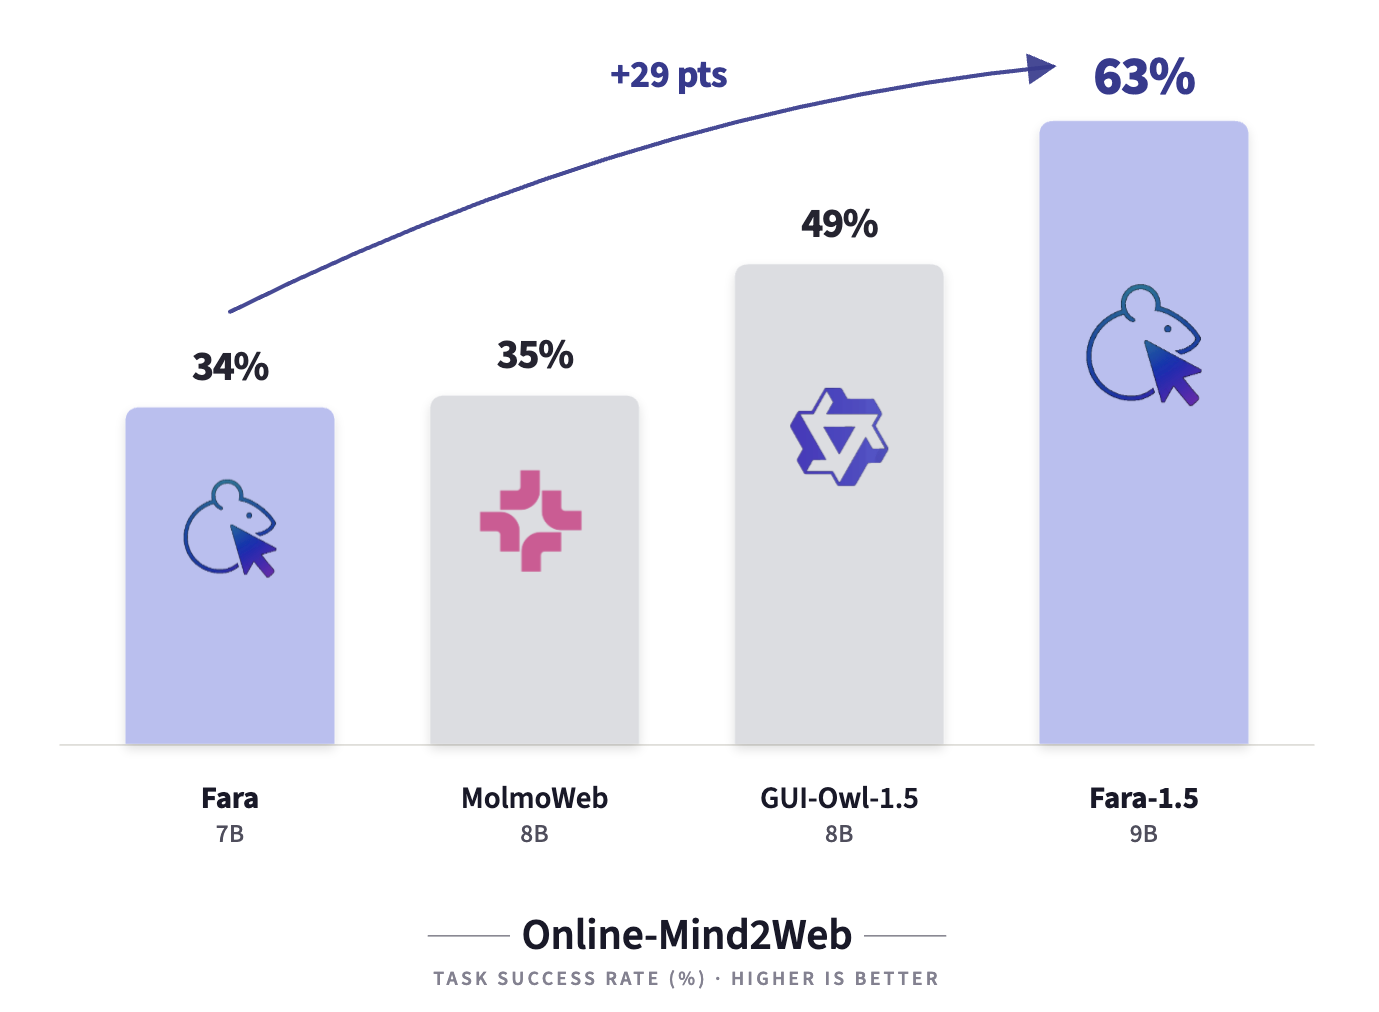
6.2Kmicrosoft/fara · PythonA family of open computer-use agent models — Fara1.5-4B, 9B and 27B, built on Qwen3.5 — that perform multi-step web tasks for you by controlling the mouse and keyboard like a human would.
- 19
knowhere
3.8KOntos-AI/knowhere · PythonKnowhere is an open-source document parsing and retrieval system: it ingests messy files and turns them into structured, navigable memory for AI agents, ready for agentic RAG and any LLM workflow.
- 20
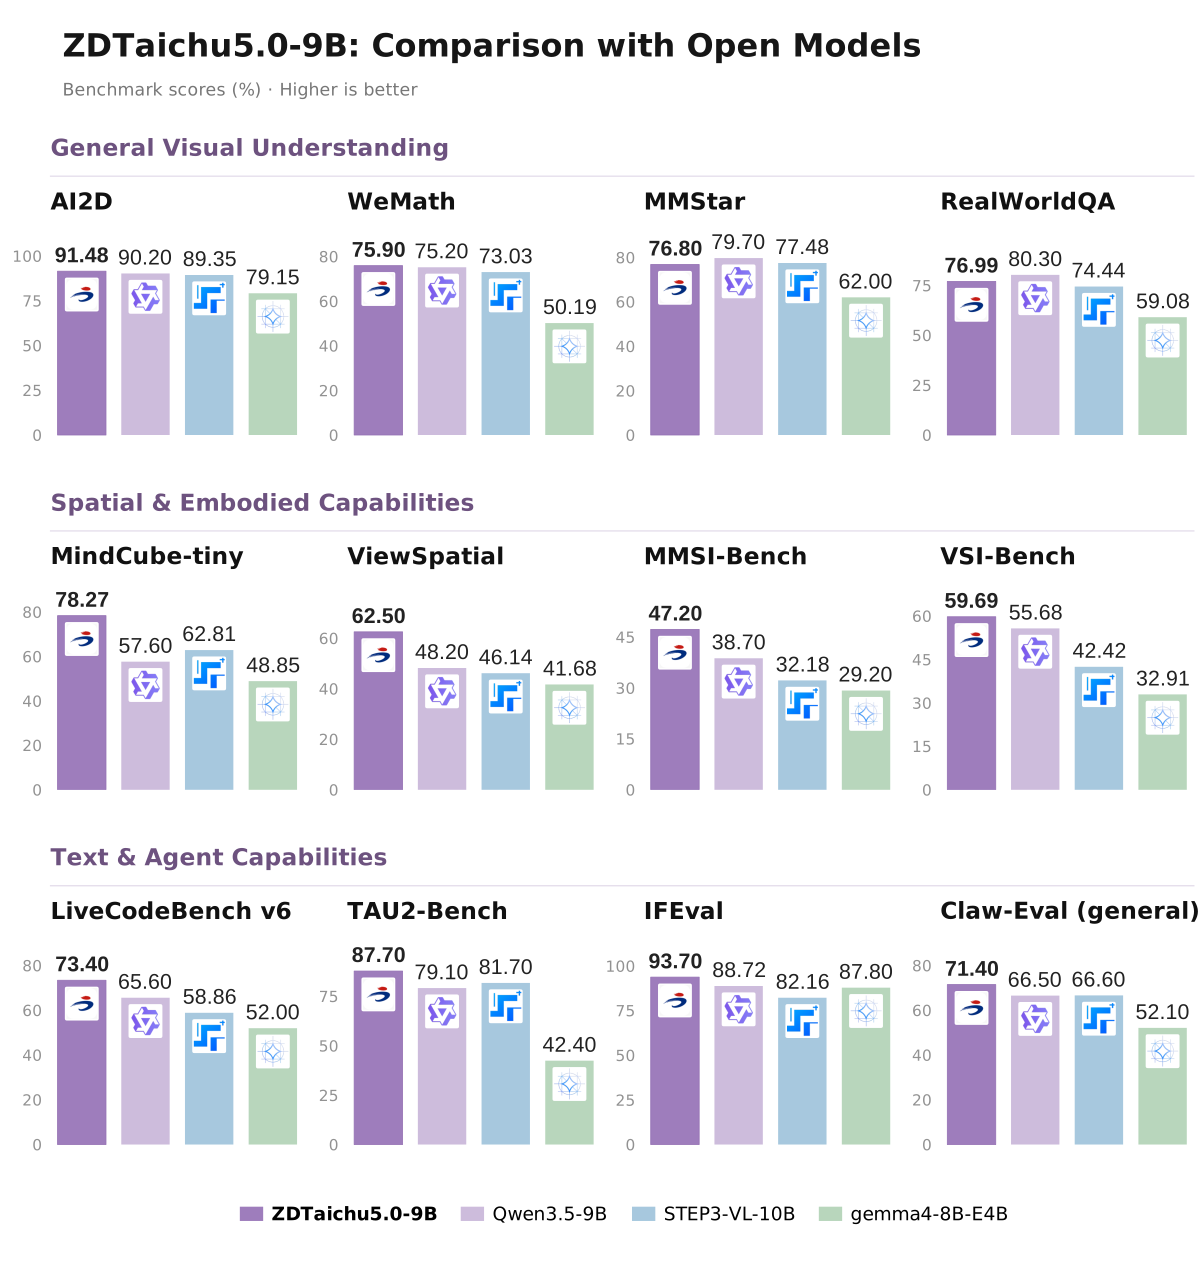
ZDTaichu5.0-9B
3.1KTaichu-AI/ZDTaichu5.0-9B · PythonZDTaichu5.0-9B is a multimodal foundation model that combines a Qwen3.5-9B language backbone with a C-RADIOv4-H vision encoder for general visual understanding, spatial reasoning, embodied-AI research and agentic tool use.
- 21
tokenspeed
2.7Klightseekorg/tokenspeed · PythonTokenSpeed is a speed-of-light LLM inference engine designed for agentic workloads, with TensorRT-LLM-level performance and vLLM-level usability. The goal is to be the most performant inference engine for production agentic workloads.
- 22
lift
1.2Kdatalab-to/lift · Pythonlift is an open-source 9B vision-language model and toolkit that extracts structured JSON data from PDFs and images by matching a schema you provide, using schema-constrained decoding to guarantee valid output.
- 23
TypeLLM
956TypeLLM/TypeLLM · PythonTypeLLM adds type-safe, schema-guaranteed output generation to existing open autoregressive LLMs, without changing their weights or architecture, letting models still think freely while returning typed JSON Schema-constrained answers.
- 24
Valen
843Liuziyu77/Valen · Jupyter NotebookValen (万澜) is a multimodal decision model that adds visual perception to System One-style decision-making: it scores candidate actions against text, images and video using a task instruction, instead of generating free-form answers.
- 25
FluxVLA
748FluxVLA/FluxVLA · PythonFluxVLA is a full-stack engineering platform for embodied AI covering the whole loop from data to real-robot deployment for vision-language-action (VLA) models, built to lower the engineering barrier for VLA research and development.
- 26
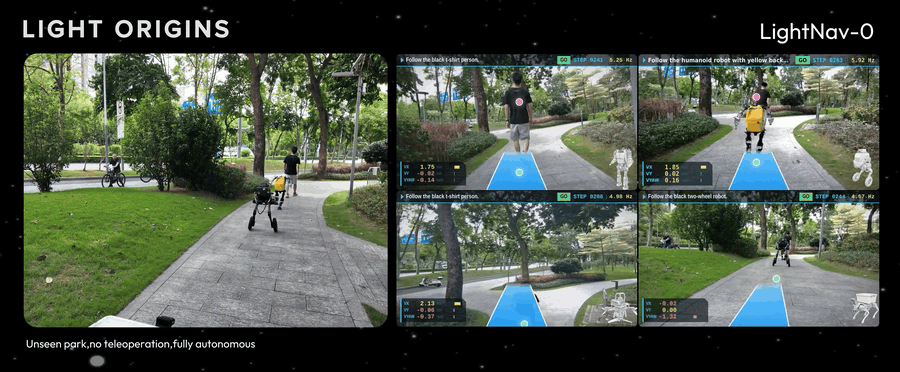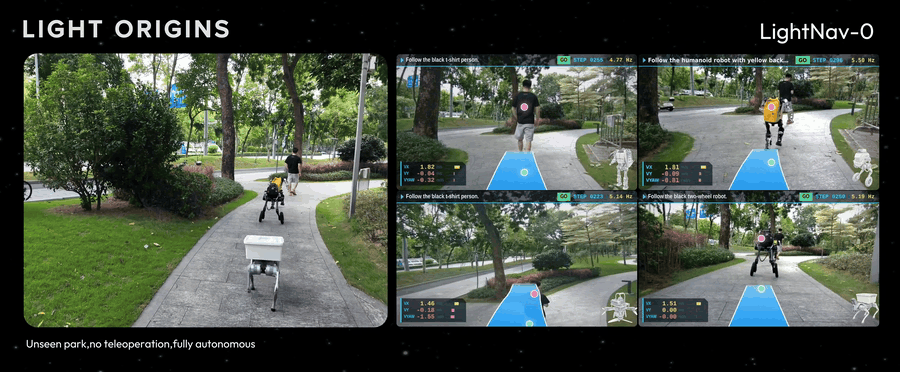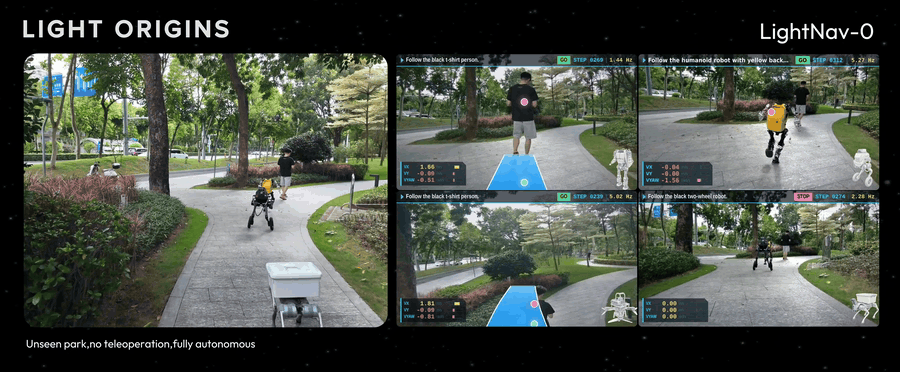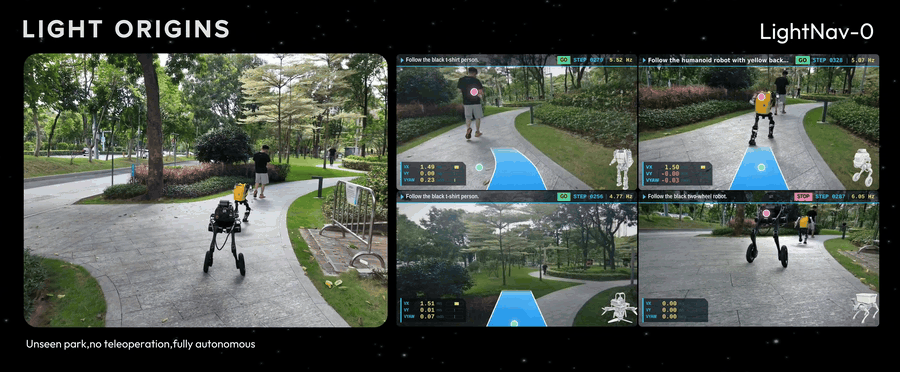
LightNav-0
721lightorigins/LightNav-0 · PythonLightNav-0 is a compact generalist embodied navigation model that gives humanoid, quadruped, wheeled and aerial robots the ability to follow language instructions and navigate autonomously in unseen environments, without any teleoperation.
- 27
verl
716XiaomiMiMo/verl · Pythonverl is an open-source RL post-training framework for large language models, started by ByteDance Seed as the open-source version of the HybridFlow paper. This XiaomiMiMo fork adds agentic RL training code for MiMo, with reproduction code for five RL environments on top of verl 0.9.0.dev.
- 28
LoongForge
687baidu-baige/LoongForge · PythonAn open-source training framework from Baidu's Baige team for LLMs, VLMs, diffusion and embodied models, built for faster training and lower cost on NVIDIA GPUs and Kunlun XPUs.
- 29
Qwen-Drive-1.0
515QwenLM/Qwen-Drive-1.0 · PythonQwen-Drive-1.0 is a vision-language foundation model for autonomous driving, built on the Qwen3.5-4B VLM and extended with 3D perception, visual question answering, and motion planning in one unified model.
- 30
SCM
486allenv0/SCM · TypeScriptSCM (Screen Memories) is a macOS desktop app that runs deep AI search locally over every photo and every video frame in a chosen folder, letting you search by meaning, on-screen text, or spoken dialogue, all without the cloud.
- 31
EvoVLM
319zzzz7788990213-ops/EvoVLM · PythonEvoVLM is a research project that runs LLM-guided, multi-objective evolutionary search over vision-language inference programs. It targets the accuracy-latency trade-off on scientific chart understanding while keeping model weights frozen.
- 32
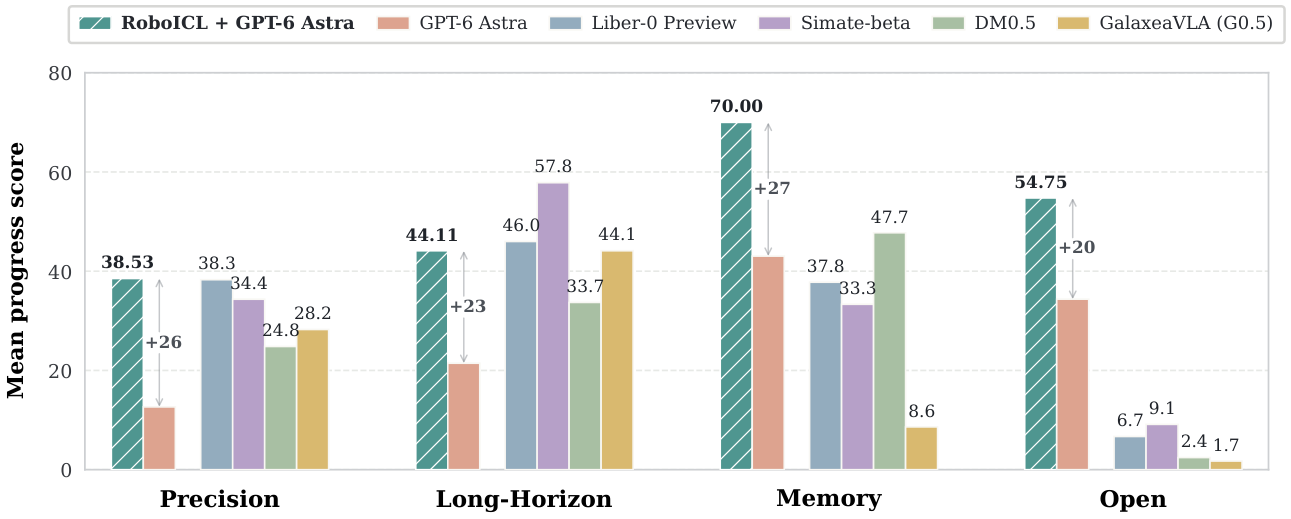
RoboICL
268Mosi-AI/RoboICL · PythonRoboICL is a research framework that lets a frozen, general-purpose vision-language model (GPT-6 Astra) control a robot in simulation purely through in-context learning, without training a dedicated robot policy.
- 33
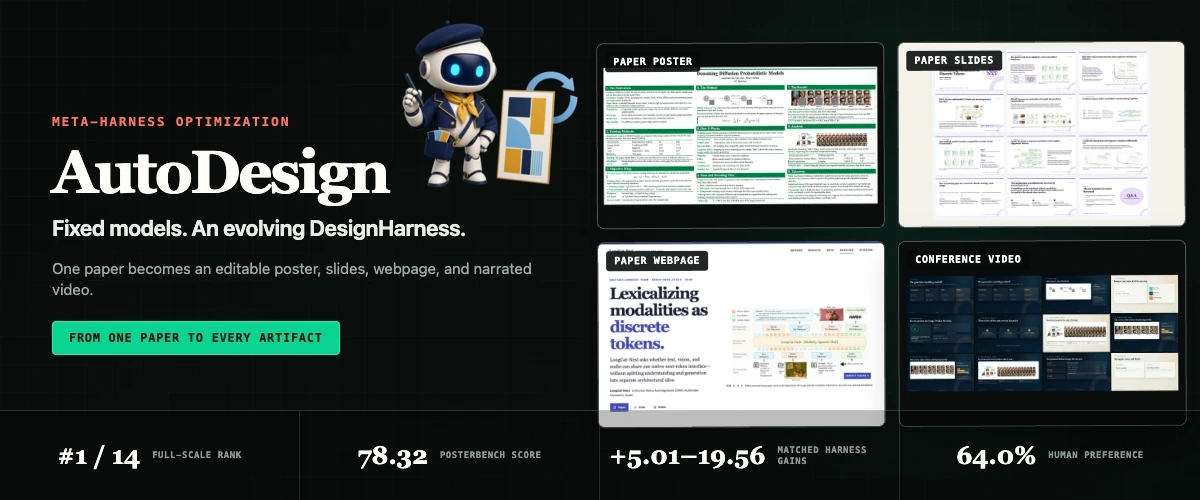
AutoDesign
245Yaxin9Luo/AutoDesign · PythonAn open-source design agent and harness that turns one research paper PDF into four editable artifacts: a poster, slide deck, webpage, and narrated video. It claims to beat Claude Design on academic communication artifacts.
- 34
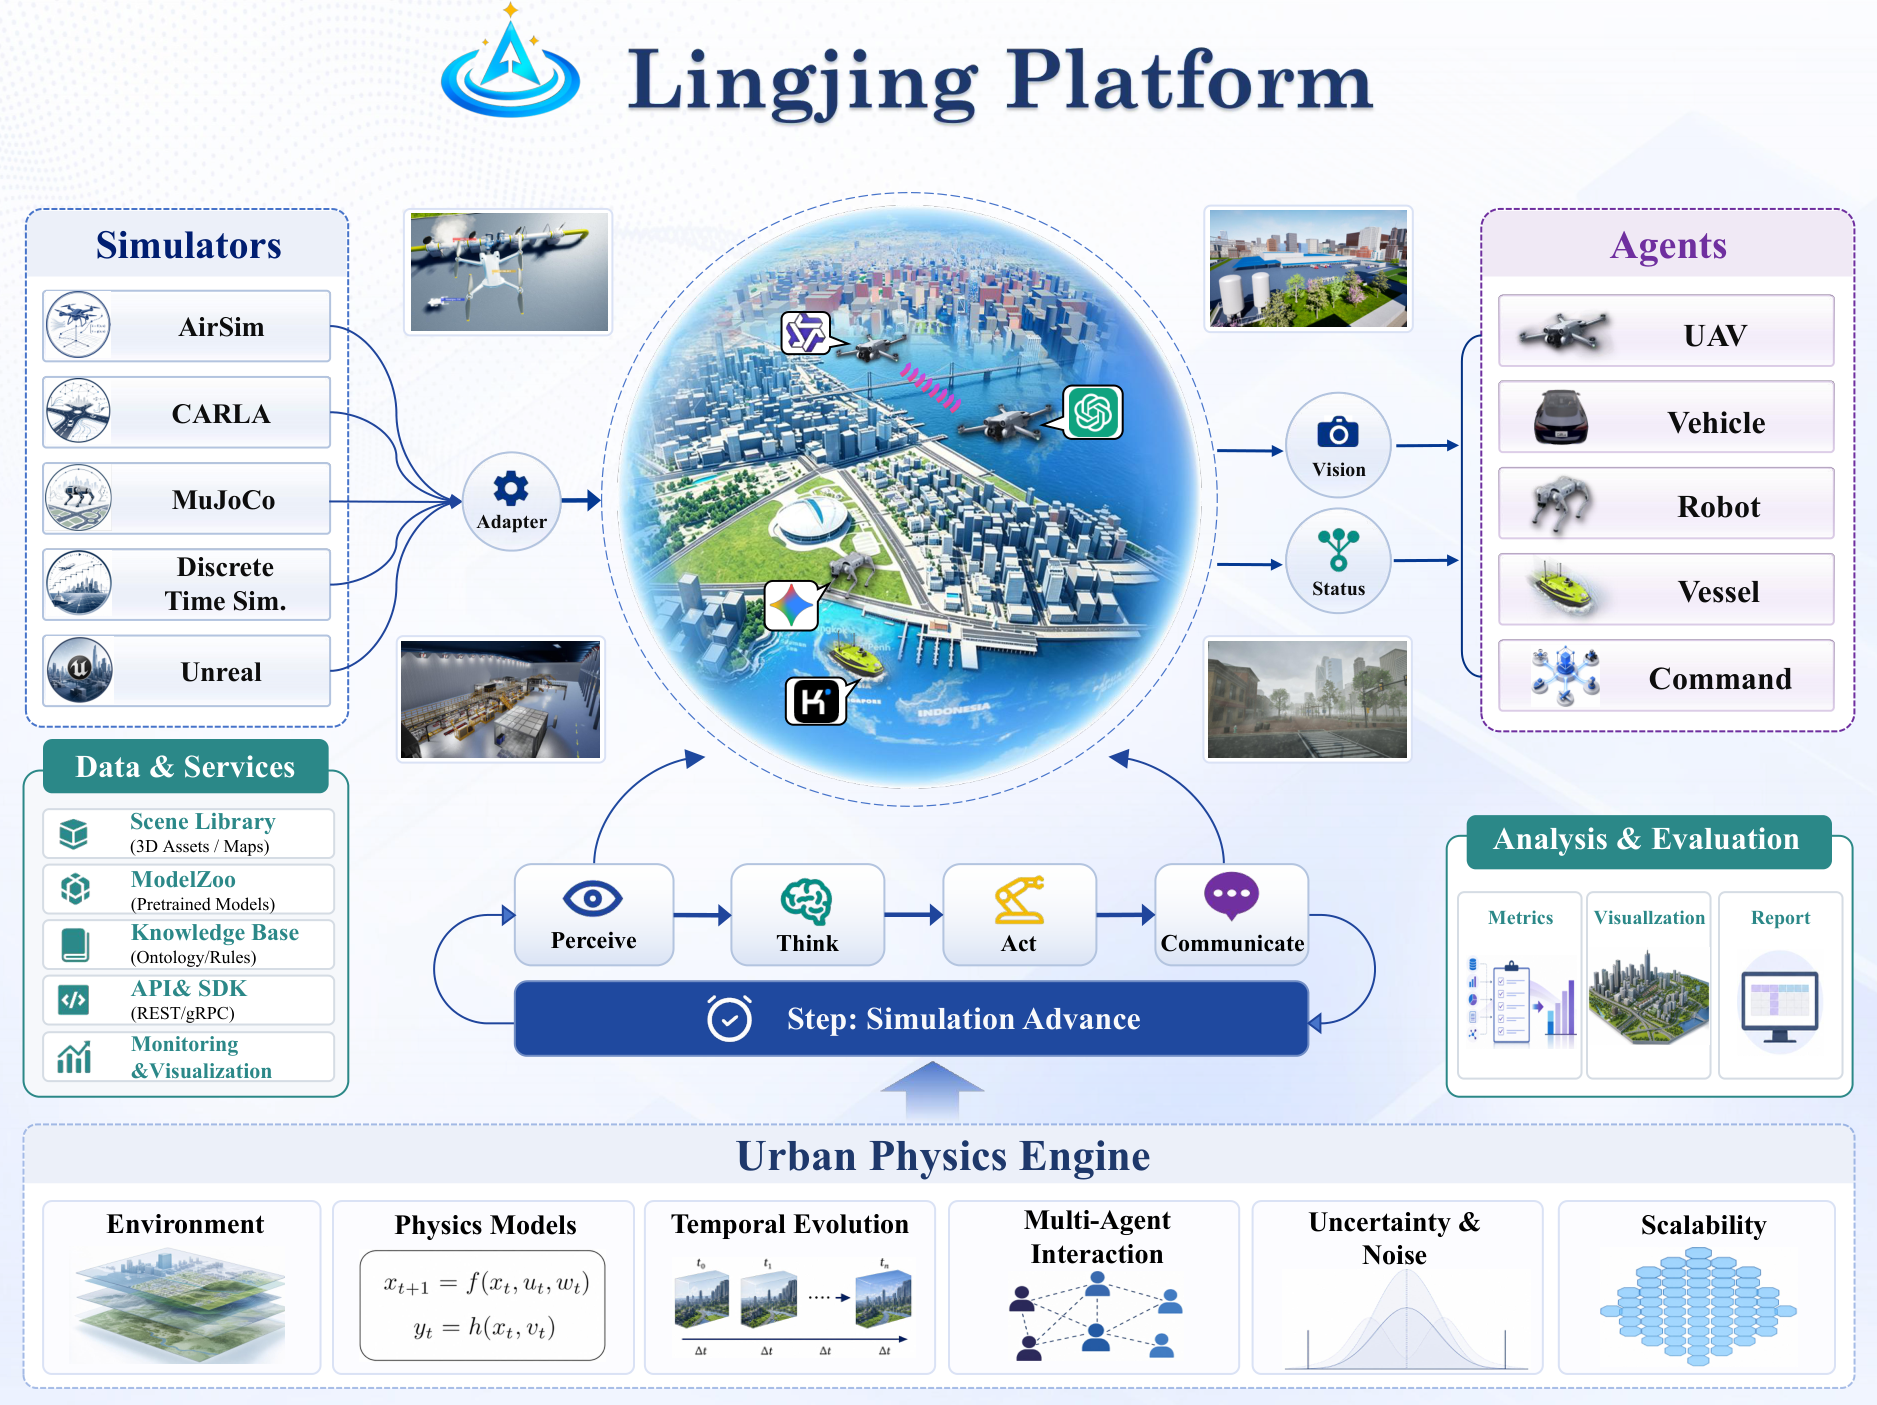
Air-Lingjing
194seanlxh/Air-Lingjing · PythonLingJing is an open simulation stack for LLM-driven embodied agents in large 3D environments: a FastAPI/LangGraph backend plus a Cesium-powered Unreal Engine 5.5 plugin, with runnable example cases.
Related topics
Often tagged together