Topics / #pretraining
Pretraining projects on GitHub
Resources on pretraining large language models from scratch.
As of , the most-starred Pretraining projects on GitHub are LLMs-from-scratch (106.8K stars), unsloth (78.2K stars) and nanochat (58.8K stars). GitHub.Locker tracks 15 Pretraining repositories with 369.3K stars combined. The fastest-growing on October 18 was train-llm-from-scratch, with +86 stars in a day.
Hot right now
Most stars gained in a day · Oct 18
 +86
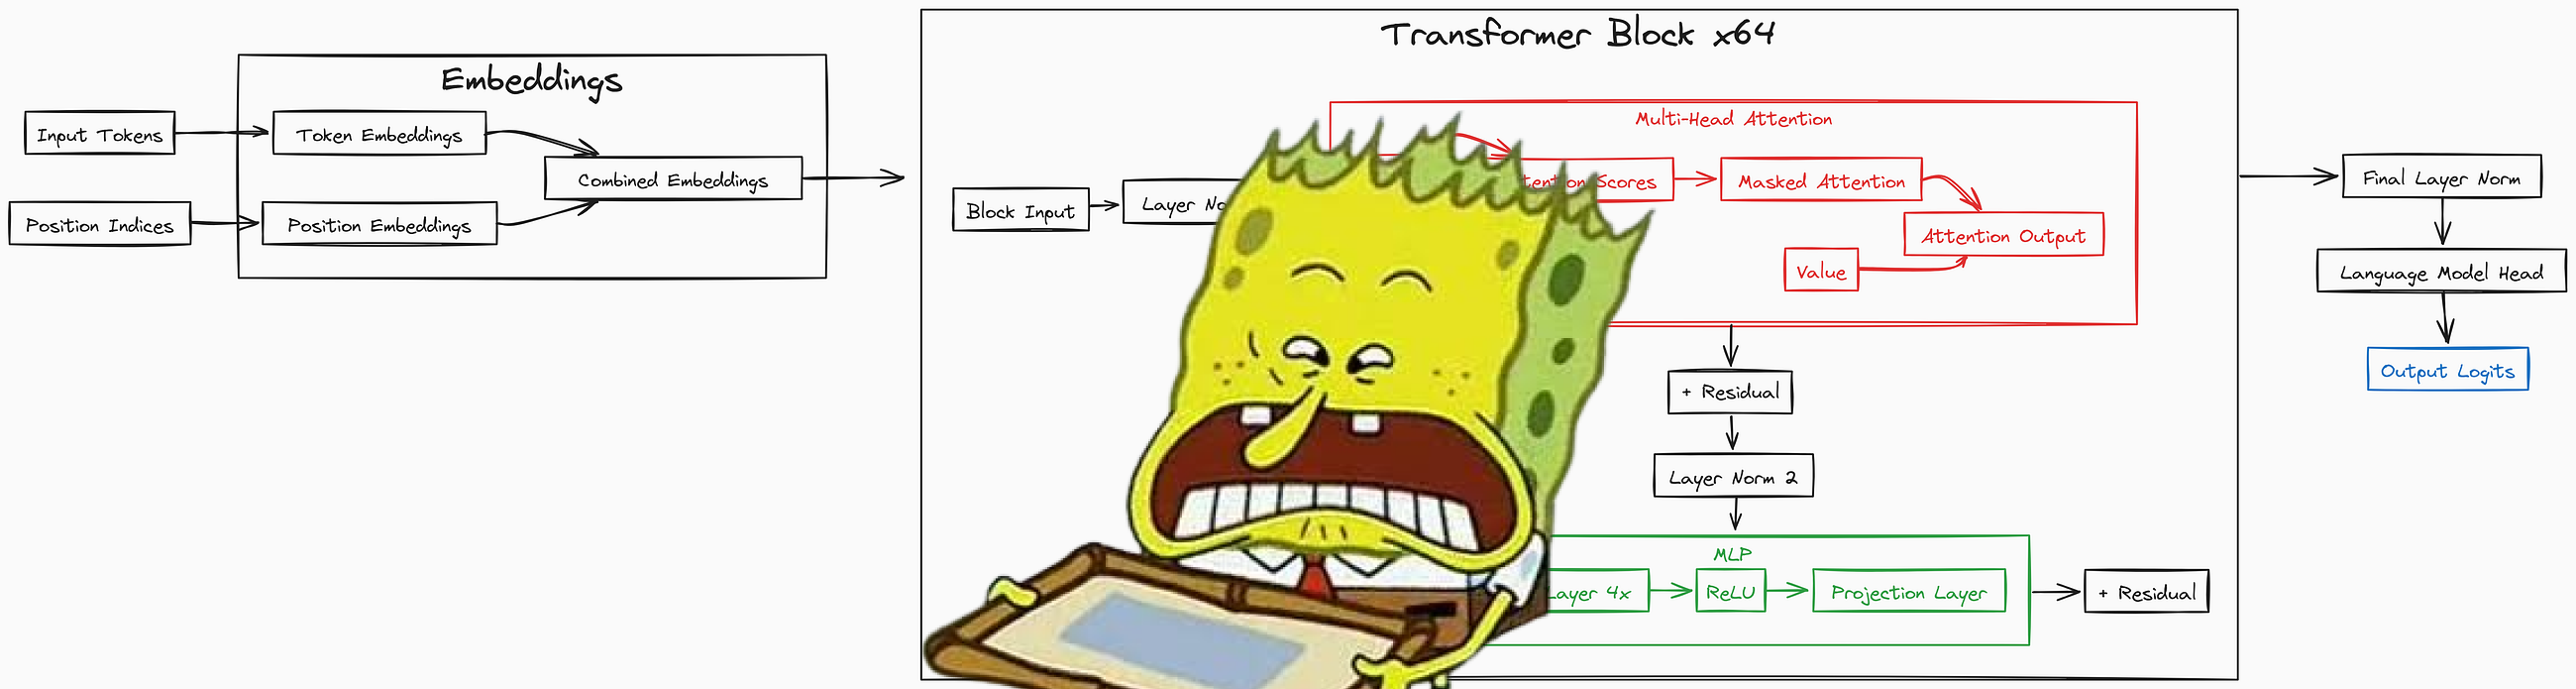
train-llm-from-scratch
FareedKhan-dev/train-llm-from-scratch · ★ 12.3KA from-scratch tutorial and codebase for training your own LLM end to end: tokenizing raw text, pretraining a GPT-style Transformer, and then post-training it with SFT, a reward model, DPO/ORPO/KTO, PPO and GRPO into an aligned, reasoning-style assistant.
 +63
LLMs-from-scratch
rasbt/LLMs-from-scratch · ★ 106.8KThis is the official code repository for the book 'Build a Large Language Model (From Scratch)', which teaches you to implement a GPT-like LLM in PyTorch step by step, from tokenization through pretraining and finetuning.
 +37
nanochat
karpathy/nanochat · ★ 58.8KA minimal, hackable harness for training your own LLM end to end (tokenization, pretraining, finetuning, evaluation, inference) on a single GPU node, ending in a chatbot you talk to over a CLI.
 +36
unsloth
unslothai/unsloth · ★ 78.2KUnsloth is a local-first app for running and training LLMs, diffusion, TTS and embedding models on your own machine, including models like Qwen3.8, DeepSeek-V4, MiniMax-H3, Gemma 4 and FLUX.
The all-time top
15 projects · by stars
- 106.8K#1 · rasbt/LLMs-from-scratch
LLMs-from-scratch
This is the official code repository for the book 'Build a Large Language Model (From Scratch)', which teaches you to implement a GPT-like LLM in PyTorch step by step, from tokenization through pretraining and finetuning.
- 78.2K#2 · unslothai/unsloth
unsloth
Unsloth is a local-first app for running and training LLMs, diffusion, TTS and embedding models on your own machine, including models like Qwen3.8, DeepSeek-V4, MiniMax-H3, Gemma 4 and FLUX.
- 58.8K#3 · karpathy/nanochat
nanochat
A minimal, hackable harness for training your own LLM end to end (tokenization, pretraining, finetuning, evaluation, inference) on a single GPU node, ending in a chatbot you talk to over a CLI.
- 4

llm.c
31.2Kkarpathy/llm.c · Cudallm.c is Karpathy's project for training large language models in raw C and CUDA, with no dependency on 245MB of PyTorch or 107MB of cPython. It currently focuses on pretraining GPT-2 and GPT-3-scale models, with train_gpt2.cu as the main CUDA training path.
- 5
Chinese-LLaMA-Alpaca
18.9Kymcui/Chinese-LLaMA-Alpaca · PythonOpen-source Chinese LLaMA and Alpaca large language models. The base LLaMA was extended with a Chinese vocabulary and further pre-trained on Chinese data, and Alpaca versions were instruction-tuned on Chinese instructions; training and deployment scripts are open too.
- 6

gpt-3
15.7Kopenai/gpt-3The official companion repo for the GPT-3 paper 'Language Models are Few-Shot Learners'. GPT-3 is an autoregressive language model with 175 billion parameters — 10x more than any previous non-sparse model — tested on few-shot learning across many NLP tasks.
- 7
Llama-Chinese
14.8KLlamaChinese/Llama-Chinese · PythonLlama-Chinese is a Chinese-language community project built around Meta's Llama models (Llama2, Llama3, Llama4). It provides Chinese pretraining and fine-tuning, a custom Atom model series optimized for Chinese, and resources for training, deploying and using Llama in Chinese for free commercial use.
- 8

dinov2
13.4Kfacebookresearch/dinov2 · Jupyter NotebookDINOv2, a self-supervised visual feature learning method from Meta AI's FAIR team, shipped as PyTorch code and pretrained models. Its features plug into classifiers as simple as linear layers across many vision tasks, with no fine-tuning required.
- 9
PaddleFormers
13KPaddlePaddle/PaddleFormers · PythonPaddleFormers is a Transformers-style library built on Baidu's PaddlePaddle deep learning framework, giving the PaddlePaddle ecosystem the same kind of model interface and training workflow as Hugging Face Transformers, with full training support for 100+ LLMs and vision-language models.
- 10
train-llm-from-scratch
12.3KFareedKhan-dev/train-llm-from-scratch · PythonA from-scratch tutorial and codebase for training your own LLM end to end: tokenizing raw text, pretraining a GPT-style Transformer, and then post-training it with SFT, a reward model, DPO/ORPO/KTO, PPO and GRPO into an aligned, reasoning-style assistant.
- 11
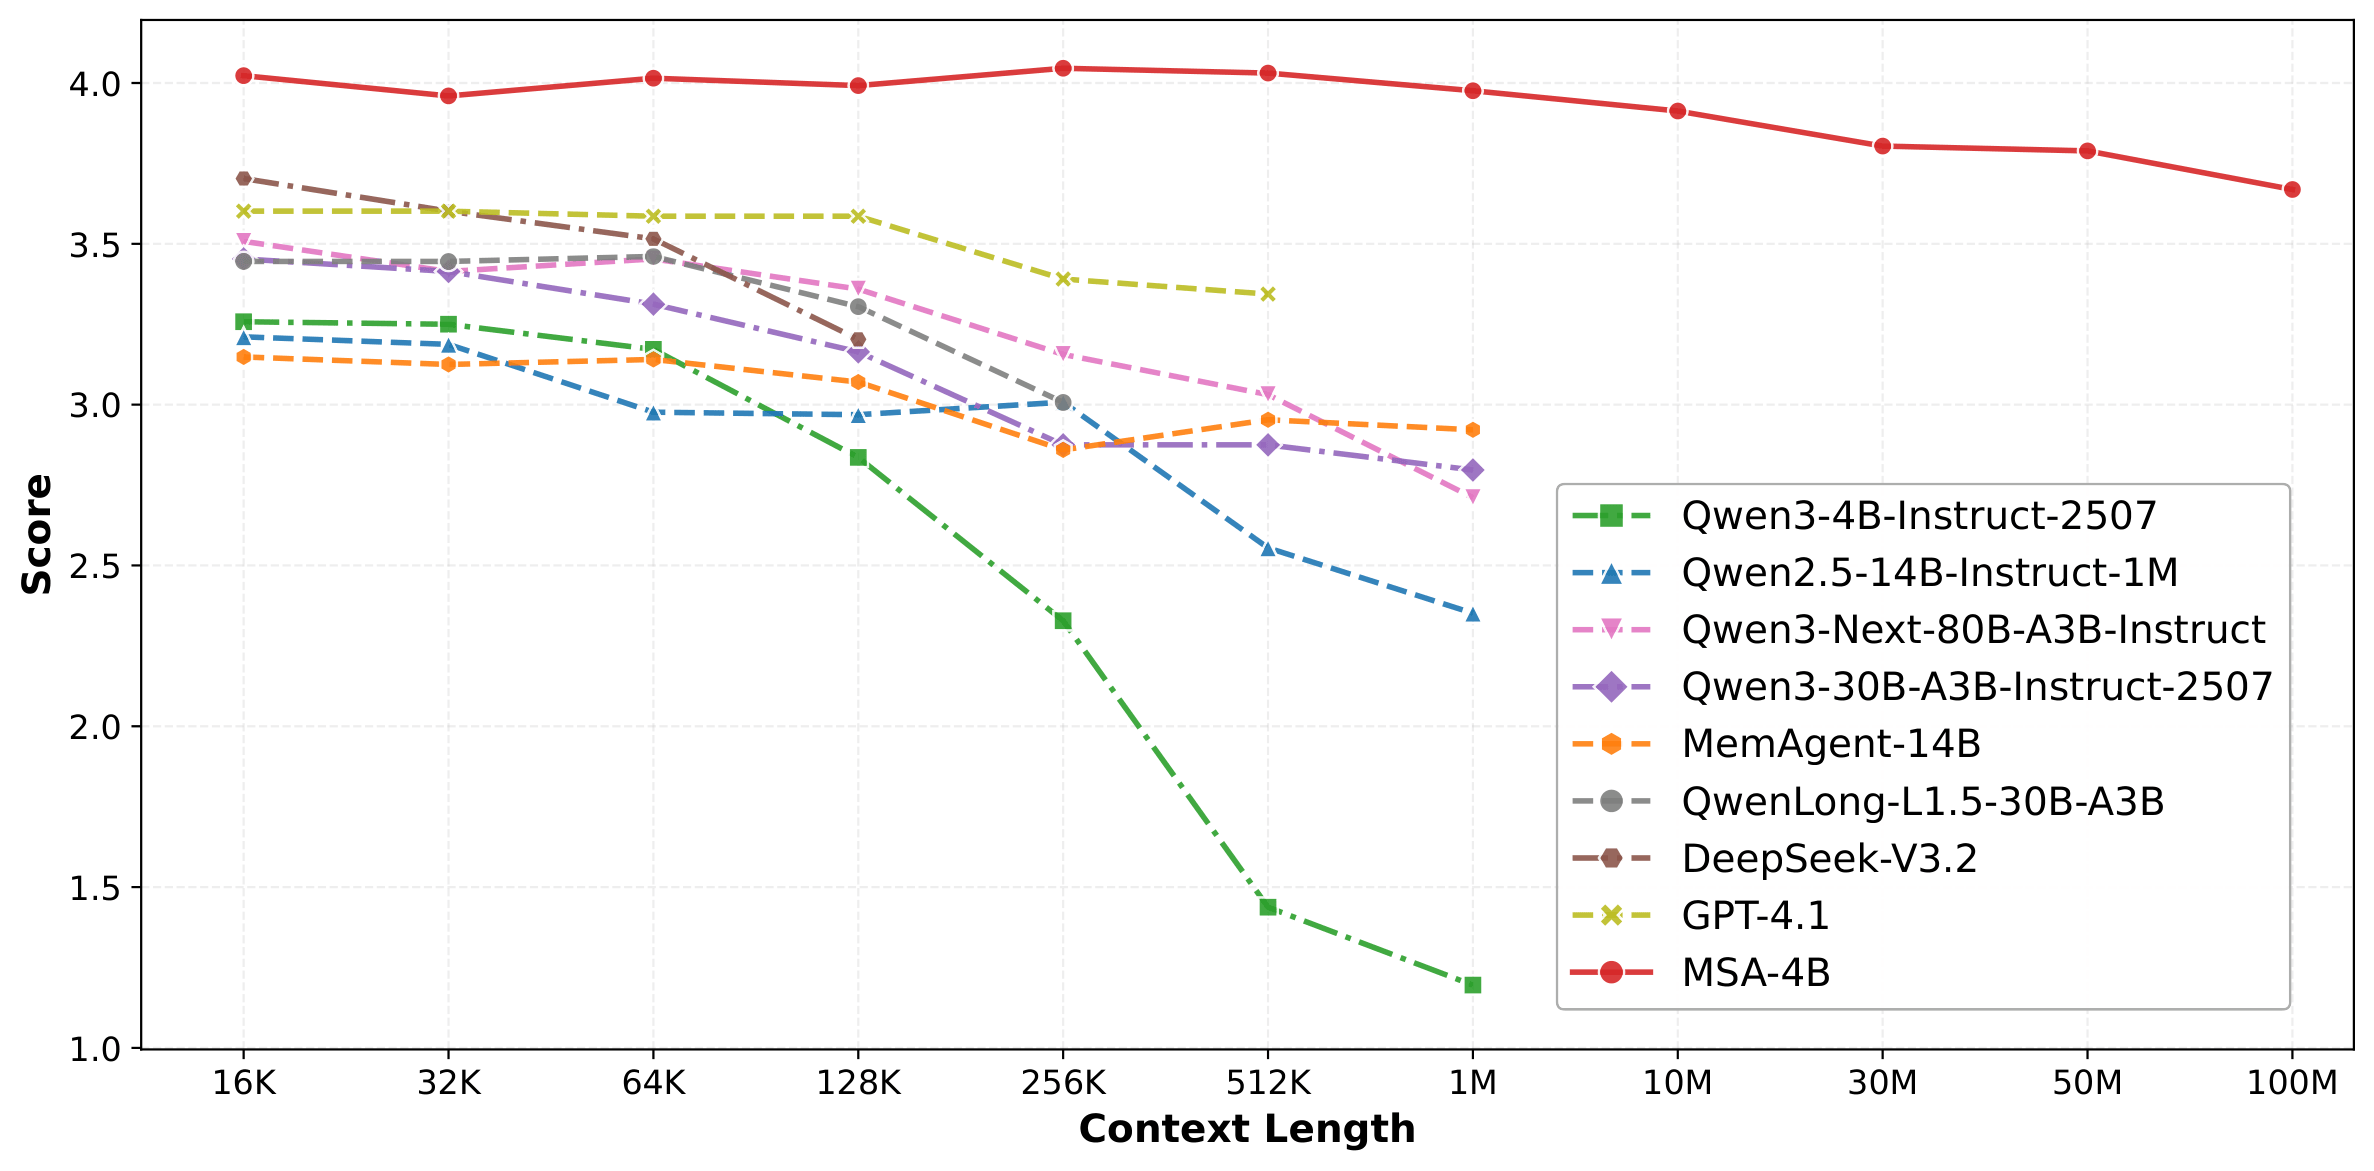
MSA
3.5KEverMind-AI/MSA · PythonMSA (Memory Sparse Attention) is an end-to-end trainable, scalable latent-memory framework that lets LLMs handle context windows up to 100M tokens, replacing RAG or fixed-size RNN-style memory with a differentiable sparse-attention memory bank.
- 12
OpenWAM
1.1KOpenWAM-Official/OpenWAM · PythonOpenWAM is an open research stack for systematically building World-Action Models (WAMs) for robots, breaking the usual tightly-coupled design choices into modular, swappable components you can compare in controlled experiments.
- 13
LoongForge
694baidu-baige/LoongForge · PythonAn open-source training framework from Baidu's Baige team for LLMs, VLMs, diffusion and embodied models, built for faster training and lower cost on NVIDIA GPUs and Kunlun XPUs.
- 14
Motus2
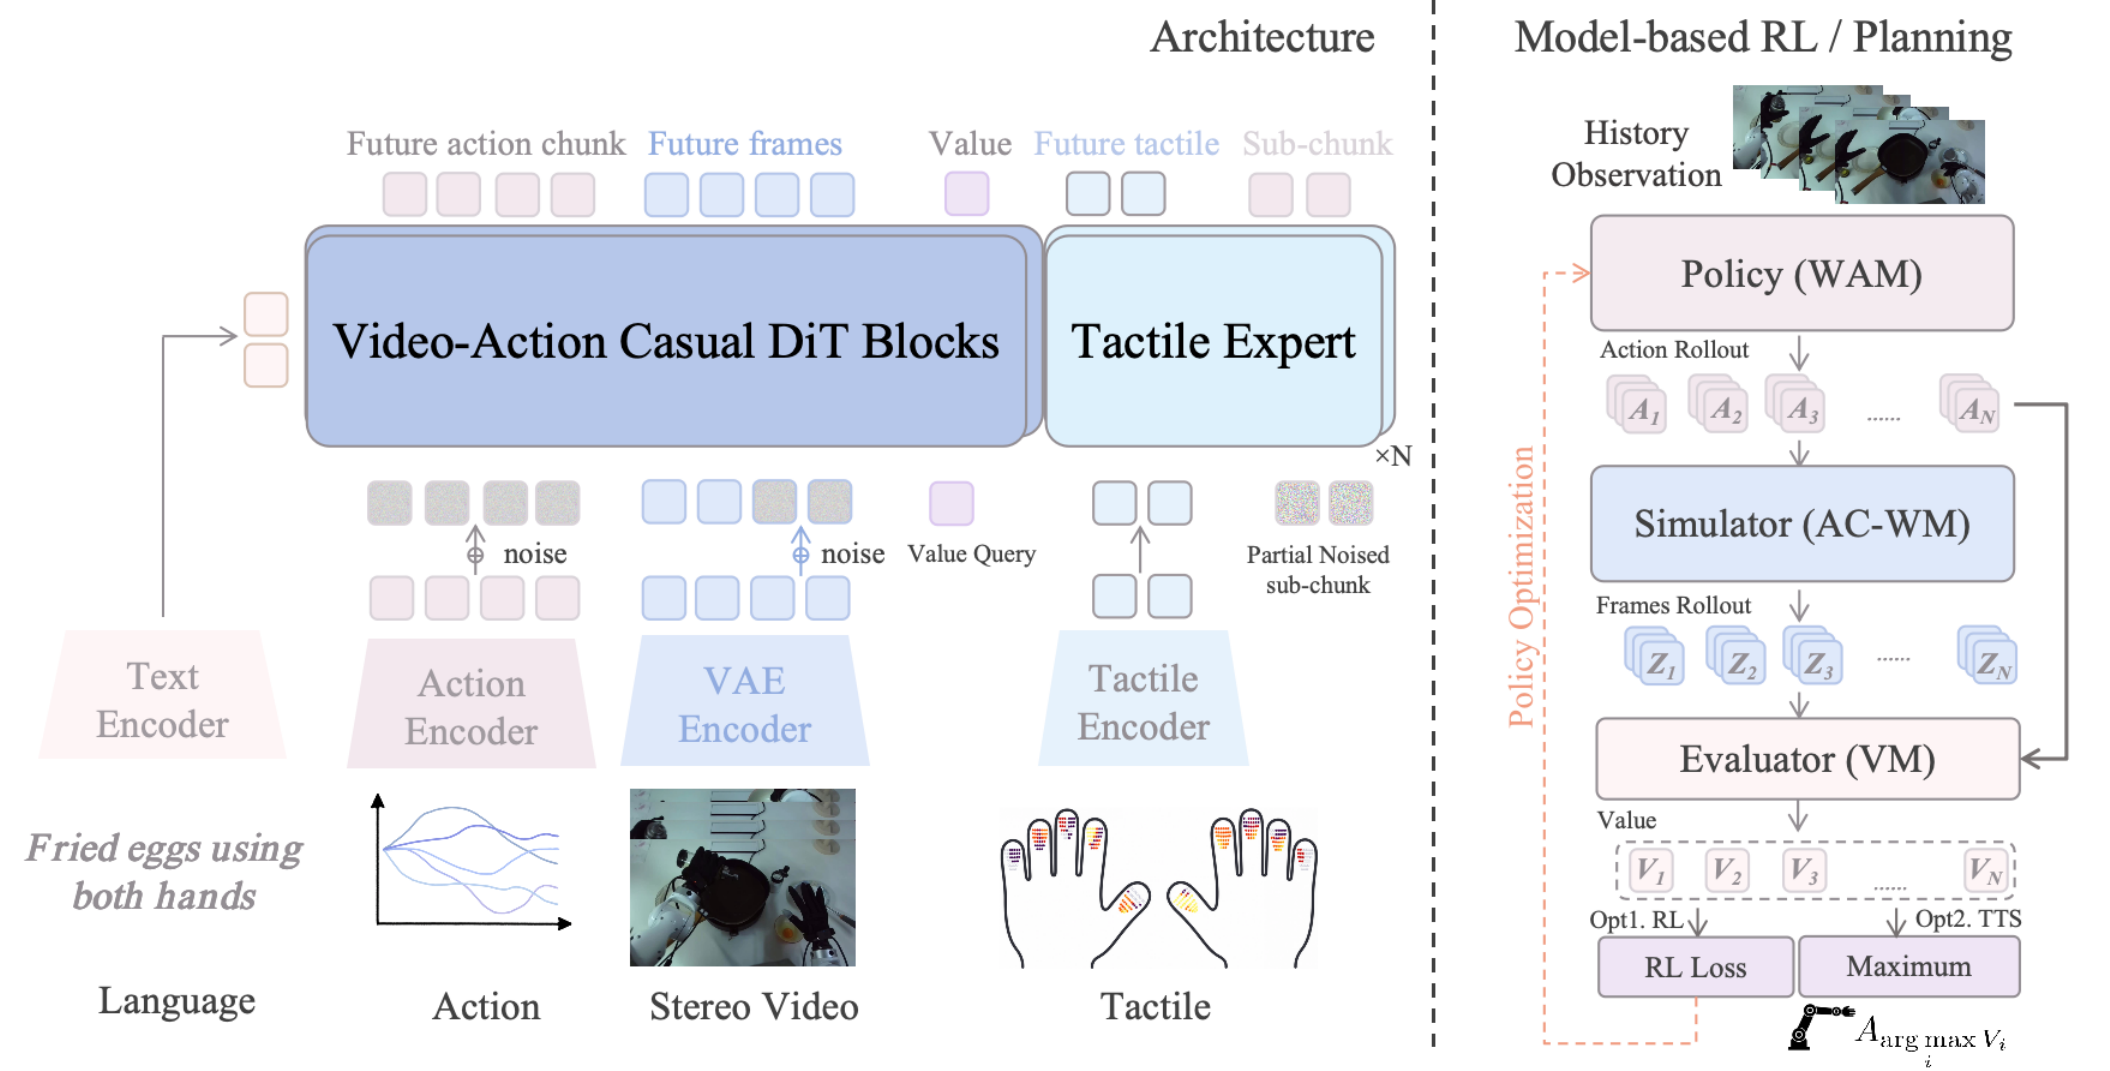
668shengshu-ai/Motus2Motus2 is a self-evolving general world model for dexterous robot manipulation. A single model with shared weights acts as a policy, a simulator, and an evaluator, coupling them into a closed decision-and-learning loop so the system can perceive, predict, act, and improve itself.
- 15
manaca-1b-base
249Instituto-IA-LNCC/manaca-1b-base · PythonAn open ~1.72B-parameter language model trained from scratch for Brazilian Portuguese. The repo holds the whole reproducible pipeline: Docker environment, corpus pipeline, tokenizer training, Megatron-LM pretraining, and a Portuguese benchmark suite.
Related topics
Often tagged together
- deep-learning746
- gpu809
- llm1,516
- python2,425
- research779
- machine-learning930
- fine-tuning188
- huggingface367
- large-language-models218
- ai1,993
- cuda401
- linux4,248
- open-source5,749
- pytorch421
- transformer214
- nvidia339
- academic-research220
- apache-2.01,452
- lora89
- nlp216
- training91
- artificial-intelligence272
- attention-mechanism54
- benchmark444