Topics / #generative-model
Generative-model projects on GitHub
Generative models like diffusion networks and image animation.
As of , the most-starred Generative-model projects on GitHub are first-order-model (15K stars), Awesome-Diffusion-Models (12.4K stars) and Open-Sora-Plan (12.2K stars). GitHub.Locker tracks 9 Generative-model repositories with 64.6K stars combined. The fastest-growing on October 16 was TRELLIS.2, with +26 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +26
TRELLIS.2
microsoft/TRELLIS.2 · ★ 12.1KTRELLIS.2 is a 4-billion-parameter 3D generative model for high-fidelity image-to-3D generation, using a novel field-free sparse voxel representation (O-Voxel) to produce assets with complex topology and full PBR materials.
 +3
MiniMax-Music3
MiniMax-AI/MiniMax-Music3 · ★ 961MiniMax Music 3 is a music generation model that creates complete songs up to five minutes long from lyrics and a music description, producing 32 kHz 16-bit stereo WAV audio with coherent structure and expressive vocals.
The all-time top
9 projects · by stars
- 15K
 #1 · AliaksandrSiarohin/first-order-model
first-order-model
This is the official source code for the 'First Order Motion Model for Image Animation' paper: it animates a static source image by transferring motion from a driving video, using self-learned keypoints instead of manual annotations.
- 12.4K
 #2 · diff-usion/Awesome-Diffusion-Models
Awesome-Diffusion-Models
A curated collection of papers and resources on Diffusion Models, covering theory, applications, and related research.
- 12.2K
#3 · PKU-YuanGroup/Open-Sora-Plan
Open-Sora-Plan
Open-Sora Plan is an open-source community project that aims to reproduce OpenAI's Sora text-to-video model, led by a PKU-affiliated AIGC lab with contributions from Huawei and Pengcheng Lab.
- 4
TRELLIS.2
12.1Kmicrosoft/TRELLIS.2 · PythonTRELLIS.2 is a 4-billion-parameter 3D generative model for high-fidelity image-to-3D generation, using a novel field-free sparse voxel representation (O-Voxel) to produce assets with complex topology and full PBR materials.
- 5
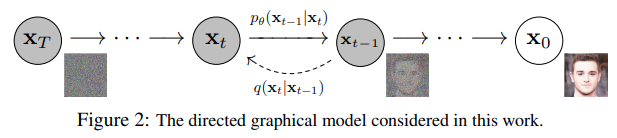
denoising-diffusion-pytorch
10.7Klucidrains/denoising-diffusion-pytorch · PythonA PyTorch implementation of the Denoising Diffusion Probabilistic Model (DDPM), a generative modeling approach the author positions as a possible rival to GANs.
- 6
MiniMax-Music3
961MiniMax-AI/MiniMax-Music3MiniMax Music 3 is a music generation model that creates complete songs up to five minutes long from lyrics and a music description, producing 32 kHz 16-bit stereo WAV audio with coherent structure and expressive vocals.
- 7
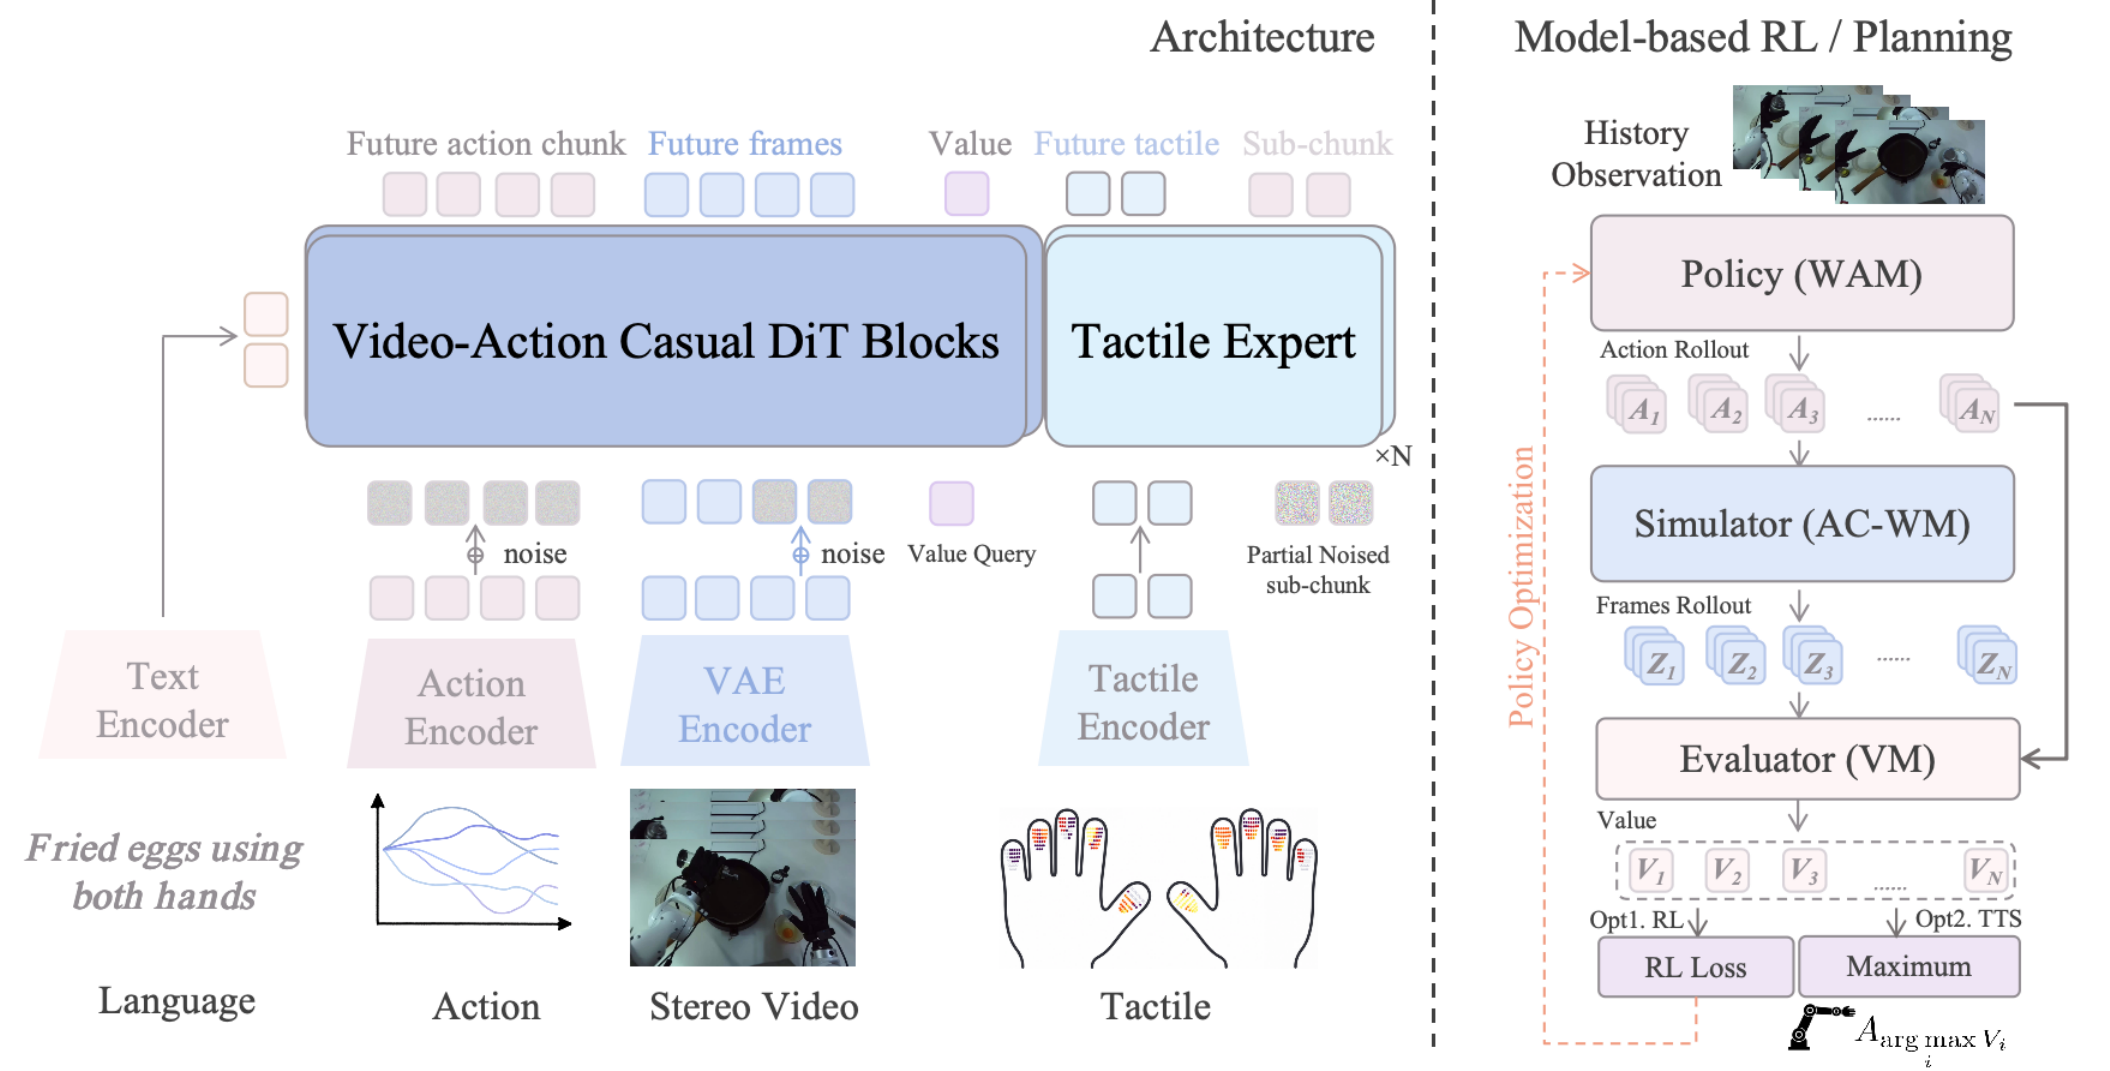
Motus2
685shengshu-ai/Motus2Motus2 is a self-evolving general world model for dexterous robot manipulation. A single model with shared weights acts as a policy, a simulator, and an evaluator, coupling them into a closed decision-and-learning loop so the system can perceive, predict, act, and improve itself.
- 8
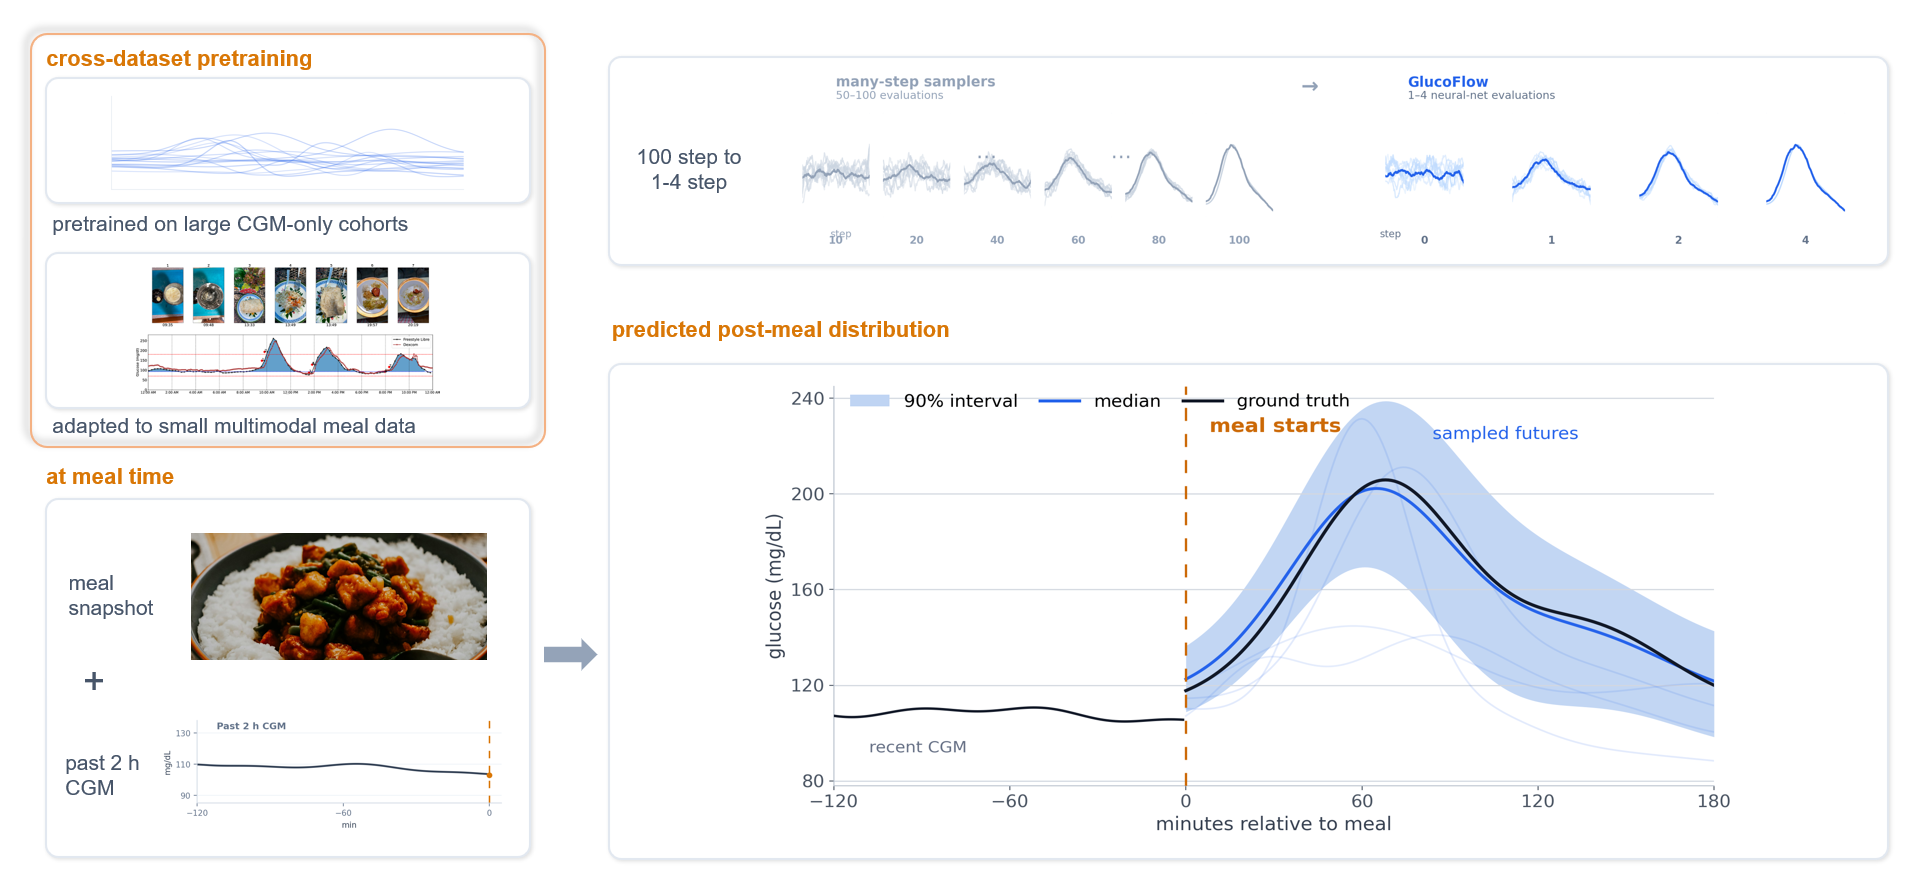
Few-step-probabilistic-glucose-forecasting-from-continuous-glucose-monitoring-and-meal-images
397OliverDOU776/Few-step-probabilistic-glucose-forecasting-from-continuous-glucose-monitoring-and-meal-images · PythonGlucoFlow is research code for probabilistic glucose forecasting: it generates full future trajectories (medians, intervals, event probabilities) in just 1-4 sampling steps using a conditional rectified-flow model, optionally conditioned on meal photos or other side information.
- 9
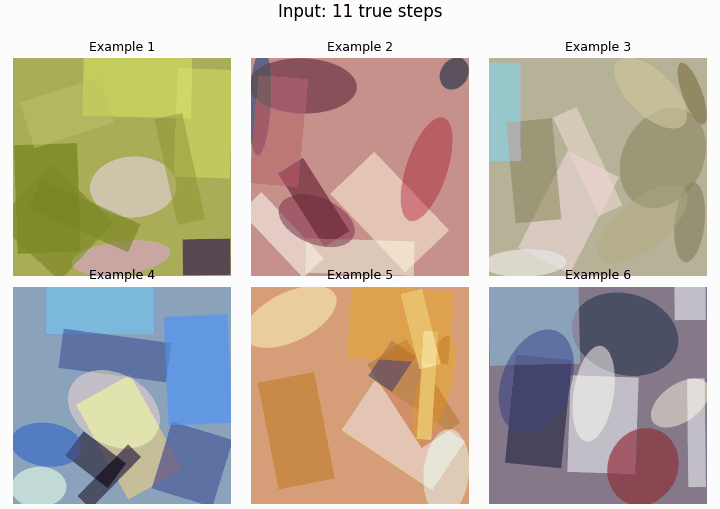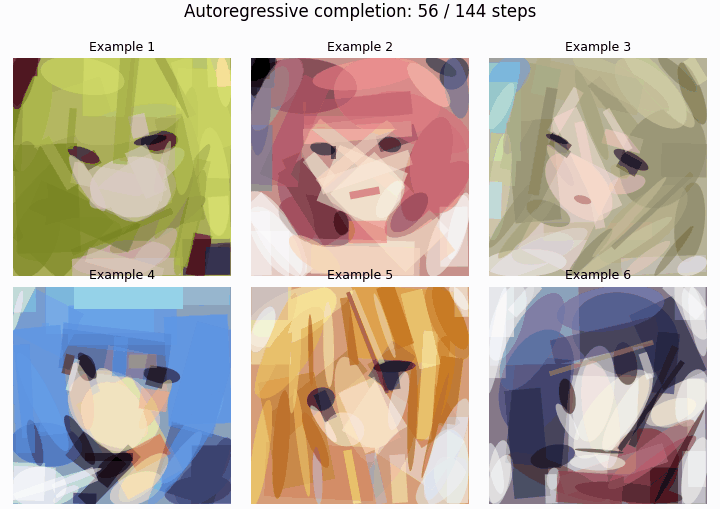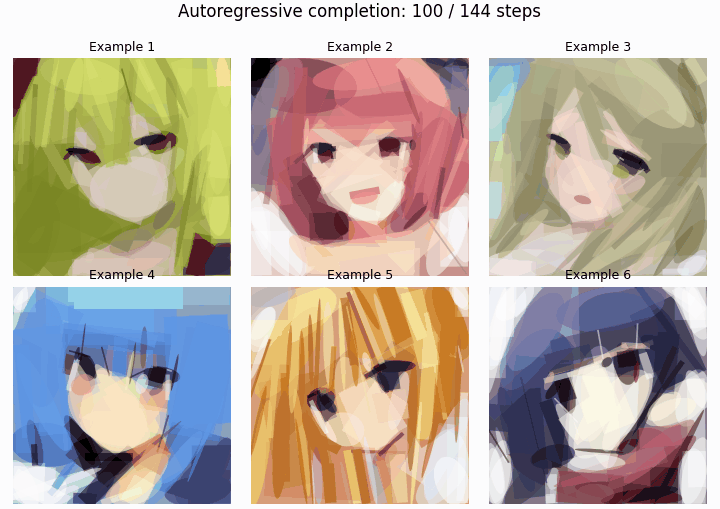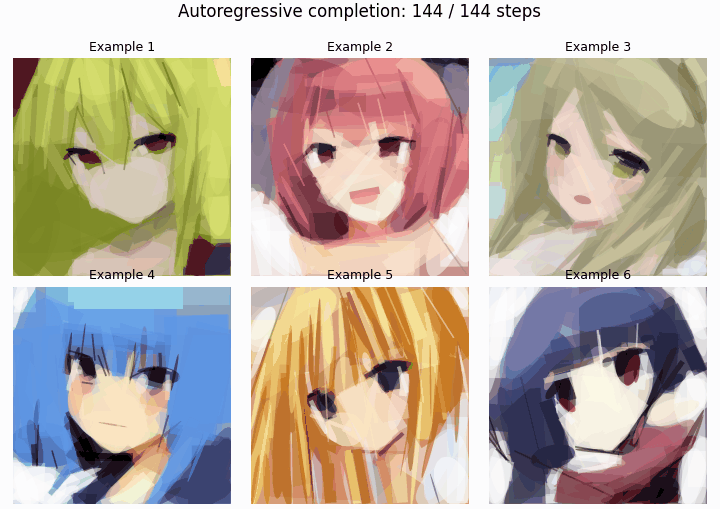
primitive-operation-painter
227wonderfulearth/primitive-operation-painter · PythonAn autoregressive image generator that builds pictures as a sequence of primitive drawing operations (background, ellipses, rotated rectangles) instead of pixels, so the drawing process stays inspectable and editable step by step.
Related topics
Often tagged together
- deep-learning737
- research764
- gpu789
- machine-learning916
- python2,383
- academic-research209
- artificial-intelligence267
- computer-vision384
- generative-ai339
- mit3,312
- transformer212
- ai1,955
- pytorch419
- diffusion-models80
- image-generation225
- nvidia328
- open-source5,666
- training91
- china414
- cuda396
- image-to-video46
- linux4,184
- multimodal189
- pretrained-models74