Topics / #gemma
Gemma projects on GitHub
Googles Gemma family of open-weight language models and fine-tuning tools.
As of , the most-starred Gemma projects on GitHub are ollama (183.7K stars), transformers (167.8K stars) and unsloth (78.2K stars). GitHub.Locker tracks 16 Gemma repositories with 577.9K stars combined. The fastest-growing on October 17 was DigUp, with +262 stars in a day.
Hot right now
Most stars gained in a day · Oct 17
 +262
DigUp
ARahim3/DigUp · ★ 4.8KDigUp is a free, open-source macOS menu bar app that lets you search the files on your Mac by what's actually in them — photos, PDFs, documents, recordings, videos and code — using Google DeepMind's EmbeddingGemma 2 model running entirely on-device.
 +162
ollama
ollama/ollama · ★ 183.7KOllama is a tool for downloading and running open large language models like DeepSeek, Qwen, Gemma, Llama, Mistral and gpt-oss on your own machine, with a simple CLI and a local REST API.
 +67
unsloth
unslothai/unsloth · ★ 78.2KUnsloth is a local-first app for running and training LLMs, diffusion, TTS and embedding models on your own machine, including models like Qwen3.8, DeepSeek-V4, MiniMax-H3, Gemma 4 and FLUX.
 +31
transformers
huggingface/transformers · ★ 167.8KTransformers is Hugging Face's model-definition framework for state-of-the-art machine learning models across text, vision, audio, video, and multimodal tasks, usable for both inference and training.
The all-time top
16 projects · by stars
- 183.7K#1 · ollama/ollama
ollama
Ollama is a tool for downloading and running open large language models like DeepSeek, Qwen, Gemma, Llama, Mistral and gpt-oss on your own machine, with a simple CLI and a local REST API.
- 167.8K#2 · huggingface/transformers
transformers
Transformers is Hugging Face's model-definition framework for state-of-the-art machine learning models across text, vision, audio, video, and multimodal tasks, usable for both inference and training.
- 78.2K#3 · unslothai/unsloth
unsloth
Unsloth is a local-first app for running and training LLMs, diffusion, TTS and embedding models on your own machine, including models like Qwen3.8, DeepSeek-V4, MiniMax-H3, Gemma 4 and FLUX.
- 4
LlamaFactory
75.5Khiyouga/LlamaFactory · PythonLlamaFactory unifies efficient fine-tuning of 100+ large language models and vision-language models in one Python toolkit, published as an ACL 2024 paper.
- 5
self-llm
32.5Kdatawhalechina/self-llm · Jupyter NotebookSelf-llm is a Chinese-language tutorial collection that teaches beginners how to configure environments, deploy, and fine-tune (full-parameter or LoRA) 50+ open-source large language models and multimodal models on Linux.
- 6
ChuanhuChatGPT
15.3KGaiZhenbiao/ChuanhuChatGPT · PythonChuanhuChatGPT is a web-based GUI for ChatGPT and many other LLMs, adding extras like agents, file-based Q&A, local model deployment, web search, and GPT fine-tuning on top of a Gradio interface.
- 7
turbo-fieldfare
6.9Kdrumih/turbo-fieldfare · SwiftTurboFieldfare is a custom Swift and Metal runtime that runs the instruction-tuned Gemma 4 26B-A4B model on Apple Silicon Macs using only about 2 GB of RAM, even on 8 GB machines, by streaming only the experts needed for each token from SSD instead of loading the full 14.3 GB model.
- 8
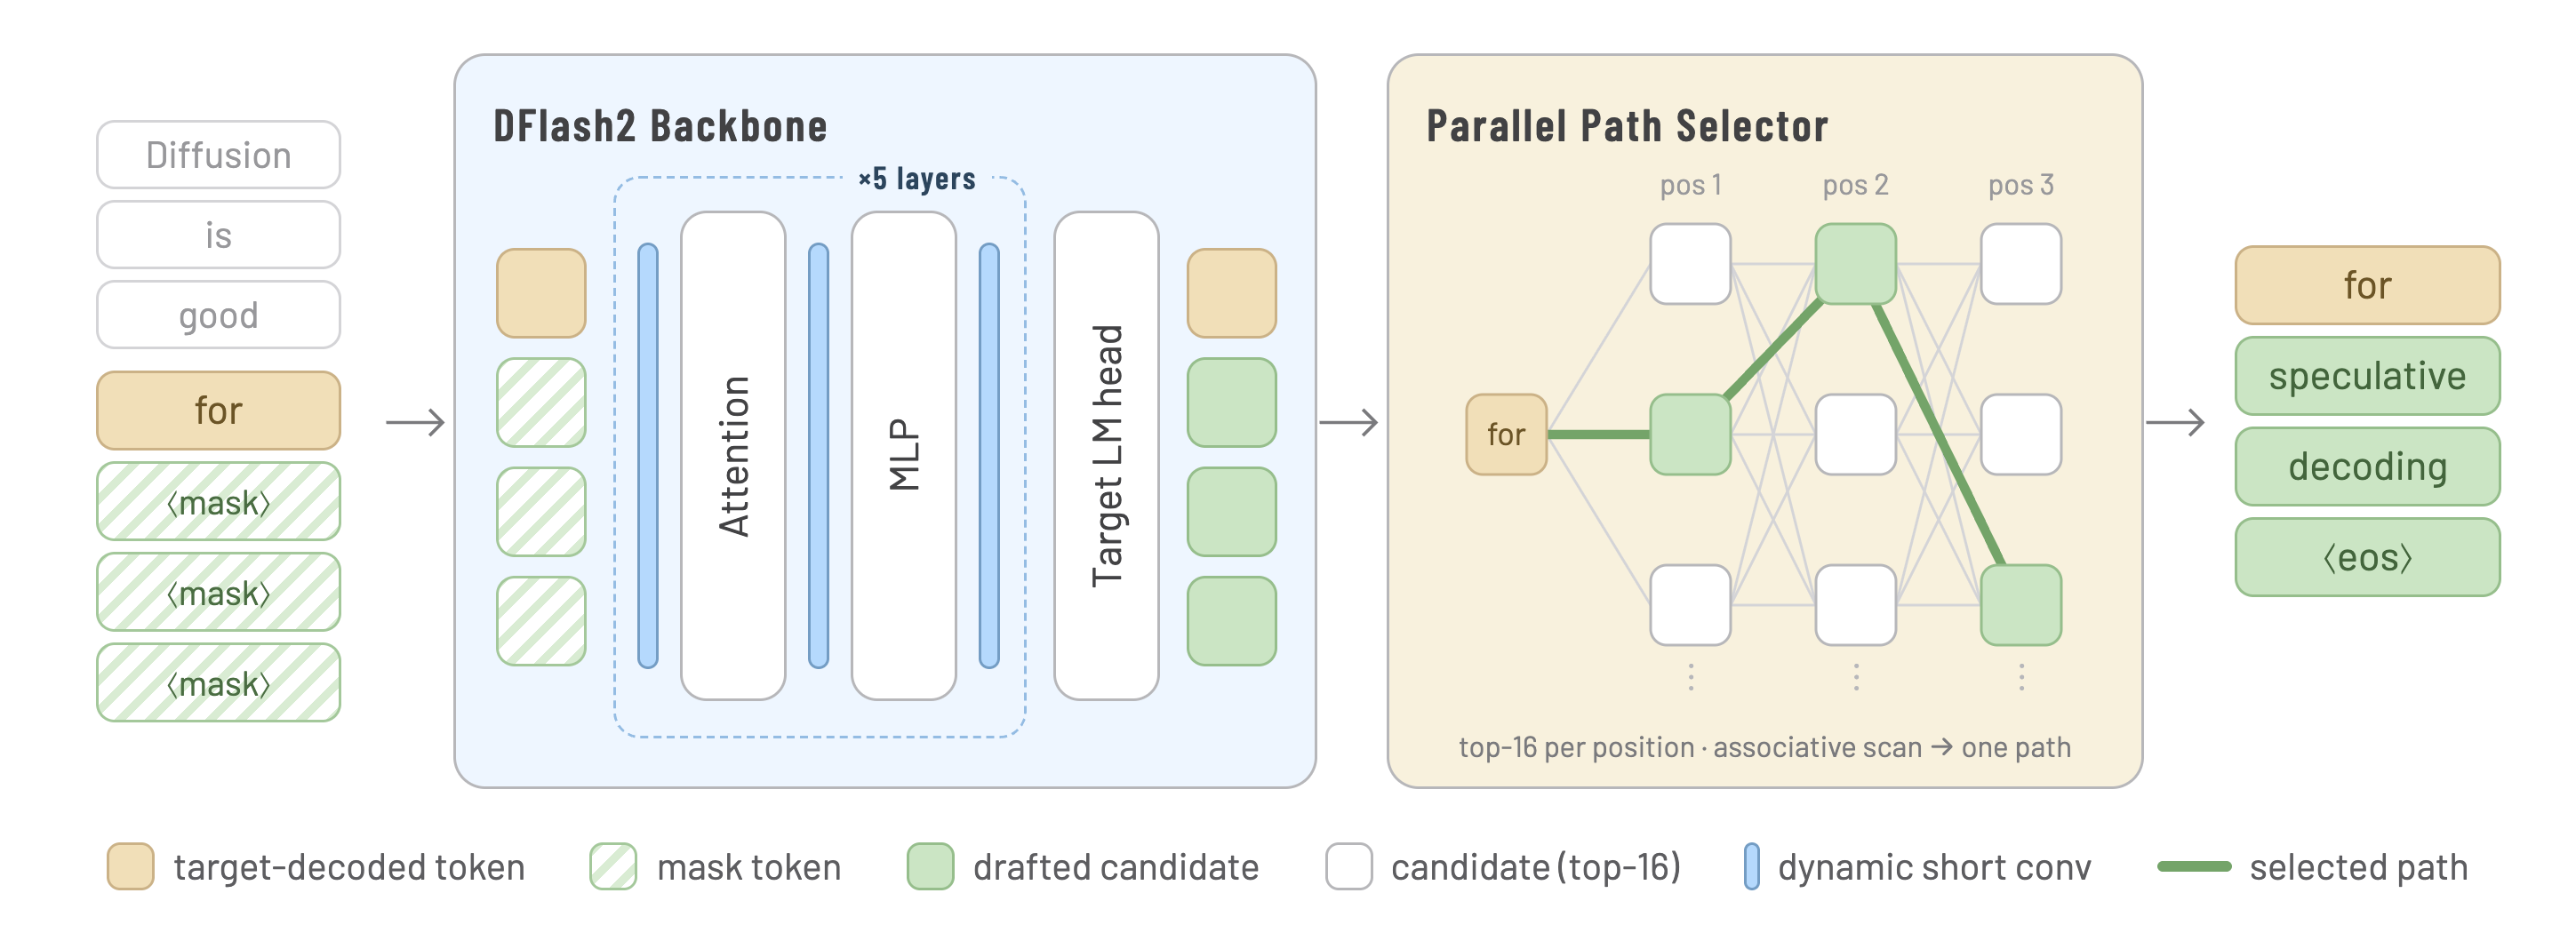
dflash
6.2Kz-lab/dflash · PythonDFlash is a lightweight block diffusion model built for speculative decoding, drafting tokens in parallel blocks so a larger target LLM can verify them faster than generating one token at a time.
- 9
DigUp
4.8KARahim3/DigUp · SwiftDigUp is a free, open-source macOS menu bar app that lets you search the files on your Mac by what's actually in them — photos, PDFs, documents, recordings, videos and code — using Google DeepMind's EmbeddingGemma 2 model running entirely on-device.
- 10
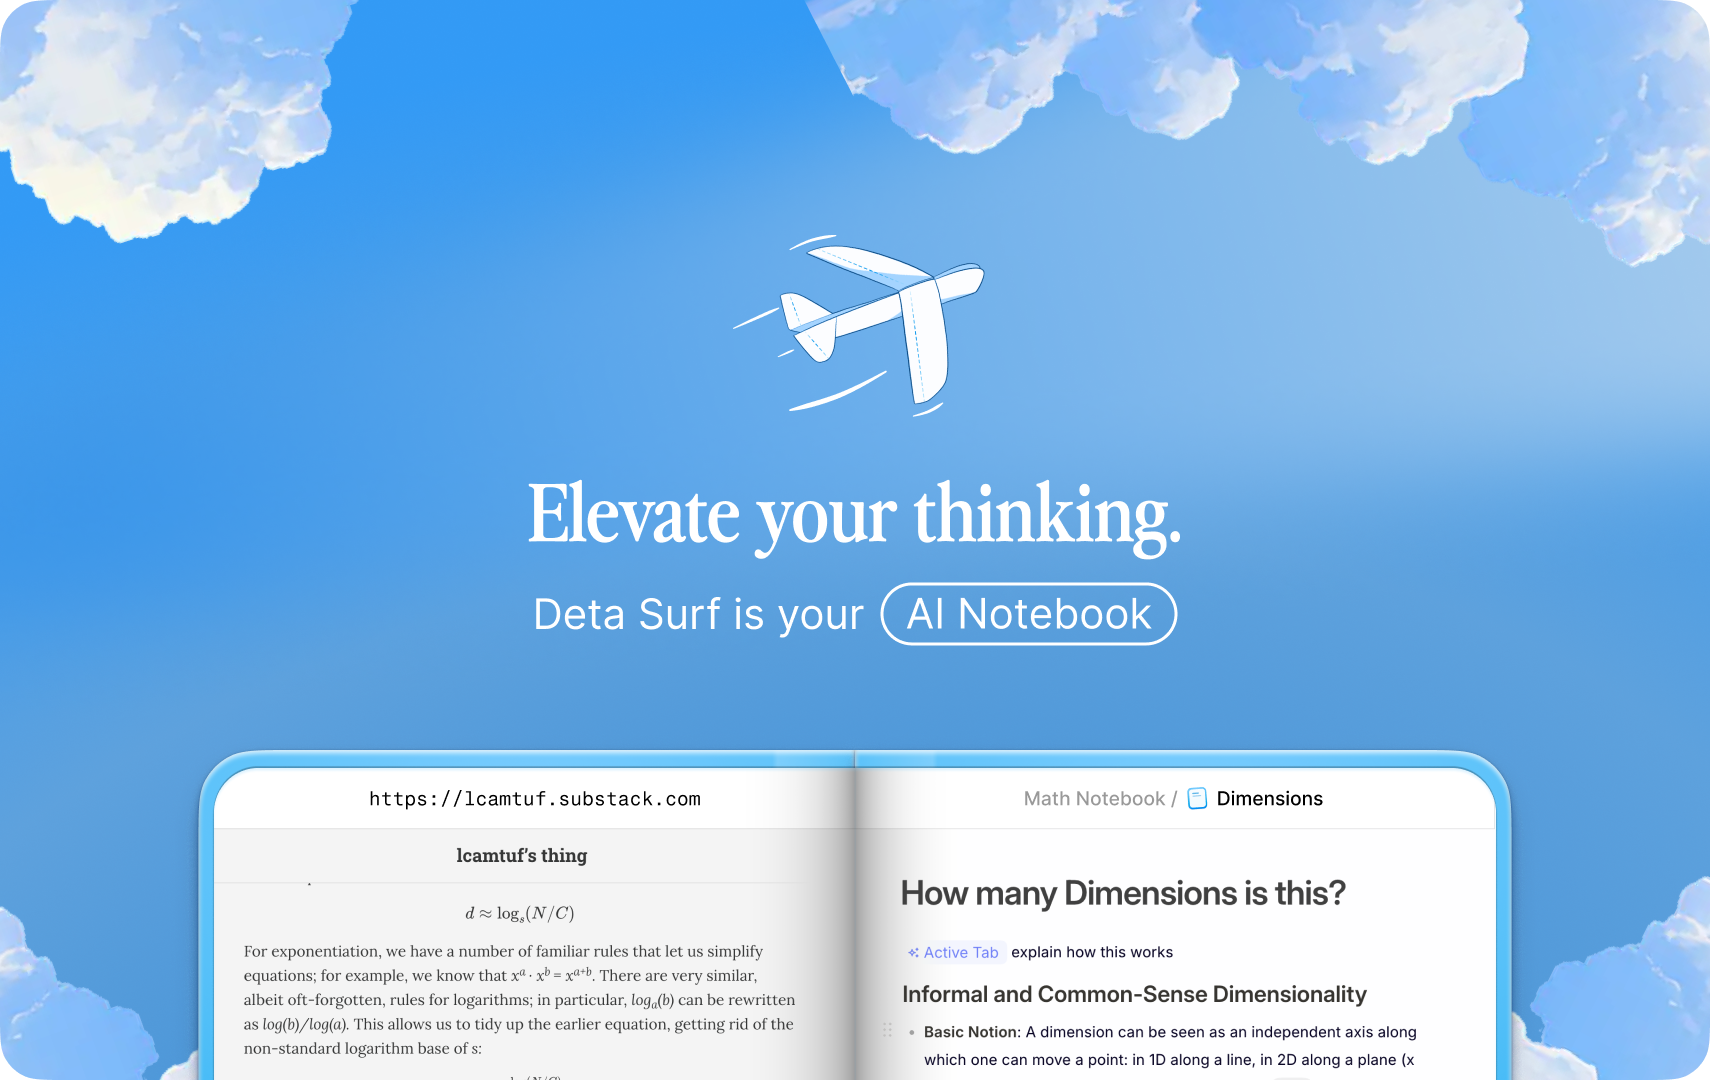
surf
3.6Kdeta/surf · TypeScriptDeta Surf is a personal AI notebook that brings your files and webpages into one place and lets you generate AI-written notes from them, so research and writing happen in the same stream instead of jumping between apps.
- 11
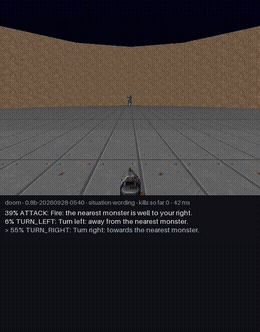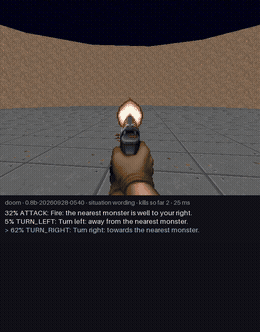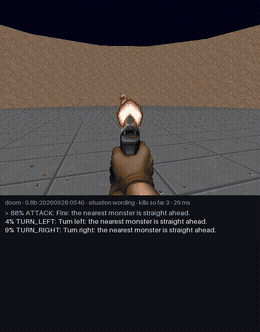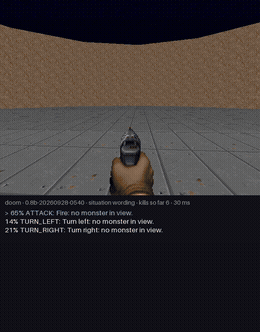
jeff
1.5Kfirelex/jeff · PythonJeff is a family of small (0.8B-2B parameter) open-weight models fine-tuned from Qwen3.5 and Gemma 4 that act as fast 'System 1' decision-makers: you describe a situation and a list of options in plain text, and Jeff returns a calibrated probability for each option from a single forward pass, with no generated text to parse.
- 12

localjev
827githubnext/localjev · TypeScriptLocalJev is a local TypeScript/Bun server that implements a Jev-compatible POST /v1/systemone decision API, backed by the DiffusionGemma model through an OpenAI-compatible Chat Completions endpoint. It lets Jev clients run against a local open model instead of OpenJev's hosted service.
- 13

OpenArch
426anuj0456/OpenArch · PythonA set of hand-written PyTorch implementations of modern open-source LLM architectures (Llama, Qwen, DeepSeek, Gemma, GPT-OSS, Kimi and more), written from scratch for readability and learning.
- 14

MoE4All
304Headmaster218/MoE4All · RustMoE4All is a portable Windows app that runs large Mixture-of-Experts (MoE) LLMs beyond what fits in VRAM by streaming expert weights between GPU VRAM, system RAM and SSD, built on a Vulkan-first Rust inference engine so consumer AMD (and other Vulkan) GPUs can run huge models locally.
- 15

gemma4.c
176qmog-ai/gemma4.c · Cgemma4.c is a CPU inference runtime for Google's Gemma 4 E2B model written in about 700 lines of pure C, built to show how LLM inference actually works under the hood.
- 16
open-jev
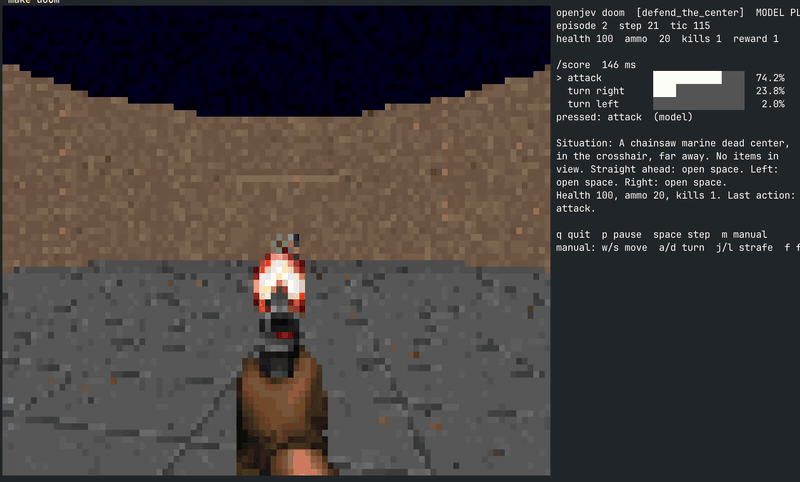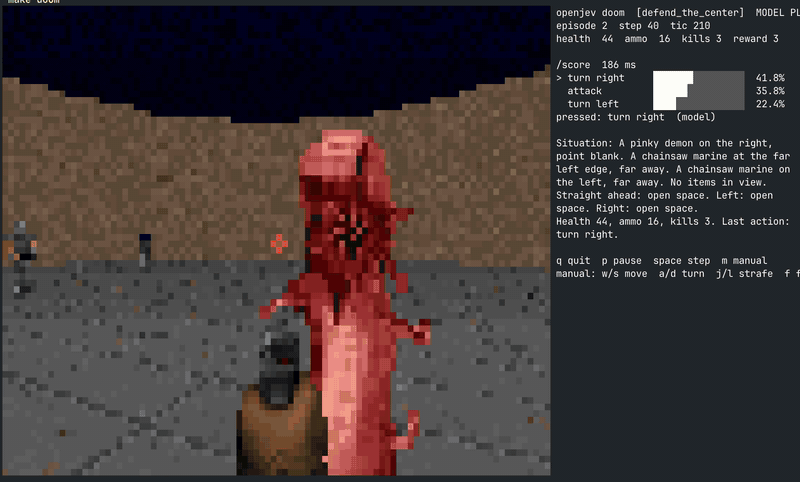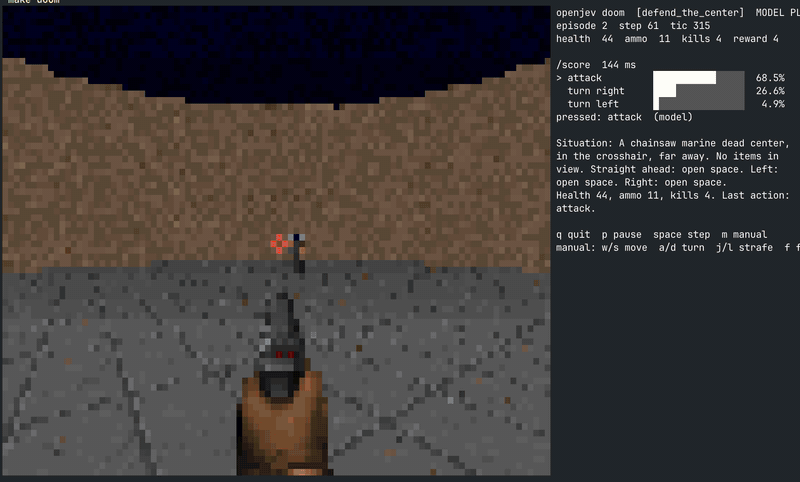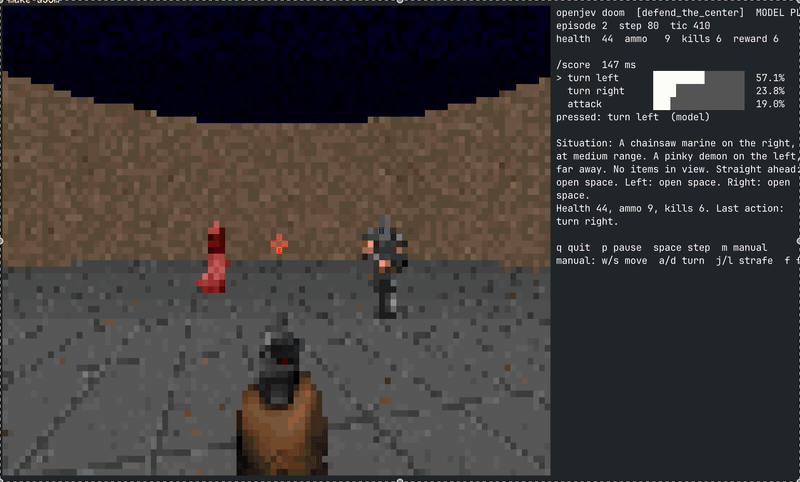
134daseinlabs/open-jev · PythonAn open implementation of Jev: a local Gemma 3 4B (via MLX) scores a list of pre-written options against a context in one batched forward pass on Apple silicon — no text generation, just log-probabilities per option.
Related topics
Often tagged together