Topics / #natural-language-processing
Natural-language-processing projects on GitHub
Spelled-out variant of the NLP topic for language understanding and generation tasks.
As of , the most-starred Natural-language-processing projects on GitHub are transformers (167.8K stars), LLMs-from-scratch (106.7K stars) and ML-For-Beginners (91.5K stars). GitHub.Locker tracks 96 Natural-language-processing repositories with 2.3M stars combined. The fastest-growing on October 16 was LLMs-from-scratch, with +65 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
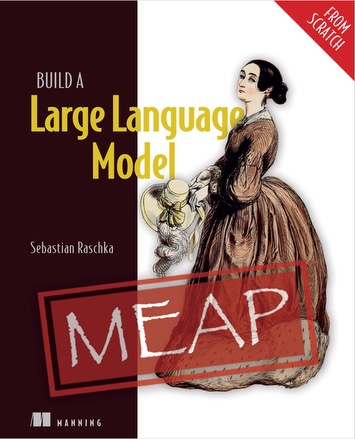 +65
LLMs-from-scratch
rasbt/LLMs-from-scratch · ★ 106.7KThis is the official code repository for the book 'Build a Large Language Model (From Scratch)', which teaches you to implement a GPT-like LLM in PyTorch step by step, from tokenization through pretraining and finetuning.
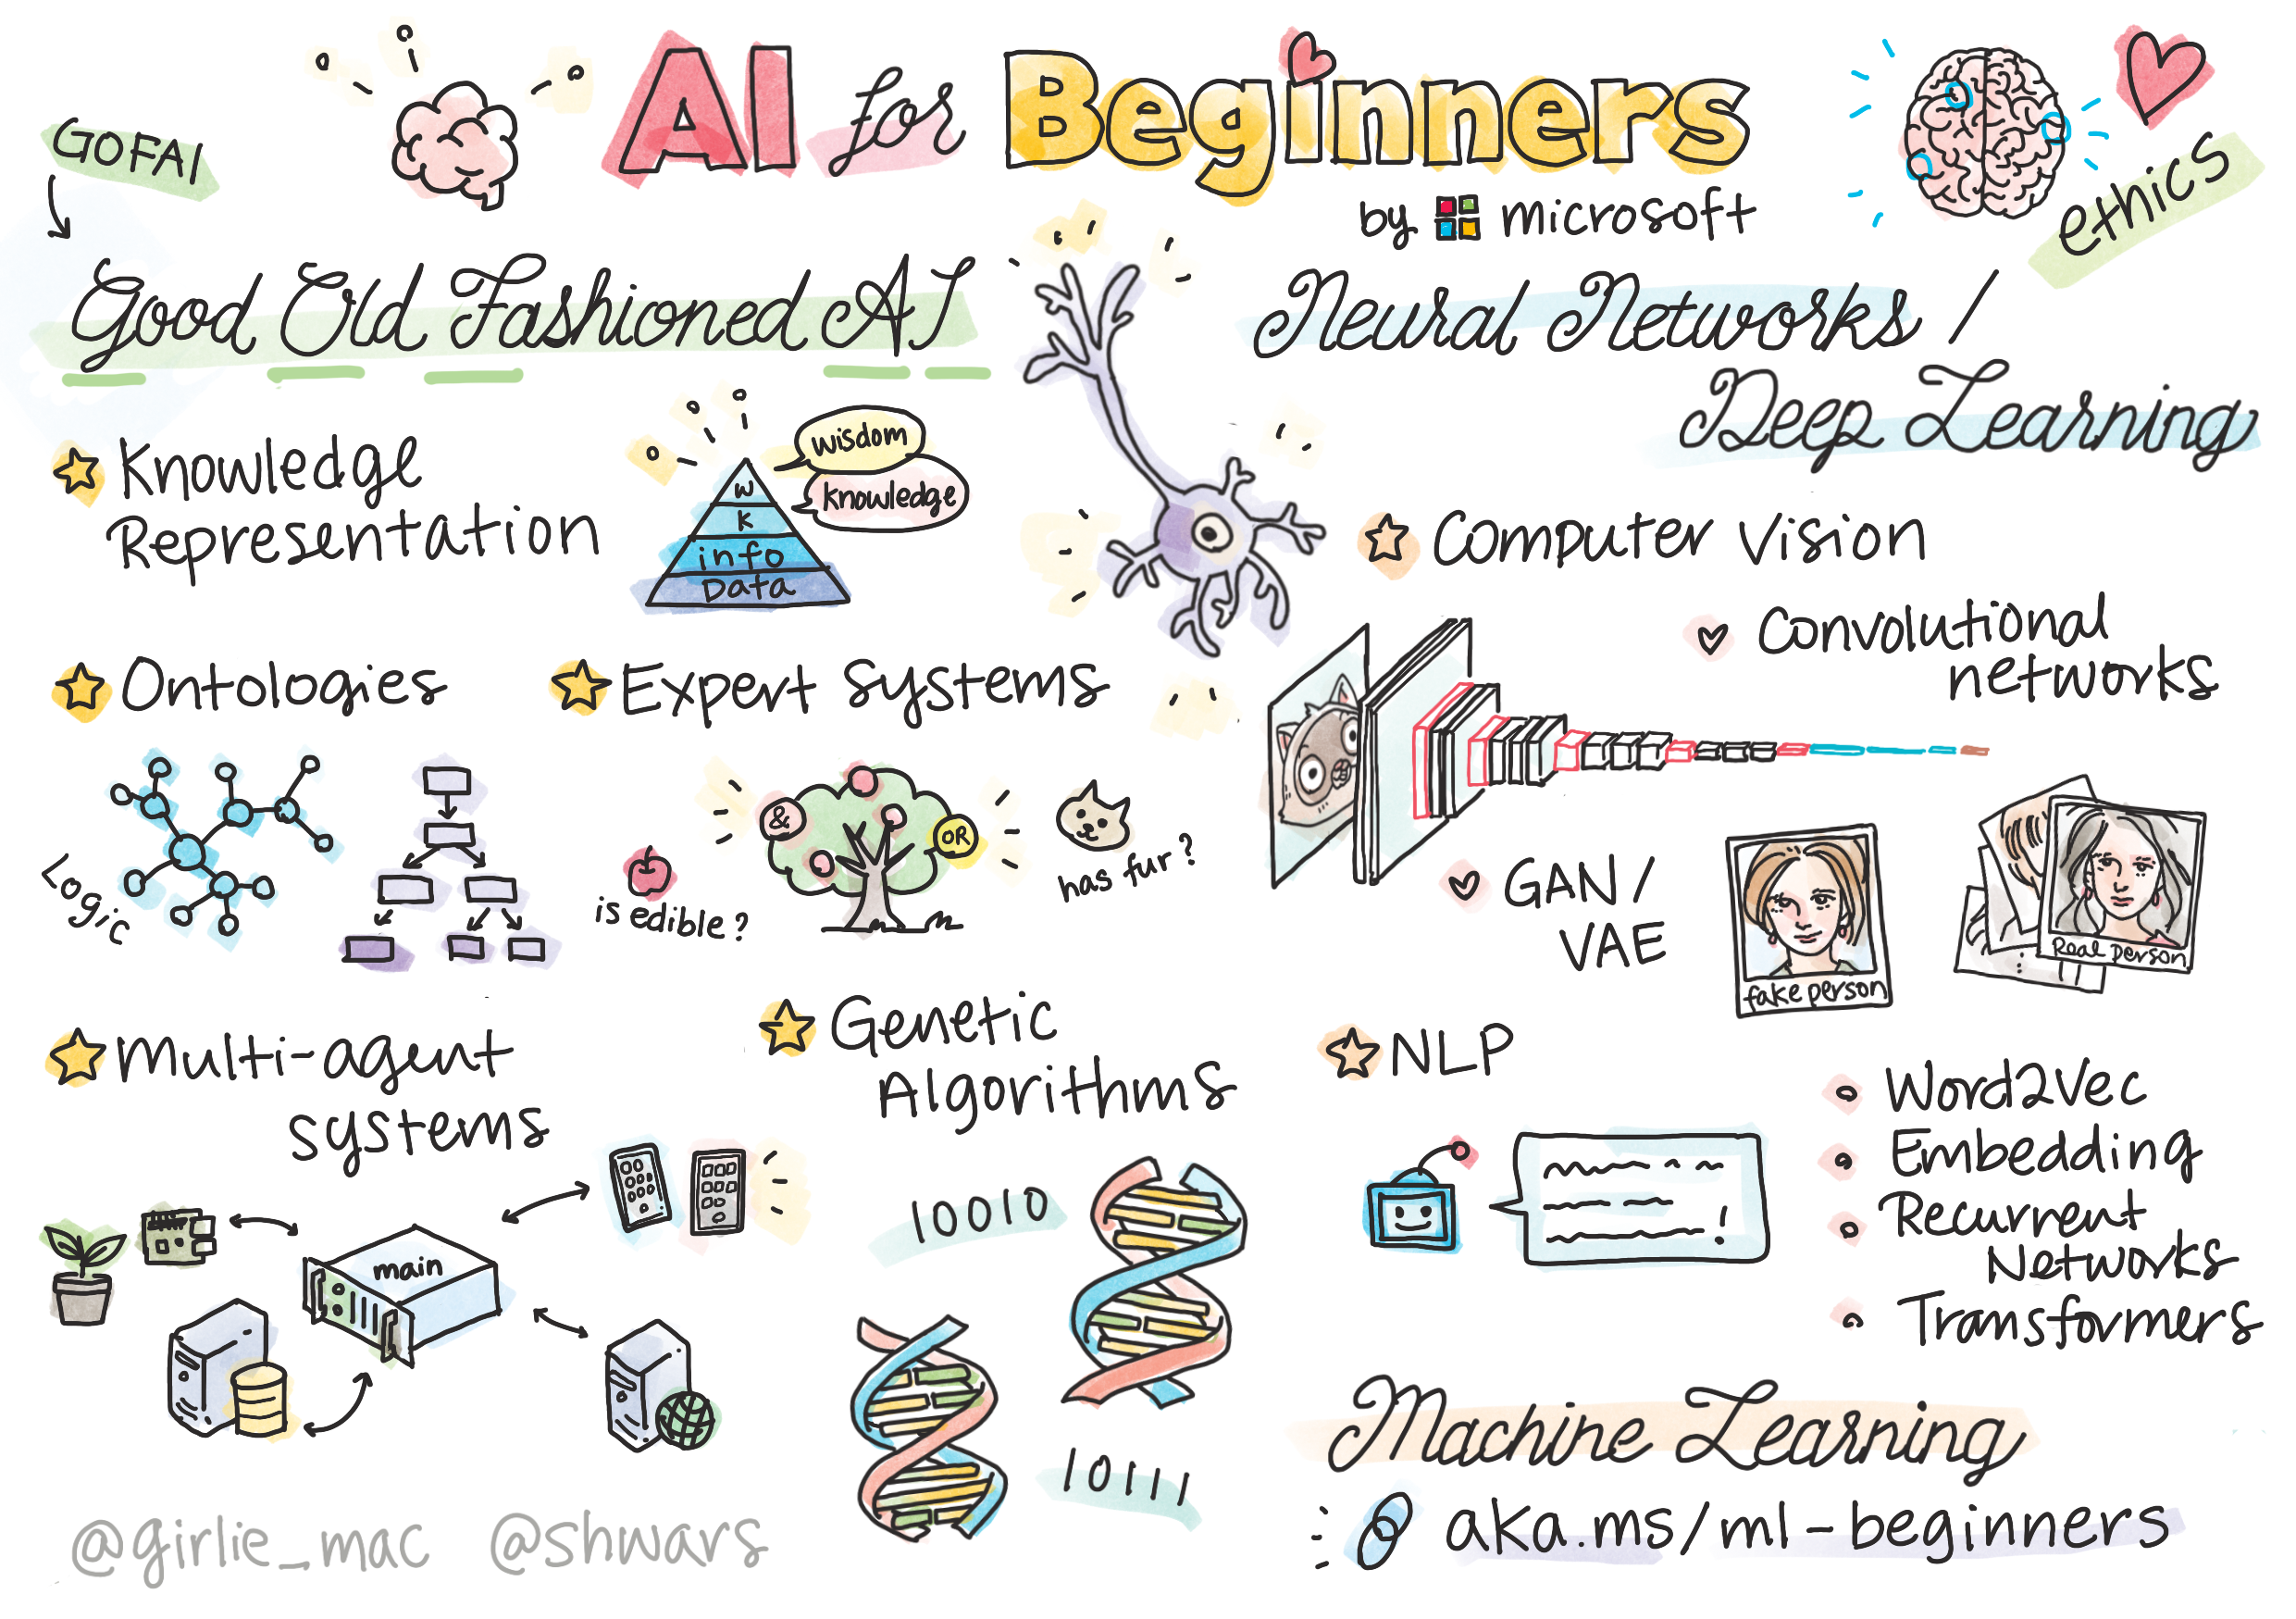 +53
AI-For-Beginners
microsoft/AI-For-Beginners · ★ 69.9KA free 12-week, 24-lesson curriculum from Microsoft that teaches Artificial Intelligence fundamentals through practical lessons, quizzes, and labs.
 +42
transformers
huggingface/transformers · ★ 167.8KTransformers is Hugging Face's model-definition framework for state-of-the-art machine learning models across text, vision, audio, video, and multimodal tasks, usable for both inference and training.
 +39
d2l-zh
d2l-ai/d2l-zh · ★ 81.8KThis is a free, open-source deep learning textbook (Dive into Deep Learning / D2L) written in Chinese, teaching math, concepts, and implementation together through runnable code; it's used as course material by over 500 universities in more than 70 countries.
The all-time top
96 projects · by stars
- 167.8K#1 · huggingface/transformers
transformers
Transformers is Hugging Face's model-definition framework for state-of-the-art machine learning models across text, vision, audio, video, and multimodal tasks, usable for both inference and training.
- 106.7K#2 · rasbt/LLMs-from-scratch
LLMs-from-scratch
This is the official code repository for the book 'Build a Large Language Model (From Scratch)', which teaches you to implement a GPT-like LLM in PyTorch step by step, from tokenization through pretraining and finetuning.
- 91.5K
 #3 · microsoft/ML-For-Beginners
ML-For-Beginners
A free 12-week, 26-lesson curriculum from Microsoft that teaches classic machine learning (not deep learning) using Scikit-learn, with each lesson tied to real-world data from different world cultures.
- 4
funNLP
83Kfighting41love/funNLP · PythonA huge curated collection of Chinese NLP resources: corpora, lexicons, tools, datasets and courses. The README calls it 'The Most Powerful NLP-Weapon Arsenal' — nearly the most complete Chinese NLP resource library.
- 5
d2l-zh
81.8Kd2l-ai/d2l-zh · PythonThis is a free, open-source deep learning textbook (Dive into Deep Learning / D2L) written in Chinese, teaching math, concepts, and implementation together through runnable code; it's used as course material by over 500 universities in more than 70 countries.
- 6

awesome-machine-learning
74.6Kjosephmisiti/awesome-machine-learning · PythonA curated, community-maintained list of machine learning frameworks, libraries, and software, organized by programming language.
- 7
AI-For-Beginners
69.9Kmicrosoft/AI-For-Beginners · Jupyter NotebookA free 12-week, 24-lesson curriculum from Microsoft that teaches Artificial Intelligence fundamentals through practical lessons, quizzes, and labs.
- 8

keras
64.4Kkeras-team/keras · PythonKeras 3 is a multi-backend deep learning framework that lets you build and train models for computer vision, NLP, audio, timeseries, and recommender systems on top of JAX, TensorFlow, or PyTorch.
- 9

DeepLearning-500-questions
57.7Kscutan90/DeepLearning-500-questions · JavaScriptIt is a Chinese-language Q&A style reference covering probability, linear algebra, machine learning, deep learning, and computer vision, organized as answers to 500+ commonly asked questions across 18 chapters and over 500,000 characters. It is also sold in print as 'Deep Learning 500 Questions — AI Engineer Interview Guide' (深度学习500问——AI工程师面试宝典).
- 10
chinese-poetry
53.8Kchinese-poetry/chinese-poetry · JavaScriptThis is a massive open database of classical Chinese poetry, containing about 55,000 Tang poems, 260,000 Song poems, and 21,050 Song ci (lyric poems), along with other classical texts like the Analects and Book of Songs.
- 11
Made-With-ML
49.8KGokuMohandas/Made-With-ML · Jupyter NotebookMade-With-ML is a free hands-on course that teaches how to design, develop, deploy, and iterate on production-grade machine learning applications, combining ML with software engineering best practices.
- 12

ailearning
42.6Kapachecn/ailearning · PythonAiLearning is a Chinese-language, practice-first study guide covering data analysis, machine learning, linear algebra, PyTorch, NLTK, and TensorFlow 2, built mainly around code-along notes for the book 'Machine Learning in Action'.
- 13
bert
40Kgoogle-research/bert · PythonGoogle's official TensorFlow implementation of BERT together with pre-trained checkpoints — a method for pre-training language representations that set state-of-the-art results on a wide range of NLP tasks, from SQuAD question answering to natural language inference.
- 14

Deep-Learning-Papers-Reading-Roadmap
39.6Kfloodsung/Deep-Learning-Papers-Reading-Roadmap · PythonA curated, structured reading roadmap of landmark deep learning papers, organized to guide a newcomer from history and basics through methods and applications to the state of the art.
- 15

500-AI-Machine-learning-Deep-learning-Computer-vision-NLP-Projects-with-code
37.3Kashishpatel26/500-AI-Machine-learning-Deep-learning-Computer-vision-NLP-Projects-with-codeIt is a curated index linking to over 500 external resources, repositories, and tutorials covering AI, machine learning, deep learning, computer vision, and NLP projects with code.
- 16
HanLP
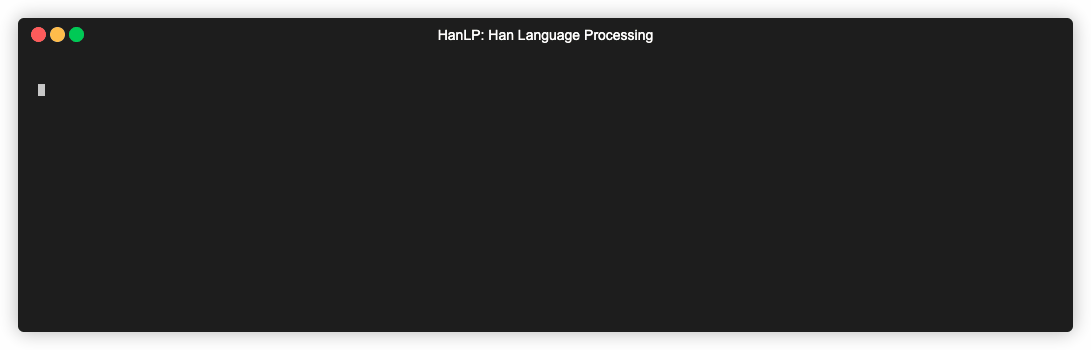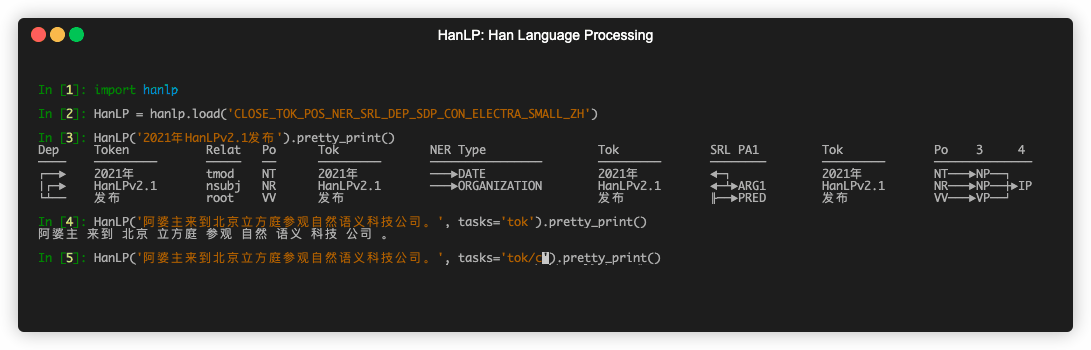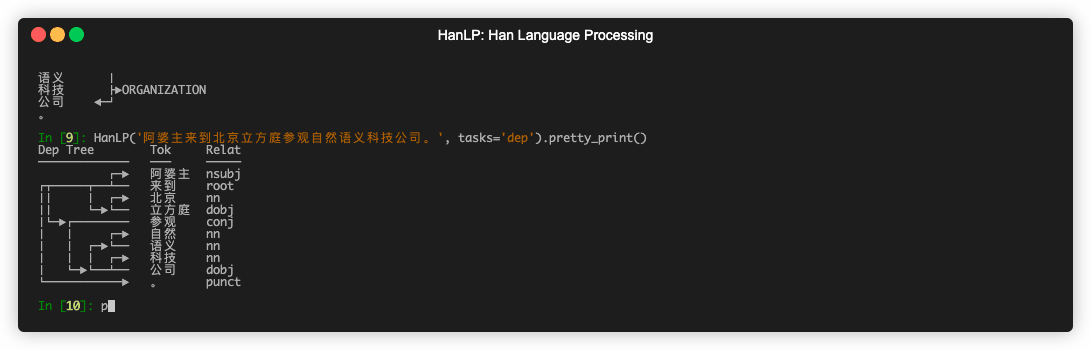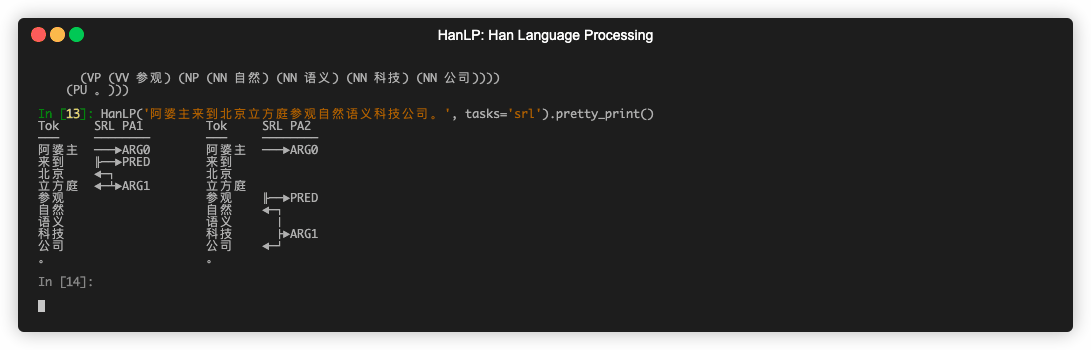
36.5Khankcs/HanLP · PythonHanLP is a production-oriented, multilingual NLP toolkit built on dual PyTorch/TensorFlow 2.x engines, supporting 130 languages with ten joint tasks such as tokenization, POS tagging, NER, dependency and constituency parsing, semantic role labeling, and text classification.
- 17

spaCy
34Kexplosion/spaCy · PythonspaCy is a library for advanced Natural Language Processing in Python and Cython, designed from day one for real products. It ships pretrained pipelines and supports tokenization and training for 70+ languages.
- 18

applied-ml
30.6Keugeneyan/applied-mlapplied-ml is a curated collection of papers, articles, and tech blogs where companies like Airbnb, Uber, Netflix, Google, and DoorDash share how they run data science and machine learning in production.
- 19
d2l-en
29.9Kd2l-ai/d2l-en · PythonAn interactive open-source deep learning book that teaches concepts, context, and runnable code together, with examples in multiple frameworks. Its premise: the best way to understand deep learning is learning by doing.
- 20
Resume-Matcher
28.7Ksrbhr/Resume-Matcher · PythonResume Matcher is a free, open-source AI harness for tailoring your resume to each job application, working with Claude, ChatGPT, DeepSeek, Kimi, GLM, Gemma and other LLMs, both local and remote.
- 21
Awesome-LLM
27.4KHannibal046/Awesome-LLMA curated, continuously updated list of resources about Large Language Models (LLMs): milestone and other research papers, training/inference frameworks, open LLM checkpoints, benchmarks, courses, and books.
- 22

fastText
26.5Kfacebookresearch/fastText · HTMLfastText is a library from Facebook Research for efficiently learning word vector representations and training text classifiers, such as for sentiment analysis.
- 23

awesome-deep-learning-papers
26.2Kterryum/awesome-deep-learning-papers · TeXA curated list of the most-cited deep learning papers published between 2012 and 2016, picked as must-read classics across research domains.
- 24

fastbook
25.4Kfastai/fastbook · Jupyter NotebookThis repo contains the official Jupyter Notebooks for 'the fastai book', an introduction to deep learning, the fastai library, and PyTorch.
- 25

pytudes
24.4Knorvig/pytudes · Jupyter NotebookPytudes is Peter Norvig's personal collection of short, deliberately difficult Python programs and Jupyter notebooks, each written to perfect one specific programming skill, in the spirit of a musical étude.
- 26
CV
24KAccumulateMore/CV · Jupyter NotebookA comprehensive collection of Chinese-language deep learning study notes covering PyTorch, classic deep learning courses, and LLM agents — written to accompany well-known video courses.
- 27

DeepSeek-OCR
24Kdeepseek-ai/DeepSeek-OCR · PythonDeepSeek-OCR is a vision-language model built to explore 'contexts optical compression' -- squeezing text-heavy document images into a small number of vision tokens that an LLM can still read back accurately, as a research probe into how much text a vision encoder can represent visually.
- 28
NLP-progress
23Ksebastianruder/NLP-progress · PythonA curated, community-maintained document that tracks progress in Natural Language Processing: it lists the standard datasets and the current state-of-the-art results for most common NLP tasks across many languages.
- 29

unilm
22.2Kmicrosoft/unilm · PythonMicrosoft's research hub for large-scale self-supervised pre-training: a family of foundation models spanning NLP, vision, speech, and multimodal tasks across 100+ languages - including BEiT, LayoutLM, Kosmos, MiniLM, TrOCR, and WavLM.
- 30

datasets
22.1Khuggingface/datasets · PythonA lightweight Python library from Hugging Face that gives one-line dataloaders for a huge catalog of ready-to-use public datasets on the HF Hub, plus fast, reproducible preprocessing for Hub and local data.
- 31

Qwen
21.9KQwenLM/Qwen · PythonThe official repo of Qwen (通义千问, Tongyi Qianwen) — Alibaba Cloud's family of chat and pretrained large language models, released in sizes from 1.8B up to 72B parameters on Hugging Face and ModelScope.
- 32

pytorch-handbook
21.7Kzergtant/pytorch-handbook · Jupyter NotebookAn open-source Chinese-language book that teaches PyTorch for deep learning, written as a set of Jupyter notebooks whose code has all been tested to actually run.
- 33

Ciphey
21.7Kbee-san/Ciphey · Rustciphey automatically decrypts ciphertext without knowing the key or cipher, decodes encodings and cracks hashes. It is the Rust-built next generation of Ciphey — roughly 7x faster per decode — and the same team intends it to fully replace the original.
- 34

rasa
21.4KRasaHQ/rasa · PythonRasa Open Source is an open source machine learning framework for automating text- and voice-based conversations — you build contextual assistants like chatbots and voice assistants, then connect them to Slack, Messenger, Telegram and other channels.
- 35
Dive-into-DL-PyTorch
19.5KShusenTang/Dive-into-DL-PyTorch · Jupyter NotebookThe Chinese book 'Dive into Deep Learning' with its MXNet code examples rewritten in PyTorch — a free, open-source deep-learning tutorial pairing runnable Jupyter notebooks with online docs.
- 36

sentence-transformers
19.2Khuggingface/sentence-transformers · PythonSentence Transformers is a framework for computing embeddings and using or training state-of-the-art embedding and reranker models, covering dense sentence embeddings, cross-encoder rerankers, sparse encoders, and multi-vector (ColBERT-style) encoders.
- 37

awesome-nlp
19.1Kkeon/awesome-nlpA curated list of resources dedicated to Natural Language Processing — research hubs, tutorials, courses, books, libraries, datasets, and task methods, collected as links with one-line descriptions.
- 38

DocsGPT
18.3Karc53/DocsGPT · PythonDocsGPT is a private, self-hosted AI platform for building agents, assistants, and enterprise search tools, with a built-in Agent Builder, document analysis, deep research mode, and support for multiple LLM providers.
- 39
camel
17.9Kcamel-ai/camel · PythonCAMEL is an open-source multi-agent framework for building, simulating and studying LLM-powered agents at scale, aimed at finding the 'scaling laws of agents'.
- 40
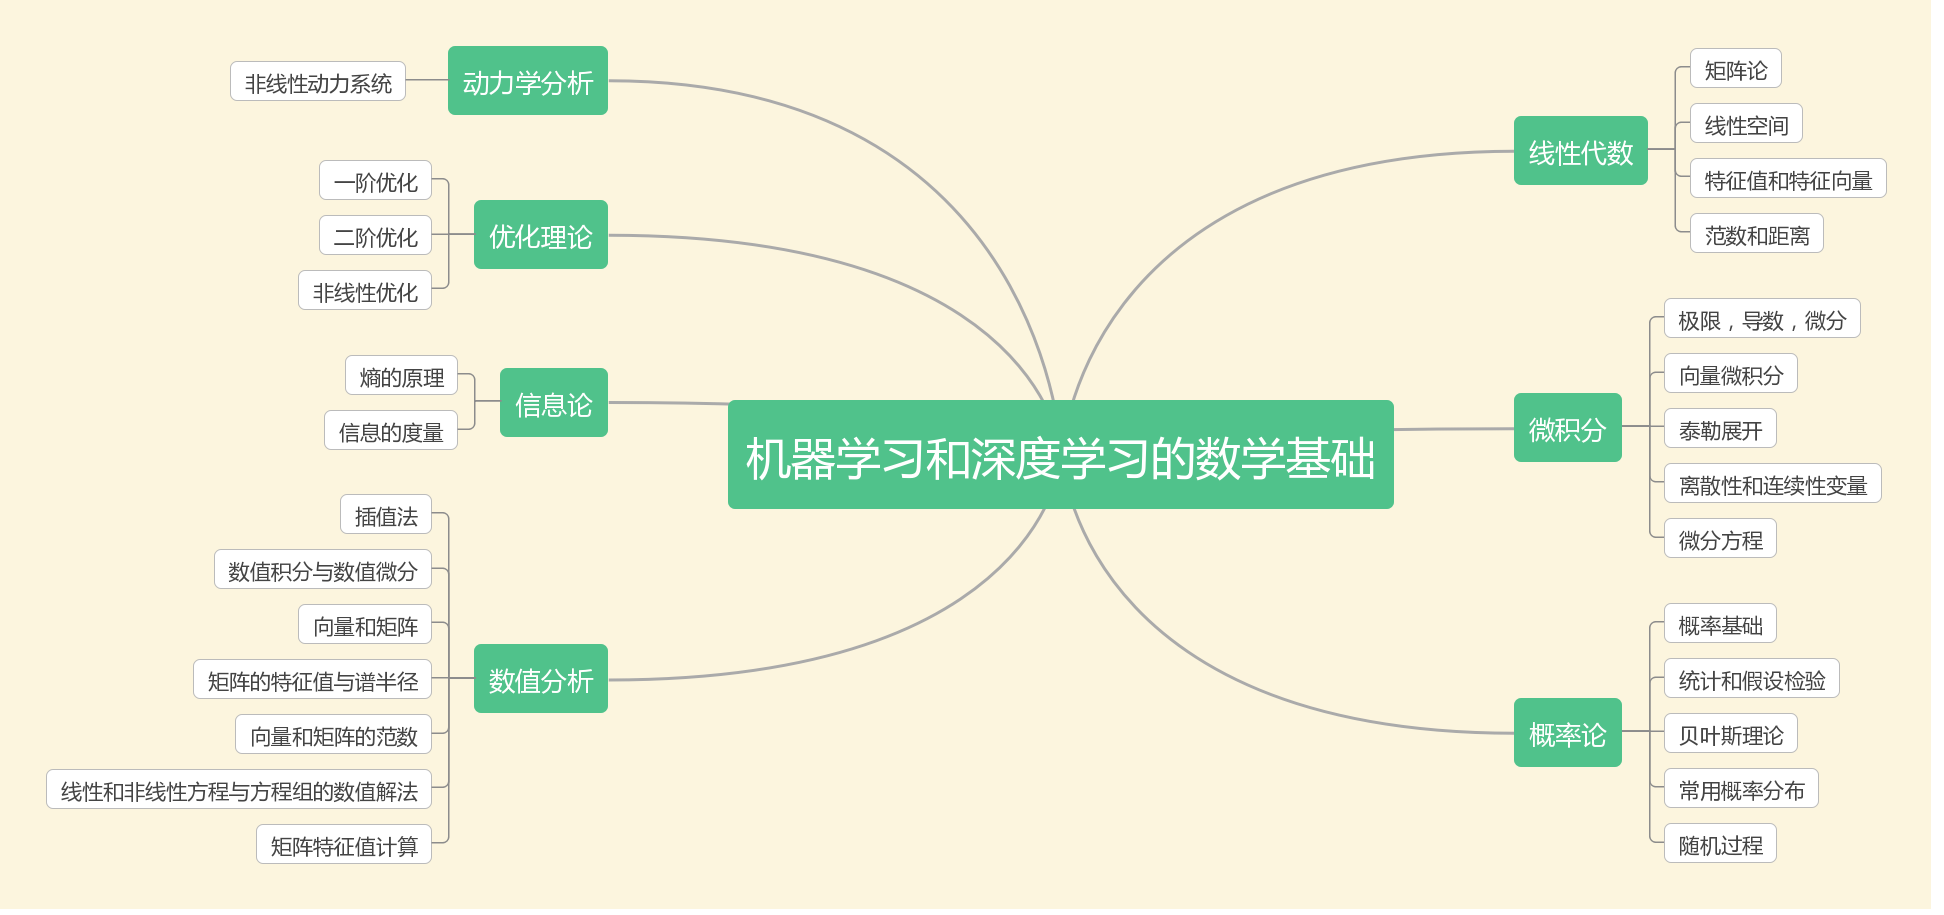
DeepLearning
17.8KMikoto10032/DeepLearning · Jupyter NotebookA Chinese-language deep learning tutorial — a huge curated collection of links to courses, books, lecture notes, surveys and code, taking you from math basics through CNNs, GANs, RNNs and GNNs to Kaggle practice and interview prep.
- 41
ML-NLP
17.8KNLP-LOVE/ML-NLP · Jupyter NotebookA curated, structured collection of machine learning, deep learning, and NLP interview knowledge points with accompanying code implementations, organized chapter by chapter (linear regression through BERT and XLNet).
- 42

deeplearning-models
17.6Krasbt/deeplearning-models · Jupyter NotebookA large collection of Jupyter Notebooks implementing various deep learning architectures, models, and training tips for TensorFlow and PyTorch.
- 43

ML-YouTube-Courses
17.4Kdair-ai/ML-YouTube-CoursesA curated index maintained by DAIR.AI that organizes the best and most recent machine learning and AI courses available on YouTube, from intro ML to deep learning, NLP, and reinforcement learning.
- 44
ml-visuals
17.4Kdair-ai/ml-visualsML Visuals is a free, community-built collection of 100+ professional figures and templates for machine learning, meant to improve science communication in presentations and blog posts.
- 45
LibreTranslate
17.1KLibreTranslate/LibreTranslate · PythonA free and open source machine translation API that you host entirely yourself. Unlike Google or Azure, it does not send your text to proprietary services — the engine is the open source Argos Translate library.
- 46

Awesome-pytorch-list
16.7Kbharathgs/Awesome-pytorch-listA curated, large-scale list of PyTorch-related projects on GitHub: models, libraries, tools, tutorials, books and paper implementations organized by category.
- 47
gensim
16.5Kpiskvorky/gensim · PythonGensim is a Python library for topic modelling, document indexing and similarity retrieval with large corpora, aimed at the natural language processing (NLP) and information retrieval (IR) community.
- 48

transformers.js
16.3Khuggingface/transformers.js · JavaScriptTransformers.js lets you run Hugging Face's state-of-the-art machine learning models directly in a web browser, with no server required, using an API designed to mirror the Python transformers library.
- 49

lectures
15.9Koxford-cs-deepnlp-2017/lecturesThe lecture slides and course description for the Deep Natural Language Processing course offered in Hilary Term 2017 at the University of Oxford: an advanced, applied NLP course organised by Phil Blunsom and delivered in partnership with the DeepMind Natural Language Research Group.
- 50

awesome-java-cn
15.7Kjobbole/awesome-java-cnThis is the Chinese-language edition of the awesome-java curated list, covering Java build tools, databases, frameworks, libraries, security, logging, and more, maintained and translated by Jobbole (伯乐在线).
- 51
unstructured
15.6KUnstructured-IO/unstructured · HTMLUnstructured is an open-source ETL toolkit that converts complex documents like PDFs, Word docs, HTML and images into clean, structured data (JSON) ready for LLMs, RAG pipelines and vector databases.
- 52
llm_interview_note
15.3Kwdndev/llm_interview_note · HTMLThis is a curated Chinese-language knowledge base of large language model (LLM) concepts and interview questions, aimed at algorithm/application engineers preparing for LLM-related job interviews.
- 53

newspaper
15.2Kcodelucas/newspaper · PythonNewspaper3k is a Python 3 library that downloads, parses, and extracts the article text, authors, publish date, top image, and keywords/summary from news articles and news sites.
- 54

languagetool
15.2Klanguagetool-org/languagetool · JavaOpen-source proofreading software that checks grammar and style in English, German, French, Spanish, Polish, Dutch and more — over 25 languages — catching many errors a simple spell checker misses.
- 55

nlp-tutorial
14.9Kgraykode/nlp-tutorial · Jupyter NotebookA collection of short PyTorch implementations covering core NLP and deep learning models, from word embeddings to Transformers and BERT, meant as a study resource.
- 56
Llama-Chinese
14.8KLlamaChinese/Llama-Chinese · PythonLlama-Chinese is a Chinese-language community project built around Meta's Llama models (Llama2, Llama3, Llama4). It provides Chinese pretraining and fine-tuning, a custom Atom model series optimized for Chinese, and resources for training, deploying and using Llama in Chinese for free commercial use.
- 57

nltk
14.7Knltk/nltk · PythonNLTK is a suite of open source Python modules, bundled data sets, and tutorials supporting research and development in Natural Language Processing.
- 58
ChatterBot
14.5Kgunthercox/ChatterBot · PythonChatterBot is a machine-learning conversational dialog engine for Python: it generates chatbot replies based on collections of known conversations, and can be trained to speak any language.
- 59
flair
14.4KflairNLP/flair · PythonFlair is a very simple framework for state-of-the-art natural language processing: a Python library for applying pre-trained NLP models to your text, developed by Humboldt University of Berlin and friends. The current release is version 0.15.1.
- 60
transferlearning
14.4Kjindongwang/transferlearning · PythonA curated knowledge base covering transfer learning, domain adaptation, domain generalization and related subfields - papers, tutorials, code, datasets, scholars and surveys, maintained in both English and Chinese.
- 61
LoRA
13.9Kmicrosoft/LoRA · PythonLoRA (loralib) is Microsoft's reference implementation of the paper 'LoRA: Low-Rank Adaptation of Large Language Models'. It lets you fine-tune large models like GPT-2, RoBERTa and DeBERTa by training small low-rank matrices instead of all the original weights.
- 62

deep-learning-drizzle
13Kkmario23/deep-learning-drizzle · HTMLA curated index that collects links to full video lectures and course materials for Deep Learning, Reinforcement Learning, Machine Learning, Computer Vision and NLP courses taught at top universities worldwide.
- 63
open-llms
12.9Keugeneyan/open-llmsA curated list of open large language models (LLMs) that are licensed for commercial use, such as Apache 2.0, MIT, or OpenRAIL-M licenses.
- 64
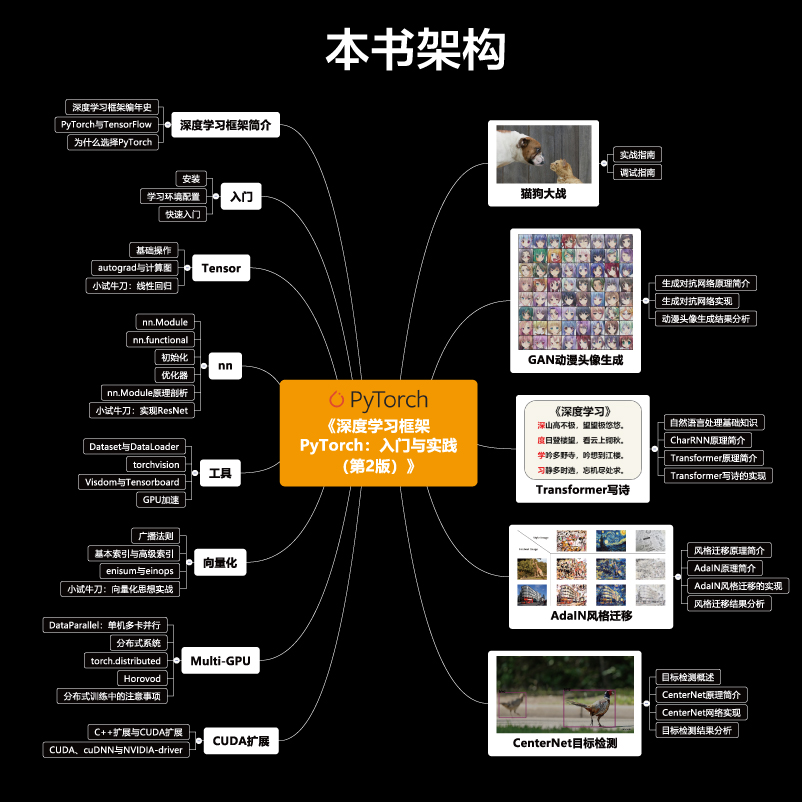
pytorch-book
12.8Kchenyuntc/pytorch-book · Jupyter NotebookThis is the companion code repository for the Chinese book 'Deep Learning Framework PyTorch: Introduction and Practice', covering PyTorch basics and fun projects like neural talk, poem writing, anime face generation, and style transfer.
- 65
MOSS
12.3KOpenMOSS/MOSS · PythonMOSS is an open-source, tool-augmented bilingual (Chinese-English) conversational language model built by Fudan University's OpenMOSS team, released with model weights, training data, and deployment/finetuning code.
- 66

Chinese-Word-Vectors
12.2KEmbedding/Chinese-Word-Vectors · PythonA collection of 100+ pre-trained Chinese word vectors (embeddings) trained with different representations, context features and corpora, plus the CA8 analogy dataset and an evaluation toolkit.
- 67
LLMSurvey
12.2KRUCAIBox/LLMSurvey · PythonIt is the official GitHub page for the survey paper 'A Survey of Large Language Models' — a curated collection of papers and resources on how LLMs are built, adapted, and used.
- 68
compromise
12.2Kspencermountain/compromise · JavaScriptCompromise is a lightweight JavaScript natural-language processing library that parses text into structured data: tokenizing words and sentences, tagging part-of-speech, and letting you query phrases like numbers, names, or dates.
- 69
sentencepiece
12.1Kgoogle/sentencepiece · C++SentencePiece is a fast, lightweight, unsupervised text tokenizer and detokenizer built for neural-network text generation systems like LLMs, where vocabulary size is fixed before training. It implements BPE and the unigram language model as subword units and trains directly from raw sentences.
- 70

seamless_communication
11.9Kfacebookresearch/seamless_communication · Jupyter NotebookSeamless Communication is Meta's family of foundational AI models for speech and text translation across roughly 100 languages, covering speech-to-speech, speech-to-text, text-to-speech and text-to-text translation plus automatic speech recognition.
- 71
allennlp
11.9Kallenai/allennlp · PythonAllenNLP is an open-source NLP research library built on PyTorch for developing state-of-the-art deep learning models across a wide range of linguistic tasks.
- 72
ludwig
11.8Kludwig-ai/ludwig · PythonLudwig is a declarative deep learning framework that lets you train, fine-tune, and deploy AI models — from LLM fine-tuning to tabular classification — using a YAML config file and zero boilerplate Python.
- 73

chinese-xinhua
11.7Kpwxcoo/chinese-xinhua · PythonA Chinese Xinhua Dictionary database (中华新华字典数据库): four JSON datasets with 31,648 idioms, 264,434 words, 16,142 characters and 14,032 xiehouyu (two-part allegorical sayings), collected from the web.
- 74
tokenizers
11.2Khuggingface/tokenizers · RustTokenizers is a library implementing today's most-used tokenizers (BPE, WordPiece, Unigram) for NLP, built in Rust for speed and exposed to other languages via bindings. It's made by Hugging Face and powers tokenization for transformer models.
- 75
openvino
11Kopenvinotoolkit/openvino · C++OpenVINO is Intel's open-source toolkit for optimizing and deploying AI inference — it takes trained deep learning models for vision, speech, NLP, and generative AI and runs them faster, from edge devices to cloud servers.
- 76
natural
10.9KNaturalNode/natural · JavaScriptNatural is a general-purpose natural language processing library for Node.js that bundles tokenizers, stemmers, classifiers and other NLP utilities into one package.
- 77
doccano
10.8Kdoccano/doccano · PythonDoccano is an open-source text annotation tool that lets humans label data for machine learning tasks like text classification, sequence labeling, and sequence-to-sequence problems such as summarization or translation.
- 78
autogluon
10.8Kautogluon/autogluon · PythonAutoGluon is an open-source Python library that automates machine learning: feed it your data and it delivers strong predictive performance in about three lines of code.
- 79

nlp_course
10.7Kyandexdataschool/nlp_course · Jupyter NotebookThis is the Yandex School of Data Analysis (YSDA) Natural Language Processing course: a full set of lecture slides, seminar notebooks, and homework assignments organized by week, covering NLP from word embeddings through modern LLM topics.
- 80
ParlAI
10.6Kfacebookresearch/ParlAI · PythonParlAI is a Python framework from Facebook (Meta) AI Research for sharing, training, and evaluating dialogue AI models, covering everything from open-domain chitchat to task-oriented dialogue and visual question answering, with over 100 datasets available through one unified API.
- 81

machine-learning-notes
10.4Kroboticcam/machine-learning-notes · Jupyter NotebookA continuously updated, free collection of over 2000 slides and lecture notes covering machine learning, probabilistic models, deep learning, and related mathematics, written by the author over more than a decade.
- 82

stanford-tensorflow-tutorials
10.4Kchiphuyen/stanford-tensorflow-tutorials · PythonThis is the code repository for Stanford's CS 20 course, 'TensorFlow for Deep Learning Research,' containing the example code used throughout the lectures.
- 83
Chinese-BERT-wwm
10.2Kymcui/Chinese-BERT-wwm · PythonThis project releases a family of pre-trained Chinese BERT models trained with Whole Word Masking (WWM), including BERT-wwm, BERT-wwm-ext, RoBERTa-wwm-ext, RoBERTa-wwm-ext-large, and smaller RBT3/RBT4/RBT6/RBTL3 variants, published alongside a paper in IEEE/ACM TASLP.
- 84
LLMsPracticalGuide
10.2KMooler0410/LLMsPracticalGuideA curated, actively updated list of practical guide resources for large language models (LLMs), covering models, data, NLP tasks, and usage restrictions. It is based on a survey paper 'Harnessing the Power of LLMs in Practice: A Survey on ChatGPT and Beyond'.
- 85

CoreNLP
10.1Kstanfordnlp/CoreNLP · JavaA Java suite of core NLP tools that takes raw human language text and returns linguistic analysis: tokenization, parts of speech, named entities, parsing, coreference, and sentiment.
- 86
im-not-ai
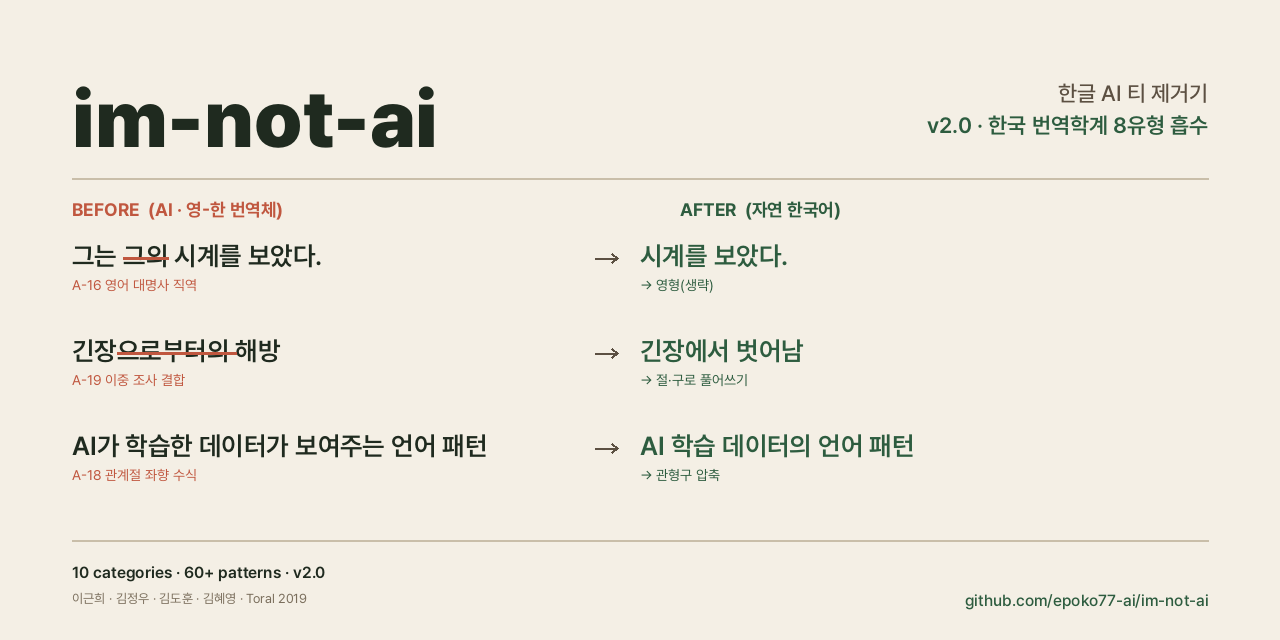
6Kepoko77-ai/im-not-ai · PythonThis is a Claude Skill that rewrites Korean text written by AI (ChatGPT, Claude, Gemini) so it reads like it was written by a human, removing translationese, mechanical parallelism and other 'AI tells' without changing the actual content.
- 87
lieflat-less-ai-tone
2.8Klarashero3-dotcom/lieflat-less-ai-tone · PythonA research-backed skill that detects and removes 'AI tone' from Chinese writing, based on a statistical study of a 2.83-million-character corpus comparing AI-generated and human-written text.
- 88
lieflat-gongwen
1.5Klarashero3-dotcom/lieflat-gongwen · PythonIt's a 'Chinese official document writing' skill distilled from 1.02 million characters of real government writing samples, turning stylistic traits into measurable, checkable quantitative parameters so an AI agent can reproduce 7 typical official-document styles.
- 89
Hy-MT2
1.3KTencent-Hunyuan/Hy-MT2 · PythonHy-MT2 is Tencent Hunyuan's family of 'fast-thinking' multilingual translation models, released in three sizes (1.8B, 7B, and 30B-A3B MoE), that translate among 33 languages and follow complex translation instructions.
- 90
pg-jev
1.2KrealZachi/pg-jev · Shellpg-jev (jev) is a PostgreSQL extension that lets you filter, rank and classify table rows using plain-language conditions instead of SQL predicates. Each row is judged by TypeSafe's Jev, a model that returns calibrated probabilities rather than generated text.
- 91
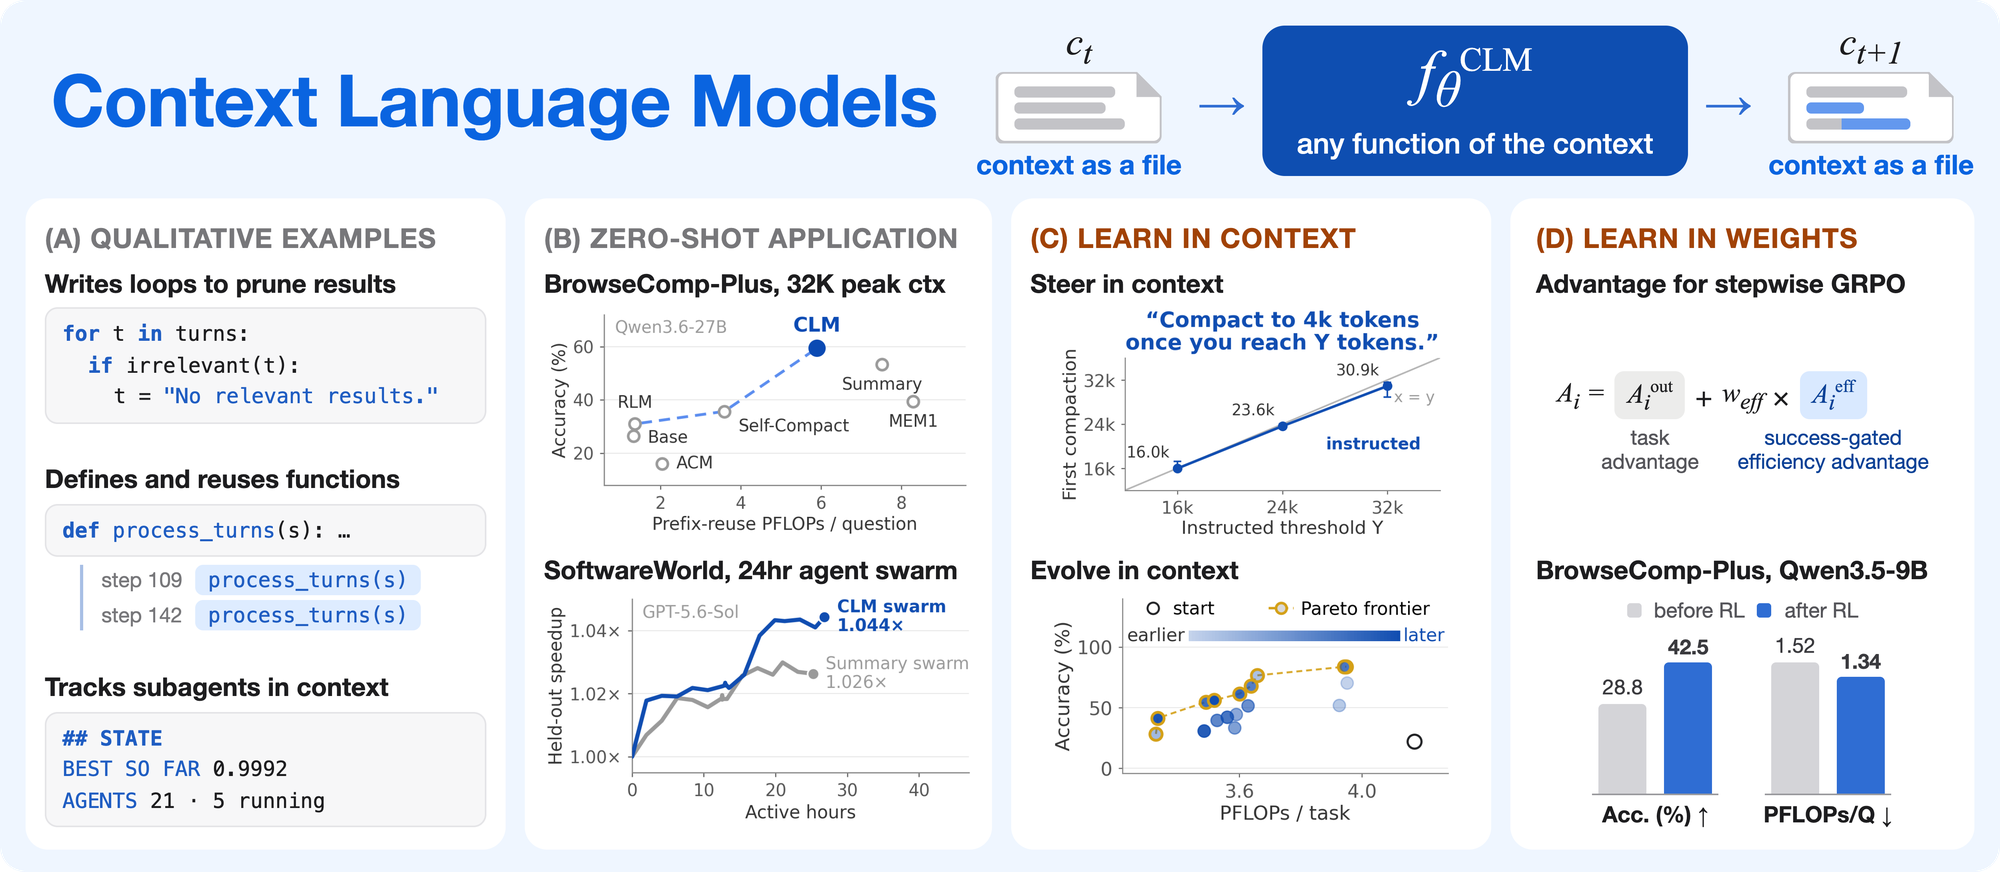
context-language-models
730facebookresearch/context-language-models · PythonThis is the official code release for 'Context Language Models (CLMs)', research from University of Washington, Meta Superintelligence Labs, MIT and Trillium Labs. CLMs are language models that natively manage their own context by treating it as a file they can freely edit, which naturally extends to multi-agent setups where each agent's context is its own file.
- 92
jeeves
425PostHog/jeeves · PythonJeeves is a reasoning-enhanced 'Jev-like' decision model built on Qwen3.5-9B with LoRA. It thinks through a reasoning chain before giving calibrated yes/no, multiple-choice, or rating answers, and ships with a diffusion drafter for faster inference.
- 93
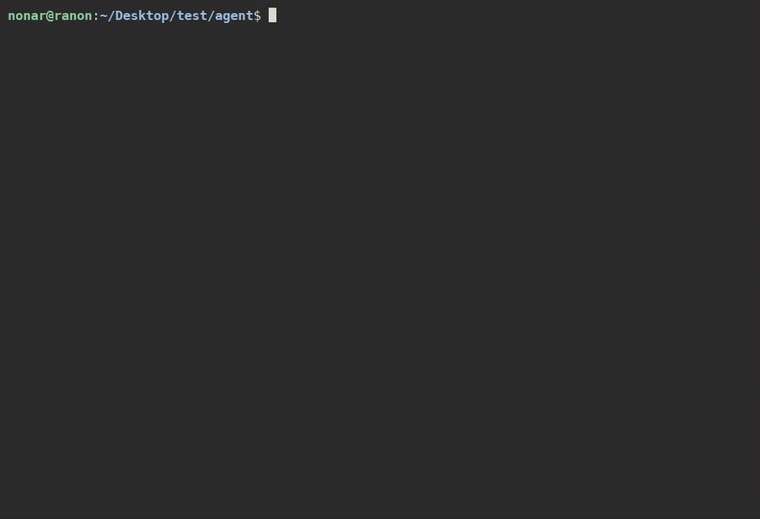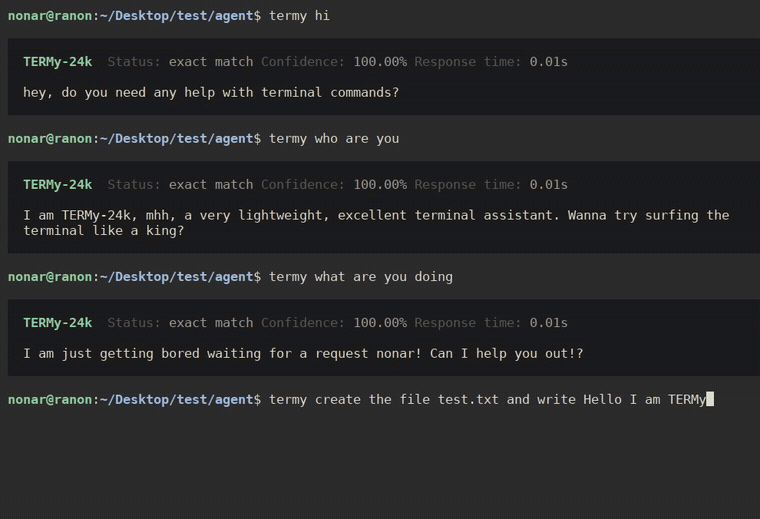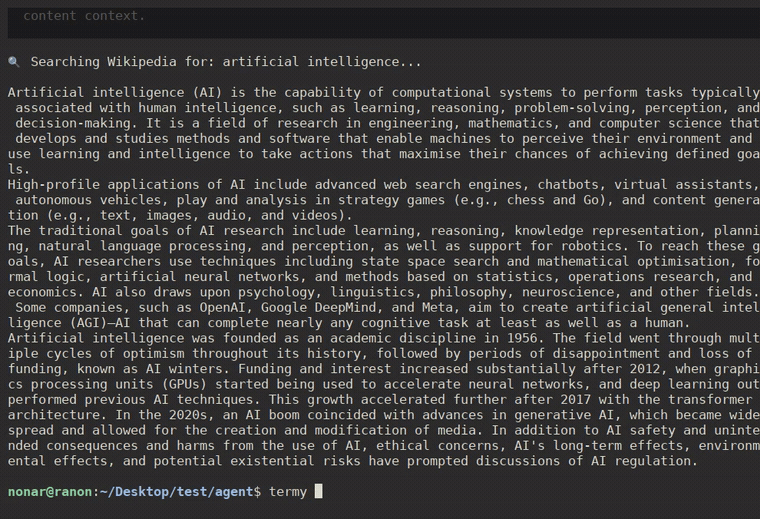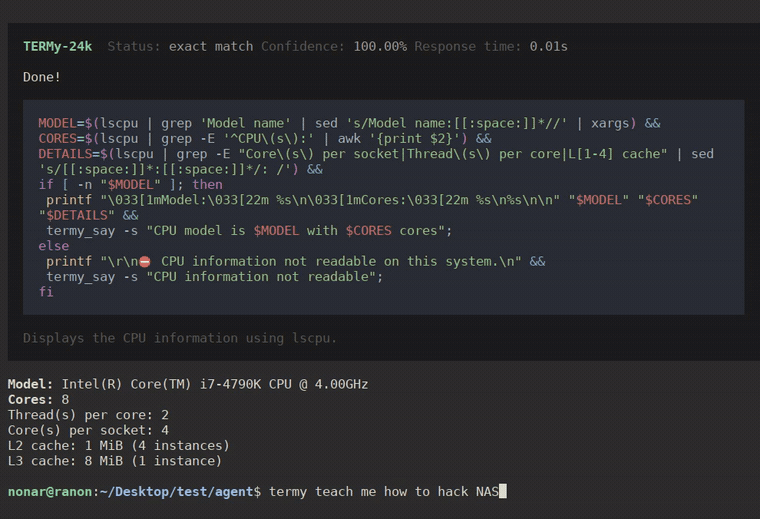
NPC-Forge
269gioblu/NPC-Forge · PythonNPC-Forge is an open-source neuro-symbolic framework for building conversational agents with distinct personalities, multi-turn context, sentiment analysis and tool-call support. Its agents run on the CPU without machine learning or LLMs.
- 94
autumn-recruitment
263Akun-python/autumn-recruitment · Jupyter NotebookIt is a community-built, Chinese-language collection of Jupyter notebooks covering math foundations, data structures, machine learning, deep learning, LLMs, agents, AI infrastructure, speech, and data science, aimed at job-hunting ('autumn recruitment') interview prep in the LLM era.
- 95
LLMSearchRecommender
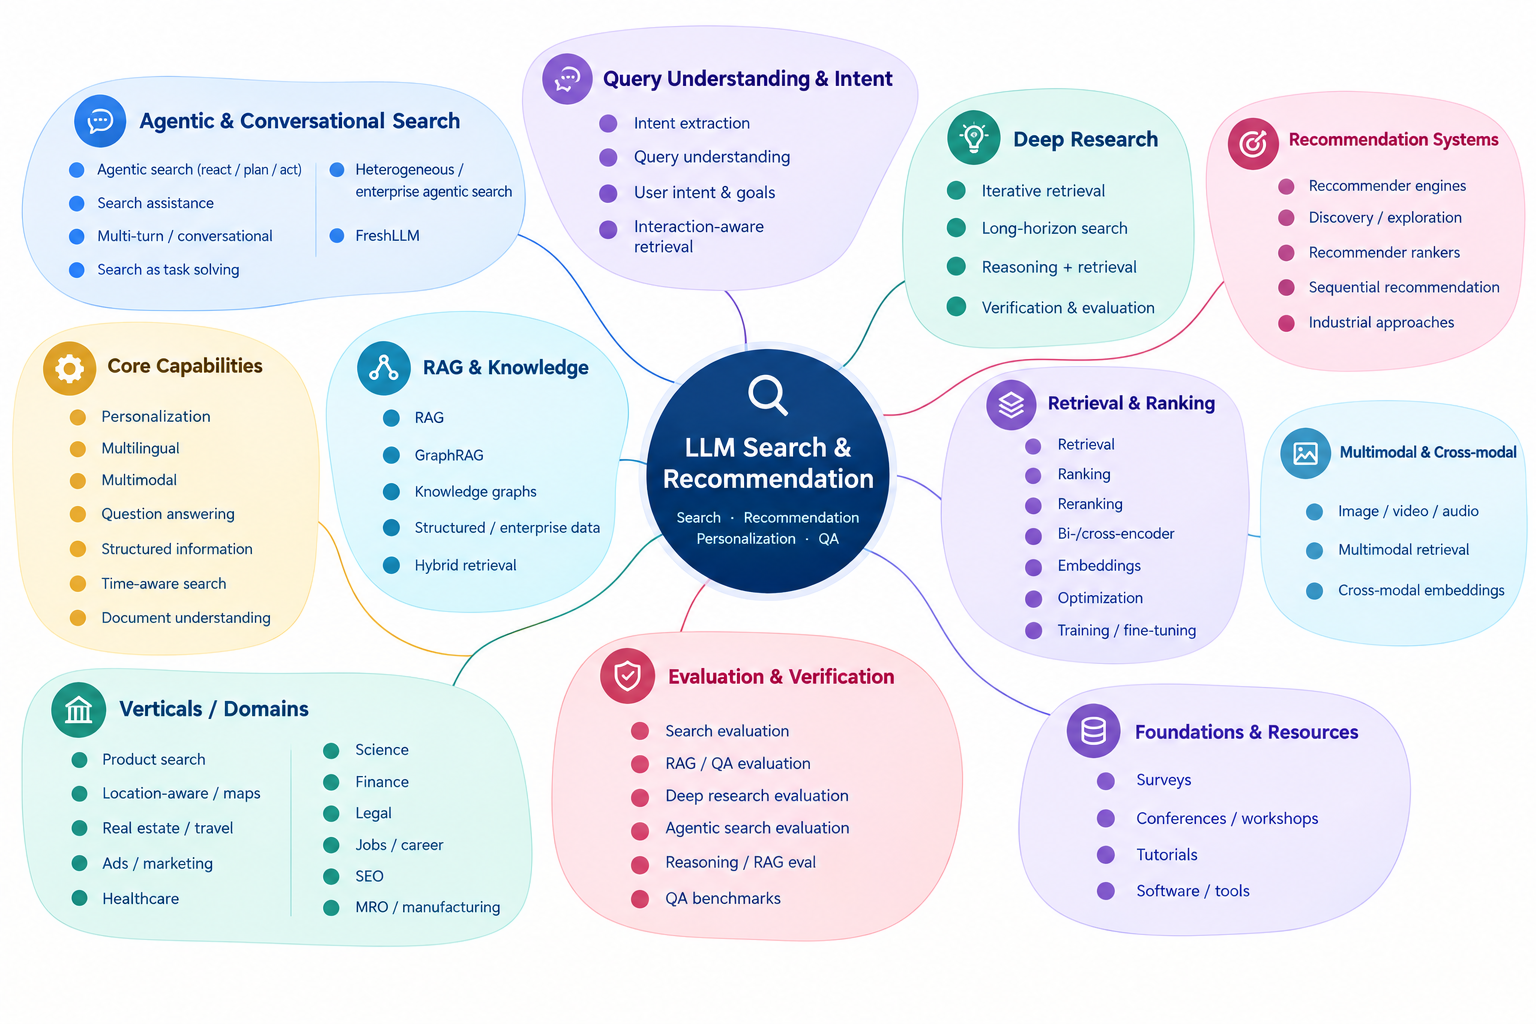
124alopatenko/LLMSearchRecommenderA curated compendium of research papers, surveys, and industry engineering practices on using Generative AI and LLMs to build search engines, recommender systems, personalization engines, and question-answering systems.
- 96

roster-match
104charlenemercury/roster-match · JavaScriptA zero-dependency JavaScript library that matches a Chinese name heard through speech recognition (or any garbled transcript) to the correct entry in a roster, comparing by pinyin syllables and surfacing candidates with reasons instead of forcing a decision when it is unsure.

Related topics
Often tagged together
- machine-learning916
- python2,396
- deep-learning737
- nlp214
- research764
- open-source5,666
- education933
- pytorch419
- llm1,484
- ai1,955
- computer-vision384
- mit3,311
- chinese1,157
- data-science231
- tutorial626
- transformer212
- artificial-intelligence267
- library1,587
- academic-research209
- resources706
- huggingface362
- apache-2.01,434
- curated-list634
- learning-resources410