Topics / #llm-inference
LLM inference projects on GitHub
Serving LLMs efficiently: quantization, batching, and local runtimes.
As of , the most-starred LLM inference projects on GitHub are llama.cpp (131.5K stars), vllm (94.1K stars) and gpt4all (77.4K stars). GitHub.Locker tracks 118 LLM inference repositories with 1.2M stars combined. The fastest-growing on October 17 was Strata, with +608 stars in a day.
Hot right now
Most stars gained in a day · Oct 17
 +608
Strata
Niko1221/Strata · ★ 27KStrata runs Qwen3.8-Flash-Next, a 125-billion-parameter AI model, on a normal gaming PC with one NVIDIA GPU (12-24GB VRAM) and 64GB of RAM, with a one-click installer for Windows and Linux.
 +213
Edge0
Edge0-AI/Edge0 · ★ 5.5KEdge0 is an open-source streaming MoE (Mixture-of-Experts) inference framework that lets you run large MoE models, like a 35B-parameter model, using only about 2.5-2.9 GB of active RAM by streaming expert weights from SSD and predicting routing one step ahead.
 +179
colibri
JustVugg/colibri · ★ 42.6KColibri is an open-source engine for running frontier mixture-of-experts (MoE) language models on hardware you already own — written in pure C with zero dependencies.
 +160
airllm
lyogavin/airllm · ★ 39.2KAn open-source Python library that runs huge LLMs on tiny GPUs: a 70B model fits on a single 4GB card without quantization, distillation or pruning — even the 2.8T-parameter Kimi K3 runs in under 4GB.
The all-time top
Top 100 of 118 · by stars
- 131.5K
 #1 · ggml-org/llama.cpp
llama.cpp
llama.cpp is a plain C/C++ implementation for running LLM (and VLM) inference with minimal setup and state-of-the-art performance, either locally or in the cloud.
- 94.1K
 #2 · vllm-project/vllm
vllm
vLLM is a library for fast LLM inference and serving, built around PagedAttention for efficient memory management of attention keys and values.
- 77.4K
 #3 · nomic-ai/gpt4all
gpt4all
GPT4All is a desktop application that runs large language models privately on everyday laptops and desktops, with no API calls or GPU required.
- 4

exo
47.9Kexo-explore/exo · Pythonexo turns a group of your own devices (Macs, Linux boxes) into a single AI cluster so you can run large AI models that would never fit on one machine, pooling their memory and compute together.
- 5

ray
44.1Kray-project/ray · PythonRay is an open-source framework for scaling AI and Python applications: a core distributed runtime plus a set of AI libraries that simplify ML compute.
- 6
colibri
42.6KJustVugg/colibri · CColibri is an open-source engine for running frontier mixture-of-experts (MoE) language models on hardware you already own — written in pure C with zero dependencies.
- 7
BitNet
41.2Kmicrosoft/BitNet · C++bitnet.cpp is Microsoft's official inference framework for 1-bit (ternary, 1.58-bit) large language models like BitNet b1.58, letting them run fast on CPUs and GPUs.
- 8
airllm
39.2Klyogavin/airllm · Jupyter NotebookAn open-source Python library that runs huge LLMs on tiny GPUs: a 70B model fits on a single 4GB card without quantization, distillation or pruning — even the 2.8T-parameter Kimi K3 runs in under 4GB.
- 9
sglang
37.3Ksgl-project/sglang · PythonSGLang is a high-performance serving framework for large language models and multimodal models, built to deliver low-latency, high-throughput inference from a single GPU up to large distributed clusters.
- 10

gitleaks
30.1Kgitleaks/gitleaks · GoGitleaks is a tool for detecting secrets like passwords, API keys, and tokens in git repos, files, or anything you pipe in via stdin.
- 11
Strata
27KNiko1221/Strata · C++Strata runs Qwen3.8-Flash-Next, a 125-billion-parameter AI model, on a normal gaming PC with one NVIDIA GPU (12-24GB VRAM) and 64GB of RAM, with a one-click installer for Windows and Linux.
- 12
llamafile
26.4Kmozilla-ai/llamafile · C++llamafile turns open LLMs into single-file executables: one file that runs a chat model locally on most operating systems and CPU architectures, with no installation. It is a Mozilla Builders project, now revamped by Mozilla.ai.
- 13
llm-action
25.2Kliguodongiot/llm-action · HTMLIt is a Chinese-language hub of in-depth tutorials on large language model engineering: training, fine-tuning, distributed training, inference, compression, evaluation, data engineering, LLMOps and AI infrastructure, organized as a big index linking the author's article series, many with companion code.
- 14
ds4
23.9Kantirez/ds4 · CDwarfStar (ds4) is a small, self-contained local inference engine specialized for running DeepSeek V4 Flash and PRO, plus GLM 5.2/5.3, on consumer hardware like high-memory Macs, NVIDIA GPUs, and AMD Strix Halo systems.
- 15

mlc-llm
23.3Kmlc-ai/mlc-llm · PythonMLC LLM is a machine learning compiler and high-performance deployment engine that lets you run large language models natively on almost any platform, from servers to phones to the browser.
- 16

omlx
22.9Kjundot/omlx · PythonoMLX is a local LLM inference server for Apple Silicon Macs. It serves text LLMs, vision models, OCR, embeddings and rerankers with continuous batching and a tiered KV cache, managed from the macOS menu bar.
- 17

eliza
19.6KelizaOS/eliza · TypeScriptelizaOS is an open-source TypeScript framework and product stack for autonomous AI agents: the core runtime, the Eliza app, the CLI, cloud services, native bridges, and first-party plugins in one monorepo. Bootable OS builds live in a separate elizaOS/os repo.
- 18
ktransformers
19.6Kkvcache-ai/ktransformers · PythonKTransformers is a research framework for efficient inference and fine-tuning of large language models through CPU-GPU heterogeneous computing, letting huge MoE models run on hardware that doesn't have enough VRAM to hold them entirely on GPU.
- 19
web-llm
19.3Kmlc-ai/web-llm · TypeScriptWebLLM runs large language models directly in the browser, accelerated by WebGPU — no server involved. It exposes the OpenAI API, so standard OpenAI-style code works against open models running locally.
- 20

codellama
16.2Kmeta-llama/codellama · PythonThis is Meta's official inference code for Code Llama, a family of large language models for code built on Llama 2. The repo itself is a minimal example for loading the models and running generation.
- 21
nano-vllm
15.9KGeeeekExplorer/nano-vllm · PythonNano-vLLM is a lightweight, from-scratch reimplementation of the vLLM inference engine for running large language models, built in roughly 1,200 lines of readable Python.
- 22
ggml
15.5Kggml-org/ggml · C++ggml is a plain C/C++ tensor library built for running machine learning models with minimal setup, no external dependencies, and support for CPU, GPU, NPU, and browser backends. It's the core engine that powers projects like llama.cpp.
- 23
Llama-Chinese
14.8KLlamaChinese/Llama-Chinese · PythonLlama-Chinese is a Chinese-language community project built around Meta's Llama models (Llama2, Llama3, Llama4). It provides Chinese pretraining and fine-tuning, a custom Atom model series optimized for Chinese, and resources for training, deploying and using Llama in Chinese for free commercial use.
- 24
FreeToken
14.6KFlashML-org/FreeToken · PythonFreeToken is an edge-native Mixture-of-Experts (MoE) serving engine built to run frontier-scale open-weight models, including 290B+ parameter models, on consumer hardware like gaming PCs.
- 25

litgpt
13.7KLightning-AI/litgpt · PythonLitGPT is a collection of 20+ high-performance large language models (Llama, Gemma, Phi, Qwen, Mistral, Falcon, TinyLlama and more) implemented from scratch, with ready-made recipes to pretrain, finetune, evaluate and deploy them at scale.
- 26

TensorRT
13.4KNVIDIA/TensorRT · C++TensorRT is NVIDIA's SDK for high-performance deep learning inference on NVIDIA GPUs. This repository holds the open source components: plugins, the ONNX parser, and sample applications that demonstrate TensorRT usage.
- 27

FlashMLA
13.1Kdeepseek-ai/FlashMLA · C++FlashMLA is DeepSeek's library of highly optimized CUDA attention kernels (Multi-head Latent Attention) that power the DeepSeek-V3 and DeepSeek-V3.2 models, covering both dense and sparse attention for prefill and decoding.
- 28
PaddleNLP
13KPaddlePaddle/PaddleNLP · PythonPaddleNLP is a large language model (LLM) and small language model (SLM) development toolkit built on the PaddlePaddle deep learning framework, offering efficient training, lossless compression, and high-performance inference for large models.
- 29
OpenLLM
12.6Kbentoml/OpenLLM · PythonOpenLLM lets you run open-source LLMs like Llama, DeepSeek, Mistral and Qwen as OpenAI-compatible API endpoints with a single command, including a built-in chat UI and cloud deployment support.
- 30
LMCache
12.1KLMCache/LMCache · PythonLMCache is a KV cache management layer for LLM inference that turns the KV cache from a temporary, per-process state into reusable, persistent 'AI-native knowledge' that can be shared across serving engines, reducing time-to-first-token and boosting throughput for long-context, multi-turn, and RAG workloads.
- 31
openvino
11Kopenvinotoolkit/openvino · C++OpenVINO is Intel's open-source toolkit for optimizing and deploying AI inference — it takes trained deep learning models for vision, speech, NLP, and generative AI and runs them faster, from edge devices to cloud servers.
- 32
llama-gpt
10.9Kgetumbrel/llama-gpt · TypeScriptLlamaGPT is a self-hosted, offline, ChatGPT-like chatbot powered by Llama 2 (and now Code Llama), so you get a familiar chat UI without sending any data to a third-party cloud.
- 33
text-generation-inference
10.9Khuggingface/text-generation-inference · PythonText Generation Inference (TGI) is a toolkit for deploying and serving large language models — a Rust, Python and gRPC server that powers Hugging Chat, the Inference API and Inference Endpoints at Hugging Face.
- 34

mistral-inference
10.8Kmistralai/mistral-inference · Jupyter NotebookThe official inference code for Mistral AI's open-weight models: minimal Python and CLI tooling to run models like Mixtral, Codestral, Pixtral and Mistral Large locally.
- 35

llama-cpp-python
10.6Kabetlen/llama-cpp-python · Python'llama-cpp-python' provides Python bindings for the llama.cpp C/C++ library, giving both low-level ctypes access and a high-level API for running GGUF language models locally for text completion, chat, embeddings and more.
- 36

petals
10.6Kbigscience-workshop/petals · PythonPetals lets you run big open LLMs at home, BitTorrent-style: you join a public swarm that serves models like Llama 3.1 (405B), Mixtral (8x22B), Falcon (40B+) and BLOOM (176B) for inference and fine-tuning right from your desktop or Google Colab, up to 10x faster than offloading.
- 37

ollama-python
10.6Kollama/ollama-python · PythonThis is the official Python library for Ollama, giving Python 3.8+ projects an easy way to call a local or cloud Ollama server to run large language models.
- 38
kimi-k3-in-c
9.1KFareedKhan-dev/kimi-k3-in-c · CAn inference engine for the 2.78-trillion-parameter Kimi K3 model, written in portable C99. It runs on a plain CPU in as little as 8 GB of RAM — no GPU, no BLAS, no framework — streaming the 1.56 TB checkpoint straight off disk.
- 39

tilelang
8.6Ktile-ai/tilelang · PythonTileLang (tile-lang) is a domain-specific language for writing high-performance GPU/CPU/NPU kernels like GEMM, Dequant GEMM, FlashAttention, and LinearAttention, using Pythonic syntax backed by a TVM-based compiler.
- 40
vllm-omni
7.2Kvllm-project/vllm-omni · PythonvLLM-Omni is an inference and serving framework that extends vLLM beyond text-only LLMs to omni-modality models, handling text, image, audio, video, and action outputs.
- 41
DeepSpec
7.2Kdeepseek-ai/DeepSpec · PythonDeepSpec is DeepSeek's full-stack Python codebase for training and evaluating draft models for speculative decoding — the technique where a small draft model accelerates a larger target LLM.
- 42

turboquant_plus
7KTheTom/turboquant_plus · PythonTurboQuant+ is the research home for TurboQuant (ICLR 2026), a KV cache compression method for transformer LLMs. It shrinks the KV cache 3.8-6.4x using PolarQuant plus Walsh-Hadamard rotation, and this repo holds the Python reference implementation, validation papers and benchmark data.
- 43
turbo-fieldfare
6.9Kdrumih/turbo-fieldfare · SwiftTurboFieldfare is a custom Swift and Metal runtime that runs the instruction-tuned Gemma 4 26B-A4B model on Apple Silicon Macs using only about 2 GB of RAM, even on 8 GB machines, by streaming only the experts needed for each token from SSD instead of loading the full 14.3 GB model.
- 44
ai-infra-book
6.7Kbojieli/ai-infra-book · PythonAn open-source book, 'Understanding AI Infra: Quantitative Analysis and System Design' by Bojie Li, that derives LLM inference and training system designs from hardware constraints and model architecture using quantitative, order-of-magnitude estimates.
- 45
Edge0
5.5KEdge0-AI/Edge0 · PythonEdge0 is an open-source streaming MoE (Mixture-of-Experts) inference framework that lets you run large MoE models, like a 35B-parameter model, using only about 2.5-2.9 GB of active RAM by streaming expert weights from SSD and predicting routing one step ahead.
- 46
Model-Optimizer
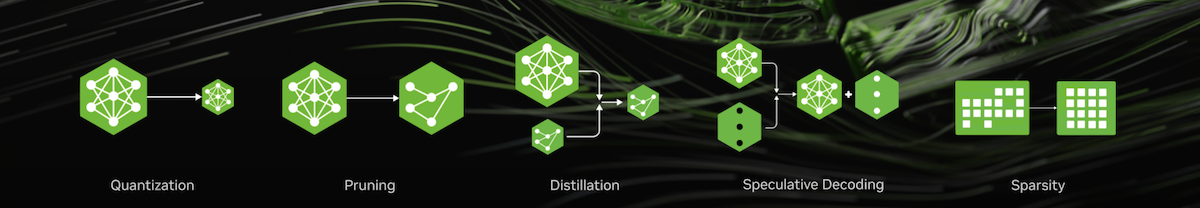
5.4KNVIDIA/Model-Optimizer · PythonNVIDIA Model Optimizer (ModelOpt) is a Python library that bundles state-of-the-art model-compression techniques - quantization, pruning, neural architecture search, distillation, speculative decoding and sparsity - to shrink and speed up deep learning models before deployment.
- 47
RuVector
4.6Kruvnet/RuVector · RustRuVector is a Rust-native persistent memory substrate for AI agents, combining local vector embeddings, graph relationships, feedback-driven learning, and memory lifecycle controls so agents can remember across sessions.
- 48
esp32-ai
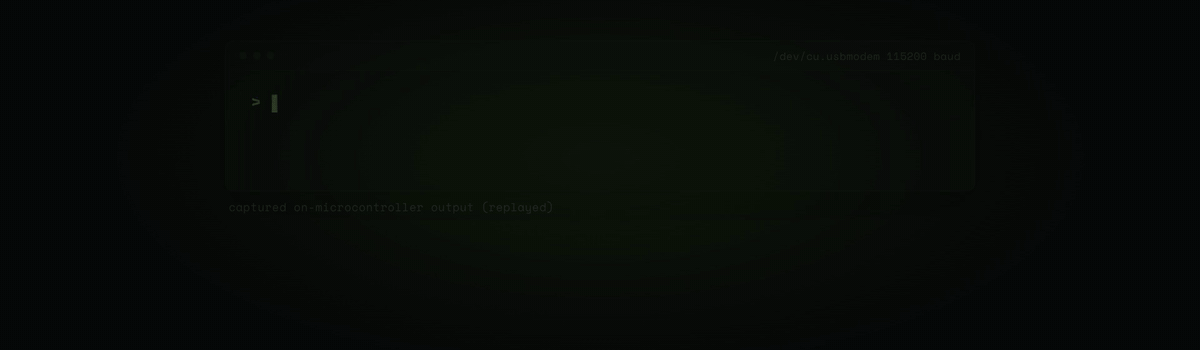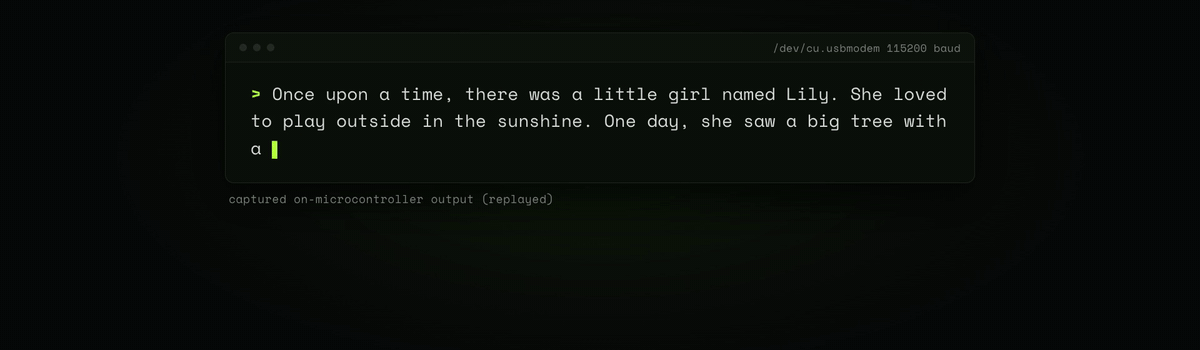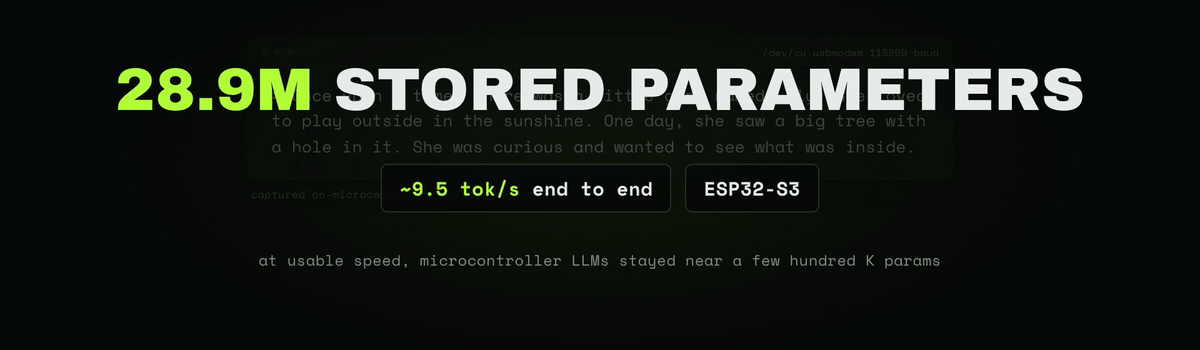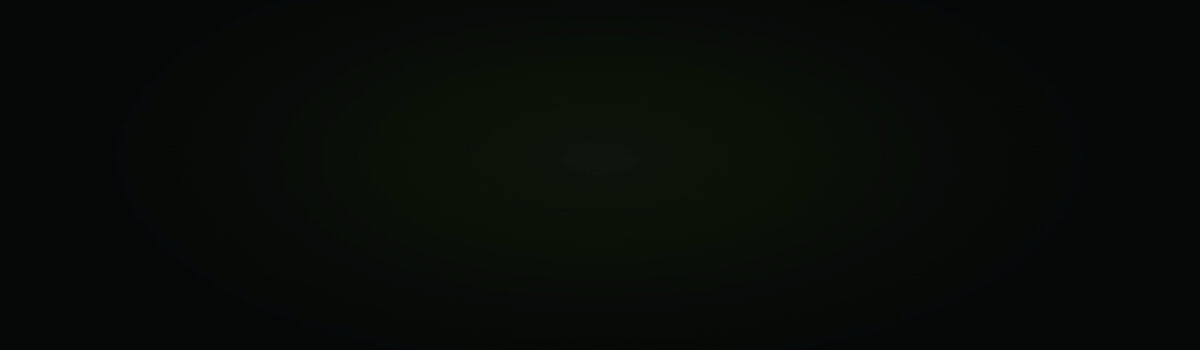
4.5KslvDev/esp32-ai · PythonA 28.9 million parameter language model that runs text generation entirely on an ESP32-S3 microcontroller, with the generated text shown on a small screen wired to the chip.
- 49
awesome-freellm-apis
4.4Kopen-free-llm-api/awesome-freellm-apisThis is a curated, machine-readable directory of 499+ free LLM APIs from 30+ providers (Google Gemini, NVIDIA NIM, Groq, OpenRouter, and more), letting you find, compare, and configure free models in seconds.
- 50

InfraTech
4.2KCalvinXKY/InfraTech · Jupyter NotebookInfraTech is a collection of Jupyter notebooks and articles sharing AI Infra knowledge: training/inference frameworks (PyTorch, vLLM/SGLang, slime/vime), performance acceleration, deep learning fundamentals and AI hardware/software basics.
- 51
Rapid-MLX
4Kraullenchai/Rapid-MLX · PythonRapid-MLX is a local LLM inference server for Apple Silicon Macs, built on MLX, that exposes OpenAI- and Anthropic-compatible APIs and focuses on reliable tool calling for coding agents like Claude Code and Codex CLI.
- 52
ZDTaichu5.0-9B
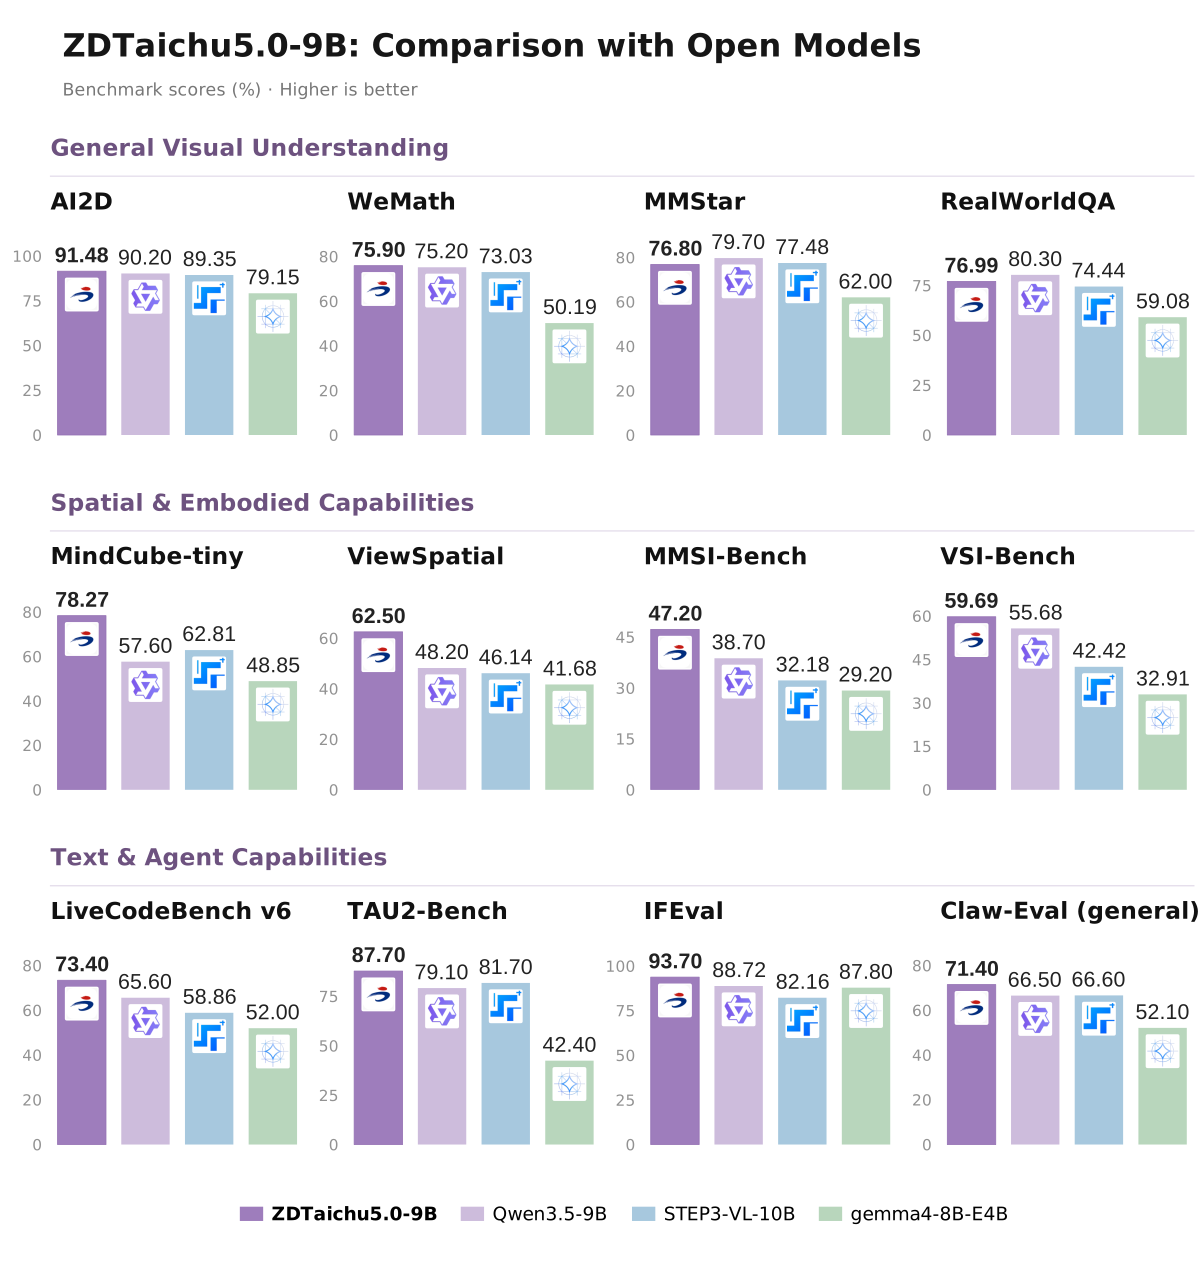
3.1KTaichu-AI/ZDTaichu5.0-9B · PythonZDTaichu5.0-9B is a multimodal foundation model that combines a Qwen3.5-9B language backbone with a C-RADIOv4-H vision encoder for general visual understanding, spatial reasoning, embodied-AI research and agentic tool use.
- 53
CLM
3.1KContrastive-LM/CLM · PythonCLM (Contrastive Language Models) is a 'System One' model trained with a contrastive learning objective that connects states and actions, served behind a TypeSafe-compatible API as CLM-8B. It is meant to be plugged into agents as a fast scorer/verifier for decisions, tool calls, and best-of-N candidates.
- 54
ai-agents-the-definitive-guide
2.8KNicolepcx/ai-agents-the-definitive-guide · Jupyter NotebookIt is the companion code repository for the book 'AI Agents - The Definitive Guide': a set of runnable Jupyter notebooks that walk through every chapter, from basic agent patterns to production deployment and threat modeling.
- 55
NanoJev
2.6KTianyuCodings/NanoJev · PythonA nano replica of Jev: a 0.6B-parameter parallel decision model that takes states and questions in and returns complete probability distributions — no output tokens are ever decoded.
- 56

warp
2.5Ksqliteai/warp · CWARP (Weight-Aware Runtime and Paging, formerly WASTE) is a dependency-free, embeddable C inference engine that runs huge mixture-of-experts models on consumer hardware by streaming each token's activated weights straight from NVMe — the full models, not distilled versions.
- 57
uzu
2.4Ktrymirai/uzu · Rustuzu is a high-performance inference engine for AI models that lets you run LLMs directly inside your app with zero latency, full data privacy, and no per-request inference costs.
- 58

HyperQwen
2.1Ksyv-ai/HyperQwen · PythonHyperQwen is a self-hosted serving setup that runs the Qwen3.8-27B model on a single 24 GB consumer GPU (like an RTX 3090) using vLLM, exposing it through an OpenAI-compatible API.
- 59
mlx-serve
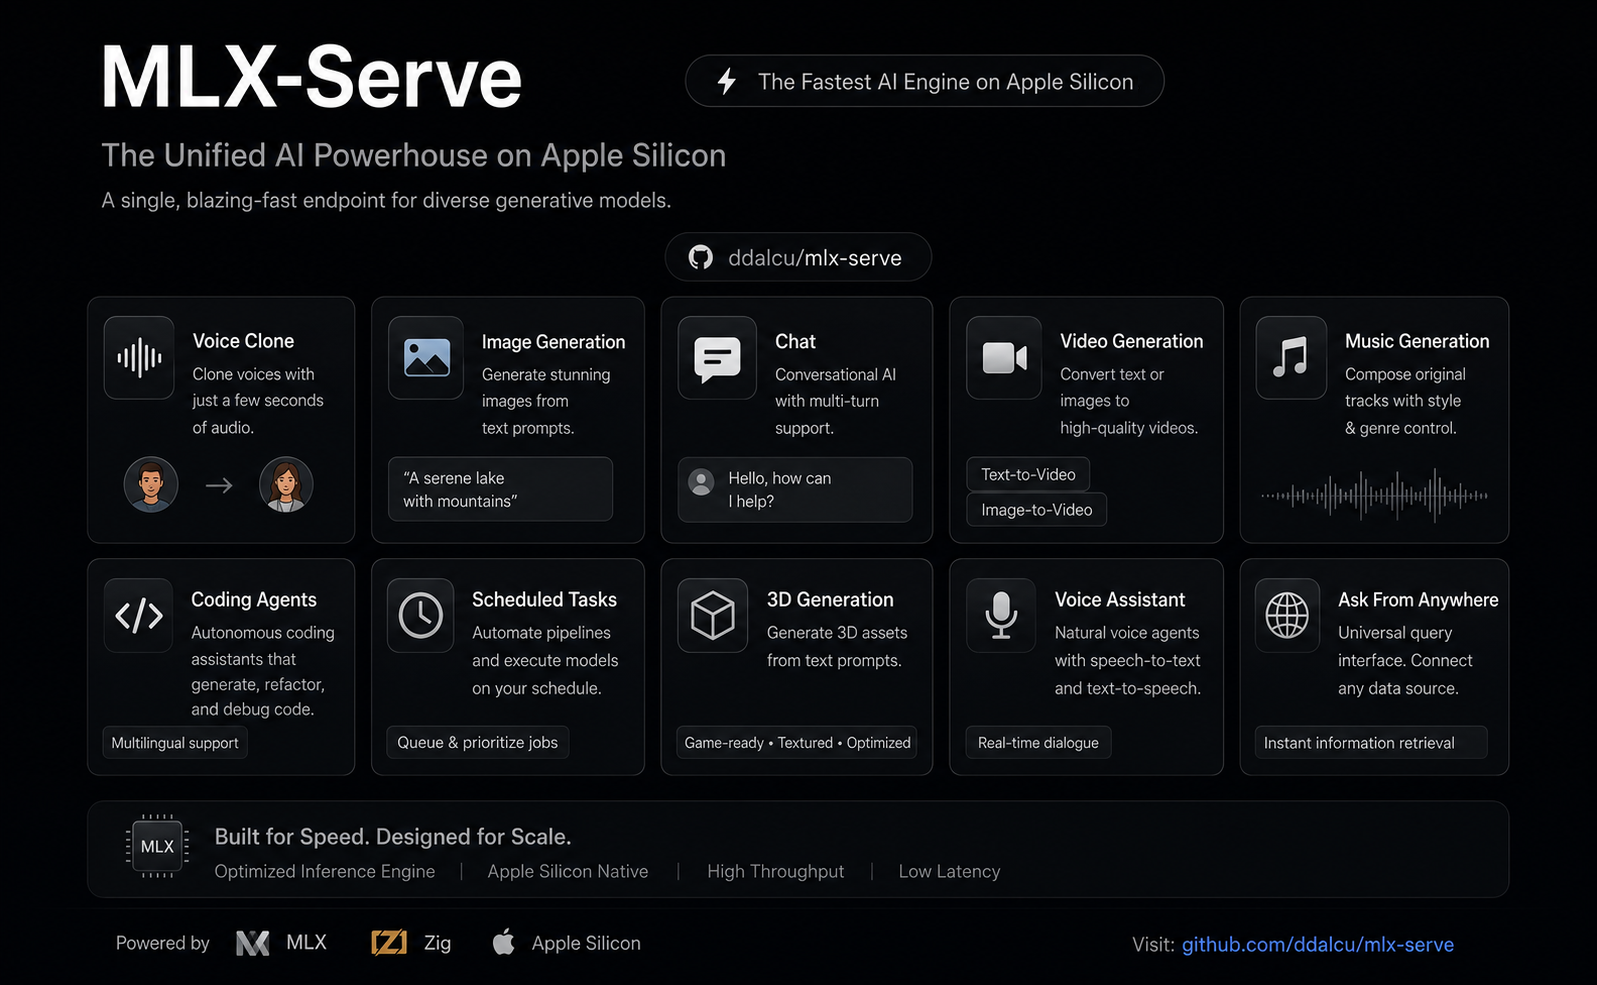
2Kddalcu/mlx-serve · Zigmlx-serve is a native local inference server for Apple Silicon Macs that runs MLX and GGUF language models and exposes OpenAI-, Anthropic-, and Ollama-compatible APIs, plus generates images, video, music, speech, and 3D models, all without Python or a cloud connection.
- 60

beta9
1.8Kbeam-cloud/beta9 · GoAn open-source runtime for serverless AI workloads — it runs Python code in autoscaling GPU containers that scale to zero. It's also the engine powering Beam, a fully managed cloud.
- 61
ai-engineering-interview-questions-company-wise
1.8Kpallavi-shekhar/ai-engineering-interview-questions-company-wise · MarkdownA free, continuously updated cheat sheet of real interview questions asked in AI Engineering interviews at 35 companies (Anthropic, OpenAI, Google DeepMind, Meta, NVIDIA, Databricks and more), organized company by company with answers linked wherever available.
- 62
laya-coreml
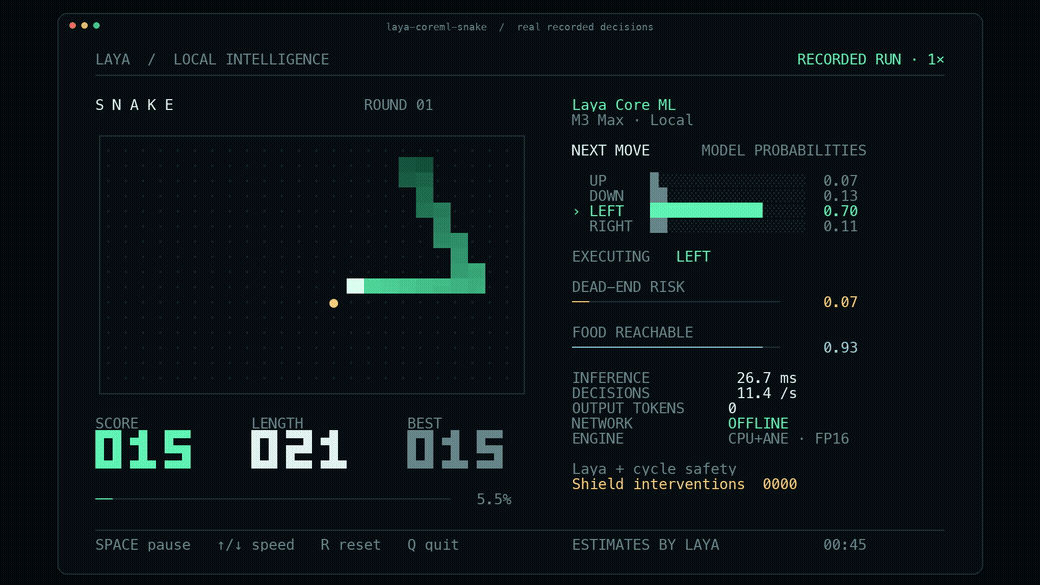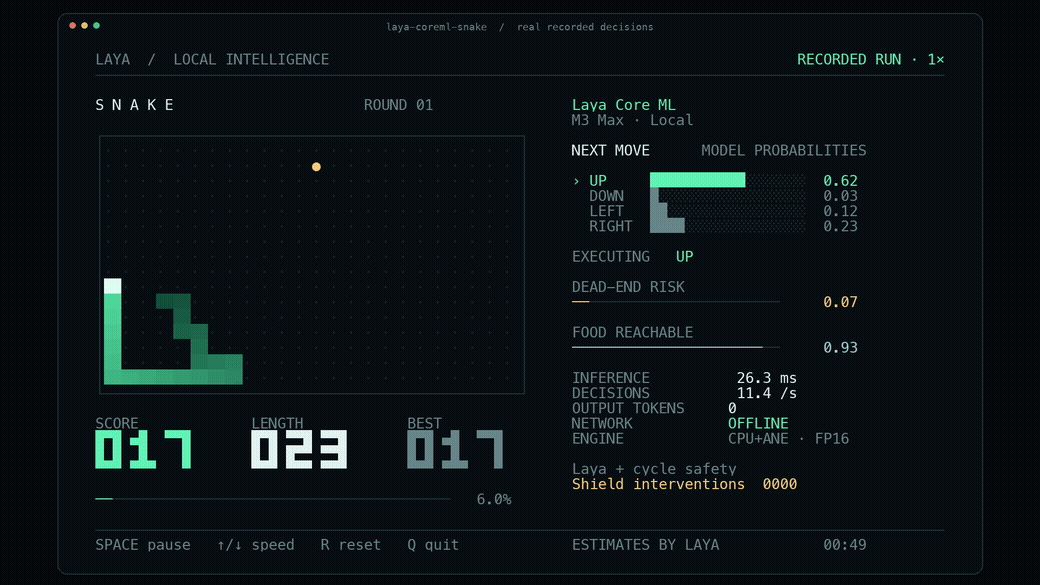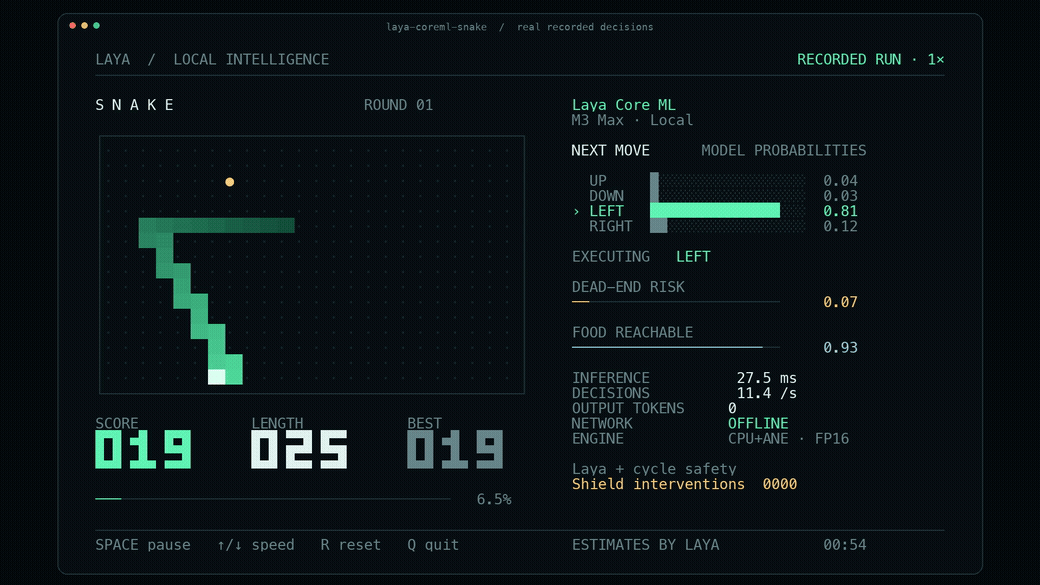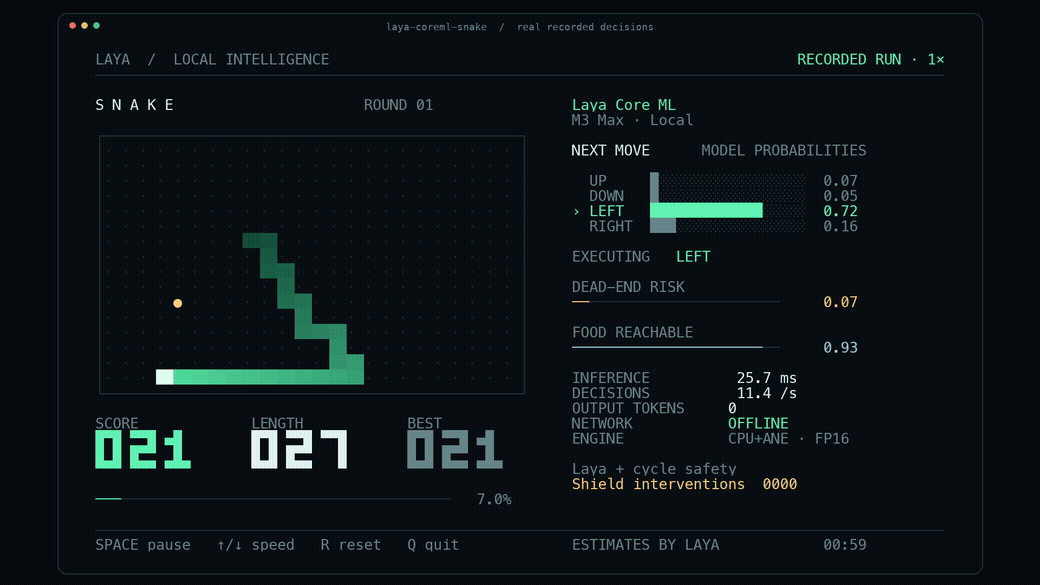
1.6Kmizorewww/laya-coreml · PythonIt's an open-weight Python port of Laya that answers typed questions — pick an option, an ordinal score, or yes/no — locally on Apple Silicon through Core ML and the Neural Engine, generating zero text tokens.
- 63
jeff
1.5Kfirelex/jeff · PythonJeff is a family of small (0.8B-2B parameter) open-weight models fine-tuned from Qwen3.5 and Gemma 4 that act as fast 'System 1' decision-makers: you describe a situation and a list of options in plain text, and Jeff returns a calibrated probability for each option from a single forward pass, with no generated text to parse.
- 64
zero-to-sglang
1.5Kdatawhalechina/zero-to-sglang · PythonThe official SGLang x Datawhale course on LLM inference: it teaches how inference engines work, has you build a mini-sglang from scratch, and then digs into the real SGLang source code.
- 65

TensorFold
1.4Kashhart/TensorFold · ZigTensorFold is an LLM inference engine that serves open-weight language models through an OpenAI-compatible API, running them on Apple Silicon via MLX or on NVIDIA GPUs via CUDA.
- 66
jev
1.4Kfeder-cr/jev · C++jevos-1b is a free, open-source yes/no decision engine that runs locally on your laptop's CPU, returning the probability that the answer is 'yes' for a given text plus question in about 50-220 ms, as a self-hosted alternative to the cloud-based Jev service.
- 67
lift
1.2Kdatalab-to/lift · Pythonlift is an open-source 9B vision-language model and toolkit that extracts structured JSON data from PDFs and images by matching a schema you provide, using schema-constrained decoding to guarantee valid output.
- 68
decider
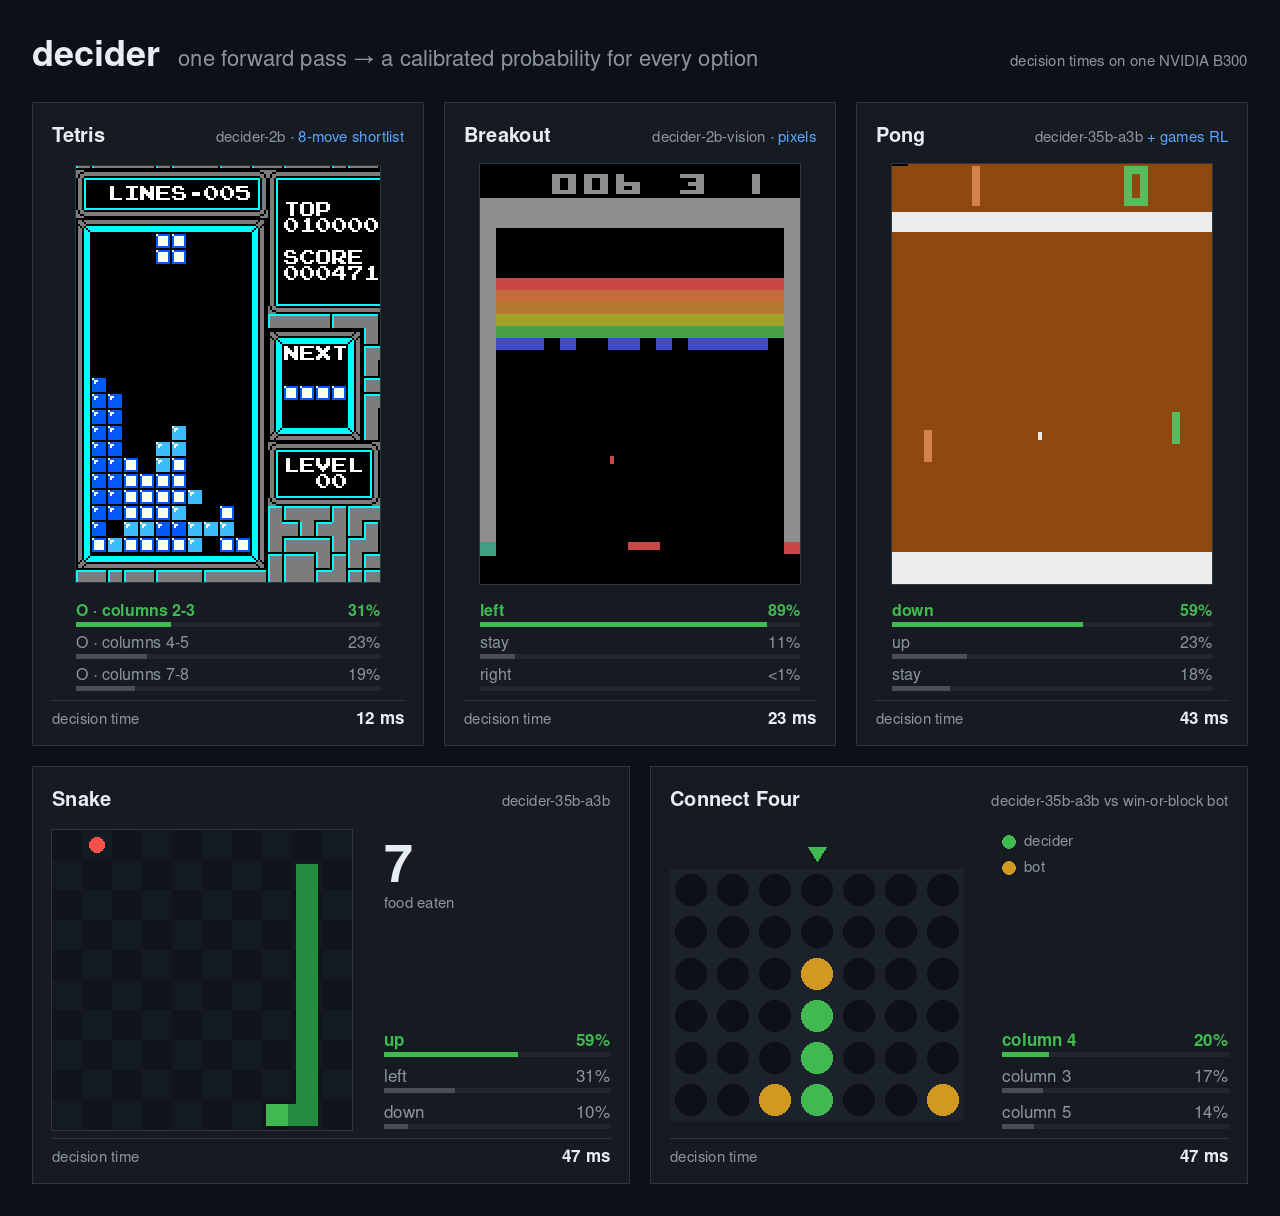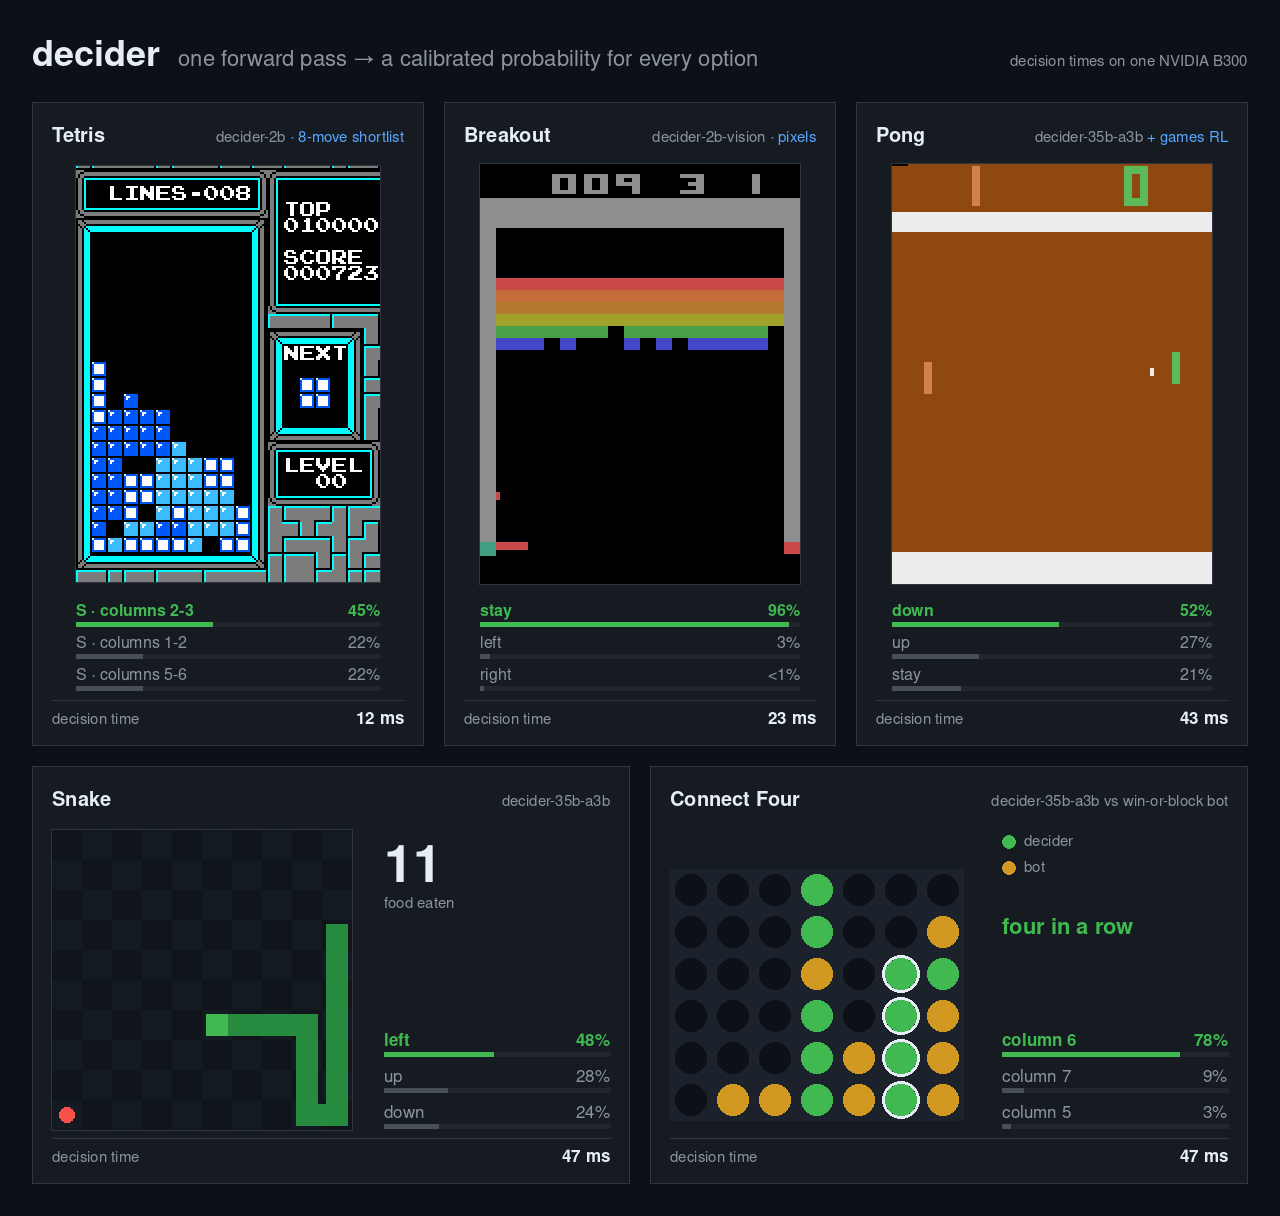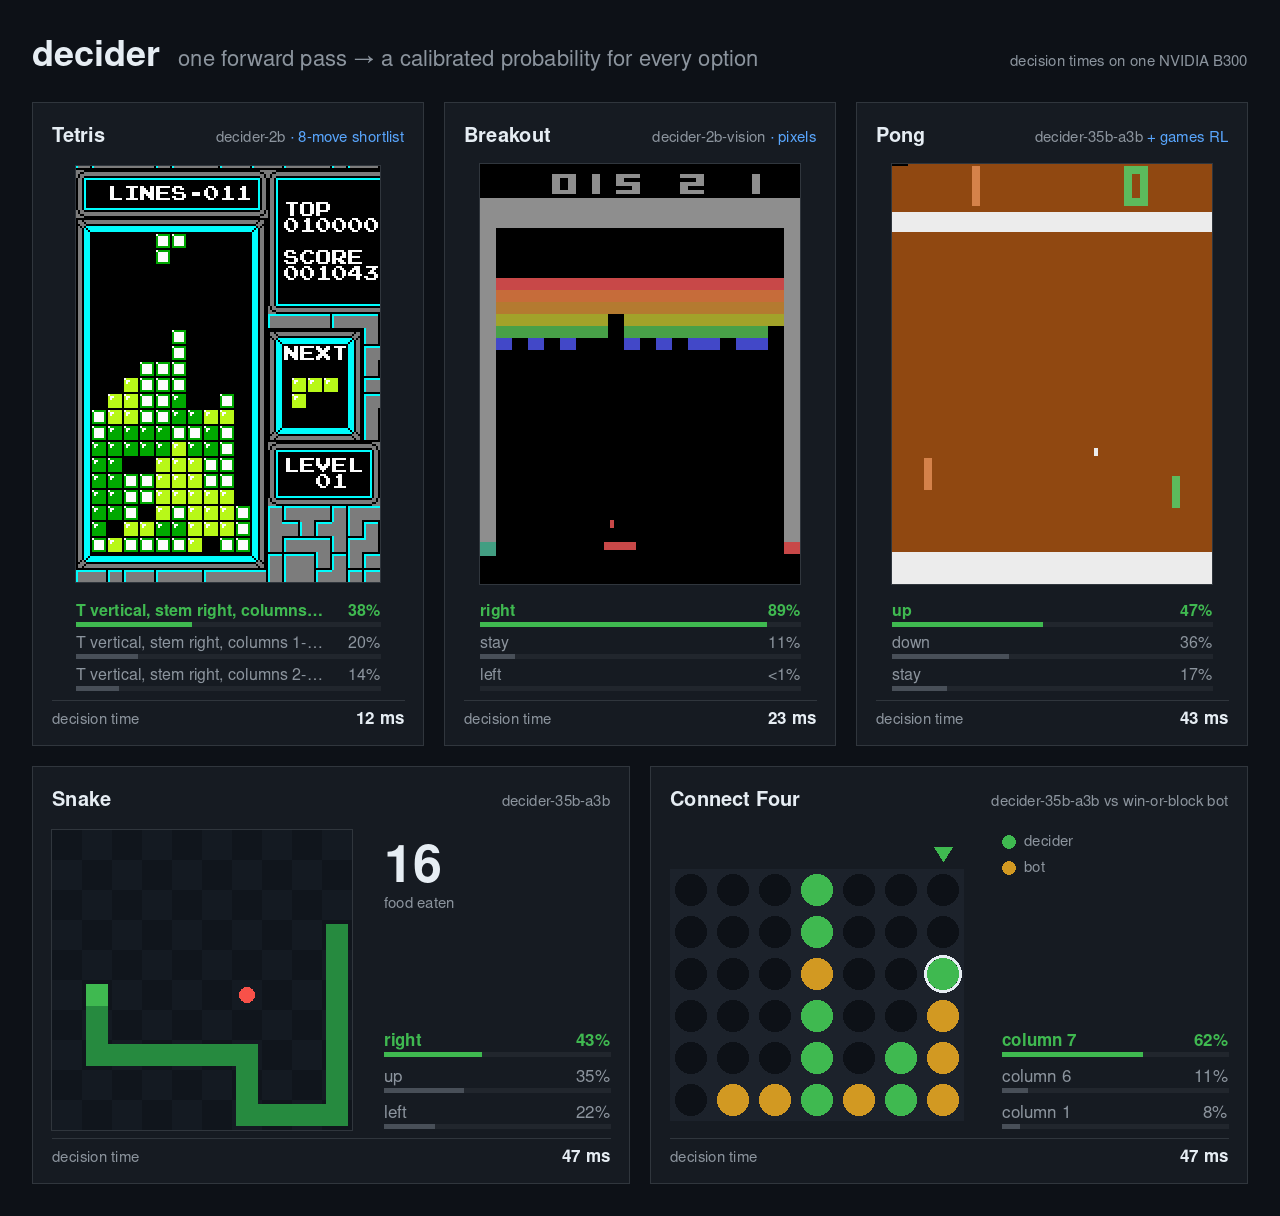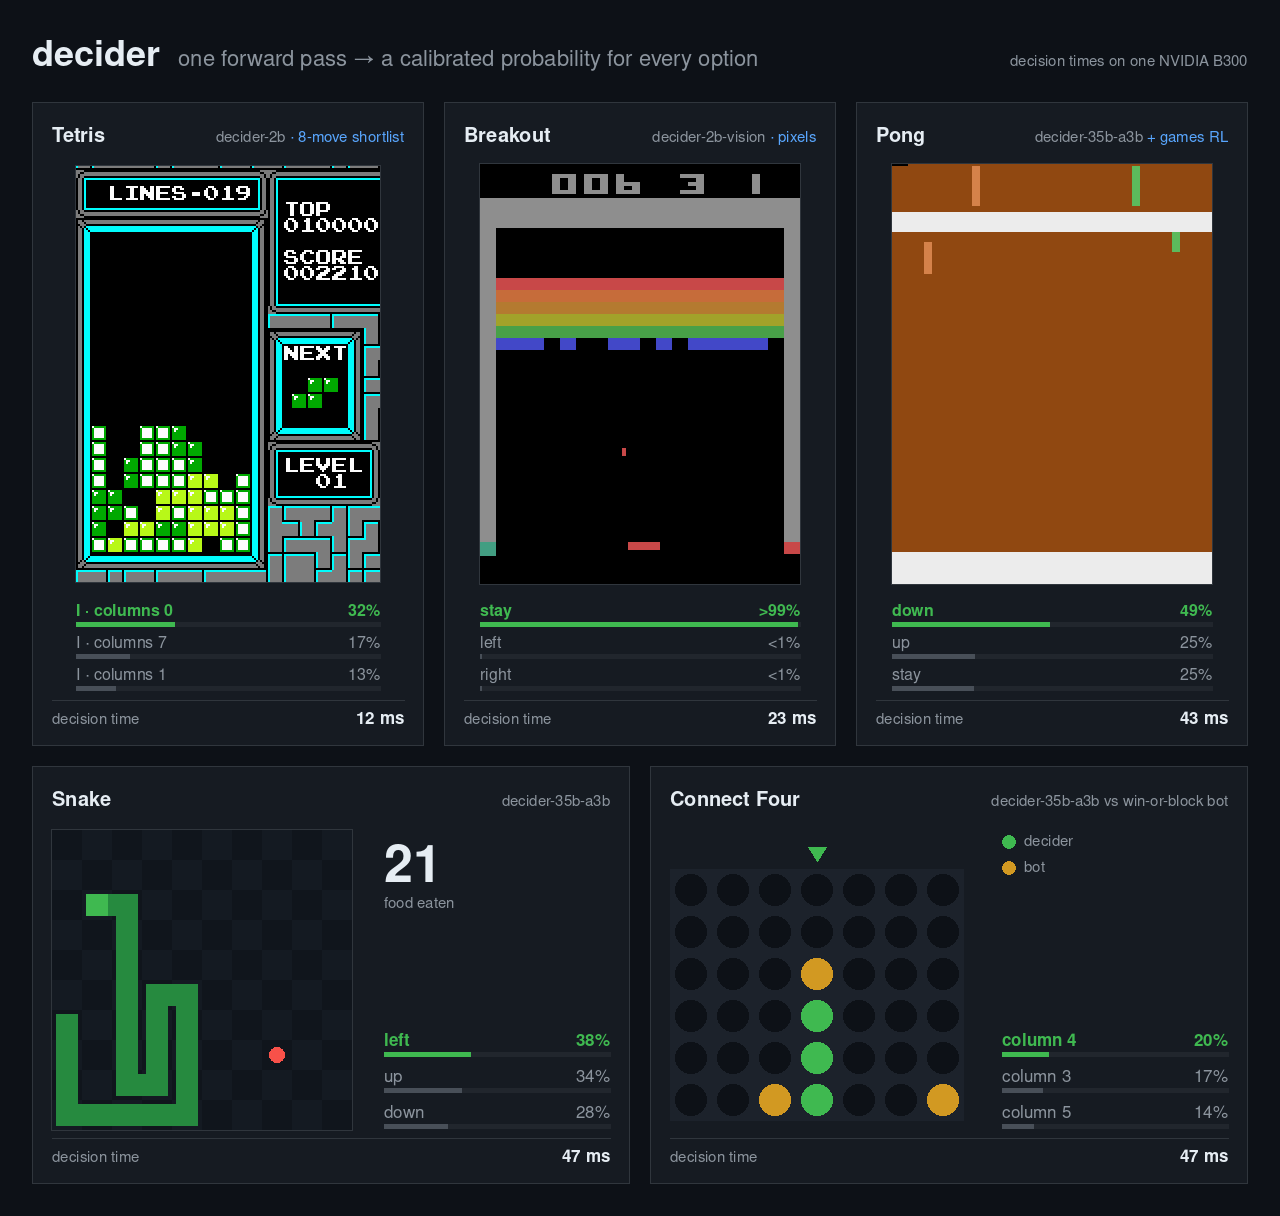
1.2KMapika/decider · PythonDecider is a family of language models fine-tuned from Qwen3.5 that don't generate text; instead they read a state plus a set of typed questions and return calibrated probability distributions for every question in one forward pass.
- 69
backburner
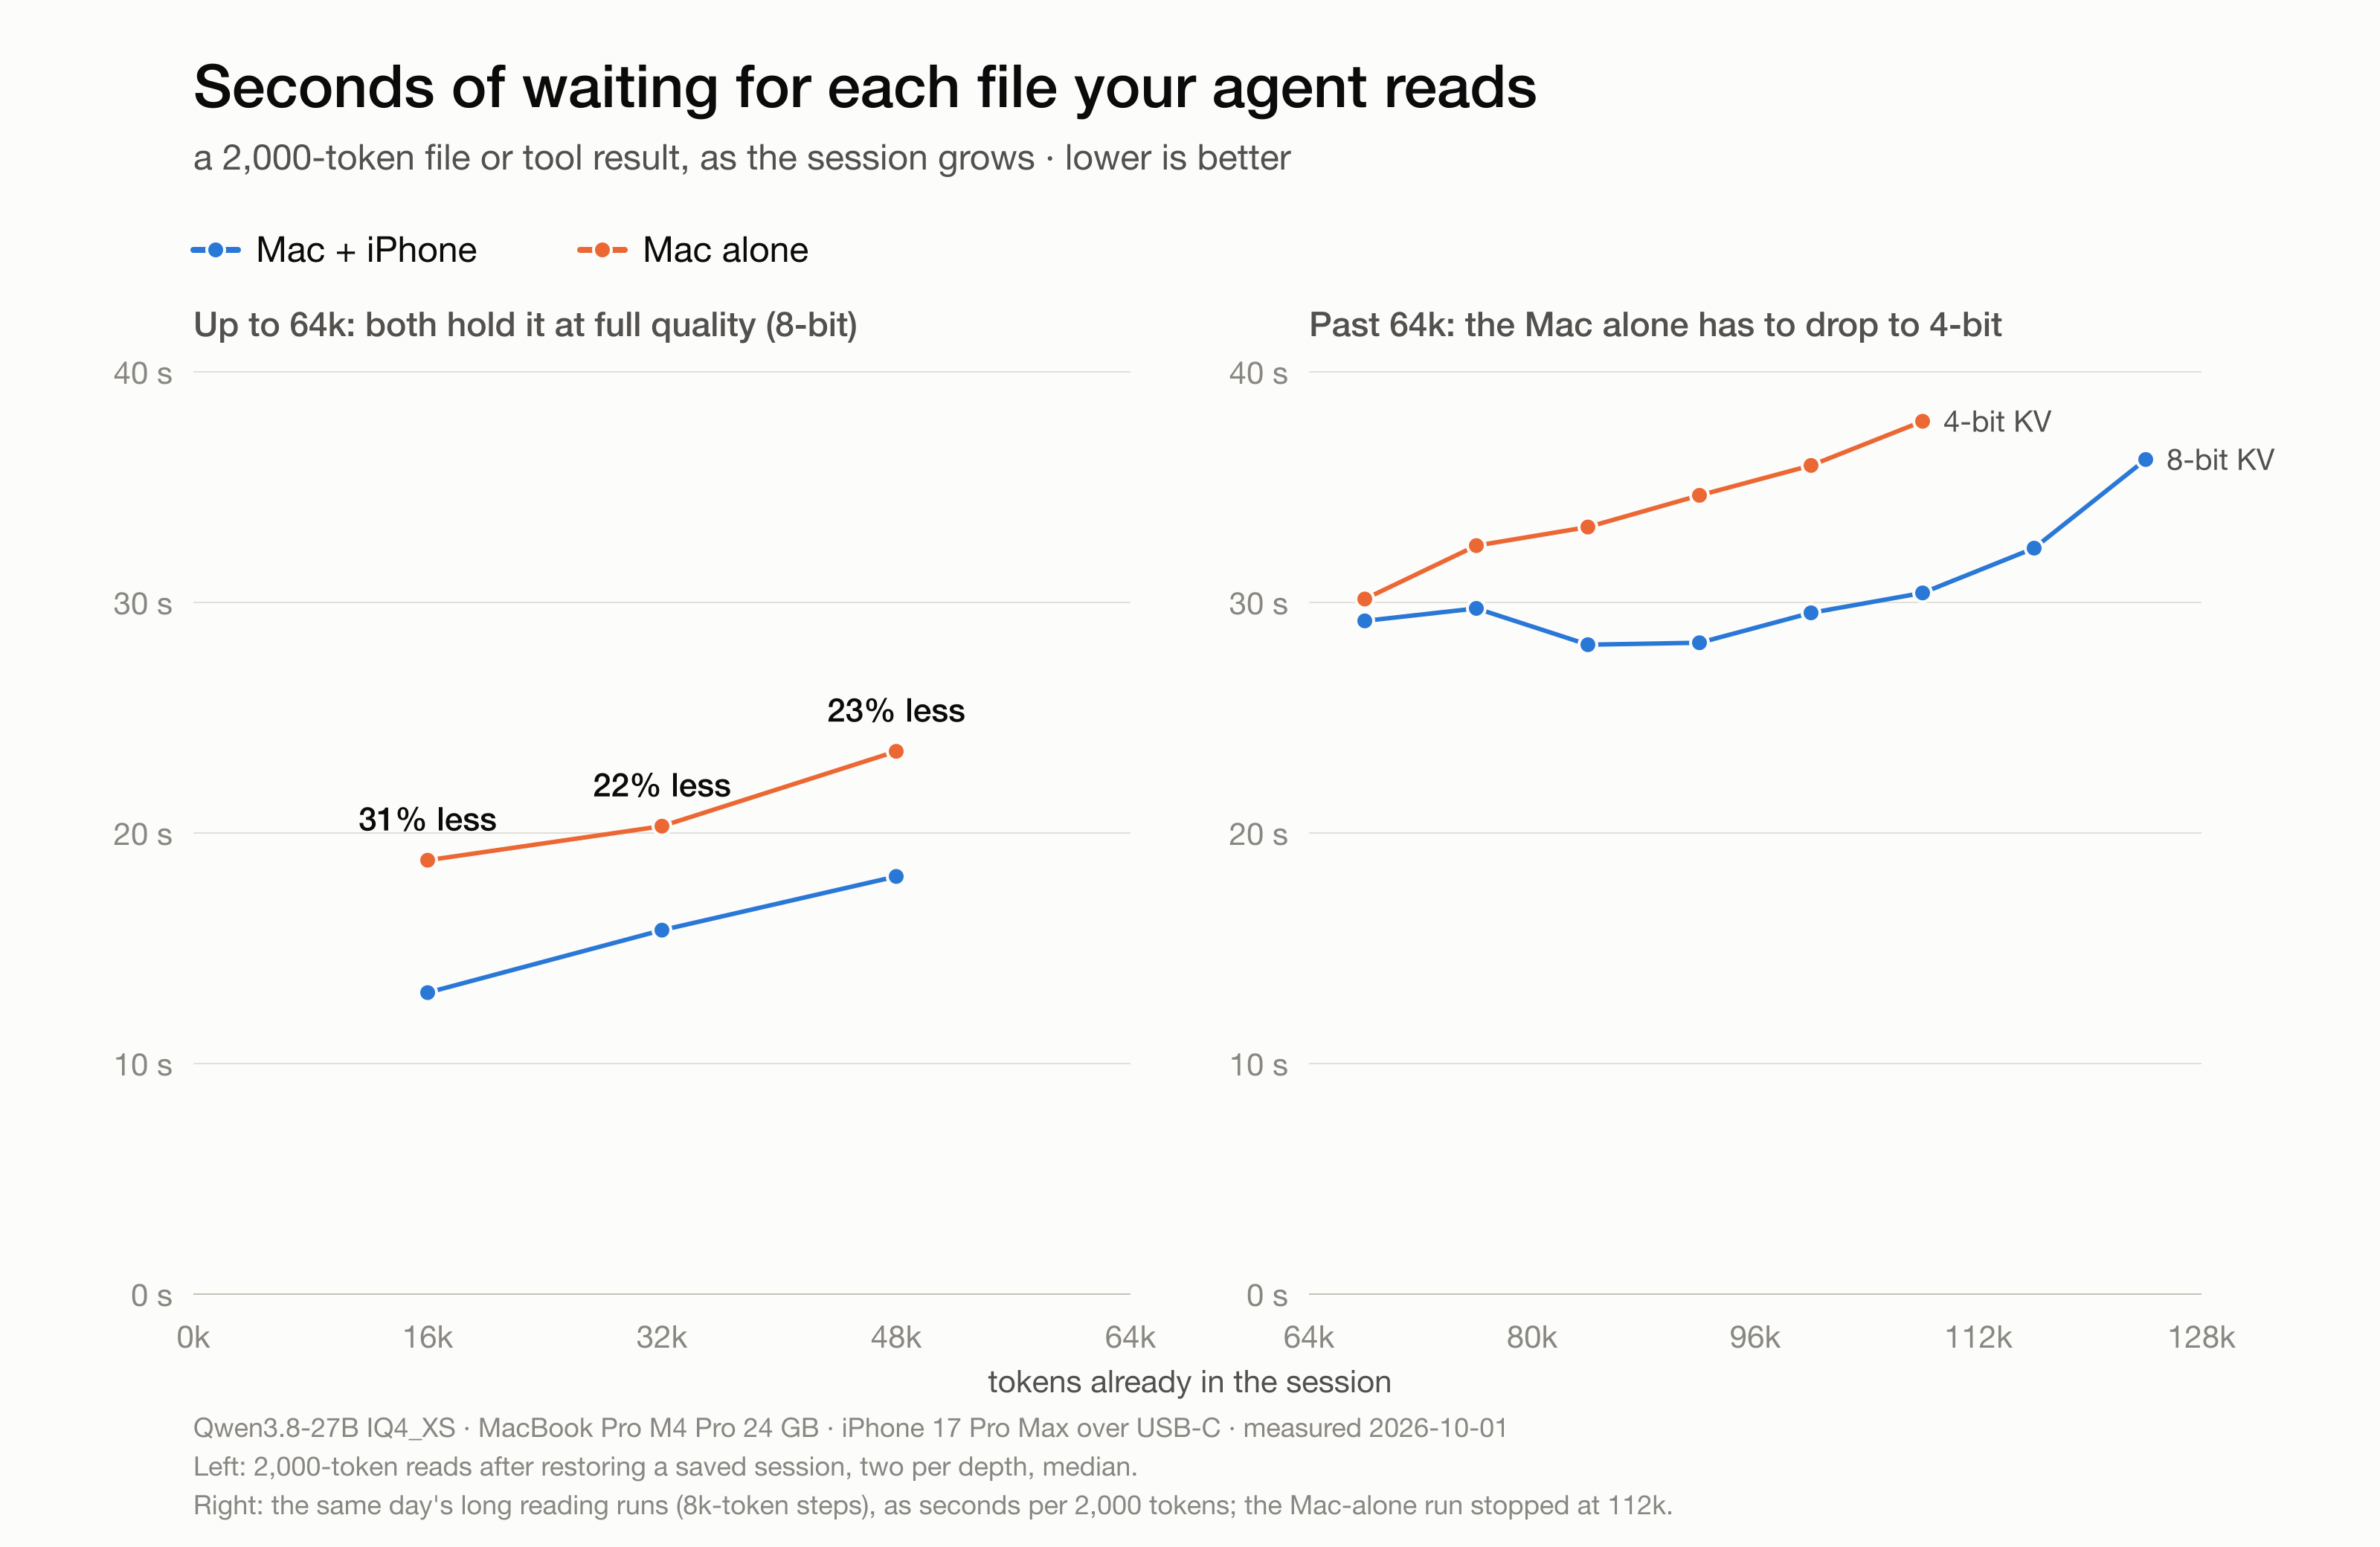
1KStayLameBro/backburner · PythonBackburner lets a nearby iPhone act as a coprocessor for your Mac so a locally-run 27B LLM (Qwen3.8-27B) reads prompts faster and holds far more context. The phone connects over a 10 Gb/s USB-C cable and offloads part of the model's layers plus storage/attention for old context.
- 70

project-maya
1Kmw00/project-maya · C++Project Maya lets you run GLM-5.3-Flash, a 321-billion-parameter mixture-of-experts AI model, on your own NVIDIA GPU(s) by streaming the model's experts across VRAM, RAM and NVMe SSD as the conversation needs them.
- 71
TypeLLM
960TypeLLM/TypeLLM · PythonTypeLLM adds type-safe, schema-guaranteed output generation to existing open autoregressive LLMs, without changing their weights or architecture, letting models still think freely while returning typed JSON Schema-constrained answers.
- 72

awesome-hosting
943dalisoft/awesome-hostingA curated directory of hosting providers — from VPS and static hosts to databases, GPU clouds and AI inference — comparing each one by the price of its cheapest plan.
- 73
rizzo-flow
904Rizzo-AI-Academy/rizzo-flow · PythonRizzo Flow is an open-source, local-first implementation of TypeSafe's Jev 'System One' model: it takes unstructured state as input and returns typed, probabilistic decisions (a yes/no, a choice, a score, a number) without generating a single text token, running entirely on your own hardware via llama.cpp.
- 74

deltafin
850gavamedia/deltafin · RustDeltafin is a native Rust binary that runs the full, unpruned 2.8-trillion-parameter Kimi K3 model on a single consumer machine, keeping all 16 experts active, plus an OpenAI-compatible API server for local chat and coding agents.
- 75
Intern-Decision
829InternLM/Intern-Decision · PythonIntern-Decision turns a state, optional images, and multiple typed questions into decisions with probabilities, by fine-tuning the language backbone of Qwen3.5 while freezing its vision tower and projector.
- 76
solo_jev
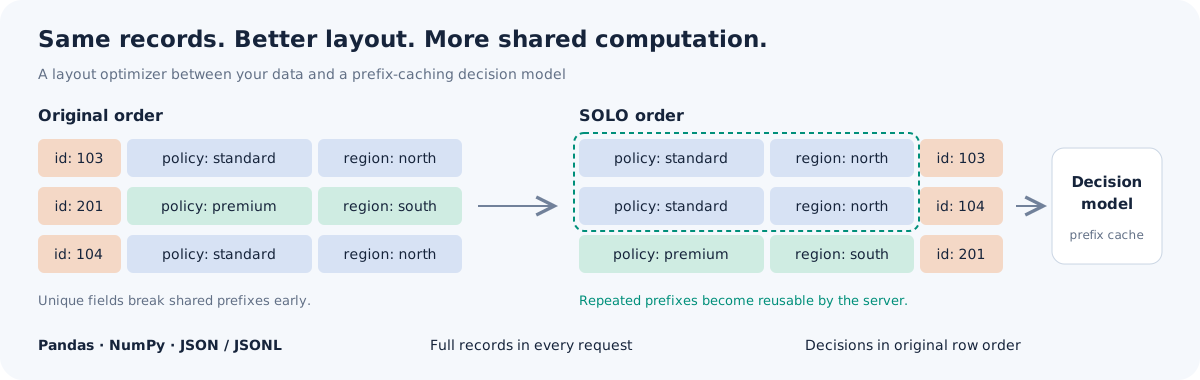
7640814wdwd/solo_jev · PythonSOLO reorders the rows and fields of a dataset so an LLM decision backend with prefix caching can reuse computation across requests, running a natural-language decision over every row while returning results in the original row order.
- 77
openTPU
764FeSens/openTPU · VerilogopenTPU is an open-source AI accelerator whose hardware design, instruction set, simulator, compiler and profiler were all built by AI agents, and it runs real LLMs like Qwen3 and LFM2.5 on an FPGA PCIe card.
- 78

GLM-5.3-Flash-EXL3-2x-DGX-Sparks
735MiaAI-Lab/GLM-5.3-Flash-EXL3-2x-DGX-Sparks · PythonA deployment recipe and Docker image that serves the GLM-5.3-Flash model as an OpenAI-compatible vLLM endpoint across 2-4 NVIDIA DGX Spark (GB10) kits, using a custom EXL3/TR3 4-bit quantization of the weights.
- 79
ai-system-design
705amitshekhariitbhu/ai-system-design · MarkdownA free, open-source guide that teaches AI System Design step by step: how to combine GPUs, inference servers, caches, vector databases, AI agents, guardrails, and evals into one system that is fast, cheap, reliable, and safe.
- 80

kaggle-tpu-lab
670ARahim3/kaggle-tpu-lab · PythonA recipe that serves frontier-class open LLMs — GLM-5.3-Flash 320B MoE and Qwen3.8-27B bf16 — on Kaggle's free TPU v5e-8, exposing a public OpenAI-compatible (and Anthropic-compatible) endpoint you can plug into coding agents like Claude Code, Codex, opencode, or pi.
- 81
strands-decider
664strands-labs/strands-decider · PythonStrands Decider is a small, fast 'system one' decision model built for agentic workflows. Instead of generating free text like an LLM, it picks between a set of options or rates something on a scale, and returns a calibrated confidence score for every decision.
- 82
StartLux-Decision
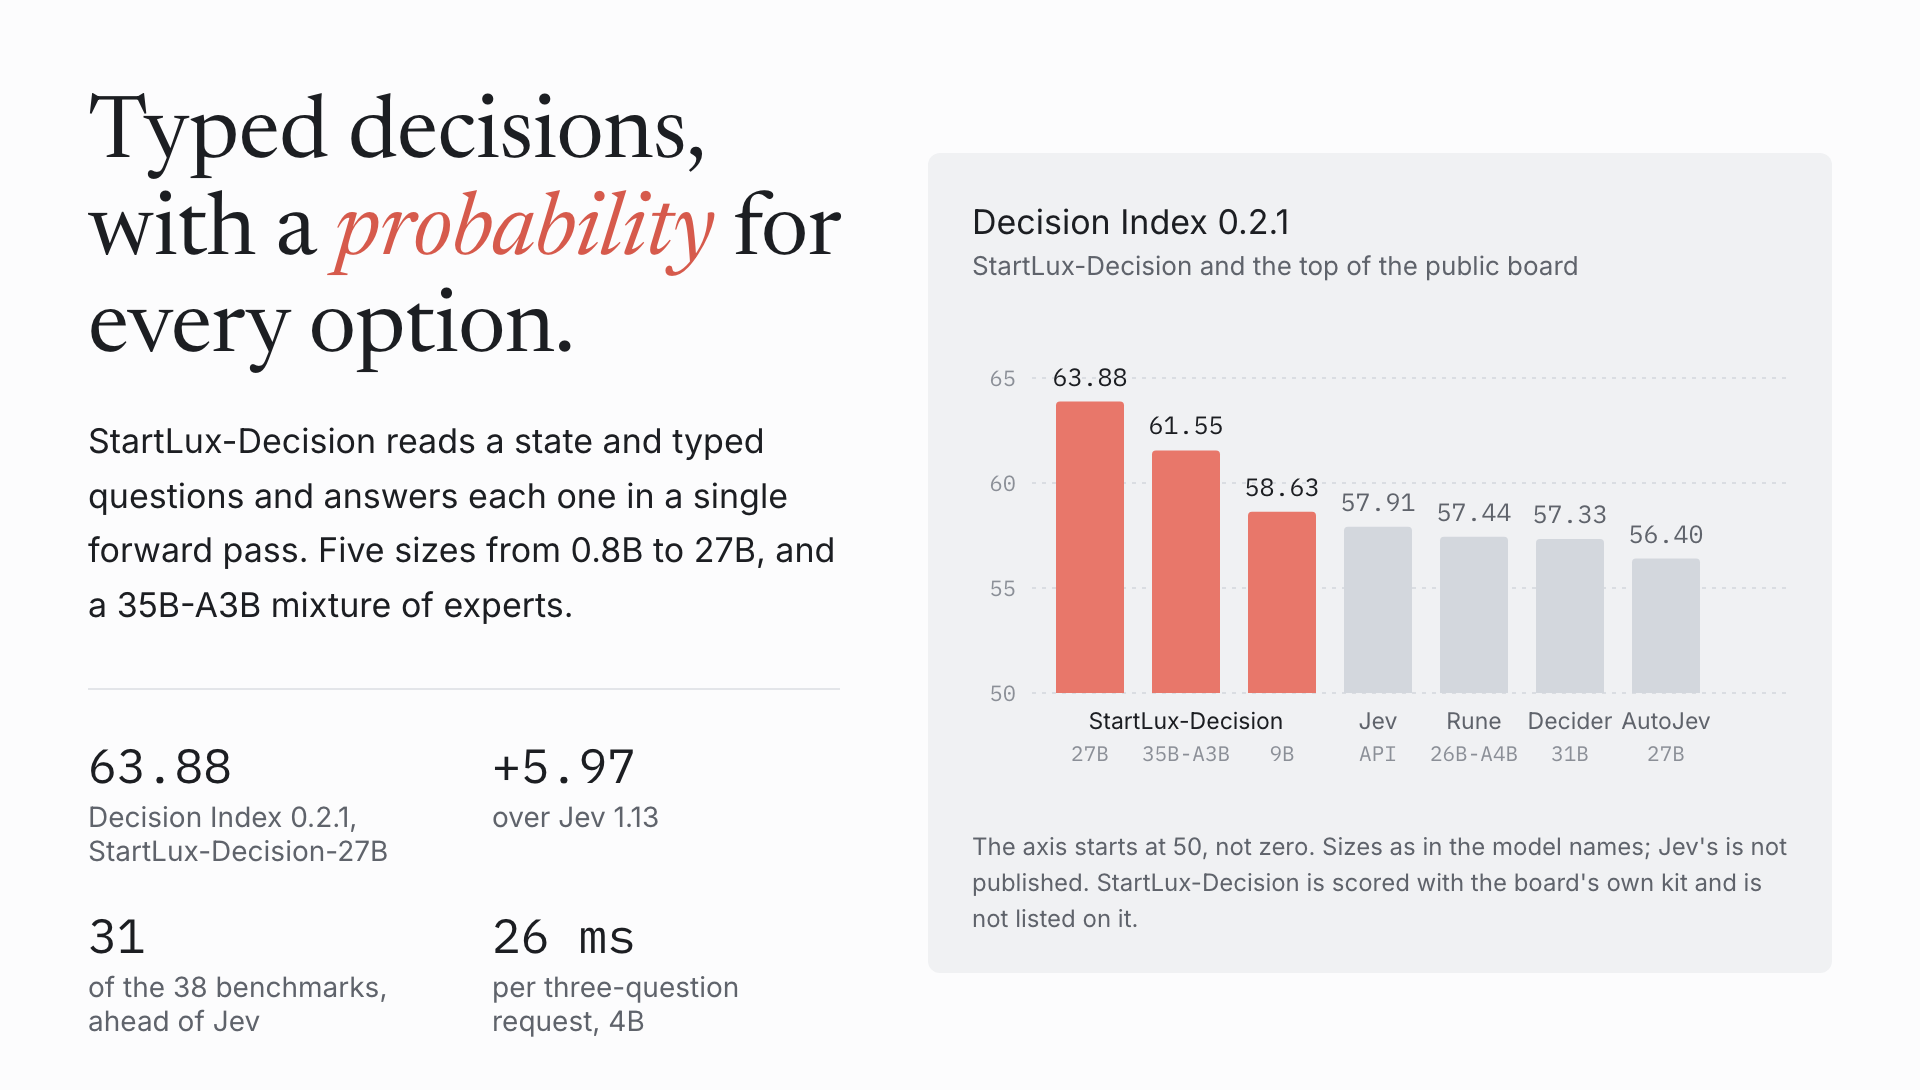
648StartLuxLabs/StartLux-Decision · PythonStartLux-Decision is a family of typed decision models (five dense sizes from 0.8B to 27B plus a 35B-A3B mixture-of-experts) that answer a question with a probability for each option instead of generating text.
- 83
Qwen3.8-Flash-Next-Single-DGX-Spark
610MiaAI-Lab/Qwen3.8-Flash-Next-Single-DGX-Spark · PythonA self-contained recipe for serving the Qwen3.8-Flash-Next-NVFP4 checkpoint from a single NVIDIA DGX Spark machine's unified memory, using vLLM with the PLE table offloaded and memory-mapped.
- 84

pooled
596Nehanth/pooled · JavaScriptSwarmLLM pools the WebGPU power of several devices open in browser tabs to run large open models that no single device could hold on its own, splitting the model into layer slices and passing a small activation vector between devices over WebRTC.
- 85
Qwen3.8-27B-16gb-NVIDIA-GPUs-one-click-install
587MiaAI-Lab/Qwen3.8-27B-16gb-NVIDIA-GPUs-one-click-install · PythonA one-click installer and serving kit for running Qwen3.8-27B locally on a single consumer NVIDIA GPU (12-32+ GB VRAM), on Windows or Linux.
- 86
DeepGEMM-Ascend
586deepseek-ai/DeepGEMM-Ascend · C++DeepGEMM-Ascend is a port of DeepSeek's DeepGEMM matrix-multiplication kernel library to Huawei Ascend NPUs, fully API-compatible with the original and supporting BF16, FP8, and FP4 GEMM along with MQA logits and MegaMoE operators.
- 87
djev-run
584taeold/djev-run · HTMLdjev-run serves DiffusionGemma-Jev (djev) behind a TypeSafe AI compatible API on Google Cloud Run with an NVIDIA RTX PRO 6000 Blackwell or L4 GPU, or runs it directly inside Google Colab Pro via colab.ipynb; it is built on mmastrac/djev.
- 88
apex-inference-chip
581SigmanticAI/apex-inference-chip · PythonAPEX is an open, verification-first hardware design for LLM inference: one transformer decoder layer written in real RTL that runs Qwen2.5-0.5B on an FPGA, with every circuit block checked bit-exact against a software golden model.
- 89

slotstream
477carloslfu/slotstream · SwiftSlotstream lets you run a 105 GB AI model (Qwen3.8-Flash-Next, a 125B-parameter mixture-of-experts model) on Macs with only 16 to 64 GB of RAM, by streaming most of the model from SSD and caching the busiest experts in memory.
- 90
Qwen3.8-27B-SGLang-DGX-Spark
474MiaAI-Lab/Qwen3.8-27B-SGLang-DGX-Spark · ShellA set of opinionated, ready-to-run Docker scripts that serve the Qwen3.8-27B model through SGLang on an NVIDIA DGX Spark (GB10, aarch64), offering three swap-in speculative-decoding modes — EAGLE/MTP, DSpark, and DFlash2 — each tuned with on-device measurements rather than guesses.
- 91

qwen3.8-Flash-DGX
456blazux/qwen3.8-Flash-DGX · PythonA recipe (scripts plus a patched Docker image) for serving the ~176B-parameter Qwen3.8-Flash-Next model with vLLM on a single NVIDIA DGX Spark (GB10). It solves the problem that the 126 GiB NVFP4 checkpoint doesn't fit next to a usable KV cache in the Spark's 128 GB unified memory, by streaming a 48 GiB lookup table from NVMe via mmap instead of keeping it resident.
- 92
GLM-5.3-Flash-EXL3-2x-DGX-Sparks-TensorFold
453MiaAI-Lab/GLM-5.3-Flash-EXL3-2x-DGX-Sparks-TensorFold · PythonThis project serves the GLM-5.3-Flash language model as an OpenAI-compatible API, with vision and video input, running across two linked NVIDIA DGX Spark machines (GB10, 128GB each) using TensorFold.
- 93
Qwen3.8-Flash-Next
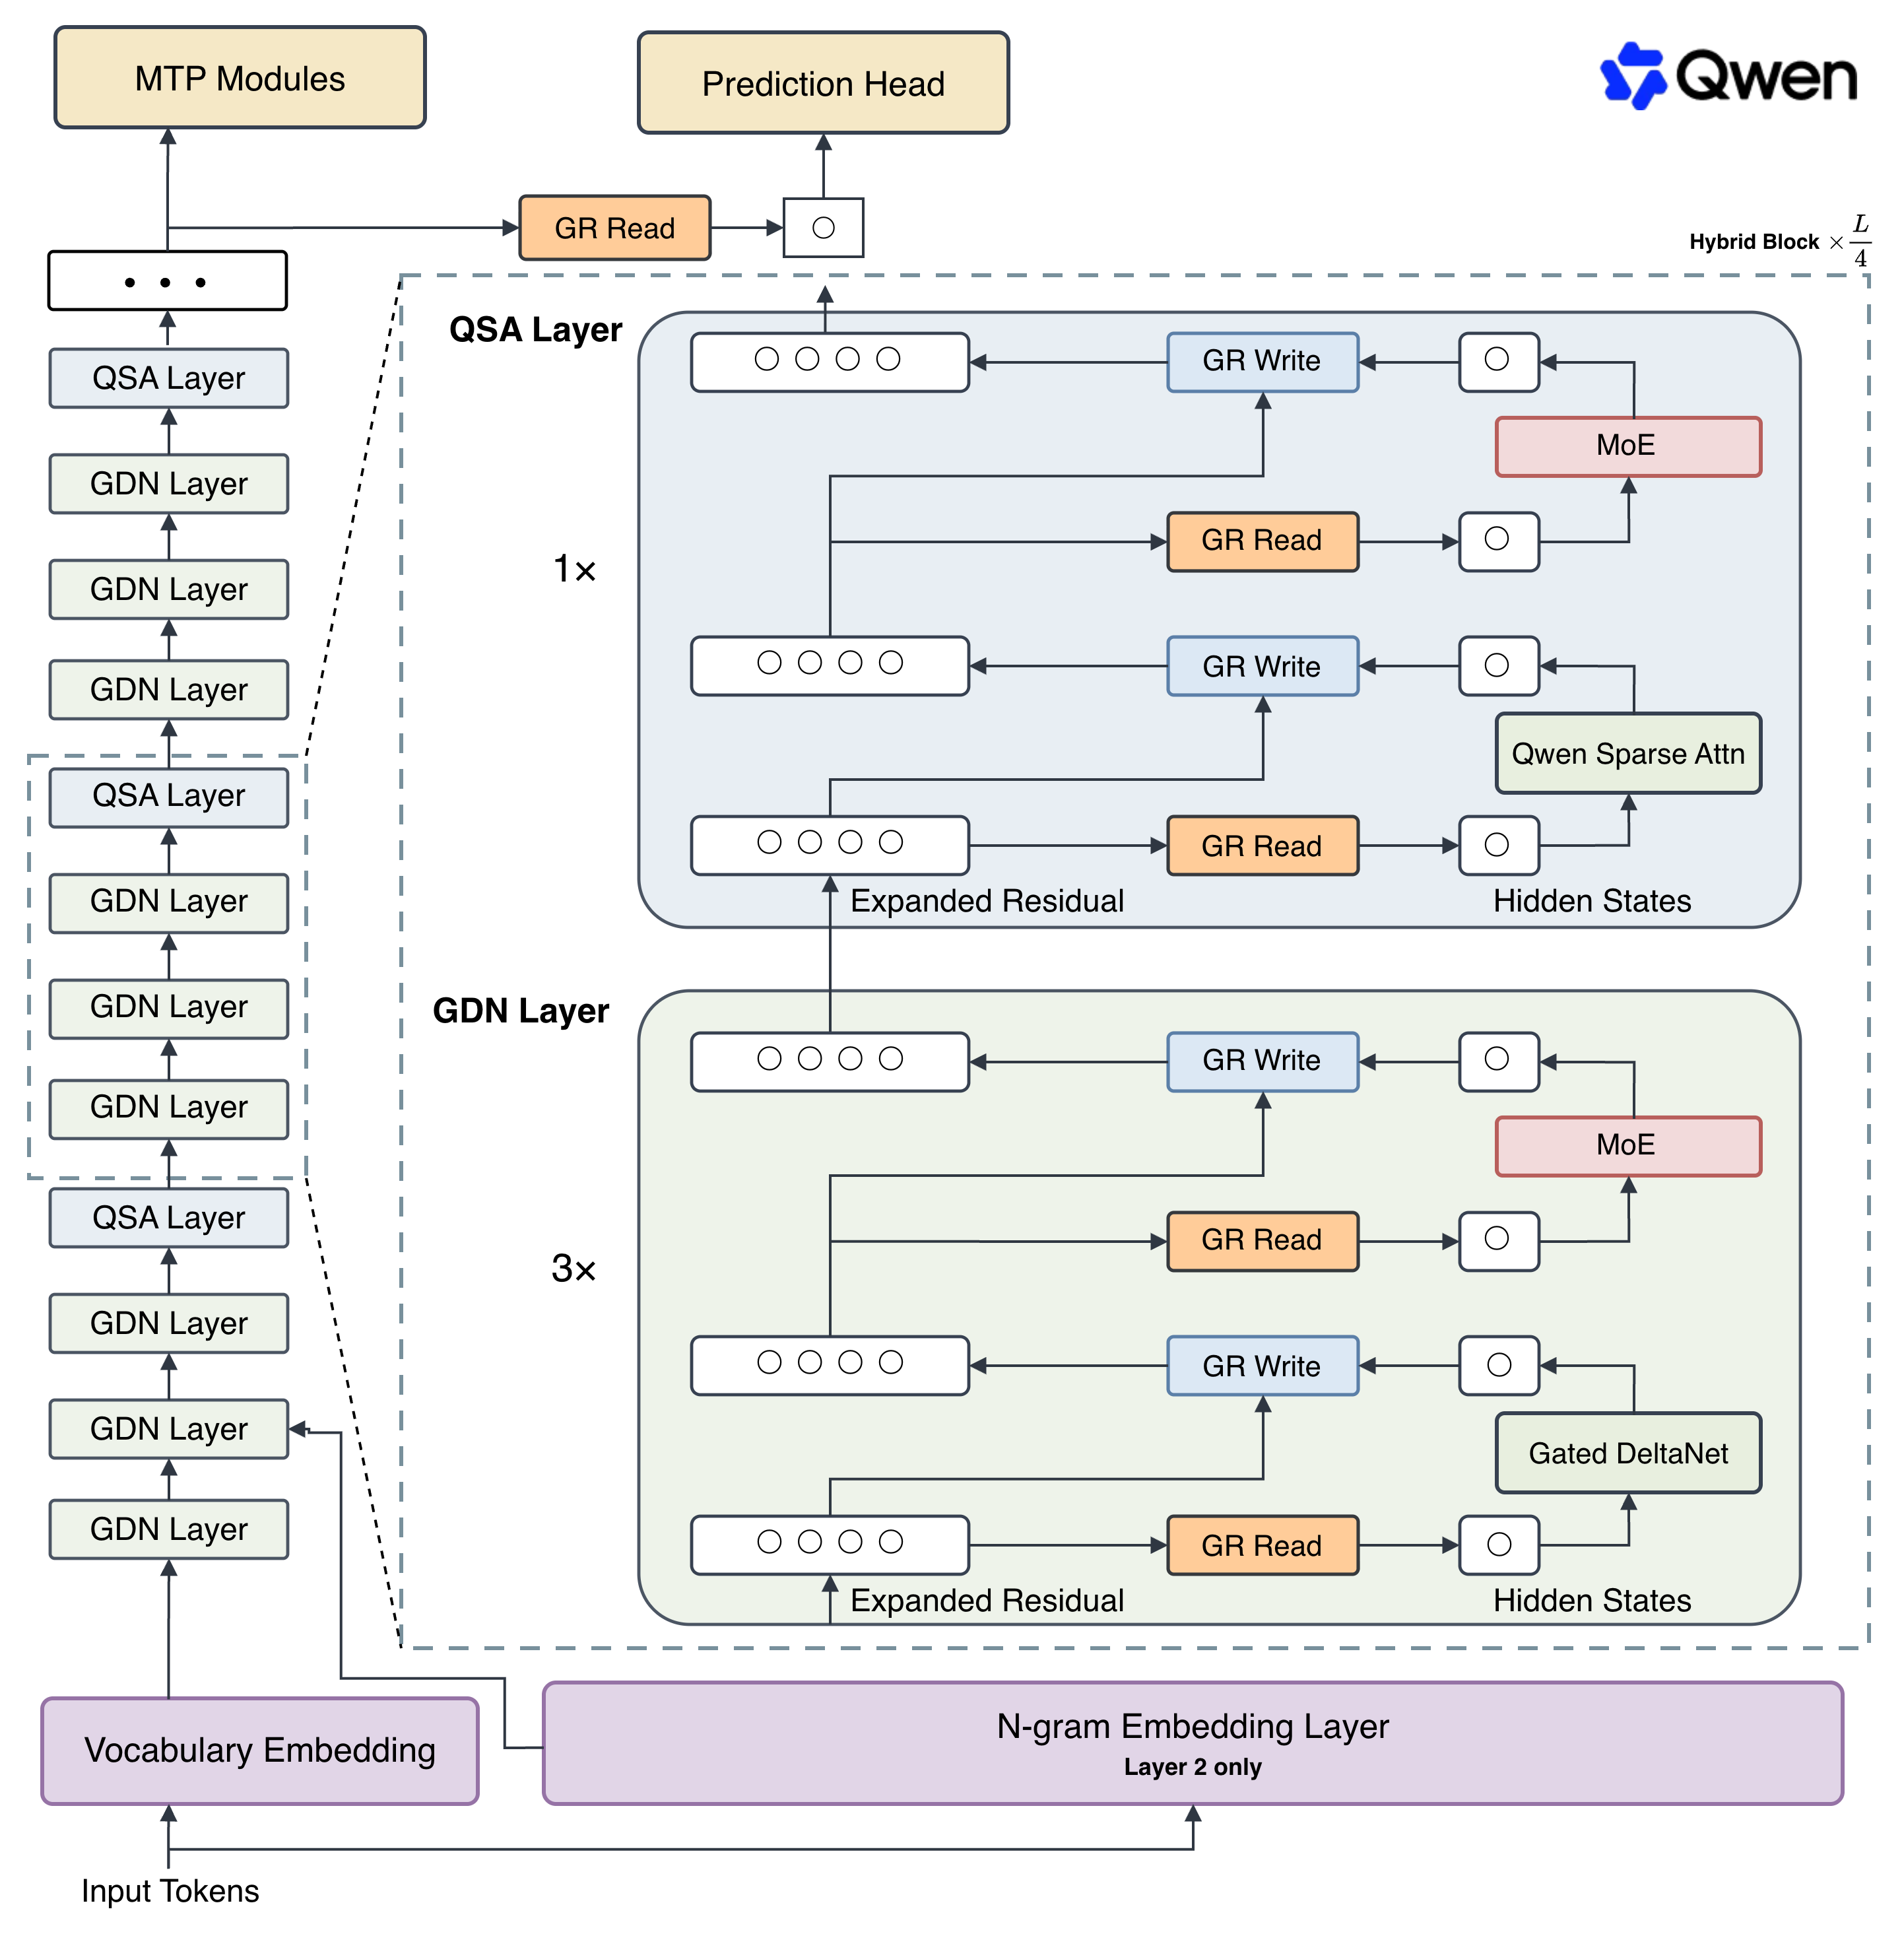
433QwenLM/Qwen3.8-Flash-NextQwen3.8-Flash-Next is an open-weight multimodal Mixture-of-Experts foundation model from Alibaba's Qwen Team, also serving as an early preview of the architecture Alibaba plans to use for the upcoming Qwen4 model family.
- 94
jeeves
425PostHog/jeeves · PythonJeeves is a reasoning-enhanced 'Jev-like' decision model built on Qwen3.5-9B with LoRA. It thinks through a reasoning chain before giving calibrated yes/no, multiple-choice, or rating answers, and ships with a diffusion drafter for faster inference.
- 95
Qwen3.8-Flash-Next-Dual-DGX-Sparks
410MiaAI-Lab/Qwen3.8-Flash-Next-Dual-DGX-Sparks · HTMLA multi-node inference launcher that runs the Qwen3.8-Flash-Next-NVFP4 language model across two NVIDIA DGX Spark nodes using vLLM with tensor parallelism, expert parallelism and speculative decoding.
- 96
qwen38-uncensored
366Wassimyounes01/qwen38-uncensored · JavaScriptA Node.js install harness that sets up Qwen 3.8 27B as a fully uncensored local model, using weight-level abliterated GGUF weights plus a reinforcement SYSTEM prompt, runnable through Ollama or Apple's MLX.
- 97

qwen38-mtp
363sudoingX/qwen38-mtp · PythonThis repo documents a single llama.cpp server flag that unlocks multi-token-prediction (MTP) speculative decoding for Qwen3.8-27B, giving +33% to +145% faster decode on consumer GPUs. It bundles the exact launch command, a crowdsourced benchmark table across dozens of GPUs, and a probe.py script for measuring the gain yourself.
- 98
llm-inference-engineering
348amitshekhariitbhu/llm-inference-engineering · MarkdownA free, continuously growing blog series that teaches LLM inference engineering step by step, covering KV cache, PagedAttention, continuous batching, speculative decoding, and serving engines like vLLM, SGLang, TensorRT-LLM, and GGUF.
- 99
DeepSeek-v4-Flash-One-DGX-Spark
347MiaAI-Lab/DeepSeek-v4-Flash-One-DGX-Spark · PythonA single-node Docker launcher that serves the DeepSeek V4 Flash 0731 model (EXL3 3.0bpw quantization) with DSpark speculative decoding, tuned to run entirely on one NVIDIA DGX Spark machine.
- 100

EvoVLM
332zzzz7788990213-ops/EvoVLM · PythonEvoVLM is a research project that runs LLM-guided, multi-objective evolutionary search over vision-language inference programs. It targets the accuracy-latency trade-off on scientific chart understanding while keeping model weights frozen.

Showing the 100 most-starred of 118. See every one in the catalog.
Related topics
Often tagged together