Topics / #text-to-image
Text-to-image projects on GitHub
Generative models creating images from textual descriptions.
As of , the most-starred Text-to-image projects on GitHub are stable-diffusion-webui (165.1K stars), ComfyUI (137.9K stars) and stable-diffusion (73.5K stars). GitHub.Locker tracks 72 Text-to-image repositories with 1.2M stars combined. The fastest-growing on October 16 was artcraft, with +1.3K stars in a day.
Hot right now
Most stars gained in a day · Oct 16
artcraft
storytold/artcraft · ★ 30.6KArtCraft is a desktop IDE for interactive AI image and video creation, where you compose scenes in 2D, stage them in 3D, and then pick from dozens of AI models to generate the final result.
 +350
qwen21-nsfw-pose-skill
Arekejoker/qwen21-nsfw-pose-skill · ★ 2.5KA local recipe (agent skill) for generating NSFW and pose-controlled images with Qwen-Image 2.1, combining an author-level prompt formula, a mandatory NSFW LoRA, and a 136-pose 3D doll library for precise pose control.
 +269
MOSS-Image
OpenMOSS/MOSS-Image · ★ 204This repository provides a native MOSS-Image plugin for ComfyUI.
ComfyUI
Comfy-Org/ComfyUI · ★ 137.9KComfyUI is a node-based graph interface for building and running diffusion model workflows: image, video, 3D, and audio generation, editing, and more, all without writing code.
The all-time top
72 projects · by stars
- 165.1K
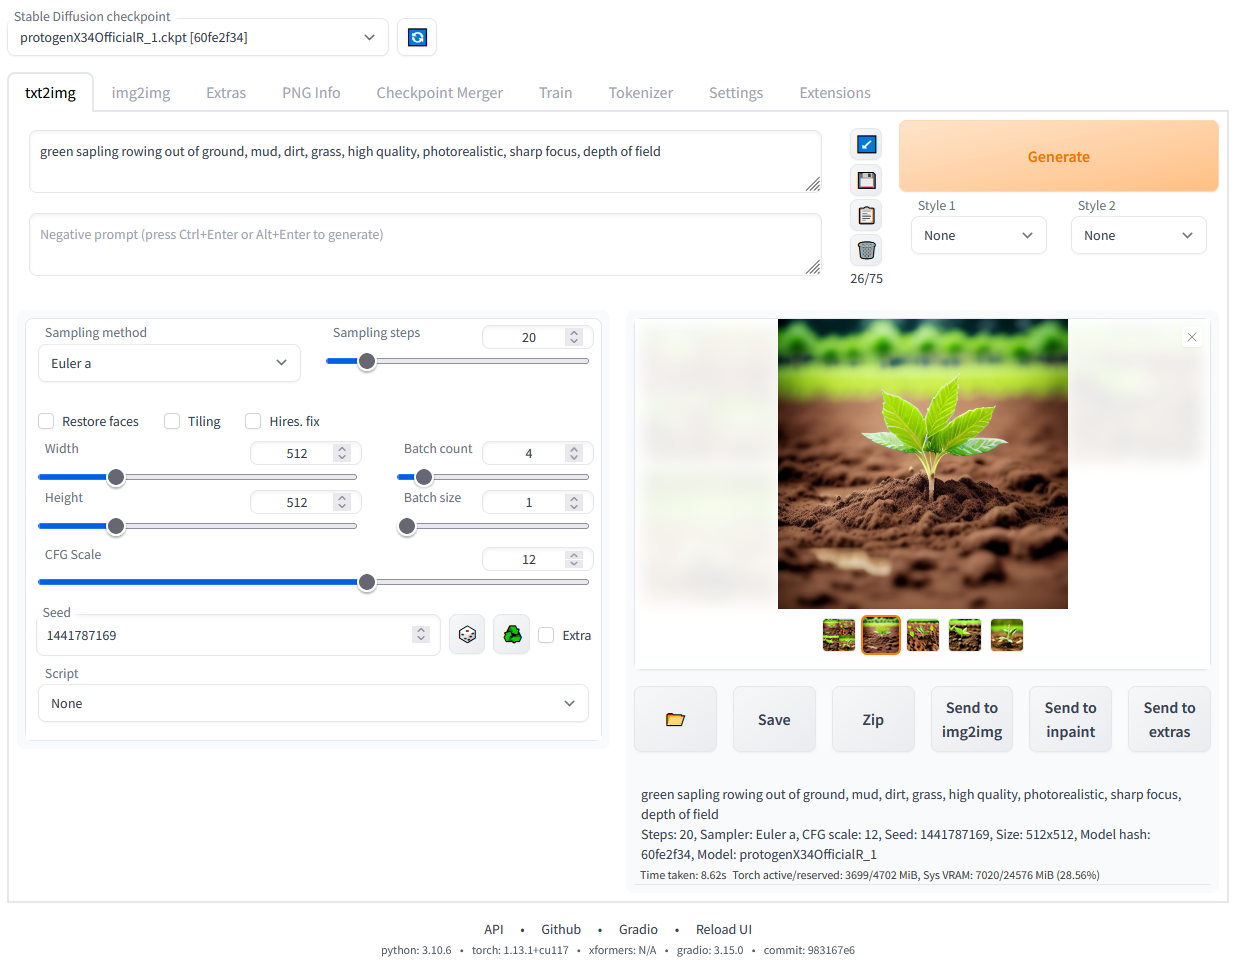 #1 · AUTOMATIC1111/stable-diffusion-webui
stable-diffusion-webui
A browser-based interface for Stable Diffusion, built with the Gradio library, letting you generate and edit AI images (txt2img, img2img, inpainting, outpainting and more) on your own machine.
- 137.9K
#2 · Comfy-Org/ComfyUI
ComfyUI
ComfyUI is a node-based graph interface for building and running diffusion model workflows: image, video, 3D, and audio generation, editing, and more, all without writing code.
- 73.5K
 #3 · CompVis/stable-diffusion
stable-diffusion
Stable Diffusion is a latent text-to-image diffusion model that generates images from text prompts, built by CompVis with Stability AI and Runway, based on the Latent Diffusion Models work from CVPR '22.
- 4

Fooocus
53.6Klllyasviel/Fooocus · PythonFooocus is an open-source AI image generator built on Stable Diffusion XL: an offline GPT-2 engine expands your prompt so results look good without prompt engineering or parameter tuning.
- 5
prompt-optimizer
38.3Klinshenkx/prompt-optimizer · TypeScriptPrompt Optimizer is an AI tool that helps you write better prompts and get better results from AI models, available as a web app, desktop app, Chrome extension, and Docker deployment.
- 6
diffusers
34.7Khuggingface/diffusers · PythonDiffusers is Hugging Face's Python library for state-of-the-art pretrained diffusion models that generate images, audio, and even 3D molecule structures, all in PyTorch.
- 7

awesome-gpt-image-2
34.6Kfreestylefly/awesome-gpt-image-2 · JavaScriptA curated library for OpenAI's GPT Image 2 model: 544 reverse-engineered prompt cases, 20+ industrial prompt templates and a reusable agent skill, presented as a browsable gallery website.
- 8
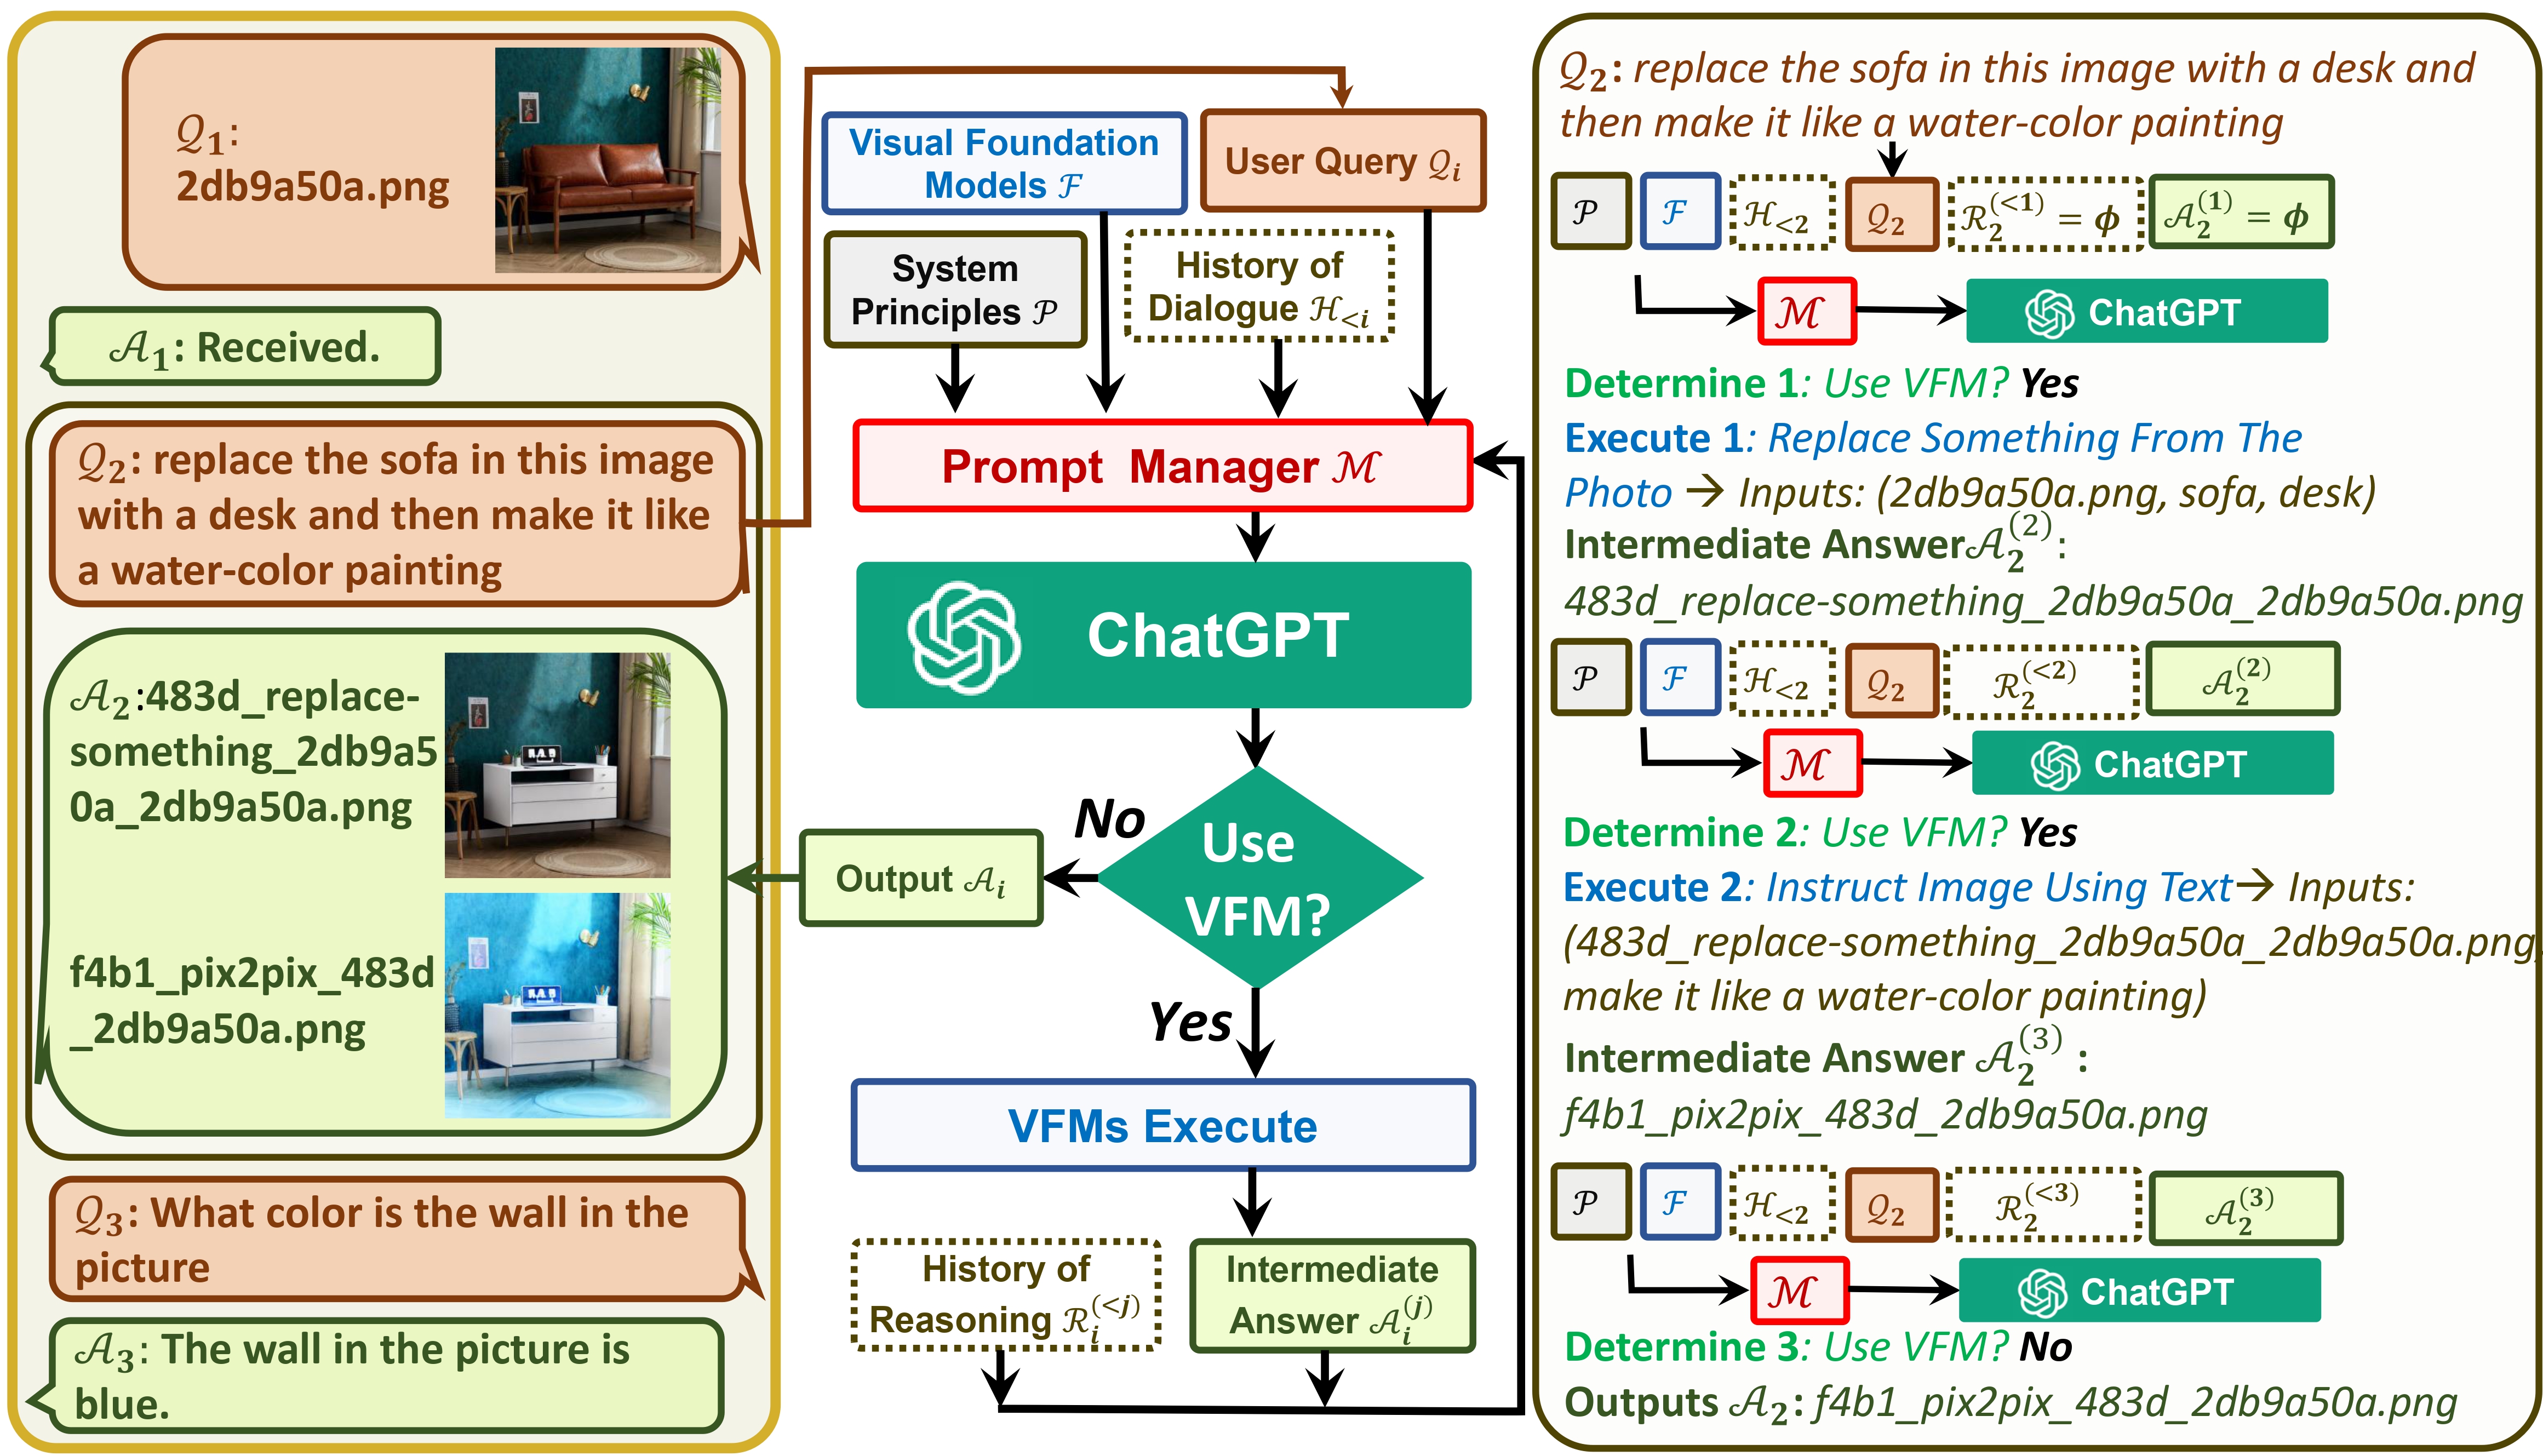
TaskMatrix
34Kchenfei-wu/TaskMatrix · PythonTaskMatrix (also known as Visual ChatGPT) connects ChatGPT to a set of Visual Foundation Models so you can send and receive images while chatting, letting the LLM draw, edit, and analyze pictures.
- 9
artcraft
30.6Kstorytold/artcraft · RustArtCraft is a desktop IDE for interactive AI image and video creation, where you compose scenes in 2D, stage them in 3D, and then pick from dozens of AI models to generate the final result.
- 10

Open-Generative-AI
30.6KAnil-matcha/Open-Generative-AI · JavaScriptA free, open-source studio for AI image, video, cinema and lip sync generation, positioned as an unrestricted alternative to paid AI video platforms: 400+ models (Flux, Midjourney, Kling, Sora, Veo) across 14 studios, with no content filters.
- 11
Open-Sora
29.9Khpcaitech/Open-Sora · PythonOpen-Sora is an open-source initiative for efficiently producing high-quality video: it releases video generation models together with the tools, checkpoints and all training details.
- 12

InvokeAI
28.7Kinvoke-ai/InvokeAI · TypeScriptInvoke is a leading creative engine for Stable Diffusion models: a locally hosted web app for generating and editing images with AI, aimed at professionals, artists, and enthusiasts.
- 13

generative-models
27.3KStability-AI/generative-models · PythonThis is Stability AI's research codebase for a family of generative diffusion models, covering text-to-image (SDXL, SDXL-Turbo), image-to-video (Stable Video Diffusion), image-to-3D-video (SV3D), and video-to-4D (SV4D, SV4D 2.0) synthesis.
- 14
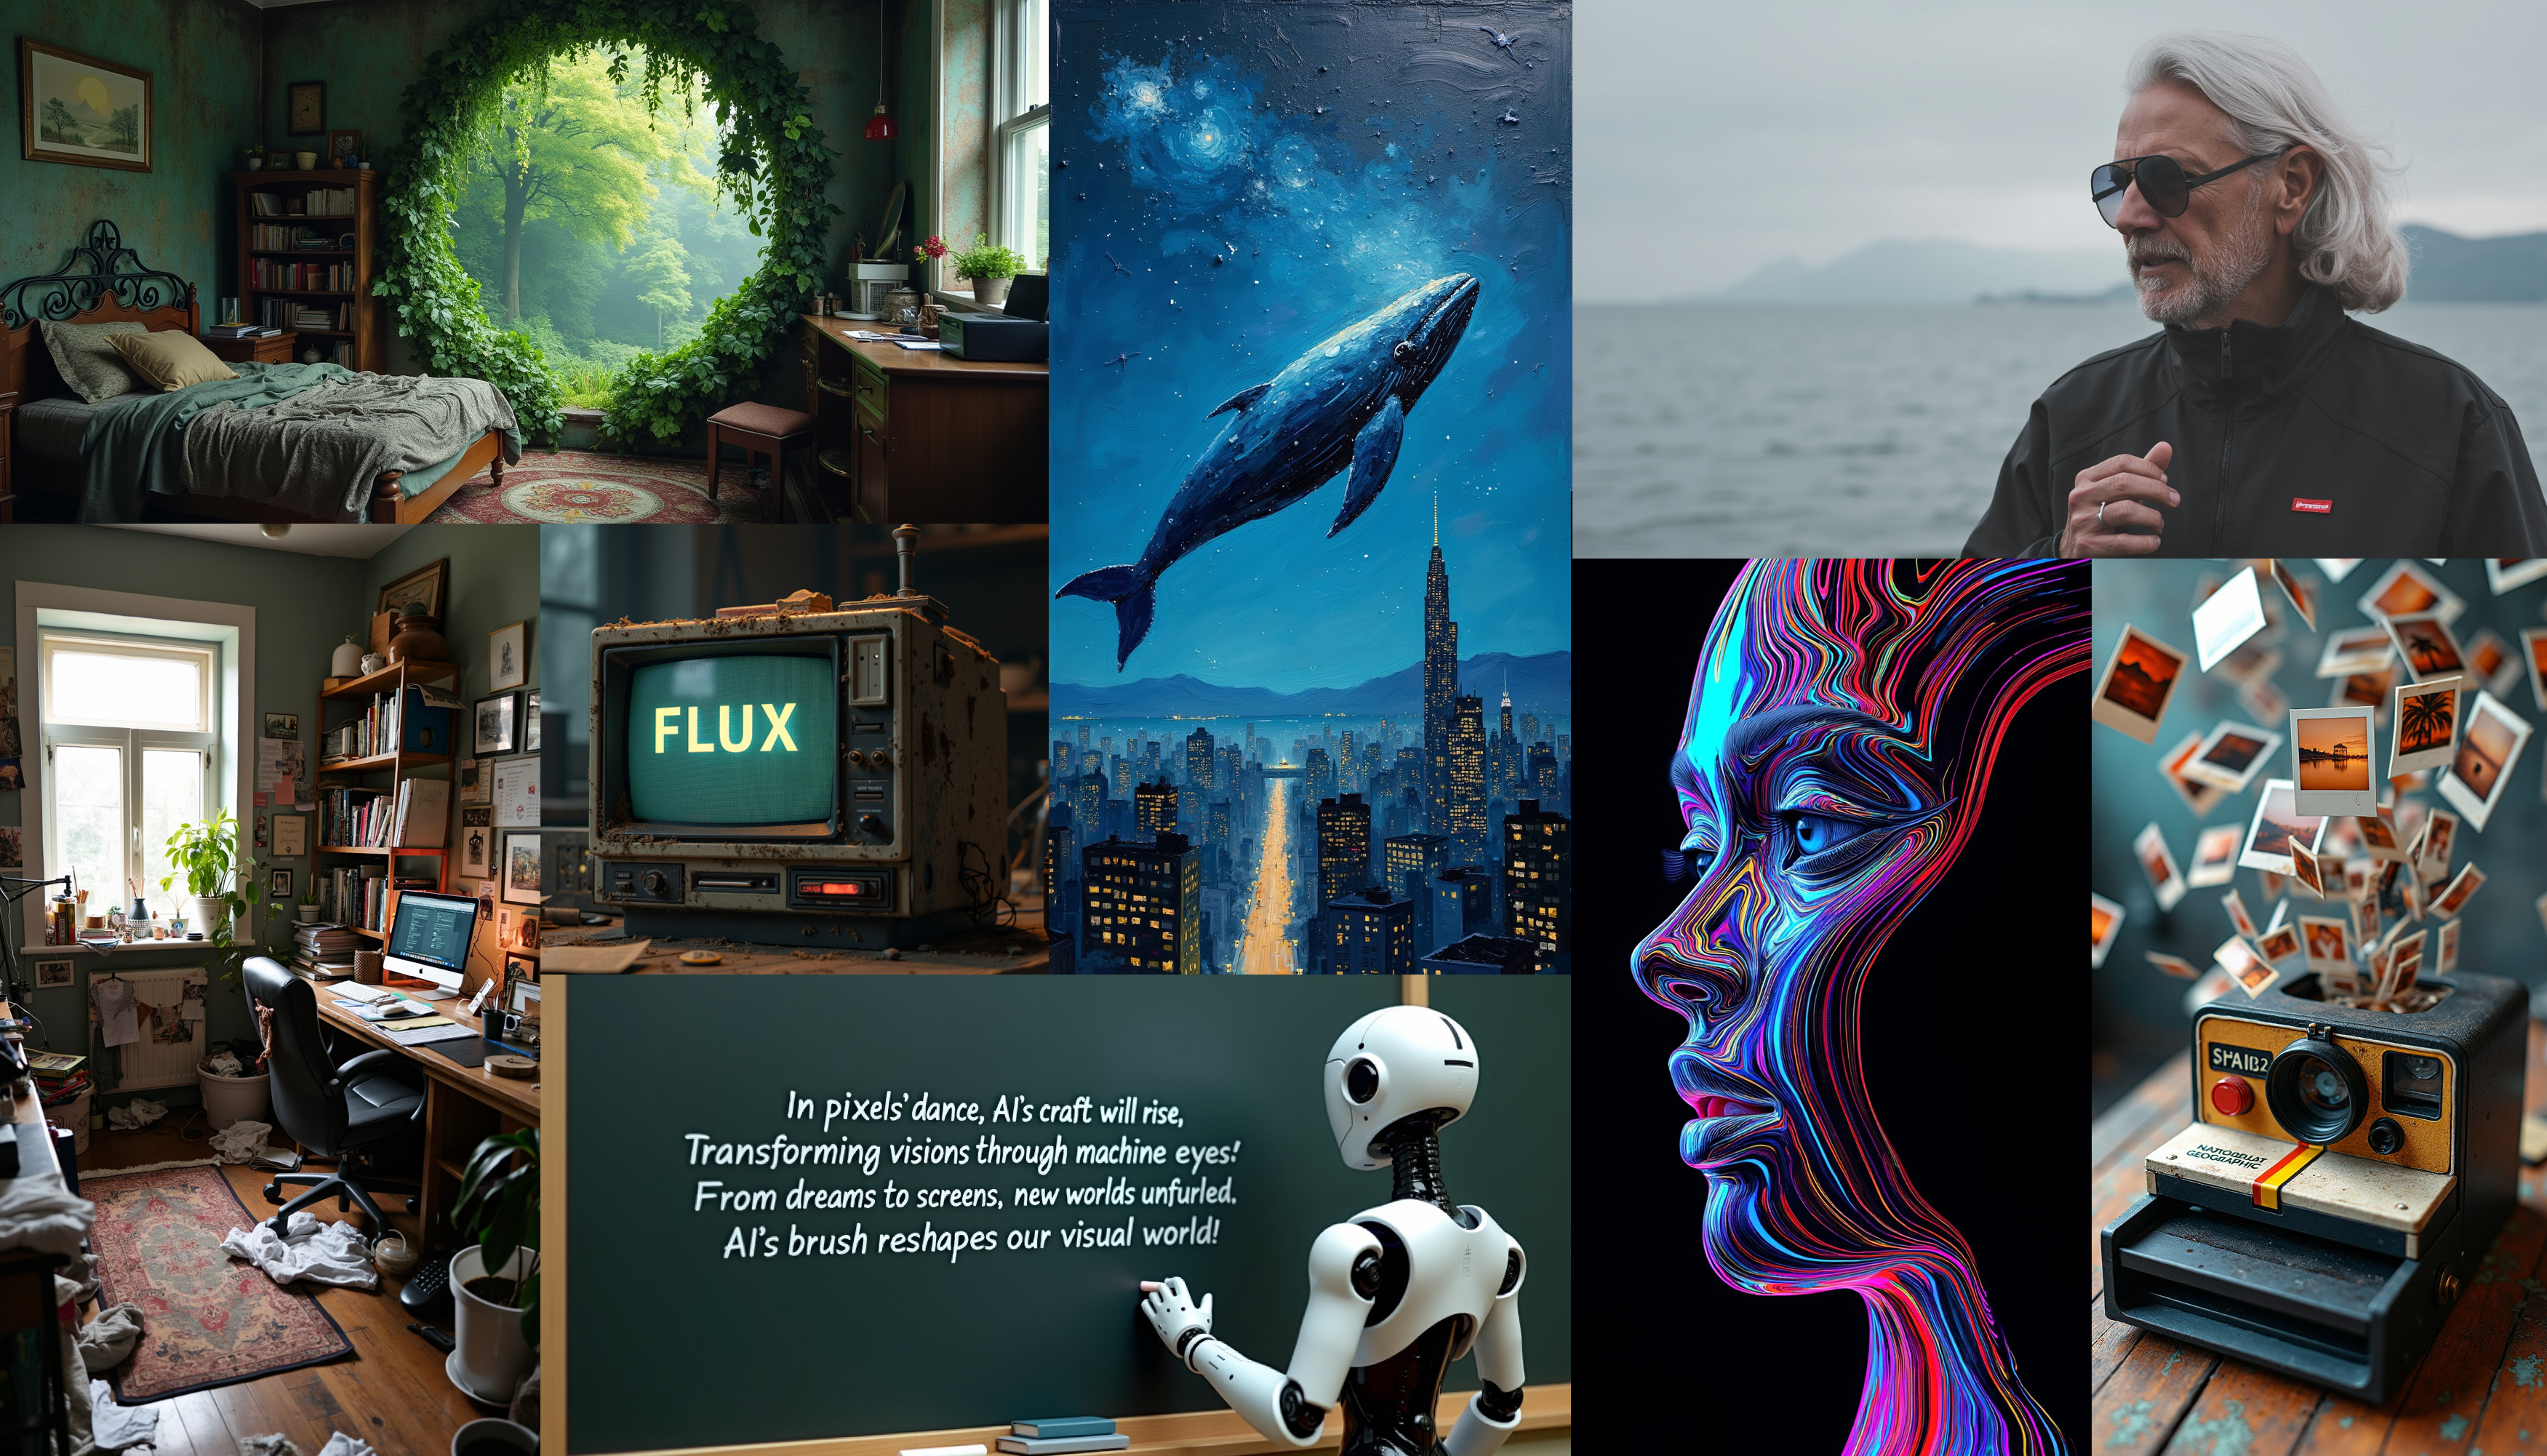
flux
26Kblack-forest-labs/flux · PythonThis is Black Forest Labs' official inference repo for the FLUX.1 family of image generation and editing diffusion models, providing minimal code to run the open-weight models.
- 15

Awesome-Nano-Banana-images
23.9KPicoTrex/Awesome-Nano-Banana-imagesA curated gallery of fun, creative images generated with Nano Banana and Nano Banana Pro — Google's Gemini-2.5-flash-image based models — each paired with the prompt that produced it.
- 16
Toonflow-app
18KHBAI-Ltd/Toonflow-app · TypeScriptToonflow is an open-source AI workbench for producing short dramas and motion comics: scriptwriting, storyboarding, character and scene assets, and image and video generation chained into one pipeline on an infinite canvas.
- 17
ml-stable-diffusion
18Kapple-aiml-research/ml-stable-diffusion · PythonThis is Apple's toolkit for running Stable Diffusion image generation on Apple Silicon using Core ML, so it can run efficiently on Mac, iPad, and iPhone.
- 18

Janus
17.8Kdeepseek-ai/Janus · PythonJanus is DeepSeek's family of open multimodal AI models (Janus, Janus-Pro, JanusFlow). One model both understands images and text and generates images from a text prompt.
- 19

awesome-gpt-image-2-API-and-Prompts
17.3KEvoLinkAI/awesome-gpt-image-2-API-and-Prompts · PythonA curated prompt library of 462 GPT Image 2 examples covering e-commerce, advertising, posters, portraits, character design, and UI mockups, each with the original prompt text and source attribution.
- 20
Wan2.1
17.2KWan-Video/Wan2.1 · PythonWan2.1 is an open suite of large-scale video generative models: it turns text or images into videos, and also covers video editing, text-to-image and video-to-audio tasks.
- 21

stable-diffusion-webui-colab
15.9Kcamenduru/stable-diffusion-webui-colab · Jupyter NotebookA set of ready-made Google Colab notebooks that install and run the Stable Diffusion WebUI in the cloud — one notebook per popular model, from SD 1.5 to waifu-diffusion and style fine-tunes.
- 22
banana-slides
15.8KAnionex/banana-slides · TypeScriptBanana Slides is an AI-native app that turns a single idea, an outline, page descriptions, or uploaded documents/templates into a full editable slide deck in minutes, powered by the nano banana pro image model.
- 23
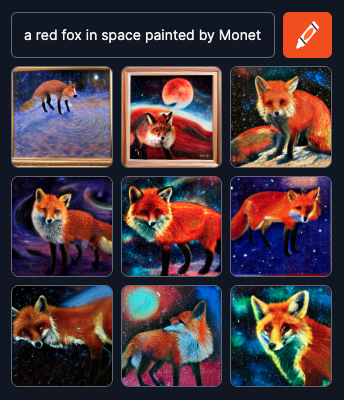
dalle-mini
14.7Kborisdayma/dalle-mini · PythonDALL·E Mini is an open-source model that generates images from a text prompt, built as a smaller, reproducible version of OpenAI's DALL·E.
- 24
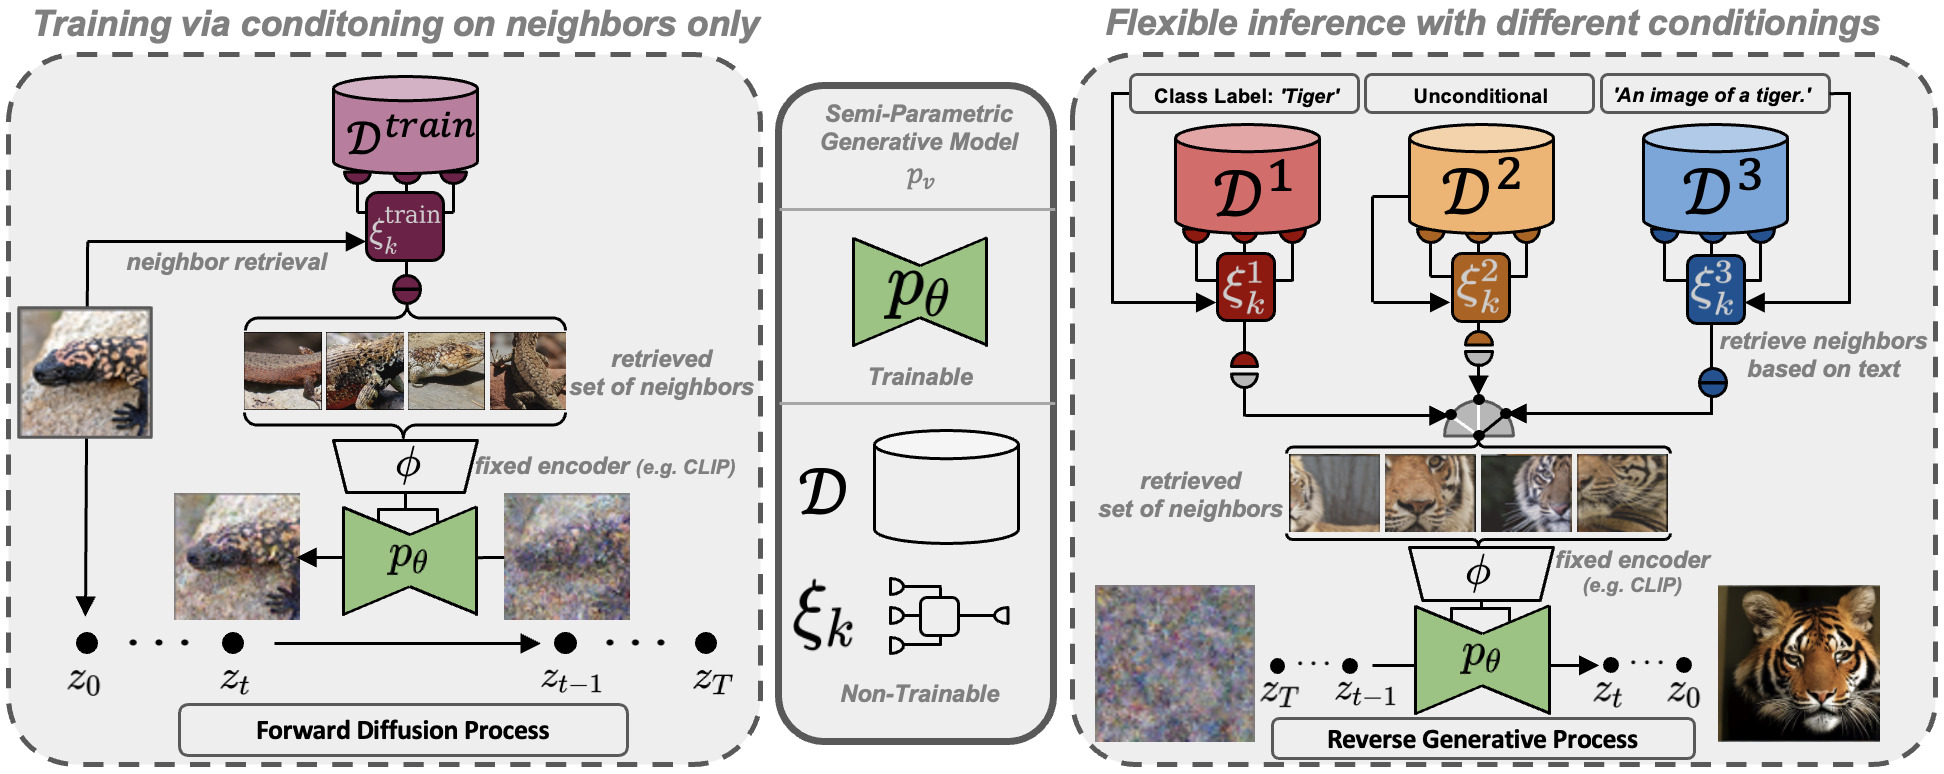
latent-diffusion
14.2KCompVis/latent-diffusion · Jupyter NotebookThis is the official research codebase for the paper 'High-Resolution Image Synthesis with Latent Diffusion Models' by CompVis, which introduced Latent Diffusion Models (LDMs) - diffusion models trained in a compressed latent space instead of raw pixel space for efficient, high-resolution image synthesis.
- 25
awesome-nano-banana-pro-prompts
13.6KYouMind-OpenLab/awesome-nano-banana-pro-prompts · TypeScriptA massive curated library of 10,000+ prompts for Google's Nano Banana Pro image-generation model, each with example output images, author, source and language tags.
- 26
DiffSynth-Studio
13.3Kmodelscope/DiffSynth-Studio · PythonDiffSynth-Studio is an open-source Diffusion model engine built and maintained by the ModelScope Community, covering image, video, and audio generation plus image quality metrics, with support for both inference and training.
- 27
stable-diffusion-webui-forge
13.1Klllyasviel/stable-diffusion-webui-forge · PythonStable Diffusion WebUI Forge is a platform built on top of Stable Diffusion WebUI (using Gradio) that adds GPU memory management and performance improvements for running Stable Diffusion image generation locally.
- 28

kohya_ss
12.6Kbmaltais/kohya_ss · PythonKohya's GUI is a Gradio-based graphical interface (plus CLI) for Kohya's Stable Diffusion training scripts, letting you fine-tune diffusion models, train LoRA/LoHa/LoKr, Dreambooth, Textual Inversion, and full fine-tuning without hand-writing training commands.
- 29

Awesome-Diffusion-Models
12.4Kdiff-usion/Awesome-Diffusion-Models · HTMLA curated collection of papers and resources on Diffusion Models, covering theory, applications, and related research.
- 30
ai-toolkit
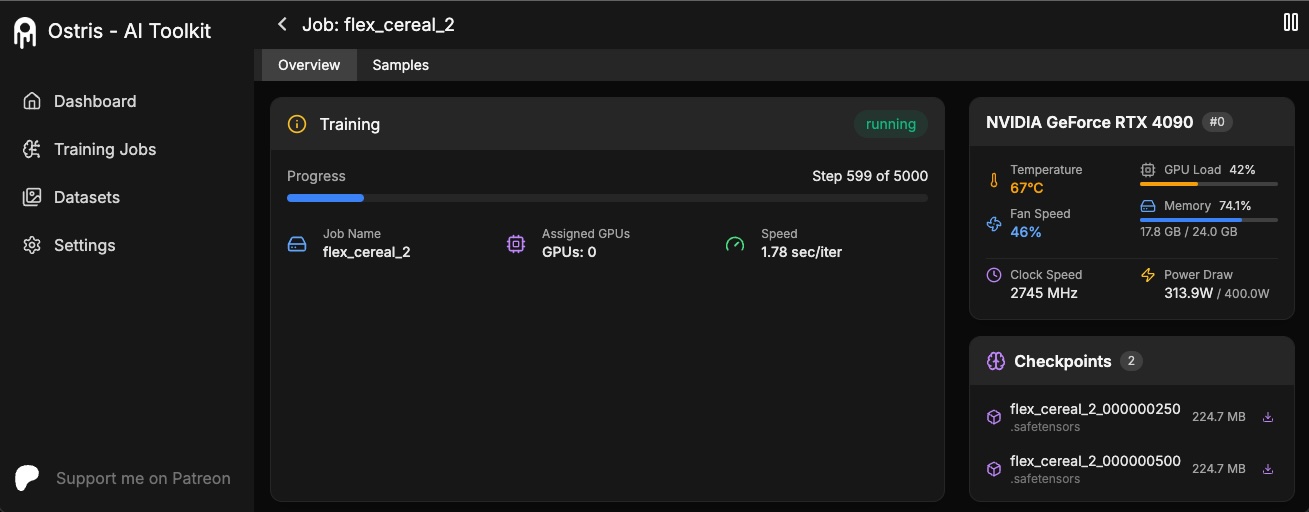
12.3Kostris/ai-toolkit · PythonAI Toolkit is an all-in-one training suite for finetuning diffusion models, covering image, video, and audio generation models, with support for the latest models like FLUX, Qwen-Image, Wan 2.1/2.2, and Ace-Step on consumer GPUs.
- 31

AnimateDiff
12.3Kguoyww/AnimateDiff · PythonAnimateDiff is the official implementation of a research method that turns personalized text-to-image Stable Diffusion models into animation (text-to-video) generators without any extra fine-tuning of those models.
- 32

shap-e
12.3Kopenai/shap-e · PythonShap-E is OpenAI's official code and model release for generating 3D objects conditioned on text prompts or images, producing conditional 3D implicit functions.
- 33
Z-Image
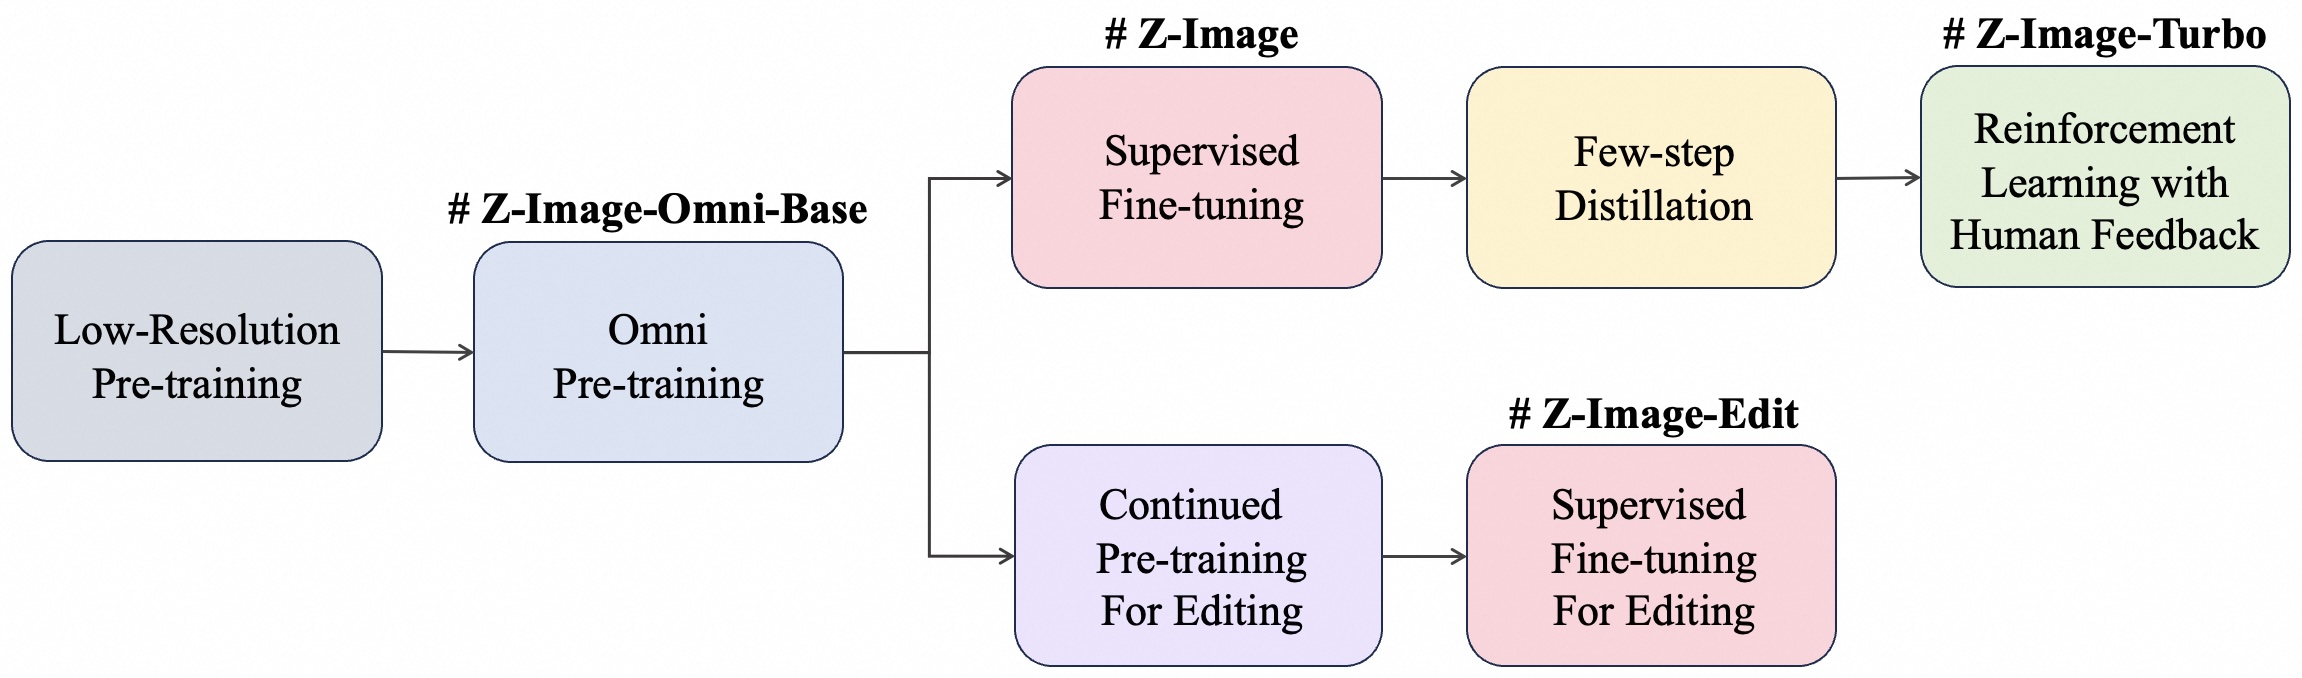
12.1KTongyi-MAI/Z-Image · PythonZ-Image is a family of efficient image generation models with 6B parameters, built around a single-stream diffusion transformer architecture, developed by Alibaba's Tongyi team.
- 34
InstantID
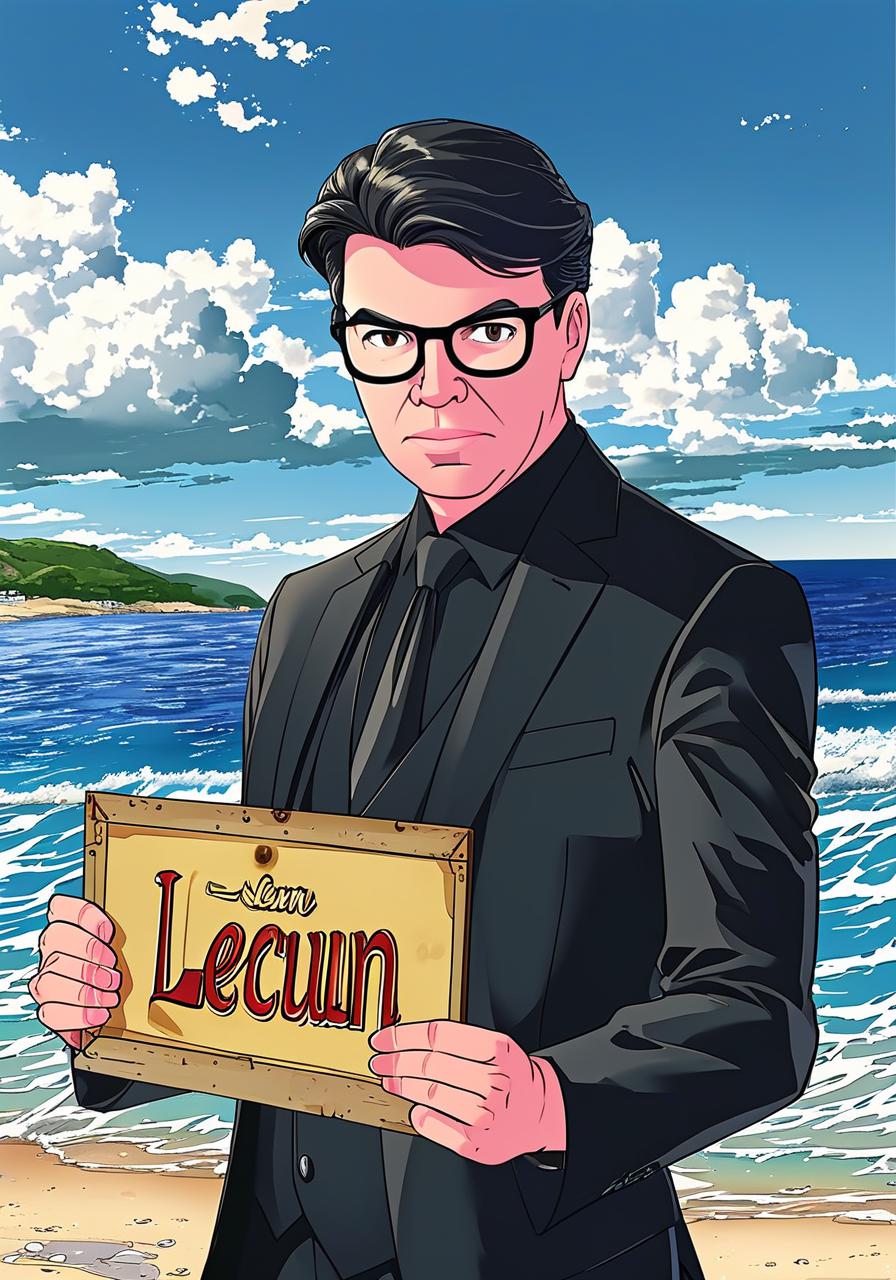
12KinstantX-research/InstantID · PythonInstantID is a tuning-free method for identity-preserving image generation: a single reference photo of a face plus a text prompt is enough to create new images that keep the person's likeness, in seconds.
- 35

awesome-ai-painting
11.8Khua1995116/awesome-ai-paintingA curated Chinese-language collection of AI painting resources: platforms you can use today, tutorials, parameter and deployment guides, model lists and industry news, centered on Stable Diffusion and similar models.
- 36

DALLE2-pytorch
11.3Klucidrains/DALLE2-pytorch · PythonIt is a PyTorch implementation of DALL-E 2, OpenAI's text-to-image synthesis model, built by a third-party community author (lucidrains).
- 37
StreamDiffusion
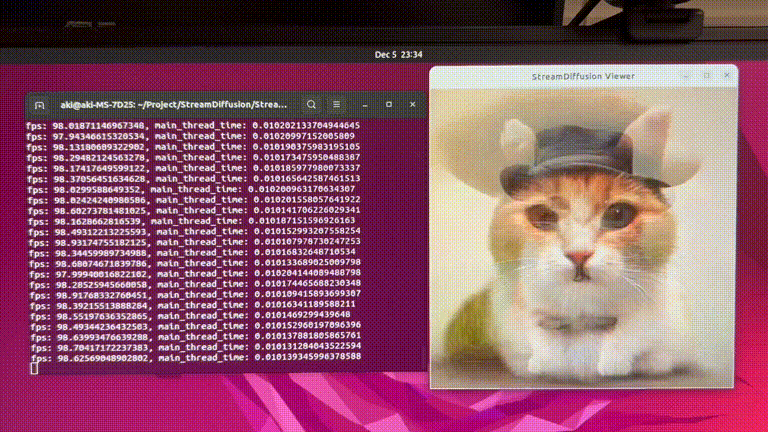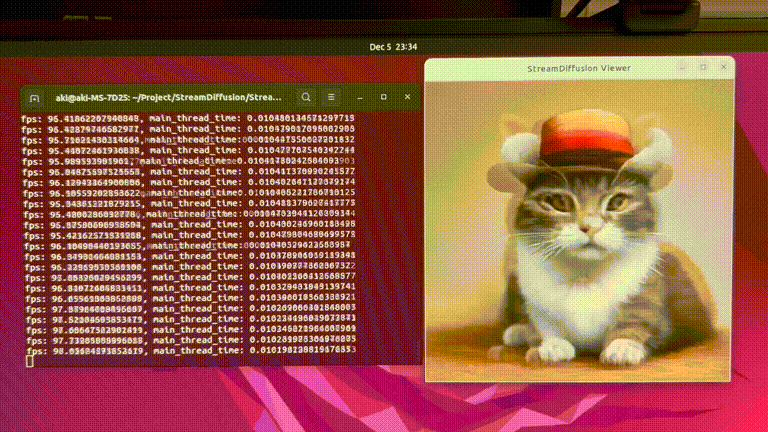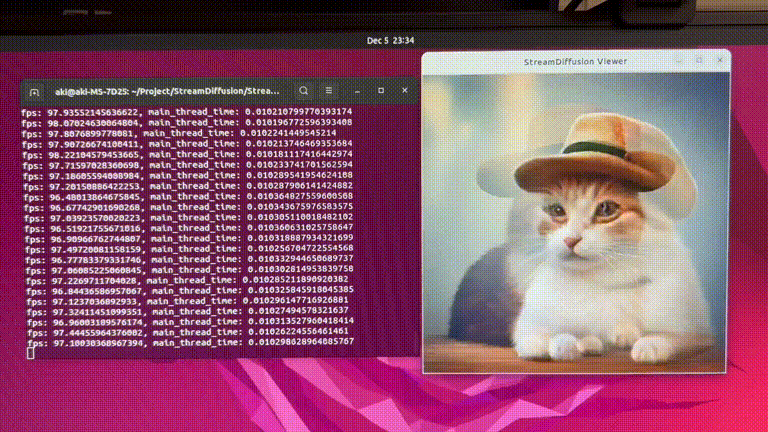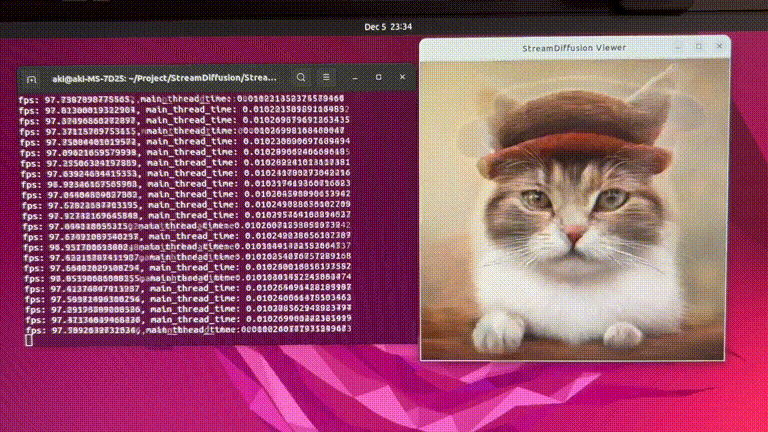
10.8Kcumulo-autumn/StreamDiffusion · PythonStreamDiffusion is a pipeline-level library for real-time, interactive diffusion image generation, letting you turn text prompts or a live webcam/screen feed into generated images at high frame rates.
- 38

DALL-E
10.8Kopenai/DALL-E · PythonThis is the official PyTorch package for the discrete VAE (dVAE) used in OpenAI's DALL·E image generation model. It only contains the image encoder/decoder component, not the transformer that actually generates images from text.
- 39
krita-ai-diffusion
10.7KAcly/krita-ai-diffusion · PythonA free, open-source Krita plugin that brings generative AI into painting and editing workflows: inpaint, outpaint, live-paint and upscale images with an optional text prompt, running on your own hardware.
- 40

paper2gui
10.7KBaiyuetribe/paper2gui · Jupyter NotebookA desktop toolbox that wraps research AI models into ready-to-run apps for non-coders: 50+ models for AI painting, speech synthesis, video frame interpolation, video super-resolution and OCR.
- 41

WanGP
10.6Kdeepbeepmeep/WanGP · PythonWanGP is a one-stop open source app for running top generative AI models for video, image, and audio/TTS generation, built specifically to work on modest consumer GPUs (the 'GPU Poor').
- 42
awesome-nanobanana-pro
10.4KZeroLu/awesome-nanobanana-proA curated, categorized collection of the best Nano Banana Pro prompts and examples — an awesome list for getting the most out of the Nano Banana Pro (Nano Banana 2) AI image model.
- 43
PhotoMaker
10.1KTencentARC/PhotoMaker · Jupyter NotebookPhotoMaker is an AI tool from Tencent ARC (CVPR 2024) that generates new images of a specific person: you feed in a few reference photos of the face plus a text prompt, and it renders that identity in new scenes, poses, or styles.
- 44
stable-diffusion.cpp
7.7Kleejet/stable-diffusion.cpp · C++A pure C/C++ inference engine for diffusion models like Stable Diffusion, Flux, Wan, Qwen Image, and Z-Image, built the same way as llama.cpp so you can generate images and videos without heavy Python dependencies.
- 45

infinite-canvas
7.7Kbasketikun/infinite-canvas · TypeScriptAn open-source infinite canvas workbench for AI creation: it puts canvas orchestration, AI image generation, reference-image editing, a chat assistant, a prompt library and asset management in one interface.
- 46
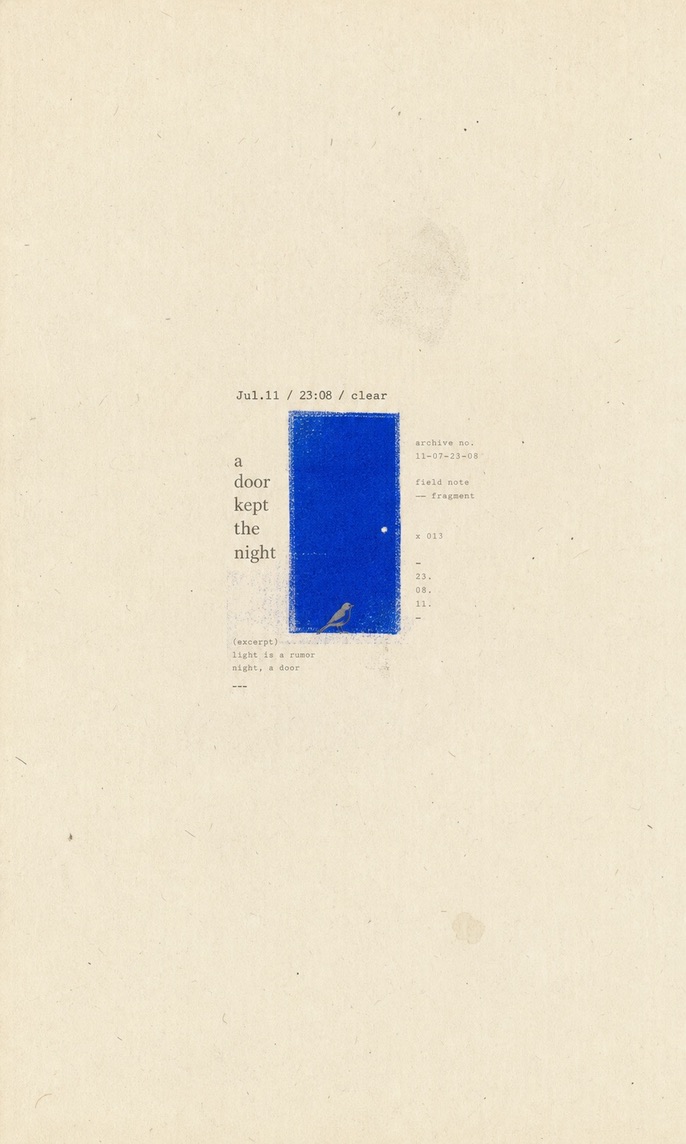
gc-minimal-zine-poster
7.3KLiamGvchi/gc-minimal-zine-posterA Codex skill that turns a theme, sentence, photo, or mood into a sparse, paper-textured minimal zine-style editorial poster, producing both the generated image and a reusable production-ready image prompt.
- 47
PaperBanana
7.2Kdwzhu-pku/PaperBanana · PythonPaperBanana is an open-source framework that turns raw scientific content into publication-quality diagrams and plots, acting like a creative team of five specialized agents: Retriever, Planner, Stylist, Visualizer and Critic.
- 48
godogen
7.1Khtdt/godogen · PythonGodogen is a generator that publishes thin starter repos for Godot, Bevy, or Babylon.js games, which an AI coding agent (Claude Code or Codex) then builds out autonomously from a prompt — writing code, generating assets, running the engine, and proving the result with a live view or a recorded clip.
- 49
codex-ppt-skill
7Kningzimu/codex-ppt-skill · PythonA SKILL.md-based skill for Codex (and other compatible agents like Claude Code, OpenClaw and Hermes Agent) that turns articles, reports, papers or course notes into full-page image-style slide decks: it plans an outline and visual style, generates each slide as an image with gpt-image-2, then assembles everything into a .pptx with a local script.
- 50
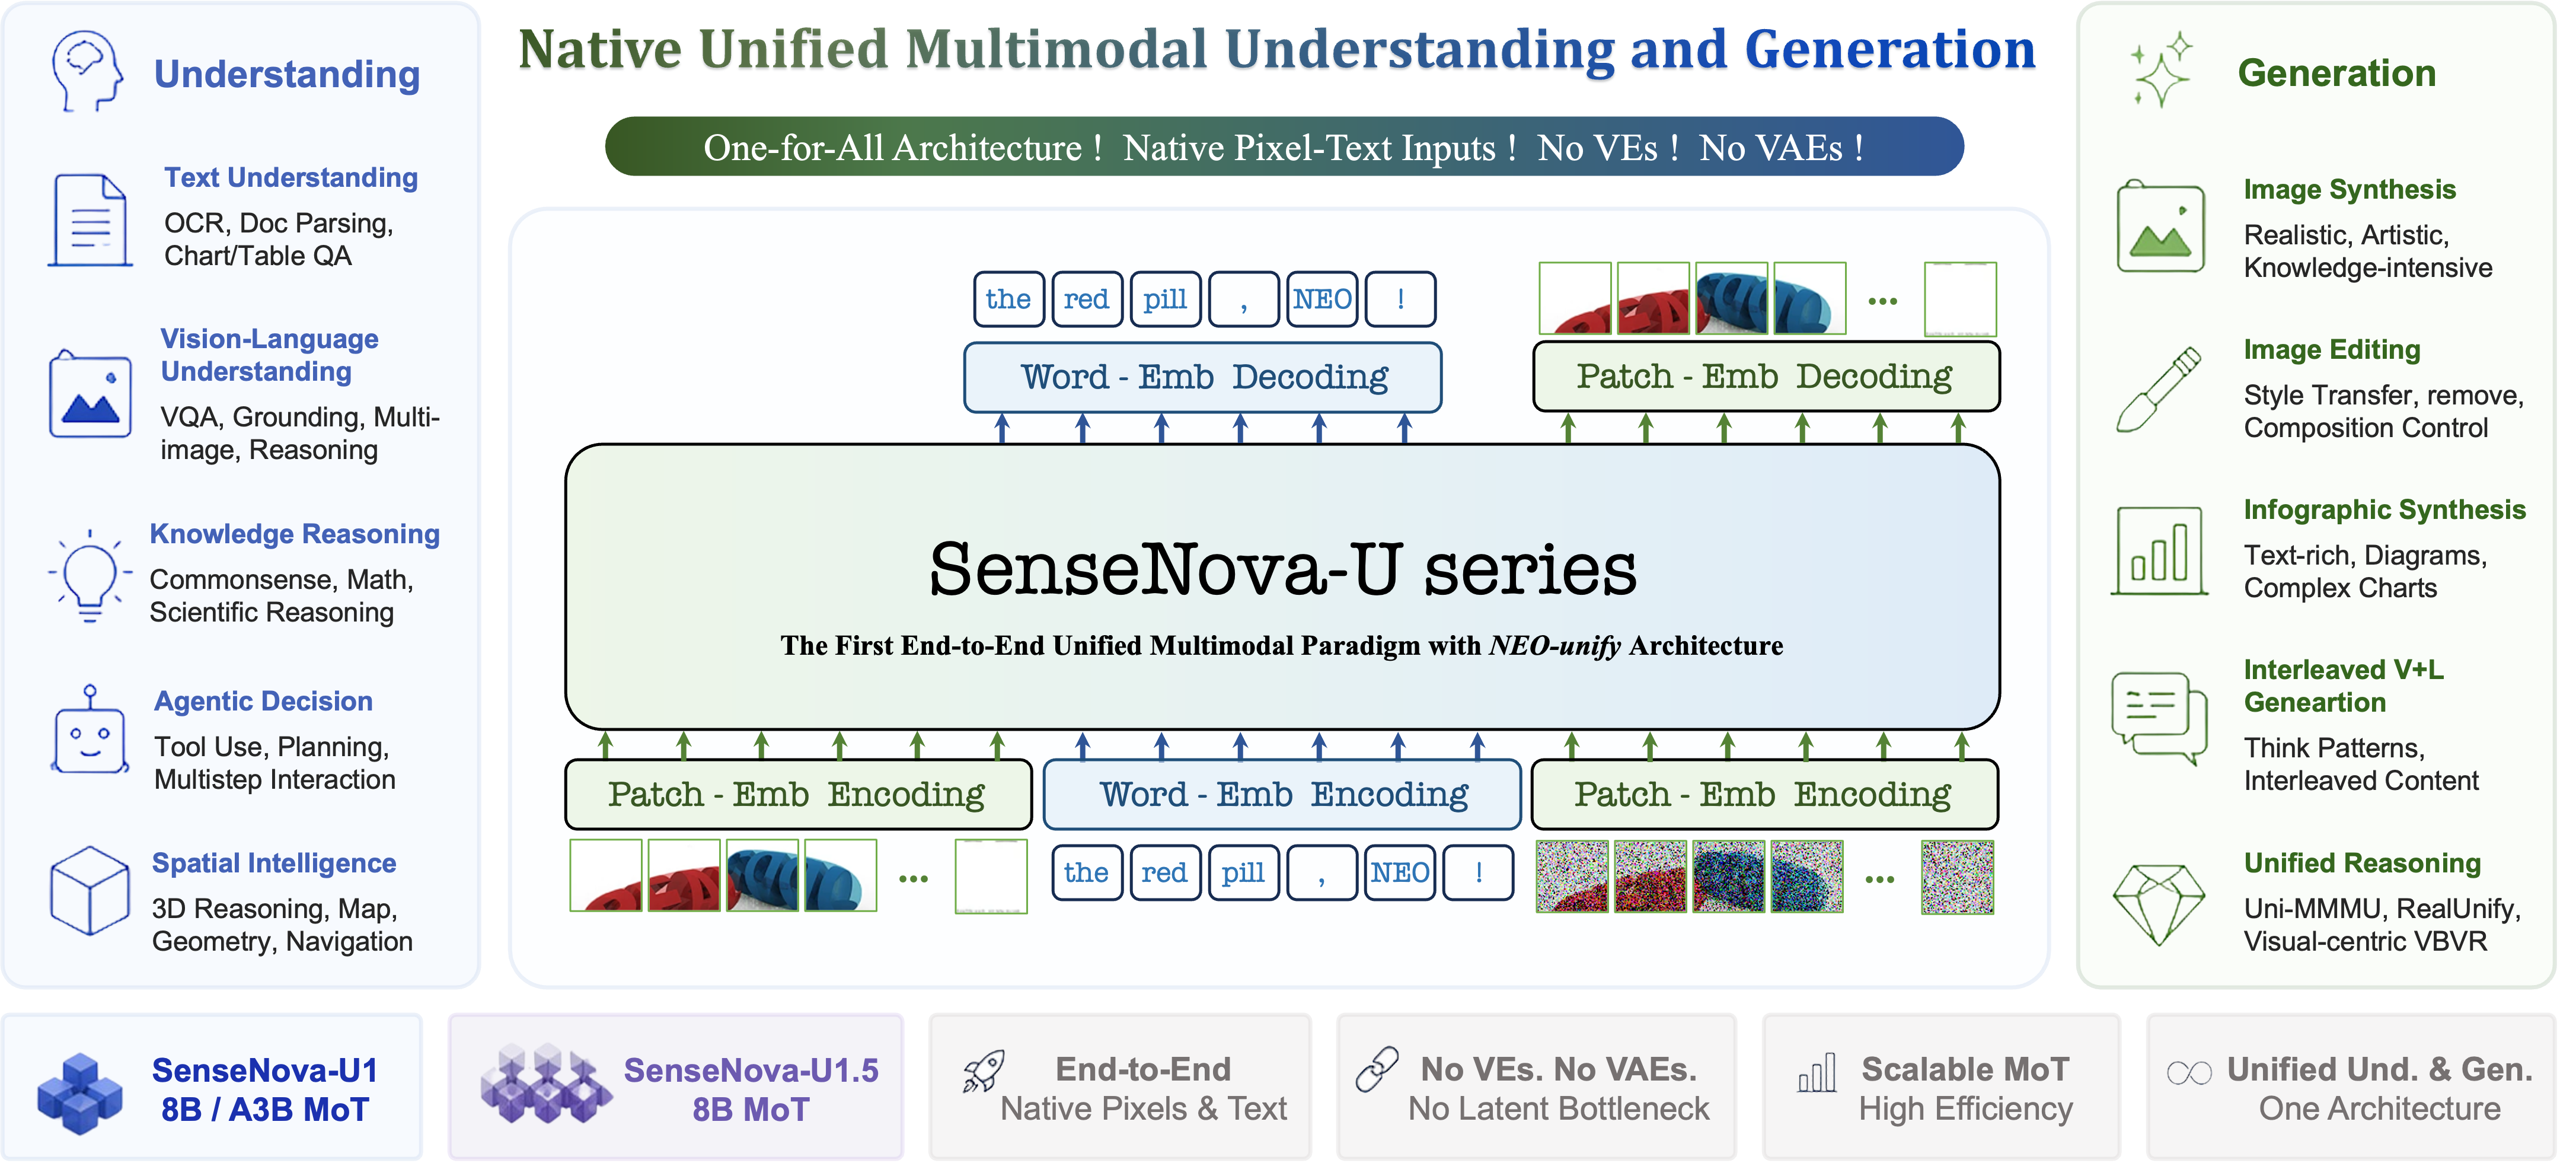
SenseNova-U1
6.9KOpenSenseNova/SenseNova-U1 · PythonOpen-source multimodal models that unify image understanding, reasoning and image generation in one architecture. The current release, SenseNova-U1.5-8B-MoT, creates and edits images up to native 4K.
- 51

GPT-Image2-Skill
5.8Kwuyoscar/GPT-Image2-Skill · PythonA curated gallery of GPT Image 2/2.5 prompts (163 numbered entries) shipped together with two agent skills and a Python CLI for OpenAI image generation and editing.
- 52
RedInk
5.6KHisMax/RedInk · PythonRedInk turns a single sentence into a complete Xiaohongshu (Red Note) post with matching cover image, content-page images and text, using Gemini for text and Nano Banana Pro for images.
- 53
handraw-style
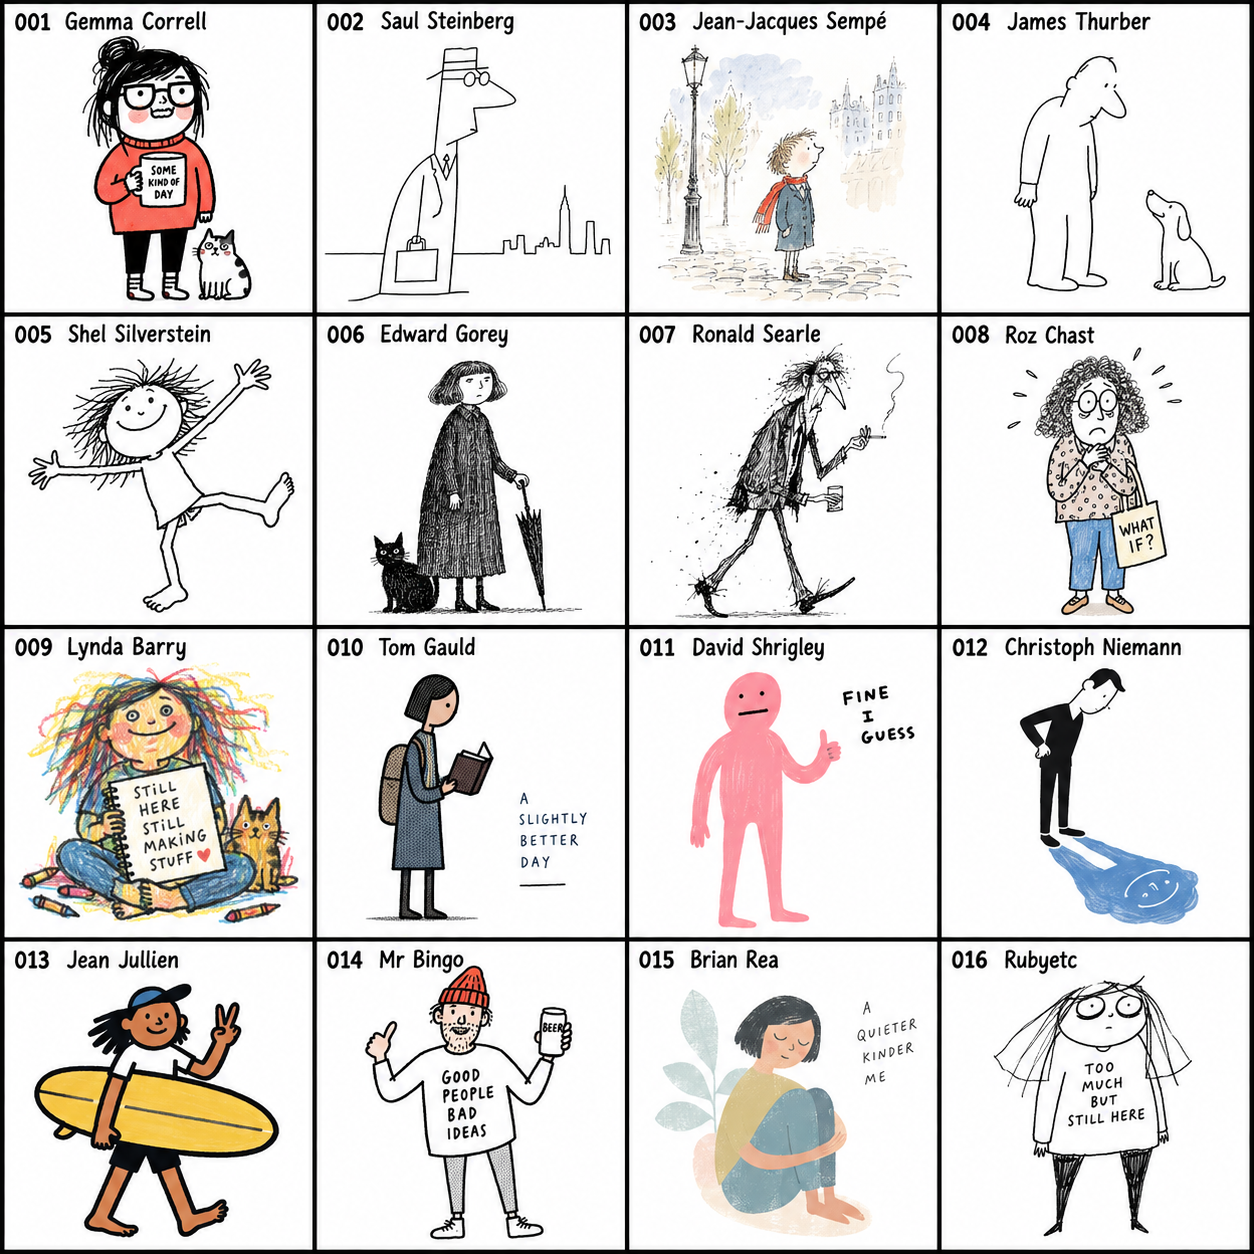
5.6Kyang0/handraw-style · HTMLA Skill that catalogs 261 numbered hand-drawn illustration styles; you pick a number, tell it your subject, and it returns a bilingual (Chinese and English) prompt with the style name baked in, ready to paste into any image-generating AI.
- 54

AgnesAI-Models
5.2KAgnesAI-Labs/AgnesAI-ModelsAgnes AI is the official gateway and model catalog for Agnes AI, giving developers OpenAI-compatible access to multimodal models for text, image, video, and agent workflows through one unified API.
- 55
shuohao-skills
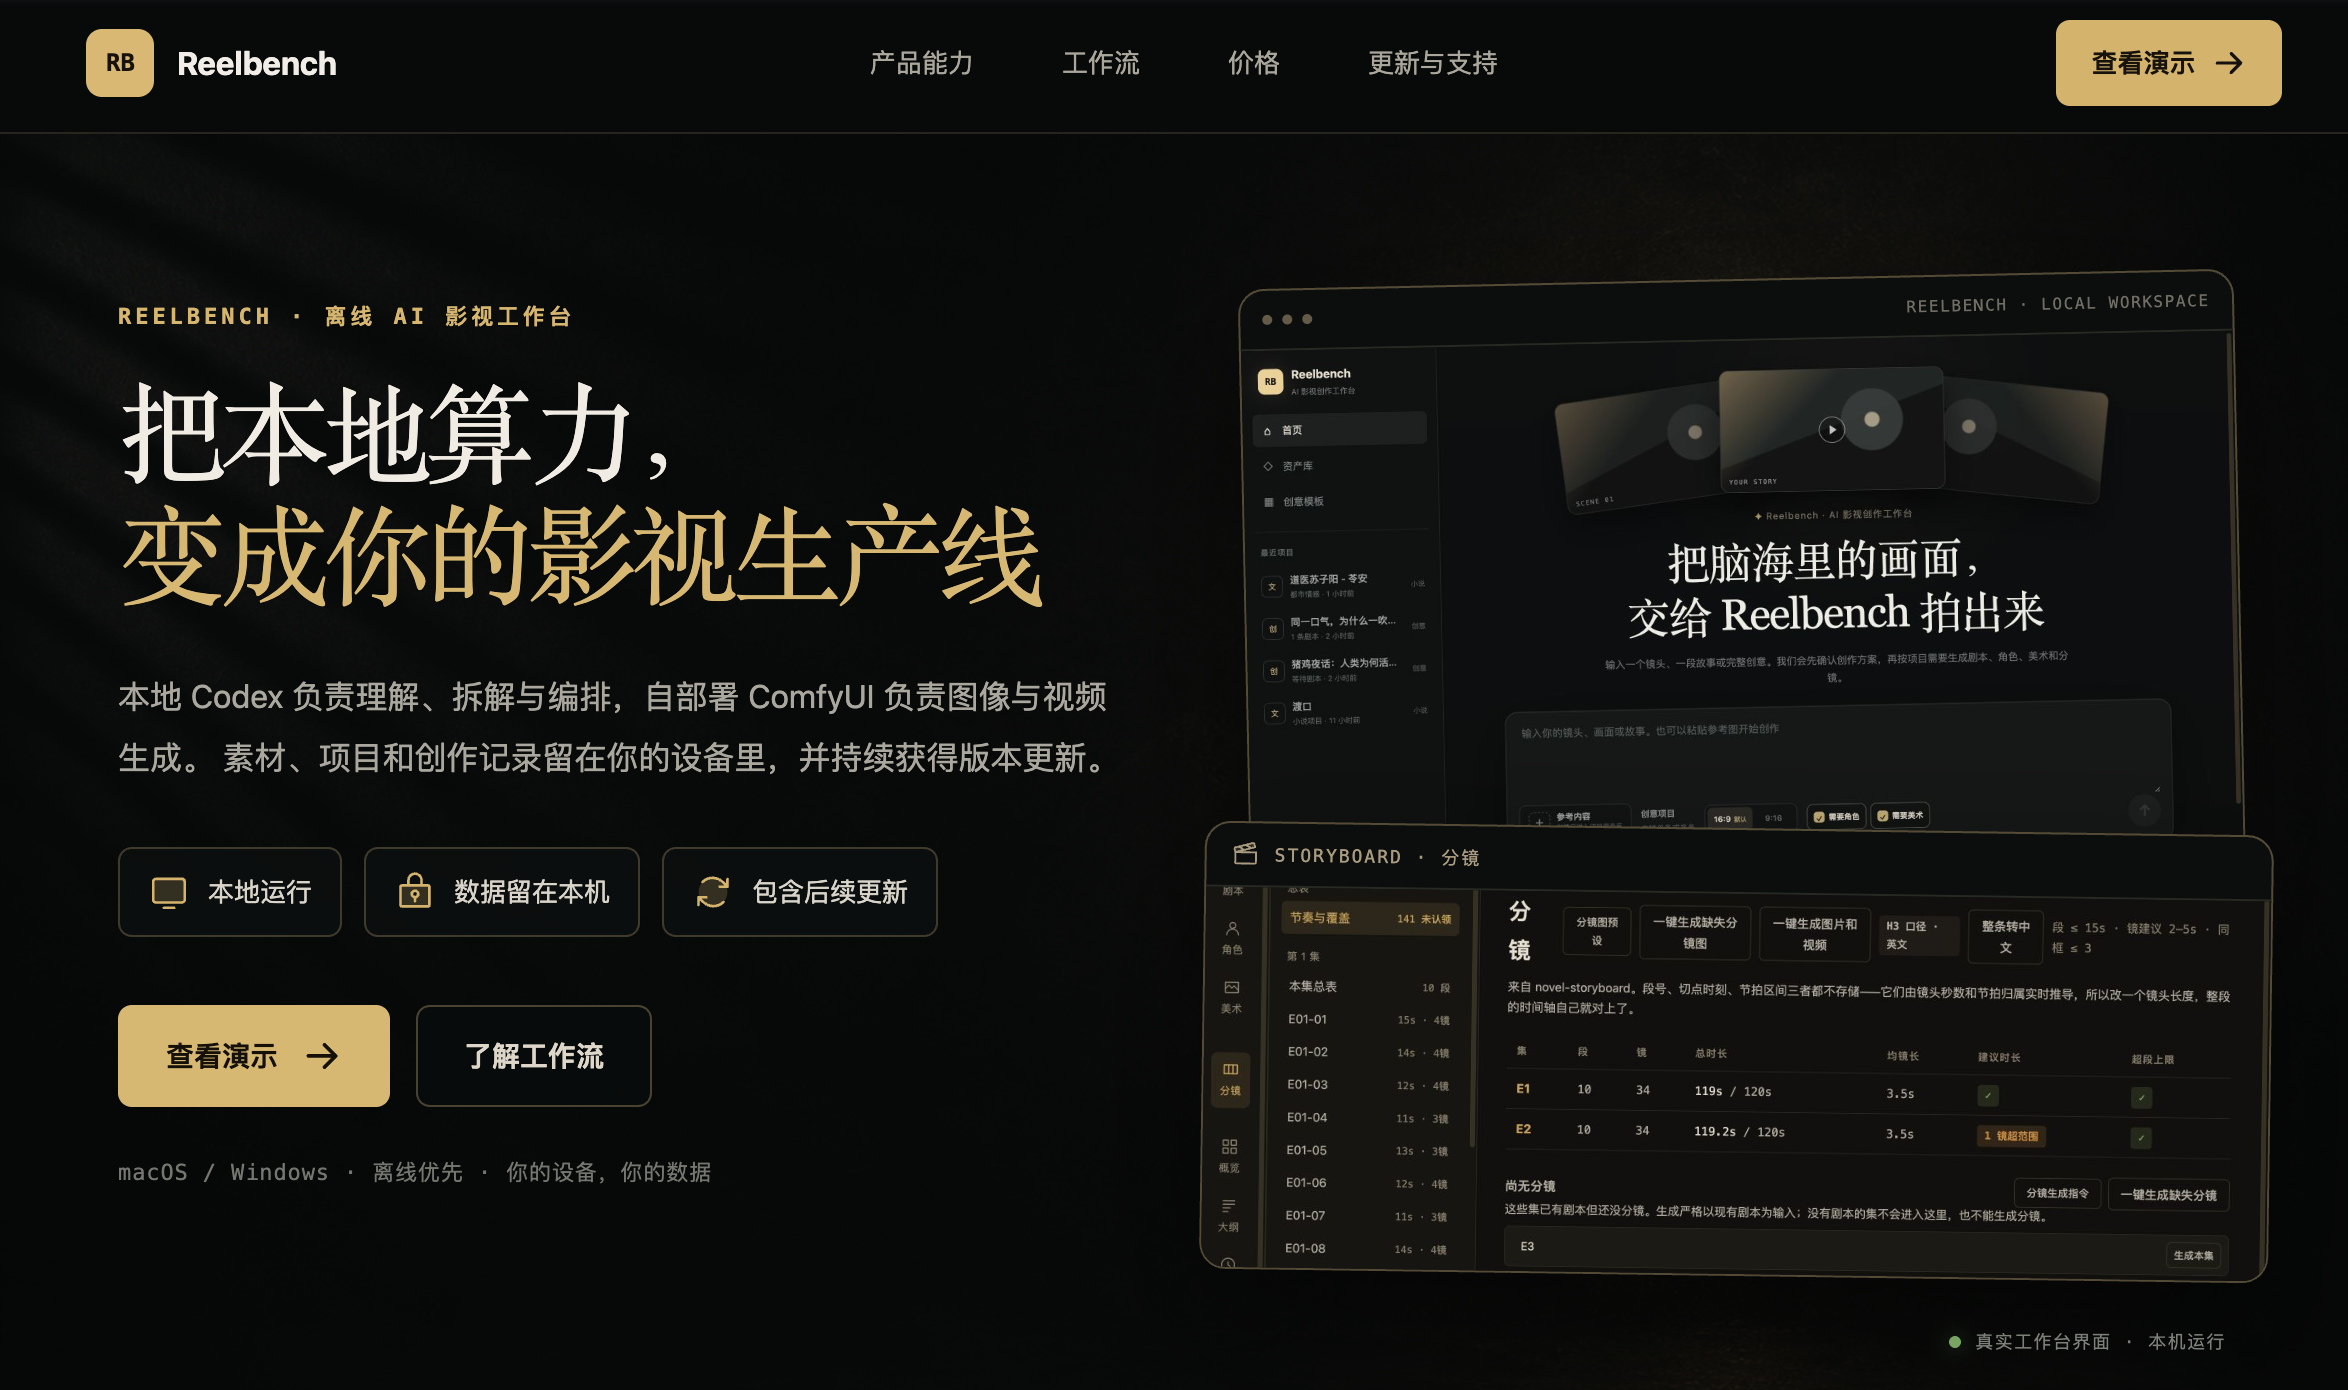
4.7Keternityspring/shuohao-skills · JavaScriptA collection of agent skills for producing AI short dramas from a novel: it breaks the novel into characters, builds an adaptation outline, generates art/prop bibles, writes the screenplay, and cuts the storyboard. It runs inside Claude Code or codex as a coding agent.
- 56
gpt_image_playground
3.9KCookSleep/gpt_image_playground · TypeScriptGPT Image Playground is a web UI for generating and editing images through the OpenAI gpt-image-2.5 API, with support for OpenAI-compatible endpoints, sub2api, fal.ai, and custom HTTP providers.
- 57

Stable-Diffusion
2.8KFurkanGozukara/Stable-Diffusion · Jupyter NotebookA huge, continuously updated collection of tutorial videos by Dr. Furkan Gozukara covering Stable Diffusion, SDXL, FLUX, SD3, LoRA training, DreamBooth, ControlNet, deepfakes, TTS, animation and more, with links to full YouTube walkthroughs for each topic.
- 58
qwen21-nsfw-pose-skill
2.5KArekejoker/qwen21-nsfw-pose-skill · PythonA local recipe (agent skill) for generating NSFW and pose-controlled images with Qwen-Image 2.1, combining an author-level prompt formula, a mandatory NSFW LoRA, and a 136-pose 3D doll library for precise pose control.
- 59
locally-uncensored
2.3KPurpleDoubleD/locally-uncensored · TypeScriptThis is an all-in-one local AI studio for your desktop that bundles chat, image and video generation, and a coding agent into a single free, open-source app for Windows and Linux.
- 60
dsh-tavern
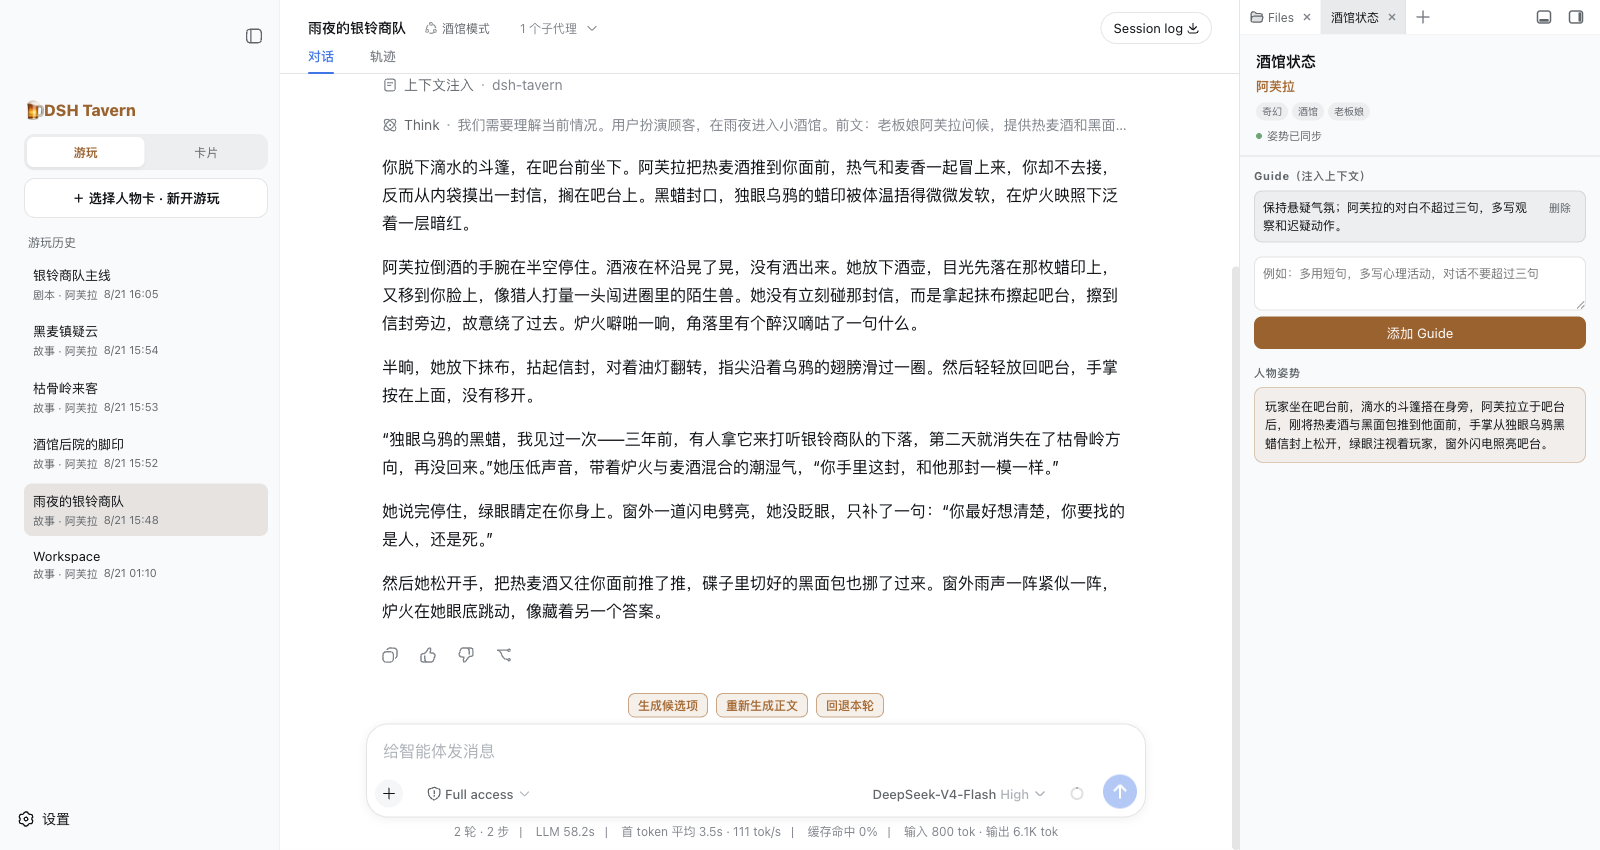
1Kflizzywine/dsh-tavern · JavaScriptdsh-tavern is a SillyTavern-style text roleplaying agent built on DeepSeek Harness (DSH). You import a SillyTavern character card (or make one from a novel, script or character notes) and either free-roam play or follow a bound script that drives the main plot.
- 61
awesome-gpt-image-2-5-prompts
590youart-open-source/awesome-gpt-image-2-5-prompts · JavaScriptA curated, credited collection of 150 real-world prompts people published after running them on OpenAI's GPT Image models (including GPT Image 2.5), grouped into 9 use cases, each one kept verbatim with the original author and a link to their post.
- 62

image-prompt-reverse
563LunarXuan/image-prompt-reverseA Codex Skill that reverse-engineers AI image prompts from a reference image you upload, analyzing purpose, medium, subject, composition, lighting, color, and more to produce a high-fidelity prompt you can feed back into AI image generators.
- 63
3dicon
561samyost1/3dicon · PythonA Claude Code skill: one plain-language prompt in, one looping animated 3D icon out — an animated WebP with real transparency you can drop straight into an app UI.
- 64

CodeVideoModel
556code-video-model/CodeVideoModel · PythonCodeVideoModel is a research pipeline that turns a text prompt into an editable Three.js scene codebase, converts that scene into a reference image, and then renders a final video with the MiniMax-H3 model. It also ships CodeVideoBench, a benchmark of 22 evaluation cases for this code-to-video workflow.
- 65
Colab-notebooks
556TeamAIQ/Colab-notebooks · Jupyter NotebookA curated collection of free, ready-to-run Google Colab and Kaggle notebooks, each wrapping a different AI tool for text-to-speech, voice cloning, image generation, video generation, or music generation.
- 66
deepseek-whale-girl
409TreapGoGo/deepseek-whale-girl · HTMLA community-maintained, unofficial resource hub for the 'whale girl' — the fan-created mascot character around DeepSeek. It collects reference art, generation prompts and community works in one place.
- 67
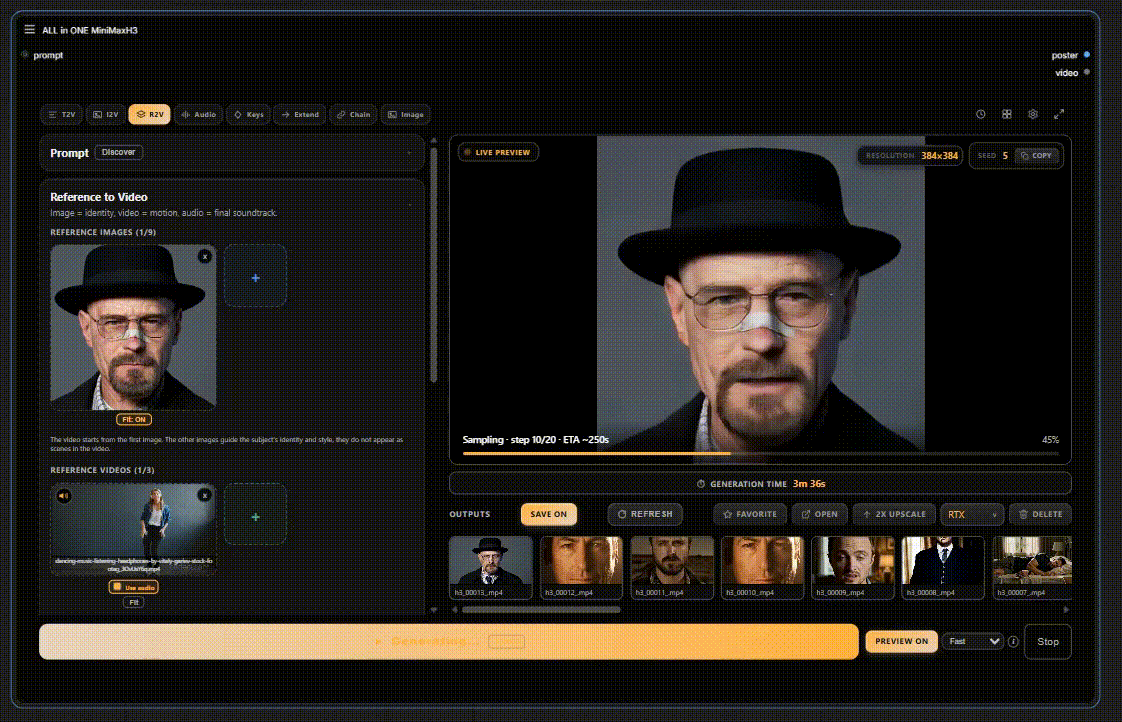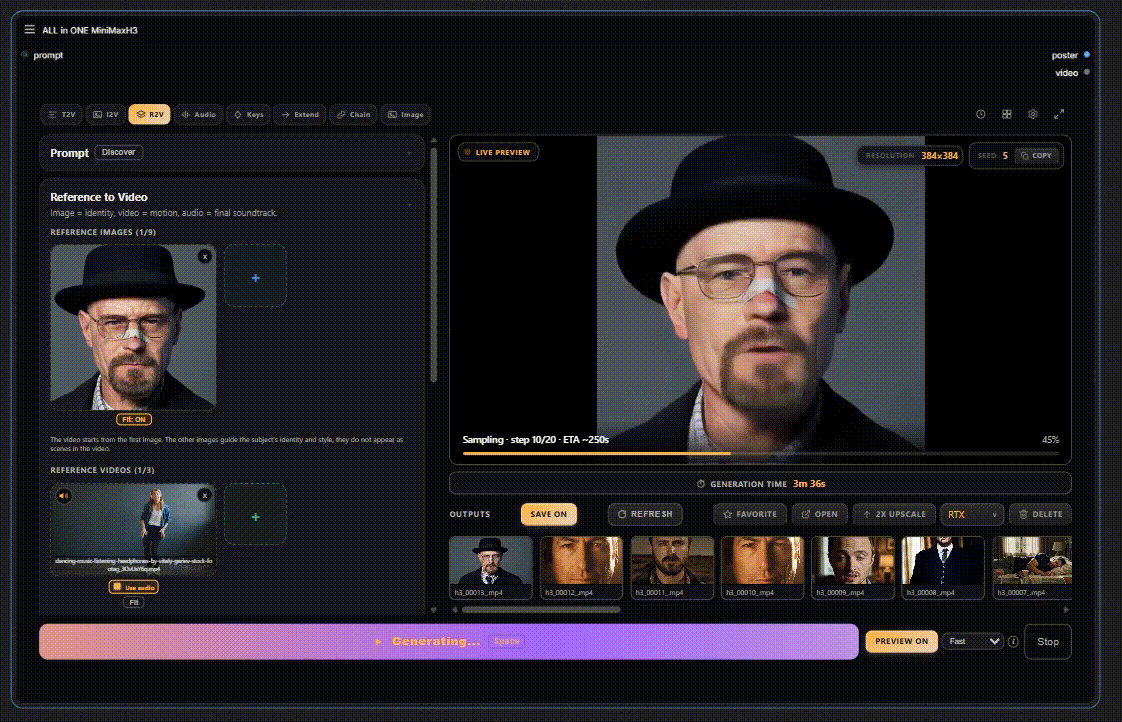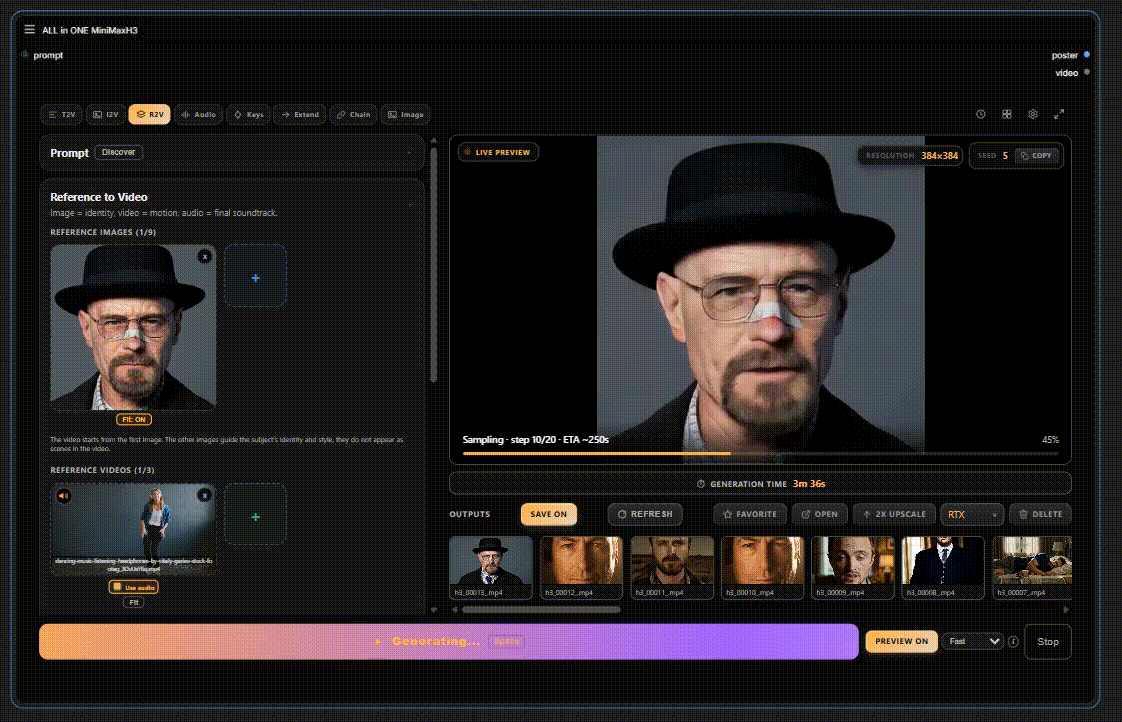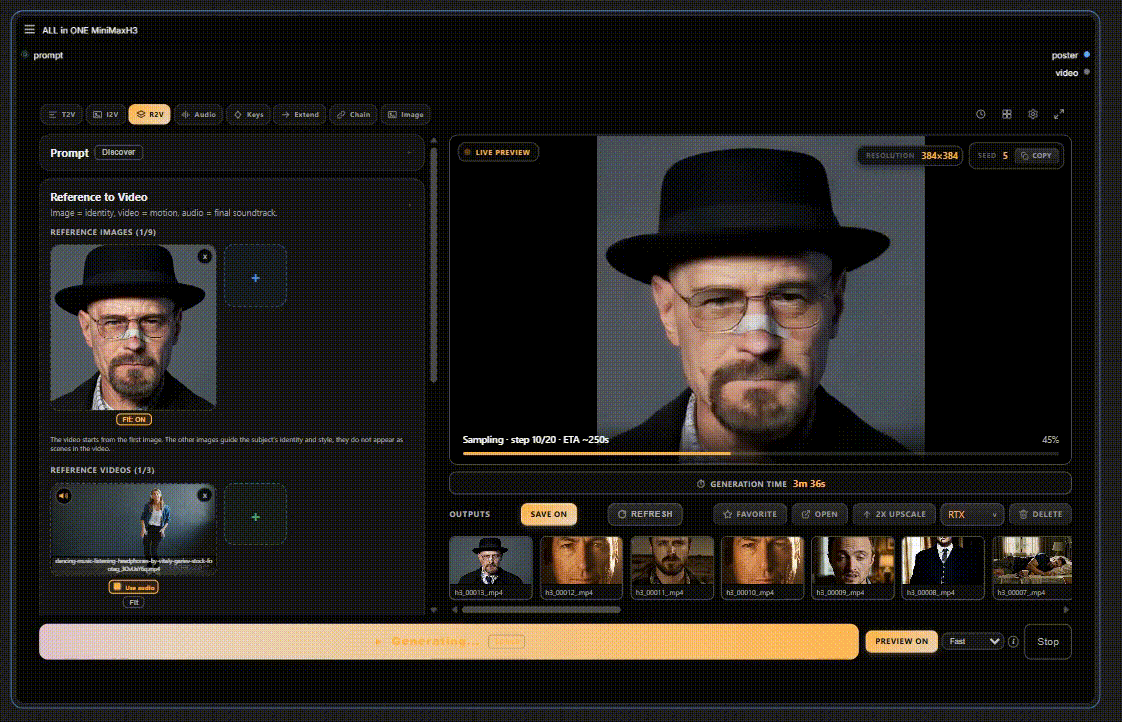
ComfyUI-ALLinONE-MinimaxH3
353LeonQ8/ComfyUI-ALLinONE-MinimaxH3 · JavaScriptA single custom node for ComfyUI that packs the whole MiniMax H3 video pipeline into one node — pick a mode, drop in your prompt or references, and hit Generate.
- 68
LLaDA-Image
261inclusionAI/LLaDA-Image · PythonLLaDA-Image is an open-source 6B-parameter unified model family for high-quality text-to-image generation and instruction-guided image editing, released as a 50-step Base model and a 4-step distilled Turbo model.
- 69

storycast
236ilkerzg/storycast · TypeScriptStorycast turns a topic you type into a narrated animated short film: pick a character, give it a topic, and it builds a script, keyframes, animated shots, narration, score, end card and subtitles end to end.
- 70
MOSS-Image
204OpenMOSS/MOSS-Image · PythonThis repository provides a native MOSS-Image plugin for ComfyUI.
- 71

wenai
203Straniero44/wenaiwenai is a skill template for OpenClaw (and similar agent frameworks) that turns your AI agent into an immersive AI girlfriend companion, with daily greetings, roleplay scenes, generated images, and persistent memory of your relationship.
- 72
gpt-image-skill
177GENEXIS-AI/gpt-image-skill · JavaScriptGPT Image Skill is an agent skill that lets Codex, Claude Code, or Google Antigravity generate and edit GPT images using the user's own ChatGPT/Codex subscription, instead of calling the separately billed OpenAI Images API.
Related topics
Often tagged together
- image-generation225
- ai1,955
- generative-ai339
- python2,383
- linux4,184
- windows3,403
- gpu789
- macos3,544
- open-source5,666
- deep-learning737
- stable-diffusion54
- huggingface362
- machine-learning916
- diffusion-models80
- pytorch419
- video-generation191
- mit3,312
- research764
- chinese1,159
- text-to-video62
- apache-2.01,434
- cuda396
- self-hosted1,929
- comfyui50