Topics / #llm-serving
LLM serving projects on GitHub
High-throughput inference engines and runtimes for serving large language models.
As of , the most-starred LLM serving projects on GitHub are vllm (94K stars), ray (44.1K stars) and sglang (37.2K stars). GitHub.Locker tracks 29 LLM serving repositories with 320.3K stars combined. The fastest-growing on October 16 was vllm, with +73 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +73
vllm
vllm-project/vllm · ★ 94KvLLM is a library for fast LLM inference and serving, built around PagedAttention for efficient memory management of attention keys and values.
 +47
ai-infra-book
bojieli/ai-infra-book · ★ 6.7KAn open-source book, 'Understanding AI Infra: Quantitative Analysis and System Design' by Bojie Li, that derives LLM inference and training system designs from hardware constraints and model architecture using quantitative, order-of-magnitude estimates.
 +38
sglang
sgl-project/sglang · ★ 37.2KSGLang is a high-performance serving framework for large language models and multimodal models, built to deliver low-latency, high-throughput inference from a single GPU up to large distributed clusters.
 +23
ds4
antirez/ds4 · ★ 23.9KDwarfStar (ds4) is a small, self-contained local inference engine specialized for running DeepSeek V4 Flash and PRO, plus GLM 5.2/5.3, on consumer hardware like high-memory Macs, NVIDIA GPUs, and AMD Strix Halo systems.
The all-time top
29 projects · by stars
- 94K#1 · vllm-project/vllm
vllm
vLLM is a library for fast LLM inference and serving, built around PagedAttention for efficient memory management of attention keys and values.
- 44.1K
 #2 · ray-project/ray
ray
Ray is an open-source framework for scaling AI and Python applications: a core distributed runtime plus a set of AI libraries that simplify ML compute.
- 37.2K#3 · sgl-project/sglang
sglang
SGLang is a high-performance serving framework for large language models and multimodal models, built to deliver low-latency, high-throughput inference from a single GPU up to large distributed clusters.
- 4
llm-action
25.2Kliguodongiot/llm-action · HTMLIt is a Chinese-language hub of in-depth tutorials on large language model engineering: training, fine-tuning, distributed training, inference, compression, evaluation, data engineering, LLMOps and AI infrastructure, organized as a big index linking the author's article series, many with companion code.
- 5
ds4
23.9Kantirez/ds4 · CDwarfStar (ds4) is a small, self-contained local inference engine specialized for running DeepSeek V4 Flash and PRO, plus GLM 5.2/5.3, on consumer hardware like high-memory Macs, NVIDIA GPUs, and AMD Strix Halo systems.
- 6

serve
21.9Kjina-ai/serve · PythonJina is an open-source Python framework for building multimodal AI applications on a cloud-native stack — you wrap models into gRPC microservices, chain them into flows, and scale from local to cloud.
- 7
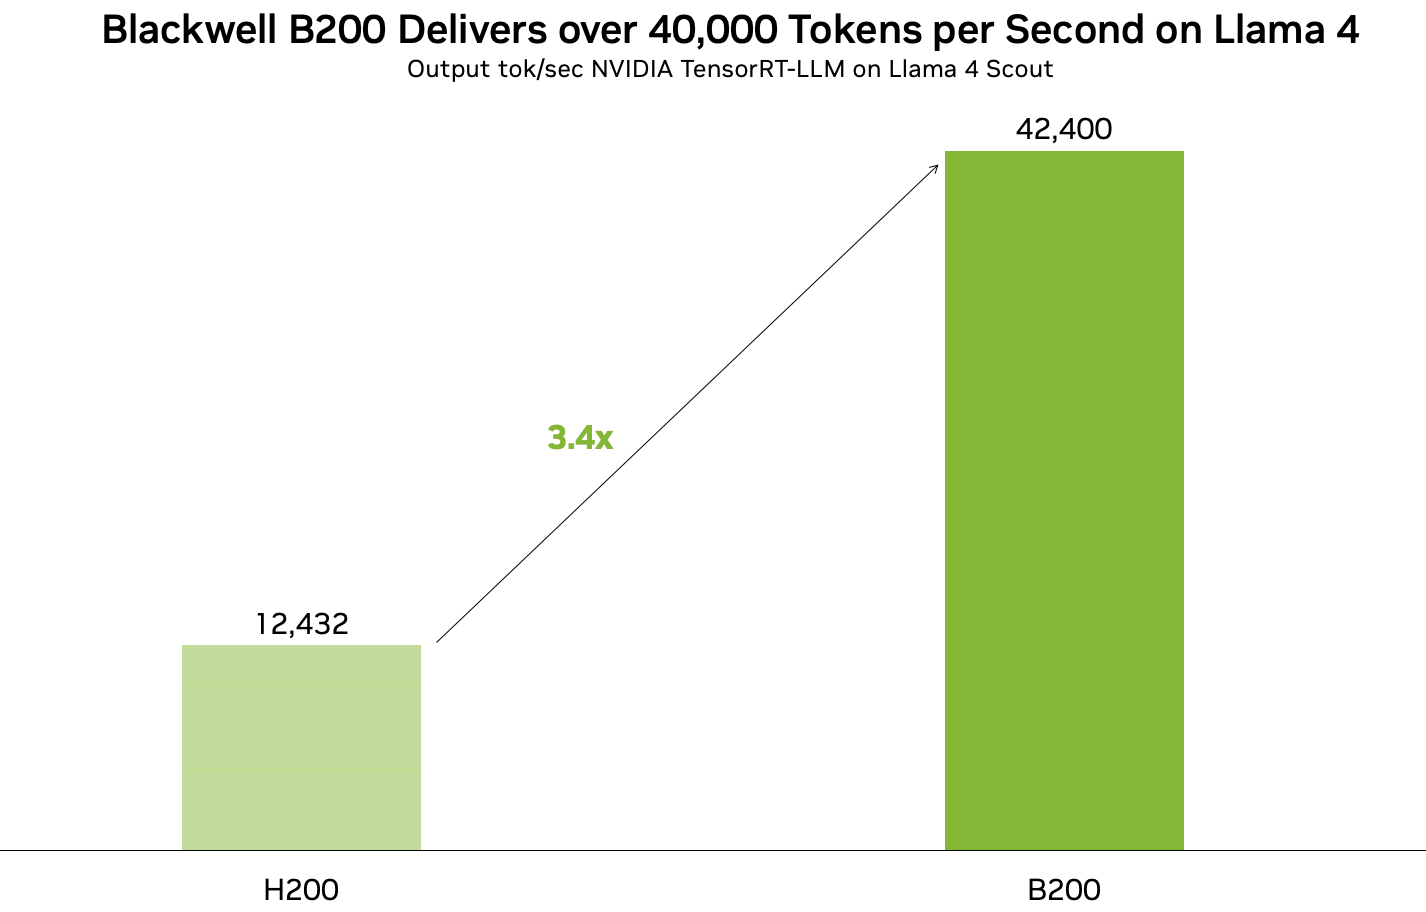
TensorRT-LLM
14.8KNVIDIA/TensorRT-LLM · PythonTensorRT LLM is NVIDIA's Python framework for defining large language models (and now visual generation models) and compiling them into highly optimized inference engines that run on NVIDIA GPUs, with specialized kernels and Python/C++ runtimes.
- 8
OpenLLM
12.6Kbentoml/OpenLLM · PythonOpenLLM lets you run open-source LLMs like Llama, DeepSeek, Mistral and Qwen as OpenAI-compatible API endpoints with a single command, including a built-in chat UI and cloud deployment support.
- 9
LMCache
12.1KLMCache/LMCache · PythonLMCache is a KV cache management layer for LLM inference that turns the KV cache from a temporary, per-process state into reusable, persistent 'AI-native knowledge' that can be shared across serving engines, reducing time-to-first-token and boosting throughput for long-context, multi-turn, and RAG workloads.
- 10
skypilot
10.7Kskypilot-org/skypilot · PythonSkyPilot is an open-source system for running, managing, and scaling AI workloads — training, serving, batch inference — on any infrastructure: your own Kubernetes or Slurm clusters, reserved GPUs, or 20+ clouds.
- 11

lectures
6.9Kgpu-mode/lectures · Jupyter NotebookThis is the supplementary material repository for the GPU MODE lectures YouTube channel — a growing collection of notebooks, slides and code from each numbered lecture on GPU and CUDA programming.
- 12
ai-infra-book
6.7Kbojieli/ai-infra-book · PythonAn open-source book, 'Understanding AI Infra: Quantitative Analysis and System Design' by Bojie Li, that derives LLM inference and training system designs from hardware constraints and model architecture using quantitative, order-of-magnitude estimates.
- 13

HyperQwen
2Ksyv-ai/HyperQwen · PythonHyperQwen is a self-hosted serving setup that runs the Qwen3.8-27B model on a single 24 GB consumer GPU (like an RTX 3090) using vLLM, exposing it through an OpenAI-compatible API.
- 14

TensorFold
1.4Kashhart/TensorFold · ZigTensorFold is an LLM inference engine that serves open-weight language models through an OpenAI-compatible API, running them on Apple Silicon via MLX or on NVIDIA GPUs via CUDA.
- 15
backburner
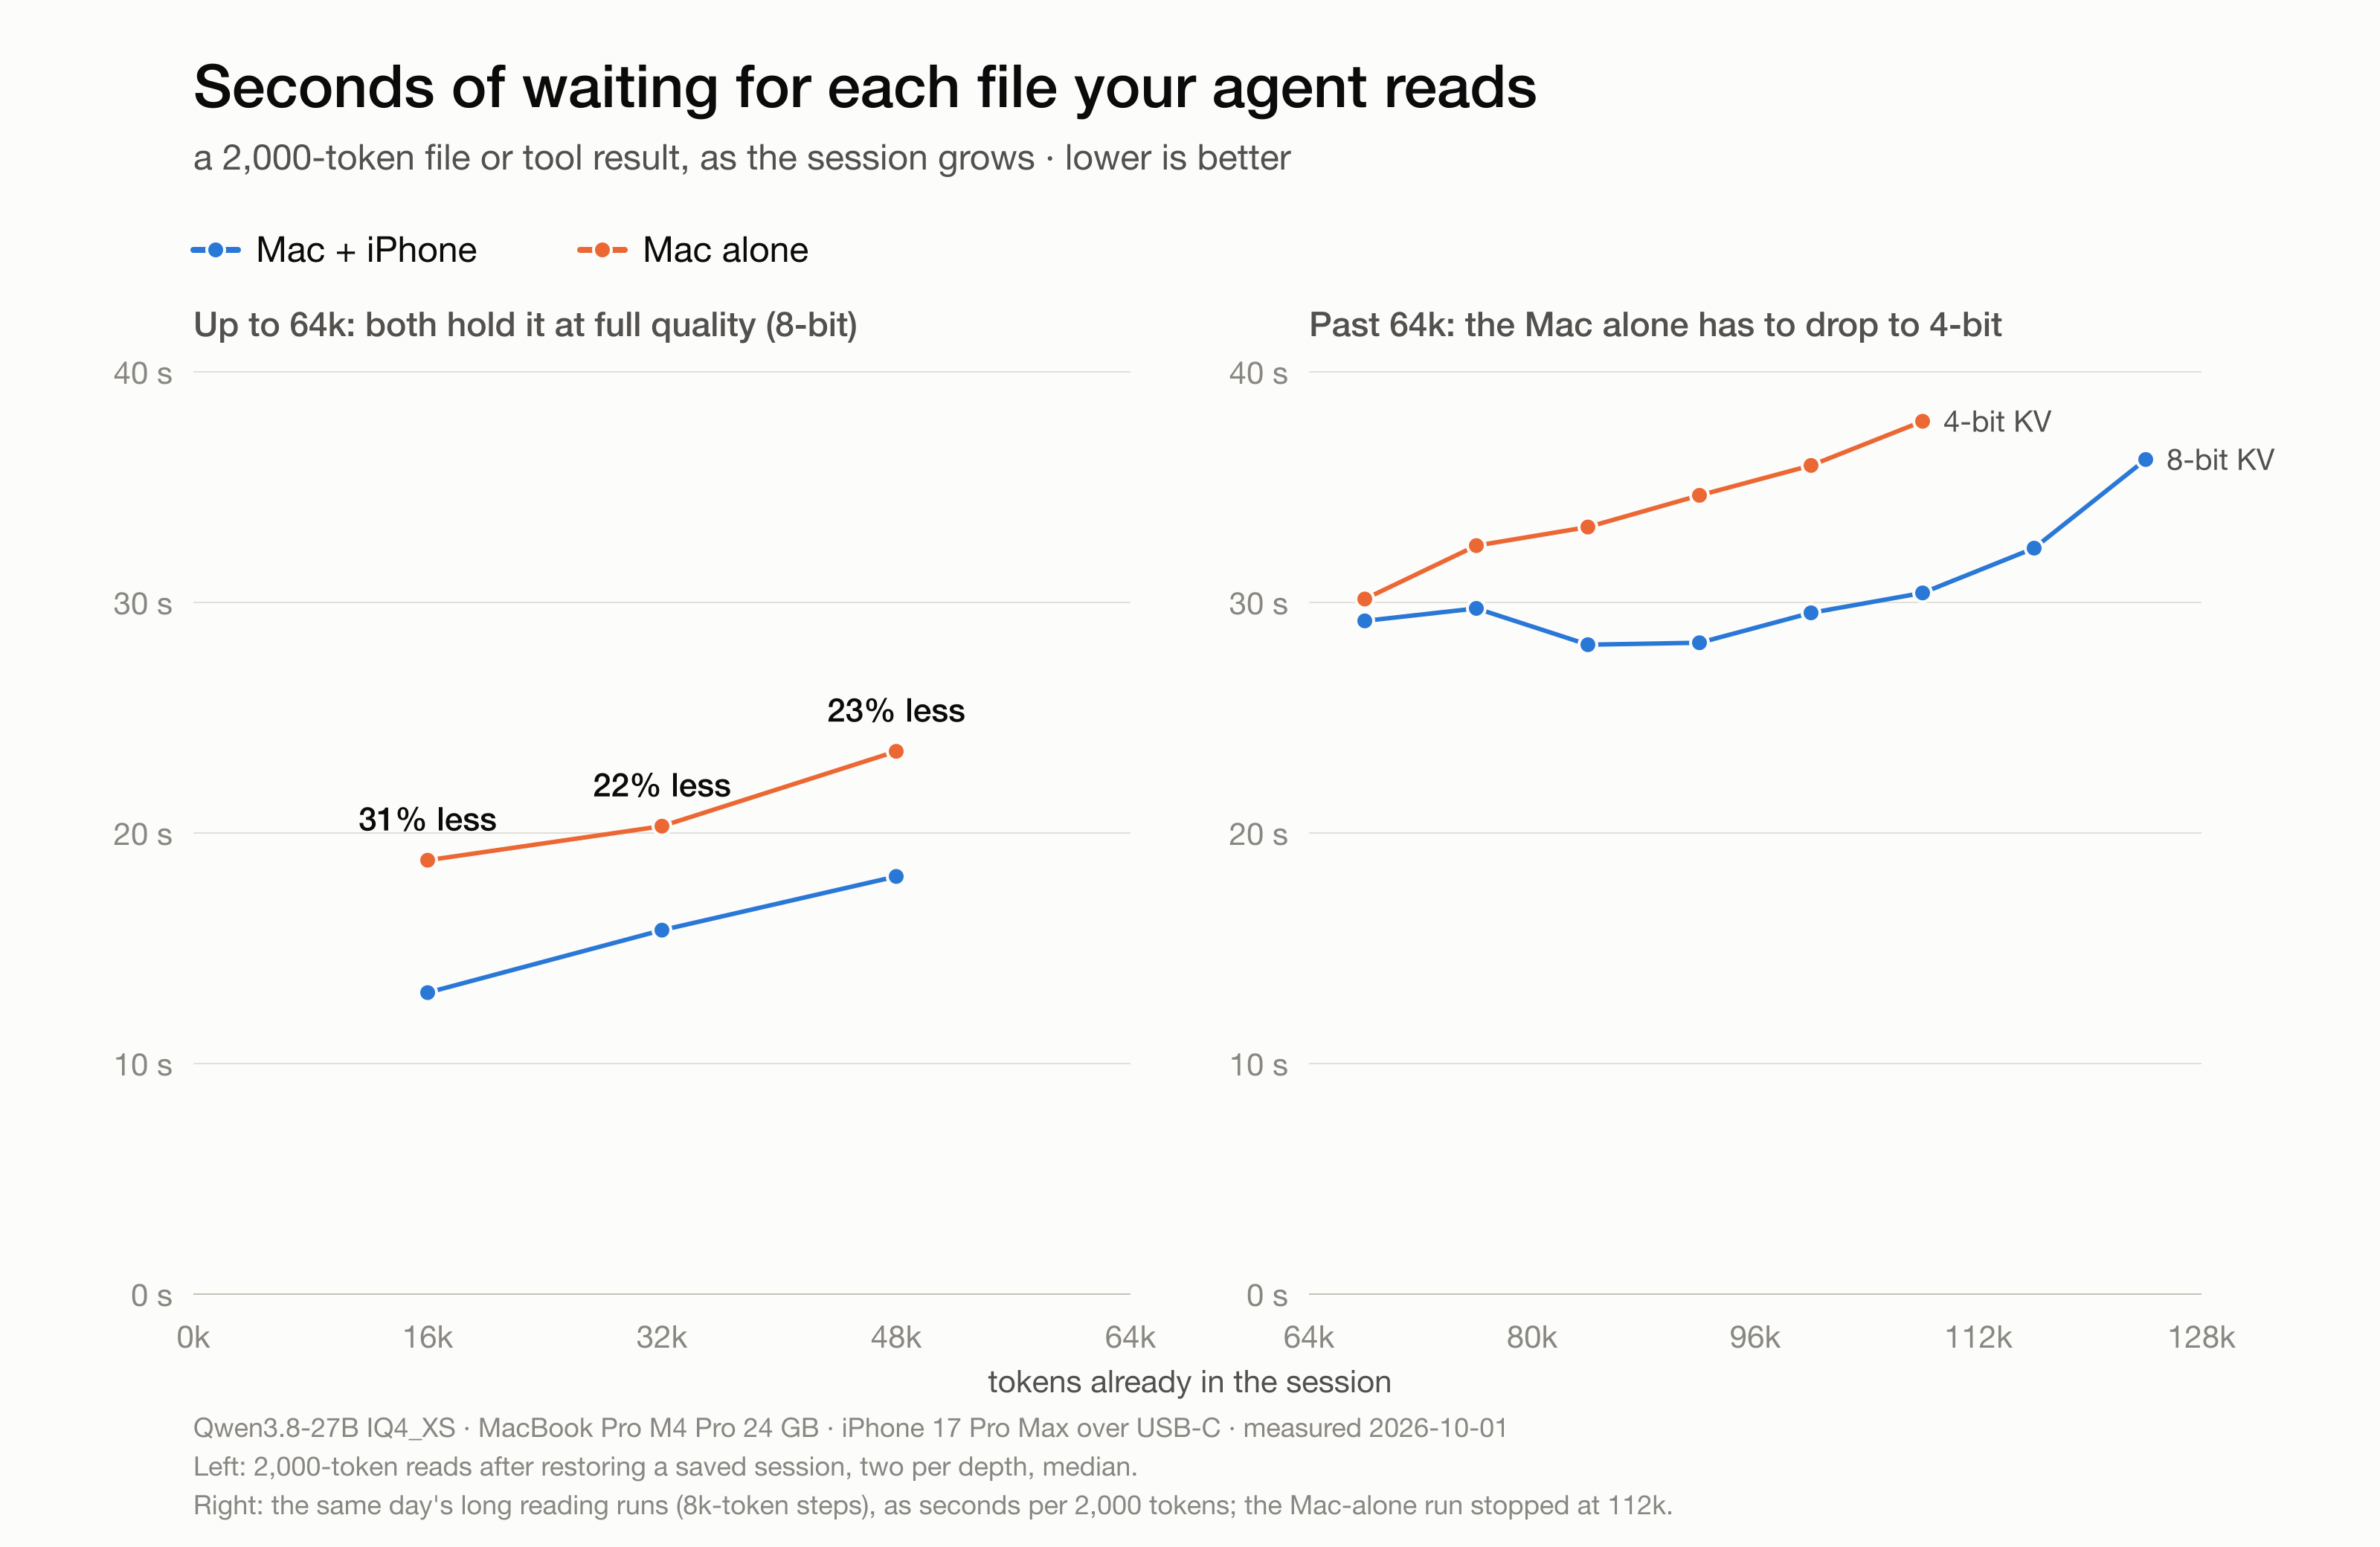
1KStayLameBro/backburner · PythonBackburner lets a nearby iPhone act as a coprocessor for your Mac so a locally-run 27B LLM (Qwen3.8-27B) reads prompts faster and holds far more context. The phone connects over a 10 Gb/s USB-C cable and offloads part of the model's layers plus storage/attention for old context.
- 16
halogen-flash-server
1Kpeonist-ai/halogen-flash-server · Shellhalogen-flash-server is a purpose-built inference server for running the Qwen3.8-Flash-Next model as fast as possible on AMD's Strix Halo (gfx1151) GPU, exposing an OpenAI-compatible API.
- 17

kaggle-tpu-lab
657ARahim3/kaggle-tpu-lab · PythonA recipe that serves frontier-class open LLMs — GLM-5.3-Flash 320B MoE and Qwen3.8-27B bf16 — on Kaggle's free TPU v5e-8, exposing a public OpenAI-compatible (and Anthropic-compatible) endpoint you can plug into coding agents like Claude Code, Codex, opencode, or pi.
- 18

Qwen3.8-Flash-Next-Single-DGX-Spark
609MiaAI-Lab/Qwen3.8-Flash-Next-Single-DGX-Spark · PythonA self-contained recipe for serving the Qwen3.8-Flash-Next-NVFP4 checkpoint from a single NVIDIA DGX Spark machine's unified memory, using vLLM with the PLE table offloaded and memory-mapped.
- 19
Qwen3.8-27B-16gb-NVIDIA-GPUs-one-click-install
587MiaAI-Lab/Qwen3.8-27B-16gb-NVIDIA-GPUs-one-click-install · PythonA one-click installer and serving kit for running Qwen3.8-27B locally on a single consumer NVIDIA GPU (12-32+ GB VRAM), on Windows or Linux.
- 20

qwen3.8-Flash-DGX
453blazux/qwen3.8-Flash-DGX · PythonA recipe (scripts plus a patched Docker image) for serving the ~176B-parameter Qwen3.8-Flash-Next model with vLLM on a single NVIDIA DGX Spark (GB10). It solves the problem that the 126 GiB NVFP4 checkpoint doesn't fit next to a usable KV cache in the Spark's 128 GB unified memory, by streaming a 48 GiB lookup table from NVMe via mmap instead of keeping it resident.
- 21
GLM-5.3-Flash-EXL3-2x-DGX-Sparks-TensorFold
444MiaAI-Lab/GLM-5.3-Flash-EXL3-2x-DGX-Sparks-TensorFold · PythonThis project serves the GLM-5.3-Flash language model as an OpenAI-compatible API, with vision and video input, running across two linked NVIDIA DGX Spark machines (GB10, 128GB each) using TensorFold.
- 22
jeeves
425PostHog/jeeves · PythonJeeves is a reasoning-enhanced 'Jev-like' decision model built on Qwen3.5-9B with LoRA. It thinks through a reasoning chain before giving calibrated yes/no, multiple-choice, or rating answers, and ships with a diffusion drafter for faster inference.
- 23
Qwen3.8-Flash-Next-Dual-DGX-Sparks
410MiaAI-Lab/Qwen3.8-Flash-Next-Dual-DGX-Sparks · HTMLA multi-node inference launcher that runs the Qwen3.8-Flash-Next-NVFP4 language model across two NVIDIA DGX Spark nodes using vLLM with tensor parallelism, expert parallelism and speculative decoding.
- 24
DeepSeek-v4-Flash-One-DGX-Spark
346MiaAI-Lab/DeepSeek-v4-Flash-One-DGX-Spark · PythonA single-node Docker launcher that serves the DeepSeek V4 Flash 0731 model (EXL3 3.0bpw quantization) with DSpark speculative decoding, tuned to run entirely on one NVIDIA DGX Spark machine.
- 25
llm-inference-engineering
344amitshekhariitbhu/llm-inference-engineering · MarkdownA free, continuously growing blog series that teaches LLM inference engineering step by step, covering KV cache, PagedAttention, continuous batching, speculative decoding, and serving engines like vLLM, SGLang, TensorRT-LLM, and GGUF.
- 26
Hyperloom
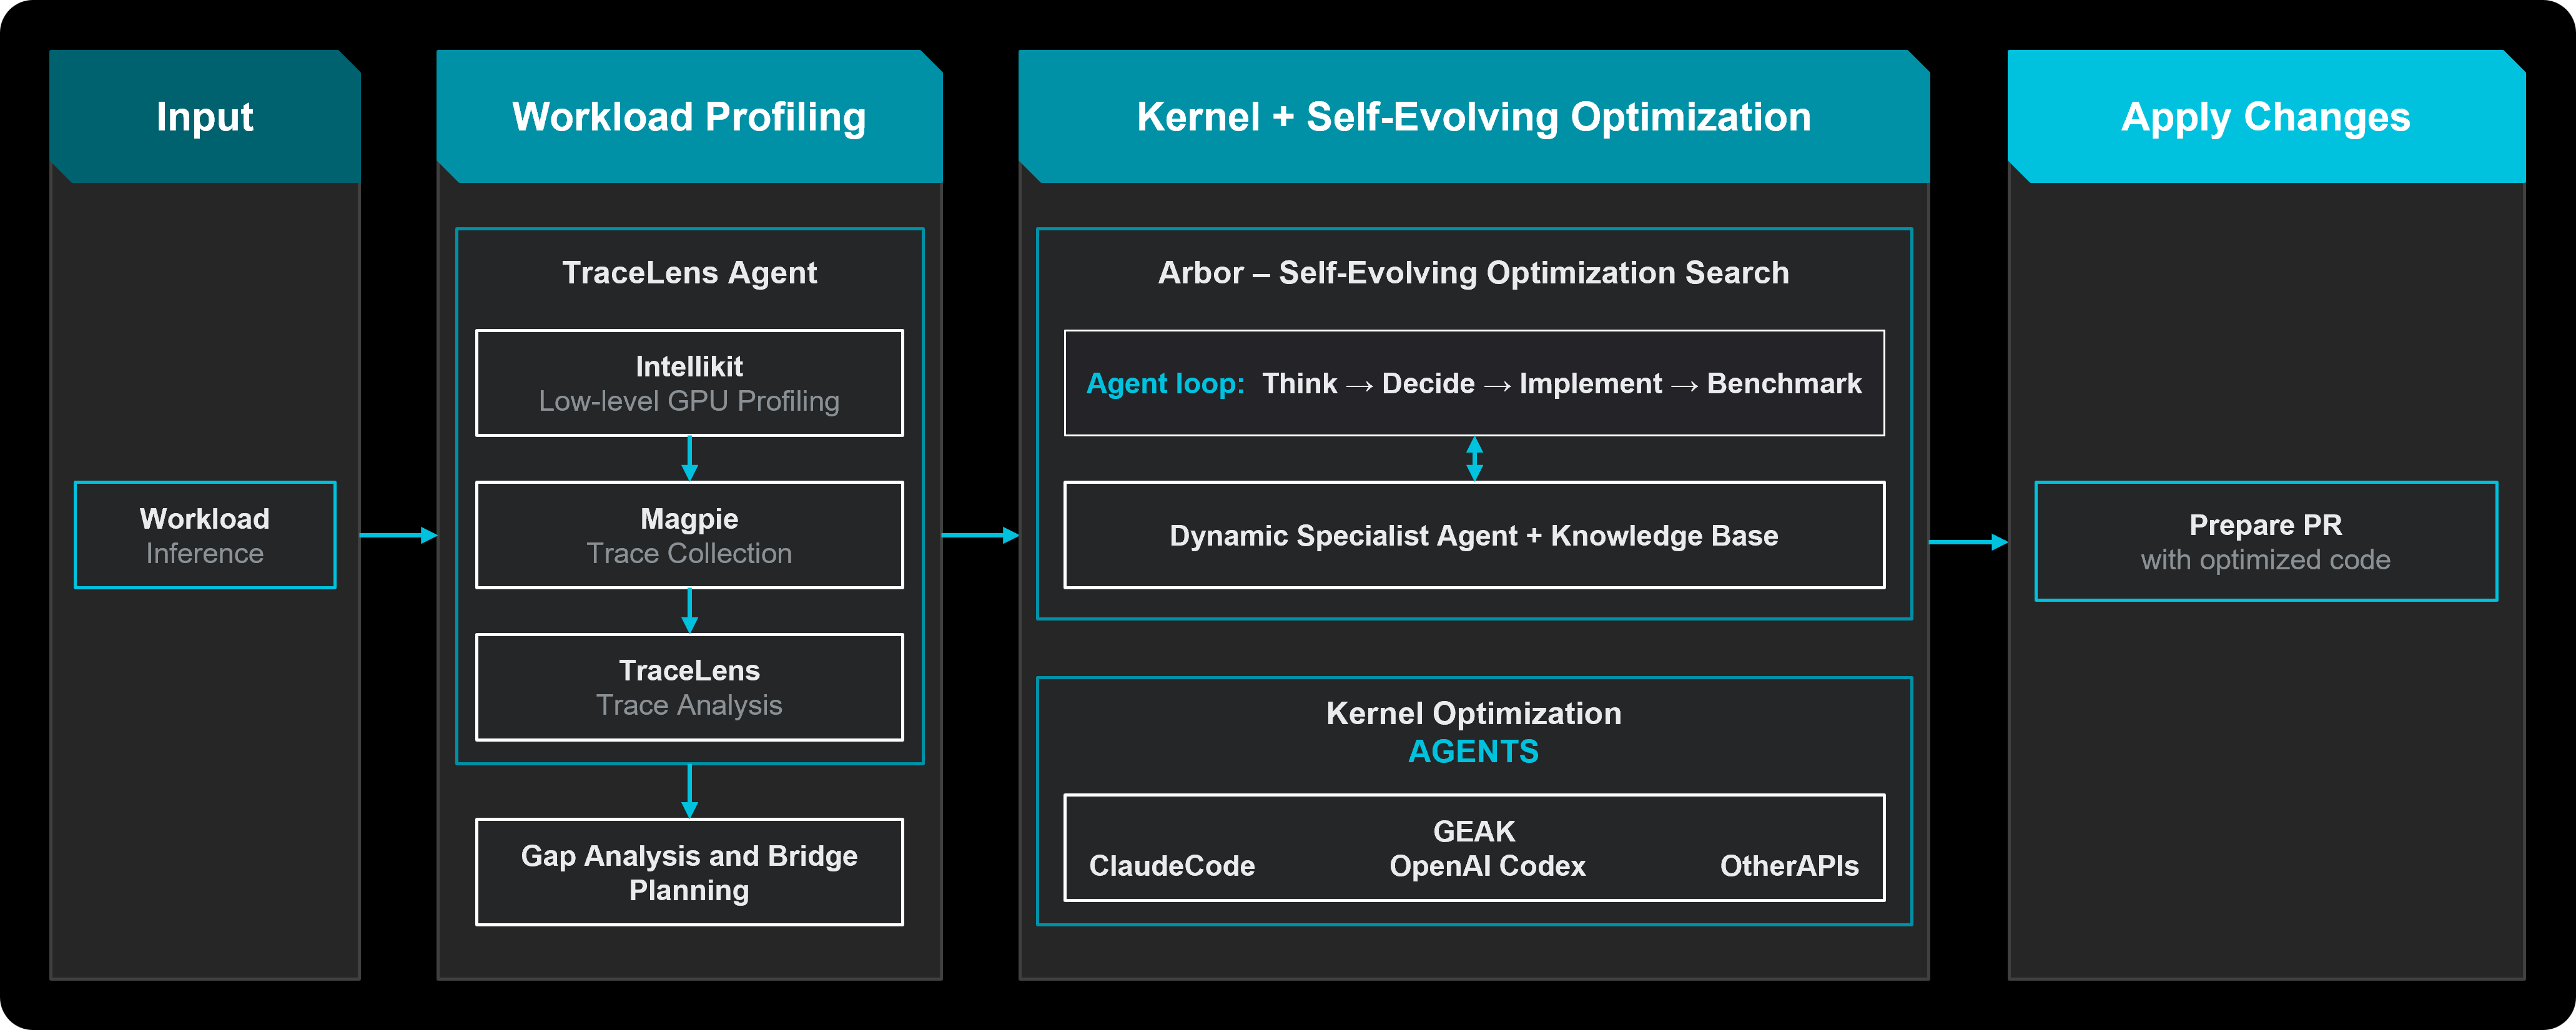
241AMD-AGI/Hyperloom · PythonA multi-agent harness that autonomously optimizes LLM inference on AMD Instinct GPUs: it profiles your workload, searches framework and GPU-kernel optimizations, validates every candidate end to end, and saves proven results into a recipe knowledge base.
- 27

v100-skinny
172dnv2003/v100-skinny · Pythonv100-skinny provides hand-written NVFP4 (W4A16) and FP8 (W8A16) CUDA kernels that let four Tesla V100-SXM2-16GB GPUs run Qwen3.8-27B's published mixed NVFP4/FP8 weights directly, serving the model through an OpenAI-compatible API.
- 28
tpu-megakernels
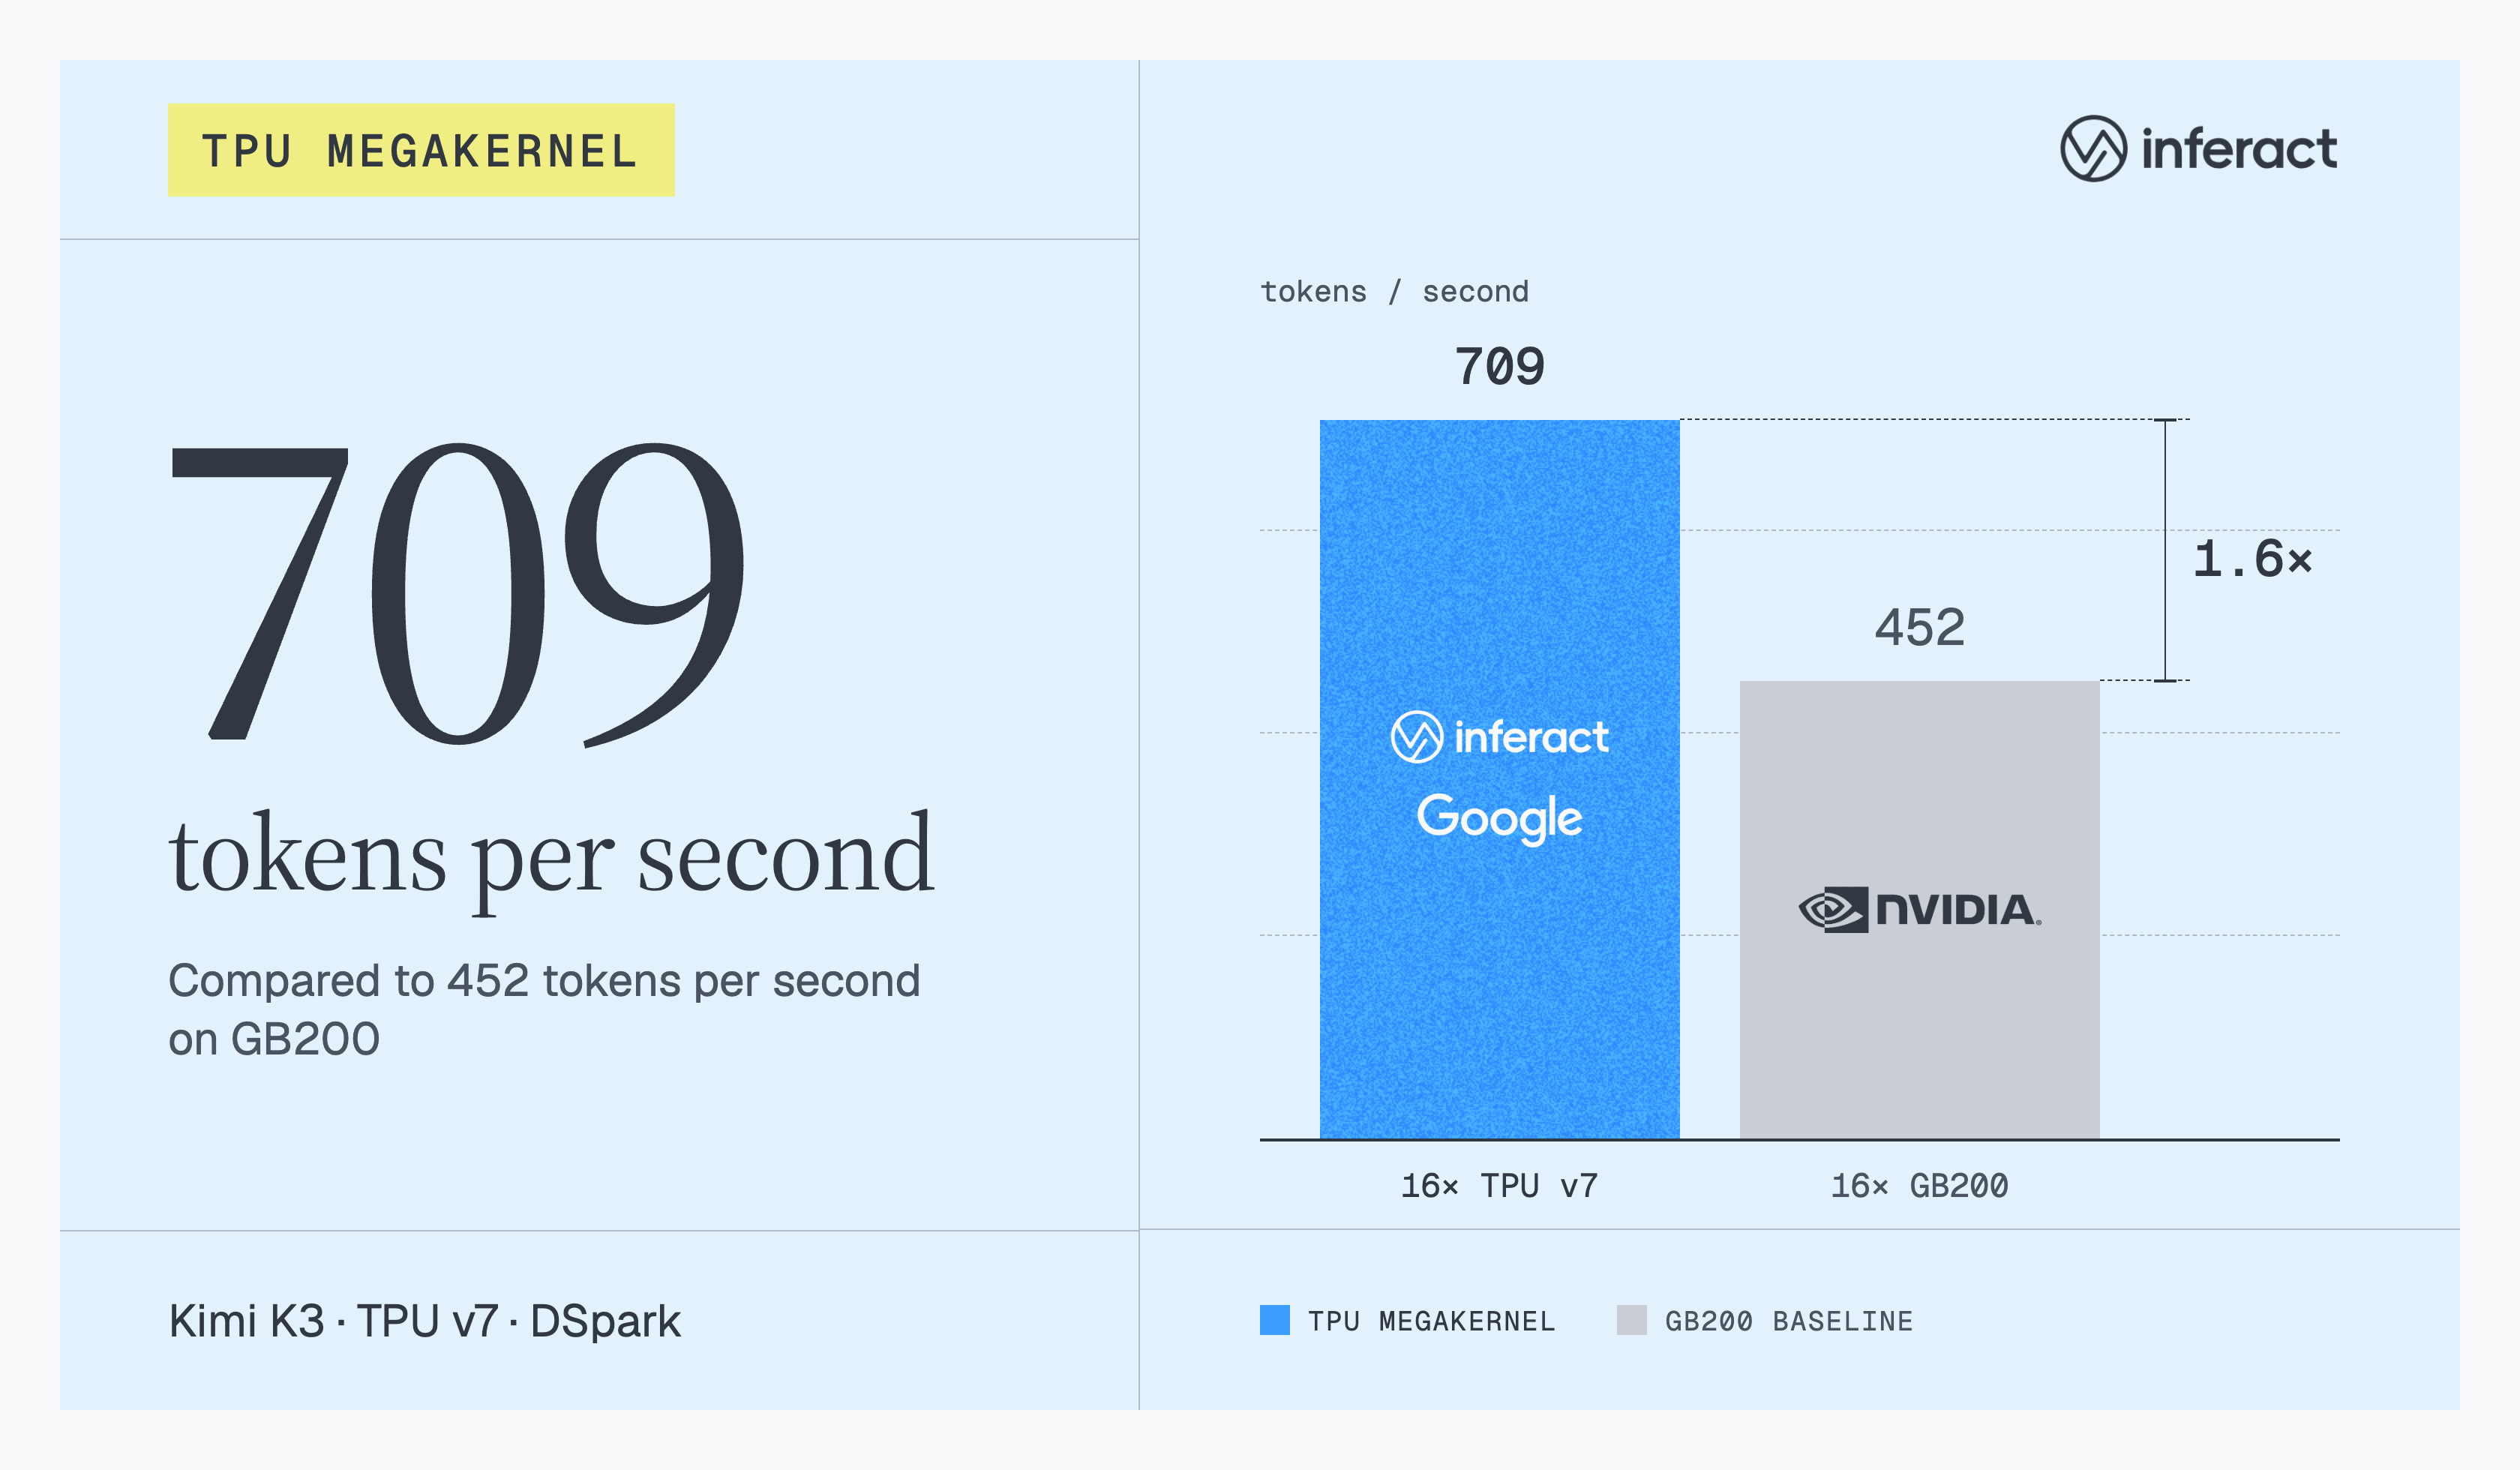
162Inferact/tpu-megakernels · PythonA companion research repo with fused 'megakernel' decode implementations for two models on Google TPUs: Kimi K3 with DSpark speculative decoding, and Qwen3.8-27B with DFlash2 speculative decoding, written to accompany the blog post '700 TPS on Kimi K3: A Case for TPU Megakernels'.
- 29
Inference-autopilot
143rednote-machine-learning/Inference-autopilot · PythonInference Autopilot (inferopt) is a CLI that benchmarks SGLang inference deployments on your own hardware and workload, diagnoses bottlenecks, and returns a reproducible, evidence-backed launch command.
Related topics
Often tagged together
- gpu789
- inference327
- llm1,483
- python2,383
- llm-inference119
- quantization183
- linux4,184
- cuda396
- nvidia328
- self-hosted1,929
- server1,459
- speculative-decoding40
- model-serving46
- open-source5,666
- large-language-models213
- local-llm218
- machine-learning916
- vllm124
- gpu-acceleration144
- openai-compatible211
- deep-learning737
- docker1,660
- qwen154
- ai1,955