Topics / #performance-optimization
Performance-optimization projects on GitHub
Guides and tools for making software faster and more efficient.
As of , the most-starred Performance-optimization projects on GitHub are flash-attention (25.1K stars), ants (14.5K stars) and KeyDB (12.5K stars). GitHub.Locker tracks 16 Performance-optimization repositories with 112.7K stars combined. The fastest-growing on October 16 was dlssg_for_sm86, with +28 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +28
dlssg_for_sm86
sdli1995/dlssg_for_sm86 · ★ 4.6KDLSSG Native is a DLL mod that lets NVIDIA RTX 20 (SM75) and RTX 30 (SM86) series GPUs run DLSS Frame Generation in D3D12 games, even though NVIDIA doesn't officially support frame generation on those cards. It bundles its own C++ wrapper, PTX/Cubin kernels for both GPU generations, and the 310.1 inference model into a single DLL instead of using NVIDIA's original feature DLL.
 +19
agent-device
callstack/agent-device · ★ 5.1Kagent-device gives AI coding agents a feedback loop on real mobile and desktop apps: it lets them inspect, control, debug, and verify apps on iOS, Android, HarmonyOS, TV platforms, web, macOS, and Linux, and save evidence for review.
 +14
sales-crm
kargulstudio/sales-crm · ★ 1.7KKargul Starter is a boilerplate for building web projects with Next.js 16, React 19, and Tailwind CSS 4, shipped with a strict set of build conventions.
 +9
flash-attention
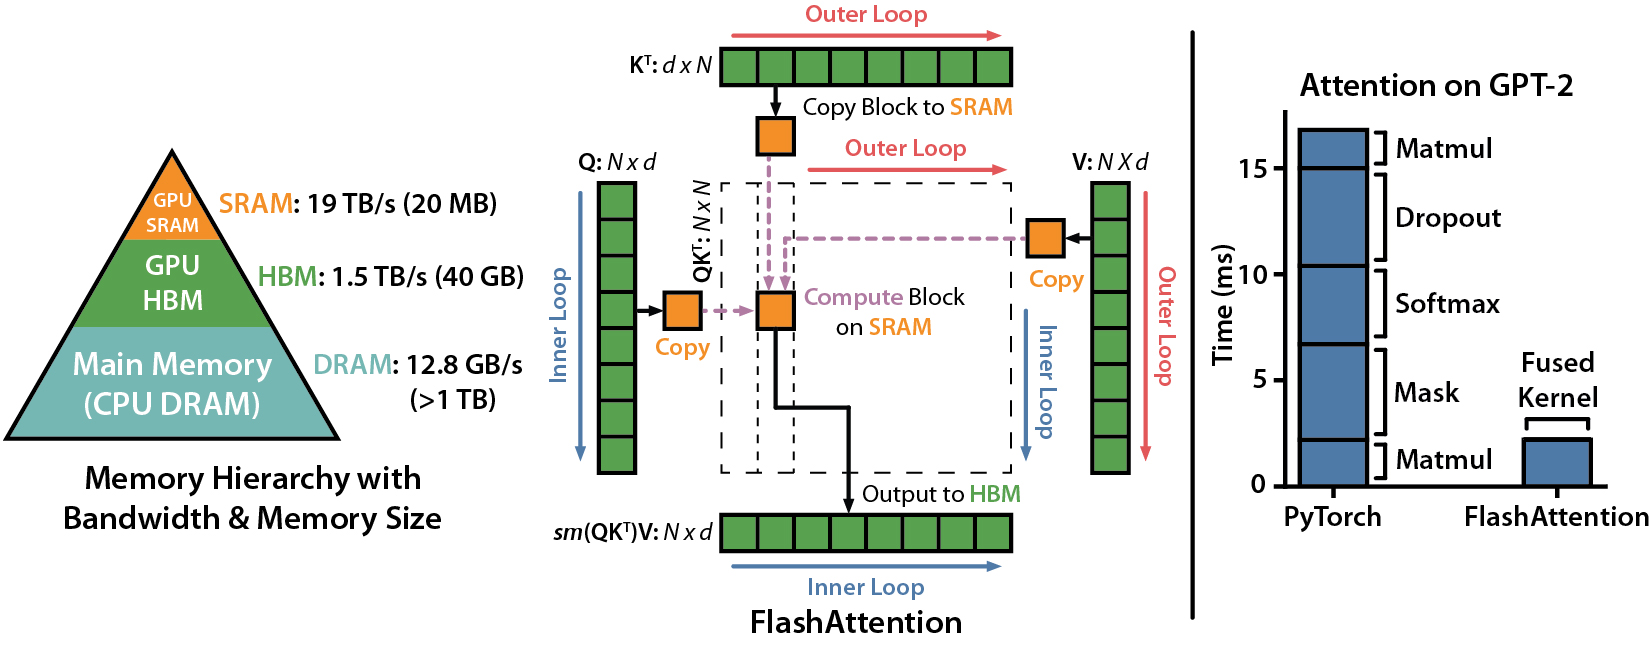
Dao-AILab/flash-attention · ★ 25.1KThe official implementation of FlashAttention and FlashAttention-2 — GPU kernels that compute exact attention faster and with less memory than standard PyTorch attention.
The all-time top
16 projects · by stars
- 25.1K#1 · Dao-AILab/flash-attention
flash-attention
The official implementation of FlashAttention and FlashAttention-2 — GPU kernels that compute exact attention faster and with less memory than standard PyTorch attention.
- 14.5K
 #2 · panjf2000/ants
ants
ants is a goroutine pool library for Go: it manages and recycles a massive number of goroutines with a fixed capacity, letting you limit how many run concurrently in your program.
- 12.5K
 #3 · Snapchat/KeyDB
KeyDB
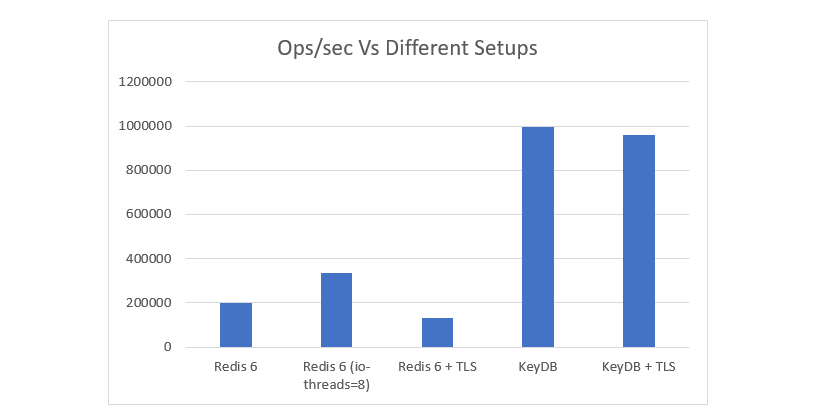
KeyDB is a multithreaded fork of Redis focused on performance, memory efficiency, and high throughput, offering extra features like Active Replication and Subkey Expires.
- 4

jemalloc
11.2Kjemalloc/jemalloc · Cjemalloc is a general purpose malloc(3) implementation — a memory allocator for C programs — emphasizing fragmentation avoidance and scalable concurrency support.
- 5

go-perfbook
10.9Kdgryski/go-perfbookIt is a free, work-in-progress book documenting best practices for writing high-performance Go code, covering both general optimization techniques and Go-specific ones.
- 6

cython
10.9Kcython/cython · CythonCython is an optimising compiler for Python: it translates your Python code into C/C++ and compiles it into fast native extension modules. It is the most widely used Python to C compiler.
- 7

xformers
10.6Kfacebookresearch/xformers · PythonxFormers is Meta's (Facebook Research) toolbox of hackable, optimized Transformer building blocks that you compose together — reusable pieces for your own models rather than a monolithic framework.
- 8
agent-device
5.1Kcallstack/agent-device · TypeScriptagent-device gives AI coding agents a feedback loop on real mobile and desktop apps: it lets them inspect, control, debug, and verify apps on iOS, Android, HarmonyOS, TV platforms, web, macOS, and Linux, and save evidence for review.
- 9
dlssg_for_sm86
4.6Ksdli1995/dlssg_for_sm86 · HTMLDLSSG Native is a DLL mod that lets NVIDIA RTX 20 (SM75) and RTX 30 (SM86) series GPUs run DLSS Frame Generation in D3D12 games, even though NVIDIA doesn't officially support frame generation on those cards. It bundles its own C++ wrapper, PTX/Cubin kernels for both GPU generations, and the 310.1 inference model into a single DLL instead of using NVIDIA's original feature DLL.
- 10

InfraTech
4.2KCalvinXKY/InfraTech · Jupyter NotebookInfraTech is a collection of Jupyter notebooks and articles sharing AI Infra knowledge: training/inference frameworks (PyTorch, vLLM/SGLang, slime/vime), performance acceleration, deep learning fundamentals and AI hardware/software basics.
- 11
sales-crm
1.7Kkargulstudio/sales-crm · TypeScriptKargul Starter is a boilerplate for building web projects with Next.js 16, React 19, and Tailwind CSS 4, shipped with a strict set of build conventions.
- 12
MAKO
613eugeniosegala/MAKO · C++MAKO is a Vulkan-powered graphics layer for Linux gaming that brings Lossless Scaling-style frame generation, LS1 spatial scaling, and an open MAKO Scaler to Steam Deck, Steam Machine, and desktop Linux. It is the continuation of the Decky LSFG-VK Experimental and LSFG-VK Experimental projects.
- 13

qwen38-mtp
363sudoingX/qwen38-mtp · PythonThis repo documents a single llama.cpp server flag that unlocks multi-token-prediction (MTP) speculative decoding for Qwen3.8-27B, giving +33% to +145% faster decode on consumer GPUs. It bundles the exact launch command, a crowdsourced benchmark table across dozens of GPUs, and a probe.py script for measuring the gain yourself.
- 14

v100-skinny
172dnv2003/v100-skinny · Pythonv100-skinny provides hand-written NVFP4 (W4A16) and FP8 (W8A16) CUDA kernels that let four Tesla V100-SXM2-16GB GPUs run Qwen3.8-27B's published mixed NVFP4/FP8 weights directly, serving the model through an OpenAI-compatible API.
- 15

seo-landing
169aleksandr-alhoff/seo-landing · HTMLIt is an Agent Skill that turns an AI coding agent into a technical SEO engineer, guiding it to build or fix landing pages for performance, Core Web Vitals, and structured data.
- 16

CalcKernel
152luxine/CalcKernel · RustCalcKernel (CK) is a statically typed language for writing focused numerical computation kernels that a larger application calls into, rather than a full application-level language.
Related topics
Often tagged together