Topics / #tokenization
Tokenization projects on GitHub
Text tokenization for NLP pipelines and model inputs.
As of , the most-starred Tokenization projects on GitHub are nanochat (58.7K stars), LLM101n (37.5K stars) and HanLP (36.5K stars). GitHub.Locker tracks 20 Tokenization repositories with 365.3K stars combined. The fastest-growing on October 17 was lm-detector, with +96 stars in a day.
Hot right now
Most stars gained in a day · Oct 17
 +96
lm-detector
Ikaleio/lm-detector · ★ 488LM Fingerpoint Detector figures out which large language model is really answering behind an API by asking it to write about 300 random integers between 1 and 355, then comparing the statistical pattern of those numbers against a reference bank of known models (GPT, Claude, Gemini, Grok, Qwen, DeepSeek, etc.) to find the closest match.
 +23
nanochat
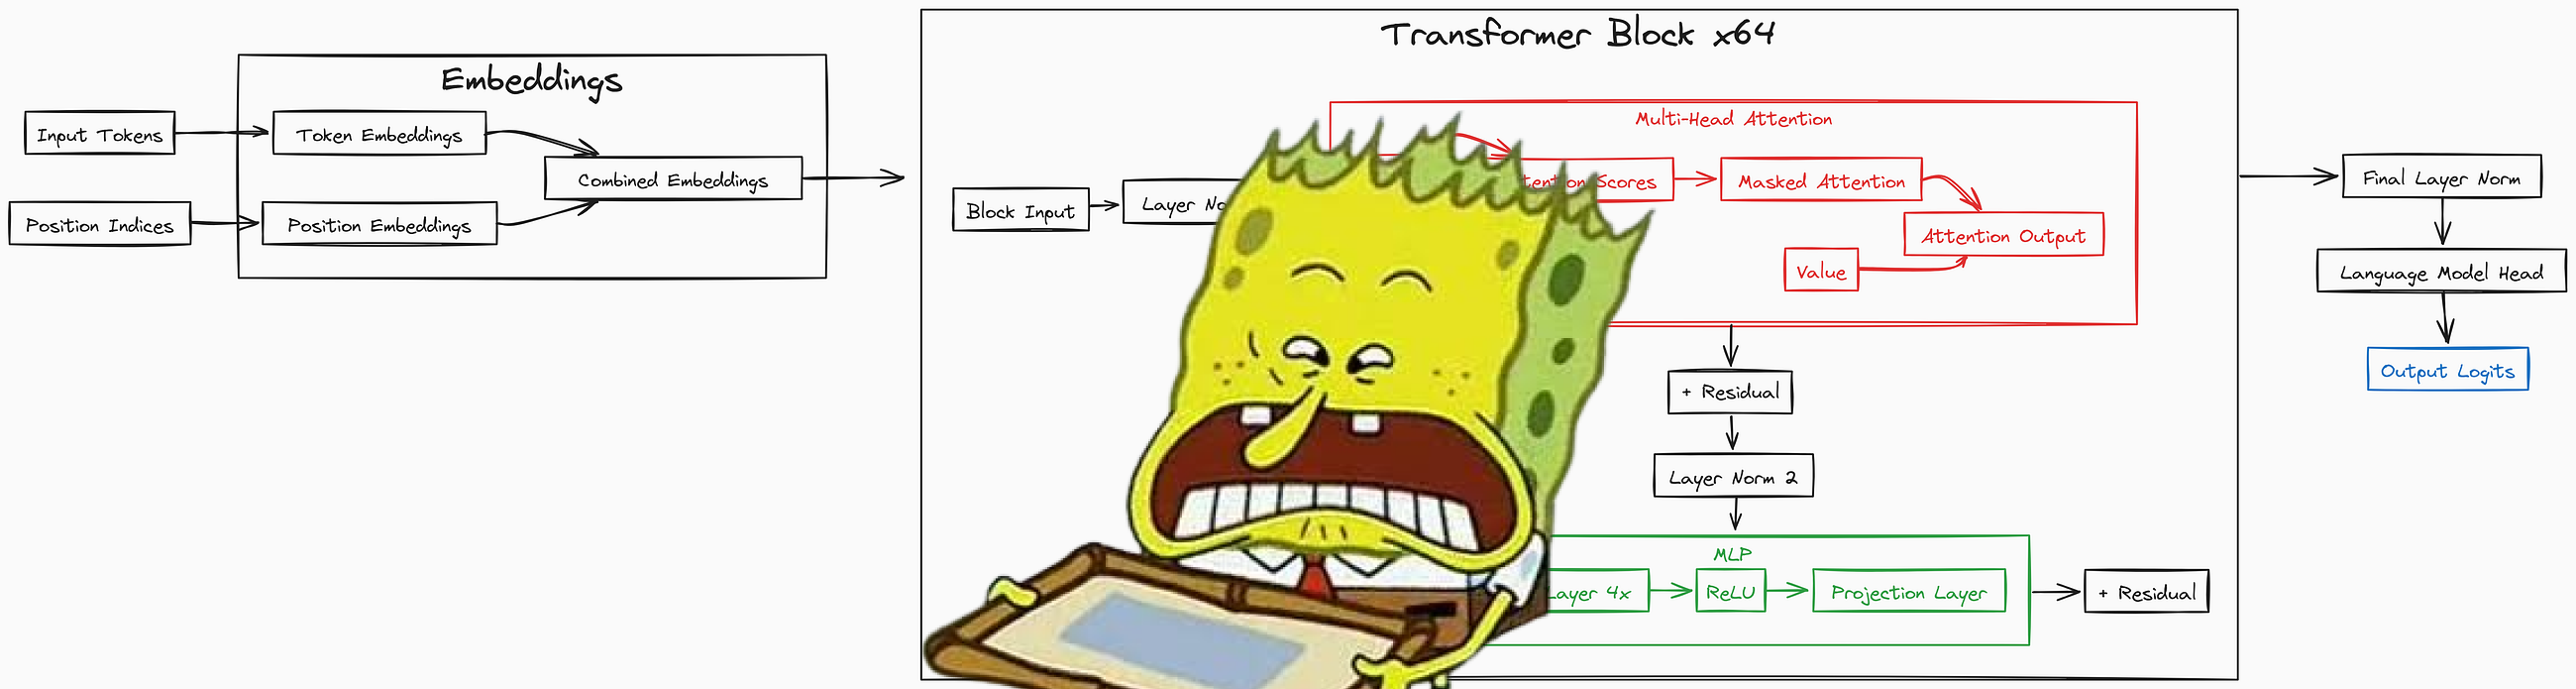
karpathy/nanochat · ★ 58.7KA minimal, hackable harness for training your own LLM end to end (tokenization, pretraining, finetuning, evaluation, inference) on a single GPU node, ending in a chatbot you talk to over a CLI.
 +10
tiktoken
openai/tiktoken · ★ 19.5Ktiktoken is a fast byte pair encoding (BPE) tokenizer built for use with OpenAI's models, converting text into tokens and back again.
 +6
train-llm-from-scratch
FareedKhan-dev/train-llm-from-scratch · ★ 12.2KA from-scratch tutorial and codebase for training your own LLM end to end: tokenizing raw text, pretraining a GPT-style Transformer, and then post-training it with SFT, a reward model, DPO/ORPO/KTO, PPO and GRPO into an aligned, reasoning-style assistant.
The all-time top
20 projects · by stars
- 58.7K#1 · karpathy/nanochat
nanochat
A minimal, hackable harness for training your own LLM end to end (tokenization, pretraining, finetuning, evaluation, inference) on a single GPU node, ending in a chatbot you talk to over a CLI.
- 37.5K
 #2 · karpathy/LLM101n
LLM101n
LLM101n is a planned course by Andrej Karpathy that walks through building a 'Storyteller' AI language model end-to-end, from basics all the way to a ChatGPT-like web app, implemented from scratch in Python, C and CUDA.
- 36.5K
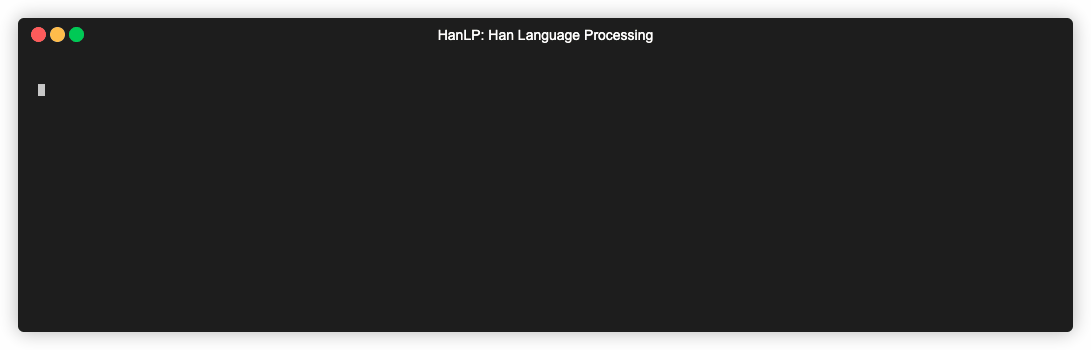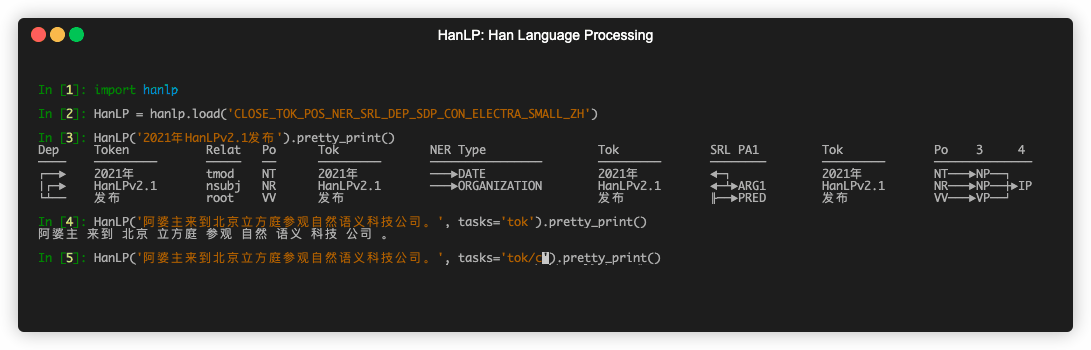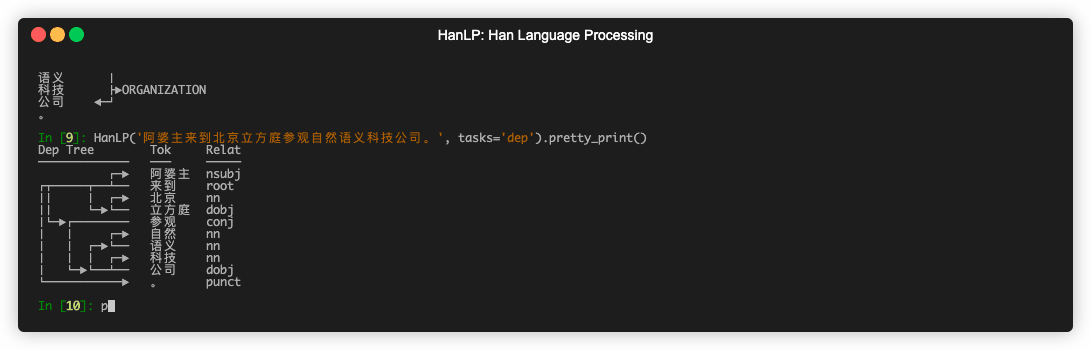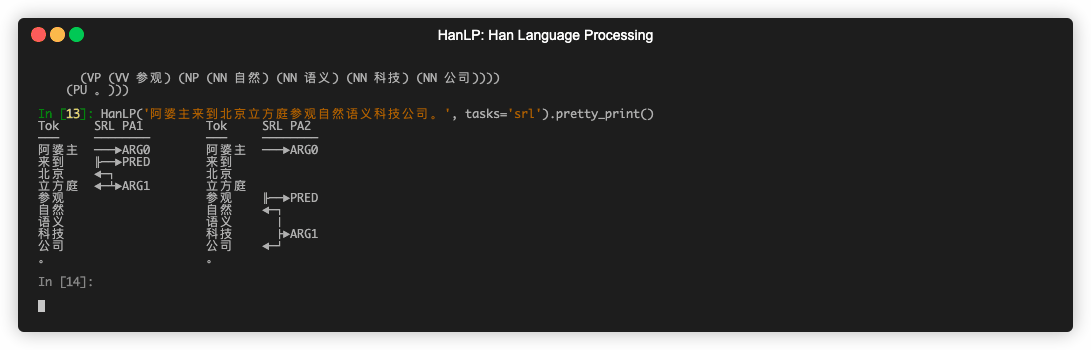 #3 · hankcs/HanLP
HanLP
HanLP is a production-oriented, multilingual NLP toolkit built on dual PyTorch/TensorFlow 2.x engines, supporting 130 languages with ten joint tasks such as tokenization, POS tagging, NER, dependency and constituency parsing, semantic role labeling, and text classification.
- 4

jieba
35.2Kfxsjy/jieba · PythonJieba is a popular open-source Python library for Chinese word segmentation: it cuts Chinese text into words, supporting Simplified and Traditional Chinese. 'Jieba' means 'to stutter' in Chinese.
- 5

spaCy
34Kexplosion/spaCy · PythonspaCy is a library for advanced Natural Language Processing in Python and Cython, designed from day one for real products. It ships pretrained pipelines and supports tokenization and training for 70+ languages.
- 6

toon
25.5Ktoon-format/toon · TypeScriptTOON (Token-Oriented Object Notation) is a compact, human-readable way to serialize JSON data so it spends fewer tokens in LLM prompts. The repo ships a TypeScript SDK, a CLI, and benchmarks.
- 7
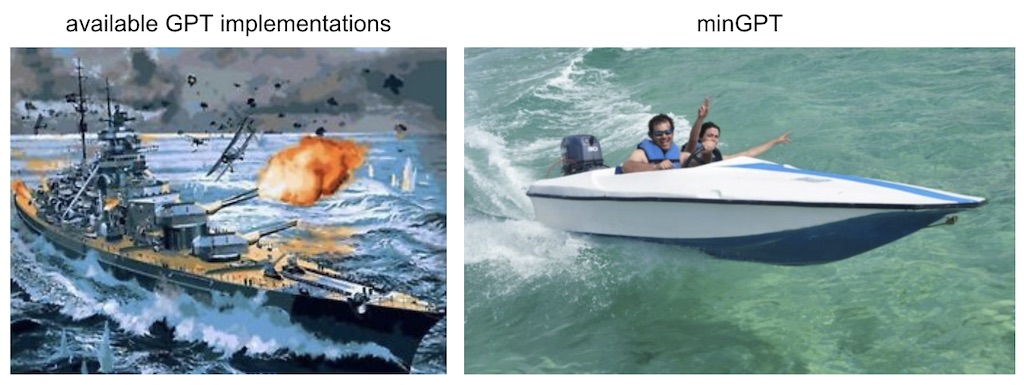
minGPT
25Kkarpathy/minGPT · PythonminGPT is a minimal PyTorch re-implementation of OpenAI's GPT, covering both training and inference, written to be small and easy to read rather than production-optimized.
- 8
tiktoken
19.5Kopenai/tiktoken · Pythontiktoken is a fast byte pair encoding (BPE) tokenizer built for use with OpenAI's models, converting text into tokens and back again.
- 9

llama3-from-scratch
15.2Knaklecha/llama3-from-scratch · Jupyter NotebookA Jupyter notebook that implements Llama3 entirely from scratch, building up every matrix multiplication by hand instead of calling pre-built transformer modules.
- 10

nltk
14.7Knltk/nltk · PythonNLTK is a suite of open source Python modules, bundled data sets, and tutorials supporting research and development in Natural Language Processing.
- 11

Chinese-Word-Vectors
12.2KEmbedding/Chinese-Word-Vectors · PythonA collection of 100+ pre-trained Chinese word vectors (embeddings) trained with different representations, context features and corpora, plus the CA8 analogy dataset and an evaluation toolkit.
- 12
train-llm-from-scratch
12.2KFareedKhan-dev/train-llm-from-scratch · PythonA from-scratch tutorial and codebase for training your own LLM end to end: tokenizing raw text, pretraining a GPT-style Transformer, and then post-training it with SFT, a reward model, DPO/ORPO/KTO, PPO and GRPO into an aligned, reasoning-style assistant.
- 13
sentencepiece
12.1Kgoogle/sentencepiece · C++SentencePiece is a fast, lightweight, unsupervised text tokenizer and detokenizer built for neural-network text generation systems like LLMs, where vocabulary size is fixed before training. It implements BPE and the unigram language model as subword units and trains directly from raw sentences.
- 14
natural
10.9KNaturalNode/natural · JavaScriptNatural is a general-purpose natural language processing library for Node.js that bundles tokenizers, stemmers, classifiers and other NLP utilities into one package.
- 15

minbpe
10.8Kkarpathy/minbpe · Pythonminbpe is a minimal, clean implementation of the Byte Pair Encoding (BPE) algorithm that modern LLMs like GPT, Llama and Mistral use to train their tokenizers.
- 16

gigatoken
4.1Kmarcelroed/gigatoken · RustGigatoken is an extremely fast tokenizer for language models, built as a near drop-in replacement for HuggingFace Tokenizers and tiktoken, encoding text at multi-GB/s speeds.
- 17
lm-detector
488Ikaleio/lm-detector · TypeScriptLM Fingerpoint Detector figures out which large language model is really answering behind an API by asking it to write about 300 random integers between 1 and 355, then comparing the statistical pattern of those numbers against a reference bank of known models (GPT, Claude, Gemini, Grok, Qwen, DeepSeek, etc.) to find the closest match.
- 18
manaca-1b-base
249Instituto-IA-LNCC/manaca-1b-base · PythonAn open ~1.72B-parameter language model trained from scratch for Brazilian Portuguese. The repo holds the whole reproducible pipeline: Docker environment, corpus pipeline, tokenizer training, Megatron-LM pretraining, and a Portuguese benchmark suite.
- 19

twinkleplop
238pngwn/twinkleplop · TypeScriptTwinkleplop is a small, fast syntax highlighter and code authoring toolkit for the web: you install just the languages you need, generate HTML or tokens from your code, and style the output with CSS.
- 20

qxotic
175qxoticai/qxotic · JavaQxotic is an open-source AI stack built specifically for the JVM, giving Java applications local AI inference — chat, vision, audio, embeddings, reranking and text-to-speech — without needing Python or ONNX.
Related topics
Often tagged together
- open-source5,666
- machine-learning915
- python2,396
- llm1,483
- mit3,311
- nlp214
- library1,587
- deep-learning736
- research764
- ai1,954
- developer-tools2,927
- large-language-models212
- artificial-intelligence267
- linux4,181
- pytorch419
- benchmark430
- cli2,227
- education933
- gpu788
- macos3,544
- natural-language-processing96
- neural-network166
- text-processing40
- transformer212