Topics / #grpo
Grpo projects on GitHub
Group Relative Policy Optimization, a reinforcement learning method for tuning large language models.
As of , the most-starred Grpo projects on GitHub are unsloth (78.2K stars), minimind (63.9K stars) and happy-llm (34.4K stars). GitHub.Locker tracks 16 Grpo repositories with 304.7K stars combined. The fastest-growing on October 17 was unsloth, with +67 stars in a day.
Hot right now
Most stars gained in a day · Oct 17
 +67
unsloth
unslothai/unsloth · ★ 78.2KUnsloth is a local-first app for running and training LLMs, diffusion, TTS and embedding models on your own machine, including models like Qwen3.8, DeepSeek-V4, MiniMax-H3, Gemma 4 and FLUX.
 +45
minimind
jingyaogong/minimind · ★ 63.9KMiniMind is an open-source project that lets you train a tiny large language model (around 64M parameters) completely from scratch, in about 2 hours on a single RTX 3090 for roughly the cost of 3 RMB in GPU rental.
 +25
AI-Research-SKILLs
Orchestra-Research/AI-Research-SKILLs · ★ 13.6KIt's an open-source library of 98 AI research and engineering skills that turn a Claude Code, Codex, or Gemini CLI agent into a full AI research agent, covering everything from idea generation to paper writing.
 +22
AgentGuide
adongwanai/AgentGuide · ★ 11KAgentGuide is a free, open-source Chinese-language knowledge base for AI Agent engineering and job hunting, modeled on JavaGuide. It stitches scattered courses, tutorials, papers and projects into one systematic path from beginner to a job offer.
The all-time top
16 projects · by stars
- 78.2K#1 · unslothai/unsloth
unsloth
Unsloth is a local-first app for running and training LLMs, diffusion, TTS and embedding models on your own machine, including models like Qwen3.8, DeepSeek-V4, MiniMax-H3, Gemma 4 and FLUX.
- 63.9K#2 · jingyaogong/minimind
minimind
MiniMind is an open-source project that lets you train a tiny large language model (around 64M parameters) completely from scratch, in about 2 hours on a single RTX 3090 for roughly the cost of 3 RMB in GPU rental.
- 34.4K
 #3 · datawhalechina/happy-llm
happy-llm
Happy-LLM is Datawhale's free open-source LLM course: a systematic tutorial that goes from NLP basics and the Transformer architecture to building and training your first large language model, then applying it with RAG and agents.
- 4
verl
23.9Kverl-project/verl · Pythonverl is a flexible, efficient and production-ready reinforcement learning training library for LLMs, initiated by ByteDance's Seed team and maintained by the community. It is the open-source version of the HybridFlow paper (EuroSys 2025).
- 5

trl
19.5Khuggingface/trl · PythonTRL (Transformers Reinforcement Learning) is a Hugging Face library for post-training foundation models — fine-tuning them with techniques like SFT, GRPO and DPO on top of the Transformers stack.
- 6
ms-swift
15.9Kmodelscope/ms-swift · Pythonms-swift is the ModelScope community's fine-tuning and deployment framework for LLMs and multimodal models, covering training, inference, evaluation, quantization and deployment in one pipeline.
- 7
AI-Research-SKILLs
13.6KOrchestra-Research/AI-Research-SKILLs · TeXIt's an open-source library of 98 AI research and engineering skills that turn a Claude Code, Codex, or Gemini CLI agent into a full AI research agent, covering everything from idea generation to paper writing.
- 8
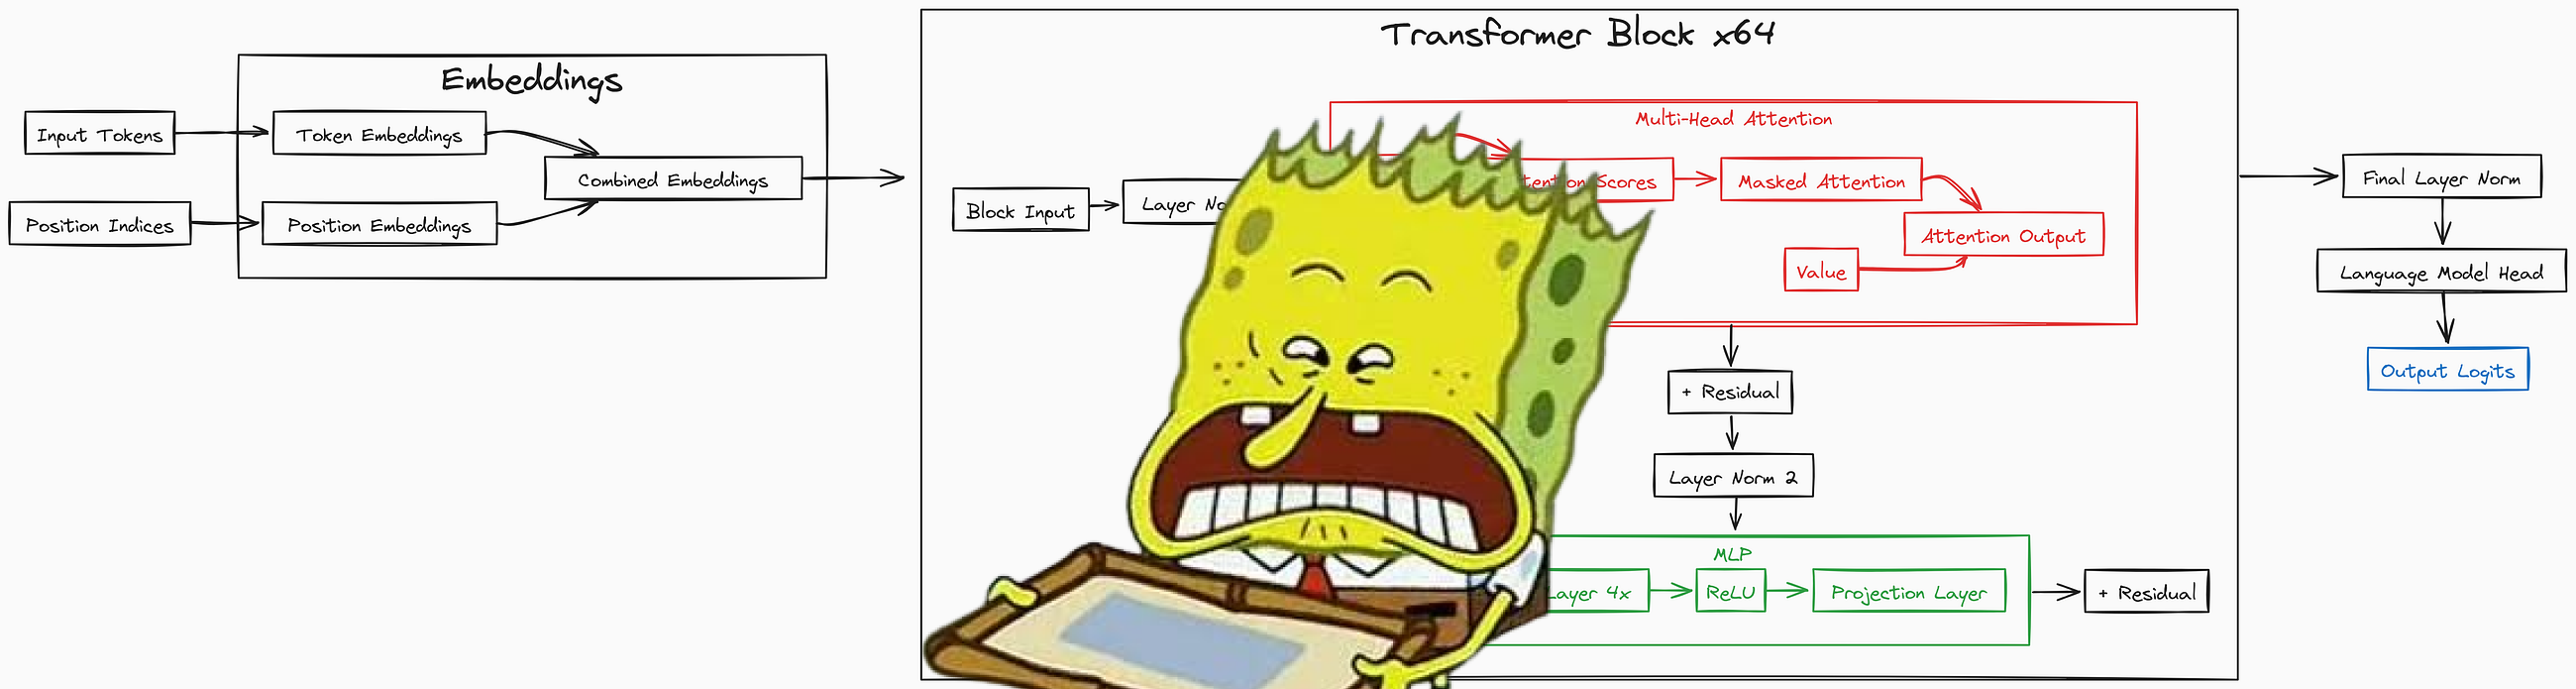
train-llm-from-scratch
12.2KFareedKhan-dev/train-llm-from-scratch · PythonA from-scratch tutorial and codebase for training your own LLM end to end: tokenizing raw text, pretraining a GPT-style Transformer, and then post-training it with SFT, a reward model, DPO/ORPO/KTO, PPO and GRPO into an aligned, reasoning-style assistant.
- 9
AgentGuide
11Kadongwanai/AgentGuide · MDXAgentGuide is a free, open-source Chinese-language knowledge base for AI Agent engineering and job hunting, modeled on JavaGuide. It stitches scattered courses, tutorials, papers and projects into one systematic path from beginner to a job offer.
- 10
ART
10.8KOpenPipe/ART · PythonART (Agent Reinforcement Trainer) is an open-source RL framework from OpenPipe that lets LLM agents learn from experience: you train multi-step agents for real-world tasks with GRPO.
- 11

LongCat-Video
9.2Kmeituan-longcat/LongCat-Video · PythonLongCat-Video is a 13.6B-parameter foundational video generation model that unifies Text-to-Video, Image-to-Video, and Video-Continuation generation in a single architecture, aimed at efficient long-video generation and framed as a first step toward world models.
- 12
OpenClaw-RL
5.7KGen-Verse/OpenClaw-RL · PythonOpenClaw-RL is a fully asynchronous reinforcement learning framework that turns everyday conversations with an agent into training signals, letting you train a personalized OpenClaw agent just by talking to it, or train general agents for terminal, GUI, SWE, and tool-call tasks.
- 13
hands-on-modern-rl
4.7Kwalkinglabs/hands-on-modern-rl · PythonHands-On Modern RL is an open-source course and book that walks learners from basic reinforcement learning concepts through LLM alignment (RLHF, DPO, GRPO, RLVR) and into advanced agentic systems, combining theory with runnable code.
- 14
halo
825whitecircle/halo · PythonHalo is an open-source framework from White Circle for training large language and multimodal models: pre-training, SFT, preference optimization, and fully asynchronous multi-turn RL in one codebase, from a single GPU up to multi-node clusters.
- 15
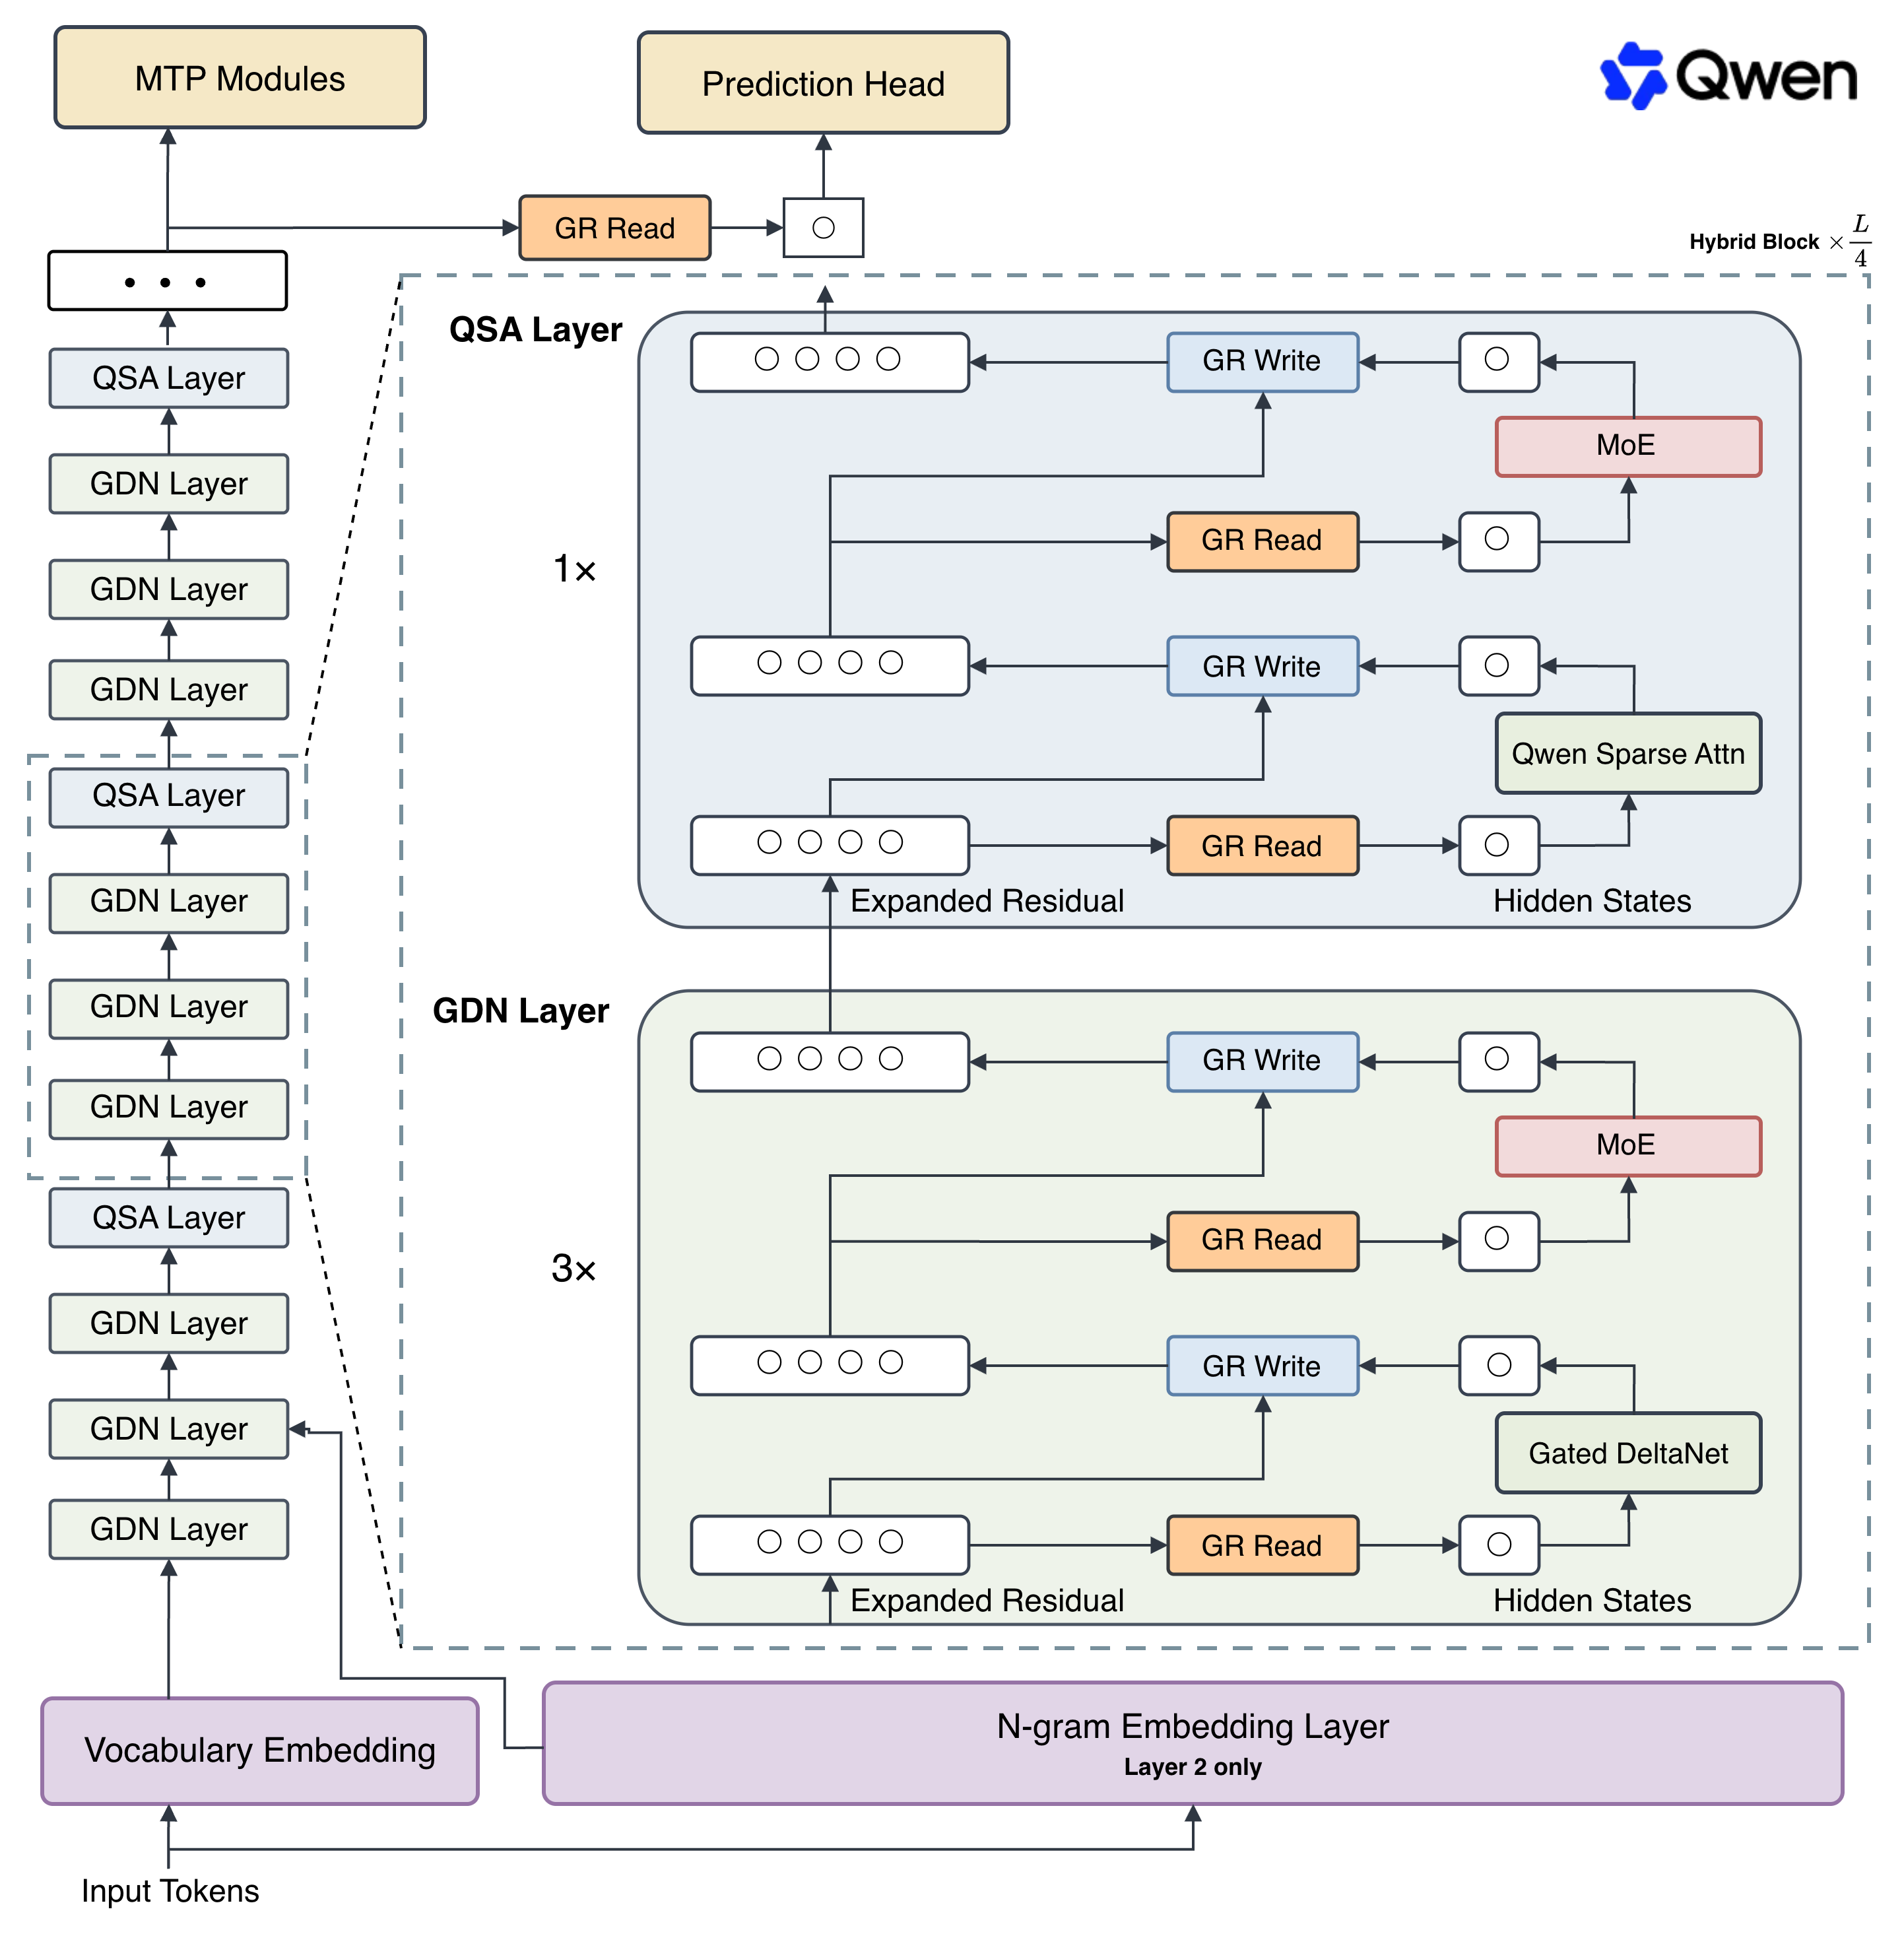
Qwen3.8-Flash-Next
433QwenLM/Qwen3.8-Flash-NextQwen3.8-Flash-Next is an open-weight multimodal Mixture-of-Experts foundation model from Alibaba's Qwen Team, also serving as an early preview of the architecture Alibaba plans to use for the upcoming Qwen4 model family.
- 16
Meshy
407OpenBMB/Meshy · PythonMeshy is an open-source framework for running reinforcement learning (RL) training jobs where every role (inference, training, rollout) runs as an independent service, communicating through a shared TransferQueue data plane. It is built on SGLang and torchtitan.
Related topics
Often tagged together