Topics / #amd
Amd projects on GitHub
AMD hardware tooling and driver support, plus possible module format usage.
As of , the most-starred Amd projects on GitHub are stable-diffusion-webui (165.1K stars), ComfyUI (138.6K stars) and llama.cpp (131.7K stars). GitHub.Locker tracks 53 Amd repositories with 1.3M stars combined. The fastest-growing on October 18 was ComfyUI, with +835 stars in a day.
Hot right now
Most stars gained in a day · Oct 18
ComfyUI
Comfy-Org/ComfyUI · ★ 138.6KComfyUI is a node-based graph interface for building and running diffusion model workflows: image, video, 3D, and audio generation, editing, and more, all without writing code.
 +183
KytyPS5
KytyPS5/KytyPS5 · ★ 9.1KKytyPS5 is a free and open-source PlayStation 5 emulator (translation layer) written in C++ for Windows and Linux, with experimental macOS support, based on a heavily modified version of the Kyty project.
 +167
uncharted_pc
Supermedo/uncharted_pc · ★ 1.4KThis is a native Windows port of 'Uncharted: The Nathan Drake Collection', letting the original PS4 game code for Uncharted 1, 2 and 3 run directly on PC with the graphics translated to Vulkan.
 +148
DLSS-NR-on-AMD
danielblnc/DLSS-NR-on-AMD · ★ 2.7KThis is a mod that lets you run DLSS 5 Neural Rendering on AMD Radeon GPUs (RX 7000/9000 series) in any DirectX 12 game that supports FSR, by reimplementing the DLSS neural network runtime for AMD hardware from scratch.
The all-time top
53 projects · by stars
- 165.1K
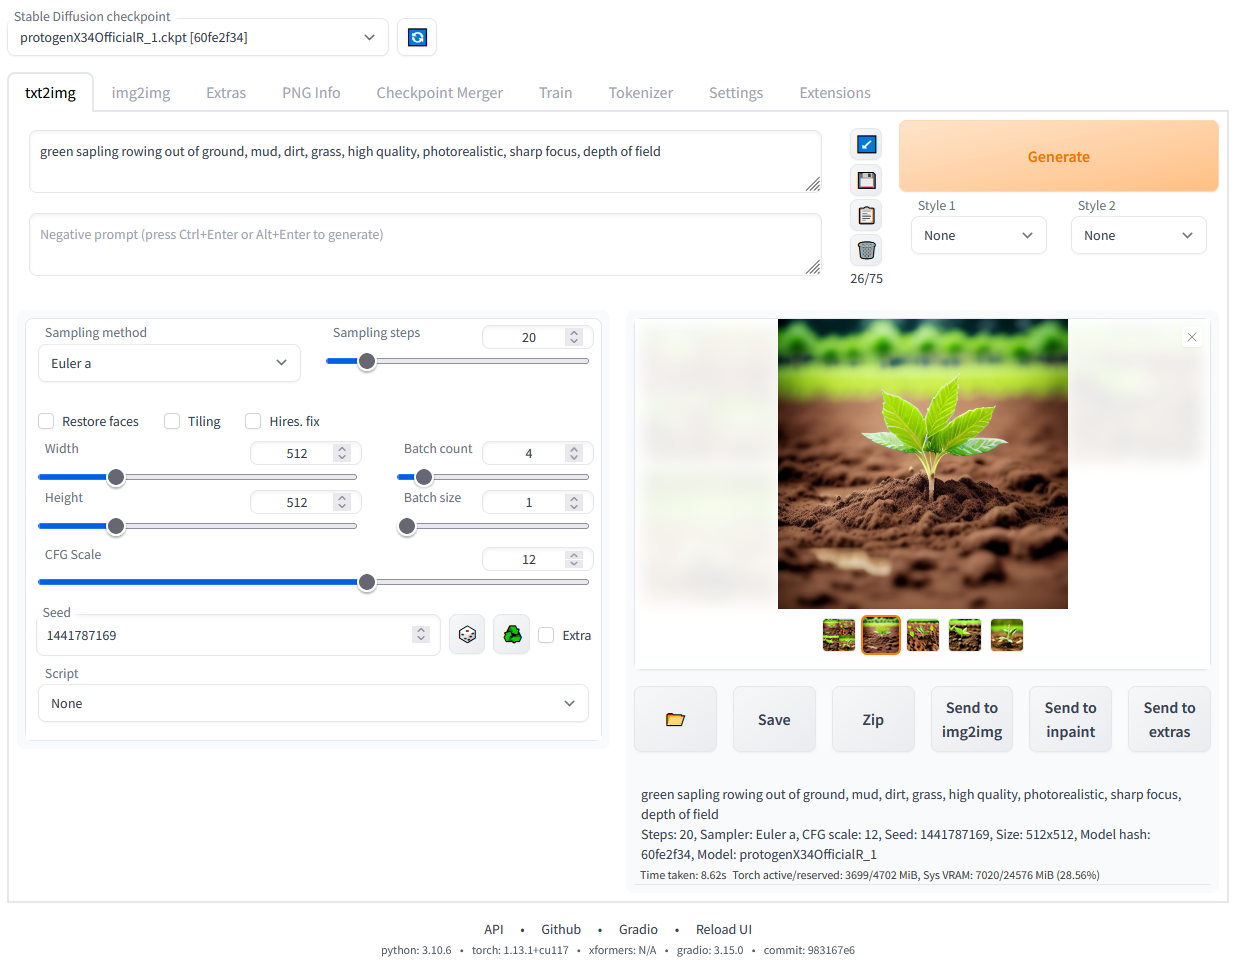 #1 · AUTOMATIC1111/stable-diffusion-webui
stable-diffusion-webui
A browser-based interface for Stable Diffusion, built with the Gradio library, letting you generate and edit AI images (txt2img, img2img, inpainting, outpainting and more) on your own machine.
- 138.6K
#2 · Comfy-Org/ComfyUI
ComfyUI
ComfyUI is a node-based graph interface for building and running diffusion model workflows: image, video, 3D, and audio generation, editing, and more, all without writing code.
- 131.7K
 #3 · ggml-org/llama.cpp
llama.cpp
llama.cpp is a plain C/C++ implementation for running LLM (and VLM) inference with minimal setup and state-of-the-art performance, either locally or in the cloud.
- 4
vllm
94.1Kvllm-project/vllm · PythonvLLM is a library for fast LLM inference and serving, built around PagedAttention for efficient memory management of attention keys and values.
- 5
unsloth
78.2Kunslothai/unsloth · PythonUnsloth is a local-first app for running and training LLMs, diffusion, TTS and embedding models on your own machine, including models like Qwen3.8, DeepSeek-V4, MiniMax-H3, Gemma 4 and FLUX.
- 6

webpack
66Kwebpack/webpack · JavaScriptWebpack is a module bundler for JavaScript and friends: it packs many modules (JS, CSS, images, JSON, and more) into a few bundled assets for use in the browser.
- 7

lodash
61.3Klodash/lodash · JavaScriptLodash is a modern JavaScript utility library - small helper functions that take the hassle out of working with arrays, numbers, objects, and strings.
- 8

jquery
59.9Kjquery/jquery · JavaScriptjQuery is the classic JavaScript library for DOM manipulation, events, AJAX and effects — this repo holds its source, fresh off the jQuery 4.0.0 release.
- 9
DeepSpeed
43.2Kdeepspeedai/DeepSpeed · PythonDeepSpeed is a deep learning optimization library that makes distributed training and inference of very large models easy, efficient and effective — it powered models like MT-530B and BLOOM.
- 10
Retrieval-based-Voice-Conversion-WebUI
38.8KRVC-Project/Retrieval-based-Voice-Conversion-WebUI · PythonRVC WebUI is a web-based tool for training and running voice conversion (voice-changing) models, letting you clone a target voice's timbre using as little as about 10 minutes of audio.
- 11
jax
36.5Kjax-ml/jax · PythonJAX is a Python library for accelerator-oriented array computation and program transformation, built for high-performance numerical computing and large-scale machine learning.
- 12
btop
35Karistocratos/btop · C++A terminal resource monitor that shows usage and stats for processor, memory, disks, network and processes. It is the C++ version and continuation of bashtop and bpytop.
- 13
DeepFaceLive
31Kiperov/DeepFaceLive · PythonDeepFaceLive is a Windows desktop app for real-time face swap: it replaces the face from your webcam — or the face in a video — with a trained face model, aimed at PC streaming and video calls.
- 14
apollo
26.9KApolloAuto/apollo · C++An open autonomous driving platform from Baidu: a high-performance, flexible software stack covering perception, prediction, planning and control, for developing, testing and deploying self-driving vehicles.
- 15
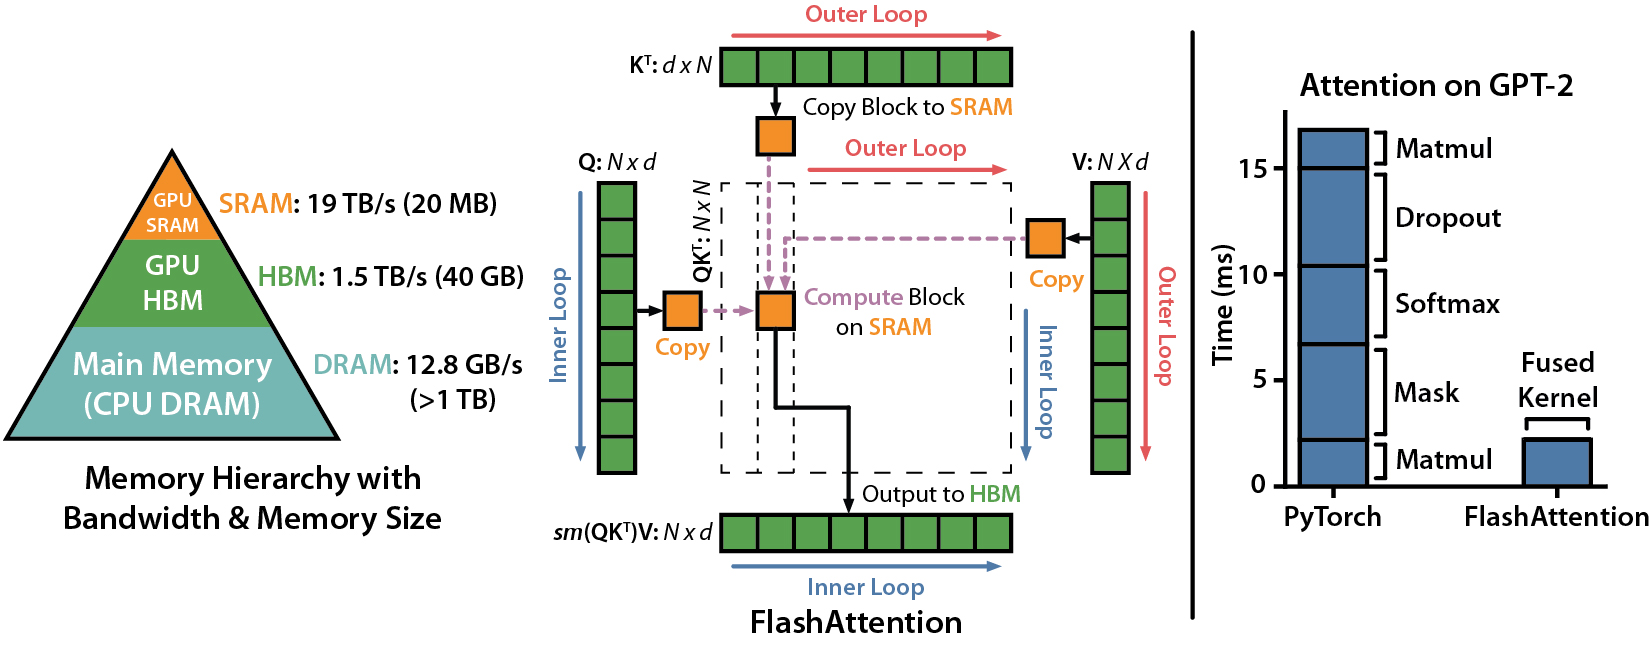
flash-attention
25.2KDao-AILab/flash-attention · PythonThe official implementation of FlashAttention and FlashAttention-2 — GPU kernels that compute exact attention faster and with less memory than standard PyTorch attention.
- 16
verl
23.9Kverl-project/verl · Pythonverl is a flexible, efficient and production-ready reinforcement learning training library for LLMs, initiated by ByteDance's Seed team and maintained by the community. It is the open-source version of the HybridFlow paper (EuroSys 2025).
- 17

FanControl.Releases
21.1KRem0o/FanControl.ReleasesFan Control is a highly customizable fan-controlling app for Windows: it drives your PC's CPU, GPU and case fans from temperature-based curves you design in a GUI.
- 18
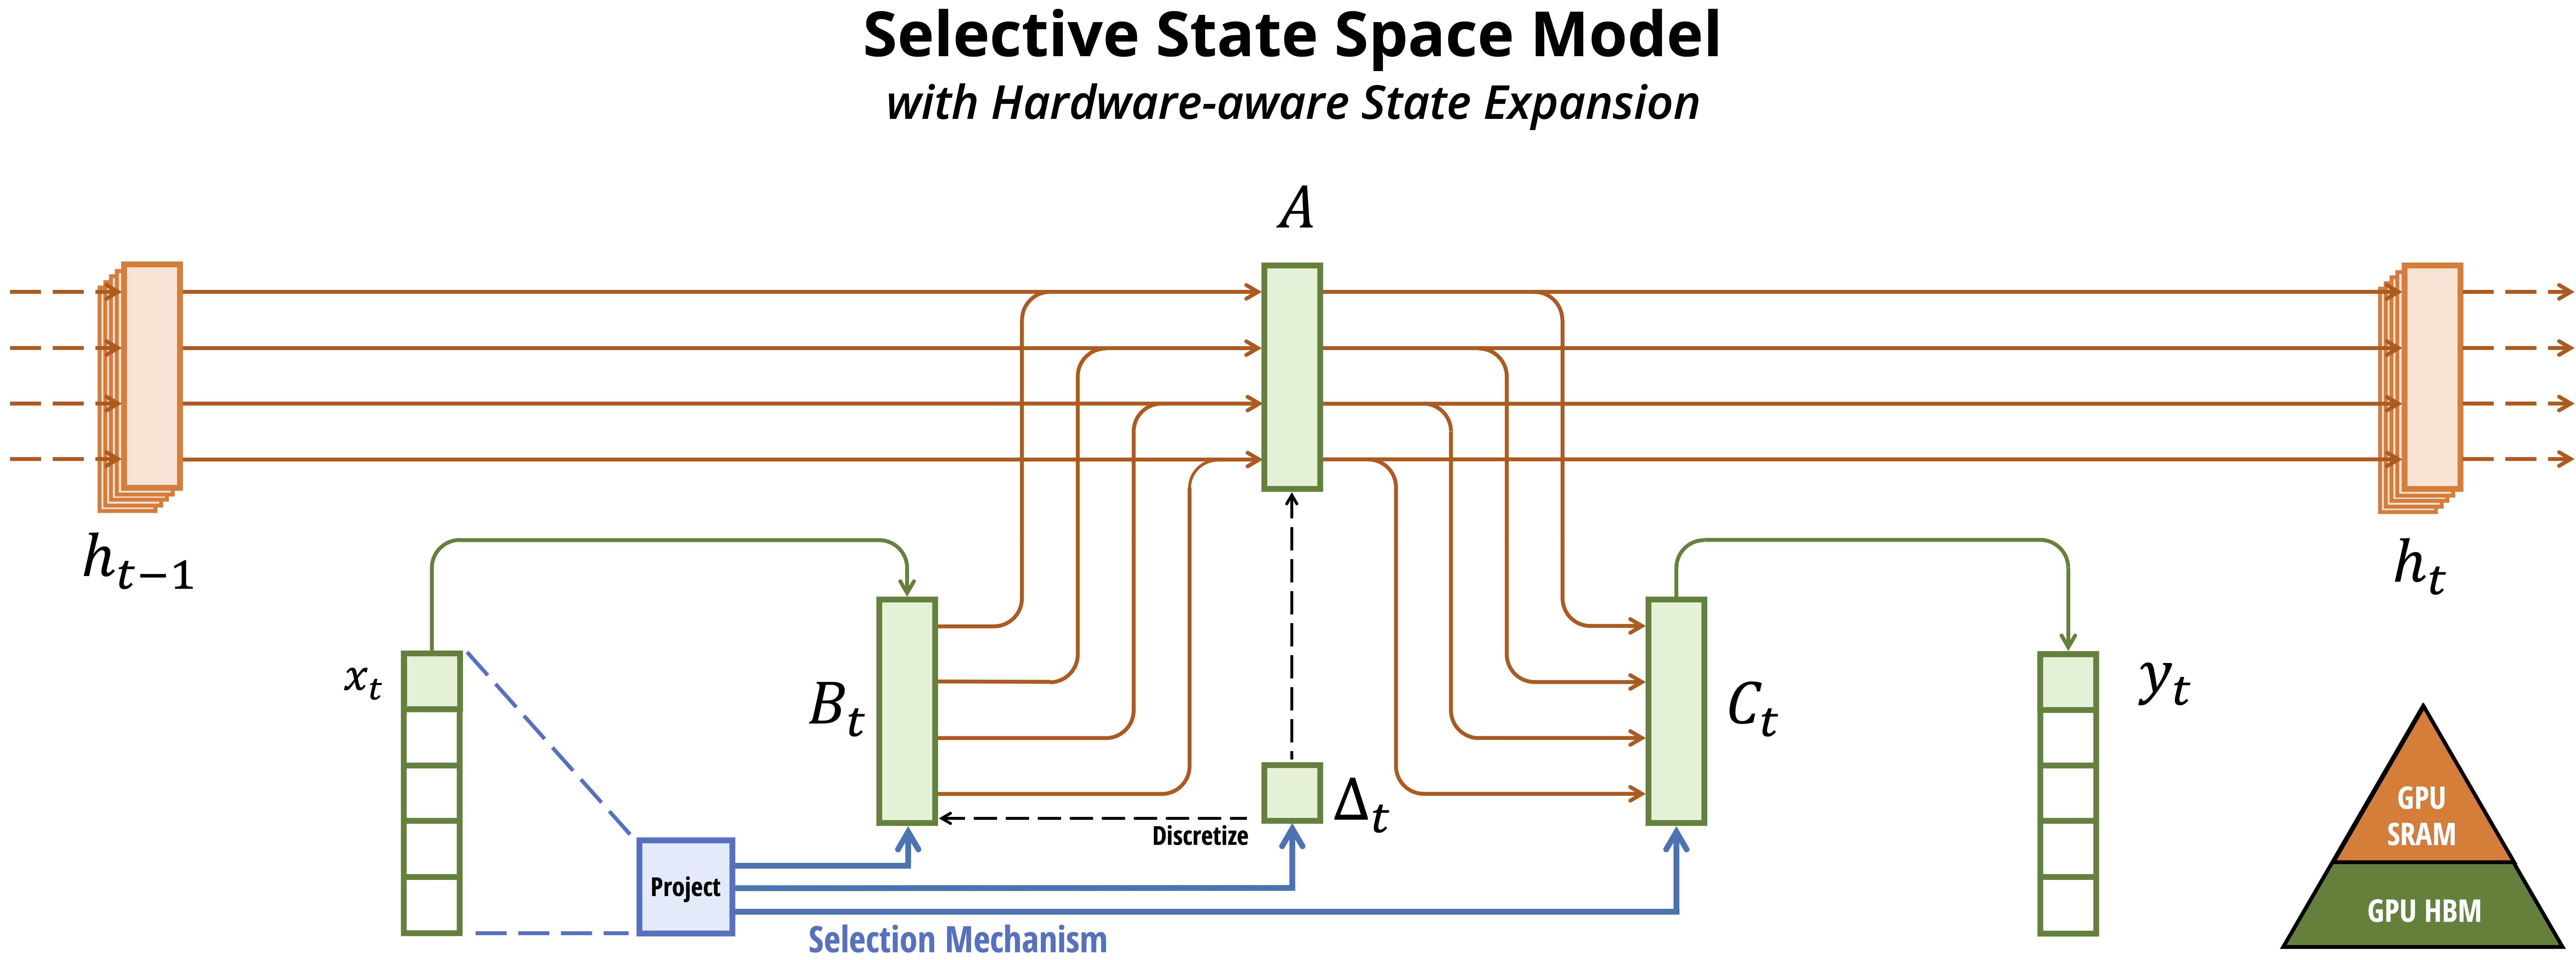
mamba
18.9Kstate-spaces/mamba · PythonMamba is a state space model architecture for sequence modeling with linear-time scaling. It shows promising performance on information-dense data like language modeling, where earlier subquadratic models fell short of Transformers; this repo is its PyTorch implementation.
- 19
Waifu2x-Extension-GUI
17.1KAaronFeng753/Waifu2x-Extension-GUI · C++Waifu2x-Extension-GUI is a Windows desktop app that upscales (super-resolution) images, GIFs, and videos, and can also interpolate video frames, using a collection of AI engines like Waifu2x, Real-ESRGAN, Real-CUGAN, RIFE and DAIN.
- 20
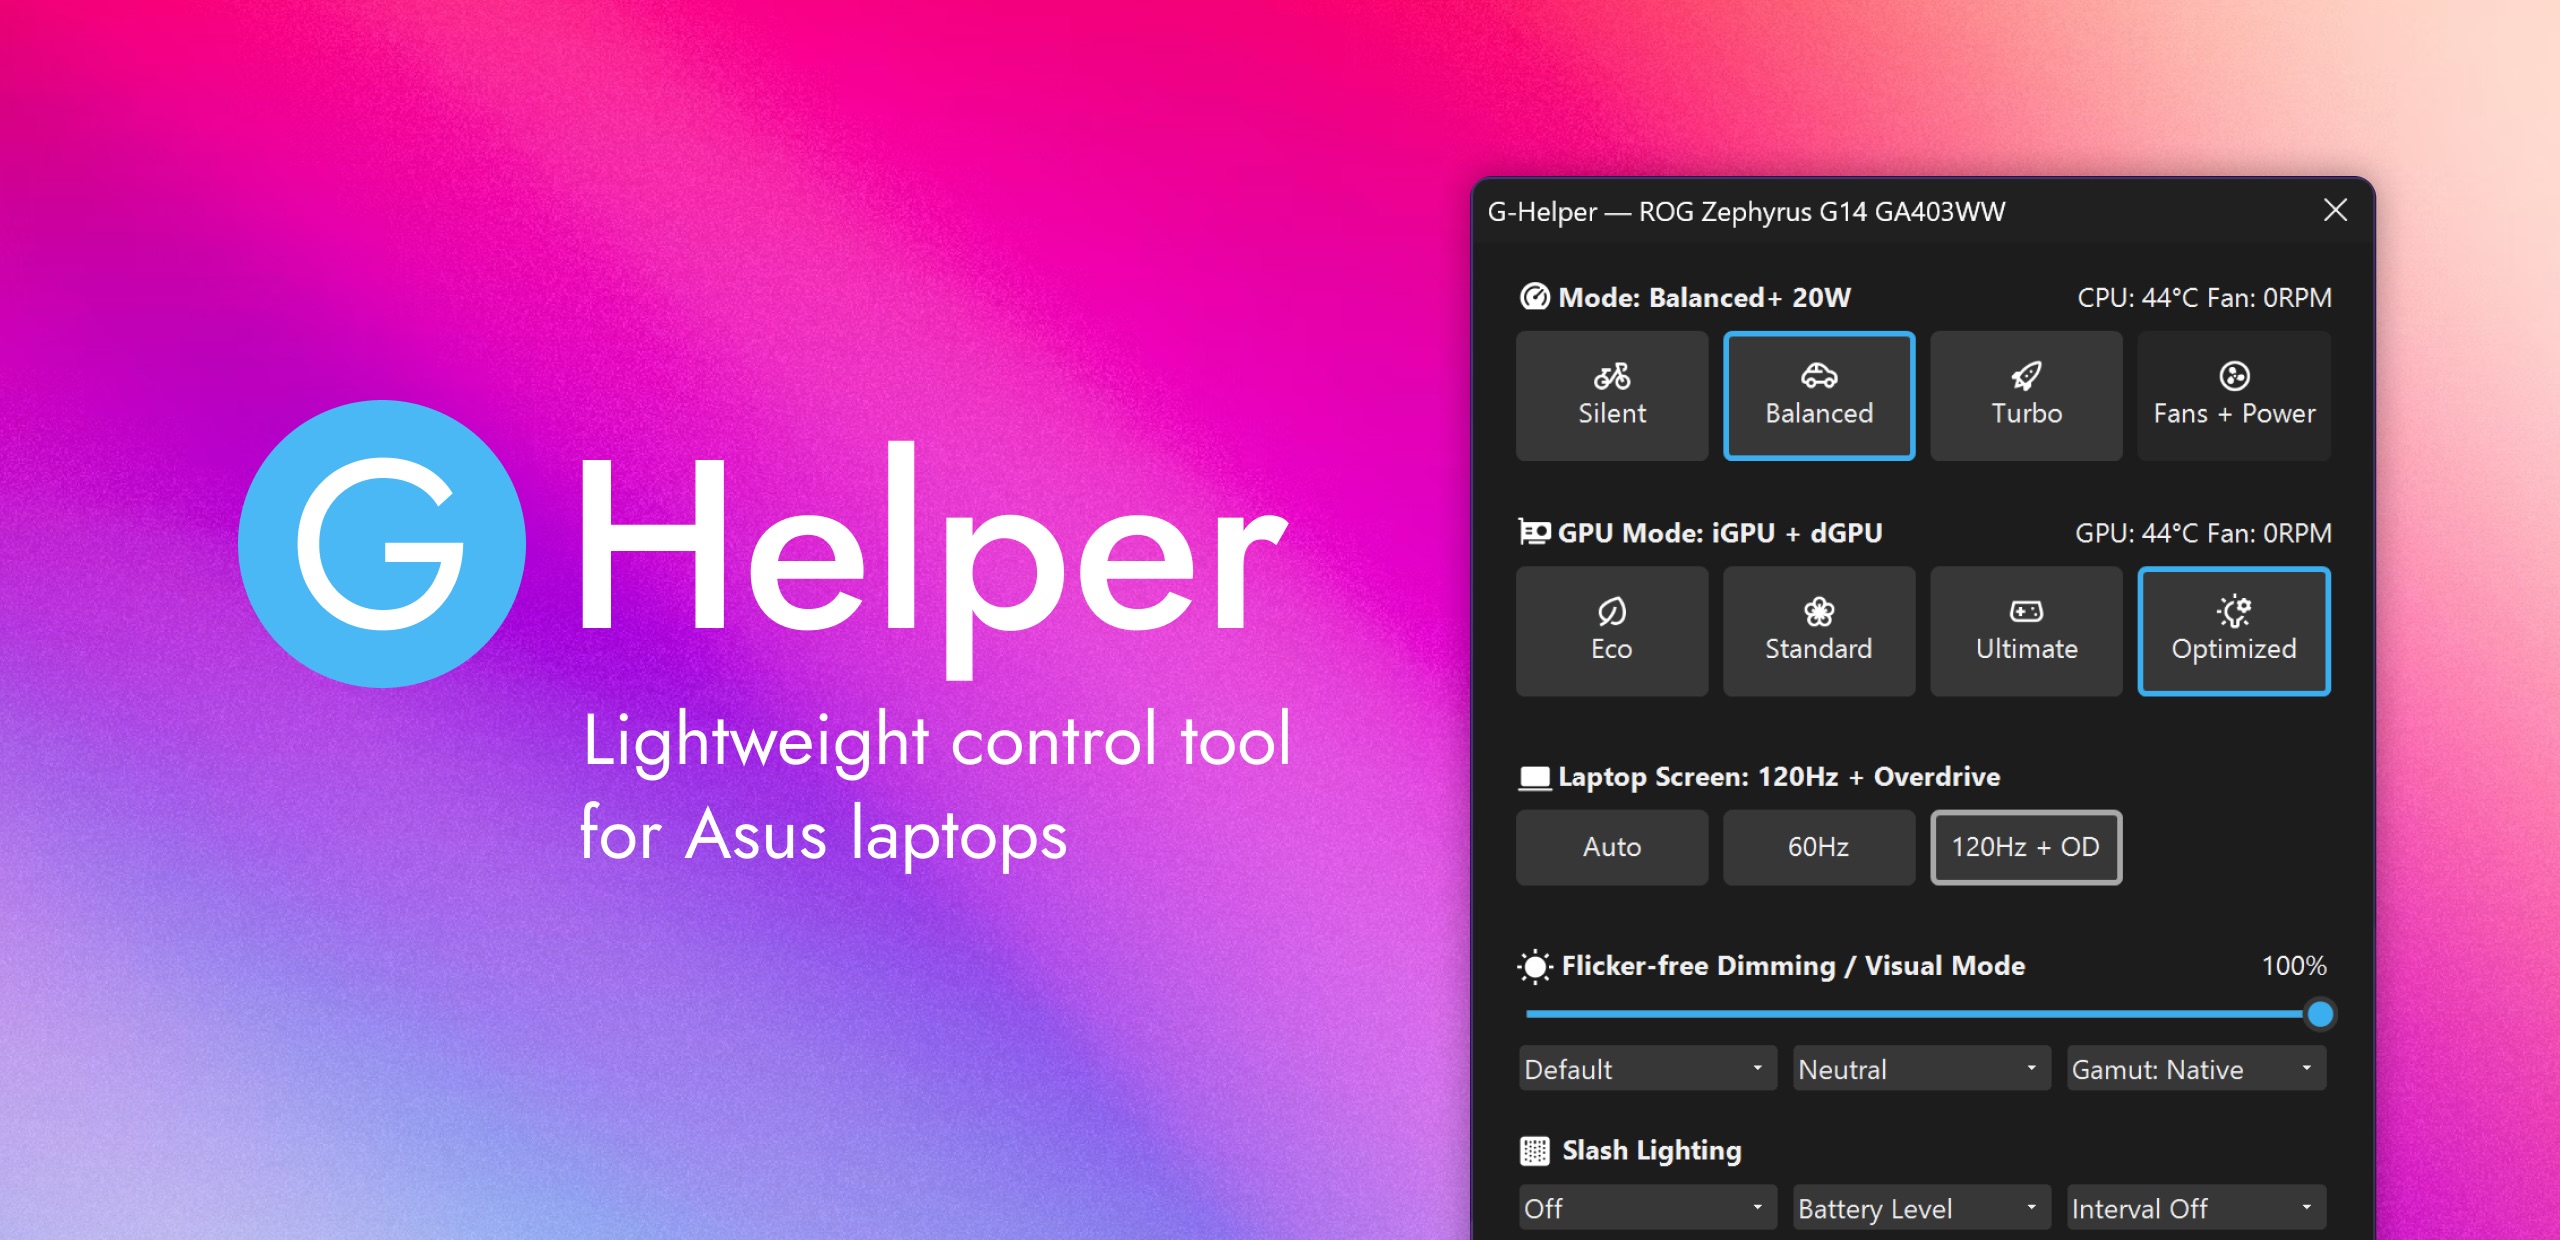
g-helper
15.6Kseerge/g-helper · C#G-Helper is a lightweight, free alternative to Asus Armoury Crate for controlling performance modes, fan curves, GPU switching, lighting and other hardware settings on Asus laptops.
- 21

requirejs
12.9Krequirejs/requirejs · JavaScriptRequireJS is a file and module loader for JavaScript, optimized for use in the browser (including Web Workers) but also usable in environments like Rhino and Node.
- 22

jsoneditor
12.3Kjosdejong/jsoneditor · JavaScriptA web-based tool to view, edit, format, and validate JSON right in the browser, instead of wrangling raw text.
- 23
LMCache
12.1KLMCache/LMCache · PythonLMCache is a KV cache management layer for LLM inference that turns the KV cache from a temporary, per-process state into reusable, persistent 'AI-native knowledge' that can be shared across serving engines, reducing time-to-first-token and boosting throughput for long-context, multi-turn, and RAG workloads.
- 24
OptiScaler
11.9Koptiscaler/OptiScaler · C++OptiScaler is a Windows tool for PC games that lets you replace the upscaler a game uses (DLSS2+, FSR2+ or XeSS) with a different one, and also manage frame generation — including adding it to DX12 games via the experimental OptiFG.
- 25
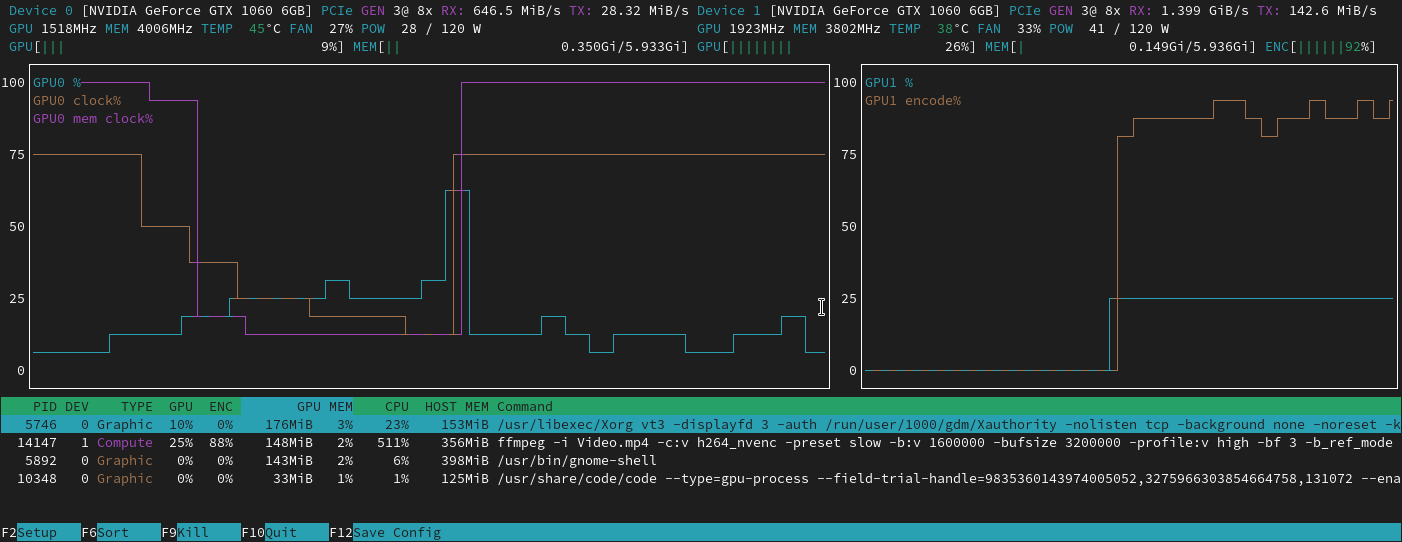
nvtop
11.1KSyllo/nvtop · CNVTOP (Neat Videocard TOP) is a htop-like task monitor for GPUs and accelerators: it runs in the terminal, handles multiple GPUs at once and shows what each device is doing, including which processes are using it.
- 26
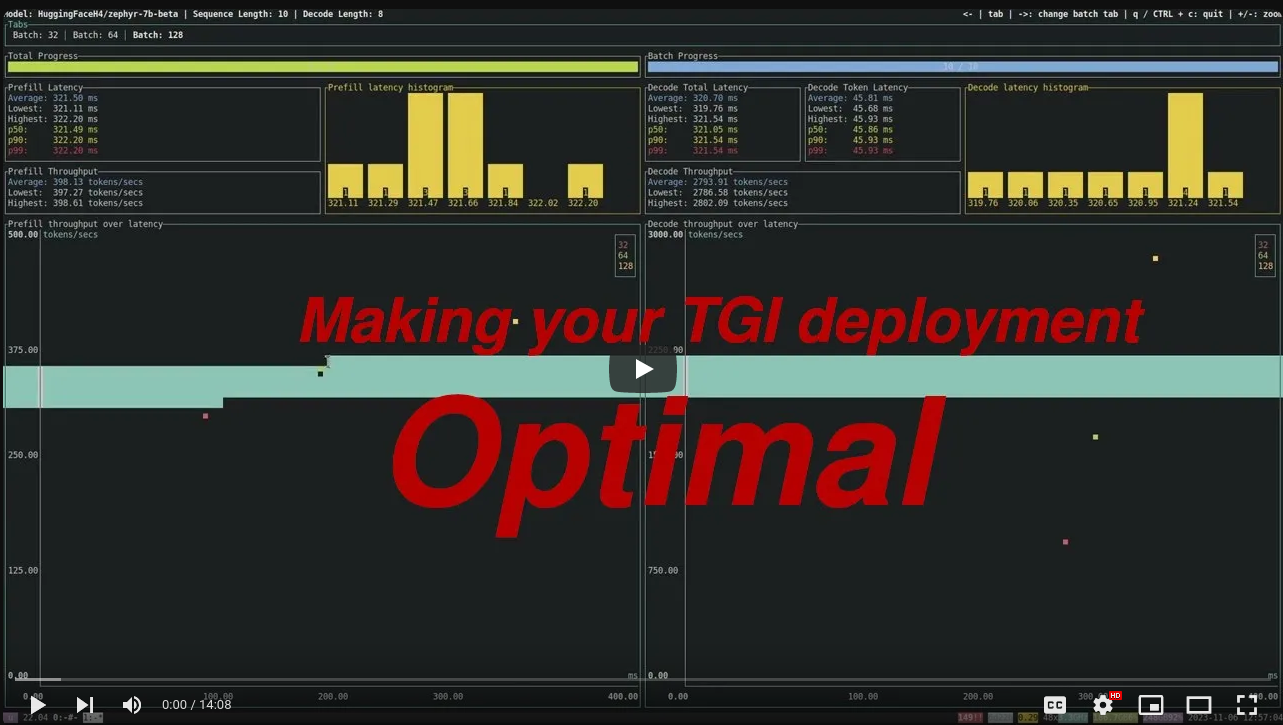
text-generation-inference
10.9Khuggingface/text-generation-inference · PythonText Generation Inference (TGI) is a toolkit for deploying and serving large language models — a Rust, Python and gRPC server that powers Hugging Chat, the Inference API and Inference Endpoints at Hugging Face.
- 27
krita-ai-diffusion
10.7KAcly/krita-ai-diffusion · PythonA free, open-source Krita plugin that brings generative AI into painting and editing workflows: inpaint, outpaint, live-paint and upscale images with an optional text prompt, running on your own hardware.
- 28

petals
10.6Kbigscience-workshop/petals · PythonPetals lets you run big open LLMs at home, BitTorrent-style: you join a public swarm that serves models like Llama 3.1 (405B), Mixtral (8x22B), Falcon (40B+) and BLOOM (176B) for inference and fine-tuning right from your desktop or Google Colab, up to 10x faster than offloading.
- 29
easydiffusion
10.5Keasydiffusion/easydiffusion · JavaScriptEasy Diffusion is a one-click way to run Stable Diffusion on your own PC: type a text prompt into its browser-based UI and get an image — no technical knowledge or pre-installed software needed.
- 30

madge
10.2Kpahen/madge · JavaScriptMadge is a developer tool that creates a visual graph of your module dependencies and finds circular dependencies in JavaScript and CSS preprocessor code.
- 31

xmrig
10.2Kxmrig/xmrig · CXMRig is a high-performance, open-source, cross-platform miner that unifies CPU and GPU mining for RandomX, KawPow, CryptoNight and GhostRider, and doubles as a RandomX benchmark.
- 32
KytyPS5
9.1KKytyPS5/KytyPS5 · C++KytyPS5 is a free and open-source PlayStation 5 emulator (translation layer) written in C++ for Windows and Linux, with experimental macOS support, based on a heavily modified version of the Kyty project.
- 33
tilelang
8.6Ktile-ai/tilelang · PythonTileLang (tile-lang) is a domain-specific language for writing high-performance GPU/CPU/NPU kernels like GEMM, Dequant GEMM, FlashAttention, and LinearAttention, using Pythonic syntax backed by a TVM-based compiler.
- 34
ODS
7.6KOsmantic/ODS · PythonODS (Osmantic Deployment System) turns your PC, Mac, or Linux box into a private AI server by installing and wiring together local LLM inference, a chat UI, agents, voice, RAG, image generation, and privacy tools in one go.
- 35
magnitude
7.2Kmagnitudedev/magnitude · RustMagnitude is an open source inference server that profiles your machine, recommends local models that fit it, then downloads, tunes, and runs them for your coding agent.
- 36

turboquant_plus
7KTheTom/turboquant_plus · PythonTurboQuant+ is the research home for TurboQuant (ICLR 2026), a KV cache compression method for transformer LLMs. It shrinks the KV cache 3.8-6.4x using PolarQuant plus Walsh-Hadamard rotation, and this repo holds the Python reference implementation, validation papers and benchmark data.
- 37
SCSKiller
3KBlueHeisenberg/SCSKiller · C#SCSKiller is a free, open-source Windows tool that pre-compiles a game's shaders into your NVIDIA or AMD driver's cache before you play, so the game doesn't have to compile them mid-session and stutter.
- 38
tokenspeed
2.7Klightseekorg/tokenspeed · PythonTokenSpeed is a speed-of-light LLM inference engine built for agentic workloads, aiming to match TensorRT-LLM-level performance with vLLM-level usability.
- 39
DLSS-NR-on-AMD
2.7Kdanielblnc/DLSS-NR-on-AMDThis is a mod that lets you run DLSS 5 Neural Rendering on AMD Radeon GPUs (RX 7000/9000 series) in any DirectX 12 game that supports FSR, by reimplementing the DLSS neural network runtime for AMD hardware from scratch.
- 40
ReBarUEFI
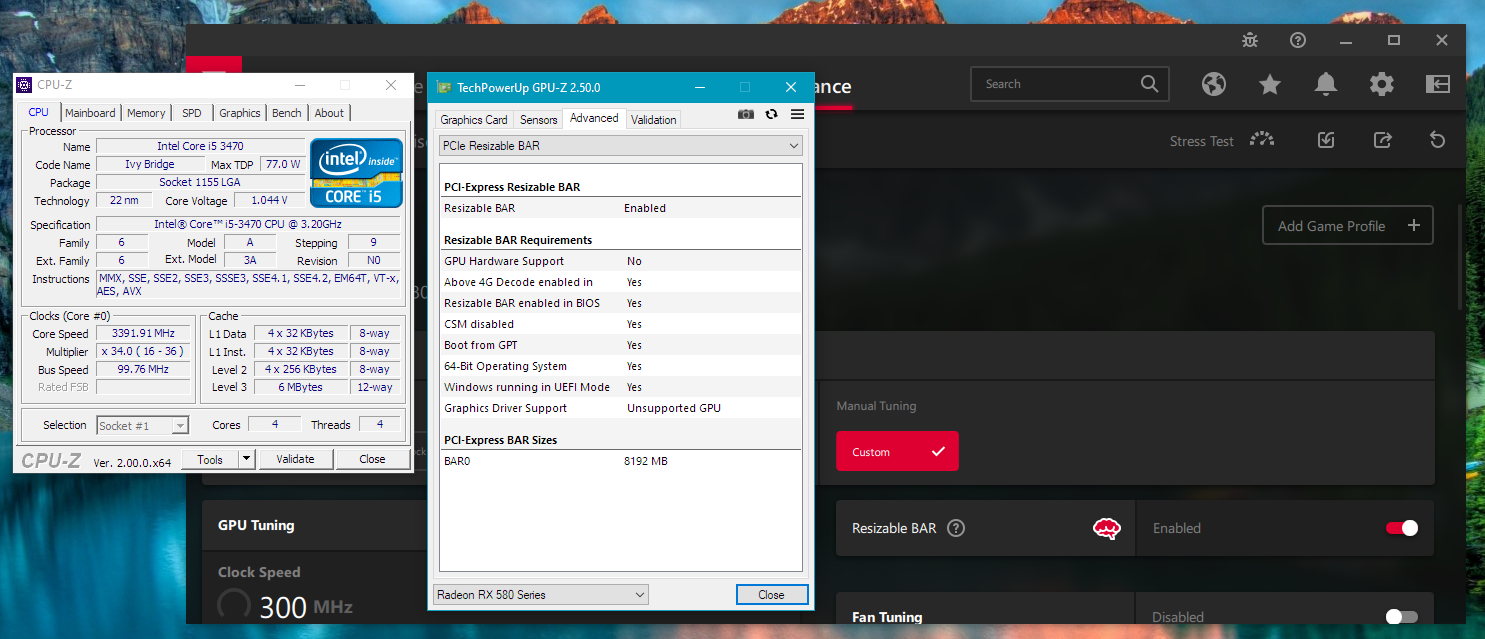
2.6KxCuri0/ReBarUEFI · CReBarUEFI is a UEFI DXE driver that enables Resizable BAR on systems whose firmware doesn't support it officially — a free performance boost, mostly noticeable in games.
- 41
pt-pc
2KLoreanXavier/pt-pc · C++A native PC port of P.T., the 2014 PS4 teaser by Kojima Productions. It is not an emulator: the game logic was rebuilt in C++ and the renderer is written in Vulkan, while every asset (levels, models, textures, sounds, scripts, cutscenes) is read at runtime from your own copy of the PS4 game.
- 42

NoGraphicsAPI
1.6Ksebbbi/NoGraphicsAPI · C++NoGraphicsAPI is an experimental Vulkan 1.4 implementation of Sebastian Aaltonen's 'No Graphics API' idea, exploring what disappears from a conventional graphics API when shaders use raw 64-bit GPU pointers instead of buffer objects and bindings.
- 43
uncharted_pc
1.4KSupermedo/uncharted_pc · C++This is a native Windows port of 'Uncharted: The Nathan Drake Collection', letting the original PS4 game code for Uncharted 1, 2 and 3 run directly on PC with the graphics translated to Vulkan.
- 44
cpu-performance-engineering
1.2Kusamahz/cpu-performance-engineering · PythonA curated reading path for CPU performance engineering: it walks you from what one instruction does on a modern core to serving ML inference on CPUs, ordered so each piece makes the next one legible.
- 45

ShadowOfTheColossus-PC
1.1KAjncSystem/ShadowOfTheColossus-PC · C++It is a native Windows port of Shadow of the Colossus (the 2018 PS4 remake by Bluepoint, CUSA08809), letting the PS4's x86-64 game code run directly on a PC's CPU while the PS4 GPU calls are translated to Vulkan.
- 46
halogen-flash-server
1Kpeonist-ai/halogen-flash-server · Shellhalogen-flash-server is a purpose-built inference server for running the Qwen3.8-Flash-Next model as fast as possible on AMD's Strix Halo (gfx1151) GPU, exposing an OpenAI-compatible API.
- 47
gufo
803gufo-org/gufo · C++Gufo is a local inference engine built specifically for AMD Strix Halo hardware (Ryzen AI MAX+ 395 with Radeon 8060S / gfx1151, up to 128 GiB unified memory), serving text, speech, image and video models through an OpenAI-compatible API.
- 48
verl
725XiaomiMiMo/verl · Pythonverl is an open-source RL post-training framework for large language models, started by ByteDance Seed as the open-source version of the HybridFlow paper. This XiaomiMiMo fork adds agentic RL training code for MiMo, with reproduction code for five RL environments on top of verl 0.9.0.dev.
- 49
RyGT
383mlgprorektm8/RyGT · C++RyGT ports the PS4 game Gran Turismo Sport (CUSA03220, update 1.69) to run natively on Windows. It is not an emulator: a converter turns the game's PS4 executable into a Windows GTSport.exe, the original game code runs directly on the CPU, and RyGT's libraries replace the PS4 system while shadGT's Vulkan renderer handles graphics.
- 50

CUDA-for-AMD-Windows
321Speedstu/CUDA-for-AMD-Windows · PythonA Windows compatibility stack that runs CUDA-targeted applications on AMD GPUs via ZLUDA plus AMD ROCm/HIP, with tooling to verify the work truly executes on the GPU instead of silently falling back to CPU or producing wrong results.
- 51

MoE4All
309Headmaster218/MoE4All · RustMoE4All is a portable Windows app that runs large Mixture-of-Experts (MoE) LLMs beyond what fits in VRAM by streaming expert weights between GPU VRAM, system RAM and SSD, built on a Vulkan-first Rust inference engine so consumer AMD (and other Vulkan) GPUs can run huge models locally.
- 52

d4r
301countervolts/d4r · C++d4r runs NVIDIA's official DLSS Super Resolution library inside Windows games on AMD Radeon GPUs under Linux and Proton, translating the DLSS network through ZLUDA (CUDA on ROCm/HIP) and replacing the heaviest kernels with hand-written RDNA3/RDNA4 code. It supports the DLSS 3 CNN model and the DLSS 4/4.5 transformer models; DLSS 5 is not supported.
- 53
Hyperloom
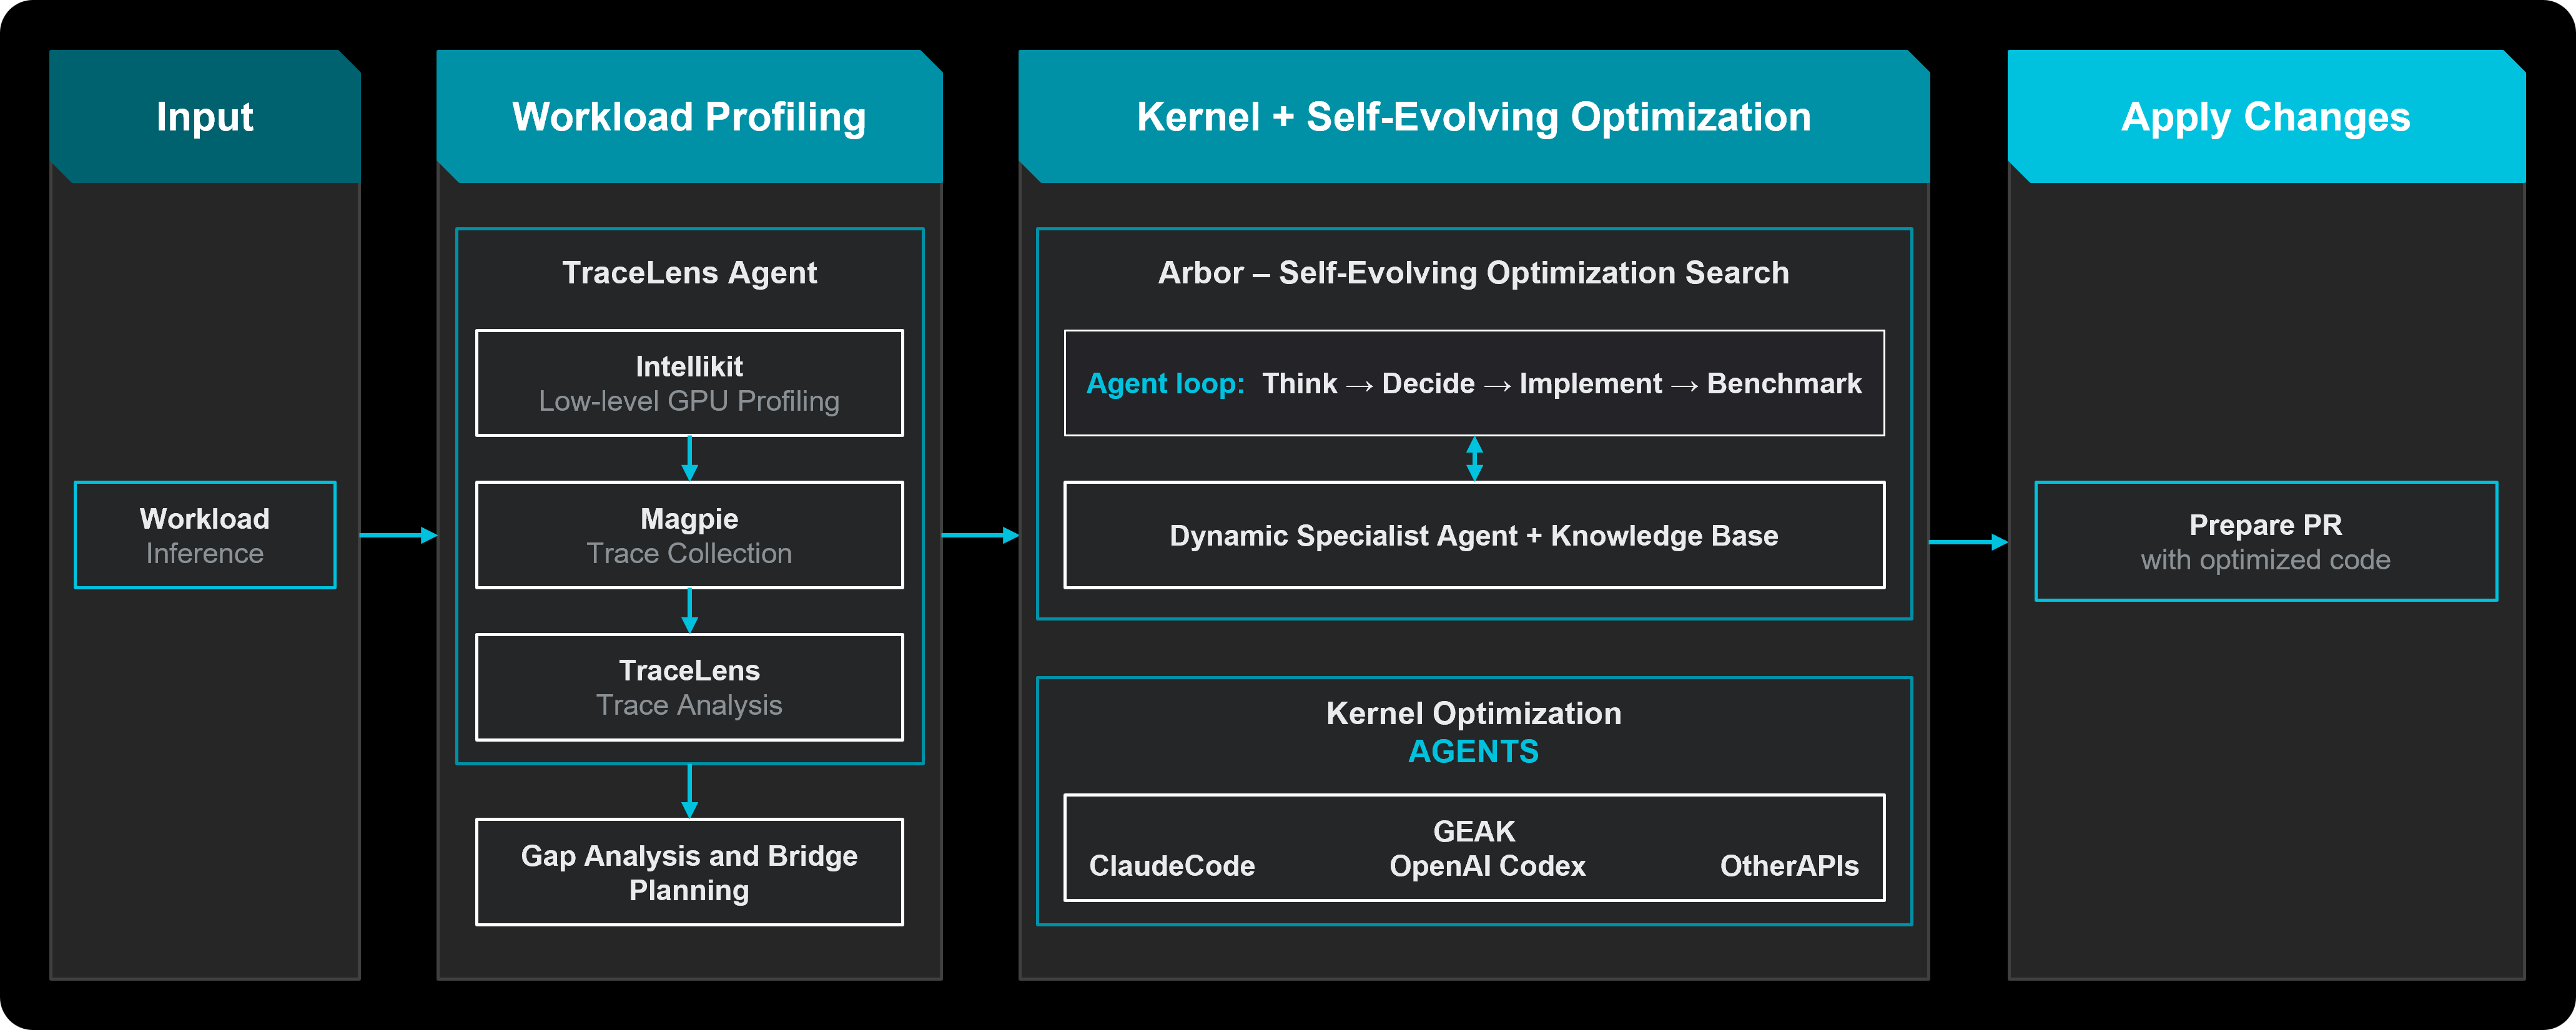
242AMD-AGI/Hyperloom · PythonA multi-agent harness that autonomously optimizes LLM inference on AMD Instinct GPUs: it profiles your workload, searches framework and GPU-kernel optimizations, validates every candidate end to end, and saves proven results into a recipe knowledge base.
Related topics
Often tagged together