Topics / #semantic-search
Semantic-search projects on GitHub
Search by meaning using embeddings instead of exact keyword matching.
As of , the most-starred Semantic-search projects on GitHub are generative-ai-for-beginners (121.5K stars), immich (116.4K stars) and Agent-Reach (98.4K stars). GitHub.Locker tracks 114 Semantic-search repositories with 1.9M stars combined. The fastest-growing on October 16 was xerj, with +1.2K stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +1.2K
xerj
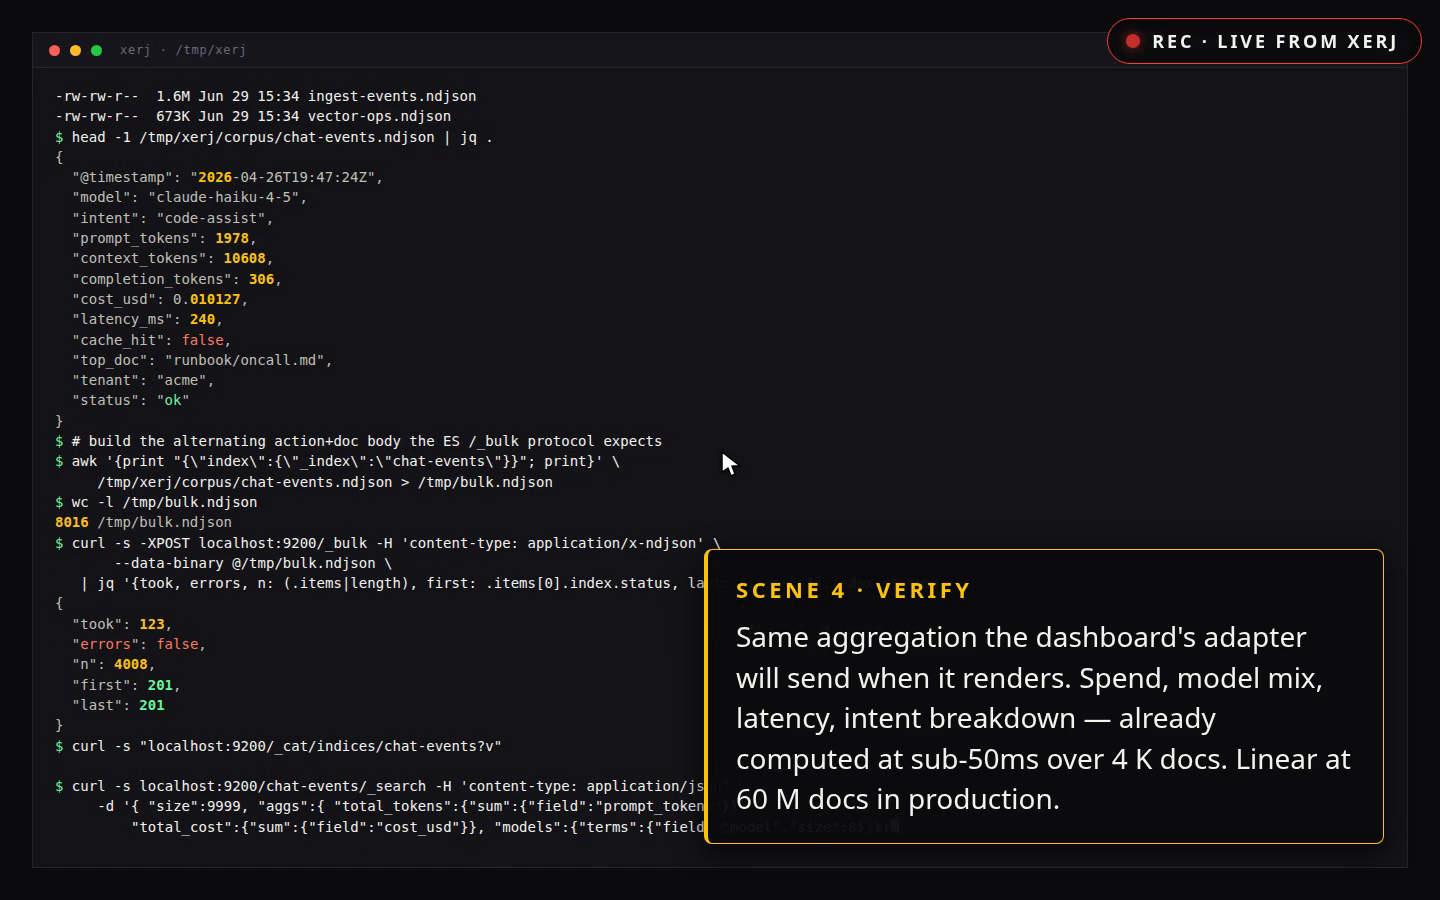
xerj-org/xerj · ★ 6.9KXERJ is a local-first search engine that automatically indexes any folder - code, docs, logs, PDFs - so an AI coding agent can pull the exact passage it needs instead of grepping or reading whole files into context, and it speaks the Elasticsearch API so existing clients work against it unchanged.
 +513
Agent-Reach
Panniantong/Agent-Reach · ★ 98.4KAgent Reach is a capability layer that gives an AI agent the ability to actually read and search the internet — Twitter/X, Reddit, YouTube, GitHub, Bilibili, XiaoHongShu, RSS, web pages and more — instead of hitting paywalls, 403s or login walls.
 +441
hindsight
vectorize-io/hindsight · ★ 50.7KHindsight is an agent memory system that helps AI agents learn over time instead of just recalling raw conversation history, aiming to outperform RAG and knowledge-graph approaches on long-term memory tasks.
 +215
DigUp
ARahim3/DigUp · ★ 4.3KDigUp is a free, open-source macOS menu bar app that lets you search the files on your Mac by what's actually in them — photos, PDFs, documents, recordings, videos and code — using Google DeepMind's EmbeddingGemma 2 model running entirely on-device.
The all-time top
Top 100 of 114 · by stars
- 121.5K
 #1 · microsoft/generative-ai-for-beginners
generative-ai-for-beginners
A 21-lesson course by Microsoft Cloud Advocates that teaches the fundamentals of building Generative AI applications, covering concepts like prompt engineering, chat apps, RAG, fine-tuning, and AI agents.
- 116.4K
 #2 · immich-app/immich
immich
Immich is a self-hosted platform for backing up, organizing and browsing your photos and videos, built as an open-source alternative to Google Photos.
- 98.4K#3 · Panniantong/Agent-Reach
Agent-Reach
Agent Reach is a capability layer that gives an AI agent the ability to actually read and search the internet — Twitter/X, Reddit, YouTube, GitHub, Bilibili, XiaoHongShu, RSS, web pages and more — instead of hitting paywalls, 403s or login walls.
- 4
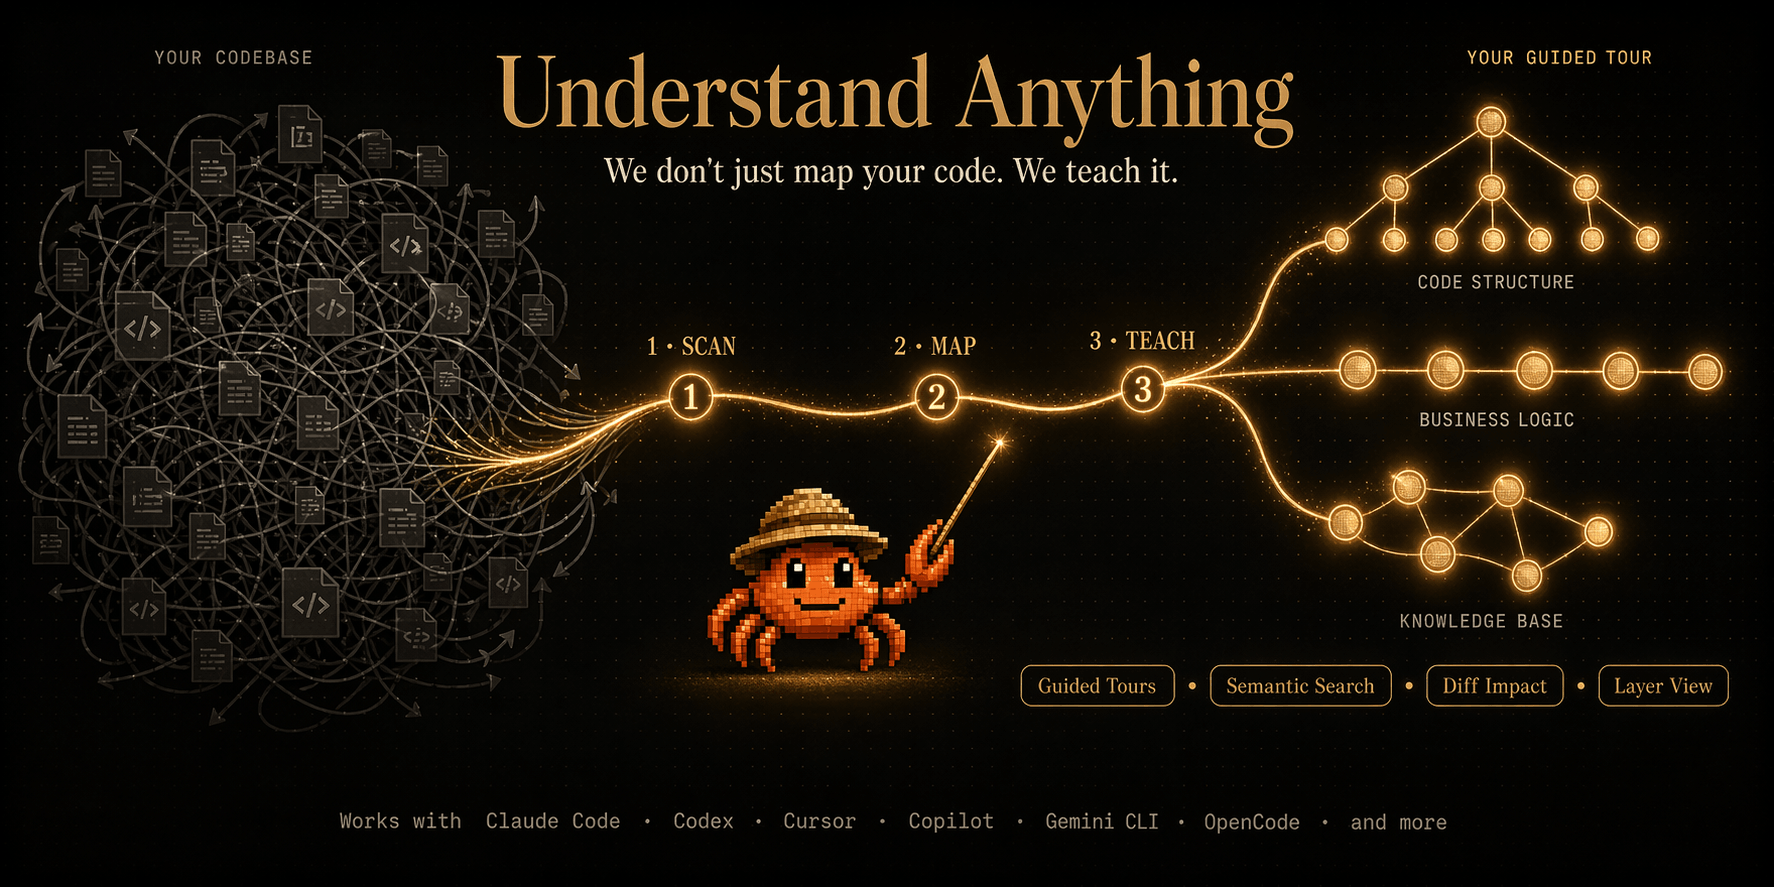
Understand-Anything
86.7KEgonex-AI/Understand-Anything · TypeScriptUnderstand Anything analyzes your codebase (or a knowledge-base/wiki) with a multi-agent pipeline and turns it into an interactive knowledge graph of every file, function, class and dependency, which you can explore in a visual dashboard.
- 5

redis
76.9Kredis/redis · CRedis is an in-memory server used as a cache, data structure store, and document/vector query engine for building real-time, data-driven applications.
- 6
mempalace
59.6KMemPalace/mempalace · PythonMemPalace is a local-first AI memory system that stores conversation history as verbatim text (not summarized) and retrieves it with semantic search, so coding agents can remember past sessions.
- 7

meilisearch
59.6Kmeilisearch/meilisearch · RustMeilisearch is a fast, open-source search engine that adds AI-powered hybrid search (combining full-text and semantic search) to websites and apps.
- 8

serviette
58.8Kpathwaycom/serviette · PythonThis repo provides ready-to-run cloud templates for RAG pipelines, AI pipelines, and enterprise search, built on the Pathway Live Data Framework and kept in sync with live data sources.
- 9
hindsight
50.7Kvectorize-io/hindsight · PythonHindsight is an agent memory system that helps AI agents learn over time instead of just recalling raw conversation history, aiming to outperform RAG and knowledge-graph approaches on long-term memory tasks.
- 10
milvus
46.4Kmilvus-io/milvus · GoMilvus is a high-performance, cloud-native vector database built to store and search embedding vectors at scale for AI applications like semantic search, RAG, and recommendation systems.
- 11
LightRAG
40.2KHKUDS/LightRAG · PythonLightRAG is an open-source, graph-based RAG framework (EMNLP 2025) by HKUDS. It indexes your documents into a knowledge graph plus vector embeddings so you can query them — a lighter, faster alternative to Microsoft GraphRAG.
- 12
quivr
39.6KThe-Vibe-Company/quivr · GoQuivr is an open-source engine that turns your files and content streams into search and monitoring — a 'second brain' you can query, built around an opinionated RAG powered by generative AI.
- 13
PageIndex
39.2KVectifyAI/PageIndex · PythonPageIndex is a vectorless, reasoning-based RAG (Retrieval-Augmented Generation) engine. Instead of a vector database and chunking, it builds a hierarchical tree index that mirrors a document's structure and lets an LLM reason its way through that tree to find relevant sections, the way a human expert flips to the right part of a report.
- 14
spacedrive
39.2Kspacedriveapp/spacedrive · RustSpacedrive is a cross-platform file explorer and a cross-device data platform. It indexes files, emails, notes, and other sources, lets you search everything in one place, and syncs data across devices via peer-to-peer connections.
- 15

khoj
37.7Kkhoj-ai/khoj · PythonKhoj is an open-source personal AI — a 'second brain' that answers your questions from the web and your own documents, runs custom agents for you, and works with any online or local LLM.
- 16

WeKnora
34.4KTencent/WeKnora · GoWeKnora is an open-source, self-hosted knowledge platform that turns raw documents into a queryable RAG knowledge base, an autonomous ReAct agent, and a self-maintaining Wiki with an interactive knowledge graph.
- 17
graphiti
31.8Kgetzep/graphiti · PythonA Python framework for building and querying temporal knowledge graphs for AI agents. Instead of static RAG, it continuously folds new data into a graph that tracks how facts change over time.
- 18

qmd
30.5Ktobi/qmd · TypeScriptQMD is an on-device search engine for your personal knowledge: it indexes markdown notes, meeting transcripts, documentation and knowledge bases, and searches them with keywords or natural language.
- 19
RAG_Techniques
29.9KNirDiamant/RAG_Techniques · Jupyter NotebookA community-driven hub of advanced techniques for Retrieval-Augmented Generation (RAG) — grounding LLM answers in retrieved documents, distilled into runnable notebook tutorials.
- 20

karakeep
29.7Kkarakeep-app/karakeep · TypeScriptKarakeep (formerly Hoarder) is a self-hostable bookmark-everything app: save links, notes, images and PDFs, and it auto-fetches link details, tags everything with an LLM and gives you full-text and semantic search over all of it.
- 21
Hands-On-Large-Language-Models
29.7KHandsOnLLM/Hands-On-Large-Language-Models · Jupyter NotebookThe official code repo for the O'Reilly book 'Hands-On Large Language Models', known as the Illustrated LLM Book. It contains a Jupyter notebook for each of the book's 12 chapters.
- 22

chroma
29.5Kchroma-core/chroma · RustChroma is open-source data infrastructure for AI: a vector database that powers search for embeddings, used for things like retrieval-augmented generation (RAG) and AI agent memory.
- 23

typesense
27Ktypesense/typesense · C++An open-source, typo-tolerant in-memory search engine for building fast search experiences — a self-hostable Algolia alternative and an easier-to-use Elasticsearch alternative.
- 24
haystack
26.8Kdeepset-ai/haystack · PythonAn open-source AI orchestration framework for building production-ready LLM applications in Python: modular pipelines and agent workflows with explicit control over retrieval, routing, memory, and generation.
- 25

llm-cookbook
24.8Kdatawhalechina/llm-cookbook · Jupyter NotebookA developer-oriented LLM starter handbook: a Chinese adaptation of Andrew Ng's LLM course series, translated and re-run for Chinese developers, covering prompt engineering through RAG development and model fine-tuning.
- 26

pgvector
23.4Kpgvector/pgvector · Cpgvector is an open-source extension that adds vector similarity search to Postgres, so embeddings are stored and queried right next to your relational data. It supports exact and approximate nearest neighbor search.
- 27
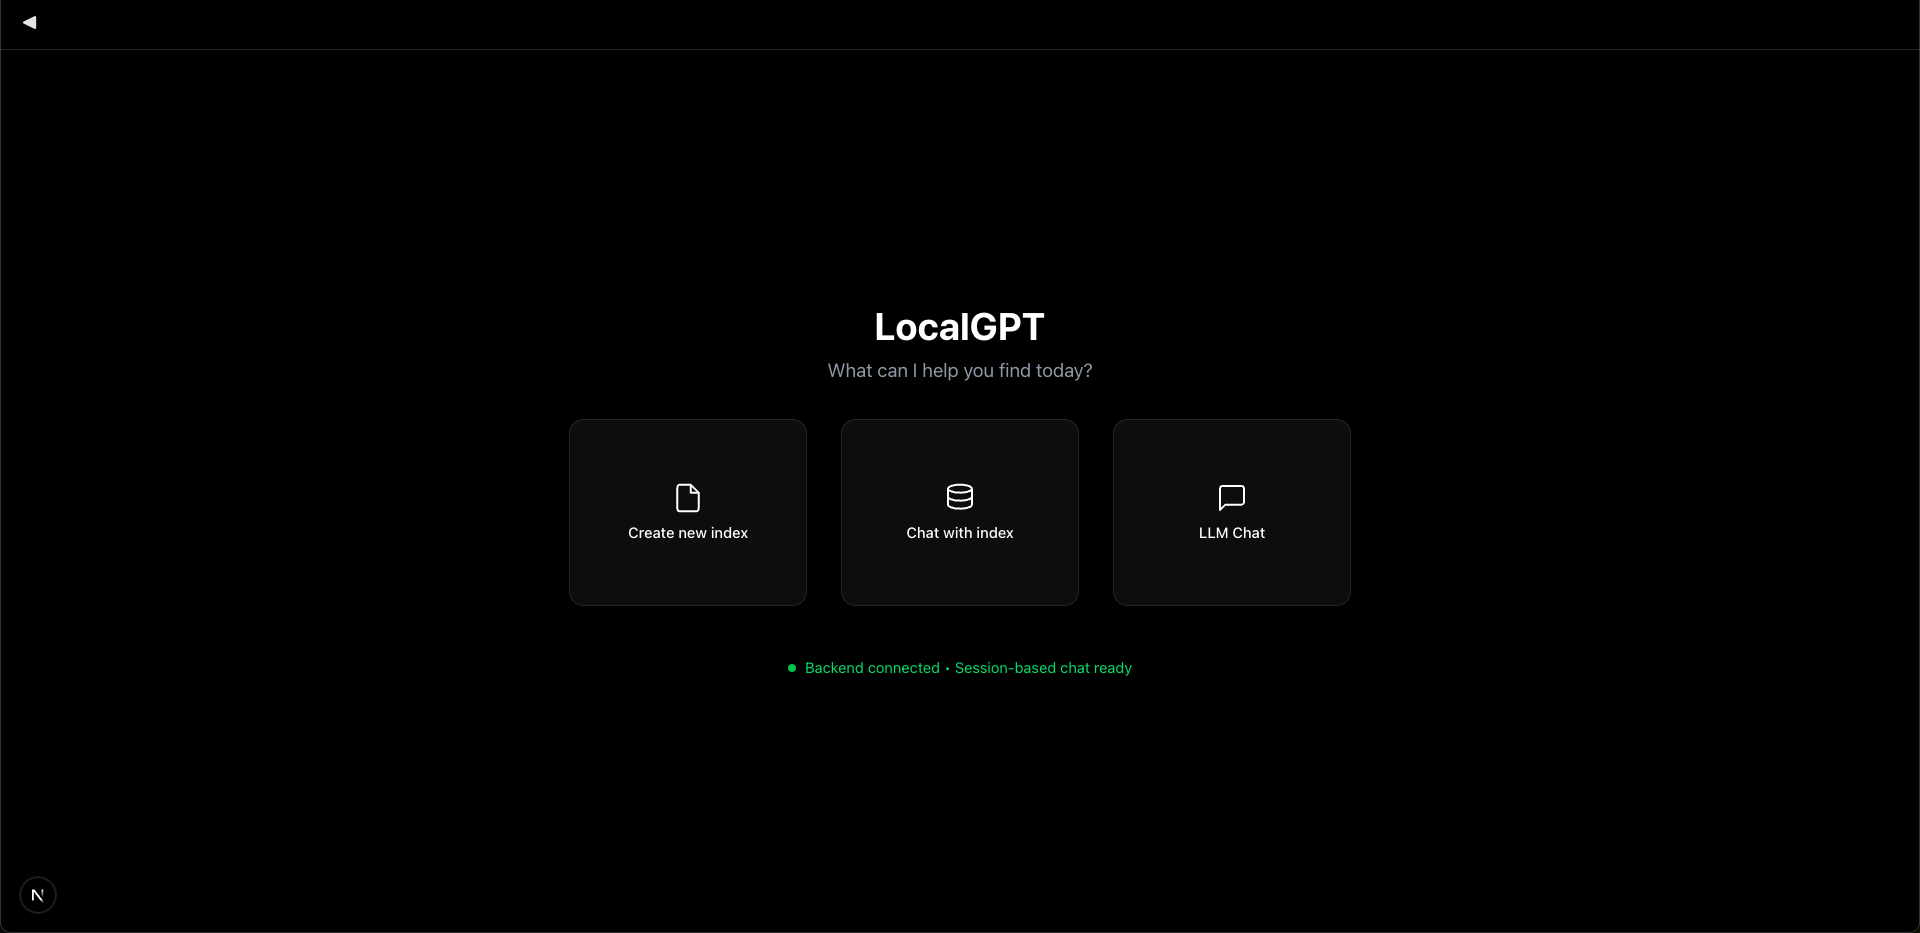
localGPT
22.2KPromtEngineer/localGPT · PythonLocalGPT is a fully private, on-premise document intelligence platform: chat with, summarise and query your own documents using LLMs that run locally, so no data ever leaves your machine.
- 28
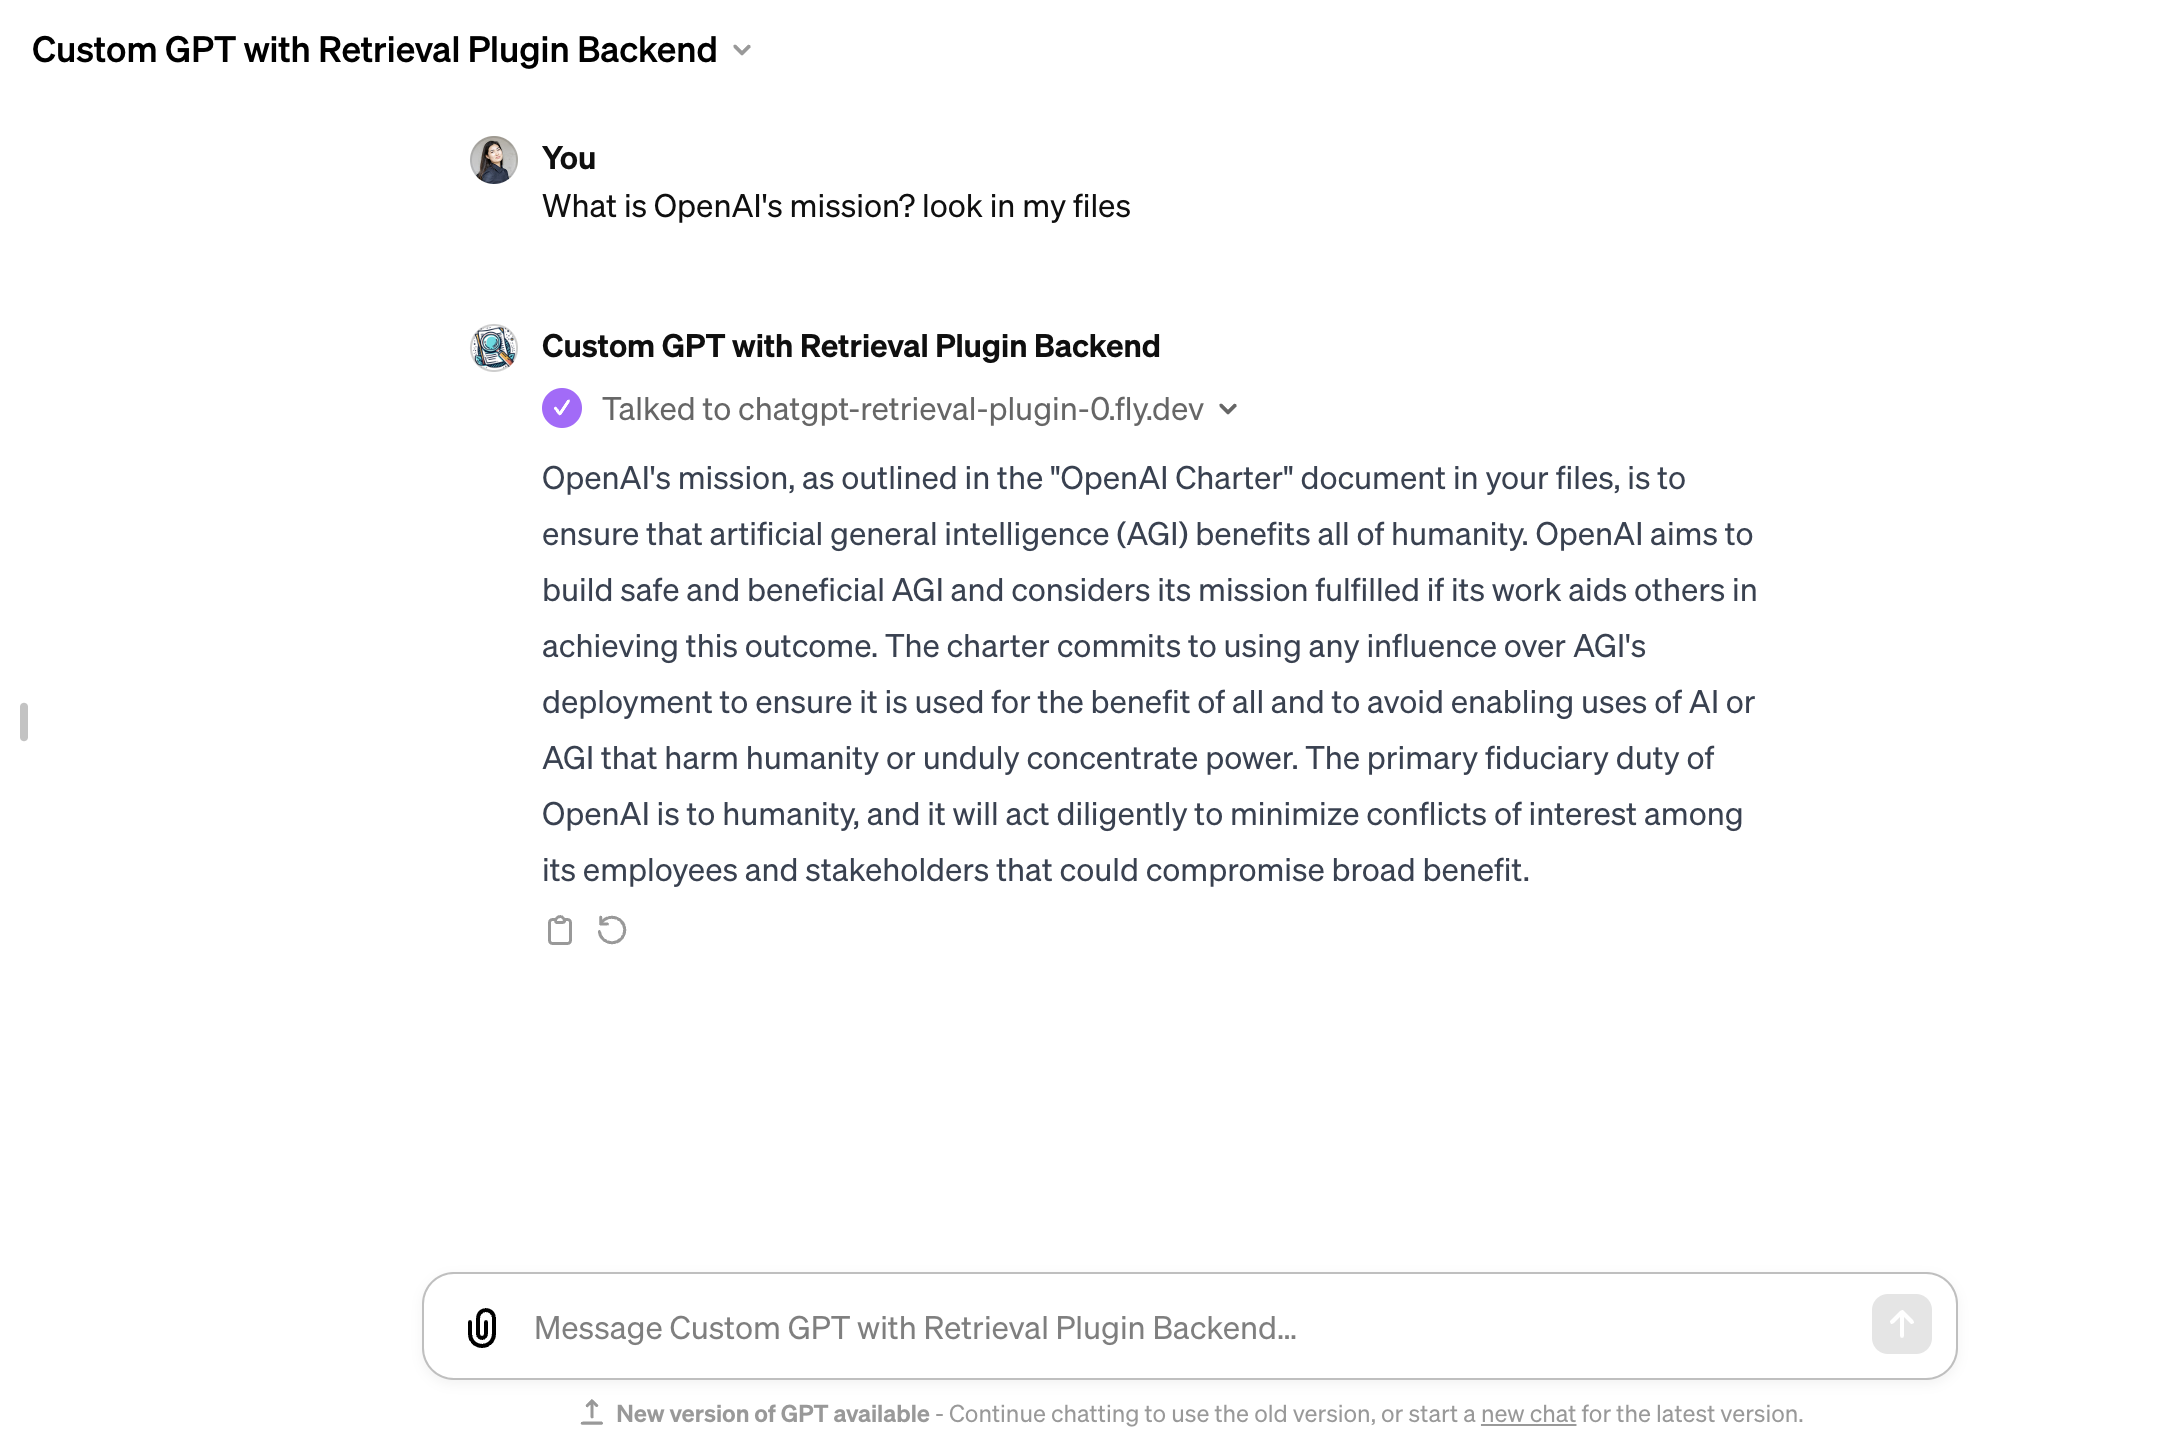
chatgpt-retrieval-plugin
21.3Kopenai/chatgpt-retrieval-plugin · PythonAn open-source retrieval backend for ChatGPT: it indexes your personal or work documents in a vector database and answers natural-language questions with the most relevant snippets — the RAG pattern. Enterprises use it to make internal docs searchable through ChatGPT.
- 29
jcode
20.9K1jehuang/jcode · Rustjcode is a high-performance coding agent harness written in Rust — a terminal-based AI coding agent that connects to LLM providers like Claude, OpenAI and Gemini and drives coding work from your TUI.
- 30
llm_wiki
20.7Knashsu/llm_wiki · TypeScriptLLM Wiki is a cross-platform desktop app that turns your documents into a persistent, interlinked knowledge base. Instead of re-deriving answers from scratch every time like traditional RAG, the LLM incrementally builds and keeps a wiki of your sources up to date.
- 31

sentence-transformers
19.2Khuggingface/sentence-transformers · PythonSentence Transformers is a framework for computing embeddings and using or training state-of-the-art embedding and reranker models, covering dense sentence embeddings, cross-encoder rerankers, sparse encoders, and multi-vector (ColBERT-style) encoders.
- 32

DocsGPT
18.3Karc53/DocsGPT · PythonDocsGPT is a private, self-hosted AI platform for building agents, assistants, and enterprise search tools, with a built-in Agent Builder, document analysis, deep research mode, and support for multiple LLM providers.
- 33
weaviate
16.9Kweaviate/weaviate · GoWeaviate is an open-source, cloud-native vector database: it stores objects and vectors together and lets you combine vector search with structured filtering for semantic search at scale.
- 34
memvid
16.6Kmemvid/memvid · RustMemvid is a single-file memory layer for AI agents: it packs your data, embeddings and search index into one portable .mv2 file, so agents get instant retrieval and long-term memory without a RAG pipeline or a vector database server.
- 35
gensim
16.5Kpiskvorky/gensim · PythonGensim is a Python library for topic modelling, document indexing and similarity retrieval with large corpora, aimed at the natural language processing (NLP) and information retrieval (IR) community.
- 36

zvec
16.1Kalibaba/zvec · C++Alibaba's open-source, in-process vector database — a lightweight, lightning-fast similarity-search engine you embed directly into your application, battle-tested inside Alibaba Group.
- 37
OpenMetadata
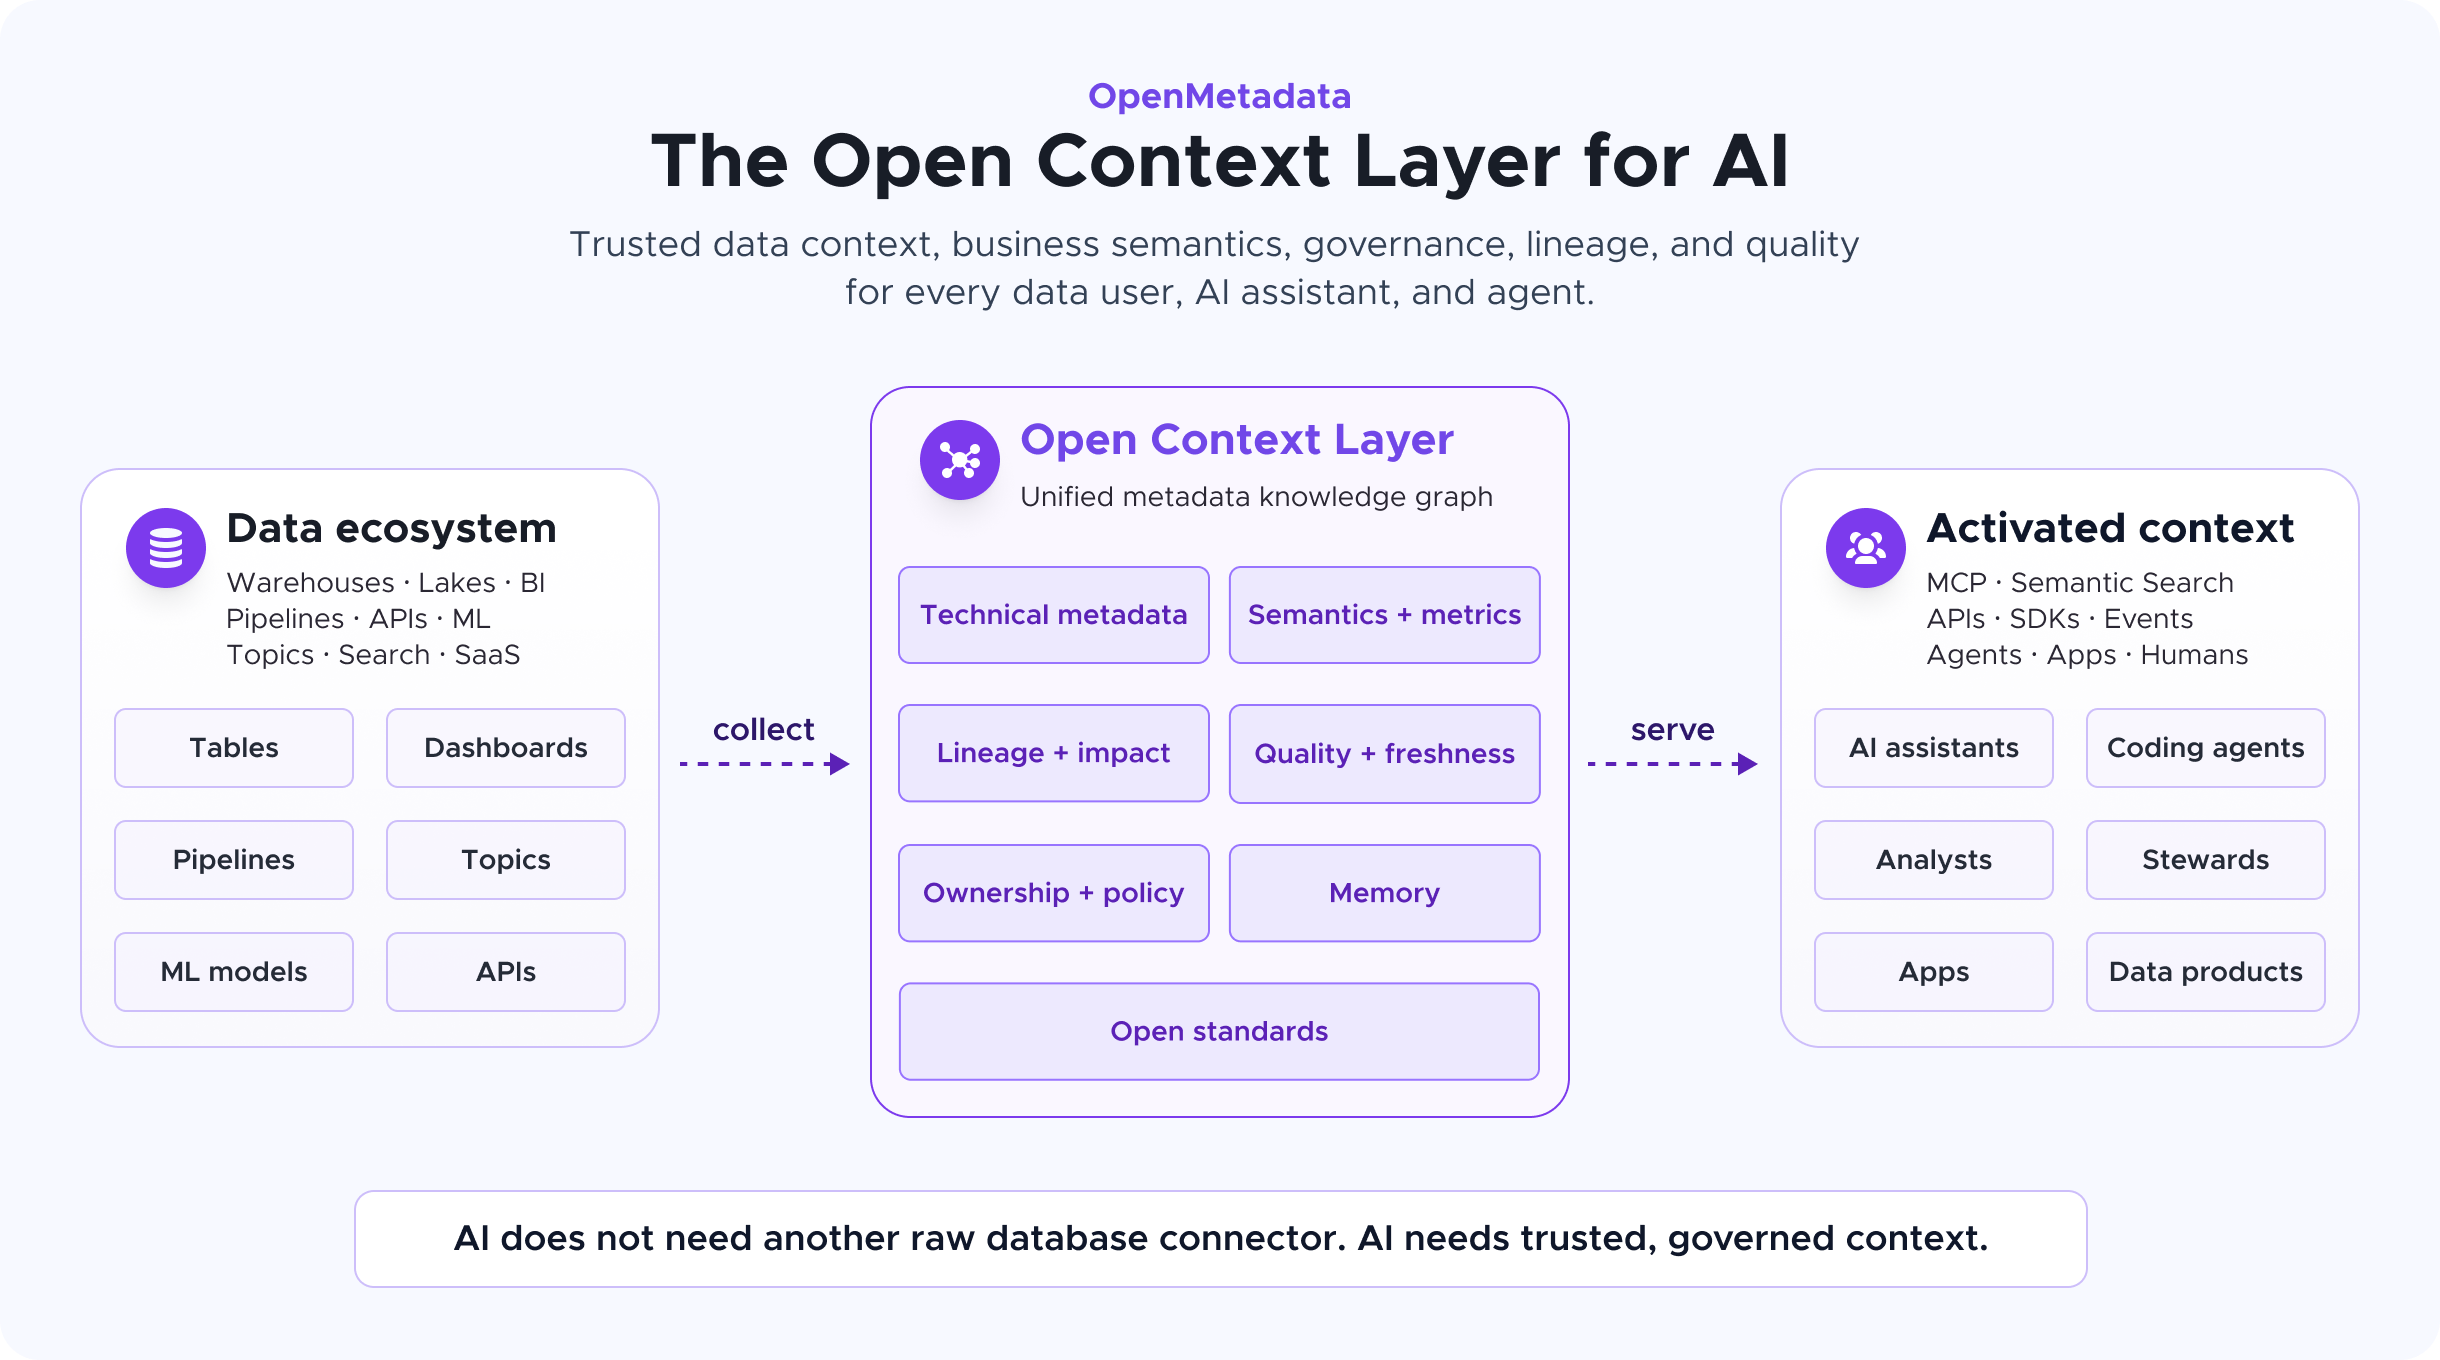
15.5Kopen-metadata/OpenMetadata · TypeScriptOpenMetadata is an open platform that unifies technical metadata, lineage, data quality, ownership and business glossaries into one knowledge graph so both humans and AI agents can discover, trust and reuse context about enterprise data.
- 38
QAnything
14.2Knetease-youdao/QAnything · PythonA local knowledge base question-answering system: load your own documents into it and ask questions — you get accurate answers drawn from your files instead of the open web.
- 39
semantica
14.1Ksemantica-agi/semantica · PythonSemantica is an open-source, graph-native infrastructure layer that ingests enterprise data and builds a structured Context Graph and knowledge graph with deterministic reasoning, ontology governance, and full decision provenance, so AI systems can be explained and audited instead of treated as black boxes.
- 40
EverOS
13.5KEverMind-AI/EverOS · PythonEverOS is a local-first, Markdown-native memory layer for AI agents: it stores conversations, files, and agent trajectories as readable Markdown, then syncs local SQLite and LanceDB indexes so any coding assistant, app, or workflow can retrieve and keep building on the same persistent memory.
- 41
LEANN
13KStarTrail-org/LEANN · PythonLEANN is a vector database that lets you run retrieval-augmented generation (RAG) over millions of personal documents on your own laptop using 97% less storage than traditional vector databases, with no accuracy loss.
- 42
txtai
13Kneuml/txtai · Pythontxtai is an all-in-one AI framework for semantic search, LLM orchestration and language model workflows. Its core is an embeddings database that combines vector indexes, graph networks and relational databases to power search or serve as a knowledge source for LLM apps.
- 43
clip-as-service
12.8Kjina-ai/clip-as-service · PythonCLIP-as-service is a low-latency, high-scalability service for embedding images and text with CLIP models, so you can plug it into neural search or cross-modal retrieval apps as a microservice.
- 44
claude-context
12.6Kzilliztech/claude-context · TypeScriptClaude Context is an MCP server that gives AI coding agents semantic search over your entire codebase, so they can pull relevant code straight into context instead of loading whole directories.
- 45
mcp-chrome
12.5Khangwin/mcp-chrome · TypeScriptChrome MCP Server turns your Chrome browser into a tool AI assistants like Claude can control via the Model Context Protocol (MCP), enabling browser automation, content analysis, and semantic search right inside your everyday browser.
- 46
FlagEmbedding
12.3KFlagOpen/FlagEmbedding · PythonFlagEmbedding (BGE) is a one-stop toolkit from BAAI for retrieval and retrieval-augmented LLMs, providing embedding models, rerankers, finetuning scripts, and evaluation tools for search and RAG.
- 47
manticoresearch
12.1Kmanticoresoftware/manticoresearch · C++Manticore Search is an open-source search database built for full-text, vector, and hybrid search with real-time indexing and SQL support. It's positioned as a fast, cost-efficient alternative to Elasticsearch.
- 48

cocoindex
11.7Kcocoindex-io/cocoindex · RustCocoIndex is an incremental engine that turns codebases, meeting notes, inboxes, Slack, PDFs, and videos into live, continuously fresh context for AI agents and LLM apps, using minimal incremental processing instead of stale batch jobs.
- 49

lancedb
11.7Klancedb/lancedb · RustLanceDB is an open-source vector database for multimodal AI: a central platform where you store, index and search petabytes of vectors and multimodal data, built for fast, production-ready retrieval.
- 50

blinko
11.1Kblinkospace/blinko · TypeScriptBlinko is an open-source, self-hosted AI note-taking app for quickly capturing fleeting thoughts as cards, with built-in AI-powered search over your notes.
- 51

PixelRAG
10.3KStarTrail-org/PixelRAG · PythonAn open-source research codebase from Berkeley for pixel-native search: PixelRAG renders web pages, PDFs and images as screenshots and retrieves over the images directly, instead of parsing pages into text.
- 52
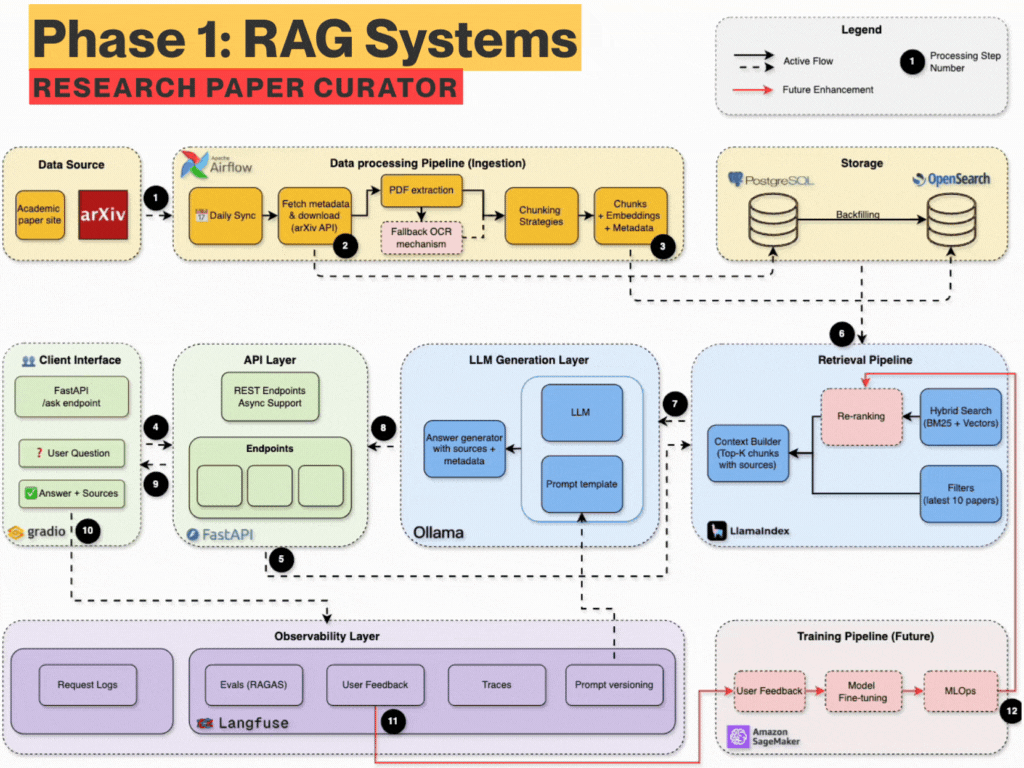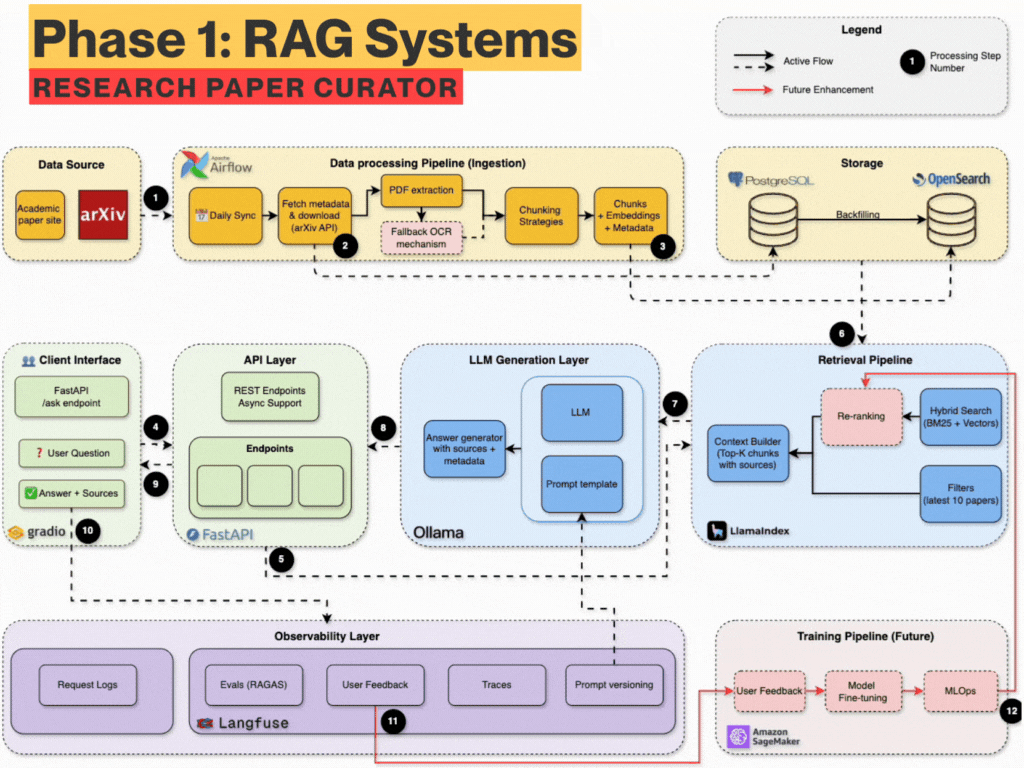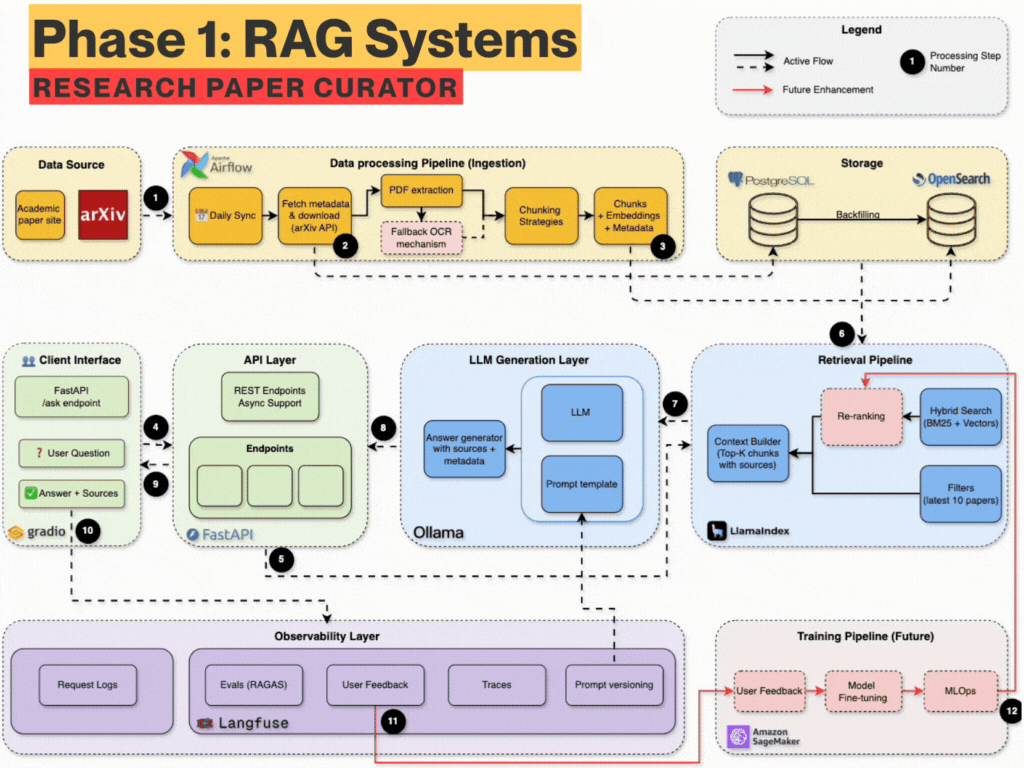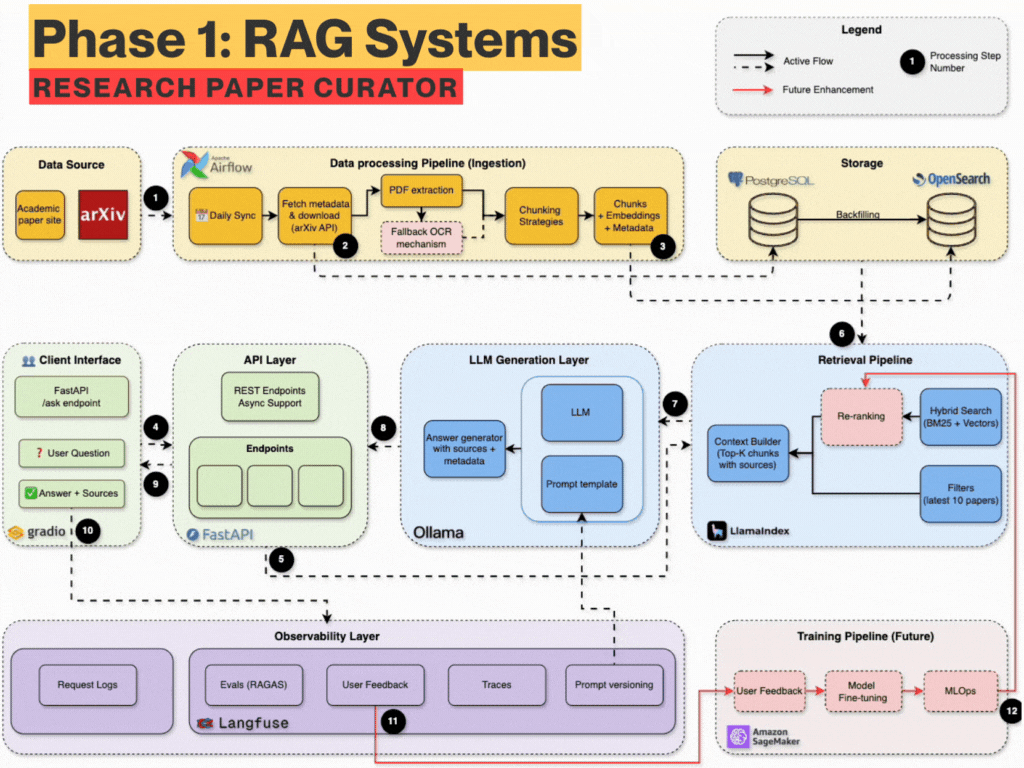
production-agentic-rag-course
9.8Kjamwithai/production-agentic-rag-course · PythonThis is a hands-on, week-by-week course that teaches you to build 'arXiv Paper Curator', a production-grade Retrieval-Augmented Generation (RAG) system that fetches academic papers, indexes them, and answers research questions about them.
- 53
clawhub
9.5Kopenclaw/clawhub · TypeScriptClawHub is the public skill registry for OpenClaw: a place to publish, version, and search text-based agent skills (a SKILL.md plus supporting files), plus a catalog of OpenClaw code and bundle plugins.
- 54

openwhispr
9.5KOpenWhispr/openwhispr · JavaScriptOpenWhispr is an open-source, privacy-first voice-to-text dictation app for desktop. Press a hotkey, speak, and the text appears at your cursor, with extra features like an AI voice assistant, meeting transcription, and notes.
- 55

knowledge-catalog
9.5KGoogleCloudPlatform/knowledge-catalog · TypeScriptThis is the samples and tools repository for Google Cloud's Knowledge Catalog, an AI-powered data catalog and metadata management platform (formerly called Dataplex) that builds a dynamic knowledge graph over structured and unstructured data to give AI agents semantic and business context.
- 56
utopia
8.4Kdeeplethe/utopia · RustUtopia is an open-source enterprise world model from DeepLethe: a self-hosted knowledge system that turns documents into a bitemporal knowledge graph you can search, chat with and reason over, running entirely on hardware you control.
- 57
AIHOT
7.9KKKKKhazix/AIHOT · TypeScriptAIHOT is a framework for building an AI-curated news site: it pulls items from your sources, has an LLM filter and score each one twice, writes Chinese headlines and summaries, clusters reports of the same story into one event, ranks events by how many independent sources cover them, and publishes a daily briefing.
- 58
OpenSpace
7.8KHKUDS/OpenSpace · PythonOpenSpace is a skill management layer for AI agents that helps them retrieve the right skill for a task, evaluate it against real outcomes, share proven workflows, and evolve skills over time, across agents like Claude Code, Codex, OpenClaw, Hermès and nanobot.
- 59
xerj
6.9Kxerj-org/xerj · RustXERJ is a local-first search engine that automatically indexes any folder - code, docs, logs, PDFs - so an AI coding agent can pull the exact passage it needs instead of grepping or reading whole files into context, and it speaks the Elasticsearch API so existing clients work against it unchanged.
- 60
semble
6.2KMinishLab/semble · PythonSemble is a code search library built for coding agents. It returns the exact relevant code snippets for a query instead of making the agent grep and read full files, using about 99% fewer tokens than grep+read.
- 61

agentsview
6.1Kkenn-io/agentsview · GoAgentsView is a local-first tool that browses, searches, and tracks costs across sessions from Claude Code, Codex, and over 20 other coding agents, all stored in a local SQLite database with no cloud accounts required.
- 62
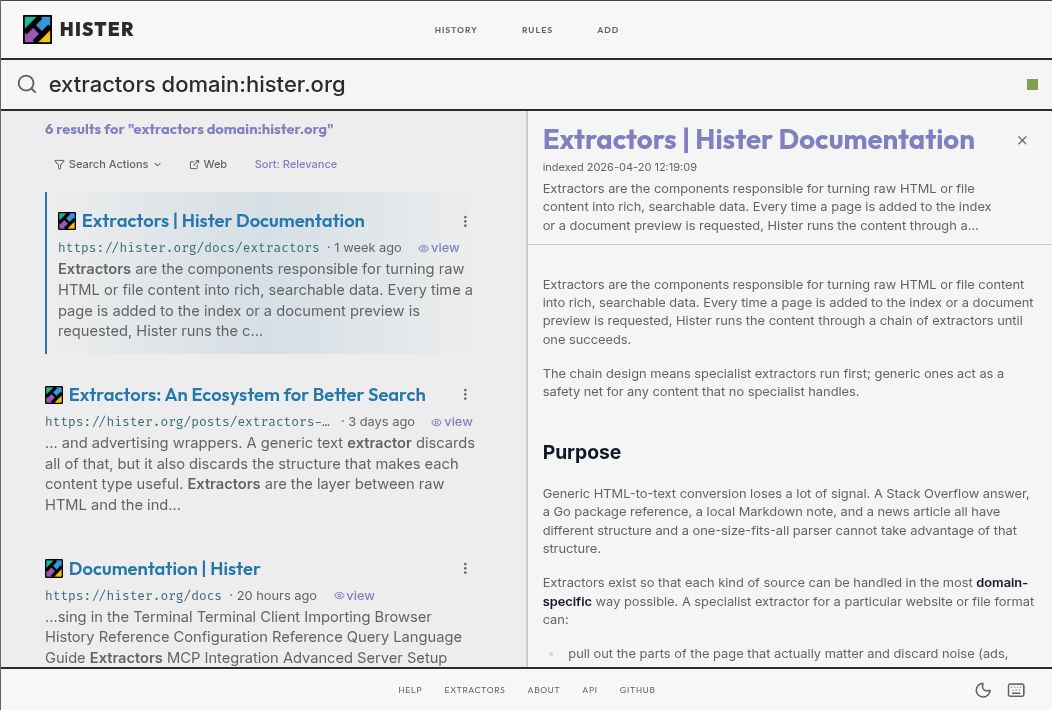
hister
6.1Kasciimoo/hister · GoHister is a private, self-hosted search engine that fully indexes the pages you visit and the files you keep, so you can search their content later from a web interface, terminal, or an AI assistant via MCP.
- 63
obsidian-mind
5.4Kbreferrari/obsidian-mind · TypeScriptObsidian Mind is a self-organizing Obsidian vault template that gives AI coding agents like Claude Code persistent memory: it stores notes, decisions, and context as markdown files so every session builds on the last instead of starting from zero.
- 64

sutskever-30-implementations
5.2Kpageman/sutskever-30-implementations · Jupyter NotebookIt is a from-scratch NumPy implementation suite covering all 30 deep learning papers from Ilya Sutskever's famous reading list, the one he told John Carmack would teach '90% of what matters' in the field.
- 65

mycontext
5KopenTrinity/mycontext · TypeScriptMyContext is a local-first desktop app that builds a persistent, evolving personal context layer from your messages, documents, meetings and other work signals, and makes that context usable by AI agents, local LLMs, and a 'digital self' that can draft replies in your style.
- 66
obsidian-second-brain
4.8Keugeniughelbur/obsidian-second-brain · PythonIt's a skill/plugin that gives Claude Code and other CLI coding agents (Codex, Gemini, Grok Bot, and more) persistent, self-rewriting memory stored as plain markdown notes in your Obsidian vault, so you stop re-explaining your projects, decisions, and people every session.
- 67
RuVector
4.6Kruvnet/RuVector · RustRuVector is a Rust-native persistent memory substrate for AI agents, combining local vector embeddings, graph relationships, feedback-driven learning, and memory lifecycle controls so agents can remember across sessions.
- 68

sentrysearch
4.6Kssrajadh/sentrysearch · PythonSentrySearch is a CLI tool that lets you semantically search through video footage (like Tesla dashcam clips) by typing what you're looking for and getting back a trimmed clip of the matching moment.
- 69
docker-agent
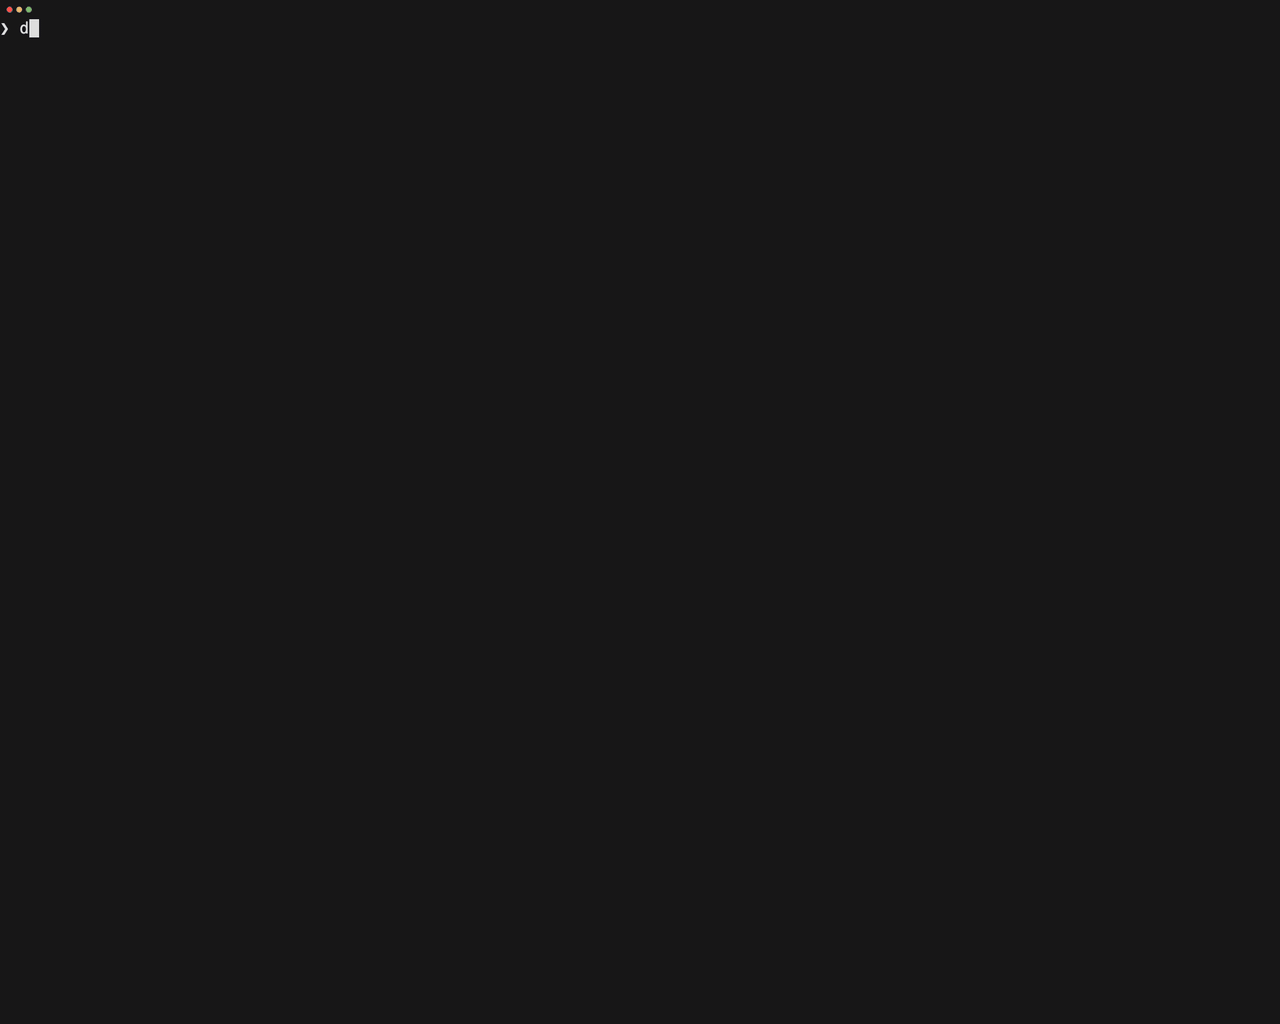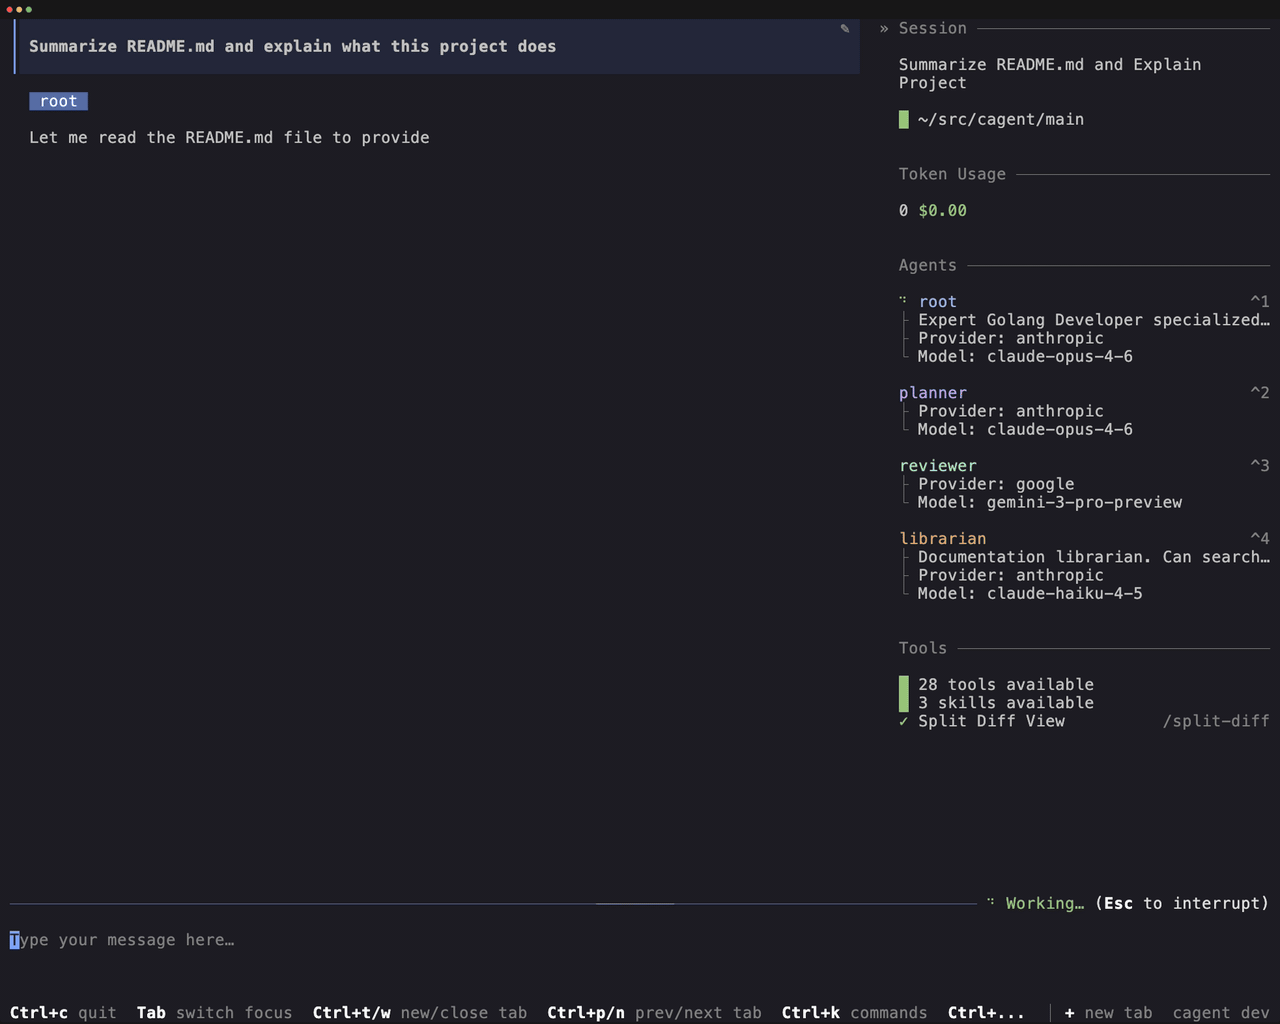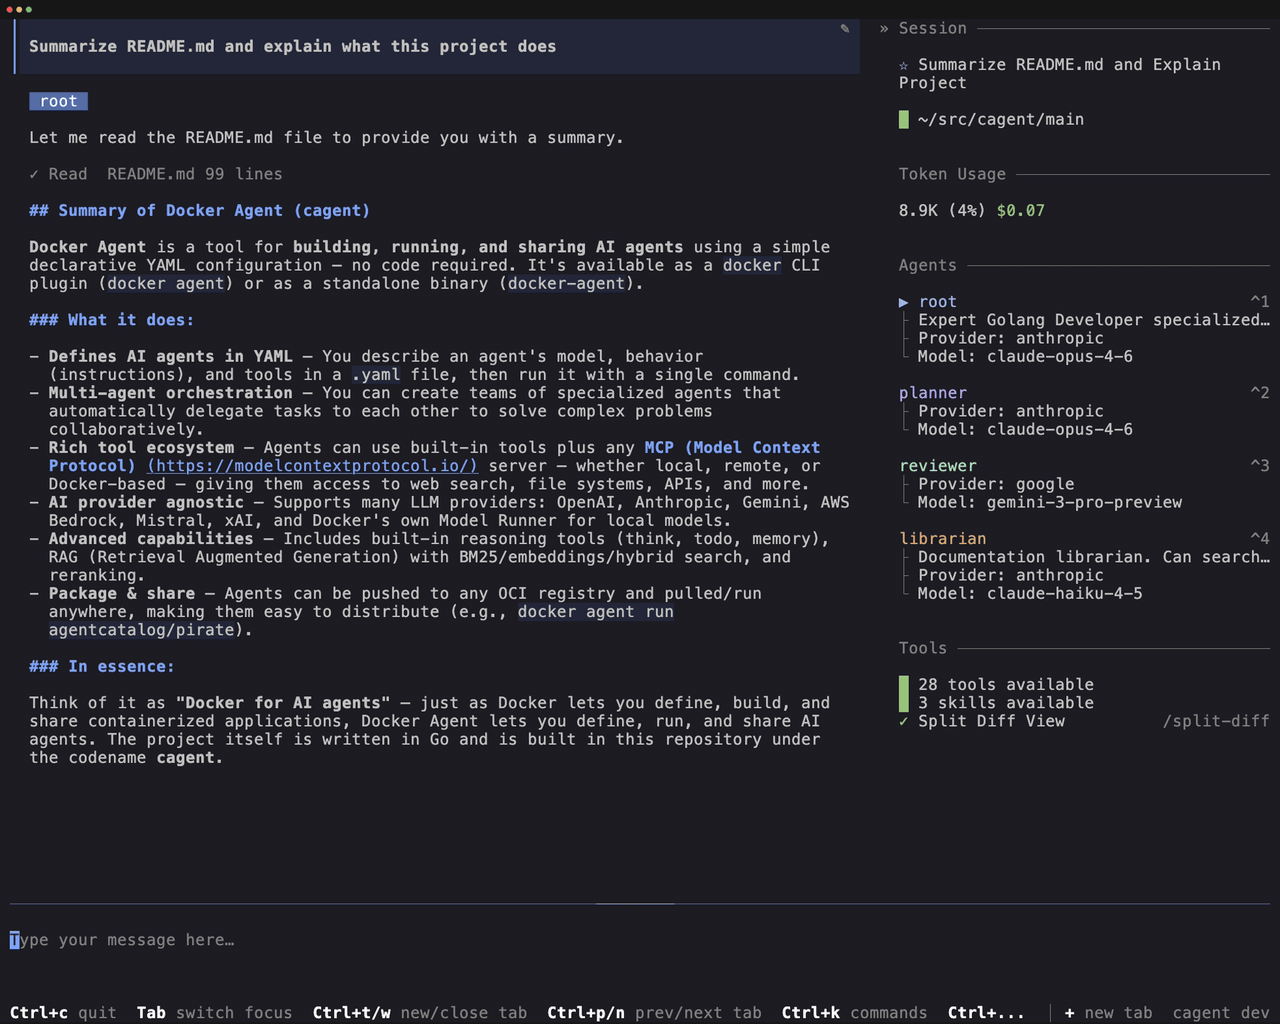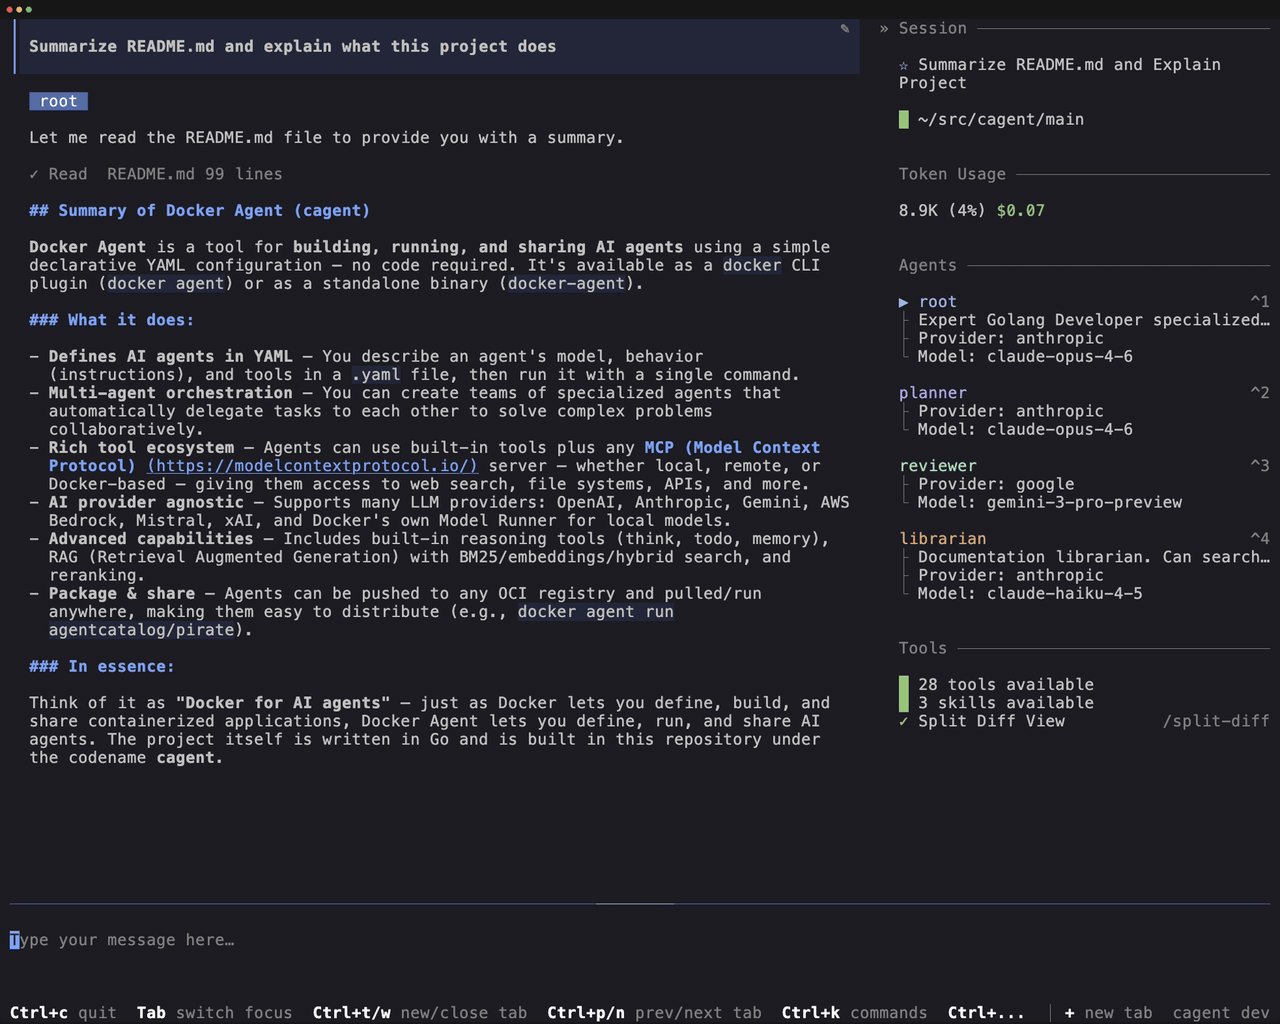
4.5Kdocker/docker-agent · GoDocker Agent is a tool for building, running, and sharing AI agents using a declarative YAML config, with built-in tools and multi-agent orchestration — no code required.
- 70

m_flow
4.5KFlowElement-xinliuyuansu/m_flow · PythonM-flow is a bio-inspired cognitive memory engine that acts as a new paradigm for Graph RAG: instead of just retrieving similar text chunks, it builds a graph of memories and scores answers by the strongest chain of evidence connecting the query to the content, the way human recall works.
- 71

memory-lancedb-pro
4.5KCortexReach/memory-lancedb-pro · JavaScriptIt is a LanceDB-backed memory plugin for OpenClaw agents that stores preferences, decisions, and project context, then auto-recalls them in future sessions instead of letting the agent forget everything between chats.
- 72
mgrep
4.4Kmixedbread-ai/mgrep · TypeScriptmgrep is a CLI tool that lets you semantically search your code, PDFs, images, and text using natural language, instead of relying on exact grep-style patterns.
- 73
DigUp
4.3KARahim3/DigUp · SwiftDigUp is a free, open-source macOS menu bar app that lets you search the files on your Mac by what's actually in them — photos, PDFs, documents, recordings, videos and code — using Google DeepMind's EmbeddingGemma 2 model running entirely on-device.
- 74
ragent
4.3Knageoffer/ragent · JavaRagent is a production-grade Java platform for Agentic RAG, covering the full chain from document ingestion to intelligent Q&A — including hybrid retrieval, query rewriting, intent recognition, session memory, MCP tool calling and deep thinking.
- 75
agentic-rag-for-dummies
4.3KGiovanniPasq/agentic-rag-for-dummies · Jupyter NotebookIt is a learning project and modular codebase that shows how to build an Agentic RAG (Retrieval-Augmented Generation) system using LangGraph, including conversation memory and human-in-the-loop query clarification.
- 76

Hyper-Extract
4.2Kyifanfeng97/Hyper-Extract · PythonHyper-Extract is a CLI tool that turns unstructured documents (PDFs, Word, text, etc.) into structured knowledge — chunk corpora, lists, graphs, hypergraphs, and spatio-temporal graphs — using LLMs, all from a single command.
- 77

lap
3.9Kjulyx10/lap · VueLap is an open-source, local-first photo manager for macOS, Windows, and Linux that lets you browse family albums, find old photos quickly, and organize large personal media libraries entirely offline.
- 78
lean-ctx
3.9Kyvgude/lean-ctx · RustLeanCTX is a 'Context Gateway' that runs locally alongside your AI coding agent, deciding what context the model actually sees, compressing it, and tracking the cost and outcome of that work.
- 79
SimpleMem
3.8Kaiming-lab/SimpleMem · PythonSimpleMem is a lifelong memory stack for LLM agents that stores, compresses, and retrieves long-term memories across text, image, audio, and video, so agents keep context without reprocessing redundant history.
- 80
heartlib
3.8KHeartMuLa/heartlib · PythonHeartMuLa is a family of open-source music foundation models for generating music from lyrics and tags, shipped together with codec, transcription and audio-text retrieval companion models.
- 81

goclaw
3.7Knextlevelbuilder/goclaw · GoGoClaw is a multi-tenant AI agent gateway/platform written in Go that connects 20+ LLM providers to 7 messaging channels, letting you deploy and orchestrate teams of AI agents at scale with production-grade security.
- 82
vault-ai
3.4Kpashpashpash/vault-ai · JavaScriptOP Vault gives ChatGPT long-term memory over your own documents: you upload a knowledge base of books, letters or PDFs and ask questions about their contents, powered by OpenAI and the Pinecone vector database.
- 83
jevgrep
2.8Kdzhng/jevgrep · TypeScriptjevgrep (the jg CLI) lets coding agents find relevant code by describing what it does in a question, instead of searching for exact text or paths. It uses an engine called Jev to judge relevance across folders, files, and declarations and returns reading leads plus verbatim source excerpts to stdout.
- 84
hotdata-cli
1.8Khotdata-dev/hotdata-cli · RustHotdata CLI is a command-line client that lets you query, search, and join data from one place — external databases, APIs, cloud storage, Iceberg catalogs, and uploaded files — using plain SQL and a handful of commands.
- 85
WeMM-Embedding
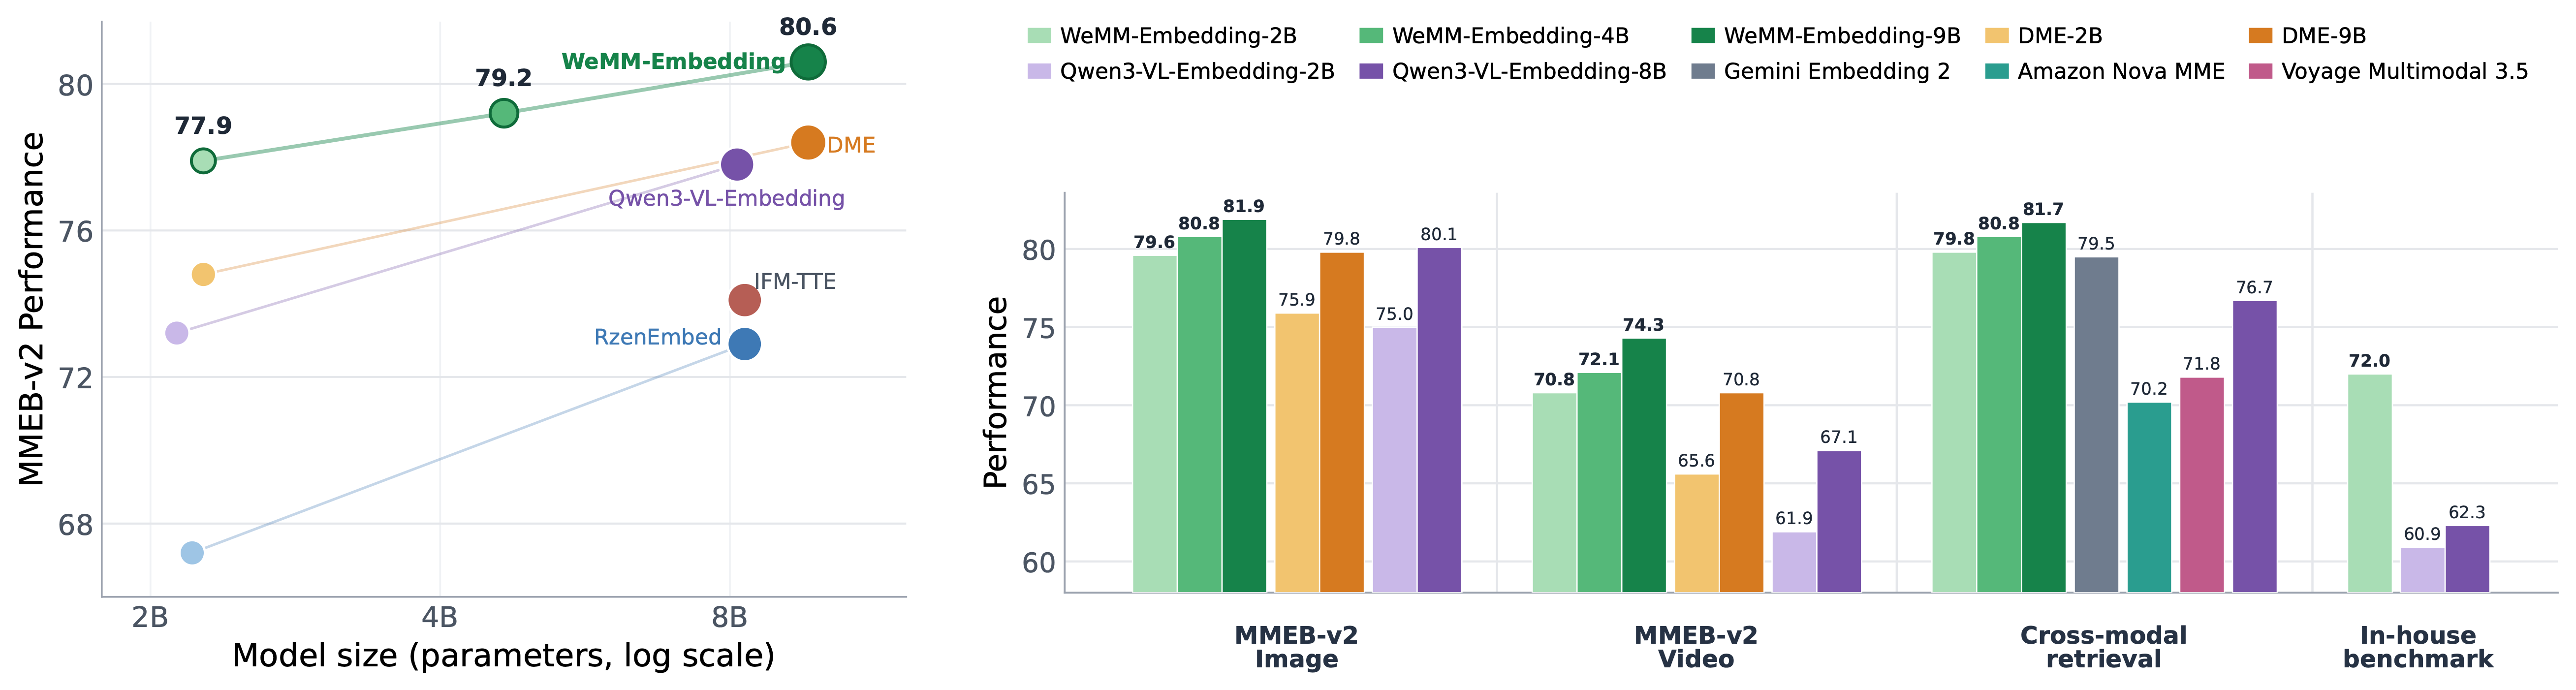
1.8KTencent/WeMM-Embedding · PythonWeMM-Embedding is a family of multimodal embedding models (2B, 4B, 9B) built by the WeChat Vision Team at Tencent that produce unified embeddings for text, images, videos, visual documents, and interleaved multimodal inputs for search and retrieval tasks.
- 86
open-glean
1.6Khydra-db/open-glean · TypeScriptOpen Glean is an open-source AI workspace built on Hydra DB: a 'second brain' you ask questions across your memories, files, and connected apps, with answers written from retrieved context and cited sources.
- 87

nautilus-compass
1.3Kchunxiaoxx/nautilus-compass · Pythonnautilus-compass is an open-source memory and reliability layer for AI coding agents: it gives them long-term memory, catches cases where the agent ignores recalled rules (drift detection), and ships its own benchmark suite to verify the claims independently.
- 88

fastembed-rs
1Kanush008/fastembed-rs · RustA Rust library that generates vector embeddings and reranks results entirely locally — no external API calls. It covers dense and sparse text embeddings, image embeddings, multimodal models, and rerankers.
- 89
XRAG
807DocAILab/XRAG · PythonXRAG is a benchmarking framework that dissects and evaluates the foundational components of Retrieval-Augmented Generation (RAG) systems, such as retrievers, embeddings, and LLMs, to show how different configurations affect overall RAG performance.
- 90
laya
704aayushch/laya · PythonLaya is a local-first AI notification command center that aggregates Slack, Gmail, GitHub, Jira, Notion, Outlook and Calendar notifications, processes them with local LLMs (Ollama/LM Studio) or your own cloud API keys, and prepares ready-to-approve Action Cards before you even open the notification.
- 91
SkillCorpus
686EverMind-AI/SkillCorpus · PythonSkillCorpus is EverMind's open-source pipeline that aggregates scattered SKILL.md files from public repos, applies safety/license/quality gates, and exports a curated, retrieval-ready corpus plus two fine-tuned retrieval models so agents can fetch the right skill at answer time.
- 92

Athena-Public
615winstonkoh87/Athena-Public · PythonAthena is a local-first memory layer for AI coding agents: it stores your working context as plain Markdown files on your own disk so any model or IDE can pick up where the last one left off.
- 93
memcode
603memcode-in/memcode · TypeScriptMemCode is memory infrastructure for AI: it gives agents, copilots, applications and workflows persistent memory that survives sessions, context windows, and even model changes.
- 94
create-photo-flipbook-ui
530HaichaoLihc/create-photo-flipbook-ui · JavaScriptA Codex skill that turns a folder of user photos into a working photobook website, using a bundled 2D HTML flipbook runtime plus optional 3D Three.js/WebGL template examples.
- 95
witchcraft
524dropbox/witchcraft · RustWitchcraft (formerly Rust-Warp) is a from-scratch, safe-Rust reimplementation of Stanford's XTR-Warp semantic search engine that stores its index in a single-file SQLite database, built for fast, fully local client-side search.
- 96
SCM
486allenv0/SCM · TypeScriptSCM (Screen Memories) is a macOS desktop app that runs deep AI search locally over every photo and every video frame in a chosen folder, letting you search by meaning, on-screen text, or spoken dialogue, all without the cloud.
- 97
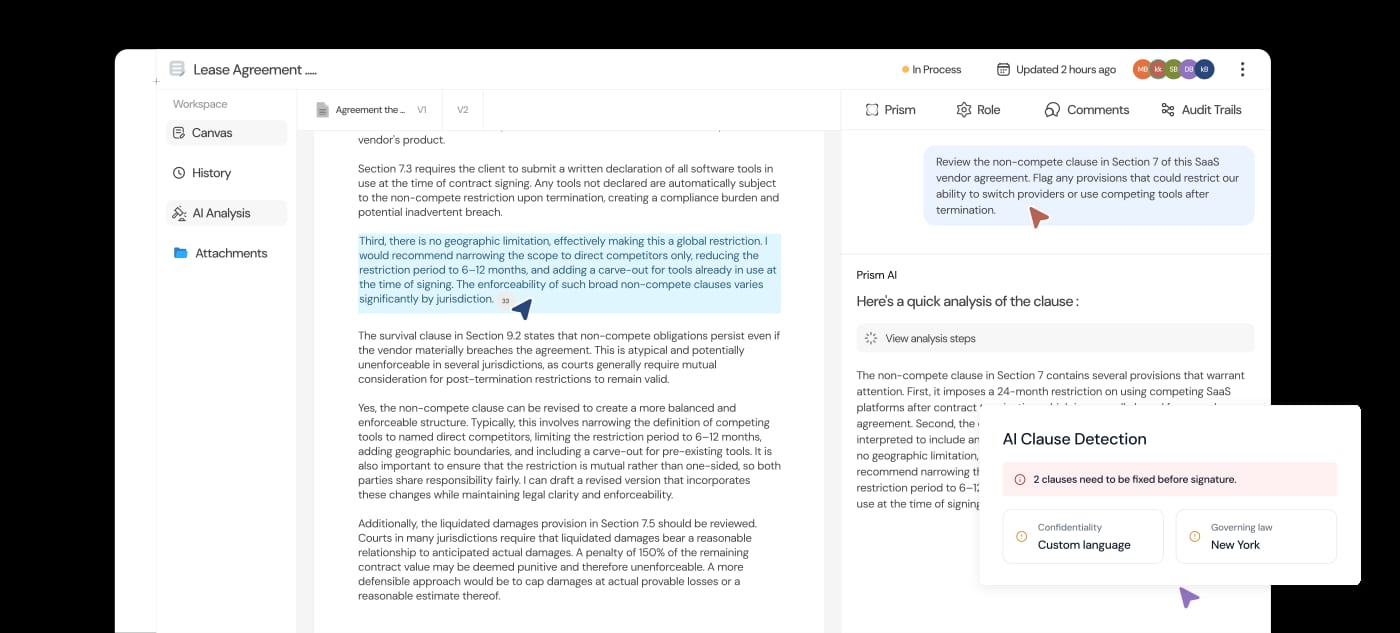
Prism-Legal-OS
334FuturixAI-and-Quantum-Works/Prism-Legal-OS · TypeScriptPrism is an open-source legal OS for contract drafting, review, legal research, and litigation management, with an AI assistant called Luna built in.
- 98
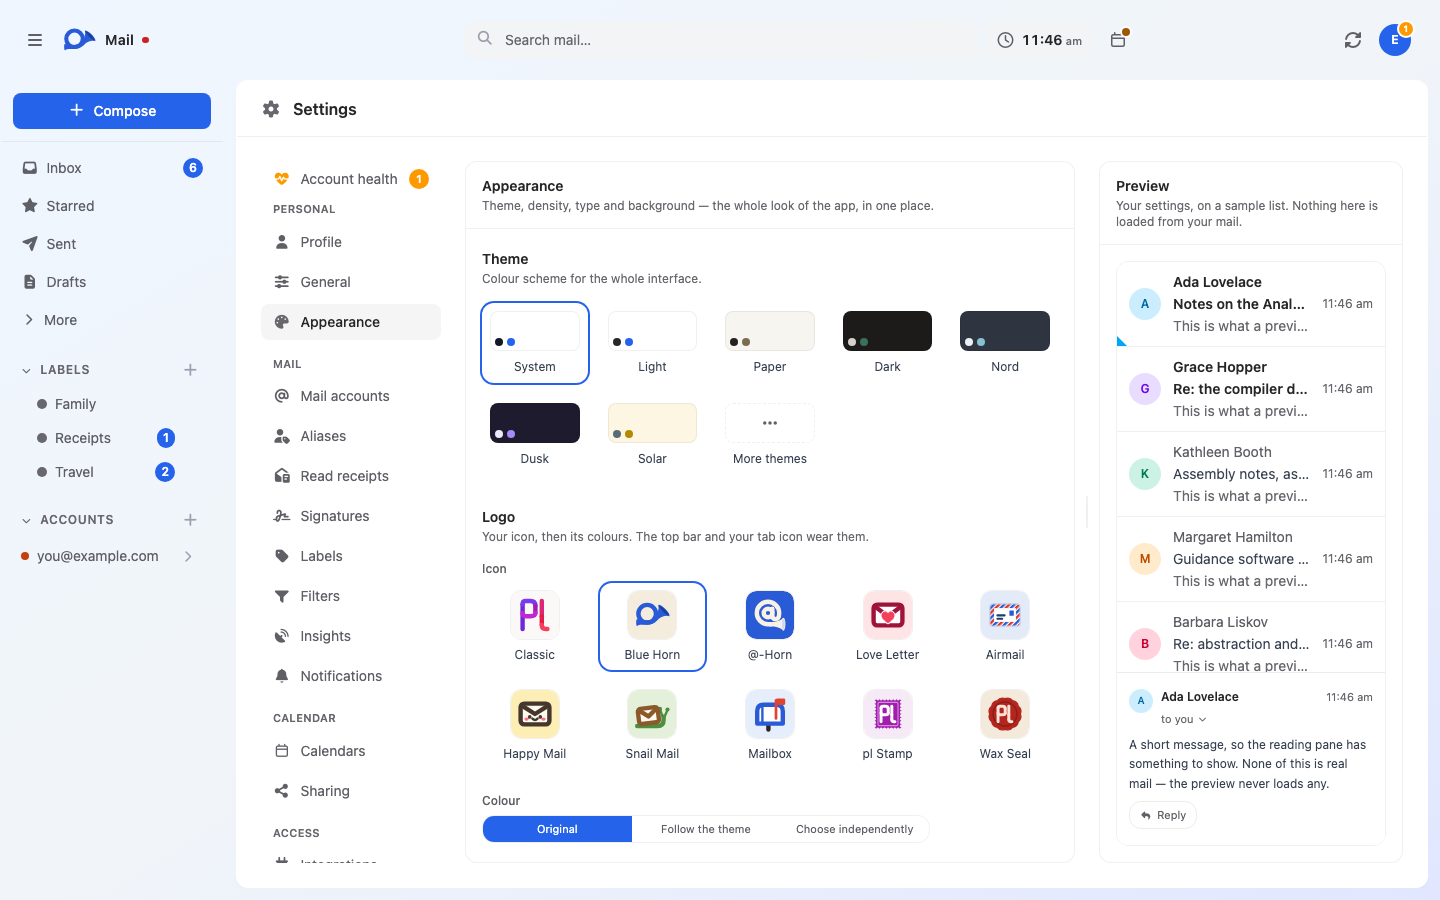
pl_mail
331karatektus/pl_mail · PHPplMail is a self-hosted, Gmail-style mail client that connects to IMAP, Gmail, and Outlook mailboxes you already have, syncs them into your own PostgreSQL database, and gives you one inbox, search box, and set of labels in the browser.
- 99
sgrep
307context-dot-dev/sgrep · Pythonsgrep is a local search tool that finds code and document passages using plain-English intent, combining semantic embeddings with ripgrep-style lexical matching, without any account or hosted index.
- 100
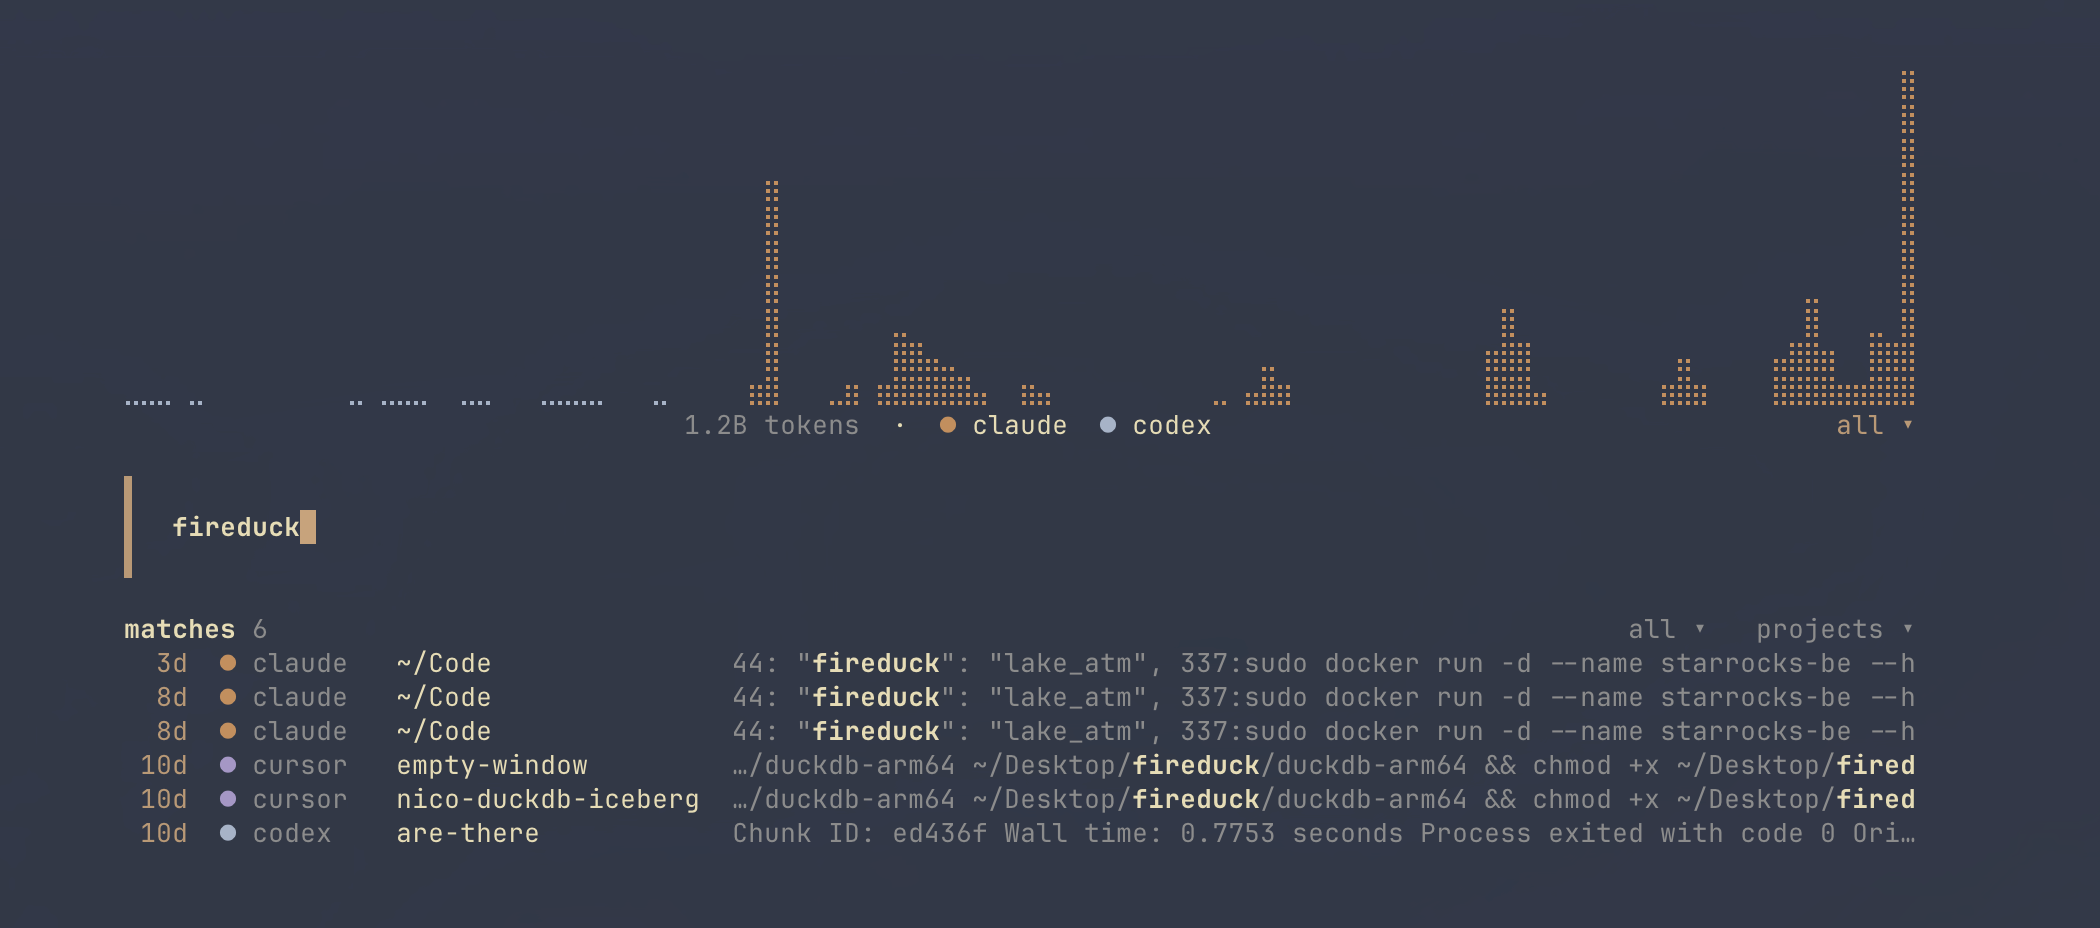
memex
266nicosuave/memex · RustMemex indexes your local coding-agent conversations (Claude Code, Codex, Cursor, and more) so you can search past work, read original transcripts, and resume sessions in the original tool.

Showing the 100 most-starred of 114. See every one in the catalog.
Related topics
Often tagged together