Topics / #diffusion
Diffusion projects on GitHub
Diffusion models that generate images and video from noise and prompts.
As of , the most-starred Diffusion projects on GitHub are stable-diffusion-webui (165.1K stars), ComfyUI (139.7K stars) and stable-diffusion (73.5K stars). GitHub.Locker tracks 45 Diffusion repositories with 977K stars combined. The fastest-growing on October 19 was ComfyUI, with +1.2K stars in a day.
Hot right now
Most stars gained in a day · Oct 19
 +1.2K
ComfyUI
Comfy-Org/ComfyUI · ★ 139.7KComfyUI is a node-based graph interface for building and running diffusion model workflows: image, video, 3D, and audio generation, editing, and more, all without writing code.
 +164
sglang
sgl-project/sglang · ★ 37.5KSGLang is a high-performance serving framework for large language models and multimodal models, built to deliver low-latency, high-throughput inference from a single GPU up to large distributed clusters.
 +59
UniMate
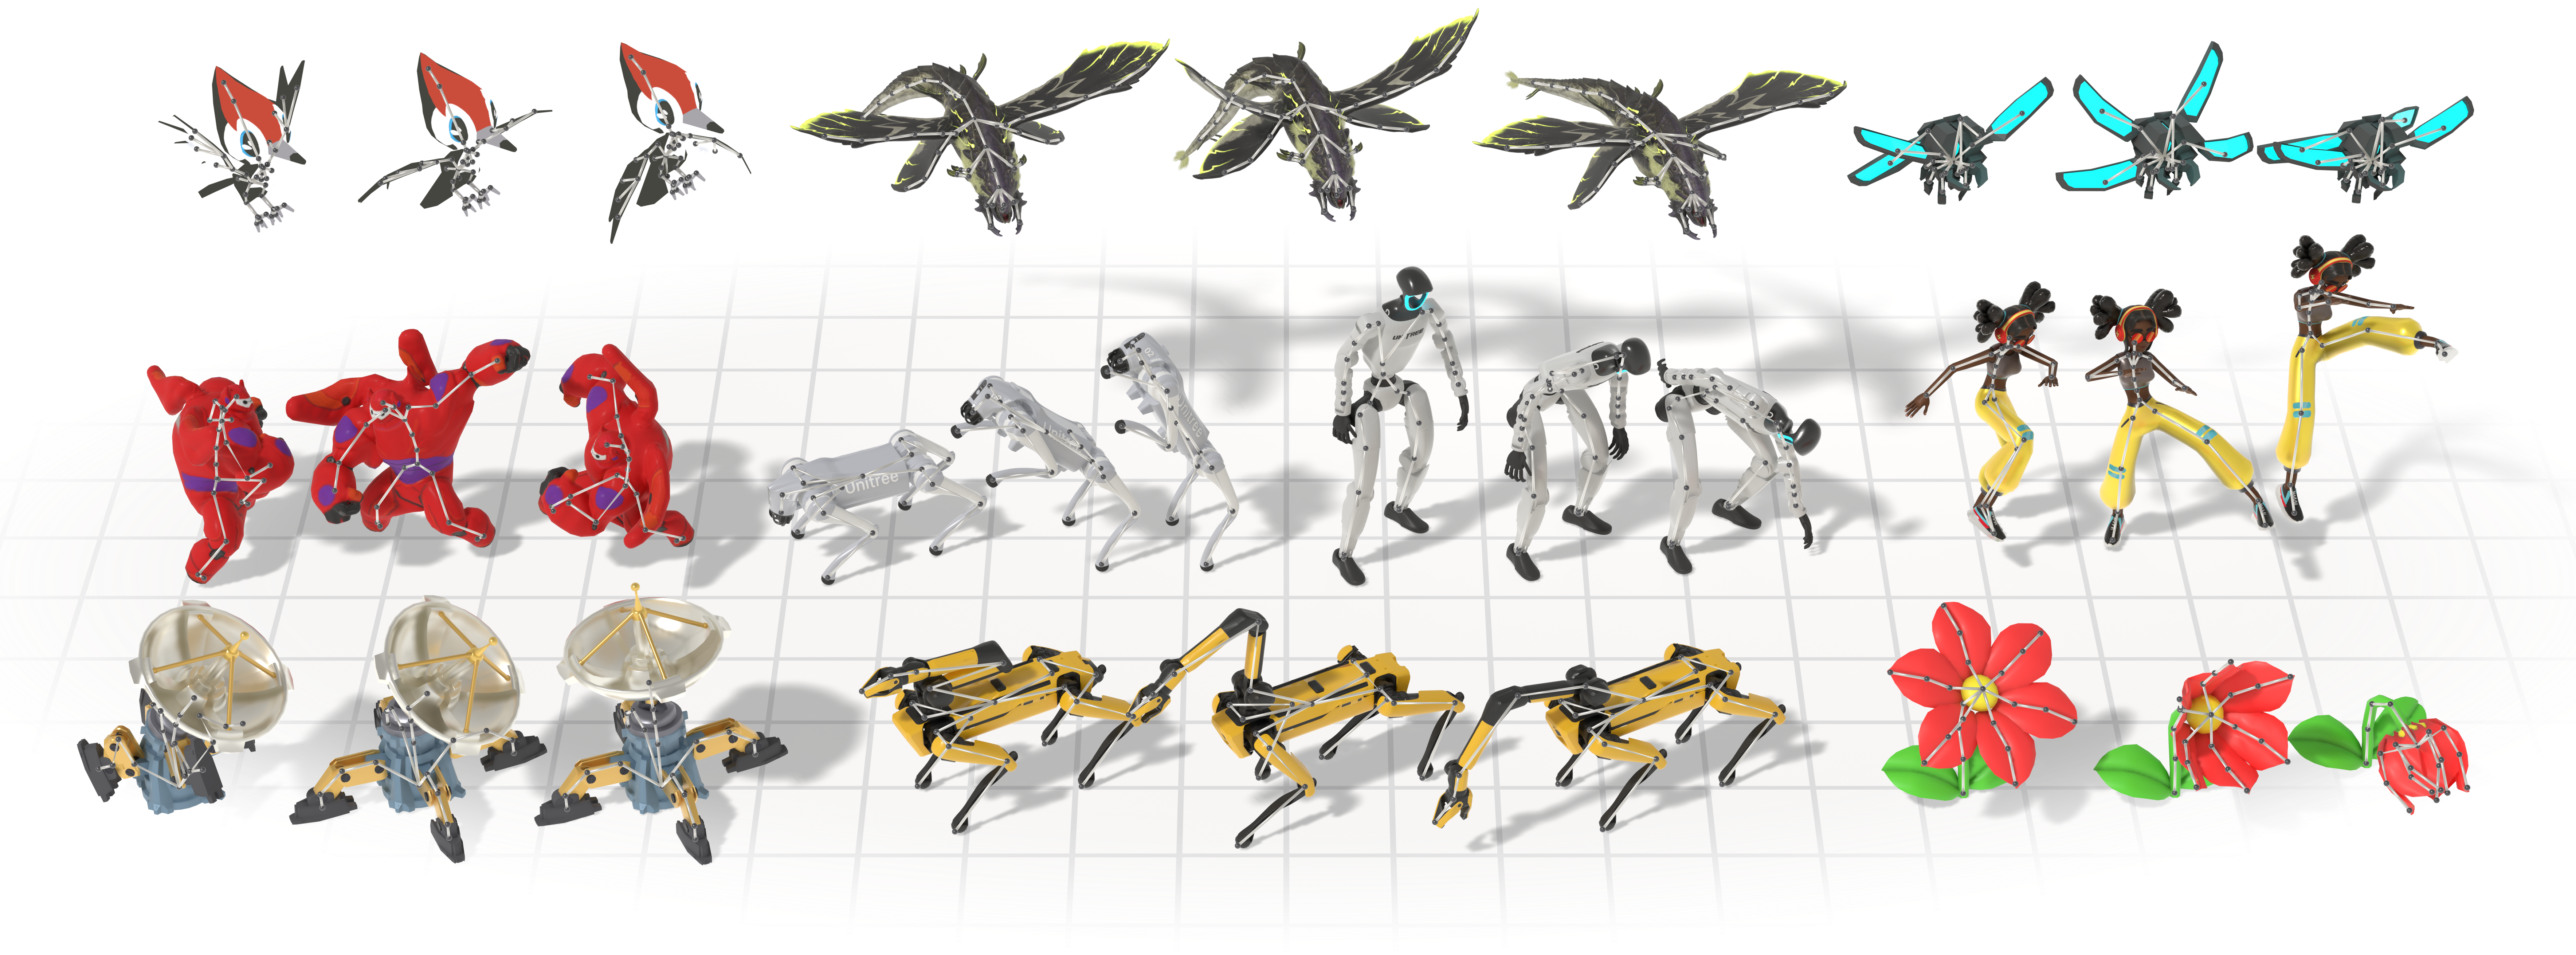
Friedrich-M/UniMate · ★ 2KUniMate is the official code release for a SIGGRAPH Asia 2026 paper: a single diffusion/flow-matching model that generates motion for very different skeleton types (bipedal, quadrupedal, avian, marine, insectoid, serpentine, and even rigid articulated objects) from a rigged 3D asset plus a text prompt, without retraining per skeleton.
 +21
stable-diffusion-webui
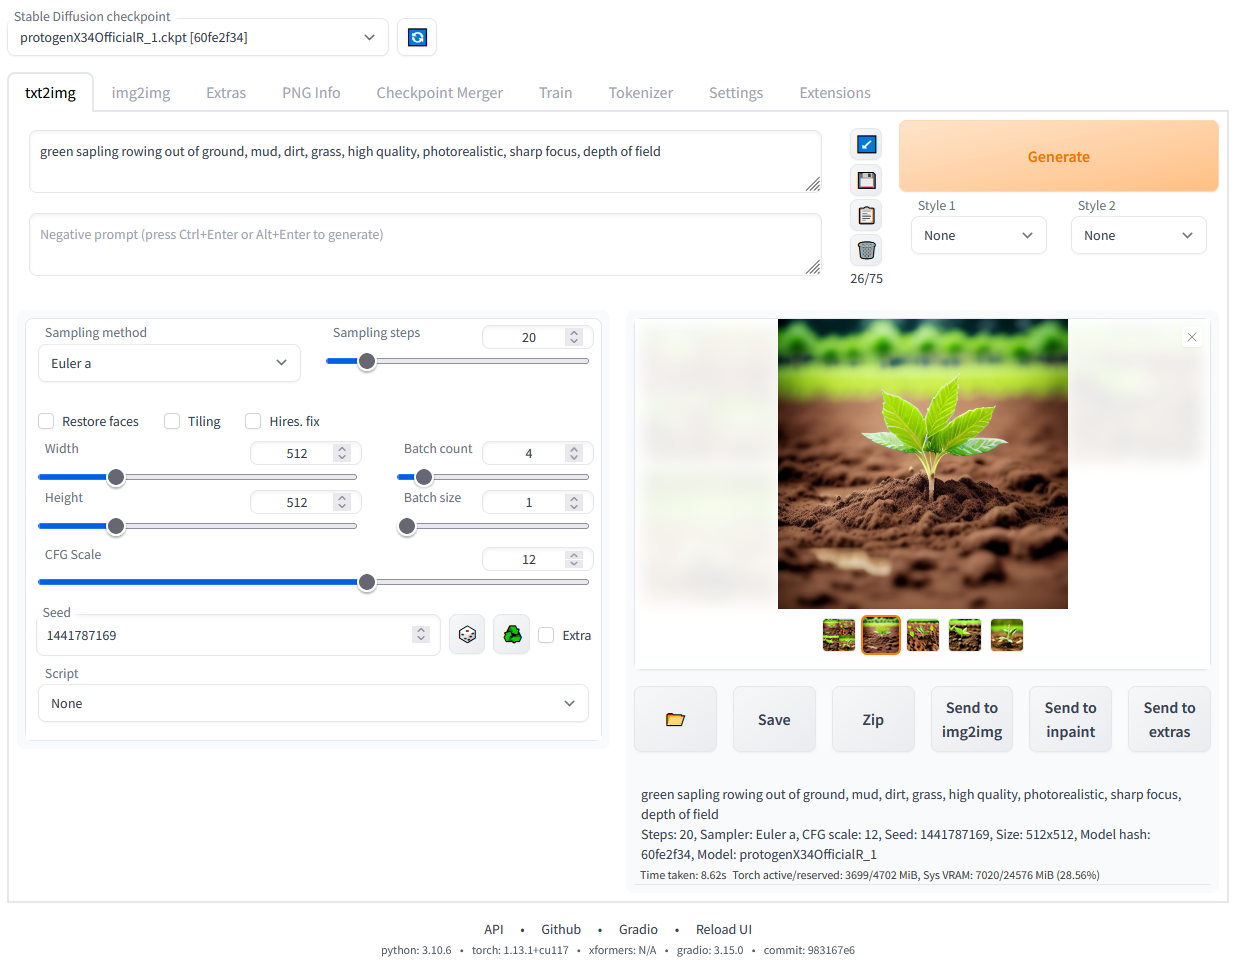
AUTOMATIC1111/stable-diffusion-webui · ★ 165.1KA browser-based interface for Stable Diffusion, built with the Gradio library, letting you generate and edit AI images (txt2img, img2img, inpainting, outpainting and more) on your own machine.
The all-time top
45 projects · by stars
- 165.1K#1 · AUTOMATIC1111/stable-diffusion-webui
stable-diffusion-webui
A browser-based interface for Stable Diffusion, built with the Gradio library, letting you generate and edit AI images (txt2img, img2img, inpainting, outpainting and more) on your own machine.
- 139.7K#2 · Comfy-Org/ComfyUI
ComfyUI
ComfyUI is a node-based graph interface for building and running diffusion model workflows: image, video, 3D, and audio generation, editing, and more, all without writing code.
- 73.5K
 #3 · CompVis/stable-diffusion
stable-diffusion
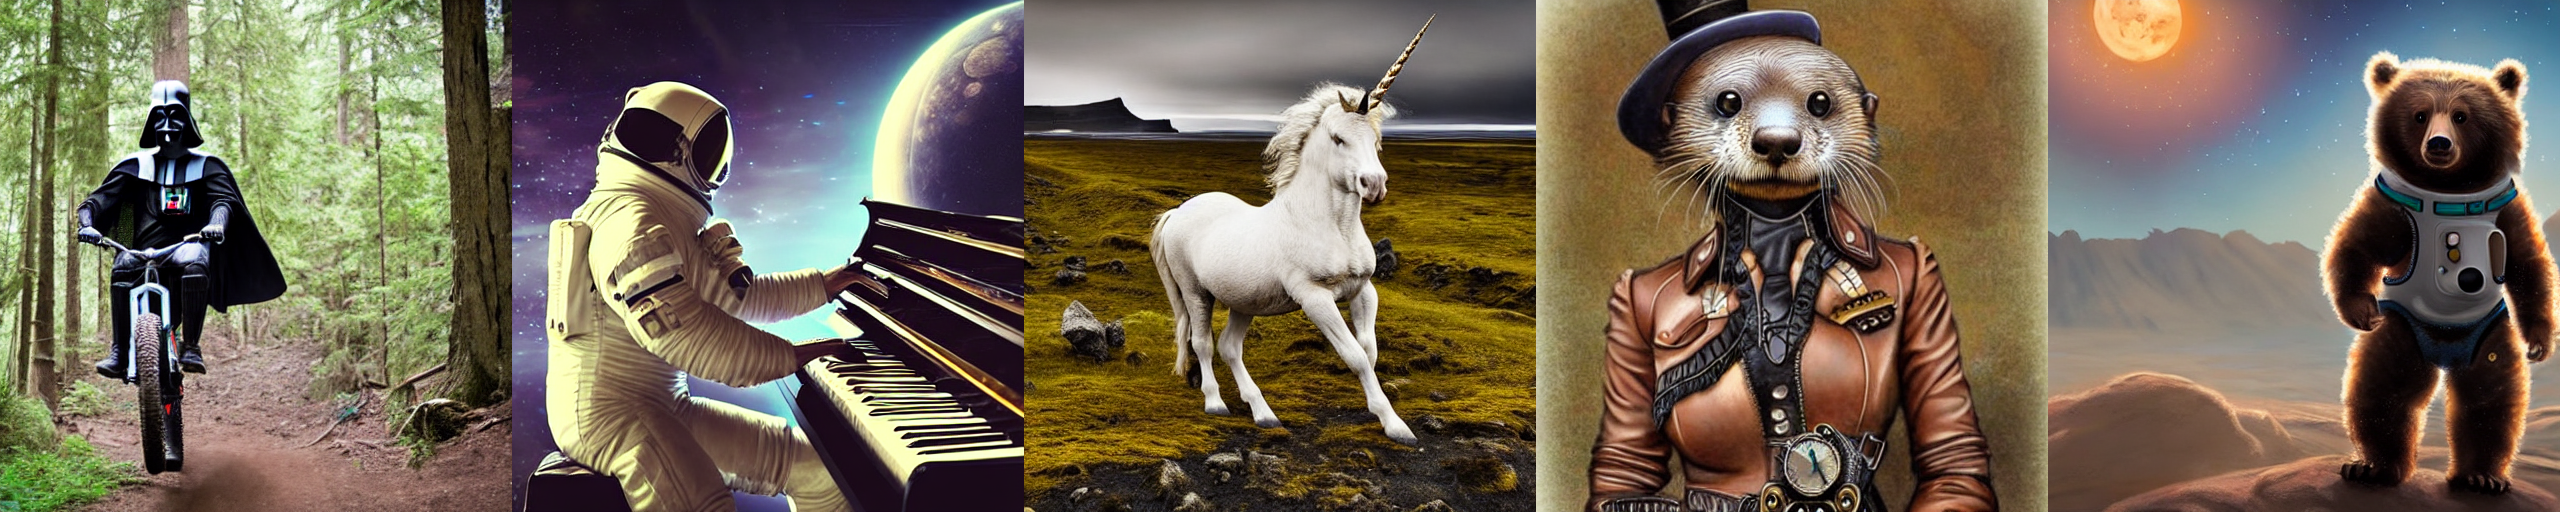
Stable Diffusion is a latent text-to-image diffusion model that generates images from text prompts, built by CompVis with Stability AI and Runway, based on the Latent Diffusion Models work from CVPR '22.
- 4
annotated_deep_learning_paper_implementations
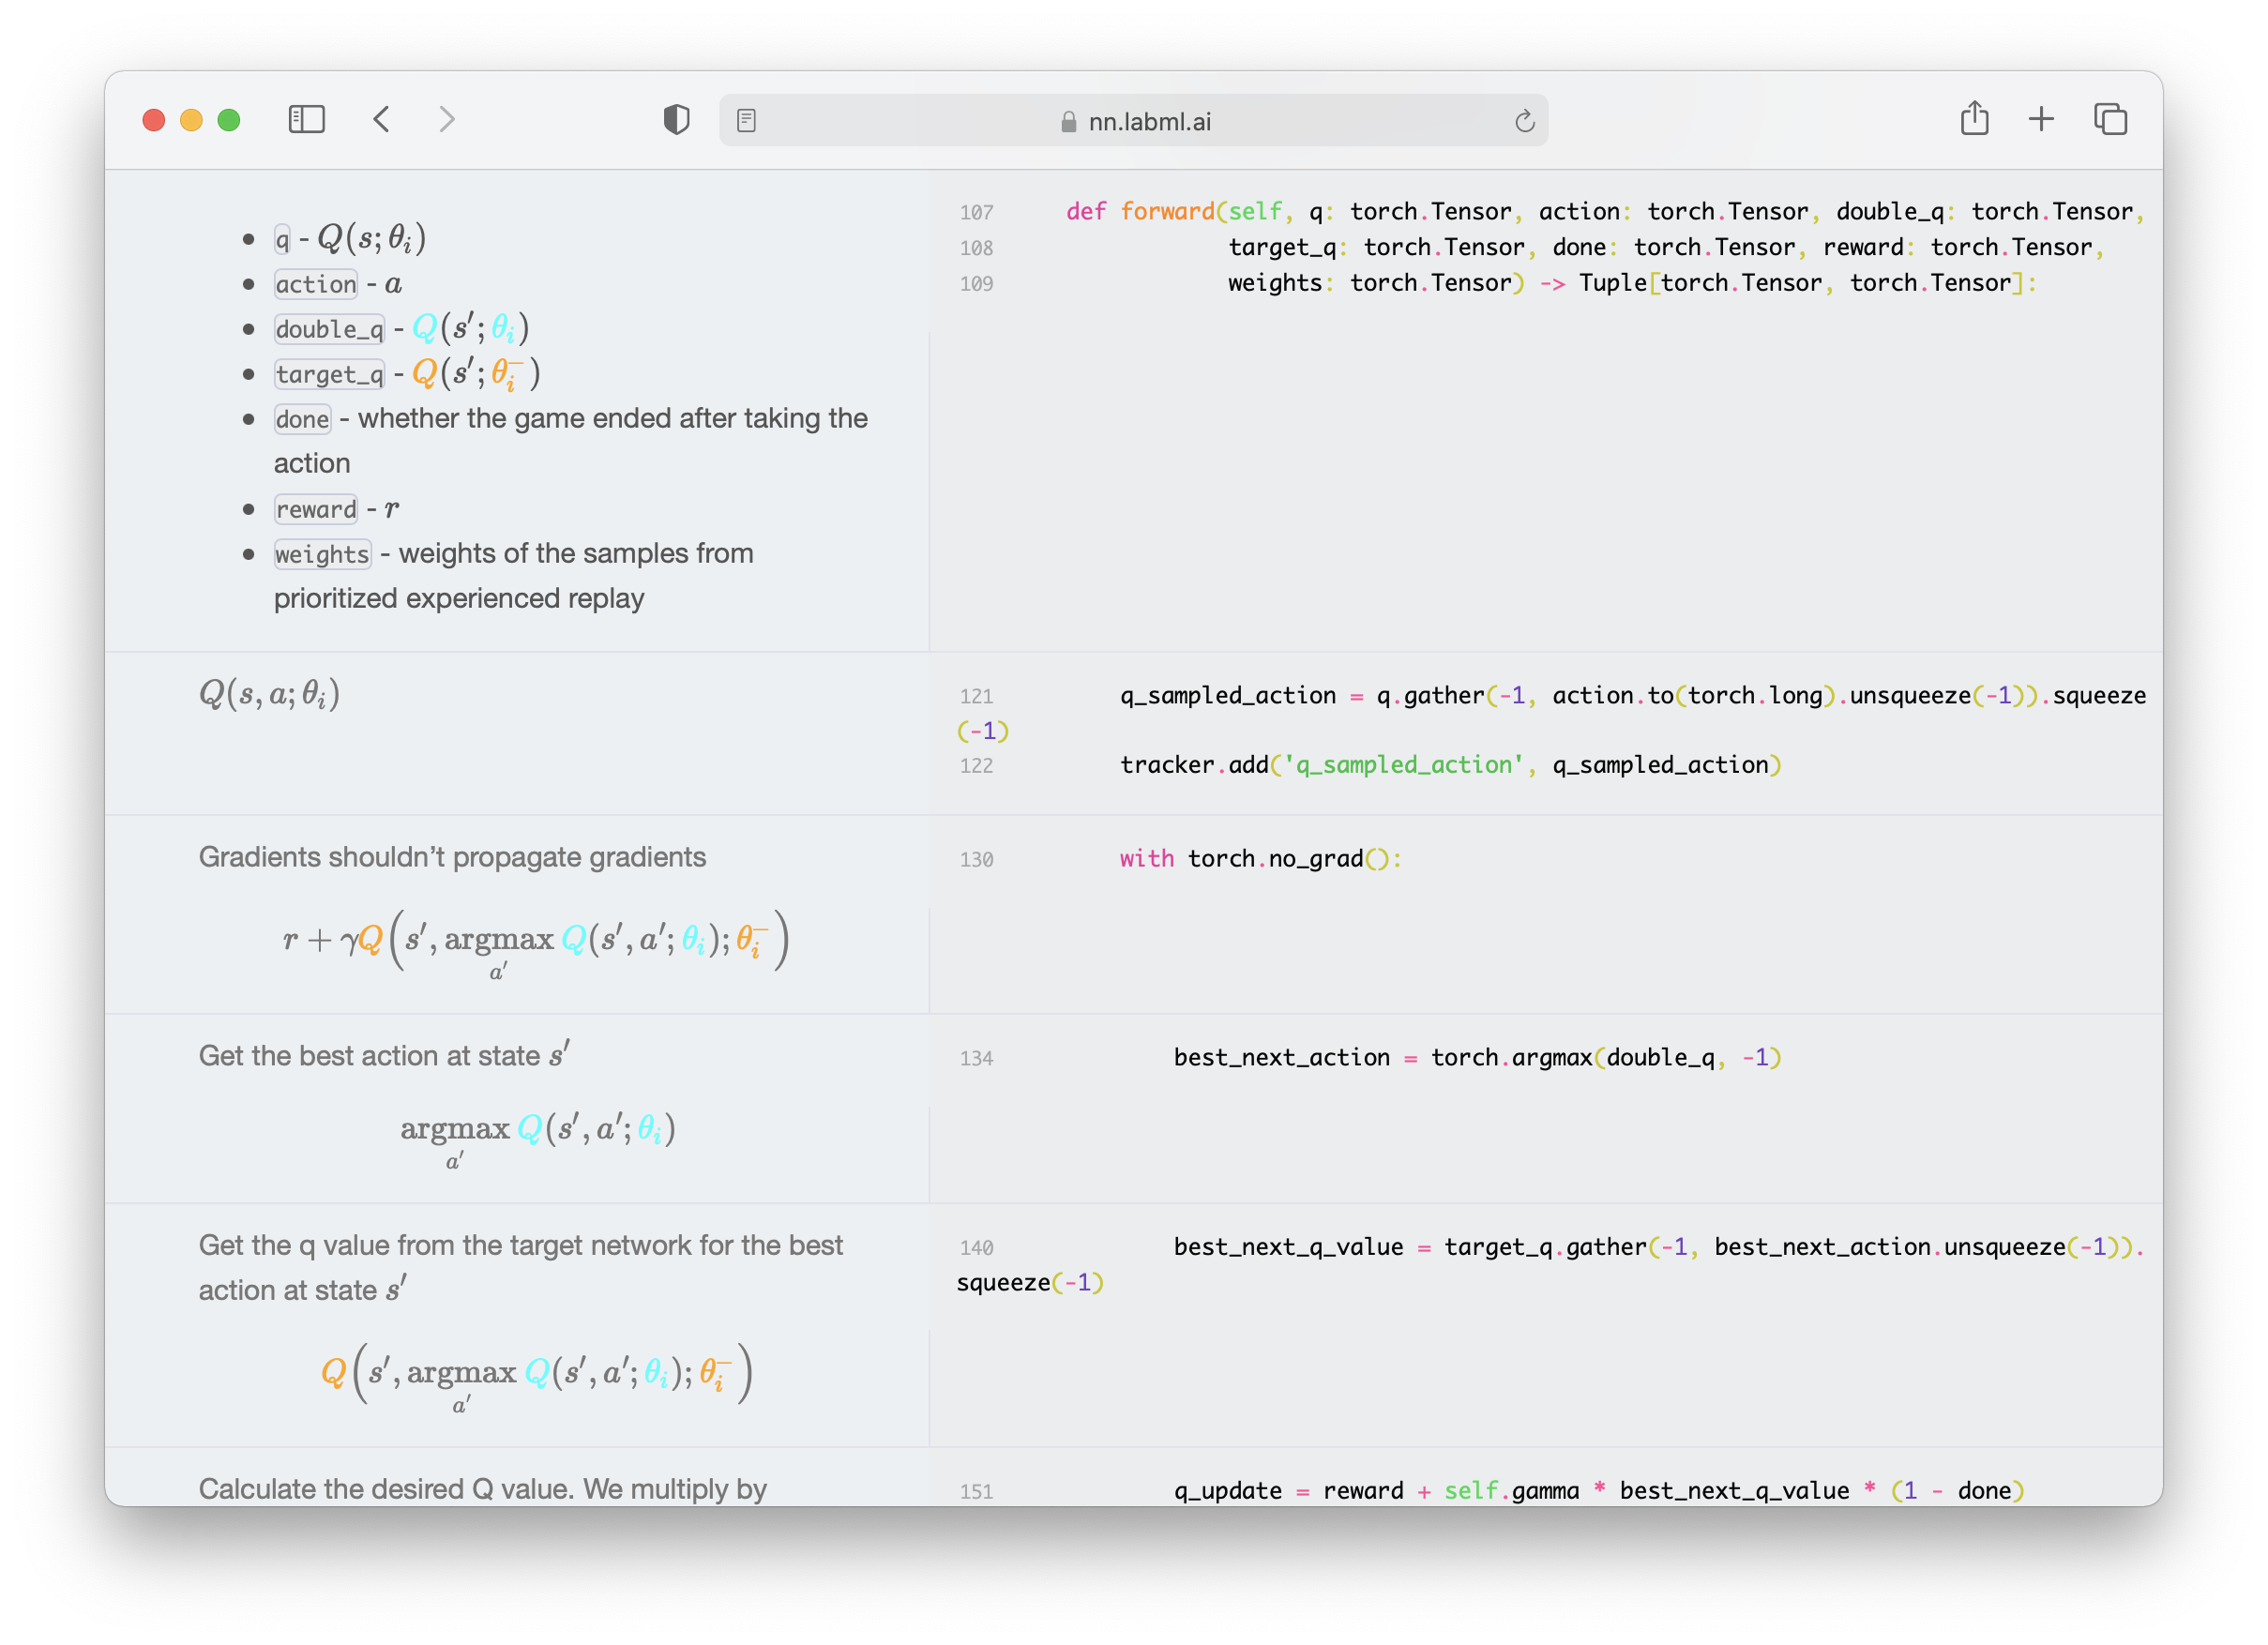
67.6Klabmlai/annotated_deep_learning_paper_implementations · PythonA collection of 60+ PyTorch implementations of deep learning papers, each annotated with side-by-side explanatory notes so you can read the code and the math/explanation together.
- 5
VibeVoice
54.9Kmicrosoft/VibeVoice · PythonVibeVoice is Microsoft's family of open-source voice AI models covering text-to-speech and speech recognition: long-form multi-speaker TTS, real-time streaming TTS, and ASR built for hour-long recordings.
- 6
sglang
37.5Ksgl-project/sglang · PythonSGLang is a high-performance serving framework for large language models and multimodal models, built to deliver low-latency, high-throughput inference from a single GPU up to large distributed clusters.
- 7
diffusers
34.8Khuggingface/diffusers · PythonDiffusers is Hugging Face's Python library for state-of-the-art pretrained diffusion models that generate images, audio, and even 3D molecule structures, all in PyTorch.
- 8
ControlNet
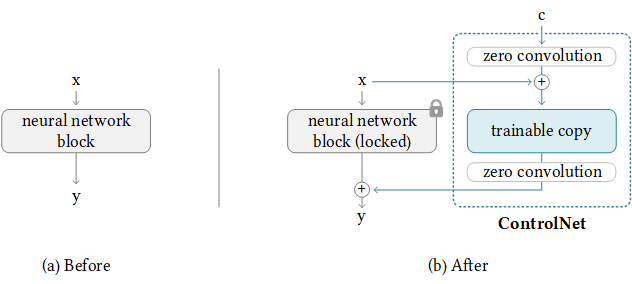
34.1Klllyasviel/ControlNet · PythonControlNet is a neural network structure that adds extra conditions to diffusion models like Stable Diffusion: instead of a text prompt alone, you steer generation with an edge map, depth map, pose skeleton or scribble. This repo is the official implementation.
- 9
so-vits-svc
28.1Ksvc-develop-team/so-vits-svc · PythonAn open-source AI singing voice conversion (SVC) framework: it trains PyTorch models that make one voice sing the lines of another, using SoftVC speech features fed into VITS with an NSF-HiFiGAN vocoder.
- 10

generative-models
27.3KStability-AI/generative-models · PythonThis is Stability AI's research codebase for a family of generative diffusion models, covering text-to-image (SDXL, SDXL-Turbo), image-to-video (Stable Video Diffusion), image-to-3D-video (SV3D), and video-to-4D (SV4D, SV4D 2.0) synthesis.
- 11
flux
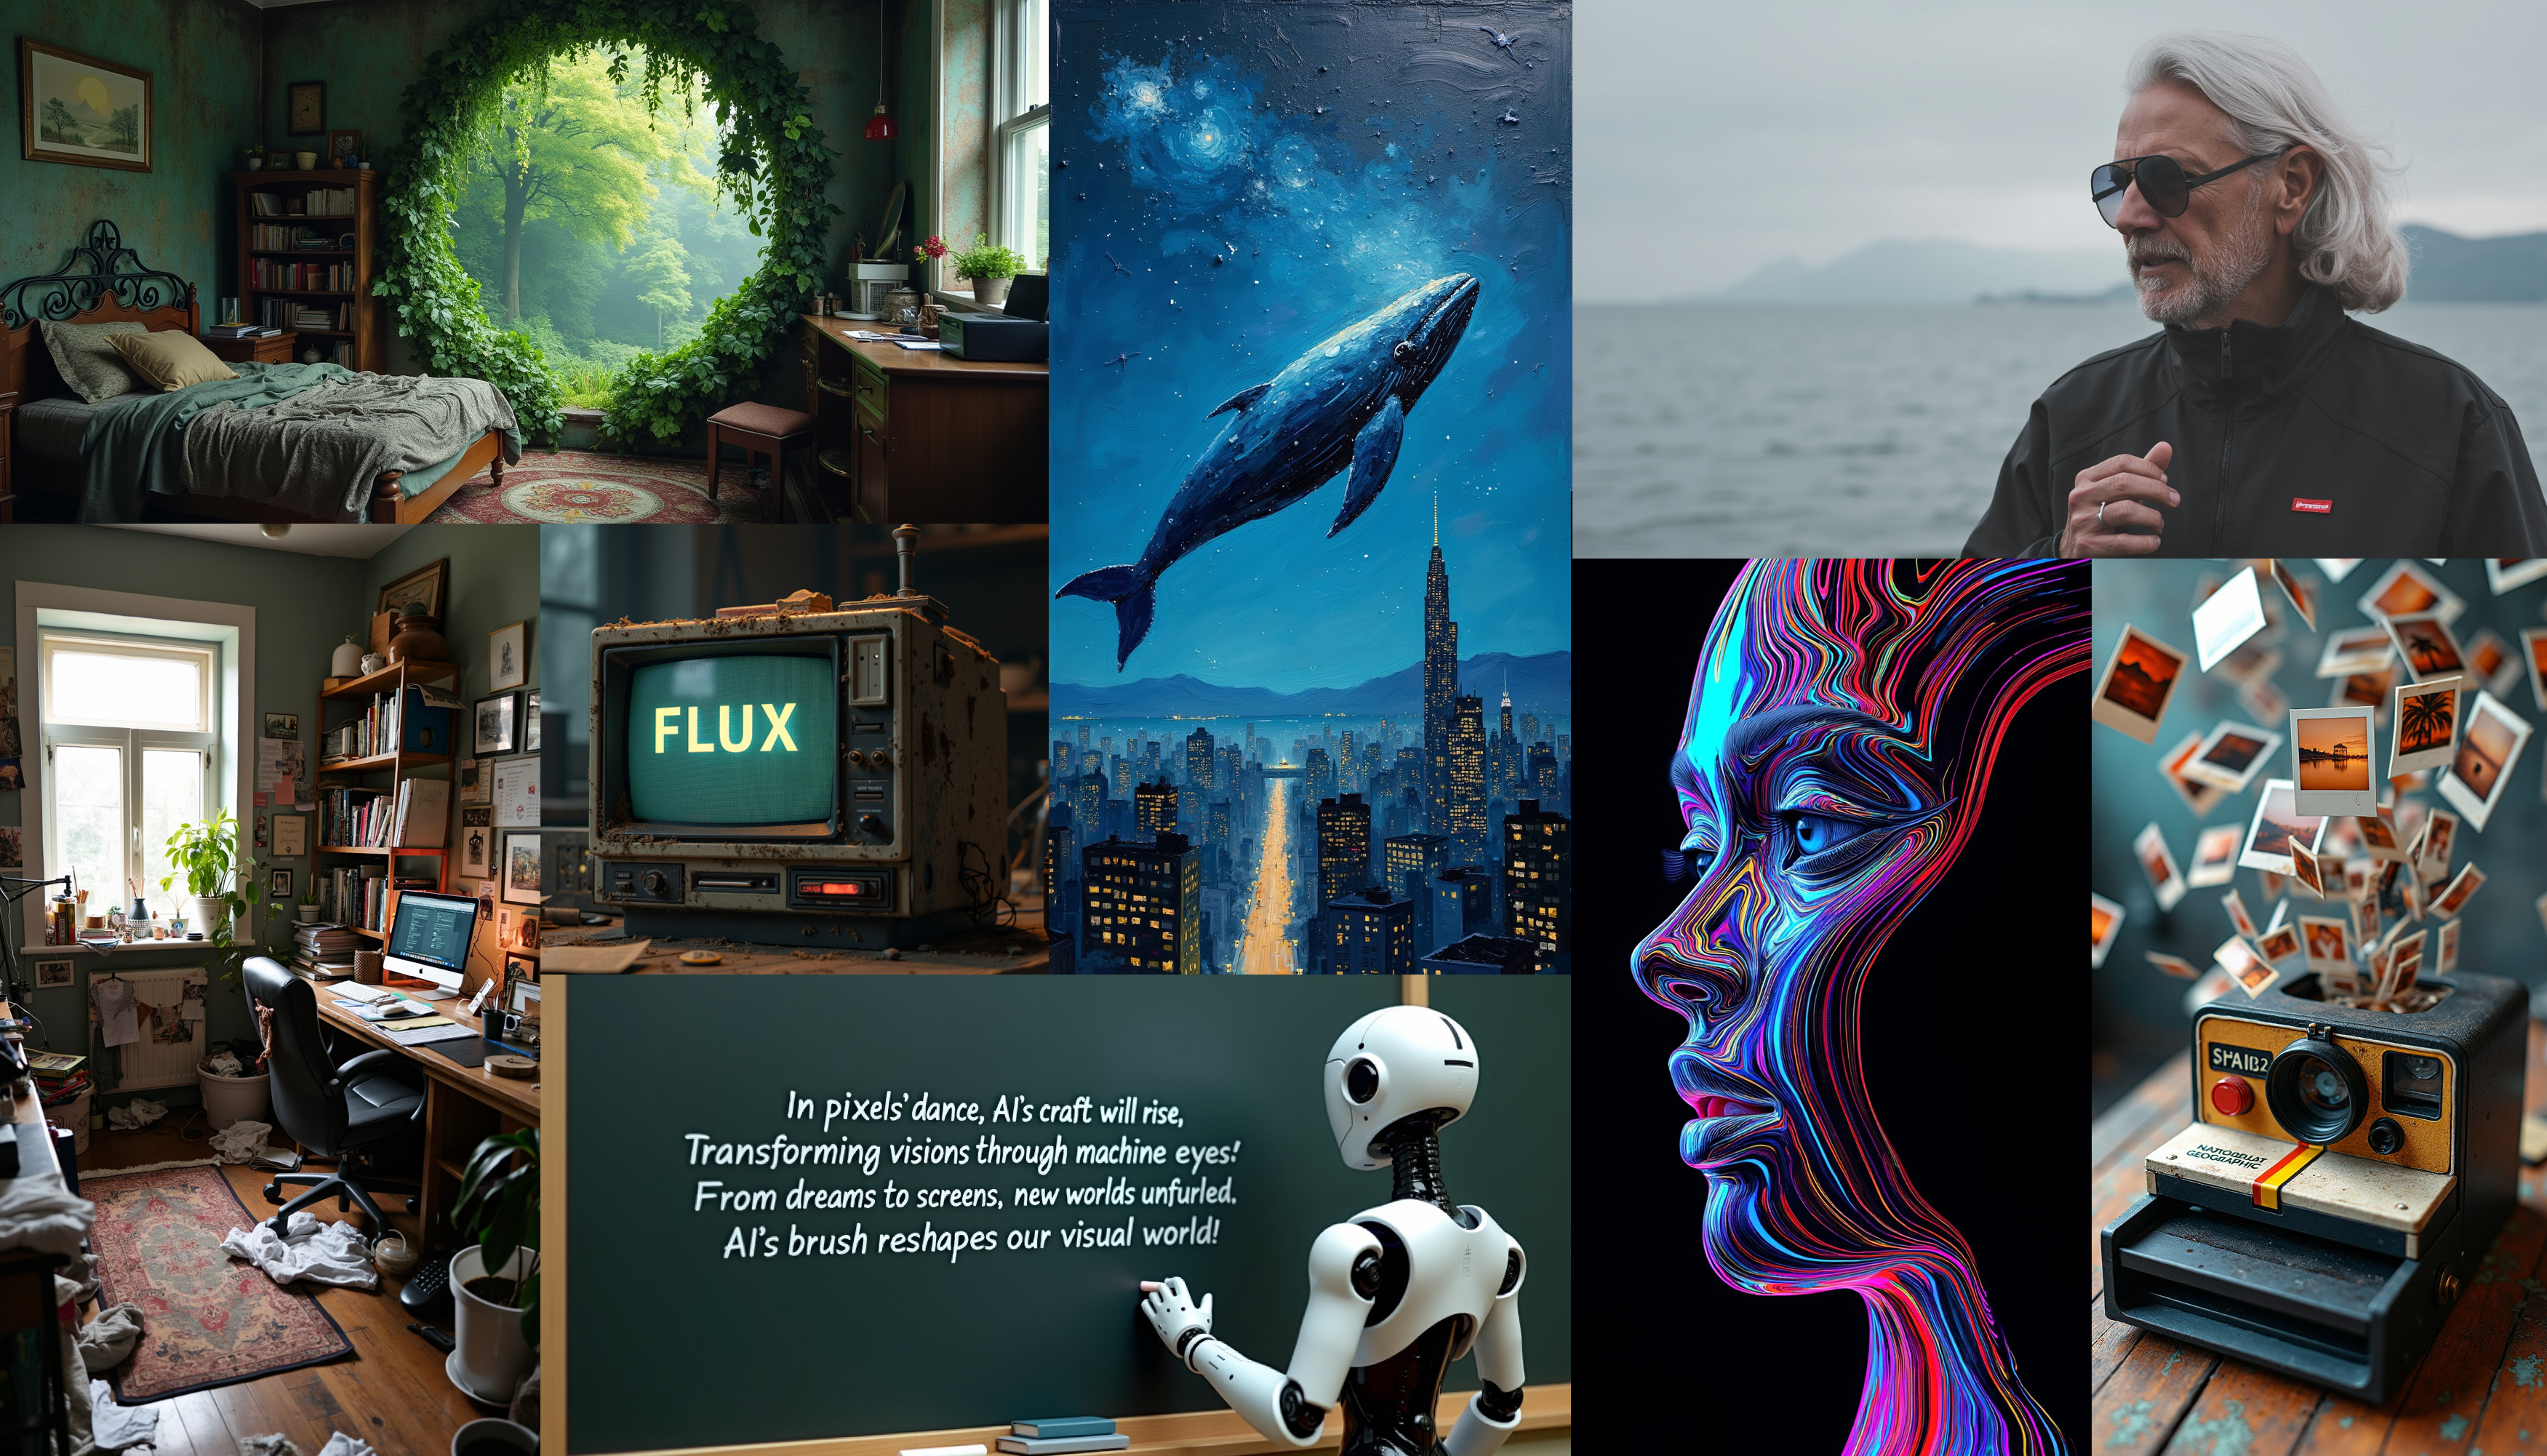
26Kblack-forest-labs/flux · PythonThis is Black Forest Labs' official inference repo for the FLUX.1 family of image generation and editing diffusion models, providing minimal code to run the open-weight models.
- 12
verl
23.9Kverl-project/verl · Pythonverl is a flexible, efficient and production-ready reinforcement learning training library for LLMs, initiated by ByteDance's Seed team and maintained by the community. It is the open-source version of the HybridFlow paper (EuroSys 2025).
- 13

IOPaint
23.3KSanster/IOPaint · PythonA free, open-source AI photo tool: it erases unwanted objects, defects, watermarks or people from pictures, and can replace or generate content with Stable Diffusion.
- 14

peft
21.8Khuggingface/peft · PythonHugging Face's library of Parameter-Efficient Fine-Tuning methods: you adapt a large pretrained model by training only a small number of extra parameters instead of all of them, which slashes compute and storage costs.
- 15

sd-webui-controlnet
17.8KMikubill/sd-webui-controlnet · PythonAn extension for AUTOMATIC1111's Stable Diffusion WebUI that adds ControlNet and other injection-based controls, guiding image generation with extra conditions like depth, poses or edges.
- 16
FramePack
17.3Klllyasviel/FramePack · PythonFramePack is a next-frame-section prediction neural network for video diffusion, shipped as the official desktop app that turns an image and a short text prompt into a progressively generated video.
- 17
leedl-tutorial
16.8Kdatawhalechina/leedl-tutorial · Jupyter NotebookA free Chinese-language deep learning tutorial (nicknamed the 'Apple Book') based on Prof. Li Hongyi's (Hung-yi Lee) 'Machine Learning' course, covering most major deep learning topics in detail.
- 18

F5-TTS
15.4KSWivid/F5-TTS · PythonF5-TTS is a text-to-speech system that generates fluent, faithful speech using flow matching with a Diffusion Transformer (ConvNeXt V2 backbone), and it supports cloning a speaker's voice from a short reference clip.
- 19

AI-Scientist
14.8KSakanaAI/AI-Scientist · Jupyter NotebookThe AI Scientist is a system from Sakana AI that lets Large Language Models conduct open-ended scientific research fully automatically: generating ideas, running experiments, and writing up results as papers.
- 20
DiffSynth-Studio
13.3Kmodelscope/DiffSynth-Studio · PythonDiffSynth-Studio is an open-source Diffusion model engine built and maintained by the ModelScope Community, covering image, video, and audio generation plus image quality metrics, with support for both inference and training.
- 21

stable-diffusion-webui-forge
13.1Klllyasviel/stable-diffusion-webui-forge · PythonStable Diffusion WebUI Forge is a platform built on top of Stable Diffusion WebUI (using Gradio) that adds GPU memory management and performance improvements for running Stable Diffusion image generation locally.
- 22
magic-animate
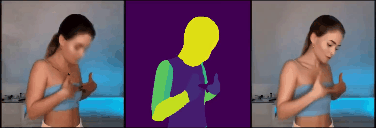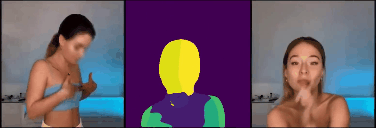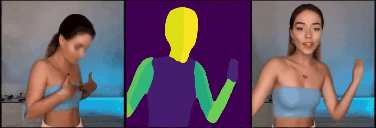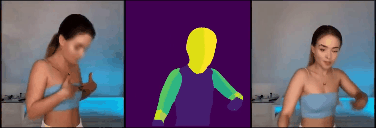
10.9Kmagic-research/magic-animate · PythonThis is the official codebase for 'MagicAnimate' (CVPR 2024), a diffusion-model method that animates a reference human image according to a motion sequence to produce temporally consistent video.
- 23
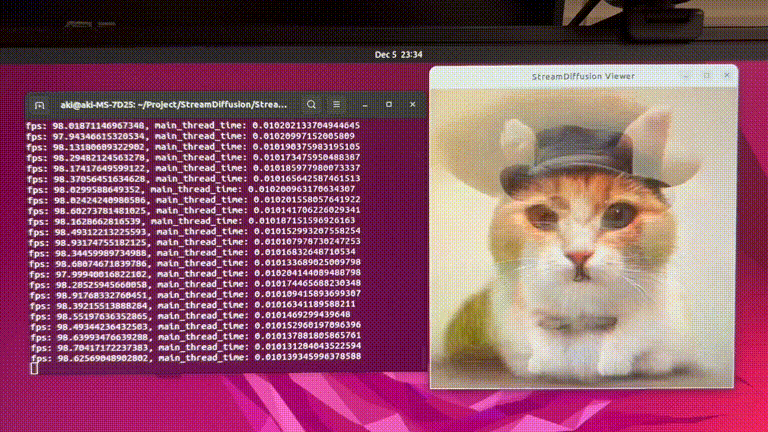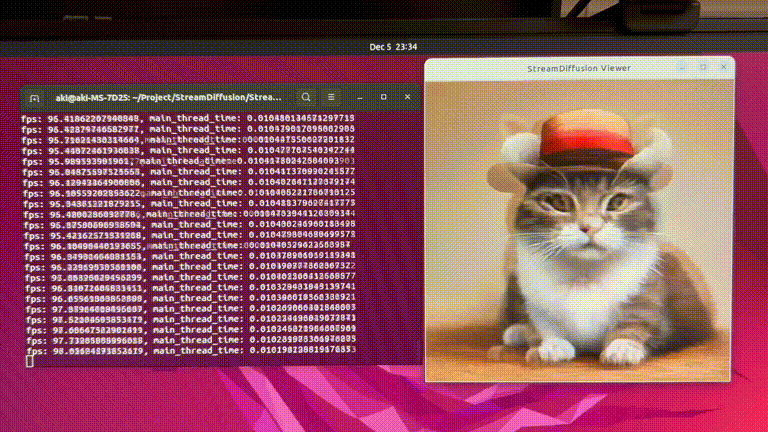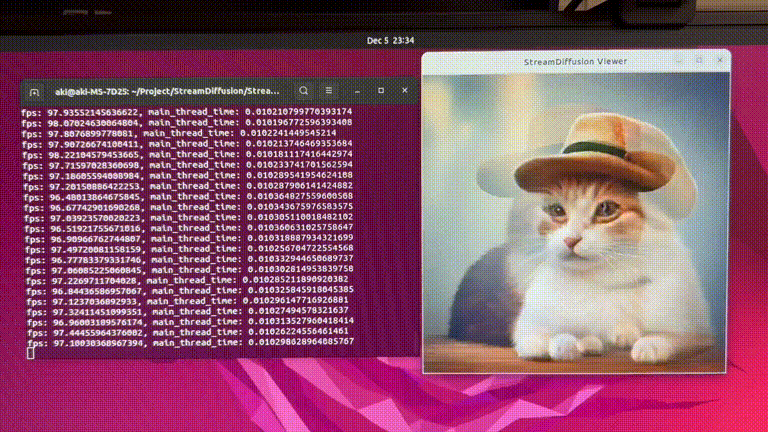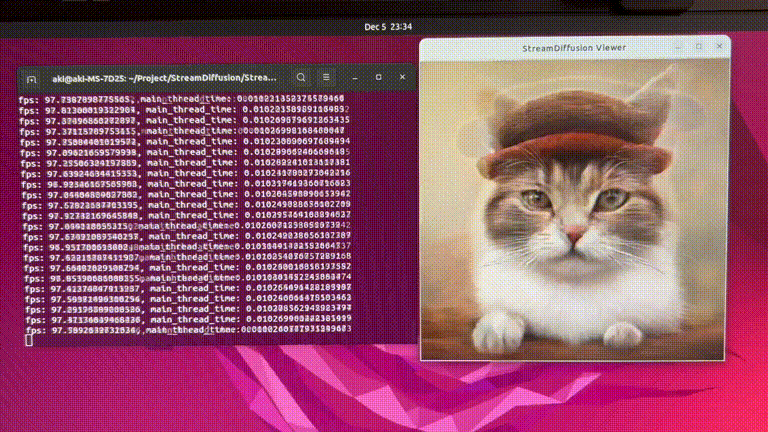
StreamDiffusion
10.8Kcumulo-autumn/StreamDiffusion · PythonStreamDiffusion is a pipeline-level library for real-time, interactive diffusion image generation, letting you turn text prompts or a live webcam/screen feed into generated images at high frame rates.
- 24
krita-ai-diffusion
10.7KAcly/krita-ai-diffusion · PythonA free, open-source Krita plugin that brings generative AI into painting and editing workflows: inpaint, outpaint, live-paint and upscale images with an optional text prompt, running on your own hardware.
- 25
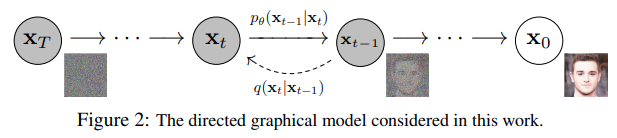
denoising-diffusion-pytorch
10.7Klucidrains/denoising-diffusion-pytorch · PythonA PyTorch implementation of the Denoising Diffusion Probabilistic Model (DDPM), a generative modeling approach the author positions as a possible rival to GANs.
- 26
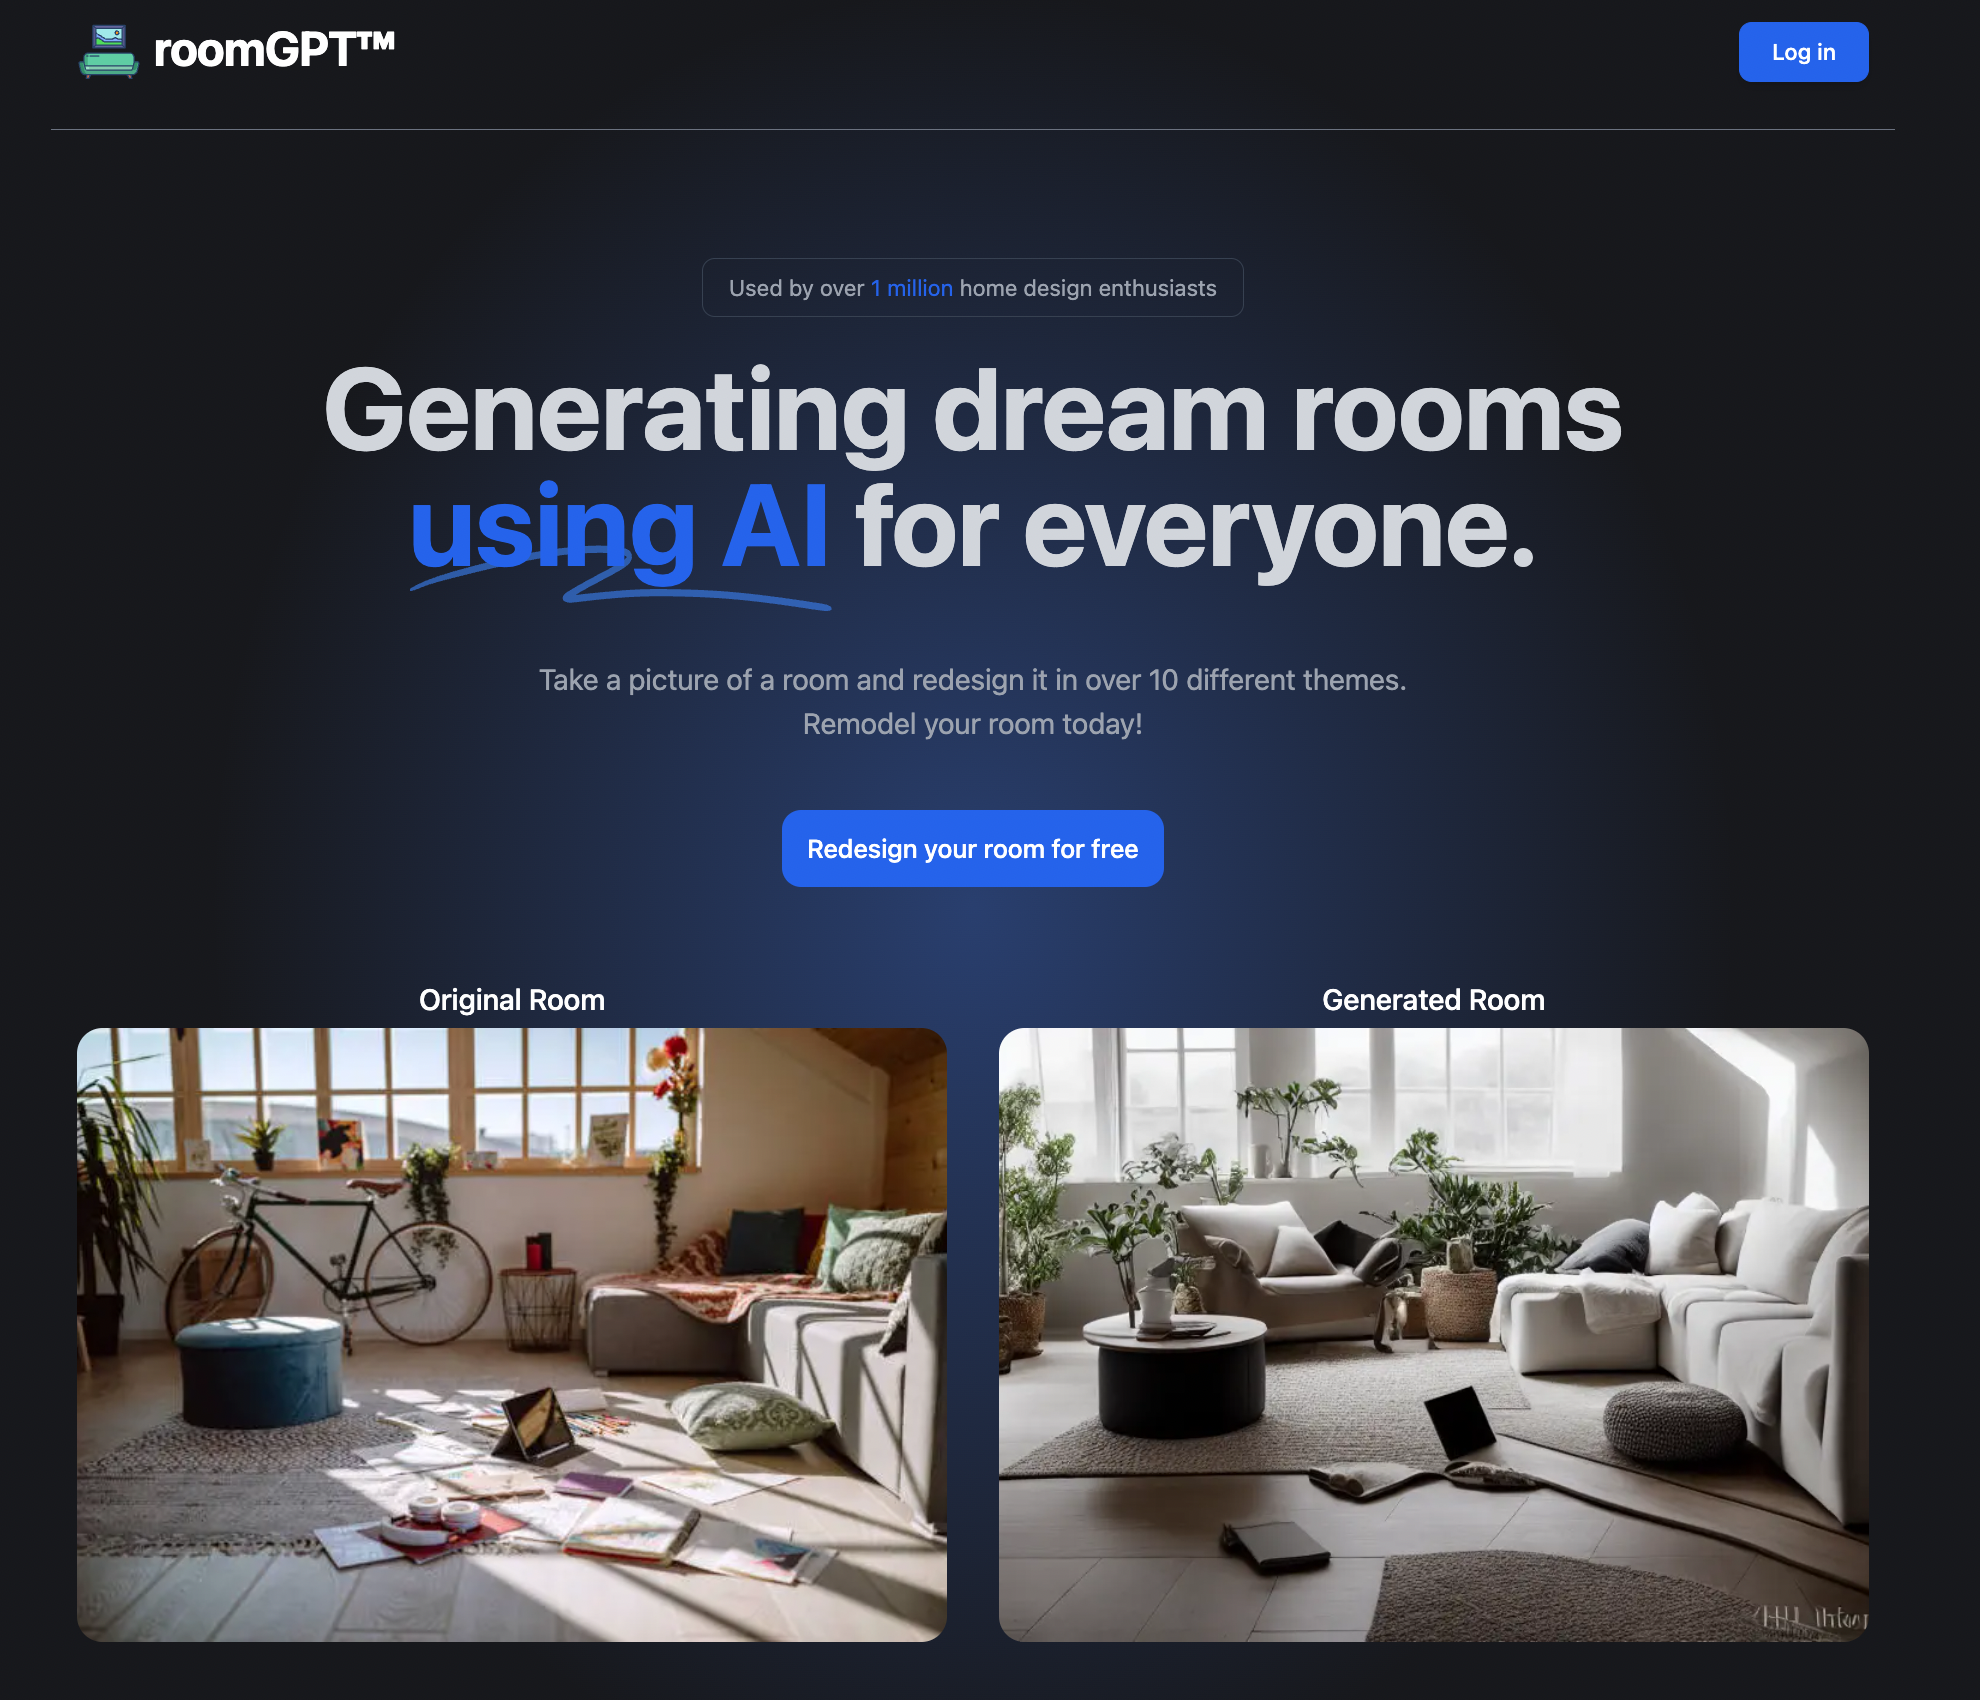
roomGPT
10.7KNutlope/roomGPT · TypeScriptRoomGPT lets you upload a photo of any room and generates an AI-redesigned version of it using a machine learning model.
- 27
easydiffusion
10.5Keasydiffusion/easydiffusion · JavaScriptEasy Diffusion is a one-click way to run Stable Diffusion on your own PC: type a text prompt into its browser-based UI and get an image — no technical knowledge or pre-installed software needed.
- 28
LTX-2
9.8KLightricks/LTX-2 · PythonThe official Python package for LTX-2, Lightricks' audio-video foundation model: one DiT-based model that generates video with synchronized audio from text or an image, in several quality/speed modes.
- 29
stable-diffusion.cpp
7.7Kleejet/stable-diffusion.cpp · C++A pure C/C++ inference engine for diffusion models like Stable Diffusion, Flux, Wan, Qwen Image, and Z-Image, built the same way as llama.cpp so you can generate images and videos without heavy Python dependencies.
- 30
vllm-omni
7.3Kvllm-project/vllm-omni · PythonvLLM-Omni is an inference and serving framework that extends vLLM beyond text-only LLMs to omni-modality models, handling text, image, audio, video, and action outputs.
- 31

HunyuanVideo-1.5
4.6KTencent-Hunyuan/HunyuanVideo-1.5 · PythonHunyuanVideo-1.5 is a video generation model from Tencent that creates text-to-video and image-to-video clips, achieving top-tier quality with only 8.3B parameters so it runs on consumer-grade GPUs.
- 32

PersonaLive
4KGVCLab/PersonaLive · PythonPersonaLive is a real-time, streamable diffusion framework that animates a single portrait image into an infinite-length talking video, designed for live-streaming use cases. It was accepted to CVPR 2026.
- 33
kimodo
3.8Knv-tlabs/kimodo · PythonKimodo is NVIDIA's kinematic motion diffusion model that generates high-quality 3D human and robot motion from text prompts and kinematic constraints like keyframes, end-effector positions, and 2D paths.
- 34
UniMate
2KFriedrich-M/UniMate · PythonUniMate is the official code release for a SIGGRAPH Asia 2026 paper: a single diffusion/flow-matching model that generates motion for very different skeleton types (bipedal, quadrupedal, avian, marine, insectoid, serpentine, and even rigid articulated objects) from a rigged 3D asset plus a text prompt, without retraining per skeleton.
- 35
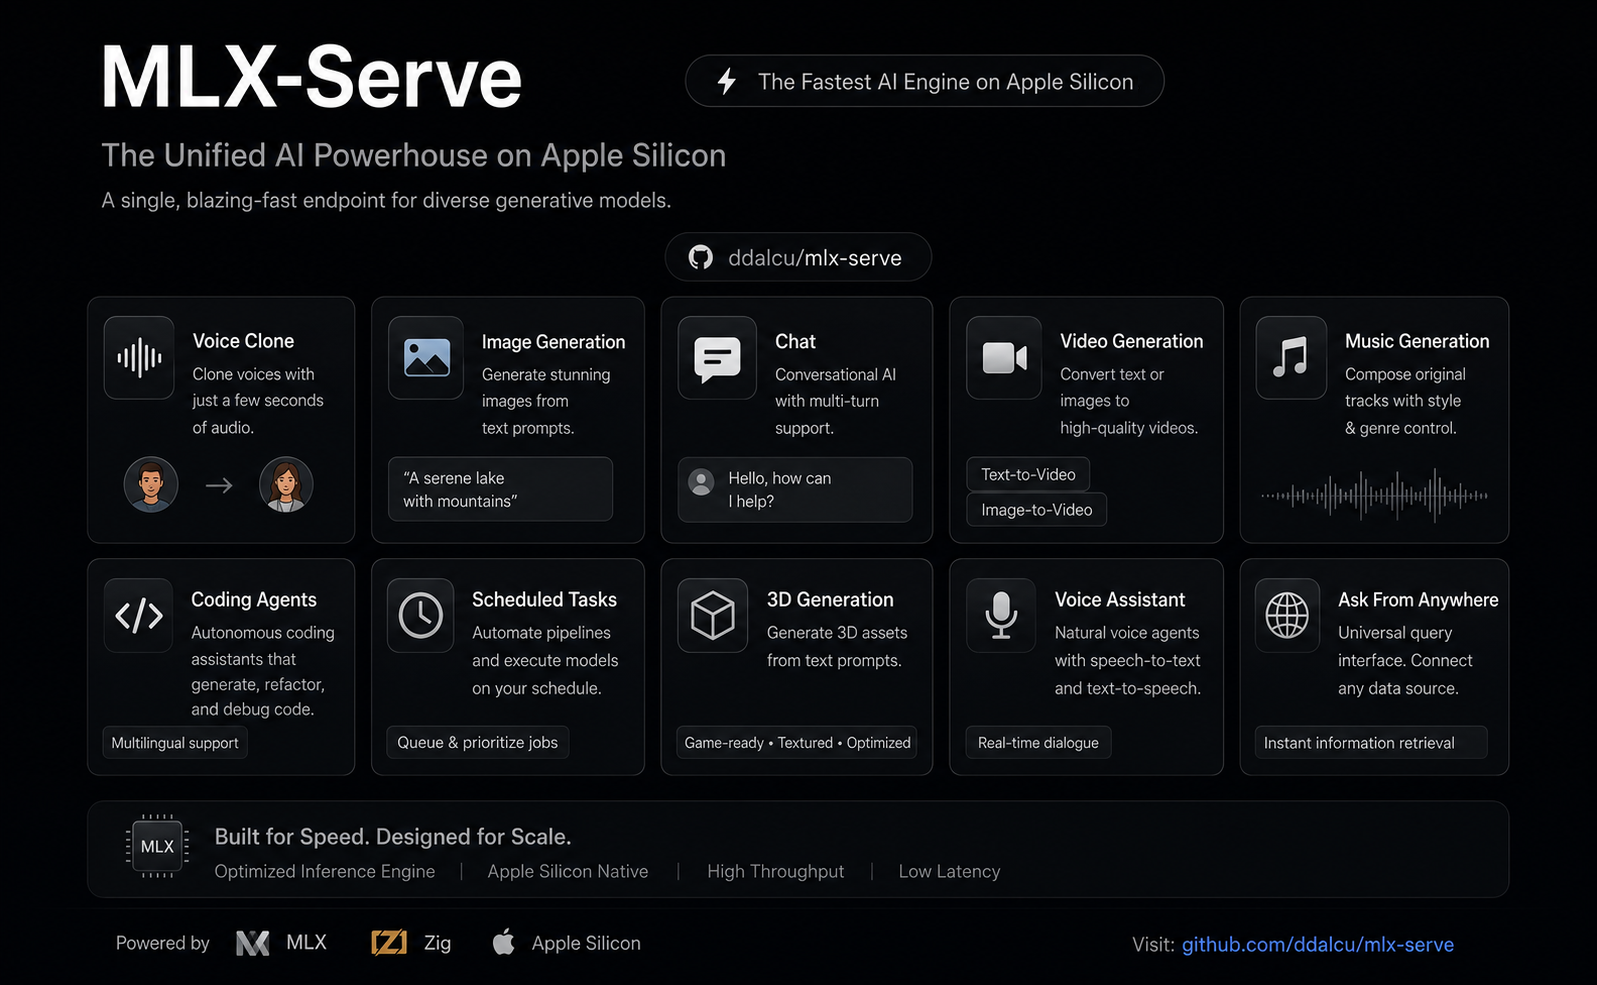
mlx-serve
2Kddalcu/mlx-serve · Zigmlx-serve is a native local inference server for Apple Silicon Macs that runs MLX and GGUF language models and exposes OpenAI-, Anthropic-, and Ollama-compatible APIs, plus generates images, video, music, speech, and 3D models, all without Python or a cloud connection.
- 36

AuK
1.5KTencent-Hunyuan/AuK · PythonAn open-source 1.5B-parameter foundation model from Tencent Hunyuan for speech generation and editing: zero-shot and instruct TTS, speech editing, enhancement, and source separation — all driven through one natural-language instruction interface.
- 37

marigold-v2
919huawei-bayerlab/marigold-v2 · PythonMarigold V2 is a family of models and a cost-effective fine-tuning protocol that repurposes a pretrained diffusion transformer into single-step dense predictors: depth, see-through depth, surface normals, albedo, and other dense modalities.
- 38
SolarWM
781Junchao-cs/SolarWM · PythonSolarWM is a fully open foundation for building interactive video world models, covering data preparation, scalable multi-backbone training, and long-horizon inference.
- 39
LoongForge
695baidu-baige/LoongForge · PythonAn open-source training framework from Baidu's Baige team for LLMs, VLMs, diffusion and embodied models, built for faster training and lower cost on NVIDIA GPUs and Kunlun XPUs.
- 40
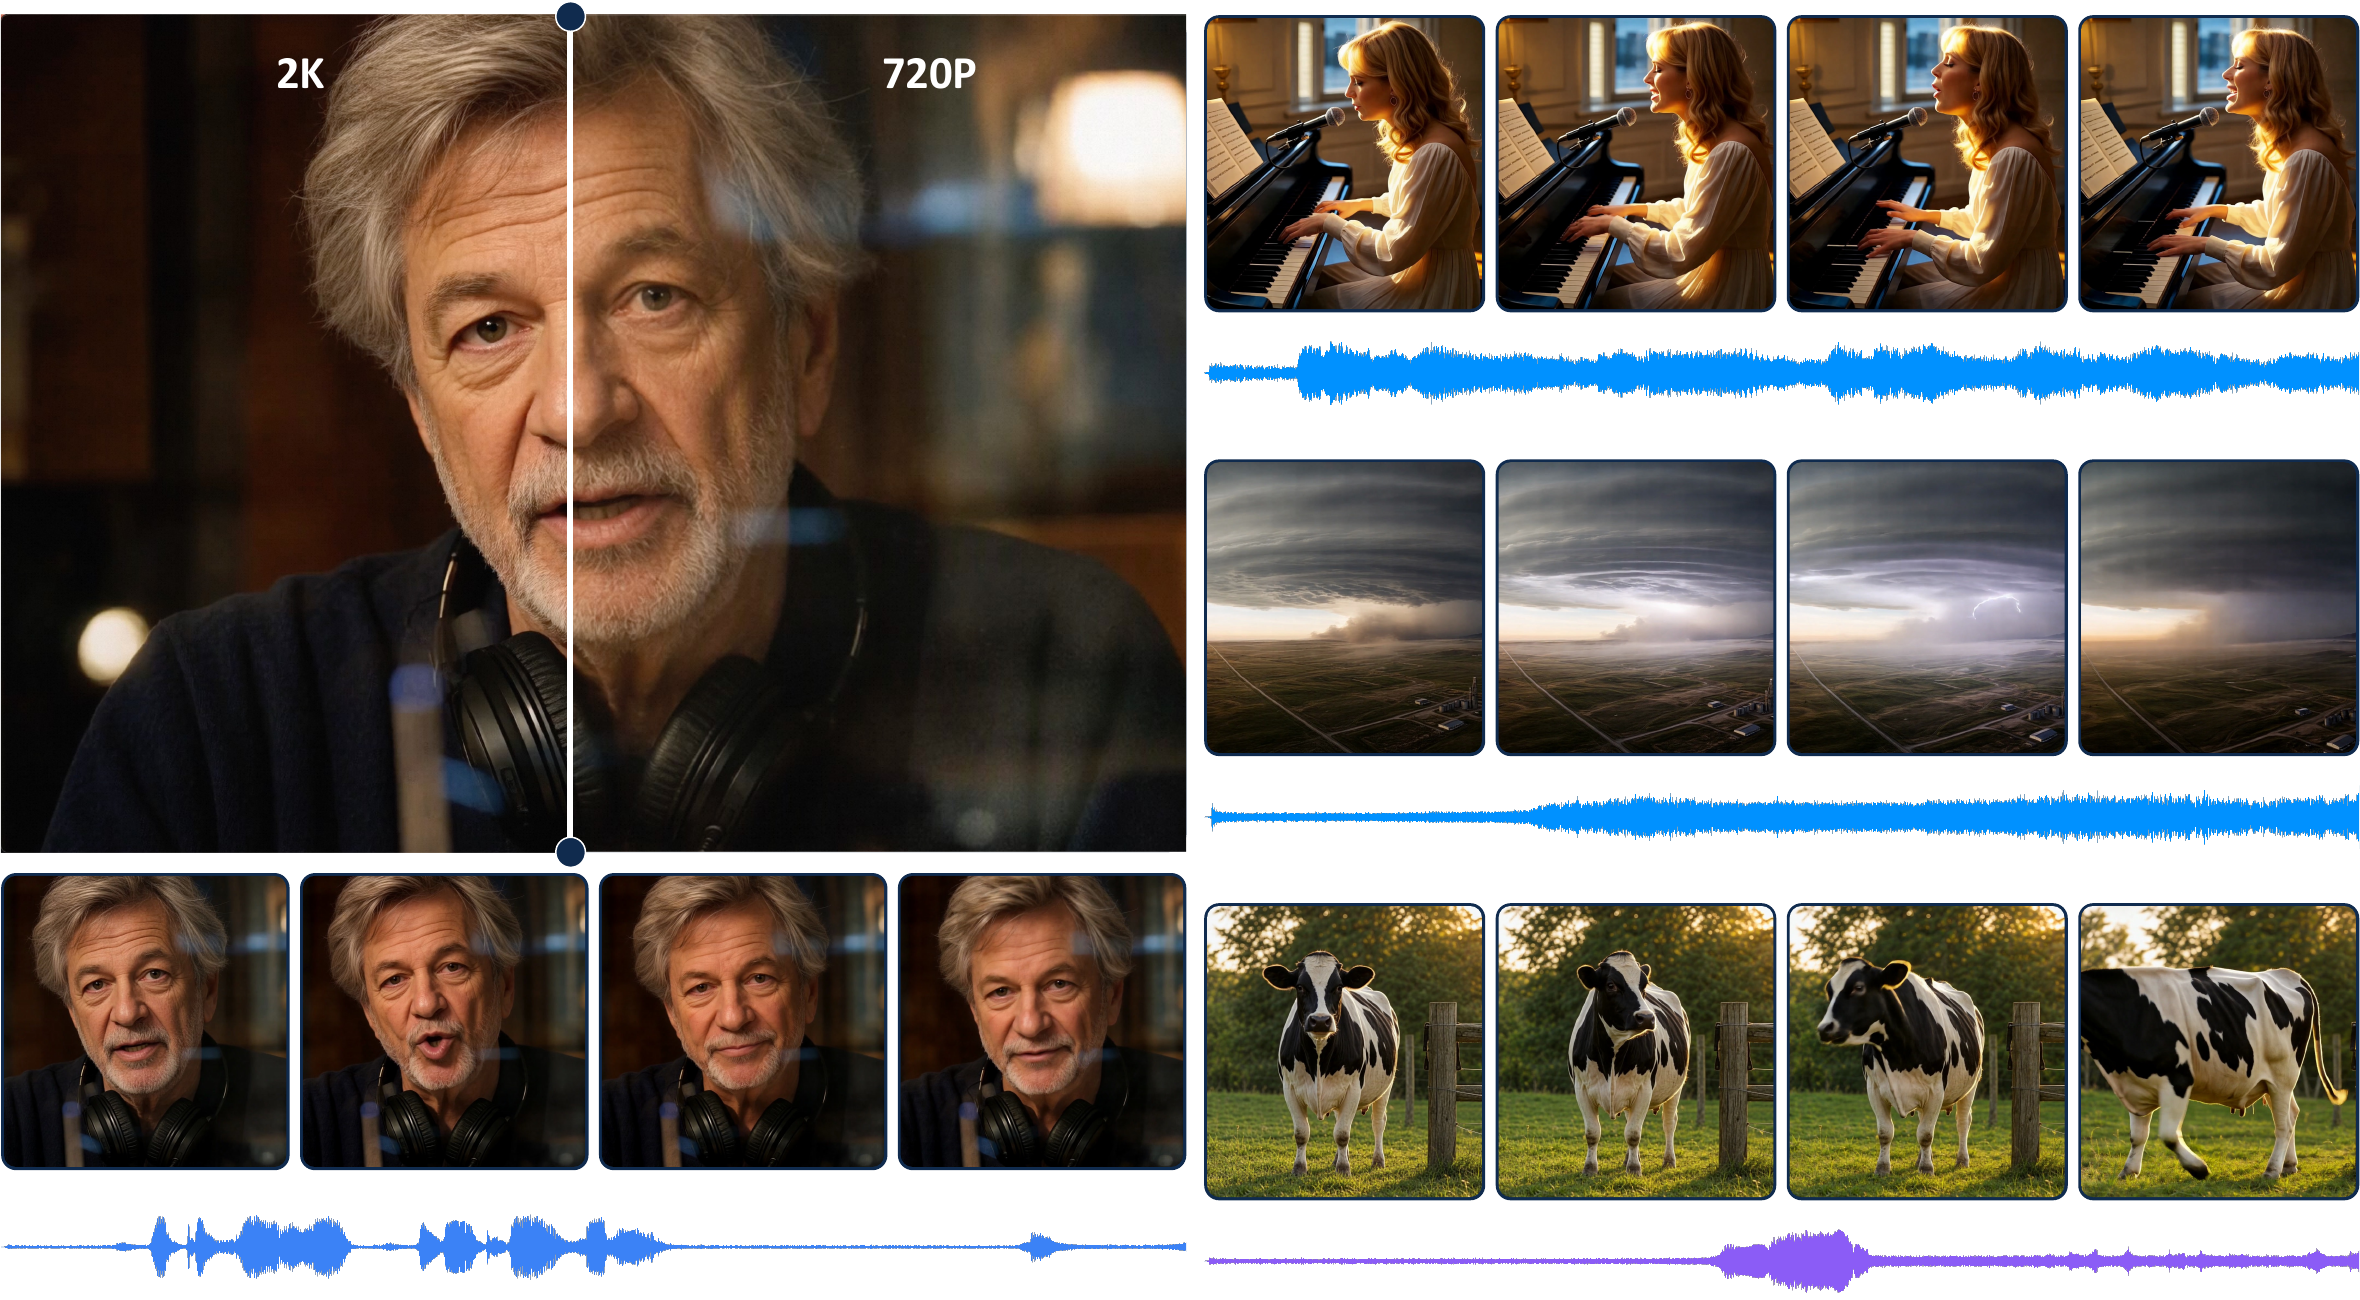
DreamX-Creator
313AMAP-ML/DreamX-Creator · PythonDreamX-Creator is an open-source research framework for native joint audio-video generation: it produces video and a synchronized audio track together, refined up to 2K resolution.
- 41
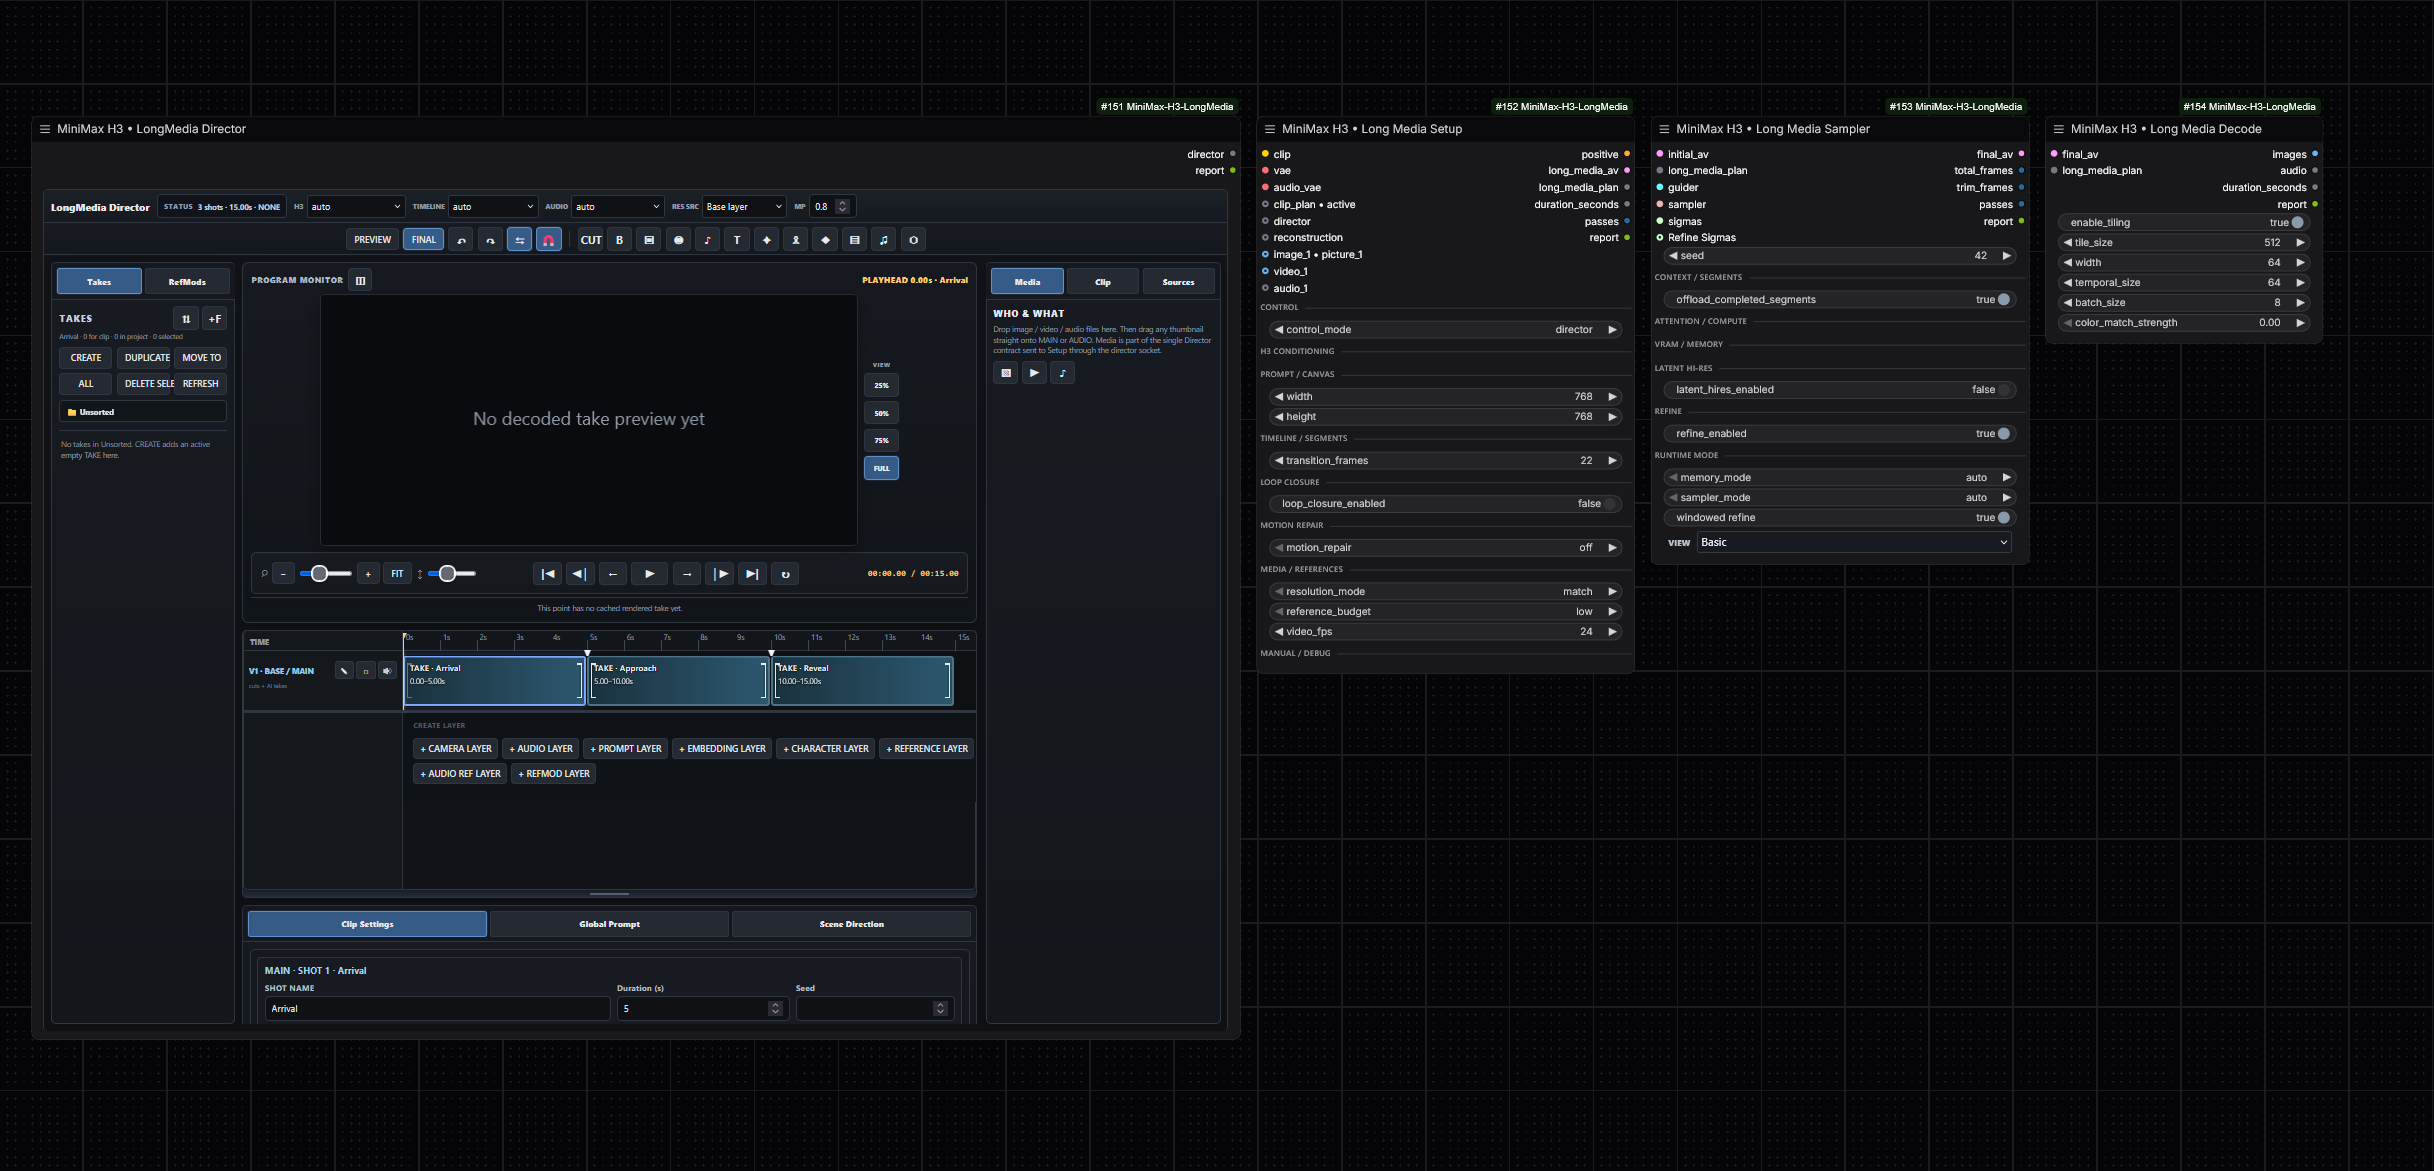
ComfyUI-MiniMax-H3-LongMedia
297vizart-vj/ComfyUI-MiniMax-H3-LongMedia · PythonA set of production-oriented custom nodes for ComfyUI that run MiniMax H3 for long-form video and audio generation: reference editing, MultiClip planning, camera direction, fixed segmentation, lip-sync and redubbing, latent hi-res refinement, and low-VRAM-safe execution.
- 42
fix-anything
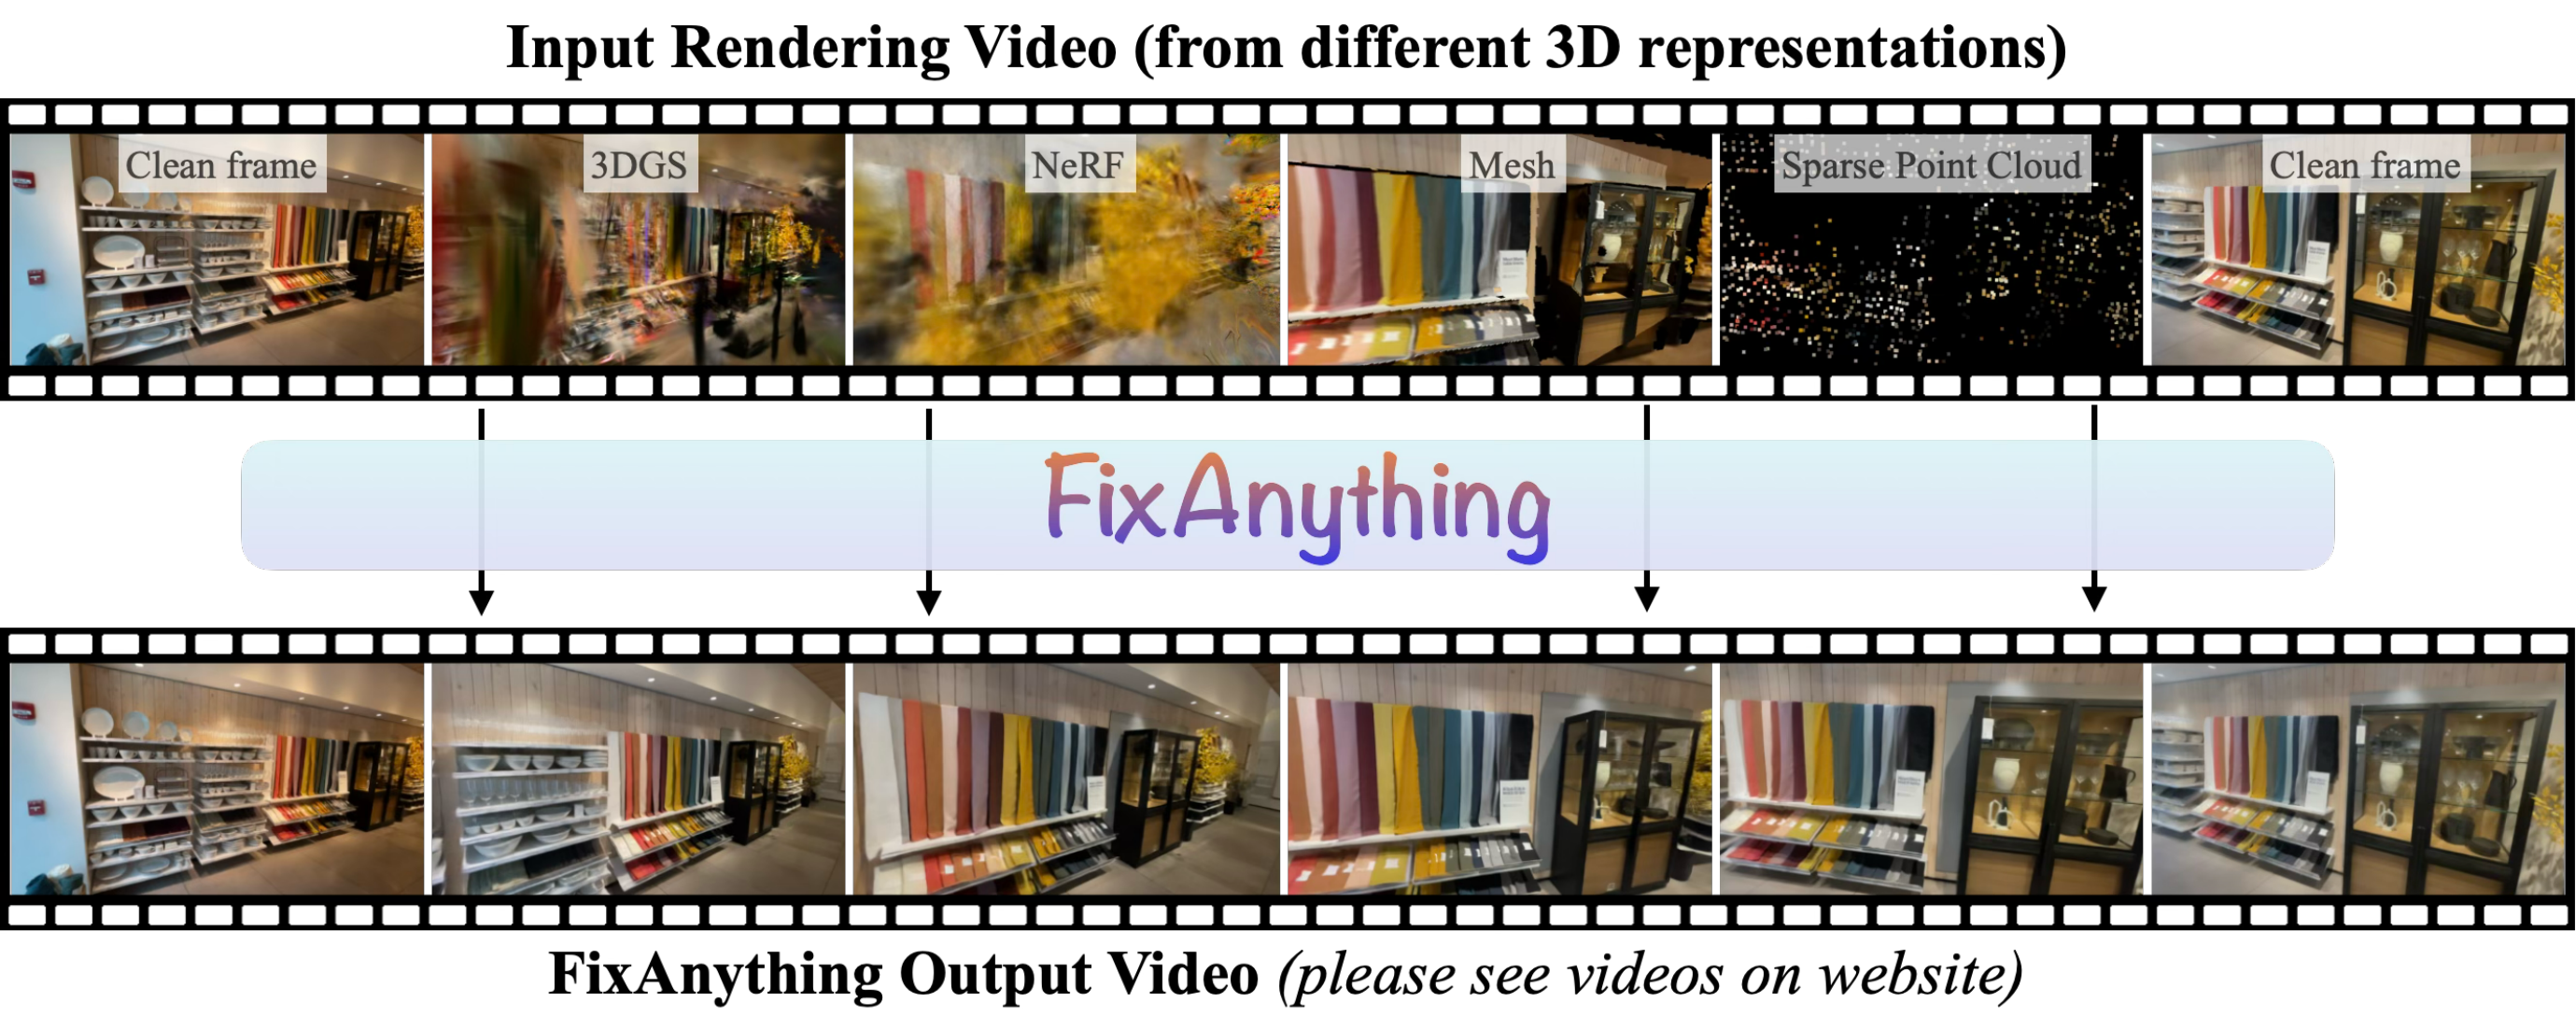
246kvuong2711/fix-anything · PythonA research tool from an ECCV 2026 paper: a video diffusion model fine-tuned to repair rendering artifacts from any 3D representation — 3DGS, NeRF, meshes, or sparse point clouds. The repo holds the inference code.
- 43

Comfyui-MMH3-UltimateUpscale
238bbaudio-2025/Comfyui-MMH3-UltimateUpscale · PythonA ComfyUI custom node that upscales long, high-resolution MiniMax H3 AV video latents on VRAM-limited GPUs, using temporal chunking and spatial tiling inside a single node while keeping the audio track intact.
- 44
zing-world-model
173seedleap/zing-world-model · PythonZing-0.5 is an efficient causal world model that generates a real-time video world, letting you steer it live with text prompts and W/A/S/D/I/J/K/L keyboard actions.
- 45

hyperflow
147Video-Rebirth/hyperflow · PythonAn 8-step LoRA adapter for MiniMax-H3, a video+audio generation model, trained by data-free flow self-distillation. This repository holds the loader and example scripts that run it on the diffusers Modular Pipeline.

Related topics
Often tagged together
- python2,440
- gpu816
- pytorch422
- deep-learning748
- ai2,001
- machine-learning931
- linux4,265
- cuda404
- generative-ai355
- huggingface368
- open-source5,768
- research783
- image-generation230
- nvidia341
- video-generation198
- diffusion-models83
- windows3,493
- apache-2.01,457
- inference331
- macos3,624
- stable-diffusion56
- lora90
- computer-vision393
- text-to-image74