




41.4K ·GitHub
What is this?
 Colossal-AI is an open-source system for training and running large AI models more cheaply, faster and with less hardware, by providing a toolbox of parallelism and memory-optimization techniques.
Is this a framework I build models with, or a standalone app?It is a Python framework/toolbox of parallel-training components (data, pipeline, tensor, sequence parallelism, ZeRO) that you plug into your own PyTorch training code, not a finished application.
It is a Python framework/toolbox of parallel-training components (data, pipeline, tensor, sequence parallelism, ZeRO) that you plug into your own PyTorch training code, not a finished application.How do I install Colossal-AI?You can install it from PyPI, build it from source, or run it via Docker, as listed in the project's installation section.
You can install it from PyPI, build it from source, or run it via Docker, as listed in the project's installation section.Is this meant for small hobby projects or serious large-scale training?It's aimed squarely at large-scale/foundation-model training and inference across multi-GPU and multi-node clusters, so getting real value from it assumes access to significant GPU hardware and benchmarks reported use 8–16 GPU setups.
It's aimed squarely at large-scale/foundation-model training and inference across multi-GPU and multi-node clusters, so getting real value from it assumes access to significant GPU hardware and benchmarks reported use 8–16 GPU setups.Who is this really built for?Researchers and companies training or fine-tuning large foundation models (LLMs, diffusion, video generation) who want to cut GPU cost and training time, as validated with benchmarks from UC Berkeley and industry funding.
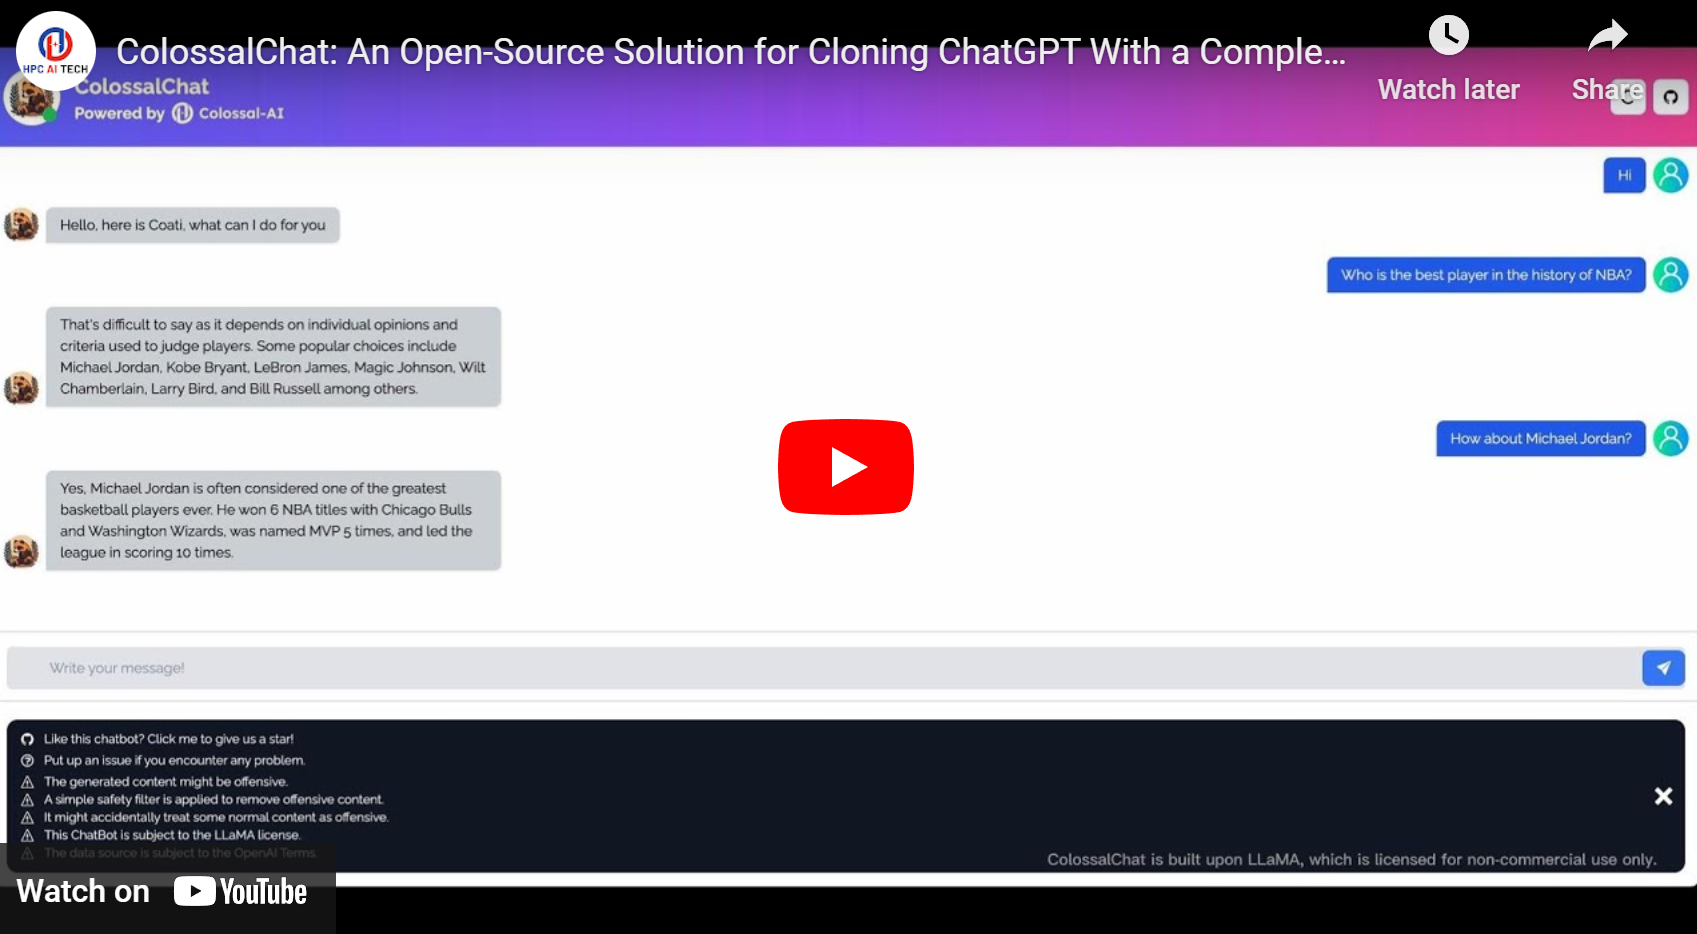
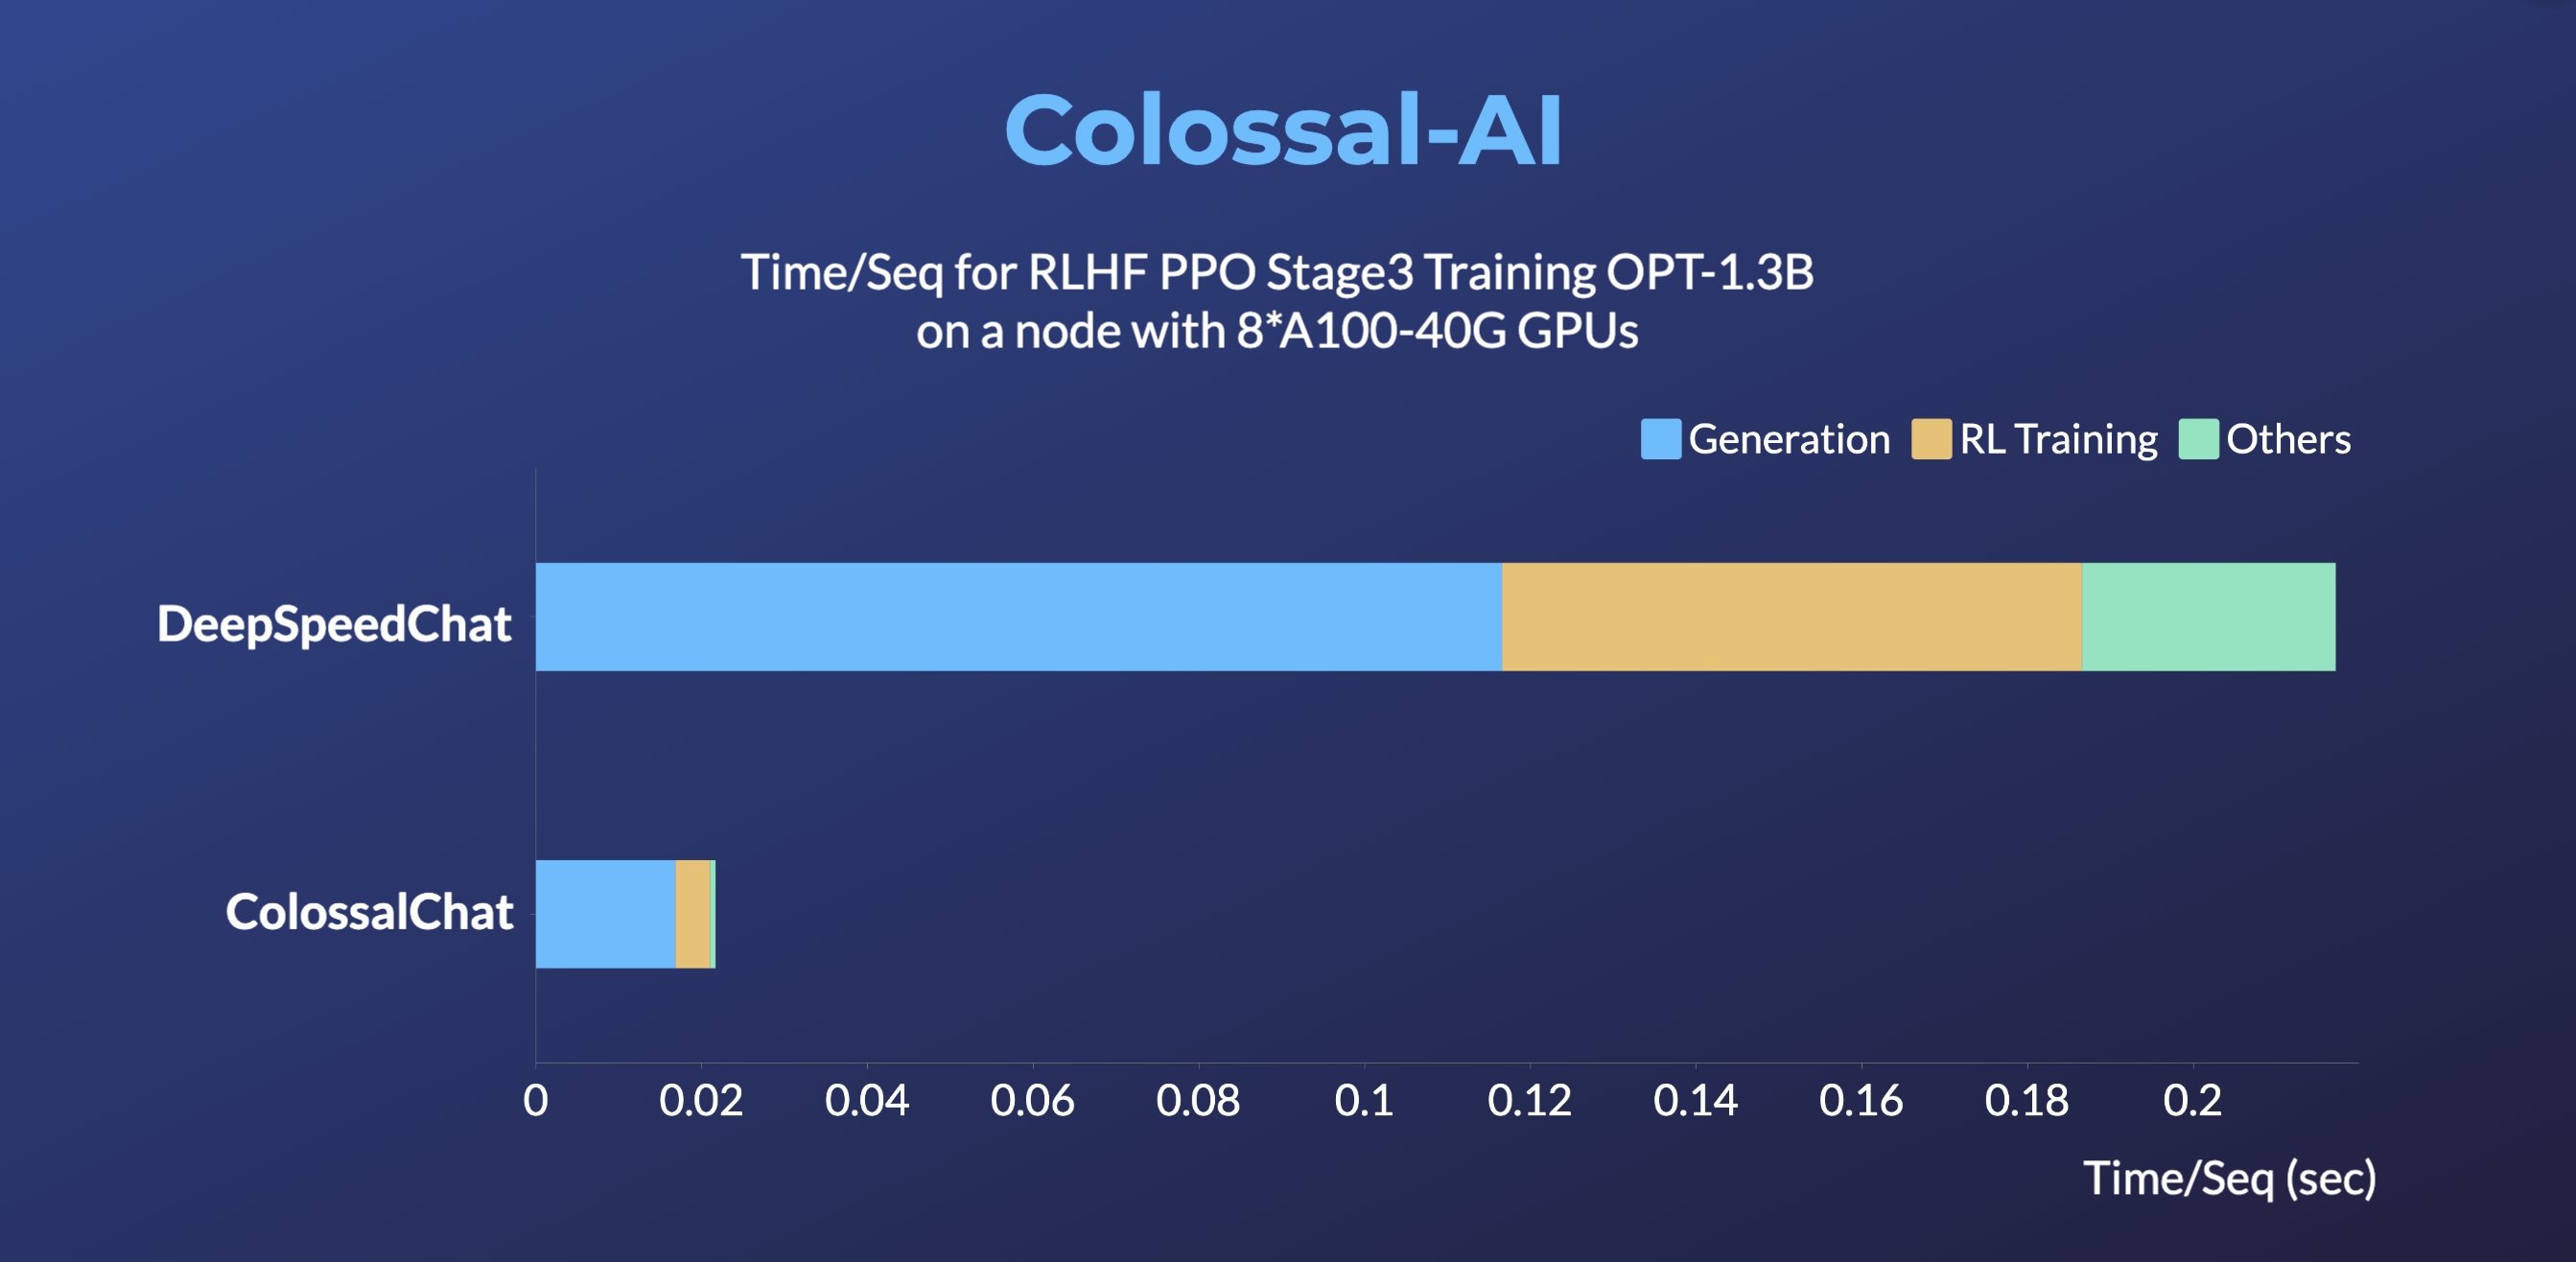
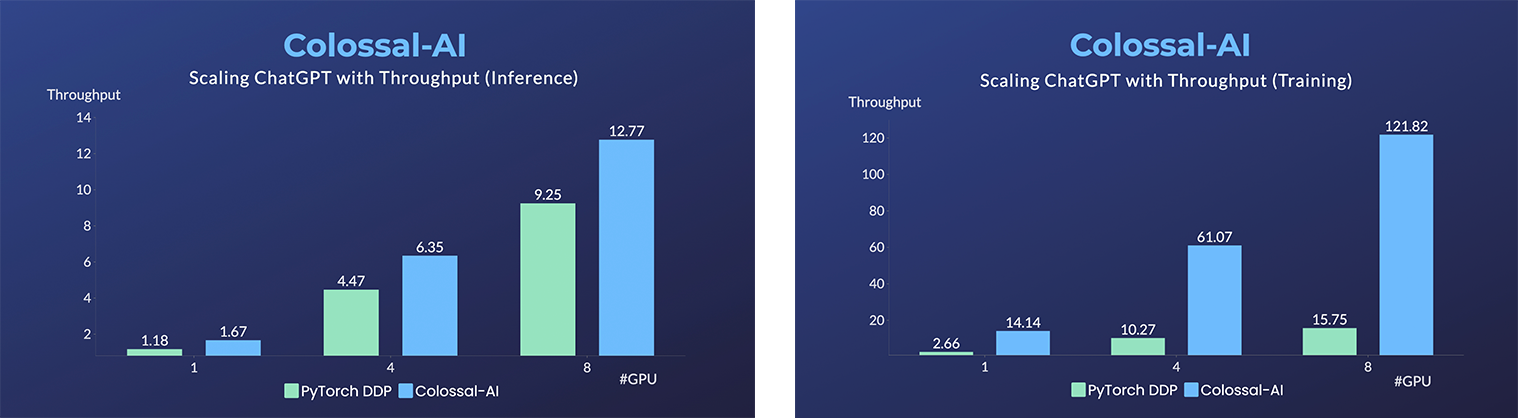
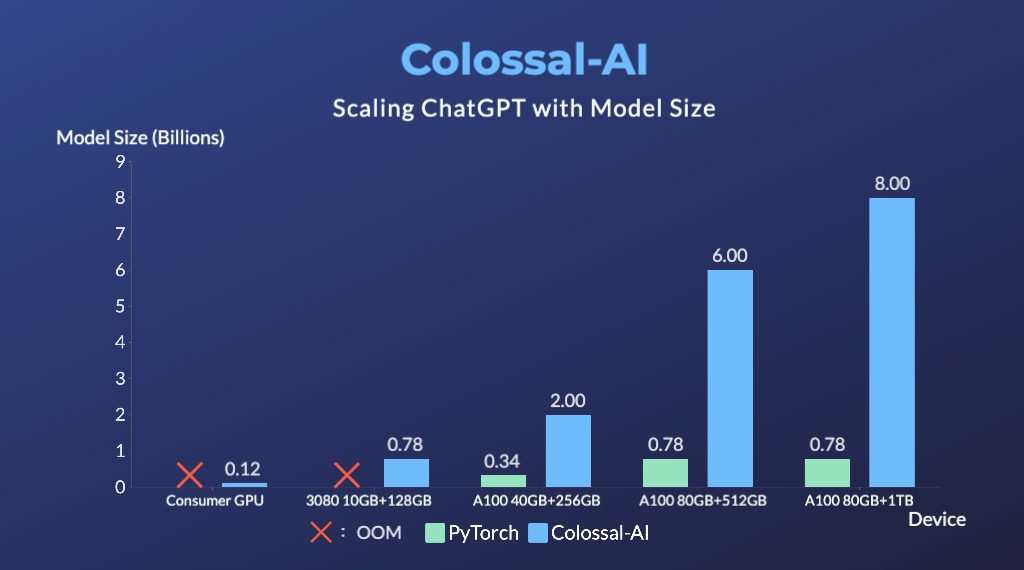
Researchers and companies training or fine-tuning large foundation models (LLMs, diffusion, video generation) who want to cut GPU cost and training time, as validated with benchmarks from UC Berkeley and industry funding.What is ColossalChat?ColossalChat is an open-source solution for cloning ChatGPT with a complete RLHF (PPO) training pipeline, claimed to be up to 10x faster for PPO Stage3 training.
ColossalChat is an open-source solution for cloning ChatGPT with a complete RLHF (PPO) training pipeline, claimed to be up to 10x faster for PPO Stage3 training.What is Colossal-LLaMA-2 used for?It's a recipe for building a domain-specific LLM cheaply, showing that about half a day of training for a few hundred dollars on top of LLaMA-2 can match mainstream model benchmarks.
It's a recipe for building a domain-specific LLM cheaply, showing that about half a day of training for a few hundred dollars on top of LLaMA-2 can match mainstream model benchmarks.What is Open-Sora in relation to this project?Open-Sora is a Colossal-AI powered open-source project that reproduces Sora-like text-to-video generation models, including code, model weights and training details.
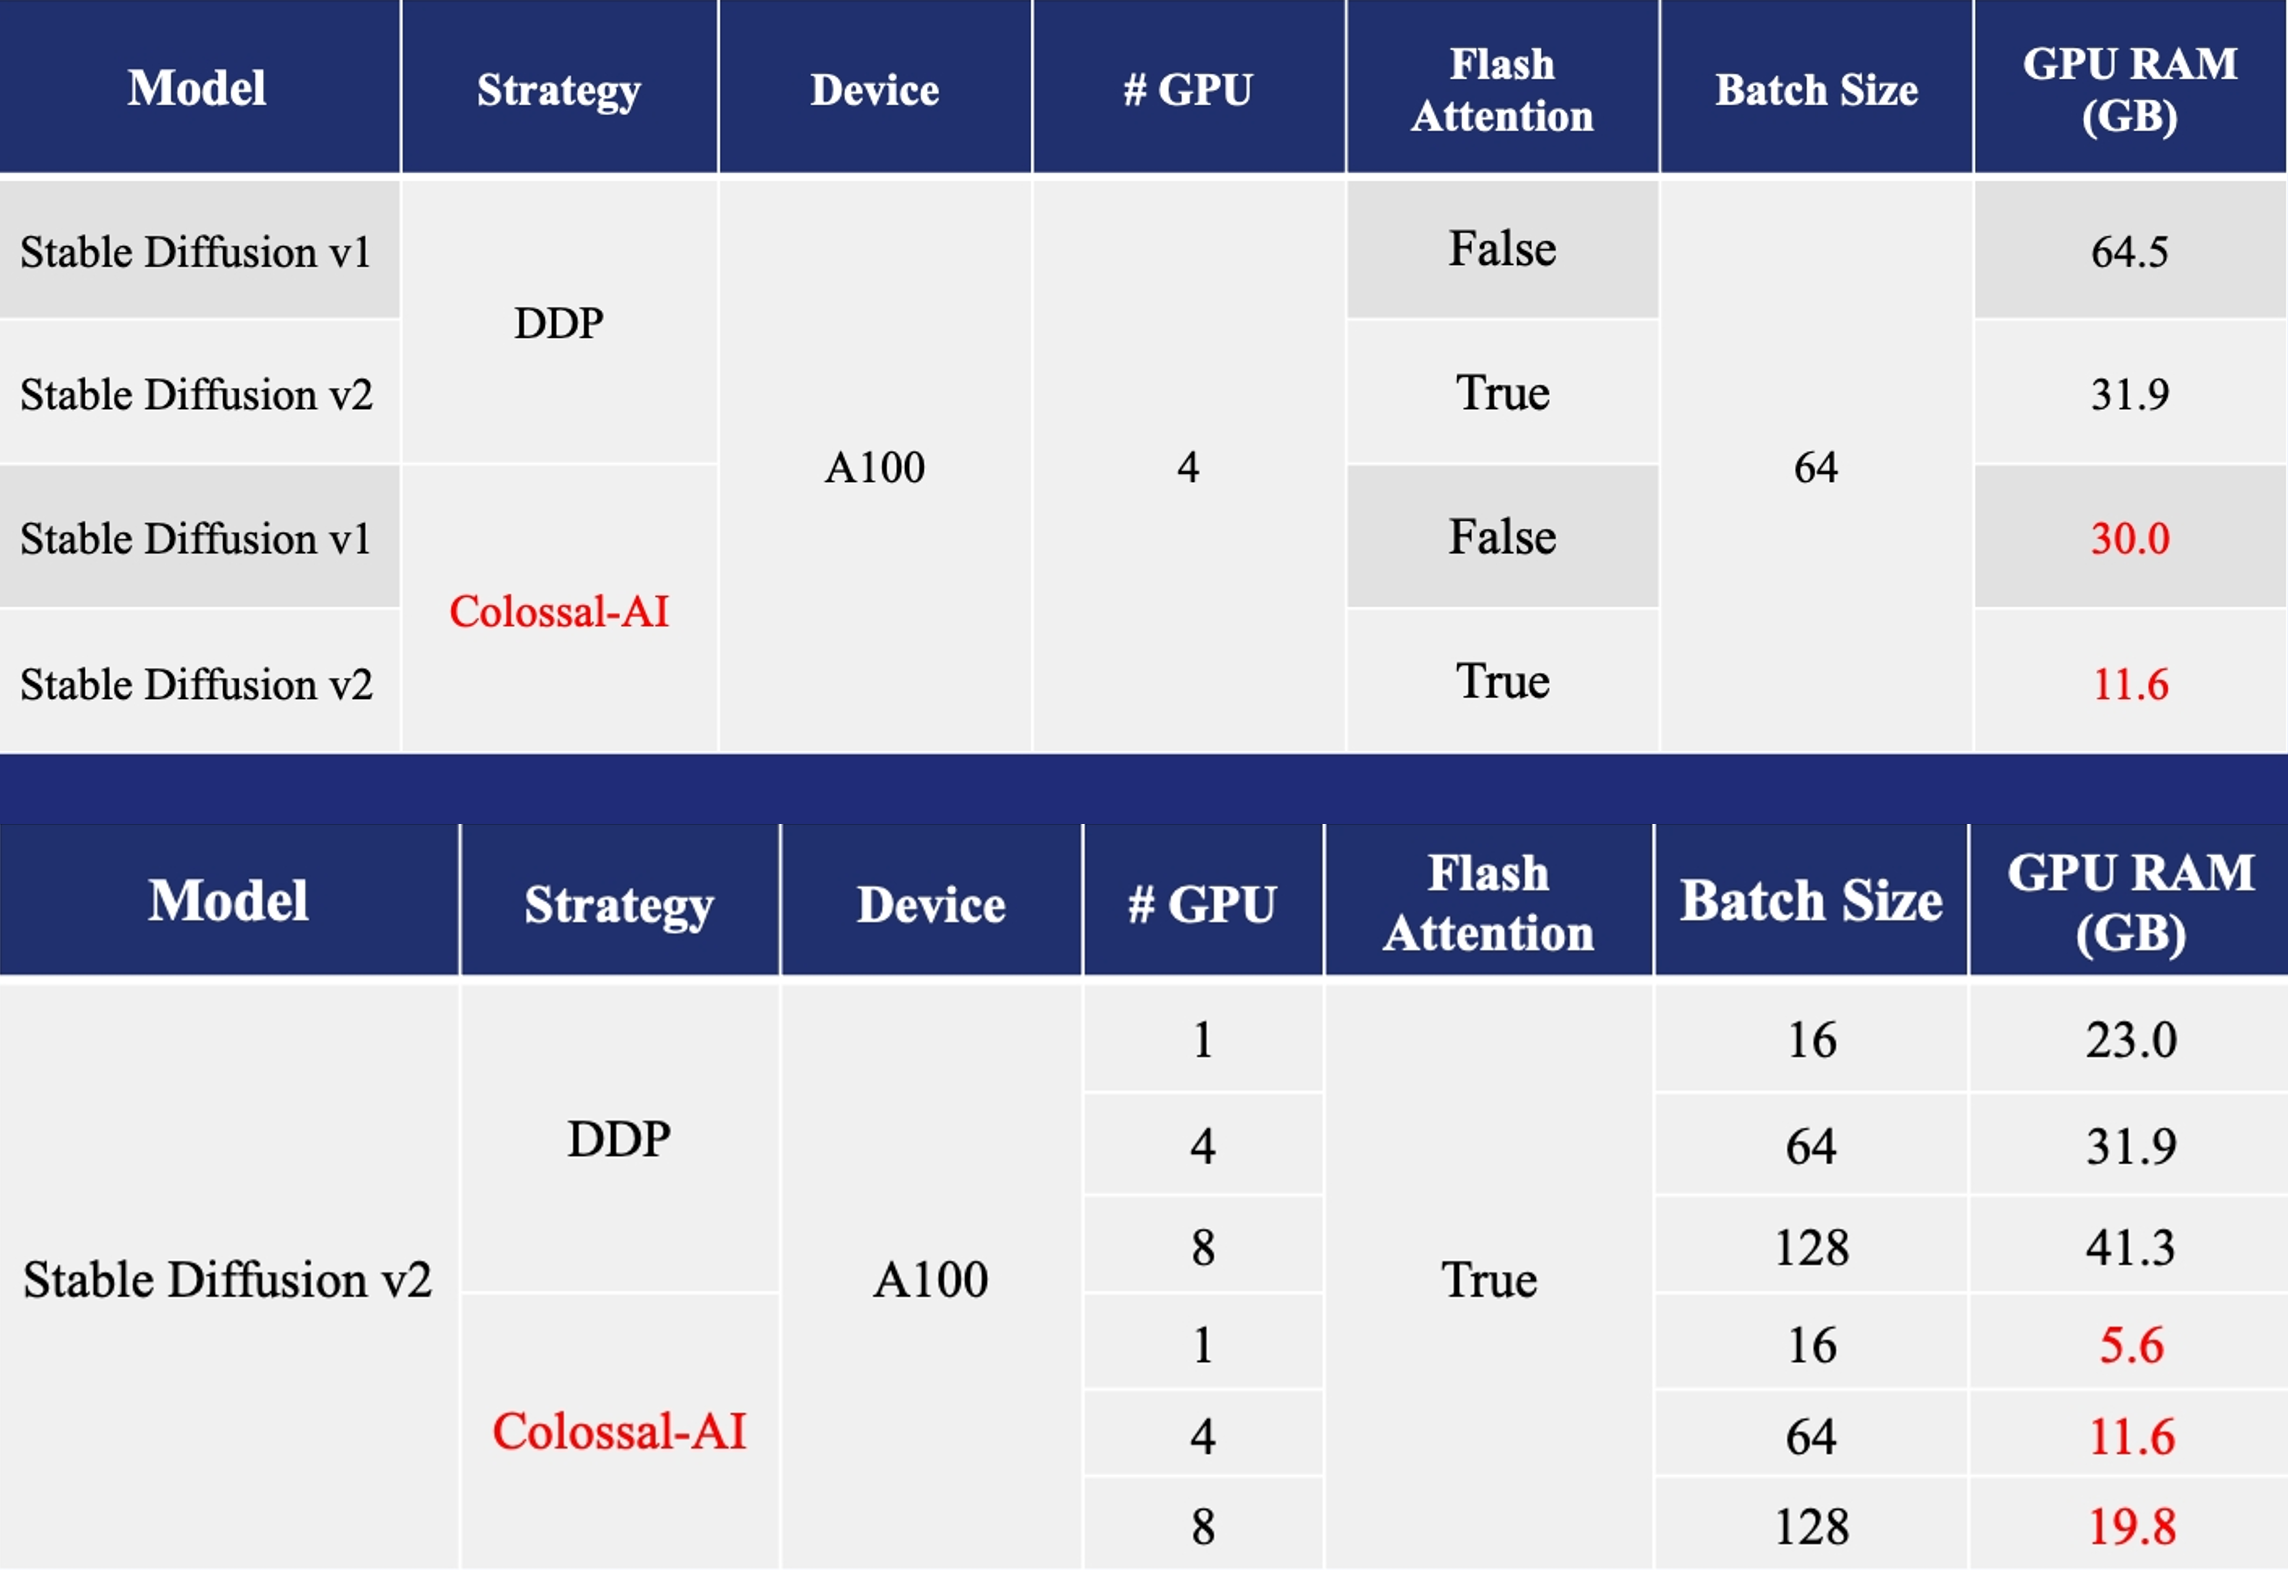
Open-Sora is a Colossal-AI powered open-source project that reproduces Sora-like text-to-video generation models, including code, model weights and training details.How much can Colossal-AI reduce Stable Diffusion training cost?The project reports cutting Stable Diffusion memory consumption by up to 5.6x and hardware cost by up to 46x, enabling training to move from an A100 down to an RTX 3060.
The project reports cutting Stable Diffusion memory consumption by up to 5.6x and hardware cost by up to 46x, enabling training to move from an A100 down to an RTX 3060.What are similar projects?petals, DeepSpeed, halo, ms-swift, verl, ml-engineering, train-llm-from-scratch, Meshy
petals, DeepSpeed, halo, ms-swift, verl, ml-engineering, train-llm-from-scratch, MeshyWhich topics is it in?hpc, distributed-computing, rlhf, distributed-training, foundation-models, stable-diffusion, llama, training, gpt, fine-tuning, video-generation, chatgpt
hpc, distributed-computing, rlhf, distributed-training, foundation-models, stable-diffusion, llama, training, gpt, fine-tuning, video-generation, chatgpt