Topics / #qwen3
Qwen3 projects on GitHub
The Qwen3 open-weight language model family and its deployment.
As of , the most-starred Qwen3 projects on GitHub are vllm (94K stars), self-llm (32.5K stars) and Qwen3 (27.7K stars). GitHub.Locker tracks 22 Qwen3 repositories with 239.9K stars combined. The fastest-growing on October 16 was vllm, with +73 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +73
vllm
vllm-project/vllm · ★ 94KvLLM is a library for fast LLM inference and serving, built around PagedAttention for efficient memory management of attention keys and values.
 +72
llm-architecture-from-scratch
YeonwooSung/llm-architecture-from-scratch · ★ 889A collection of PyTorch implementations of modern LLM architectures (GPT-2, Llama 3/3.2, Llama 4, OLMo 2, Phi-4, DeepSeek v3, Gemma 3, xLSTM, Mistral 3.1) built from scratch to understand how they work internally.
 +53
kev
jaredpalmer/kev · ★ 9.3KKev is an open family of small decision models (0.8B to 27B parameters) built on Qwen3.5/3.8 that answer yes/no, multiple-choice and rating questions about text with calibrated probabilities, acting as a self-hosted drop-in replacement for TypeSafe's hosted Jev model.
 +20
Intern-Decision
InternLM/Intern-Decision · ★ 811Intern-Decision turns a state, optional images, and multiple typed questions into decisions with probabilities, by fine-tuning the language backbone of Qwen3.5 while freezing its vision tower and projector.
The all-time top
22 projects · by stars
- 94K#1 · vllm-project/vllm
vllm
vLLM is a library for fast LLM inference and serving, built around PagedAttention for efficient memory management of attention keys and values.
- 32.5K
 #2 · datawhalechina/self-llm
self-llm
Self-llm is a Chinese-language tutorial collection that teaches beginners how to configure environments, deploy, and fine-tune (full-parameter or LoRA) 50+ open-source large language models and multimodal models on Linux.
- 27.7K
 #3 · QwenLM/Qwen3
Qwen3
Qwen3 is a series of open-weight large language models built by the Qwen team at Alibaba Cloud, released as both dense and Mixture-of-Experts (MoE) models from 0.6B up to 235B-A22B parameters, with switchable 'thinking' and 'non-thinking' reasoning modes.
- 4
MaxKB
23K1Panel-dev/MaxKB · PythonMaxKB (Max Knowledge Brain) is an open-source platform for building enterprise-grade AI agents, combining RAG pipelines, an agentic workflow engine and MCP tool-use. Typical uses: intelligent customer service, internal company knowledge bases, research and education.
- 5
ms-swift
15.9Kmodelscope/ms-swift · Pythonms-swift is the ModelScope community's fine-tuning and deployment framework for LLMs and multimodal models, covering training, inference, evaluation, quantization and deployment in one pipeline.
- 6
Qwen3-TTS
13.8KQwenLM/Qwen3-TTS · PythonQwen3-TTS is an open-source text-to-speech model series from Alibaba's Qwen team that generates stable, expressive speech, supports voice design from text descriptions, and can clone voices from a short audio sample.
- 7
ART
10.8KOpenPipe/ART · PythonART (Agent Reinforcement Trainer) is an open-source RL framework from OpenPipe that lets LLM agents learn from experience: you train multi-step agents for real-world tasks with GRPO.
- 8
kev
9.3Kjaredpalmer/kev · PythonKev is an open family of small decision models (0.8B to 27B parameters) built on Qwen3.5/3.8 that answer yes/no, multiple-choice and rating questions about text with calibrated probabilities, acting as a self-hosted drop-in replacement for TypeSafe's hosted Jev model.
- 9
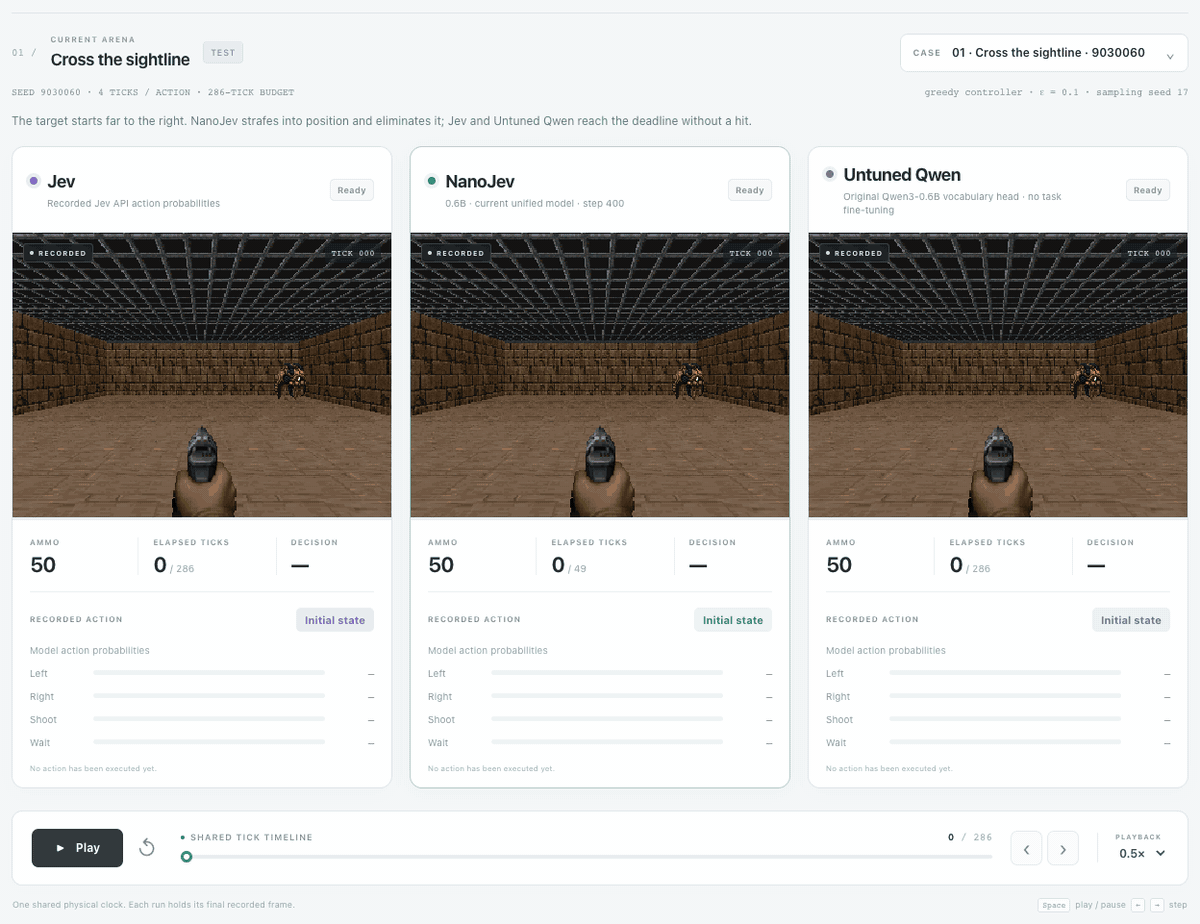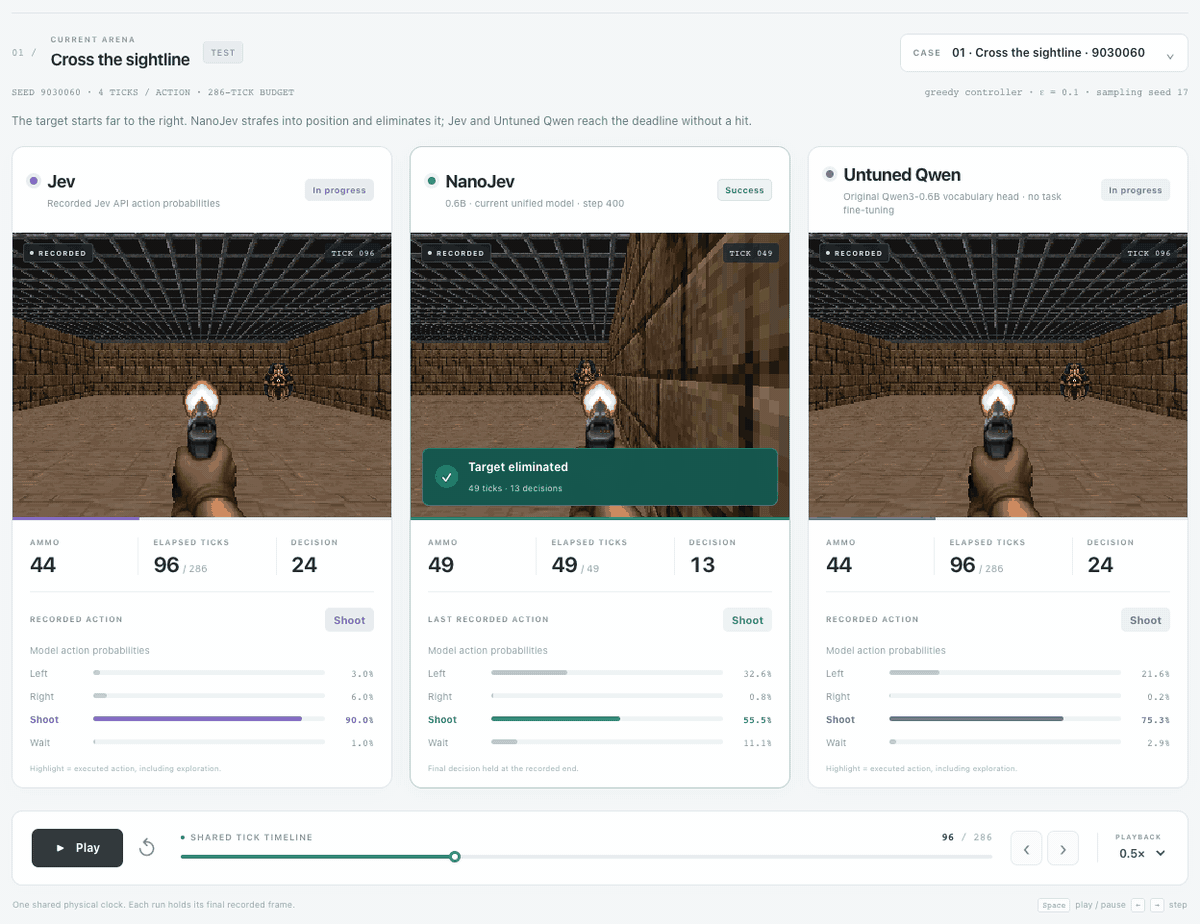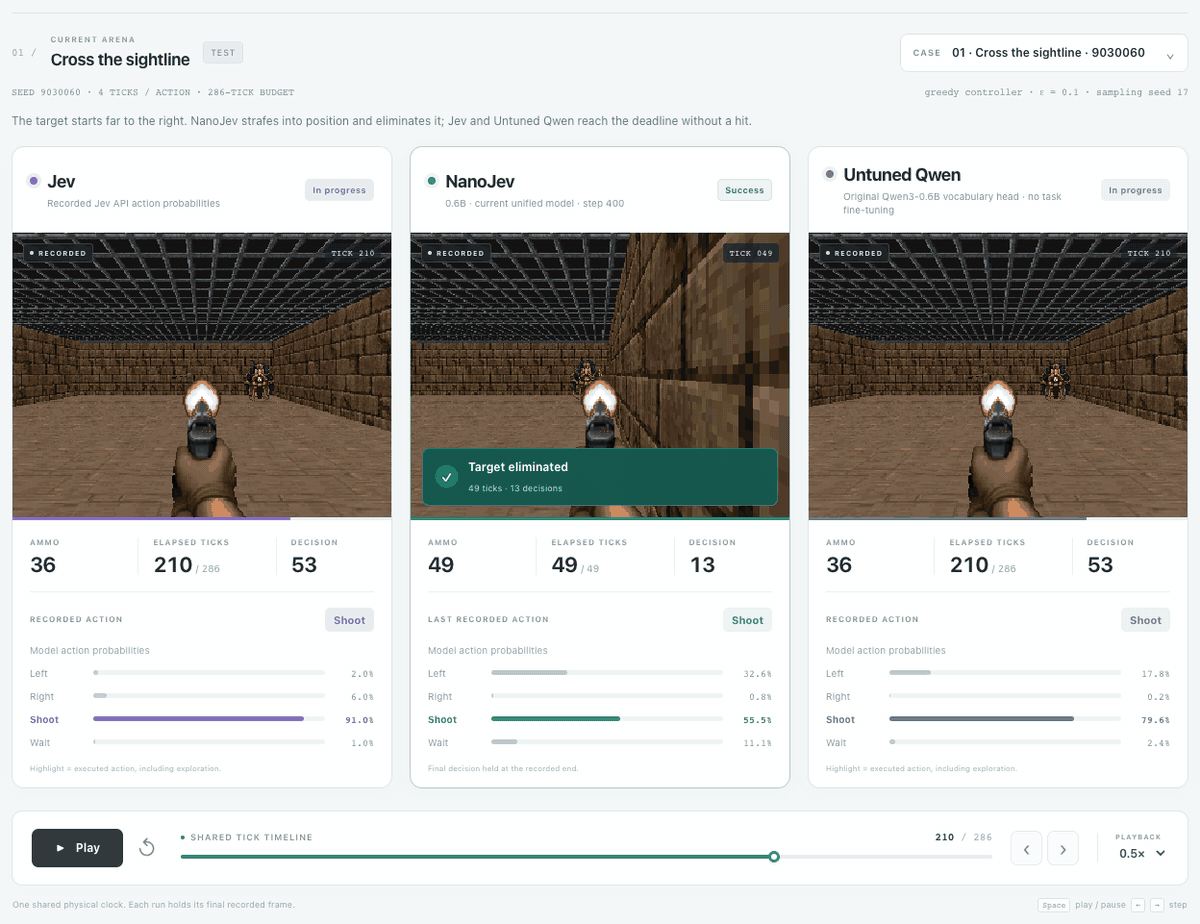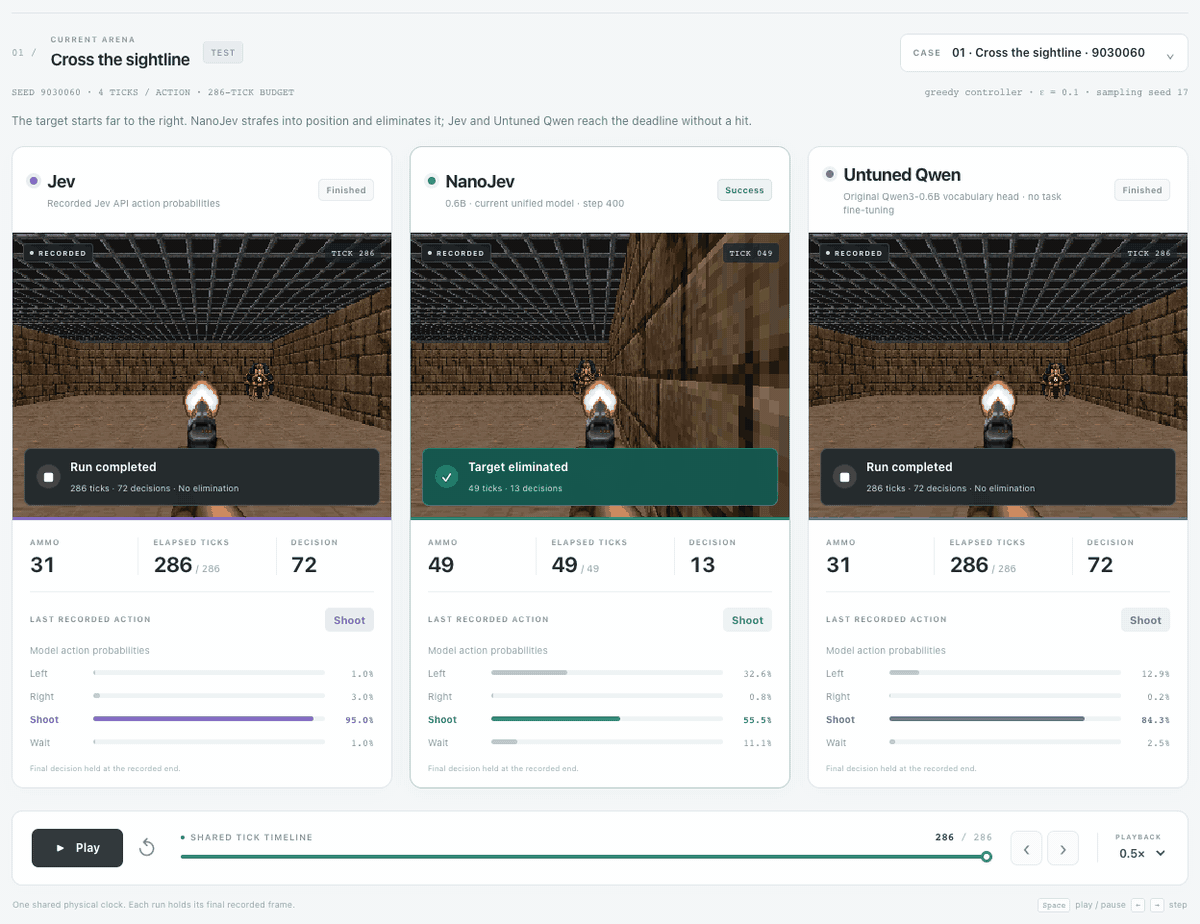
NanoJev
2.6KTianyuCodings/NanoJev · PythonA nano replica of Jev: a 0.6B-parameter parallel decision model that takes states and questions in and returns complete probability distributions — no output tokens are ever decoded.
- 10

HyperQwen
2Ksyv-ai/HyperQwen · PythonHyperQwen is a self-hosted serving setup that runs the Qwen3.8-27B model on a single 24 GB consumer GPU (like an RTX 3090) using vLLM, exposing it through an OpenAI-compatible API.
- 11
jeff
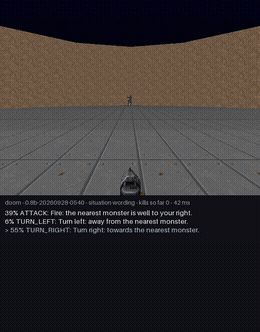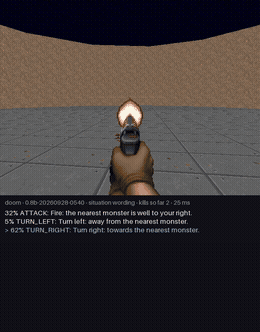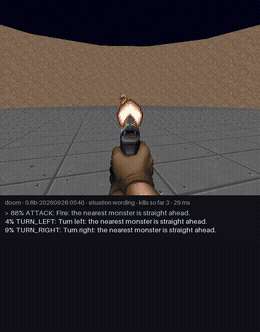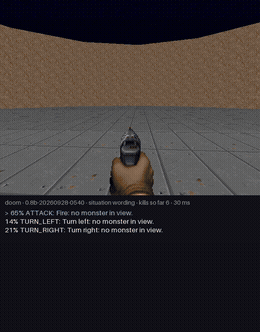
1.5Kfirelex/jeff · PythonJeff is a family of small (0.8B-2B parameter) open-weight models fine-tuned from Qwen3.5 and Gemma 4 that act as fast 'System 1' decision-makers: you describe a situation and a list of options in plain text, and Jeff returns a calibrated probability for each option from a single forward pass, with no generated text to parse.
- 12
halogen-flash-server
1Kpeonist-ai/halogen-flash-server · Shellhalogen-flash-server is a purpose-built inference server for running the Qwen3.8-Flash-Next model as fast as possible on AMD's Strix Halo (gfx1151) GPU, exposing an OpenAI-compatible API.
- 13

ai-torture-chamber
965terrafying/ai-torture-chamber · PythonA research project that steers small open-weight language models into strong negative or positive emotional states and measures what they say and do. A live version runs at wirehead.agency.
- 14
llm-architecture-from-scratch
889YeonwooSung/llm-architecture-from-scratch · PythonA collection of PyTorch implementations of modern LLM architectures (GPT-2, Llama 3/3.2, Llama 4, OLMo 2, Phi-4, DeepSeek v3, Gemma 3, xLSTM, Mistral 3.1) built from scratch to understand how they work internally.
- 15

localjev
828githubnext/localjev · TypeScriptLocalJev is a local TypeScript/Bun server that implements a Jev-compatible POST /v1/systemone decision API, backed by the DiffusionGemma model through an OpenAI-compatible Chat Completions endpoint. It lets Jev clients run against a local open model instead of OpenJev's hosted service.
- 16
Intern-Decision
811InternLM/Intern-Decision · PythonIntern-Decision turns a state, optional images, and multiple typed questions into decisions with probabilities, by fine-tuning the language backbone of Qwen3.5 while freezing its vision tower and projector.
- 17

kaggle-tpu-lab
657ARahim3/kaggle-tpu-lab · PythonA recipe that serves frontier-class open LLMs — GLM-5.3-Flash 320B MoE and Qwen3.8-27B bf16 — on Kaggle's free TPU v5e-8, exposing a public OpenAI-compatible (and Anthropic-compatible) endpoint you can plug into coding agents like Claude Code, Codex, opencode, or pi.
- 18

slotstream
474carloslfu/slotstream · SwiftSlotstream lets you run a 105 GB AI model (Qwen3.8-Flash-Next, a 125B-parameter mixture-of-experts model) on Macs with only 16 to 64 GB of RAM, by streaming most of the model from SSD and caching the busiest experts in memory.
- 19
Qwen3.8-Flash-Next
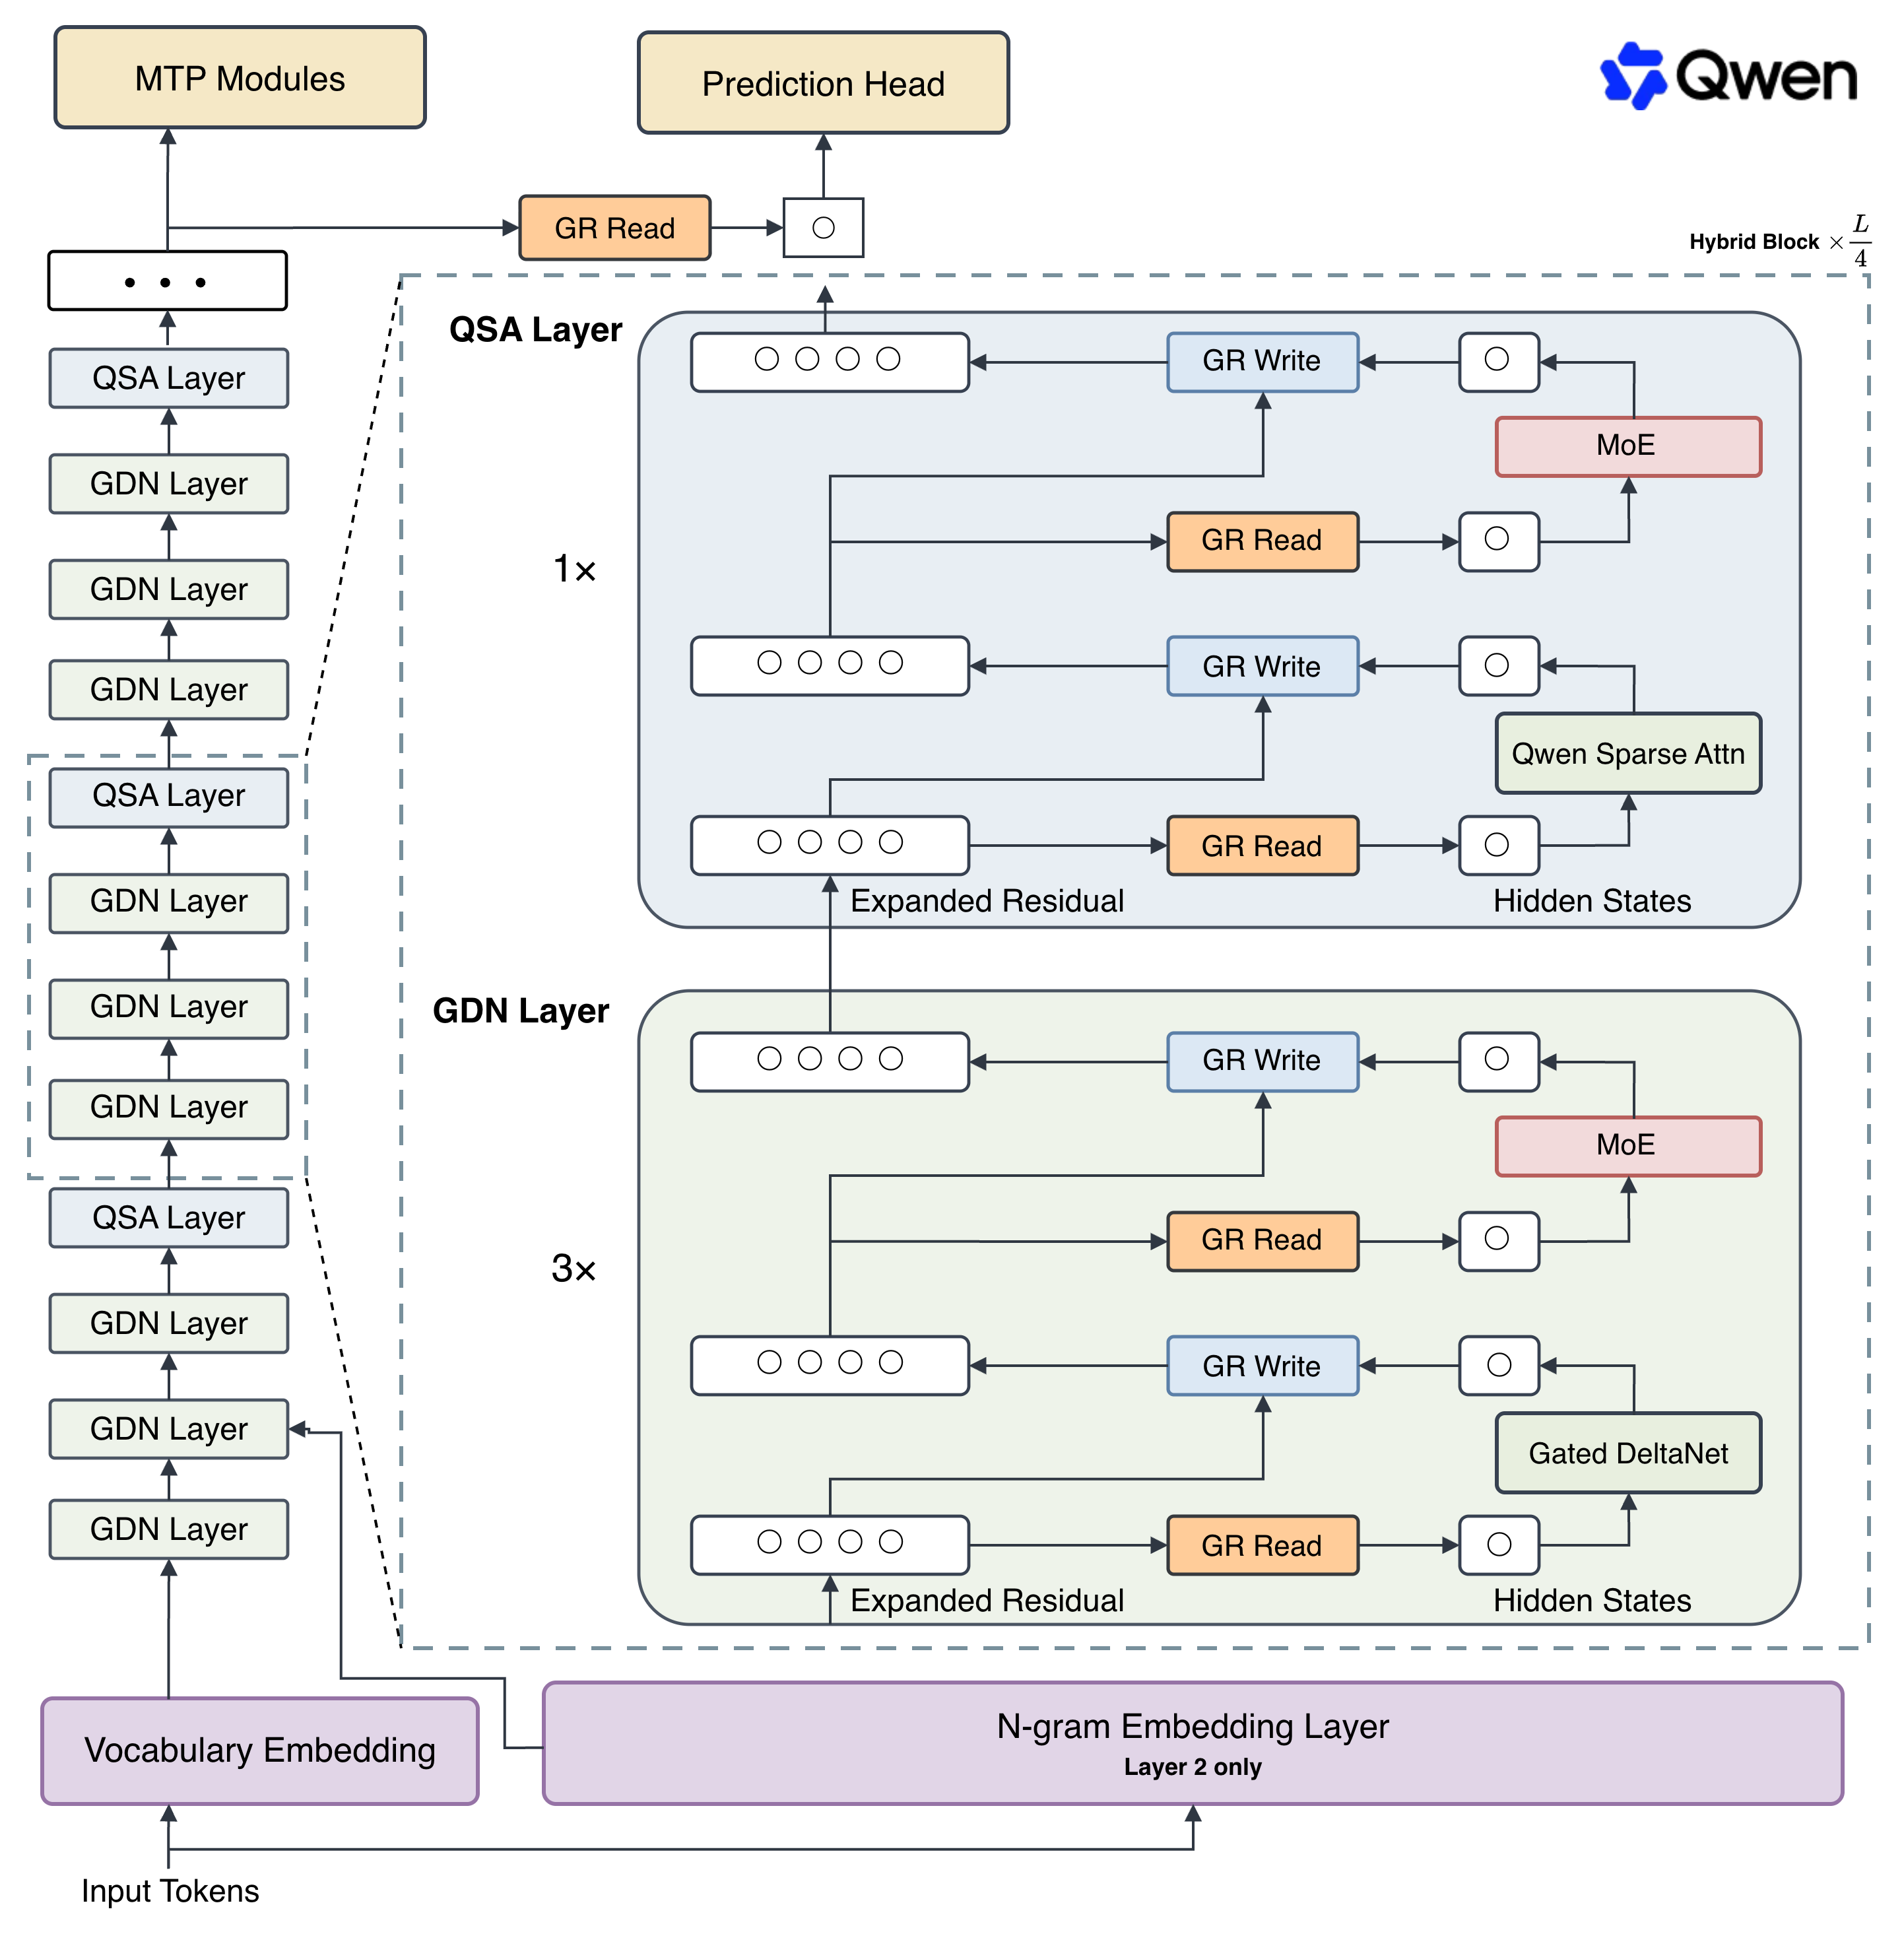
433QwenLM/Qwen3.8-Flash-NextQwen3.8-Flash-Next is an open-weight multimodal Mixture-of-Experts foundation model from Alibaba's Qwen Team, also serving as an early preview of the architecture Alibaba plans to use for the upcoming Qwen4 model family.
- 20
qwen38-uncensored
365Wassimyounes01/qwen38-uncensored · JavaScriptA Node.js install harness that sets up Qwen 3.8 27B as a fully uncensored local model, using weight-level abliterated GGUF weights plus a reinforcement SYSTEM prompt, runnable through Ollama or Apple's MLX.
- 21

Nex-N2.5
267nex-agi/Nex-N2.5Nex-N2.5 is a family of open-weight agentic large language models (mini, Pro, Max) from Nex-AGI built for long-horizon tasks like computer use, web browsing, and autonomous coding, with Max built on a 1.6-trillion-parameter Mixture-of-Experts foundation.
- 22
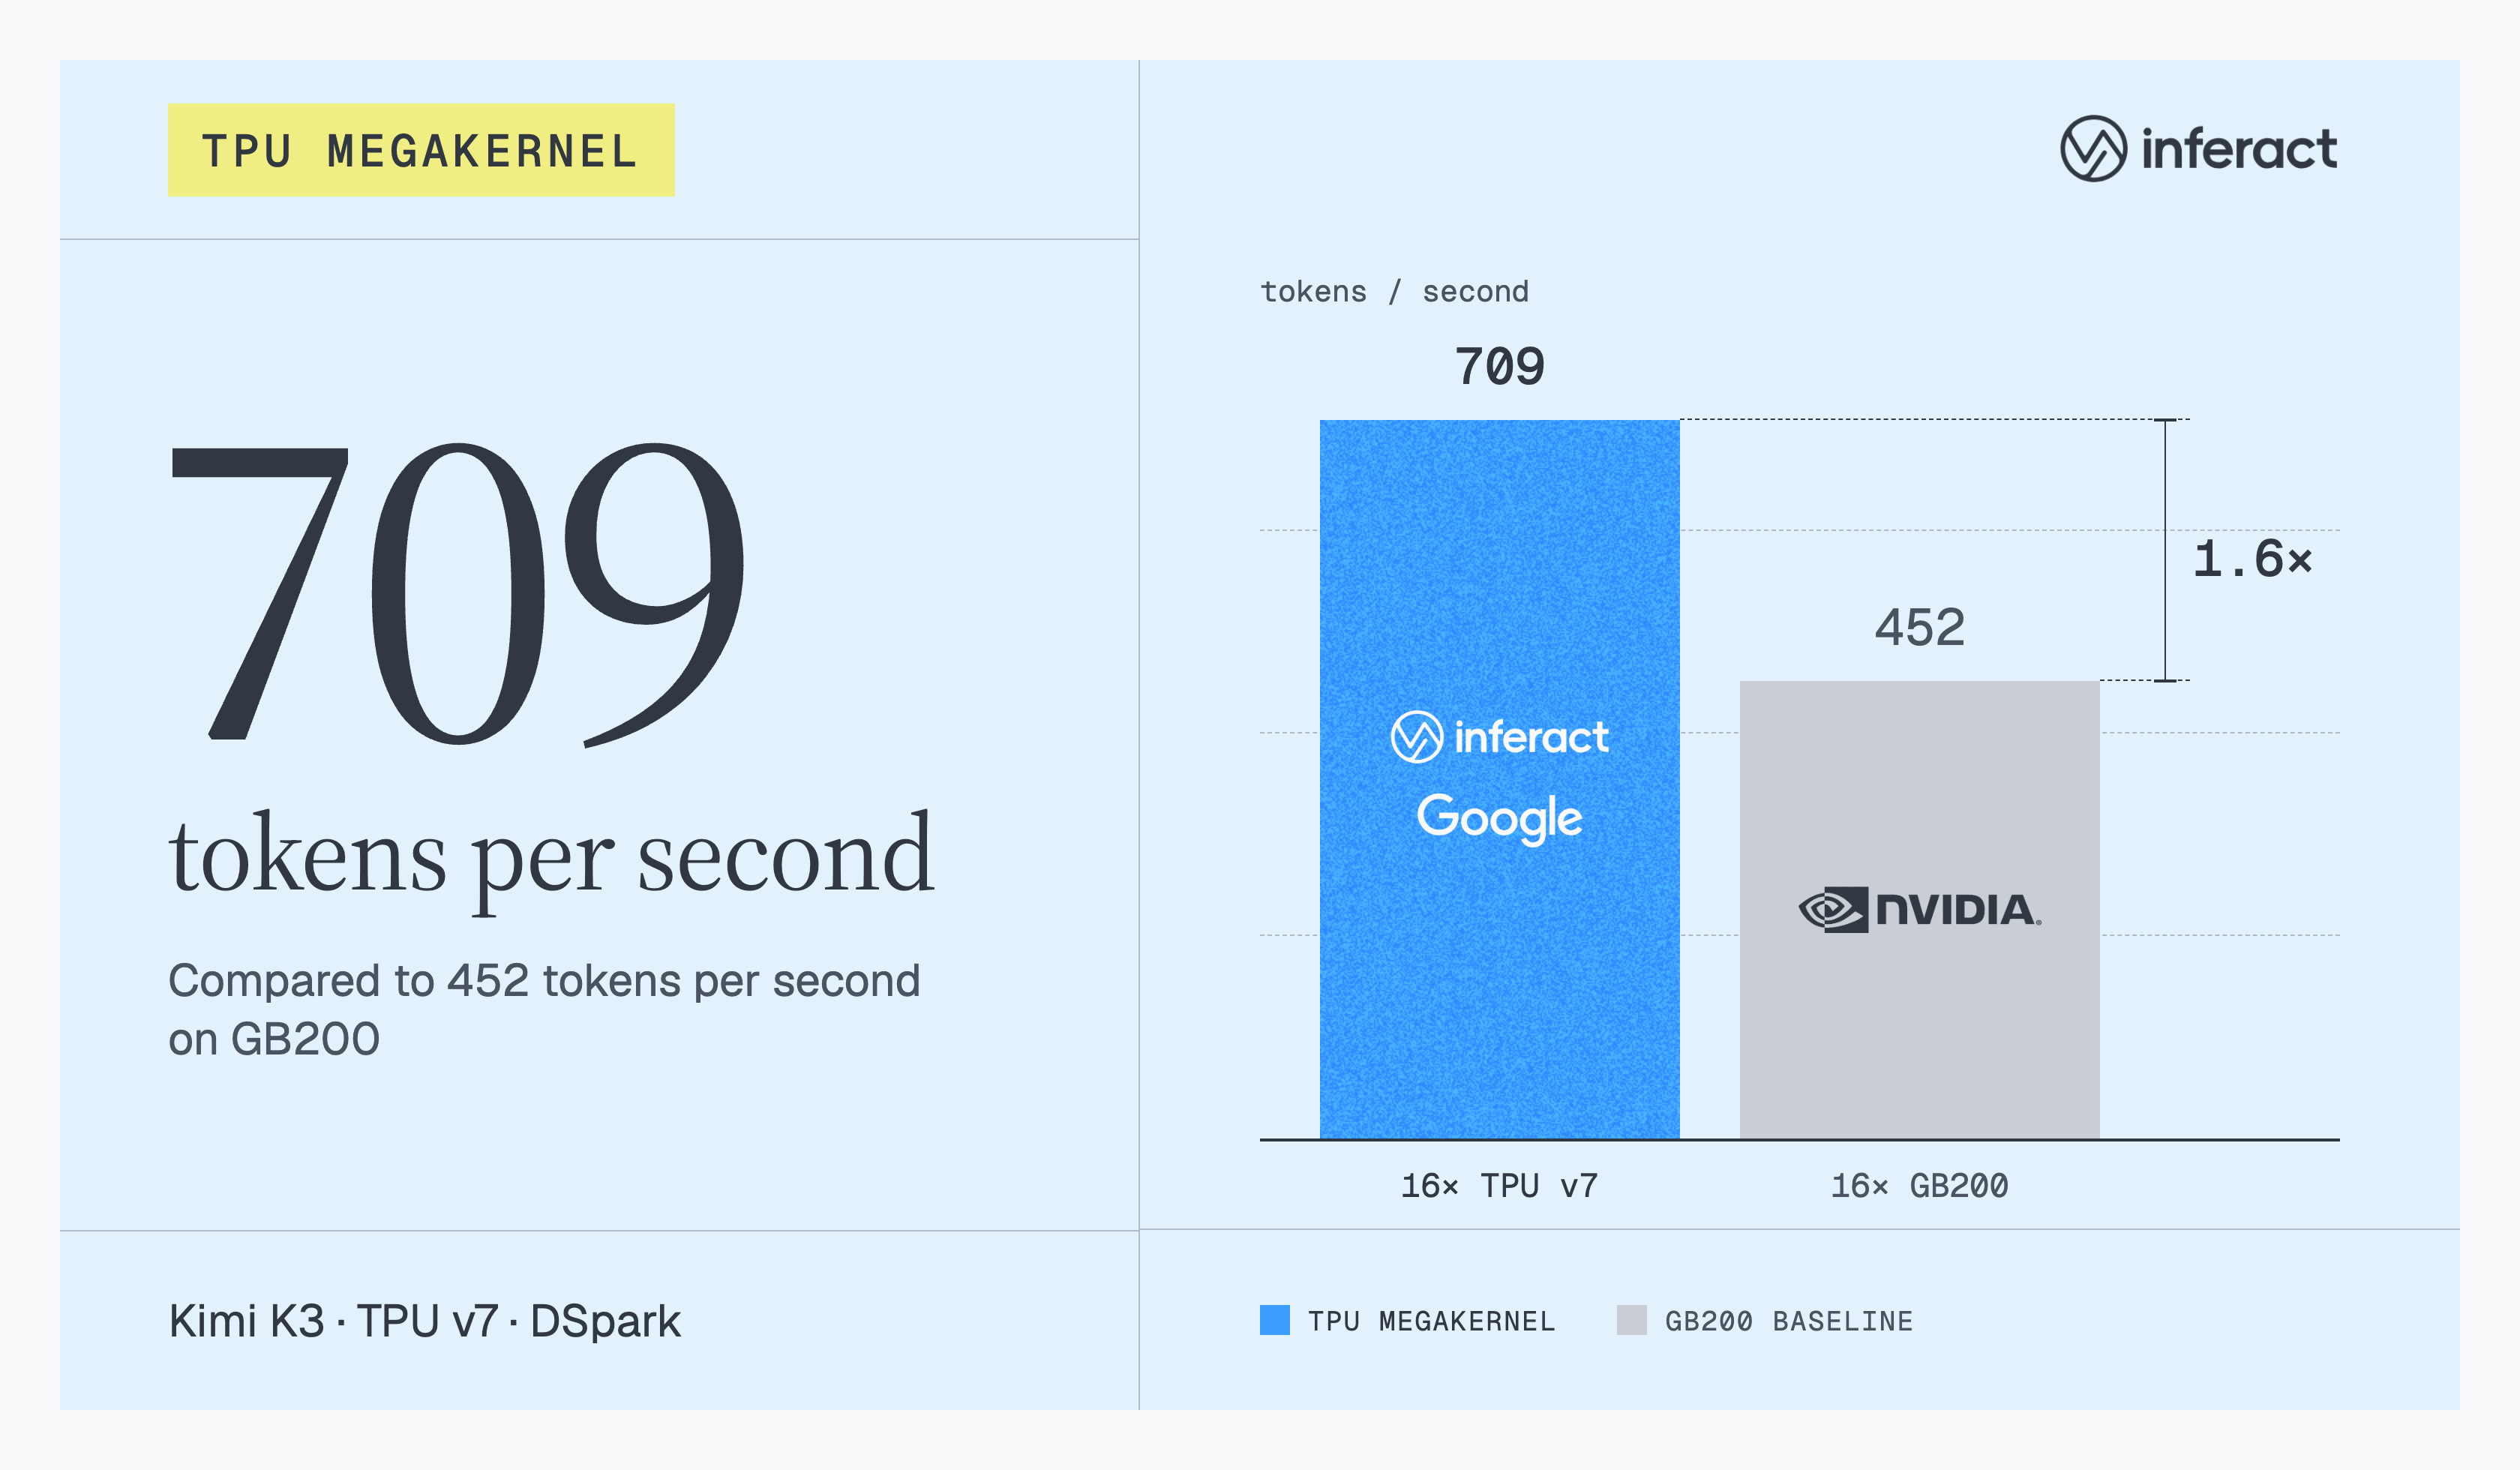
tpu-megakernels
162Inferact/tpu-megakernels · PythonA companion research repo with fused 'megakernel' decode implementations for two models on Google TPUs: Kimi K3 with DSpark speculative decoding, and Qwen3.8-27B with DFlash2 speculative decoding, written to accompany the blog post '700 TPS on Kimi K3: A Case for TPU Megakernels'.
Related topics
Often tagged together
- gpu789
- llm1,483
- python2,383
- qwen154
- inference327
- huggingface362
- linux4,184
- machine-learning916
- cuda396
- llm-inference119
- apache-2.01,434
- deep-learning737
- fine-tuning185
- large-language-models213
- multimodal189
- self-hosted1,929
- vllm124
- ai1,955
- apple-silicon232
- moe57
- benchmark431
- mixture-of-experts46
- openai-compatible211
- quantization183