Topics / #dpo
Dpo projects on GitHub
Direct preference optimization for aligning models with human preferences.
As of , the most-starred Dpo projects on GitHub are unsloth (78.2K stars), trl (19.5K stars) and train-llm-from-scratch (12.2K stars). GitHub.Locker tracks 7 Dpo repositories with 124.4K stars combined. The fastest-growing on October 16 was Soup, with +79 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +79
Soup
MakazhanAlpamys/Soup · ★ 9.2KSoup is a command-line tool for fine-tuning and post-training LLMs from a single YAML config file, automating GPU detection, batching and quantization so you just write a config and run one command.
 +56
unsloth
unslothai/unsloth · ★ 78.2KUnsloth is a local-first app for running and training LLMs, diffusion, TTS and embedding models on your own machine, including models like Qwen3.8, DeepSeek-V4, MiniMax-H3, Gemma 4 and FLUX.
 +20
train-llm-from-scratch
FareedKhan-dev/train-llm-from-scratch · ★ 12.2KA from-scratch tutorial and codebase for training your own LLM end to end: tokenizing raw text, pretraining a GPT-style Transformer, and then post-training it with SFT, a reward model, DPO/ORPO/KTO, PPO and GRPO into an aligned, reasoning-style assistant.
 +11
hands-on-modern-rl
walkinglabs/hands-on-modern-rl · ★ 4.7KHands-On Modern RL is an open-source course and book that walks learners from basic reinforcement learning concepts through LLM alignment (RLHF, DPO, GRPO, RLVR) and into advanced agentic systems, combining theory with runnable code.
The all-time top
7 projects · by stars
- 78.2K#1 · unslothai/unsloth
unsloth
Unsloth is a local-first app for running and training LLMs, diffusion, TTS and embedding models on your own machine, including models like Qwen3.8, DeepSeek-V4, MiniMax-H3, Gemma 4 and FLUX.
- 19.5K
 #2 · huggingface/trl
trl
TRL (Transformers Reinforcement Learning) is a Hugging Face library for post-training foundation models — fine-tuning them with techniques like SFT, GRPO and DPO on top of the Transformers stack.
- 12.2K#3 · FareedKhan-dev/train-llm-from-scratch
train-llm-from-scratch
A from-scratch tutorial and codebase for training your own LLM end to end: tokenizing raw text, pretraining a GPT-style Transformer, and then post-training it with SFT, a reward model, DPO/ORPO/KTO, PPO and GRPO into an aligned, reasoning-style assistant.
- 4
Soup
9.2KMakazhanAlpamys/Soup · PythonSoup is a command-line tool for fine-tuning and post-training LLMs from a single YAML config file, automating GPU detection, batching and quantization so you just write a config and run one command.
- 5
hands-on-modern-rl
4.7Kwalkinglabs/hands-on-modern-rl · PythonHands-On Modern RL is an open-source course and book that walks learners from basic reinforcement learning concepts through LLM alignment (RLHF, DPO, GRPO, RLVR) and into advanced agentic systems, combining theory with runnable code.
- 6
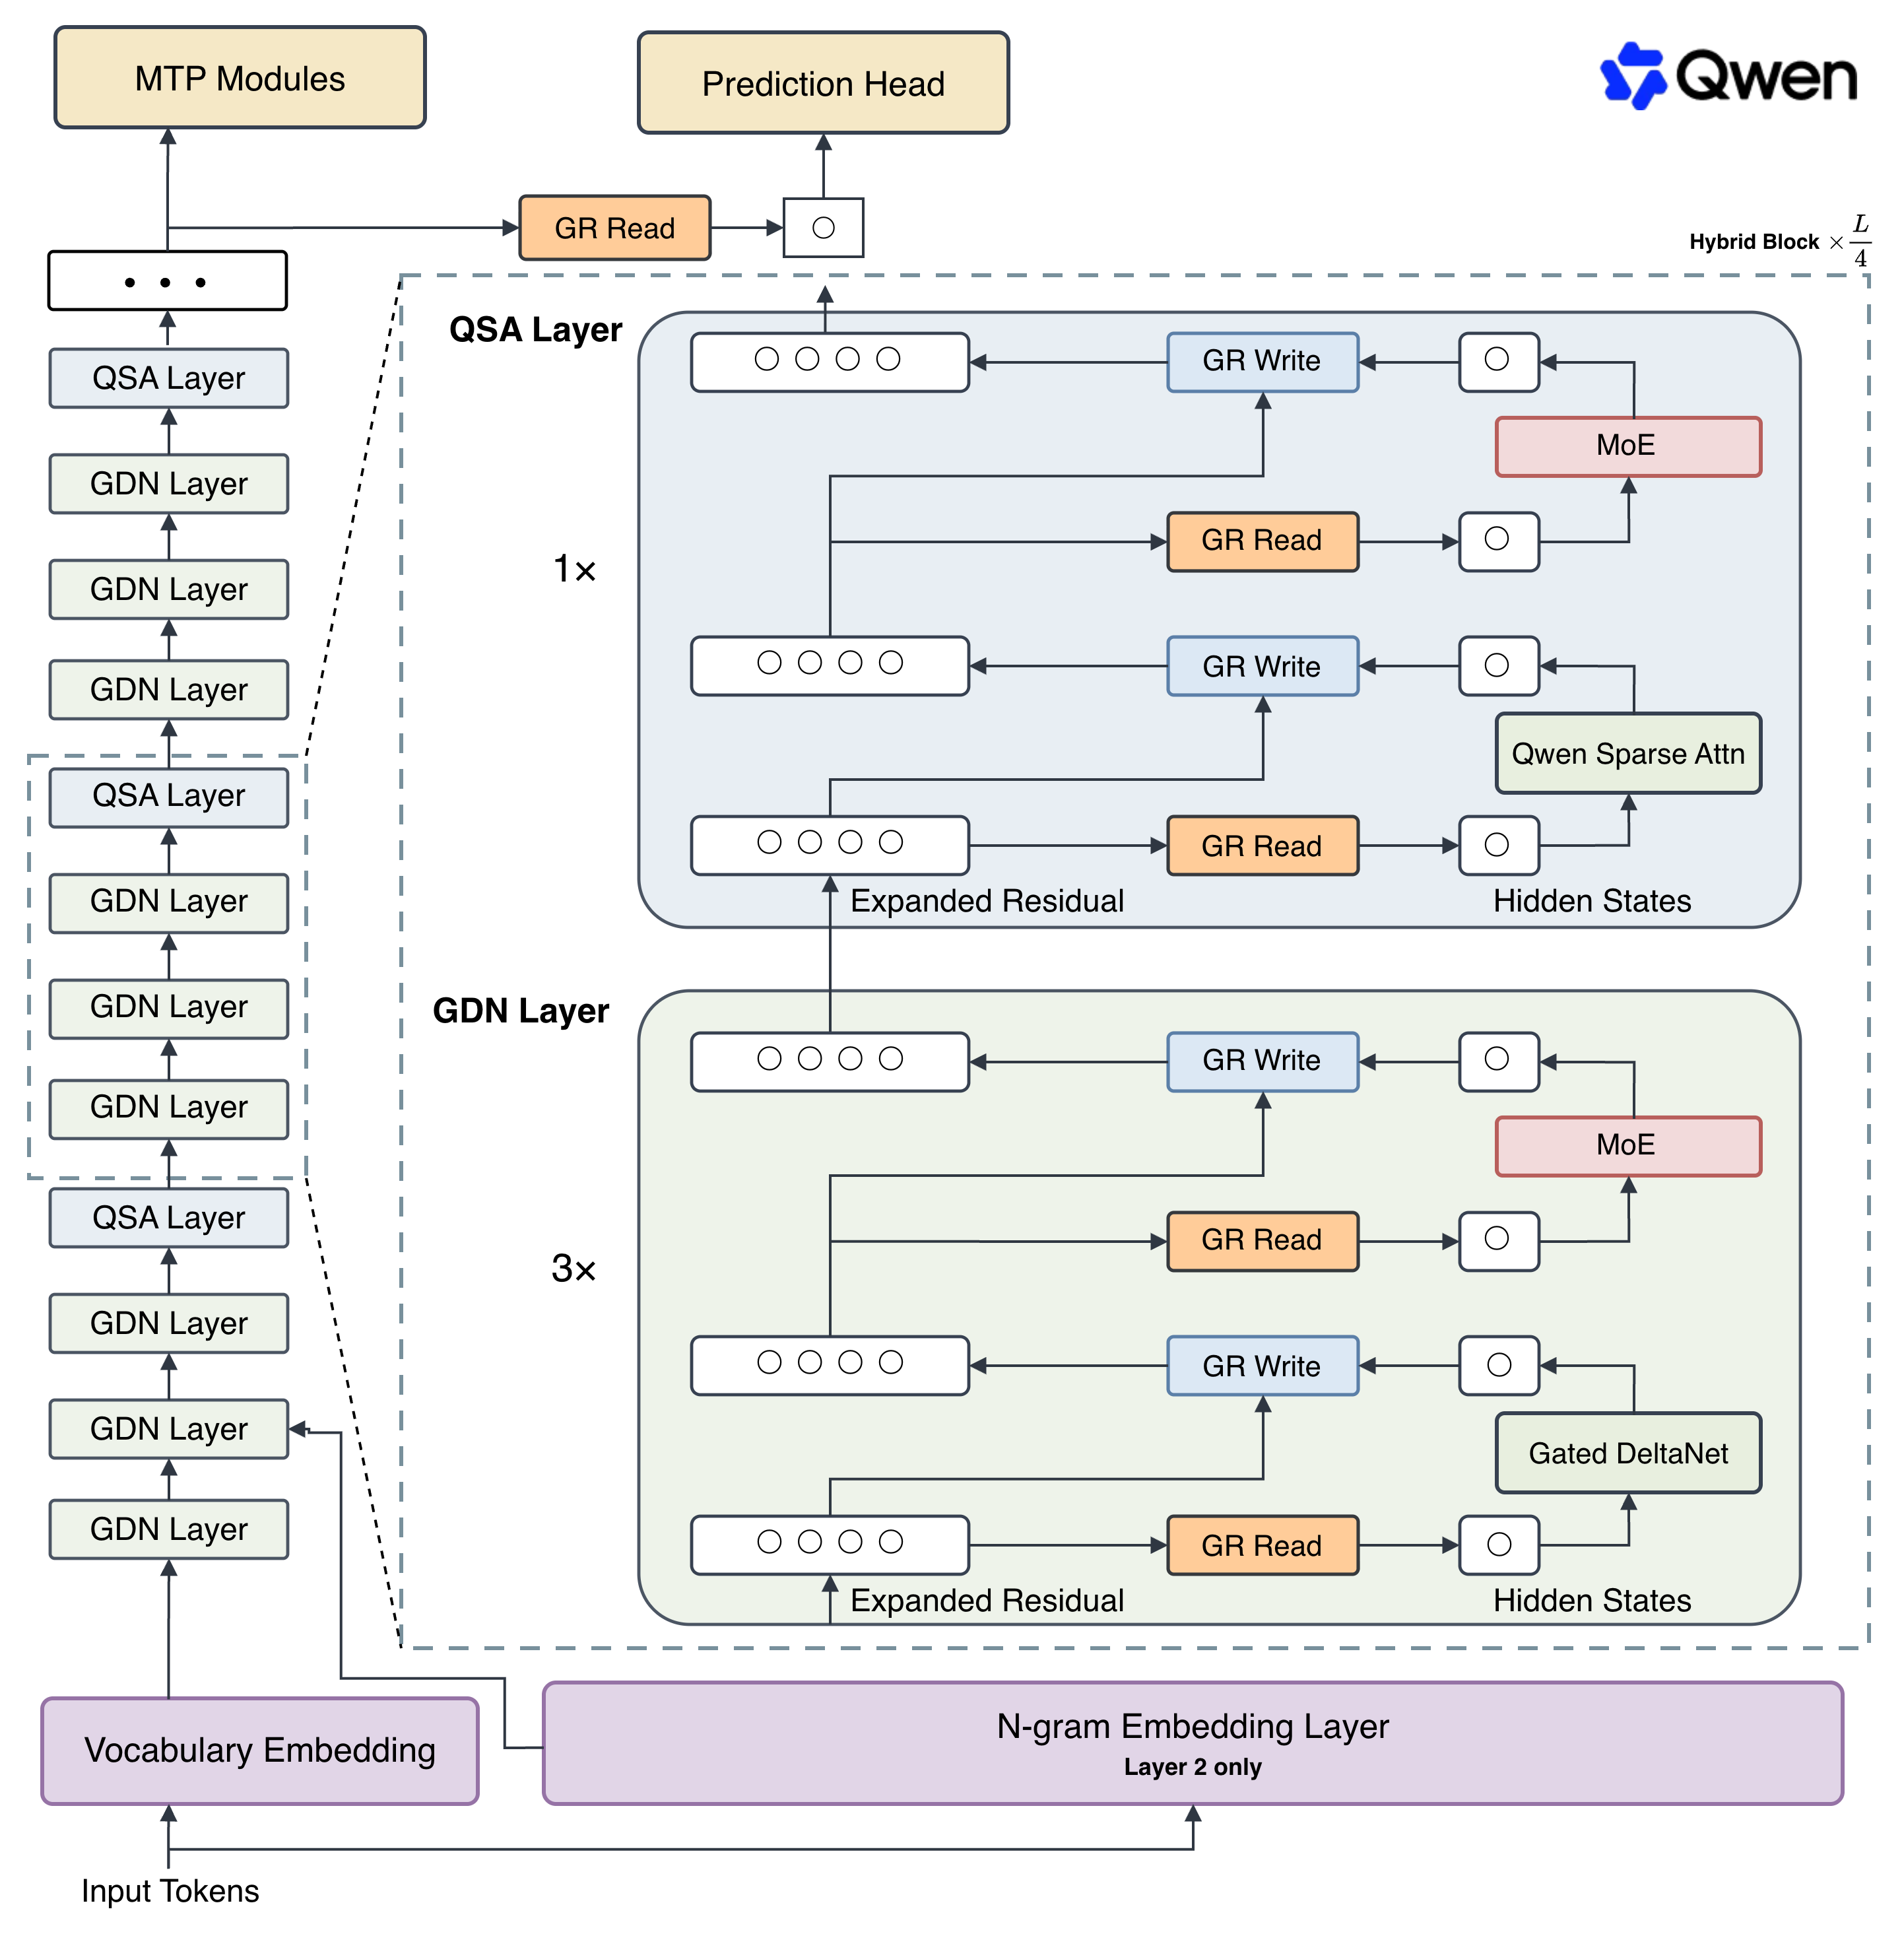
Qwen3.8-Flash-Next
433QwenLM/Qwen3.8-Flash-NextQwen3.8-Flash-Next is an open-weight multimodal Mixture-of-Experts foundation model from Alibaba's Qwen Team, also serving as an early preview of the architecture Alibaba plans to use for the upcoming Qwen4 model family.
- 7

swarm-agent
190lyt2003-yt/swarm-agent · PythonSwarmAgent is a conversational agent that turns natural-language requests like 'choreograph this song, make the second section gentler' into validated drone-swarm trajectories, built on the ReAct paradigm and sitting on top of a separately deployed SwarmGPT service.
Related topics
Often tagged together