Topics / #asr
Asr projects on GitHub
Automatic speech recognition that converts spoken audio into text.
As of , the most-starred Asr projects on GitHub are whisper (110.8K stars), docling (69K stars) and VibeVoice (54.9K stars). GitHub.Locker tracks 33 Asr repositories with 555.5K stars combined. The fastest-growing on October 17 was whisper, with +89 stars in a day.
Hot right now
Most stars gained in a day · Oct 17
 +89
whisper
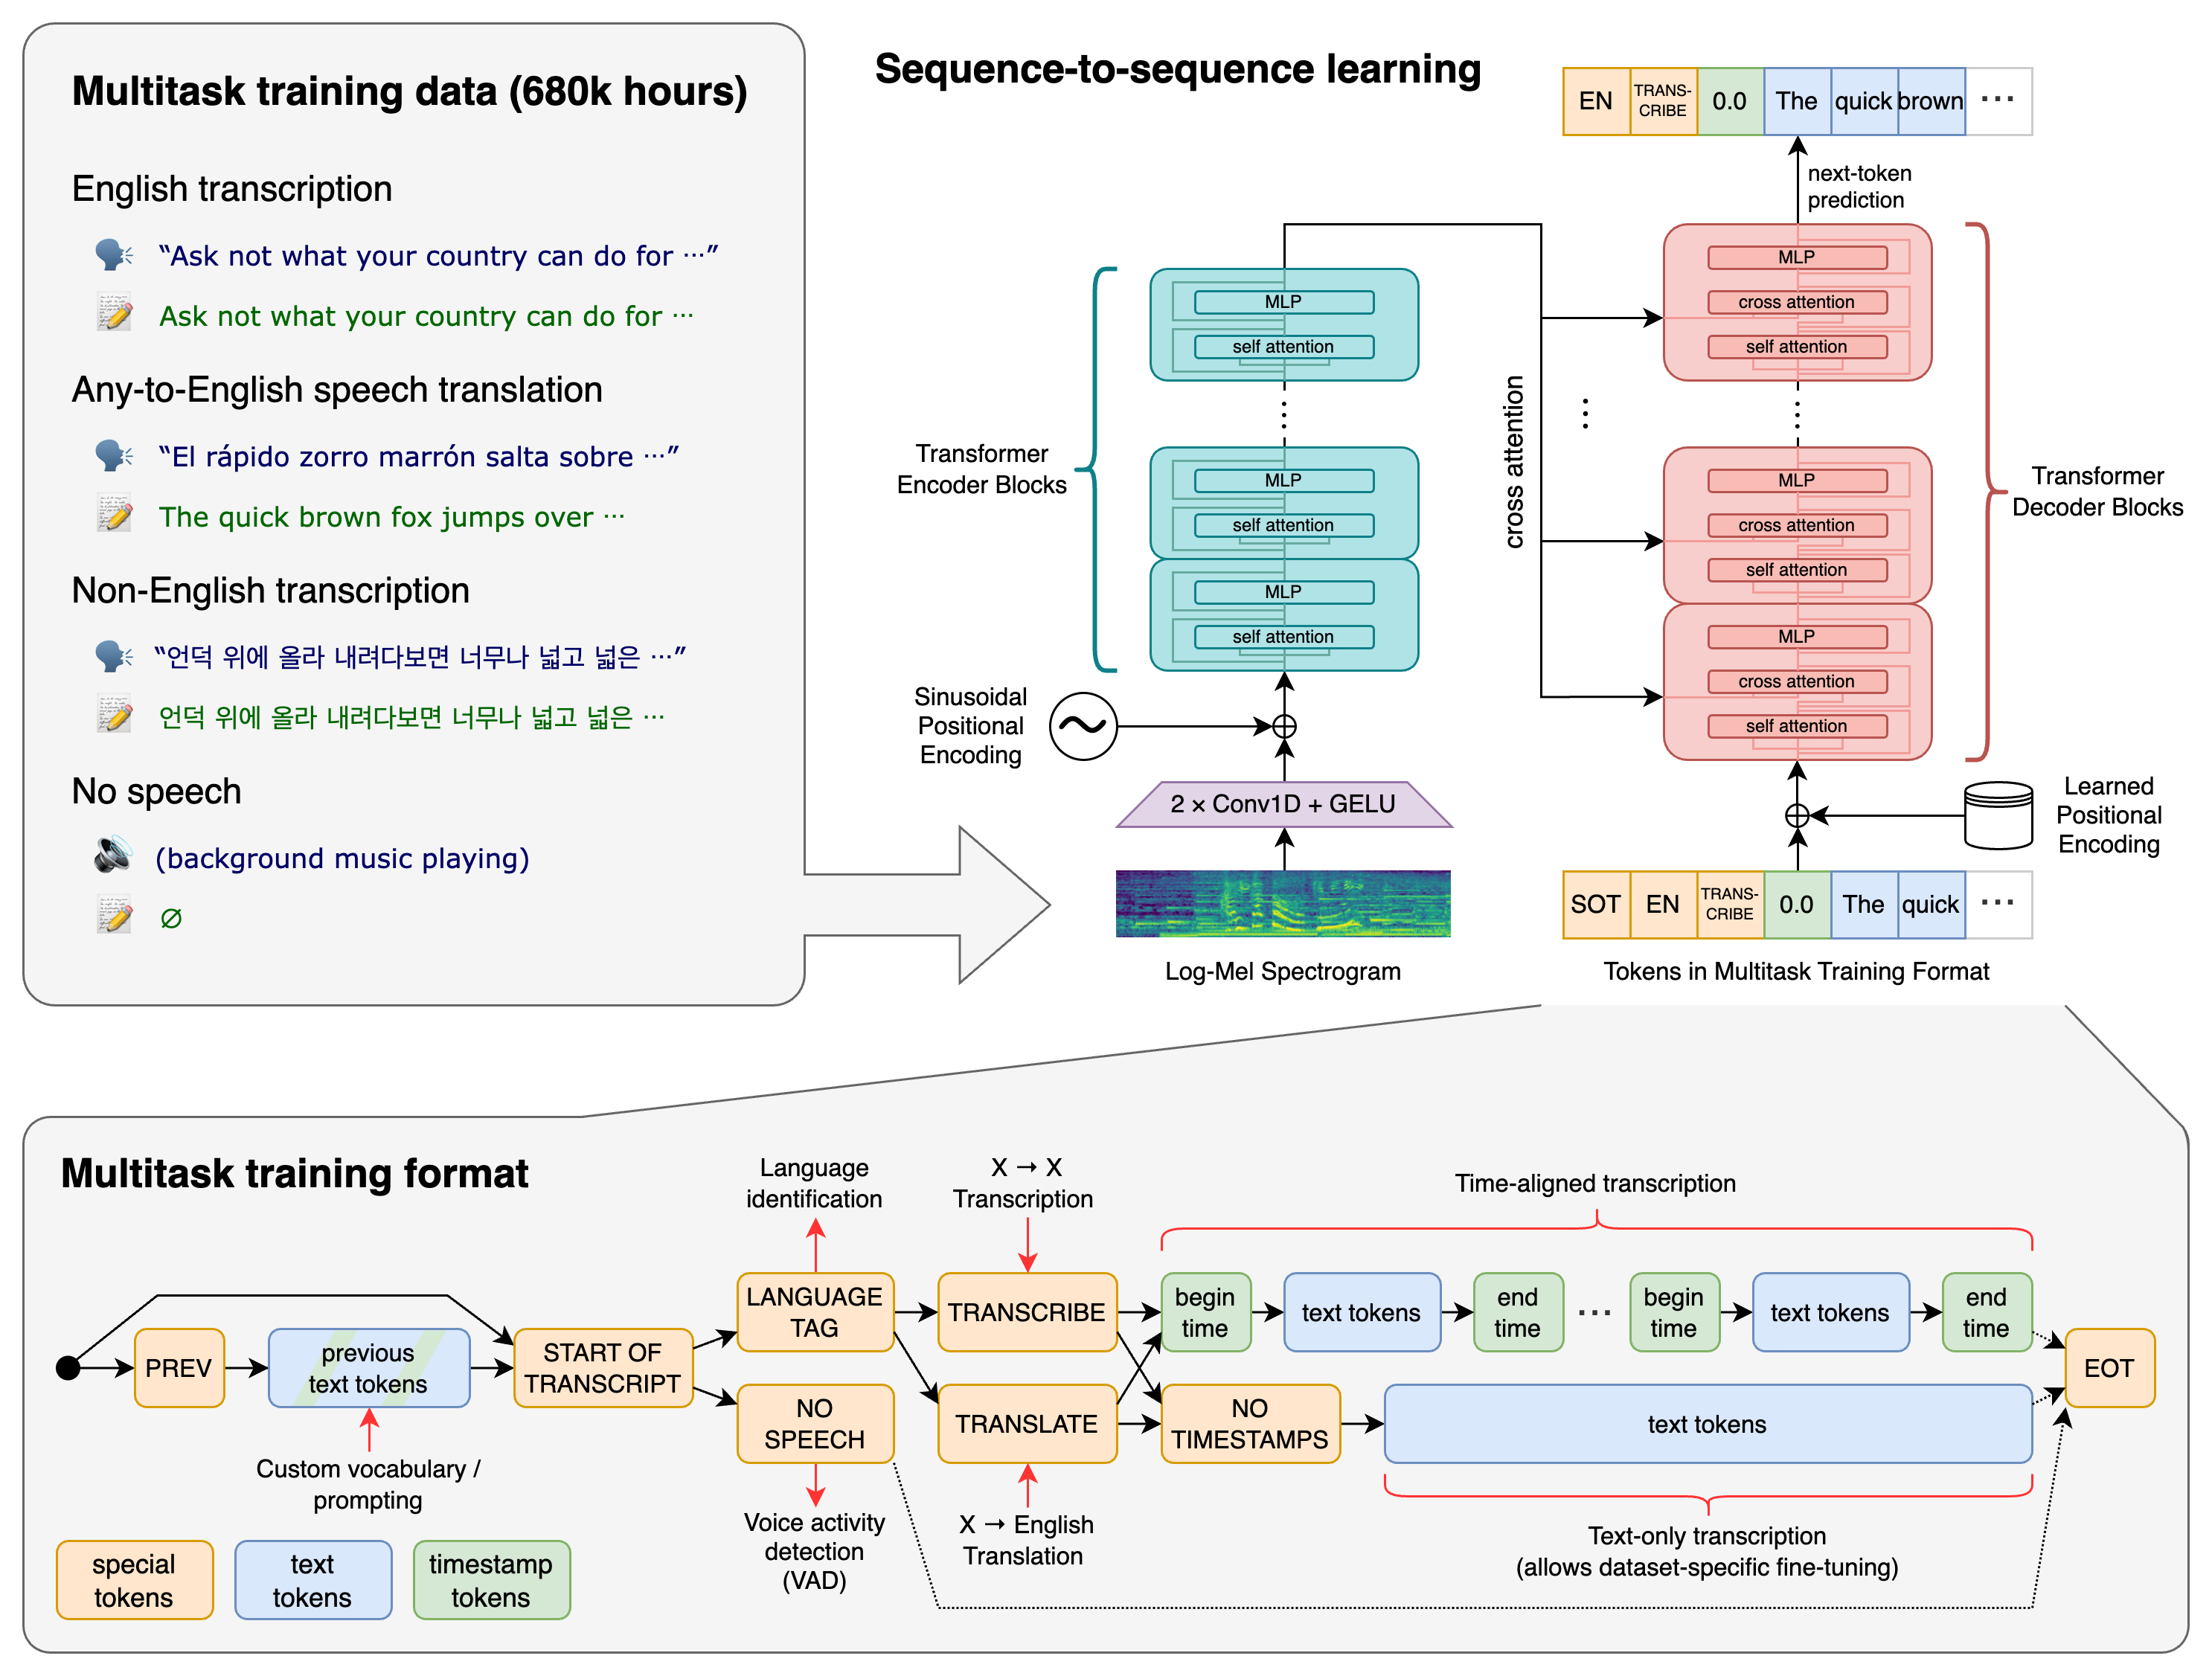
openai/whisper · ★ 110.8KWhisper is a general-purpose speech recognition model trained on a large, diverse dataset with weak supervision. It can perform multilingual transcription, translate speech into English, and identify the spoken language.
 +64
OpenMAIC
THU-MAIC/OpenMAIC · ★ 41KOpenMAIC (Open Multi-Agent Interactive Classroom) is an open-source AI platform that turns any topic or document into an interactive classroom: AI teachers and AI classmates deliver the material, speak out loud, draw on a whiteboard and discuss with you in real time.
 +60
meetily
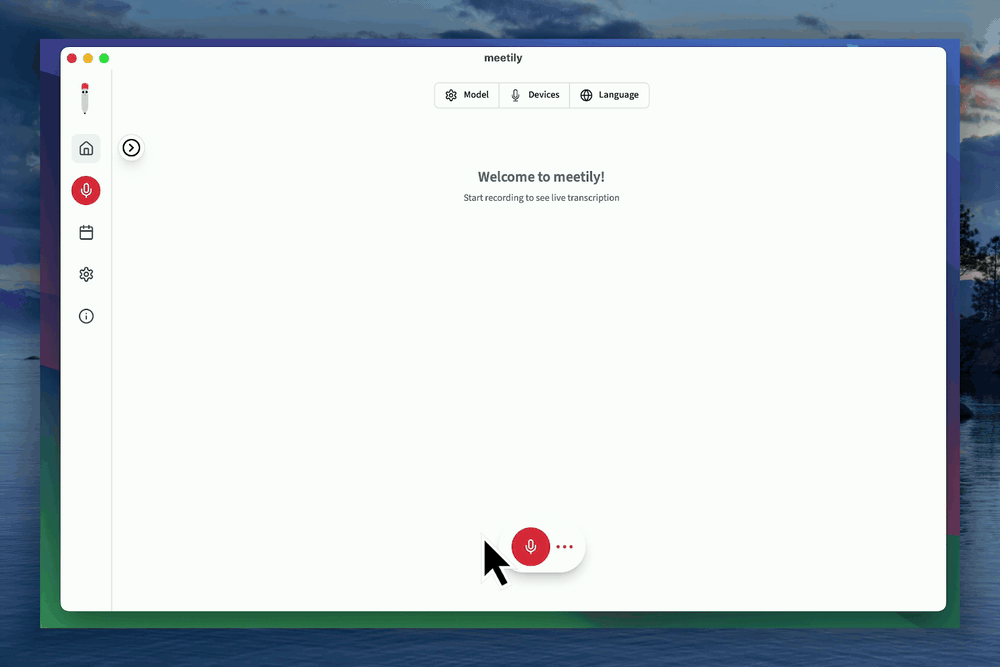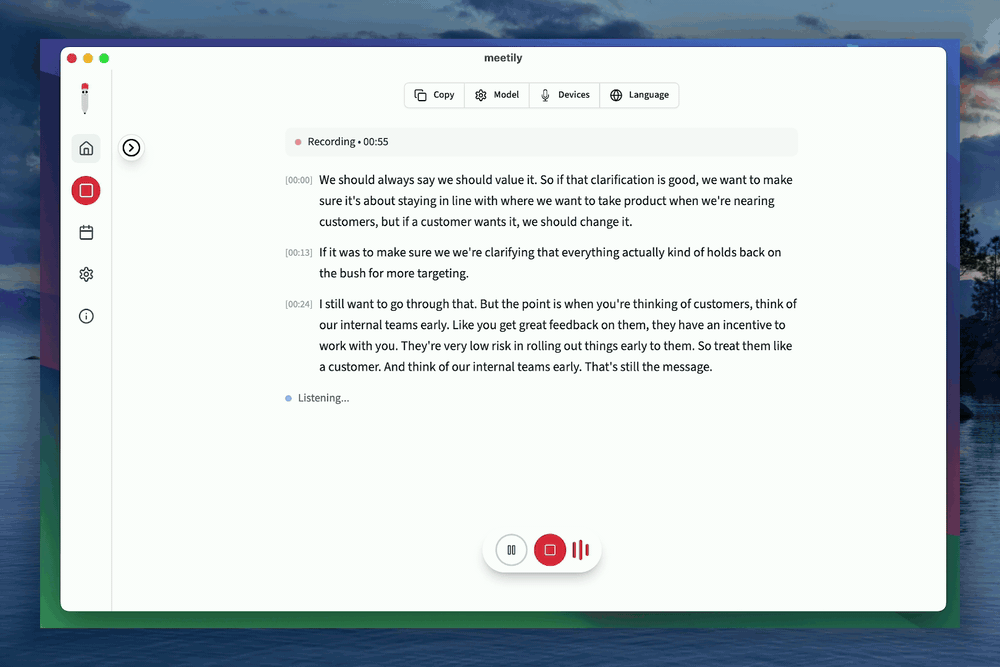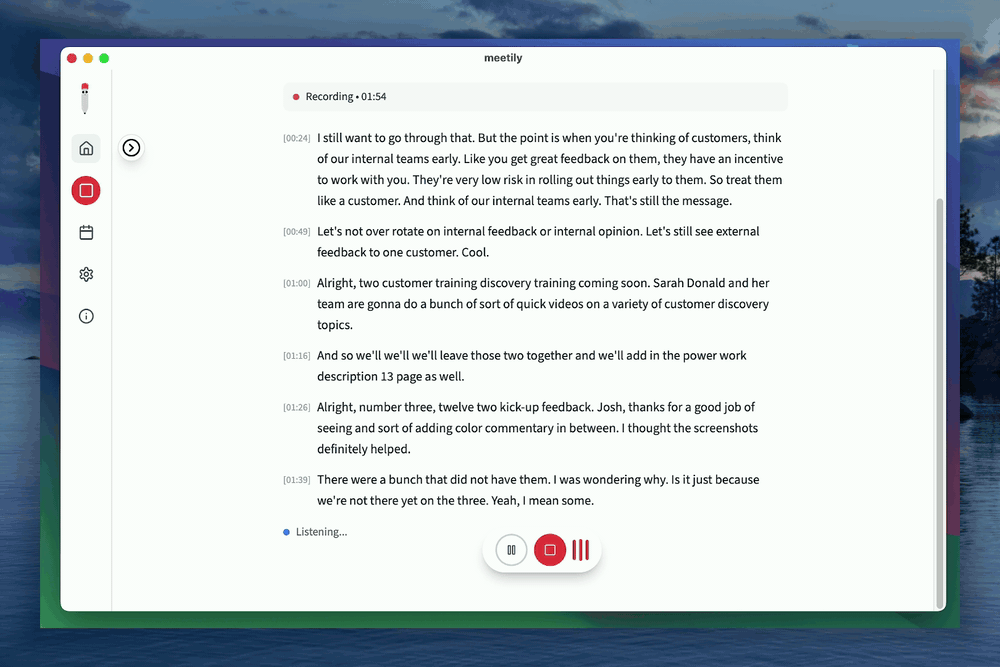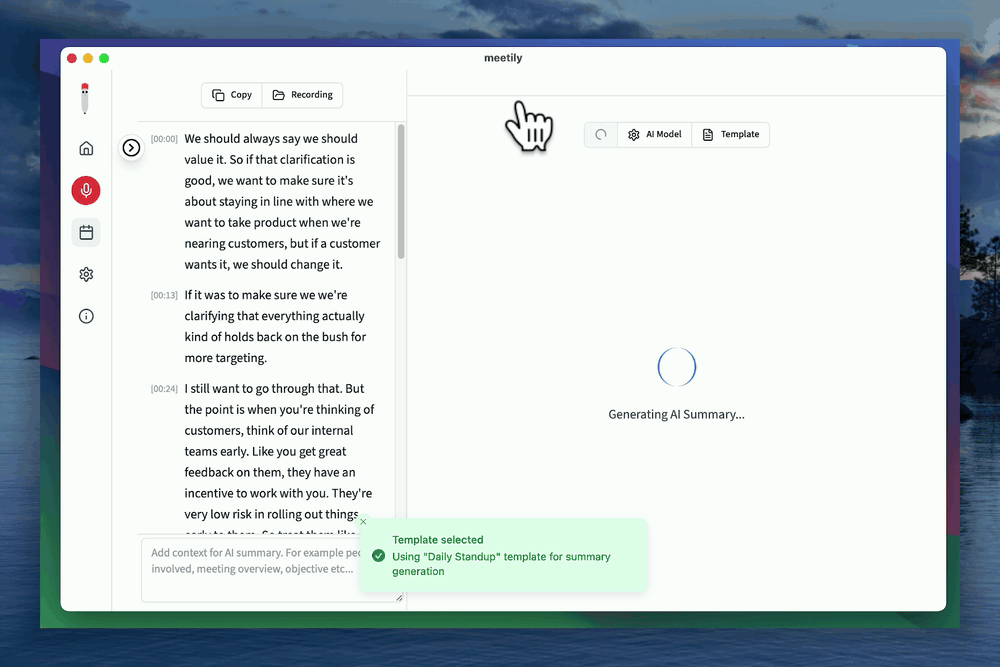
Zackriya-Solutions/meetily · ★ 31.9KA privacy-first AI meeting assistant that captures your meetings, transcribes them in real time, and generates summaries — entirely on your own machine, with no data sent to the cloud.
 +43
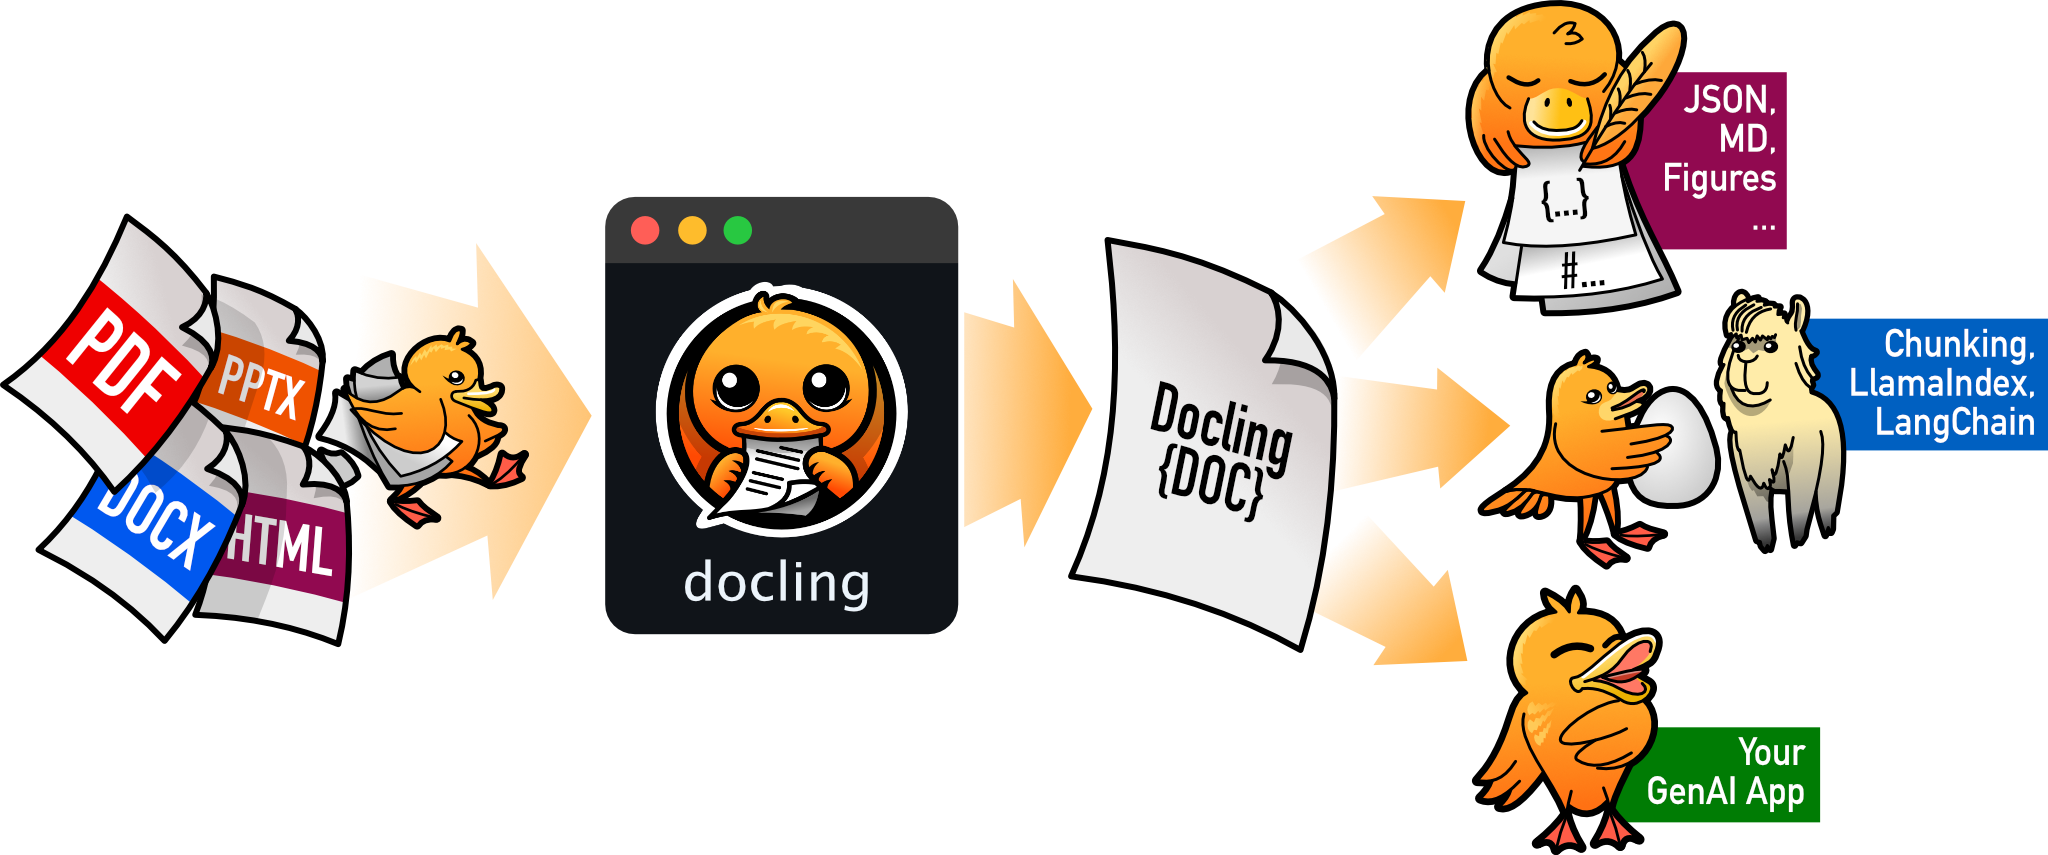
docling
docling-project/docling · ★ 69KDocling parses diverse document formats such as PDF, DOCX, PPTX, XLSX, HTML and more, turning them into a unified representation ready for generative AI pipelines.
The all-time top
33 projects · by stars
- 110.8K#1 · openai/whisper
whisper
Whisper is a general-purpose speech recognition model trained on a large, diverse dataset with weak supervision. It can perform multilingual transcription, translate speech into English, and identify the spoken language.
- 69K#2 · docling-project/docling
docling
Docling parses diverse document formats such as PDF, DOCX, PPTX, XLSX, HTML and more, turning them into a unified representation ready for generative AI pipelines.
- 54.9K
 #3 · microsoft/VibeVoice
VibeVoice
VibeVoice is Microsoft's family of open-source voice AI models covering text-to-speech and speech recognition: long-form multi-speaker TTS, real-time streaming TTS, and ASR built for hour-long recordings.
- 4
OpenMAIC
41KTHU-MAIC/OpenMAIC · TypeScriptOpenMAIC (Open Multi-Agent Interactive Classroom) is an open-source AI platform that turns any topic or document into an interactive classroom: AI teachers and AI classmates deliver the material, speak out loud, draw on a whiteboard and discuss with you in real time.
- 5
meetily
31.9KZackriya-Solutions/meetily · RustA privacy-first AI meeting assistant that captures your meetings, transcribes them in real time, and generates summaries — entirely on your own machine, with no data sent to the cloud.
- 6

DeepSpeech
26.8Kmozilla/DeepSpeech · C++Mozilla DeepSpeech is an open-source Speech-To-Text engine — a machine-learning model that turns audio into text on your own hardware.
- 7

faster-whisper
25.9KSYSTRAN/faster-whisper · PythonA Python reimplementation of OpenAI's Whisper model on CTranslate2, a fast Transformer inference engine — up to 4x faster than the original at the same accuracy, using less memory, with optional 8-bit quantization on CPU and GPU.
- 8
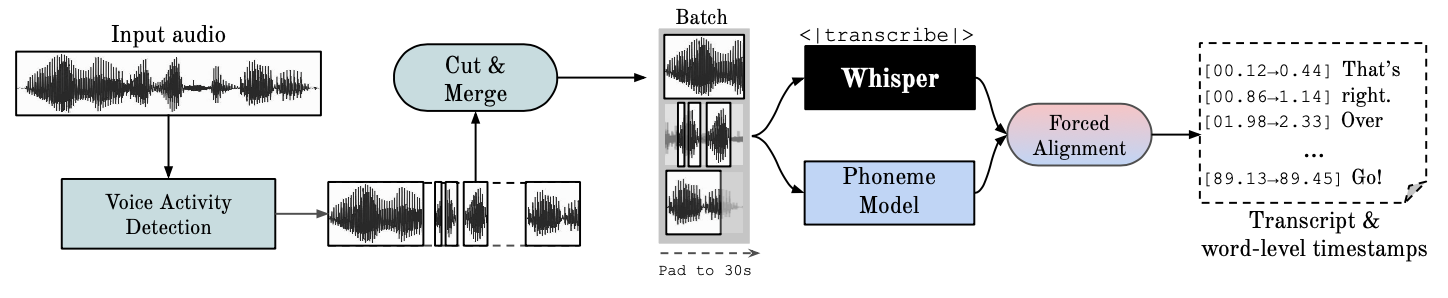
whisperX
24.6Km-bain/whisperX · PythonWhisperX is an open-source speech recognition tool that transcribes audio with accurate word-level timestamps and optional speaker diarization. It builds on OpenAI's Whisper and came out of PhD research at the University of Oxford.
- 9
FunASR
20.7Kmodelscope/FunASR · PythonFunASR is an open-source industrial speech recognition toolkit covering ASR, VAD, punctuation, speaker diarization, and emotion/audio-event models, deployable offline, in streaming mode, on edge devices, or behind an OpenAI-compatible API.
- 10

Speech
18.6KNVIDIA-NeMo/Speech · PythonAn open-source NVIDIA framework for building speech AI models — automatic speech recognition (ASR), text-to-speech (TTS), and speech LLMs — with pre-trained checkpoints you can customize and deploy.
- 11

kaldi
15.5Kkaldi-asr/kaldi · ShellKaldi is an open-source speech recognition toolkit: C++ code plus example recipes for building speech-to-text, speaker-ID and speaker-verification systems.
- 12

sherpa-onnx
15.3Kk2-fsa/sherpa-onnx · C++sherpa-onnx is an offline toolkit for speech-to-text, text-to-speech, speaker diarization, speaker identification/verification, spoken language identification, audio tagging, VAD, speech enhancement, keyword spotting and source separation, built on next-gen Kaldi and ONNX Runtime, with no internet connection required.
- 13

vosk-api
15.2Kalphacep/vosk-api · Jupyter NotebookVosk is an offline, open-source speech recognition toolkit that transcribes speech to text in over 20 languages and dialects, running entirely on-device without needing an internet connection.
- 14

Fay
13.6Kxszyou/Fay · PythonAn open-source Python agent framework that connects a digital human or an LLM to your business systems: it adapts to various avatar model tech and LLMs on top, and serves digital-human APIs down to microcontrollers, apps and websites.
- 15
PaddleSpeech
12.7KPaddlePaddle/PaddleSpeech · PythonPaddleSpeech is an open-source speech and audio toolkit built on the PaddlePaddle platform, covering tasks like Automatic Speech Recognition (ASR), Text-to-Speech (TTS), Speaker Verification, Speech Translation, Keyword Spotting and Punctuation Restoration. It won the NAACL2022 Best Demo Award.
- 16

speechbrain
11.9Kspeechbrain/speechbrain · PythonAn open-source, PyTorch-based toolkit for Conversational AI — the technology behind speech assistants and chatbots. It bundles training recipes and pretrained models for a wide range of speech and text processing tasks.
- 17
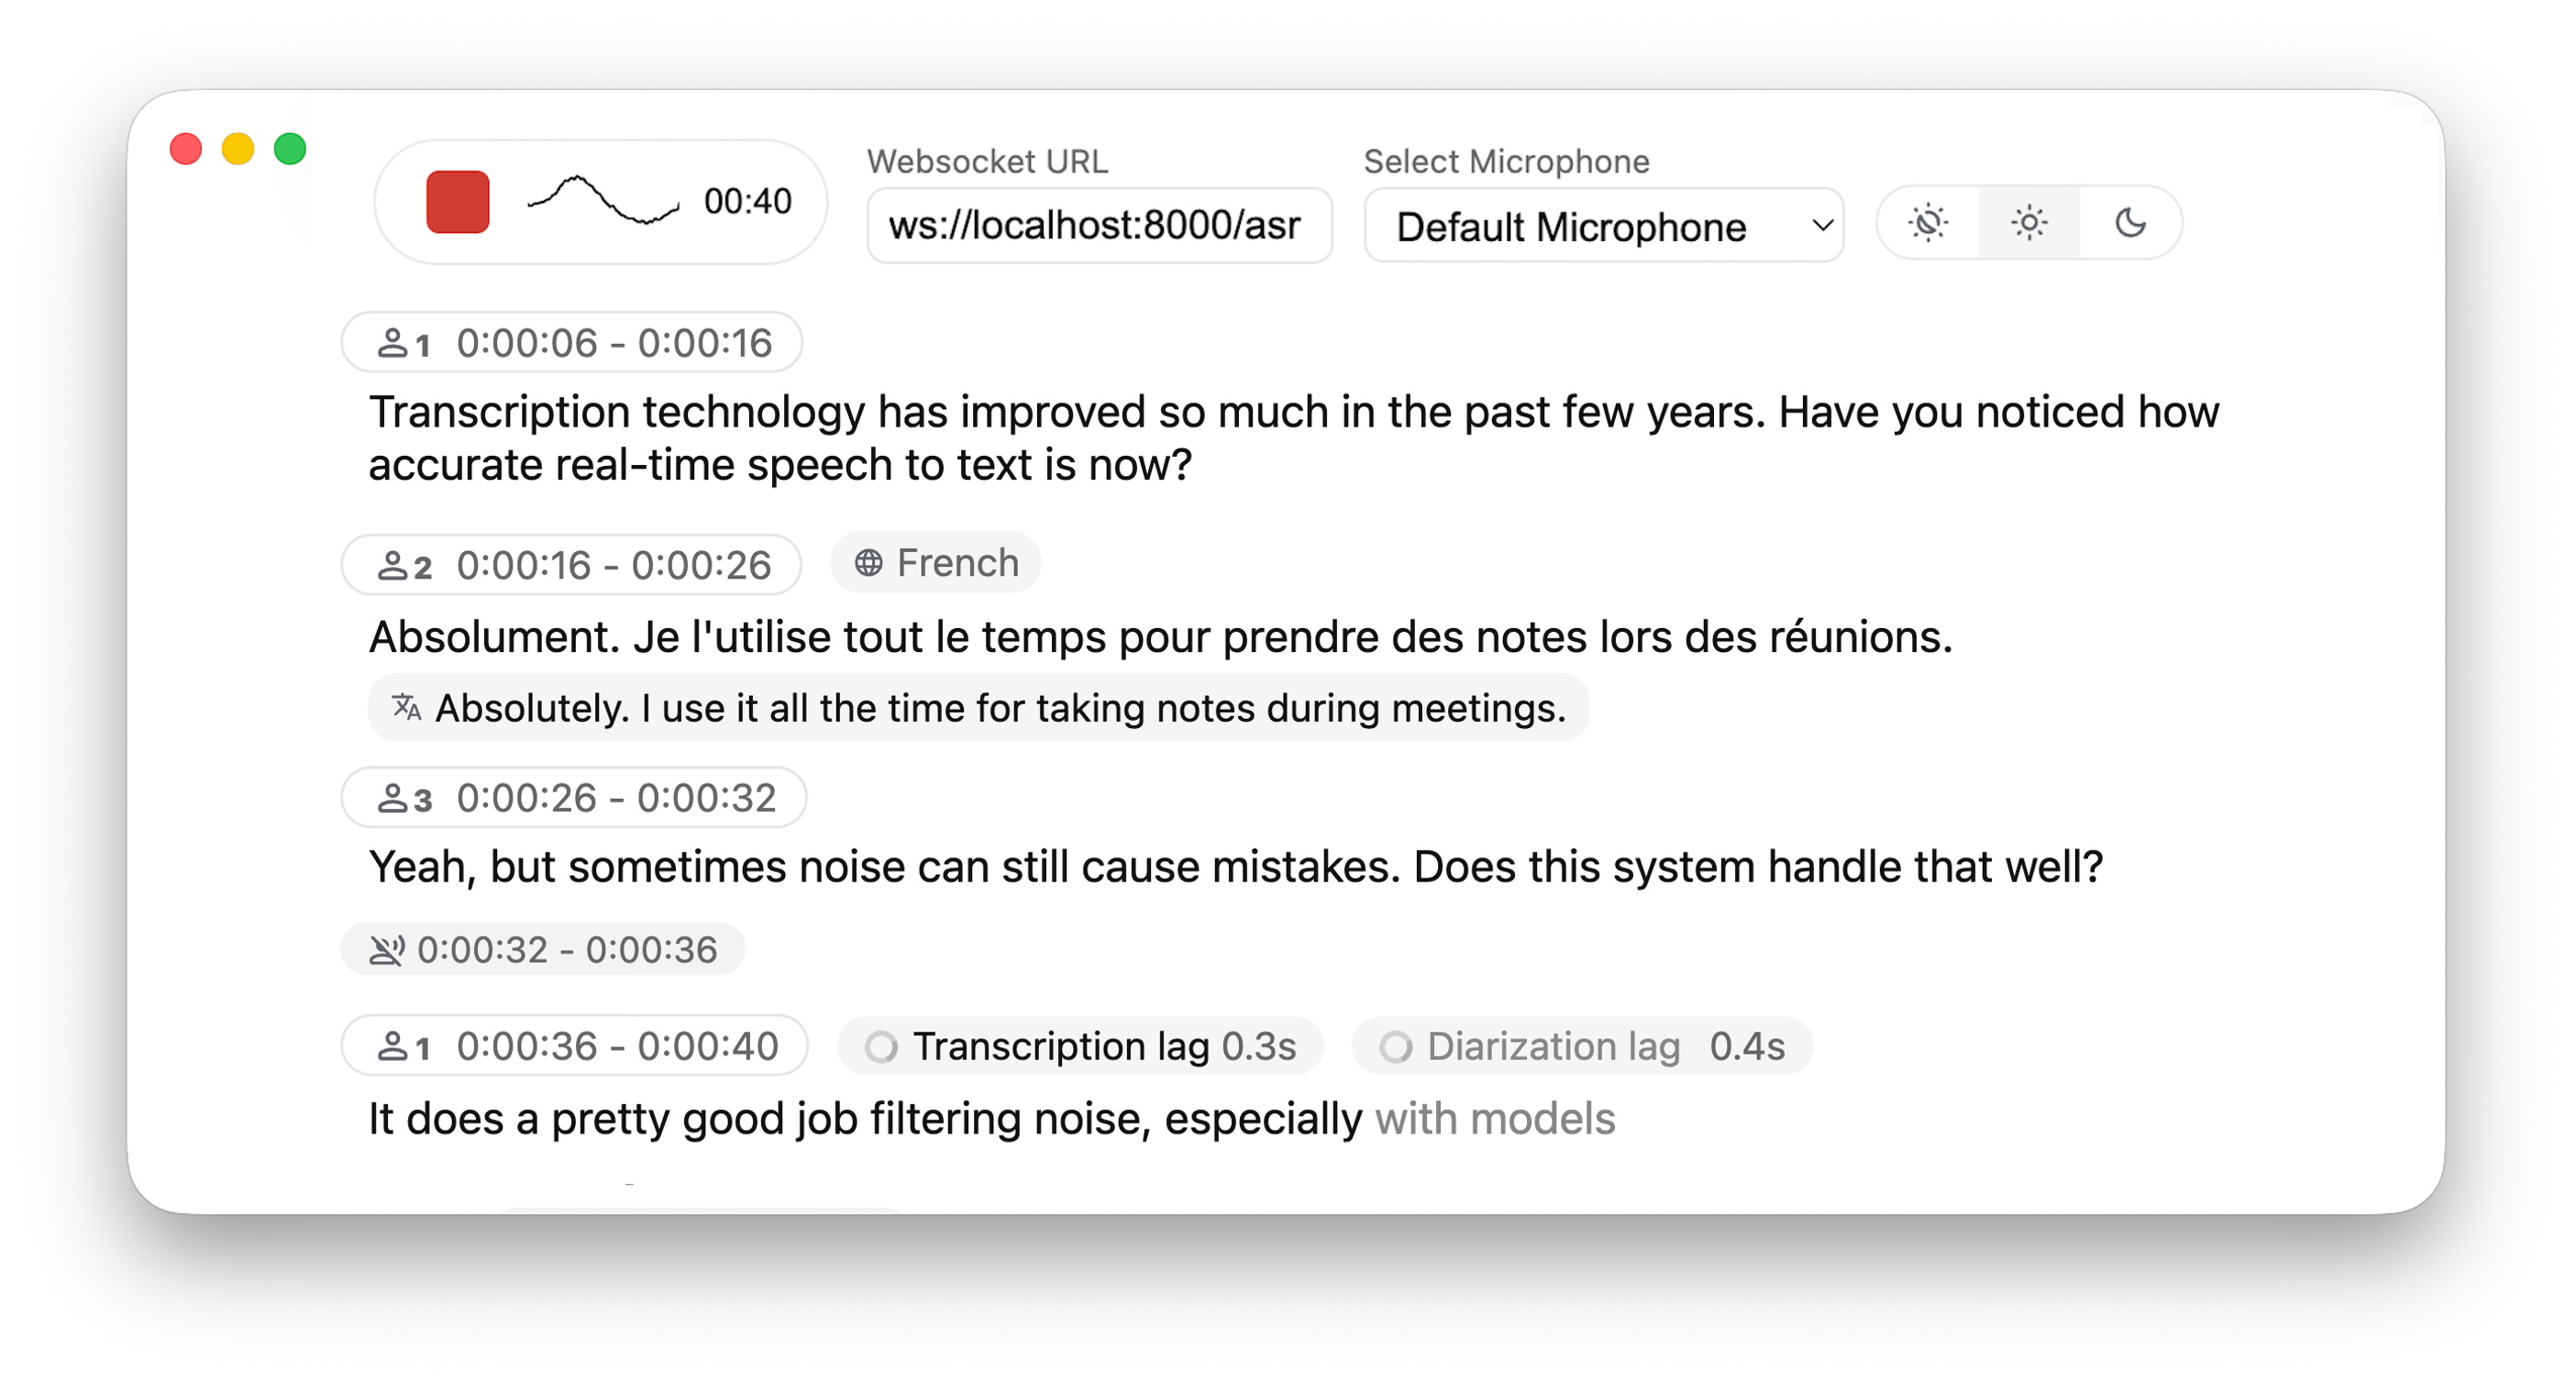
WhisperLiveKit
11.1KQuentinFuxa/WhisperLiveKit · PythonWhisperLiveKit is a self-hosted pipeline for real-time, local speech-to-text with streaming ASR, speaker diarization, live translation, and OpenAI/Deepgram-compatible APIs.
- 18

xiaozhi-esp32-server
10.9Kxinnan-tech/xiaozhi-esp32-server · JavaScriptIt is the backend server for the xiaozhi-esp32 voice assistant hardware. It handles ASR, LLM dialogue, TTS and device control, so your ESP32 gadget talks to a server you host yourself instead of a third-party one.
- 19
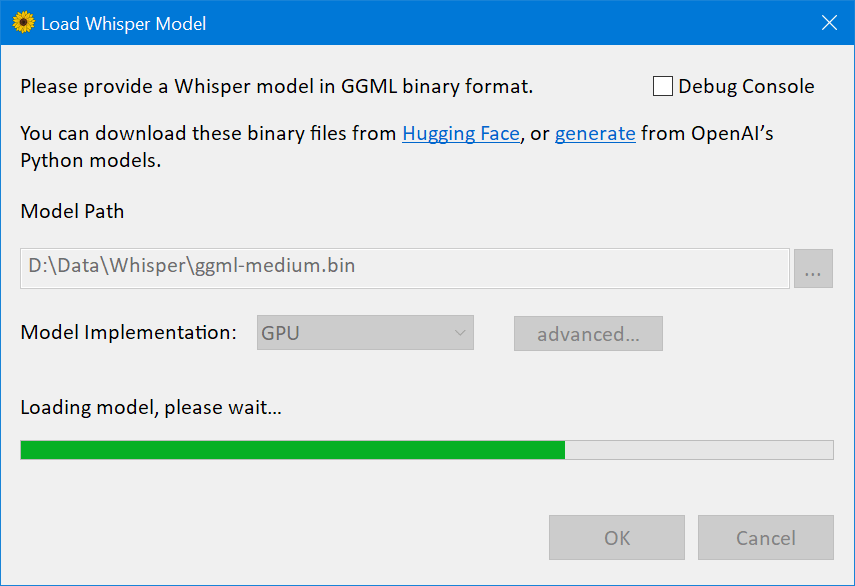
Whisper
10.7KConst-me/Whisper · C++A Windows port of OpenAI's Whisper speech-recognition model that runs inference on the GPU using DirectCompute instead of CUDA, delivering much faster transcription than the official PyTorch implementation.
- 20

openless
3.9KOpen-Less/openless · RustOpenLess is an open-source voice-input app for macOS, Windows, and Linux: hold a hotkey, speak, and AI-polished text is inserted directly at your cursor in any app.
- 21
msime-windows
3Kmetasequoiaime/msime-windows · C++Metasequoia IME (水杉输入法) is a free, open-source Windows input method for Chinese and Japanese, built entirely on the TSF (Text Services Framework) architecture.
- 22
FireRedAudio
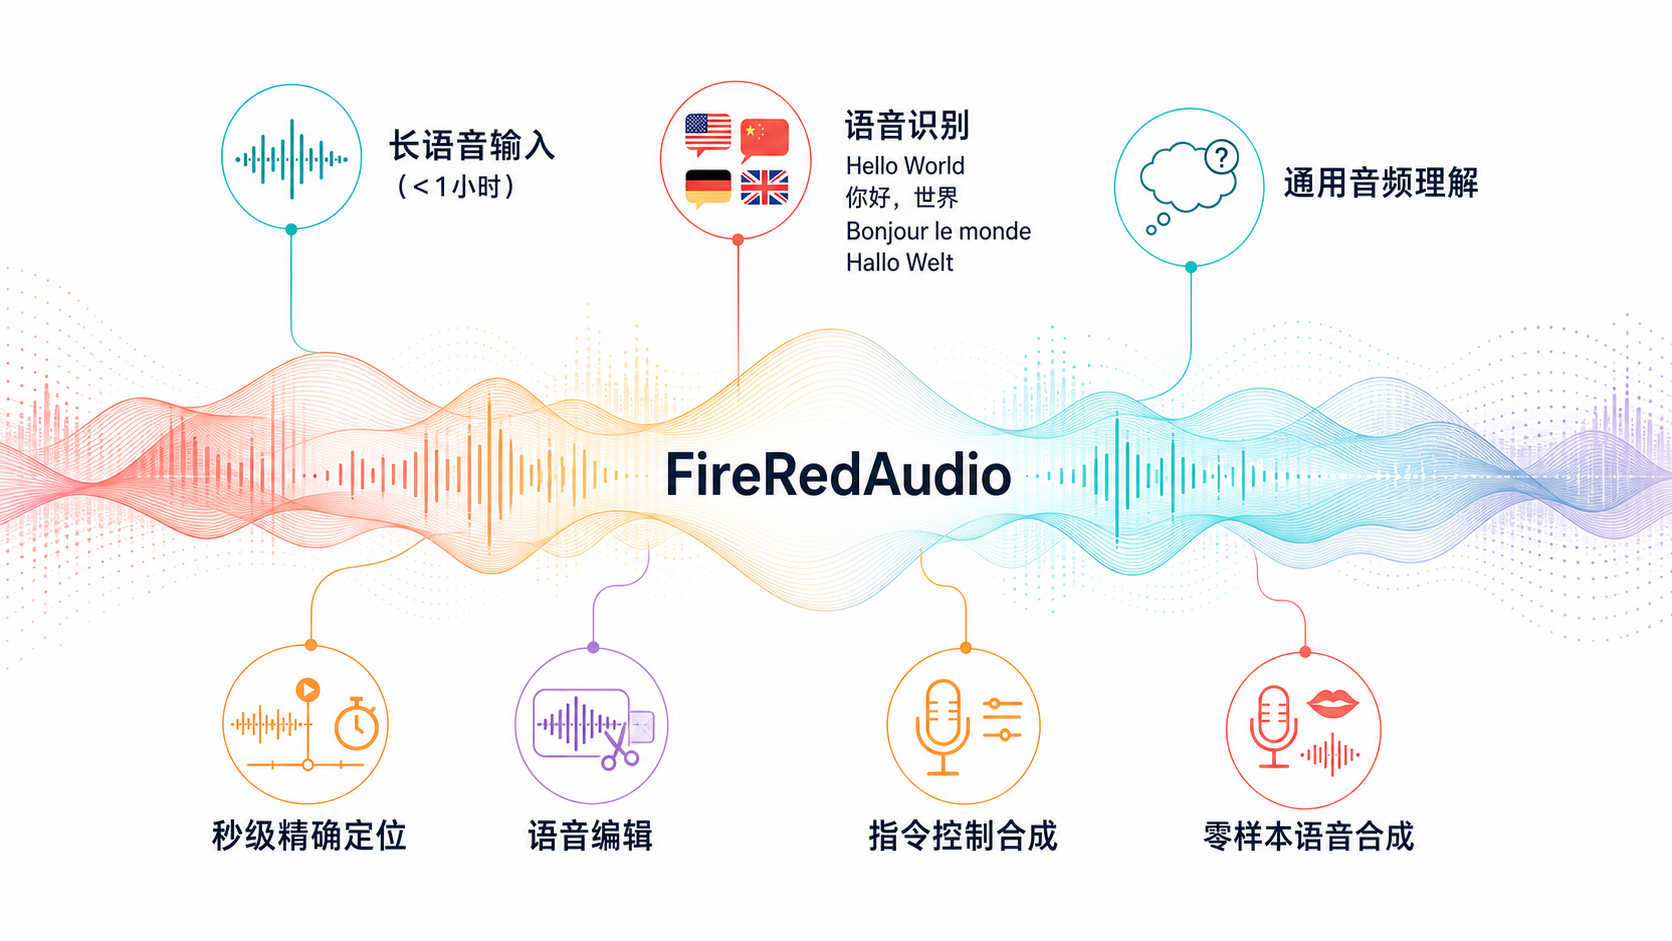
2KFireRedTeam/FireRedAudio · PythonFireRedAudio is a general-purpose audio language model built on a shared 9B-parameter LLM that can transcribe speech (ASR), understand audio, do zero-shot and instruct text-to-speech, and edit speech, all from one model.
- 23
speech-swift
1.2Ksoniqo/speech-swift · SwiftLocal Speech AI on a MacBook — watch the 4-minute open-source library tour on YouTube
- 24
gufo
794gufo-org/gufo · C++Gufo is a local inference engine built specifically for AMD Strix Halo hardware (Ryzen AI MAX+ 395 with Radeon 8060S / gfx1151, up to 128 GiB unified memory), serving text, speech, image and video models through an OpenAI-compatible API.
- 25
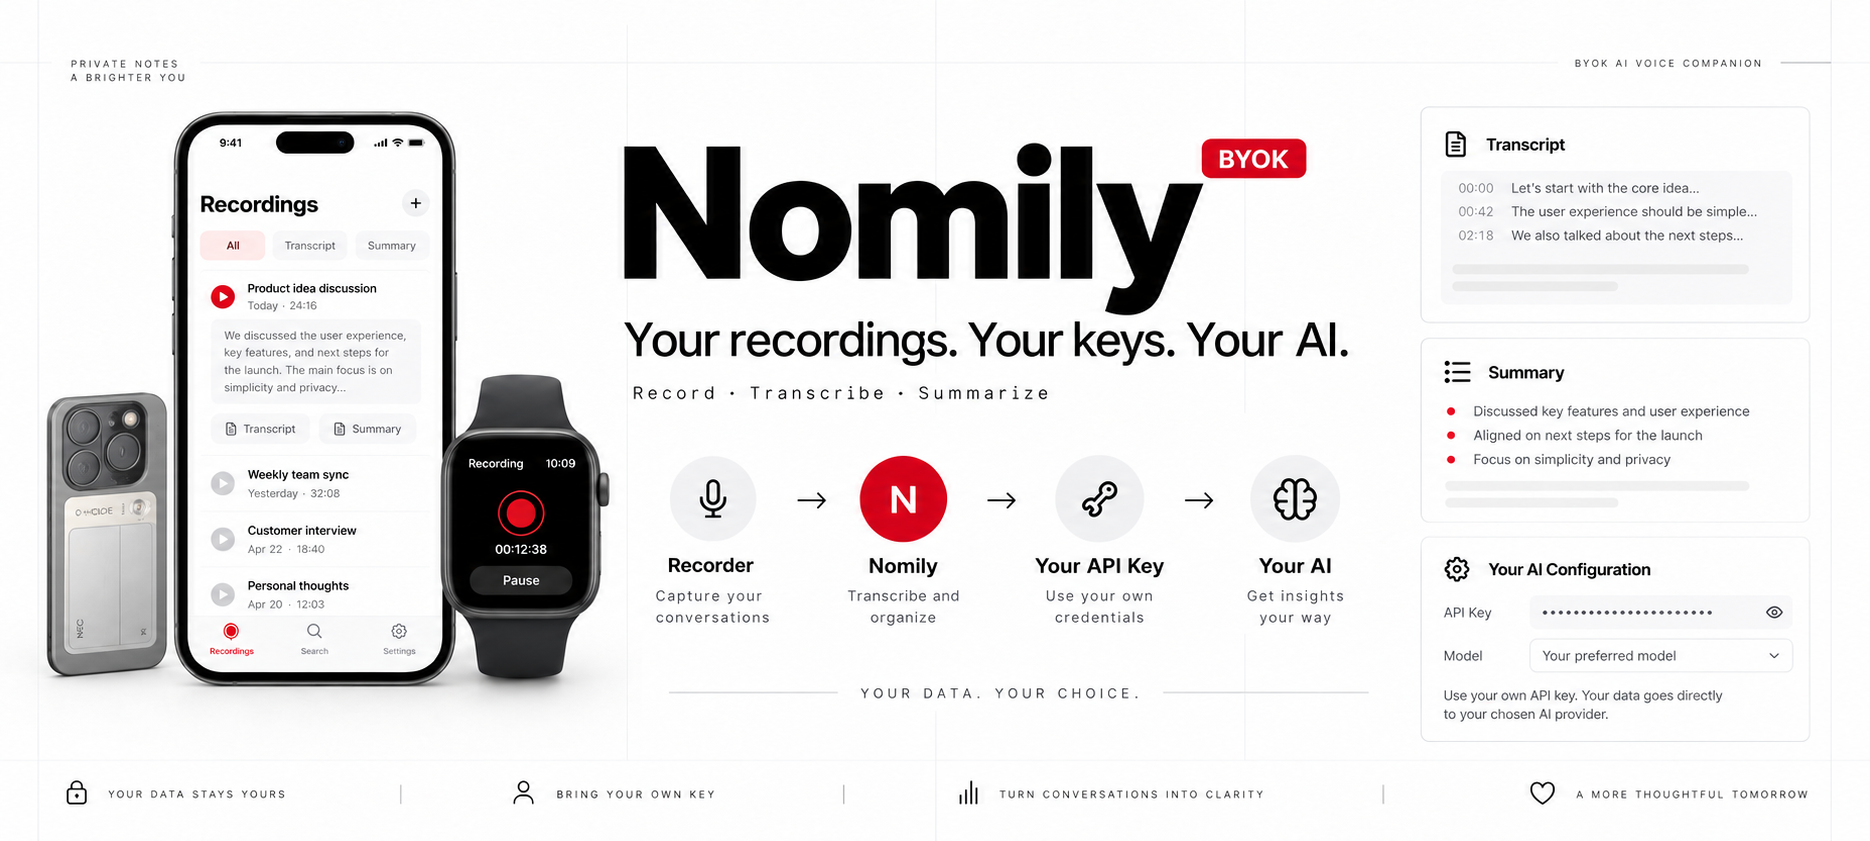
nomily-app
706Nomily-Ai/nomily-appNomily AI is a BYOK (bring-your-own-key) voice recording companion for the V05E BLE recorder, iPhone, and Apple Watch, offering ASR transcription, speaker diarization, and AI-generated summaries where you choose and pay for your own transcription and LLM providers.
- 26
jot-gemini-transcribe-macOS
493google-gemini/jot-gemini-transcribe-macOS · SwiftJot is a macOS app that turns your voice into clean, punctuated text right where your cursor is - hold a hotkey, speak, and it types the result using Google's Gemini transcription model.
- 27

LongCat-Next
477meituan-longcat/LongCat-Next · PythonLongCat-Next is a native multimodal foundation model from Meituan that processes text, vision, and audio under a single autoregressive objective using discrete tokens, built on the LongCat-Flash-Lite MoE backbone (A3B).
- 28

ai-aug-edu
467HytidelLegend/ai-aug-edu · PythonA Chinese-language toolbox of Agent Skills for AI-assisted learning, teaching and research, built for students, teachers and academics.
- 29
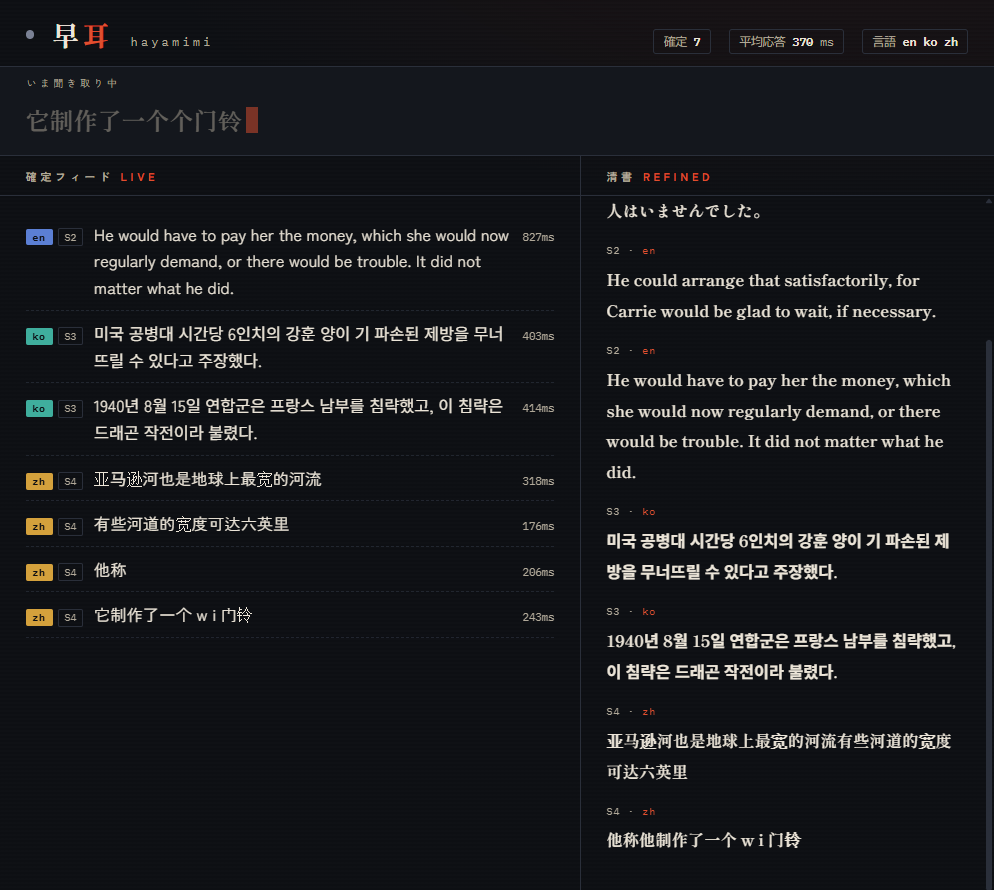
hayamimi
446oboroge0/hayamimi · Pythonhayamimi is a real-time, multilingual speech-to-text tool that runs entirely on CPU, giving you live subtitles, a browser dashboard, speaker labels, and on-the-fly translation without a GPU or cloud API.
- 30

yapsnap
379kouhxp/yapsnap · PythonA command-line tool that turns any video URL or local audio/video file into a plaintext transcript, running entirely on your own CPU — no GPU, no cloud, one command.
- 31

pi-voice
301earendil-works/pi-voice · TypeScriptA speech-to-text extension for the Pi coding agent: you hit a shortcut, speak, and the transcript is inserted at your editor cursor. Everything is transcribed locally on your machine.
- 32

qxotic
175qxoticai/qxotic · JavaQxotic is an open-source AI stack built specifically for the JVM, giving Java applications local AI inference — chat, vision, audio, embeddings, reranking and text-to-speech — without needing Python or ONNX.
- 33
personal-assistant
109r-ayin/personal-assistant · C++A memory system for an AI companion that stores conversations as structured, narrative memory and carefully decides when to bring a memory back and when to stay silent, instead of just doing retrieval. It pairs a configurable backend (ASR/LLM/embeddings) with an ESP32-S3 recording device.
Related topics
Often tagged together