Topics / #moe
Moe projects on GitHub
Mixture-of-experts architectures that route tokens to specialized subnetworks.
As of , the most-starred Moe projects on GitHub are DeepSeek-V3 (104.5K stars), vllm (94.1K stars) and DeepSeek-R1 (91.9K stars). GitHub.Locker tracks 56 Moe repositories with 1M stars combined. The fastest-growing on October 18 was Strata, with +654 stars in a day.
Hot right now
Most stars gained in a day · Oct 18
 +654
Strata
Niko1221/Strata · ★ 27.7KStrata runs Qwen3.8-Flash-Next, a 125-billion-parameter AI model, on a normal gaming PC with one NVIDIA GPU (12-24GB VRAM) and 64GB of RAM, with a one-click installer for Windows and Linux.
 +238
Edge0
Edge0-AI/Edge0 · ★ 5.7KEdge0 is an open-source streaming MoE (Mixture-of-Experts) inference framework that lets you run large MoE models, like a 35B-parameter model, using only about 2.5-2.9 GB of active RAM by streaming expert weights from SSD and predicting routing one step ahead.
 +169
airllm
lyogavin/airllm · ★ 39.4KAn open-source Python library that runs huge LLMs on tiny GPUs: a 70B model fits on a single 4GB card without quantization, distillation or pruning — even the 2.8T-parameter Kimi K3 runs in under 4GB.
 +151
colibri
JustVugg/colibri · ★ 42.8KColibri is an open-source engine for running frontier mixture-of-experts (MoE) language models on hardware you already own — written in pure C with zero dependencies.
The all-time top
56 projects · by stars
- 104.5K
 #1 · deepseek-ai/DeepSeek-V3
DeepSeek-V3
DeepSeek-V3 is an open-weight Mixture-of-Experts (MoE) language model with 671B total parameters but only 37B activated per token, built for efficient yet high-performing inference and matching leading closed-source models on many benchmarks.
- 94.1K
 #2 · vllm-project/vllm
vllm
vLLM is a library for fast LLM inference and serving, built around PagedAttention for efficient memory management of attention keys and values.
- 91.9K#3 · deepseek-ai/DeepSeek-R1
DeepSeek-R1
DeepSeek-R1 is an open-source family of reasoning-focused large language models from DeepSeek, trained with large-scale reinforcement learning to handle math, code, and general reasoning at a level comparable to OpenAI's o1.
- 4
unsloth
78.2Kunslothai/unsloth · PythonUnsloth is a local-first app for running and training LLMs, diffusion, TTS and embedding models on your own machine, including models like Qwen3.8, DeepSeek-V4, MiniMax-H3, Gemma 4 and FLUX.
- 5
LlamaFactory
75.6Khiyouga/LlamaFactory · PythonLlamaFactory unifies efficient fine-tuning of 100+ large language models and vision-language models in one Python toolkit, published as an ACL 2024 paper.
- 6
minimind
64Kjingyaogong/minimind · PythonMiniMind is an open-source project that lets you train a tiny large language model (around 64M parameters) completely from scratch, in about 2 hours on a single RTX 3090 for roughly the cost of 3 RMB in GPU rental.
- 7

grok-1
52.2Kxai-org/grok-1 · PythonGrok-1 is the 314B-parameter Mixture-of-Experts language model that xAI opened up; this repository holds the JAX example code for loading and running it.
- 8
colibri
42.8KJustVugg/colibri · CColibri is an open-source engine for running frontier mixture-of-experts (MoE) language models on hardware you already own — written in pure C with zero dependencies.
- 9
airllm
39.4Klyogavin/airllm · Jupyter NotebookAn open-source Python library that runs huge LLMs on tiny GPUs: a 70B model fits on a single 4GB card without quantization, distillation or pruning — even the 2.8T-parameter Kimi K3 runs in under 4GB.
- 10
sglang
37.3Ksgl-project/sglang · PythonSGLang is a high-performance serving framework for large language models and multimodal models, built to deliver low-latency, high-throughput inference from a single GPU up to large distributed clusters.
- 11

Qwen3
27.7KQwenLM/Qwen3 · PythonQwen3 is a series of open-weight large language models built by the Qwen team at Alibaba Cloud, released as both dense and Mixture-of-Experts (MoE) models from 0.6B up to 235B-A22B parameters, with switchable 'thinking' and 'non-thinking' reasoning modes.
- 12
Strata
27.7KNiko1221/Strata · C++Strata runs Qwen3.8-Flash-Next, a 125-billion-parameter AI model, on a normal gaming PC with one NVIDIA GPU (12-24GB VRAM) and 64GB of RAM, with a one-click installer for Windows and Linux.
- 13
verl
23.9Kverl-project/verl · Pythonverl is a flexible, efficient and production-ready reinforcement learning training library for LLMs, initiated by ByteDance's Seed team and maintained by the community. It is the open-source version of the HybridFlow paper (EuroSys 2025).
- 14
gpt-oss
20.5Kopenai/gpt-oss · PythonThe gpt-oss series: two open-weight language models from OpenAI — gpt-oss-120b and gpt-oss-20b — built for powerful reasoning, agentic tasks, and versatile developer use cases. The repo itself adds reference implementations, tools, and example clients around the models.
- 15
Qwen3-VL
20.1KQwenLM/Qwen3-VL · Jupyter NotebookQwen3-VL is a family of multimodal vision-language models built by the Qwen team at Alibaba Cloud, combining strong text understanding with deep visual perception, reasoning, and agent capabilities.
- 16
DeepResearch
20.1KAlibaba-NLP/DeepResearch · PythonTongyi DeepResearch — an open-source agentic LLM from Alibaba's Tongyi Lab, built for long-horizon, deep information-seeking on the web. This repo ships the model weights plus Python inference and benchmark evaluation scripts.
- 17
ktransformers
19.6Kkvcache-ai/ktransformers · PythonKTransformers is a research framework for efficient inference and fine-tuning of large language models through CPU-GPU heterogeneous computing, letting huge MoE models run on hardware that doesn't have enough VRAM to hold them entirely on GPU.
- 18
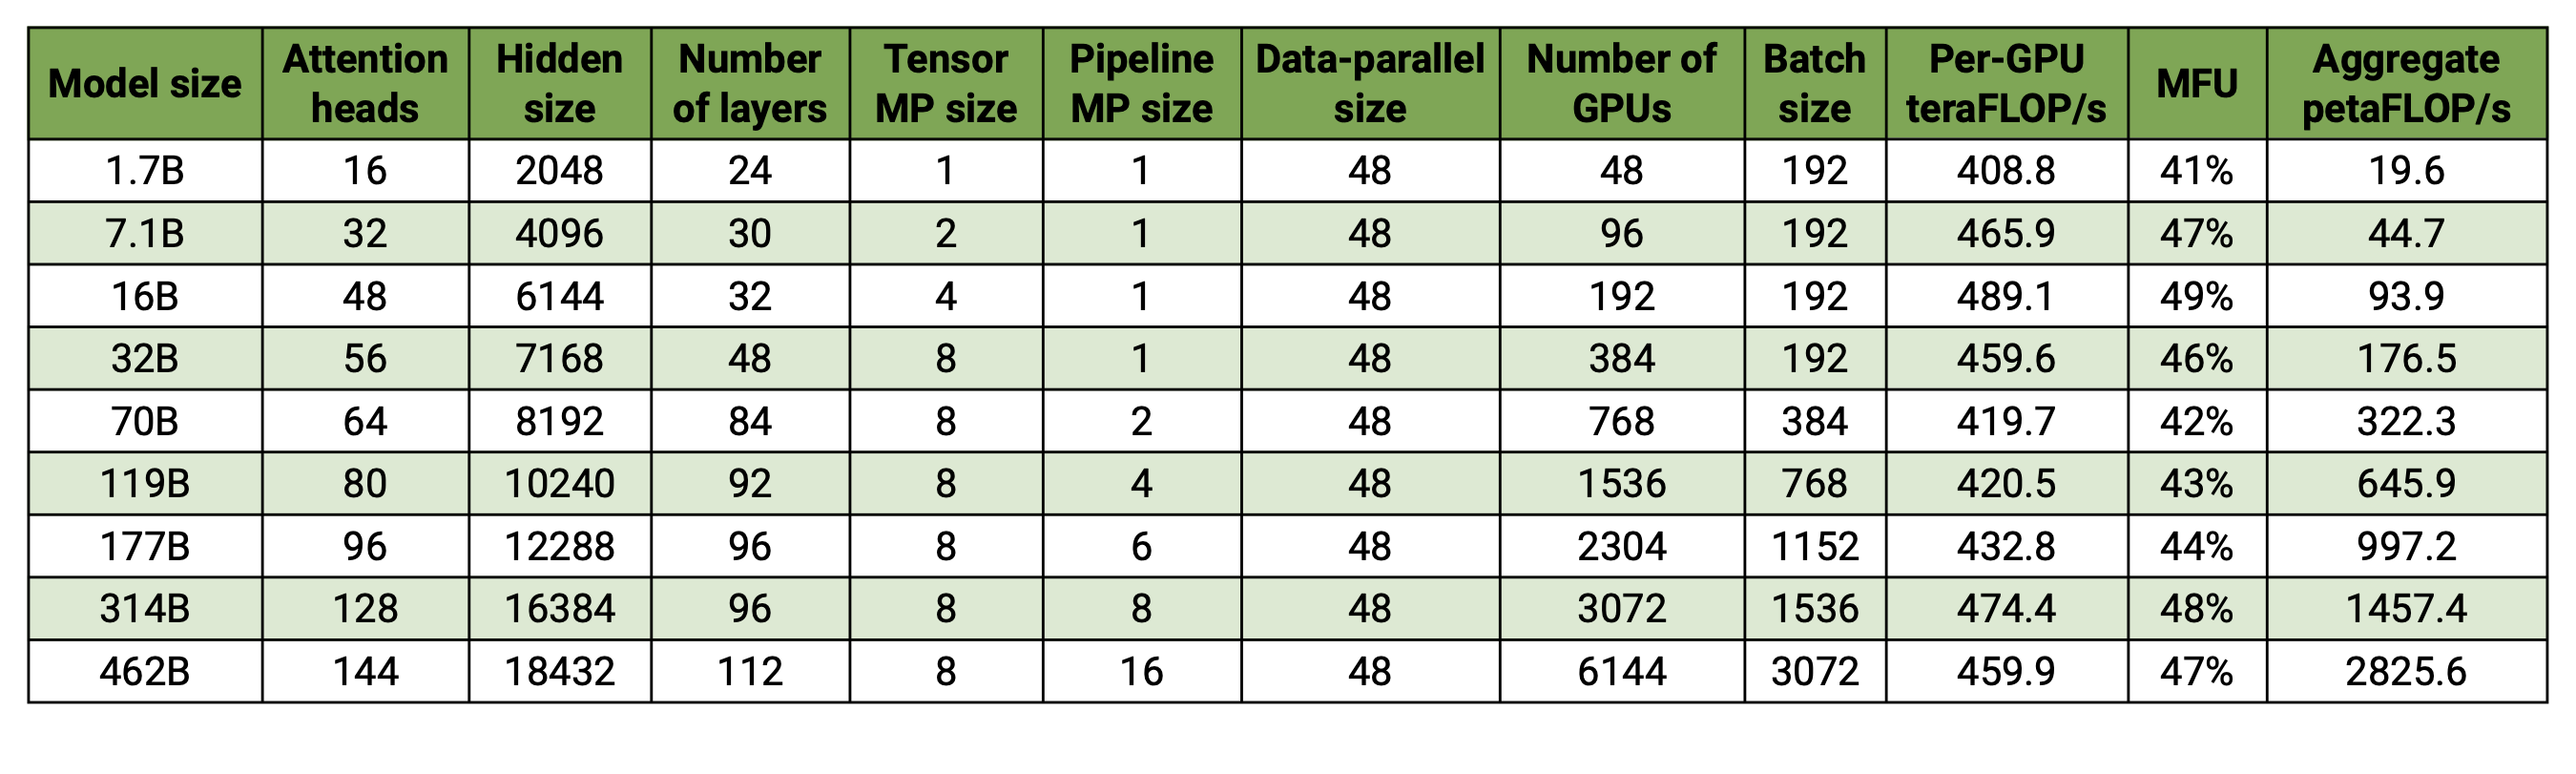
Megatron-LM
18.2KNVIDIA/Megatron-LM · PythonNVIDIA's open-source toolkit for training large transformer (LLM) models at scale. It comes as Megatron-LM, a reference setup with ready training scripts, and Megatron Core, a composable library of GPU-optimized building blocks for training models across thousands of GPUs.
- 19
Wan2.2
18KWan-Video/Wan2.2 · PythonAn open-source family of large-scale video generation models: text-to-video, image-to-video, speech-to-video and character animation, with inference code and model weights released under Apache-2.0.
- 20
Qwen3-Coder
16.8KQwenLM/Qwen3-Coder · PythonQwen3-Coder is the code-focused branch of the Qwen3 large language model family from the Qwen team — open-weight models built for coding and agentic tasks, available in several sizes.
- 21
ms-swift
15.9Kmodelscope/ms-swift · Pythonms-swift is the ModelScope community's fine-tuning and deployment framework for LLMs and multimodal models, covering training, inference, evaluation, quantization and deployment in one pipeline.
- 22
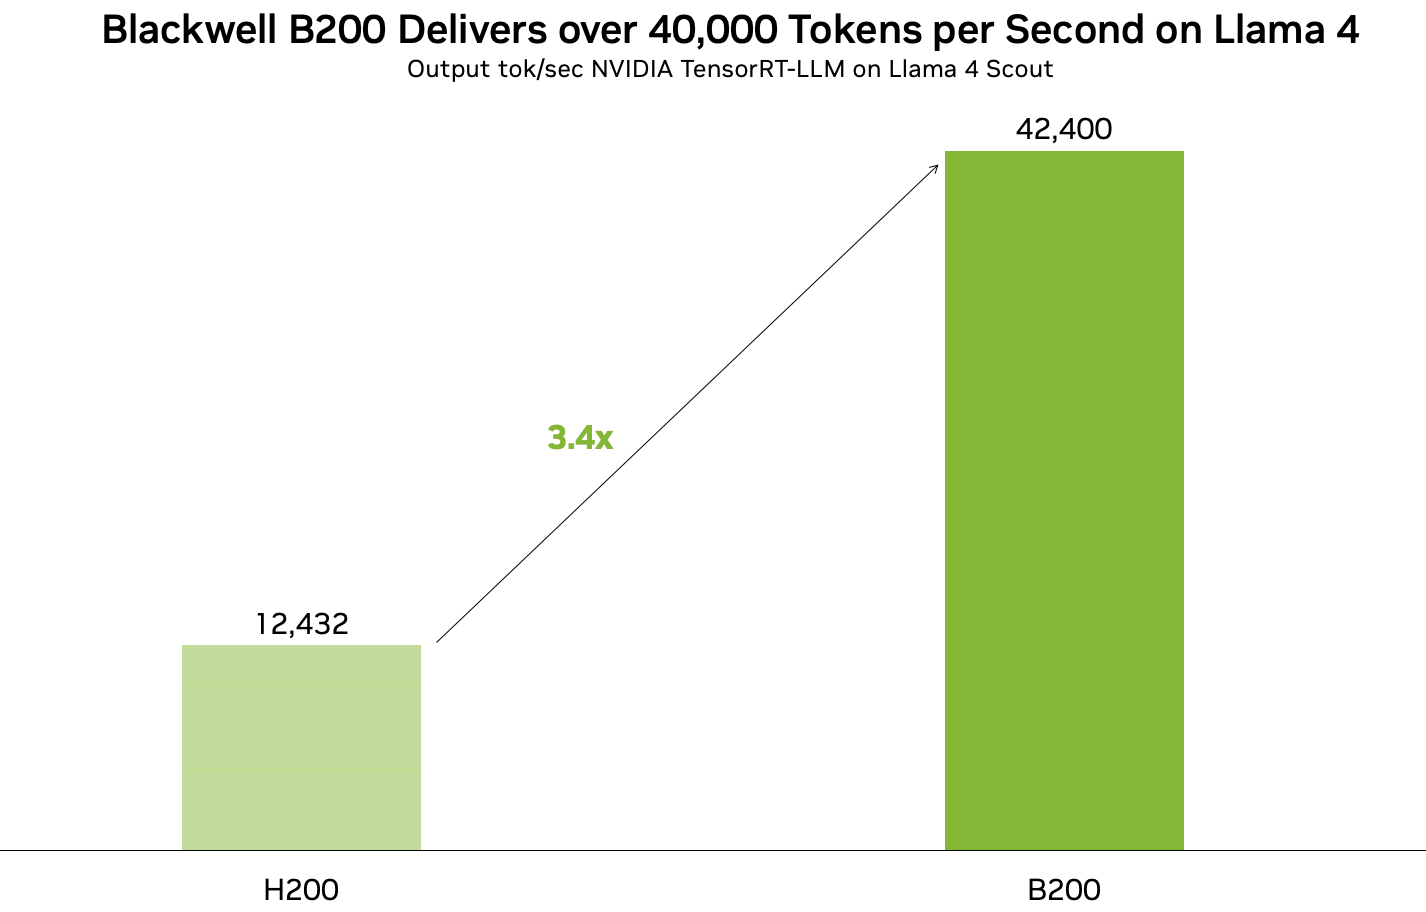
TensorRT-LLM
14.9KNVIDIA/TensorRT-LLM · PythonTensorRT LLM is NVIDIA's Python framework for defining large language models (and now visual generation models) and compiling them into highly optimized inference engines that run on NVIDIA GPUs, with specialized kernels and Python/C++ runtimes.
- 23
FreeToken
14.6KFlashML-org/FreeToken · PythonFreeToken is an edge-native Mixture-of-Experts (MoE) serving engine built to run frontier-scale open-weight models, including 290B+ parameter models, on consumer hardware like gaming PCs.
- 24
PaddleNLP
13KPaddlePaddle/PaddleNLP · PythonPaddleNLP is a large language model (LLM) and small language model (SLM) development toolkit built on the PaddlePaddle deep learning framework, offering efficient training, lossless compression, and high-performance inference for large models.
- 25
axolotl
12.6Kaxolotl-ai-cloud/axolotl · PythonAxolotl is a free, open-source framework that streamlines post-training and fine-tuning of large language models — you describe your run in one YAML config and it drives the whole pipeline.
- 26

True-Story-of-Pangu
11.5KHW-whistleblower/True-Story-of-PanguA long first-person exposé by a self-identified member of Huawei's Pangu LLM team at the Noah's Ark Lab, telling what he says really went on behind the model's development — including claims that some Pangu models were secretly continued-trained from Qwen and DeepSeek.
- 27
Kimi-K2
11.1KMoonshotAI/Kimi-K2Kimi K2 is a large language model series from Moonshot AI: a mixture-of-experts model with 1 trillion total parameters (32B activated per token), trained for frontier knowledge, reasoning, coding and especially agentic tool-use tasks.
- 28

DeepEP
10.3Kdeepseek-ai/DeepEP · CudaDeepEP is a high-performance communication library for MoE (mixture-of-experts) models, providing fast all-to-all GPU kernels for expert-parallel dispatch and combine operations used in ML training and inference.
- 29
kimi-k3-in-c
9.1KFareedKhan-dev/kimi-k3-in-c · CAn inference engine for the 2.78-trillion-parameter Kimi K3 model, written in portable C99. It runs on a plain CPU in as little as 8 GB of RAM — no GPU, no BLAS, no framework — streaming the 1.56 TB checkpoint straight off disk.
- 30
Kimi-K3
8.9KMoonshotAI/Kimi-K3Kimi K3 is MoonshotAI's open-weight, native multimodal agentic model — a 2.8T-parameter Mixture-of-Experts system built for frontier-level long-horizon coding, agentic knowledge work, and reasoning.
- 31
Edge0
5.7KEdge0-AI/Edge0 · PythonEdge0 is an open-source streaming MoE (Mixture-of-Experts) inference framework that lets you run large MoE models, like a 35B-parameter model, using only about 2.5-2.9 GB of active RAM by streaming expert weights from SSD and predicting routing one step ahead.
- 32
Qwen3.8
4.3KQwenLM/Qwen3.8Qwen3.8 is the latest open large language model release from Alibaba's Qwen team, part of the Qwen3.5 series that also includes Qwen3.5 and Qwen3.6, aimed at coding, professional work, research, and long-horizon agentic tasks.
- 33

InfraTech
4.2KCalvinXKY/InfraTech · Jupyter NotebookInfraTech is a collection of Jupyter notebooks and articles sharing AI Infra knowledge: training/inference frameworks (PyTorch, vLLM/SGLang, slime/vime), performance acceleration, deep learning fundamentals and AI hardware/software basics.
- 34

Qwen3-Omni
4.1KQwenLM/Qwen3-Omni · Jupyter NotebookQwen3-Omni is a family of open, natively end-to-end omni-modal LLMs from Alibaba's Qwen team: they take text, images, audio and video as input and stream back answers as text or natural speech in real time.
- 35

warp
2.5Ksqliteai/warp · CWARP (Weight-Aware Runtime and Paging, formerly WASTE) is a dependency-free, embeddable C inference engine that runs huge mixture-of-experts models on consumer hardware by streaming each token's activated weights straight from NVMe — the full models, not distilled versions.
- 36
Hy-MT2
1.3KTencent-Hunyuan/Hy-MT2 · PythonHy-MT2 is Tencent Hunyuan's family of 'fast-thinking' multilingual translation models, released in three sizes (1.8B, 7B, and 30B-A3B MoE), that translate among 33 languages and follow complex translation instructions.
- 37
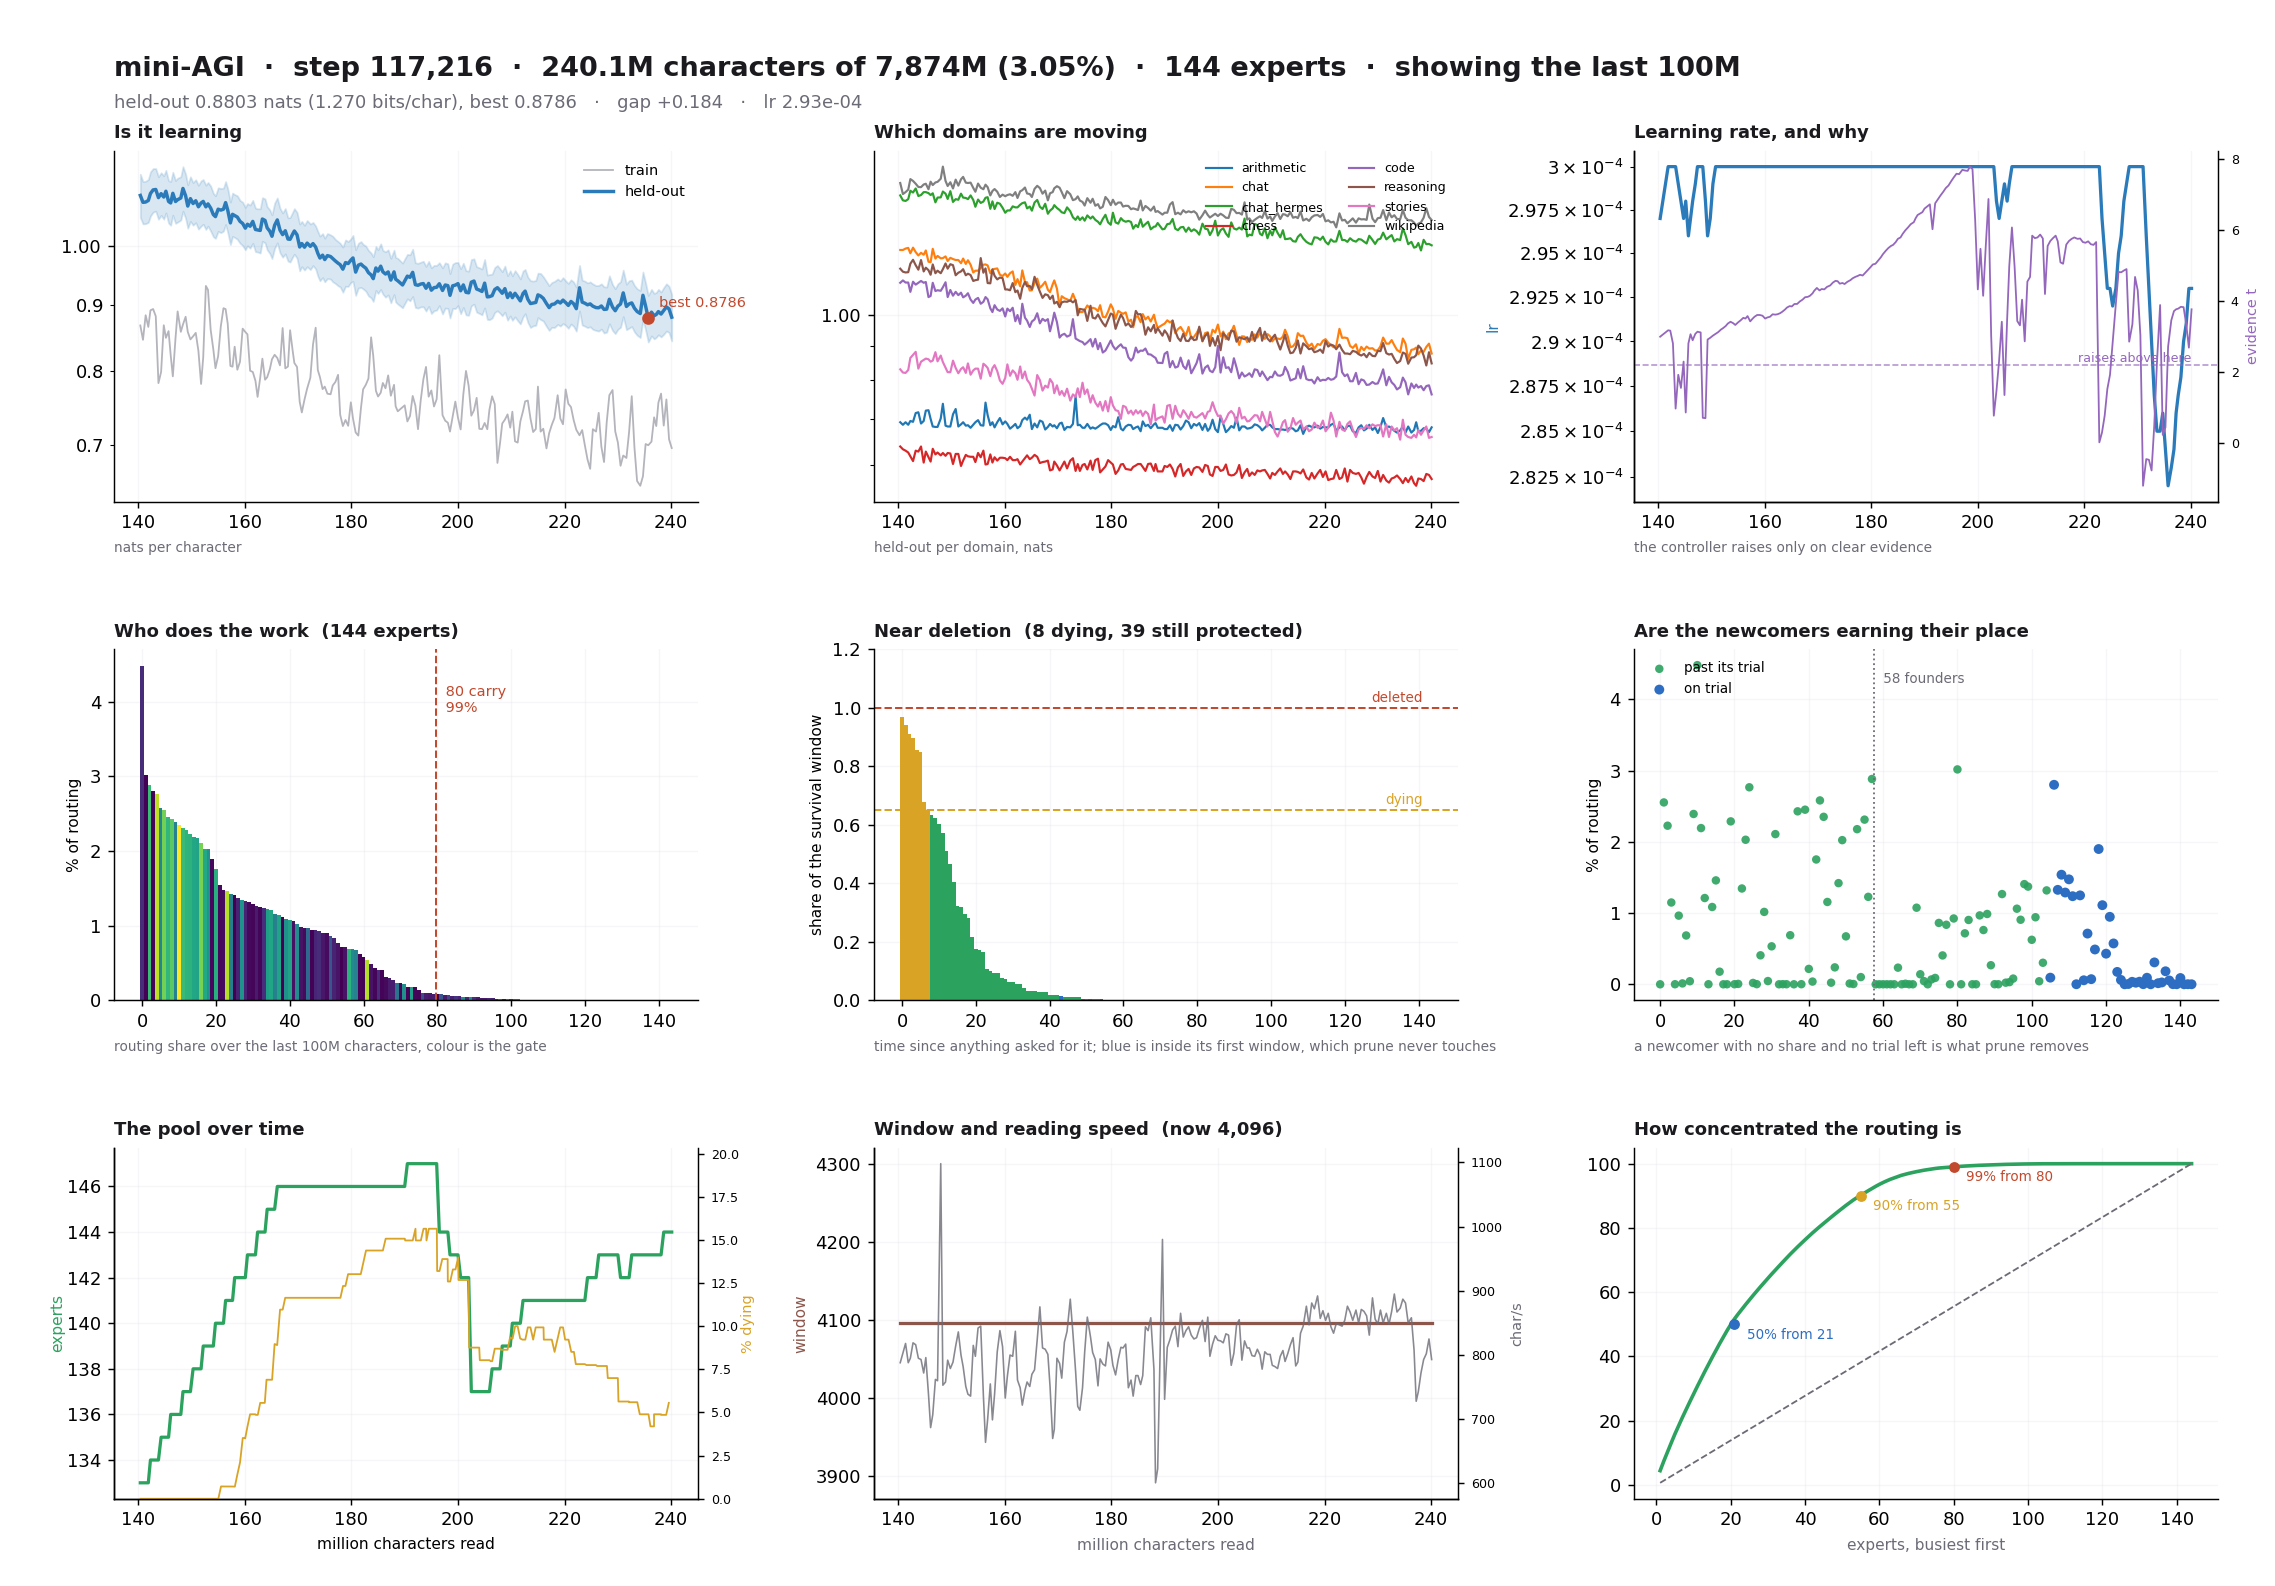
mini-AGI
1.3Kvolotat/mini-AGI · Pythonmini-AGI is a continual learning, byte-level language model that assembles its own architecture, trains from scratch on a single 8GB VRAM GPU, and keeps learning from everything it reads, without a separate fine-tuning phase.
- 38

project-maya
1Kmw00/project-maya · C++Project Maya lets you run GLM-5.3-Flash, a 321-billion-parameter mixture-of-experts AI model, on your own NVIDIA GPU(s) by streaming the model's experts across VRAM, RAM and NVMe SSD as the conversation needs them.
- 39

llm-architecture-from-scratch
1KYeonwooSung/llm-architecture-from-scratch · PythonA collection of PyTorch implementations of modern LLM architectures (GPT-2, Llama 3/3.2, Llama 4, OLMo 2, Phi-4, DeepSeek v3, Gemma 3, xLSTM, Mistral 3.1) built from scratch to understand how they work internally.
- 40

deltafin
851gavamedia/deltafin · RustDeltafin is a native Rust binary that runs the full, unpruned 2.8-trillion-parameter Kimi K3 model on a single consumer machine, keeping all 16 experts active, plus an OpenAI-compatible API server for local chat and coding agents.
- 41
halo
825whitecircle/halo · PythonHalo is an open-source framework from White Circle for training large language and multimodal models: pre-training, SFT, preference optimization, and fully asynchronous multi-turn RL in one codebase, from a single GPU up to multi-node clusters.
- 42
gufo
803gufo-org/gufo · C++Gufo is a local inference engine built specifically for AMD Strix Halo hardware (Ryzen AI MAX+ 395 with Radeon 8060S / gfx1151, up to 128 GiB unified memory), serving text, speech, image and video models through an OpenAI-compatible API.
- 43
verl
725XiaomiMiMo/verl · Pythonverl is an open-source RL post-training framework for large language models, started by ByteDance Seed as the open-source version of the HybridFlow paper. This XiaomiMiMo fork adds agentic RL training code for MiMo, with reproduction code for five RL environments on top of verl 0.9.0.dev.
- 44
Offensive-Security-AI-Models
698JoasASantos/Offensive-Security-AI-ModelsA curated list of open-weight, uncensored language models fine-tuned for offensive-security tasks like penetration testing, red teaming, and security research. The README documents over 20 models sourced from HuggingFace model cards as of September 2026.
- 45
LoongForge
691baidu-baige/LoongForge · PythonAn open-source training framework from Baidu's Baige team for LLMs, VLMs, diffusion and embodied models, built for faster training and lower cost on NVIDIA GPUs and Kunlun XPUs.
- 46
DeepGEMM-Ascend
588deepseek-ai/DeepGEMM-Ascend · C++DeepGEMM-Ascend is a port of DeepSeek's DeepGEMM matrix-multiplication kernel library to Huawei Ascend NPUs, fully API-compatible with the original and supporting BF16, FP8, and FP4 GEMM along with MQA logits and MegaMoE operators.
- 47

slotstream
477carloslfu/slotstream · SwiftSlotstream lets you run a 105 GB AI model (Qwen3.8-Flash-Next, a 125B-parameter mixture-of-experts model) on Macs with only 16 to 64 GB of RAM, by streaming most of the model from SSD and caching the busiest experts in memory.
- 48
Qwen3.8-Flash-Next
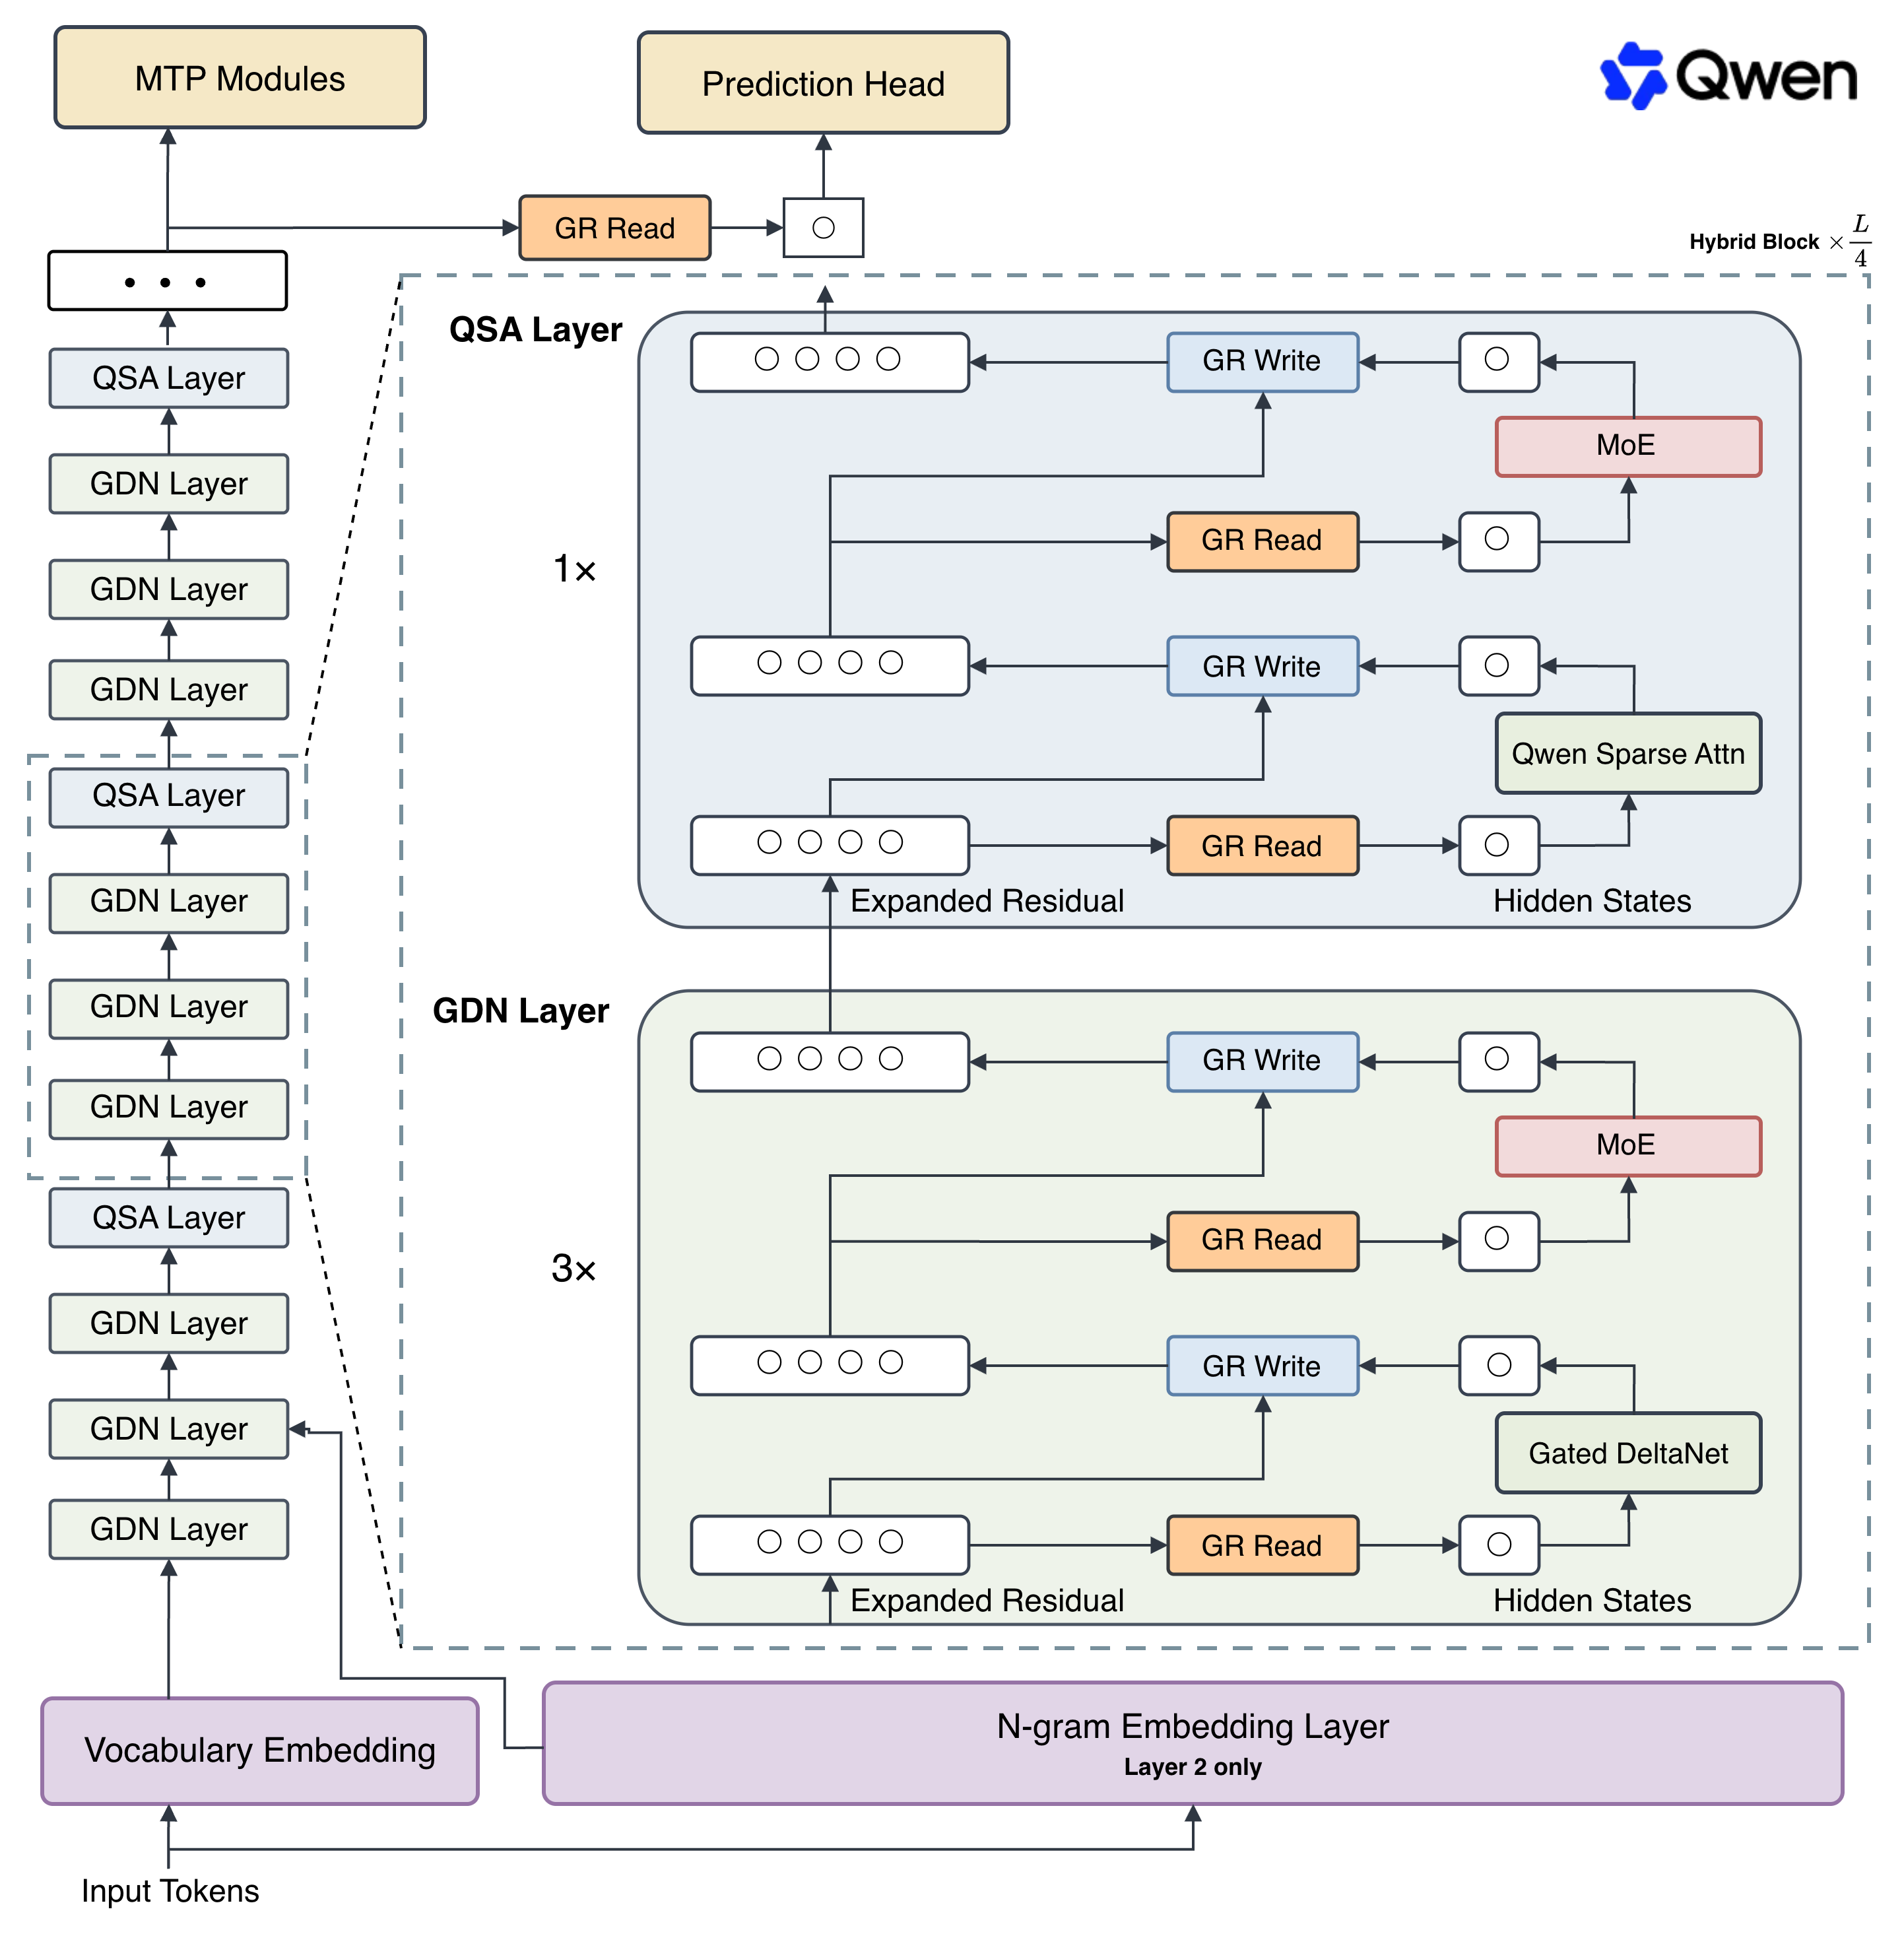
434QwenLM/Qwen3.8-Flash-NextQwen3.8-Flash-Next is an open-weight multimodal Mixture-of-Experts foundation model from Alibaba's Qwen Team, also serving as an early preview of the architecture Alibaba plans to use for the upcoming Qwen4 model family.
- 49

OpenArch
426anuj0456/OpenArch · PythonA set of hand-written PyTorch implementations of modern open-source LLM architectures (Llama, Qwen, DeepSeek, Gemma, GPT-OSS, Kimi and more), written from scratch for readability and learning.
- 50

MoE4All
309Headmaster218/MoE4All · RustMoE4All is a portable Windows app that runs large Mixture-of-Experts (MoE) LLMs beyond what fits in VRAM by streaming expert weights between GPU VRAM, system RAM and SSD, built on a Vulkan-first Rust inference engine so consumer AMD (and other Vulkan) GPUs can run huge models locally.
- 51
autumn-recruitment
270Akun-python/autumn-recruitment · Jupyter NotebookIt is a community-built, Chinese-language collection of Jupyter notebooks covering math foundations, data structures, machine learning, deep learning, LLMs, agents, AI infrastructure, speech, and data science, aimed at job-hunting ('autumn recruitment') interview prep in the LLM era.
- 52
DeepEP-Ascend
259deepseek-ai/DeepEP-Ascend · C++DeepEP-Ascend is a high-performance communication library for machine learning training and inference on Huawei Ascend NPUs, providing expert-parallel all-to-all operations for MoE dispatch and combine.
- 53

dgx-spark-qwen38
230hasso5703/dgx-spark-qwen38 · PythonA one-command installer that sets up a hardened, boot-persistent SGLang serving stack for the Qwen3.8 model family on a single NVIDIA DGX Spark (GB10), reaching 50 tok/s greedy median and up to 1M context on the 27B NVFP4 config, with a 176B Flash-Next MoE model also fitting on one box.
- 54

twinspark
176raullenchai/twinspark · ShellThis is a production-grade deployment recipe for running DeepSeek-V4-Flash-0731 (a 284B-parameter MoE model) across two networked NVIDIA DGX Spark machines, using a self-healing 2-node vLLM cluster tuned for speculative decoding.
- 55
tpu-megakernels
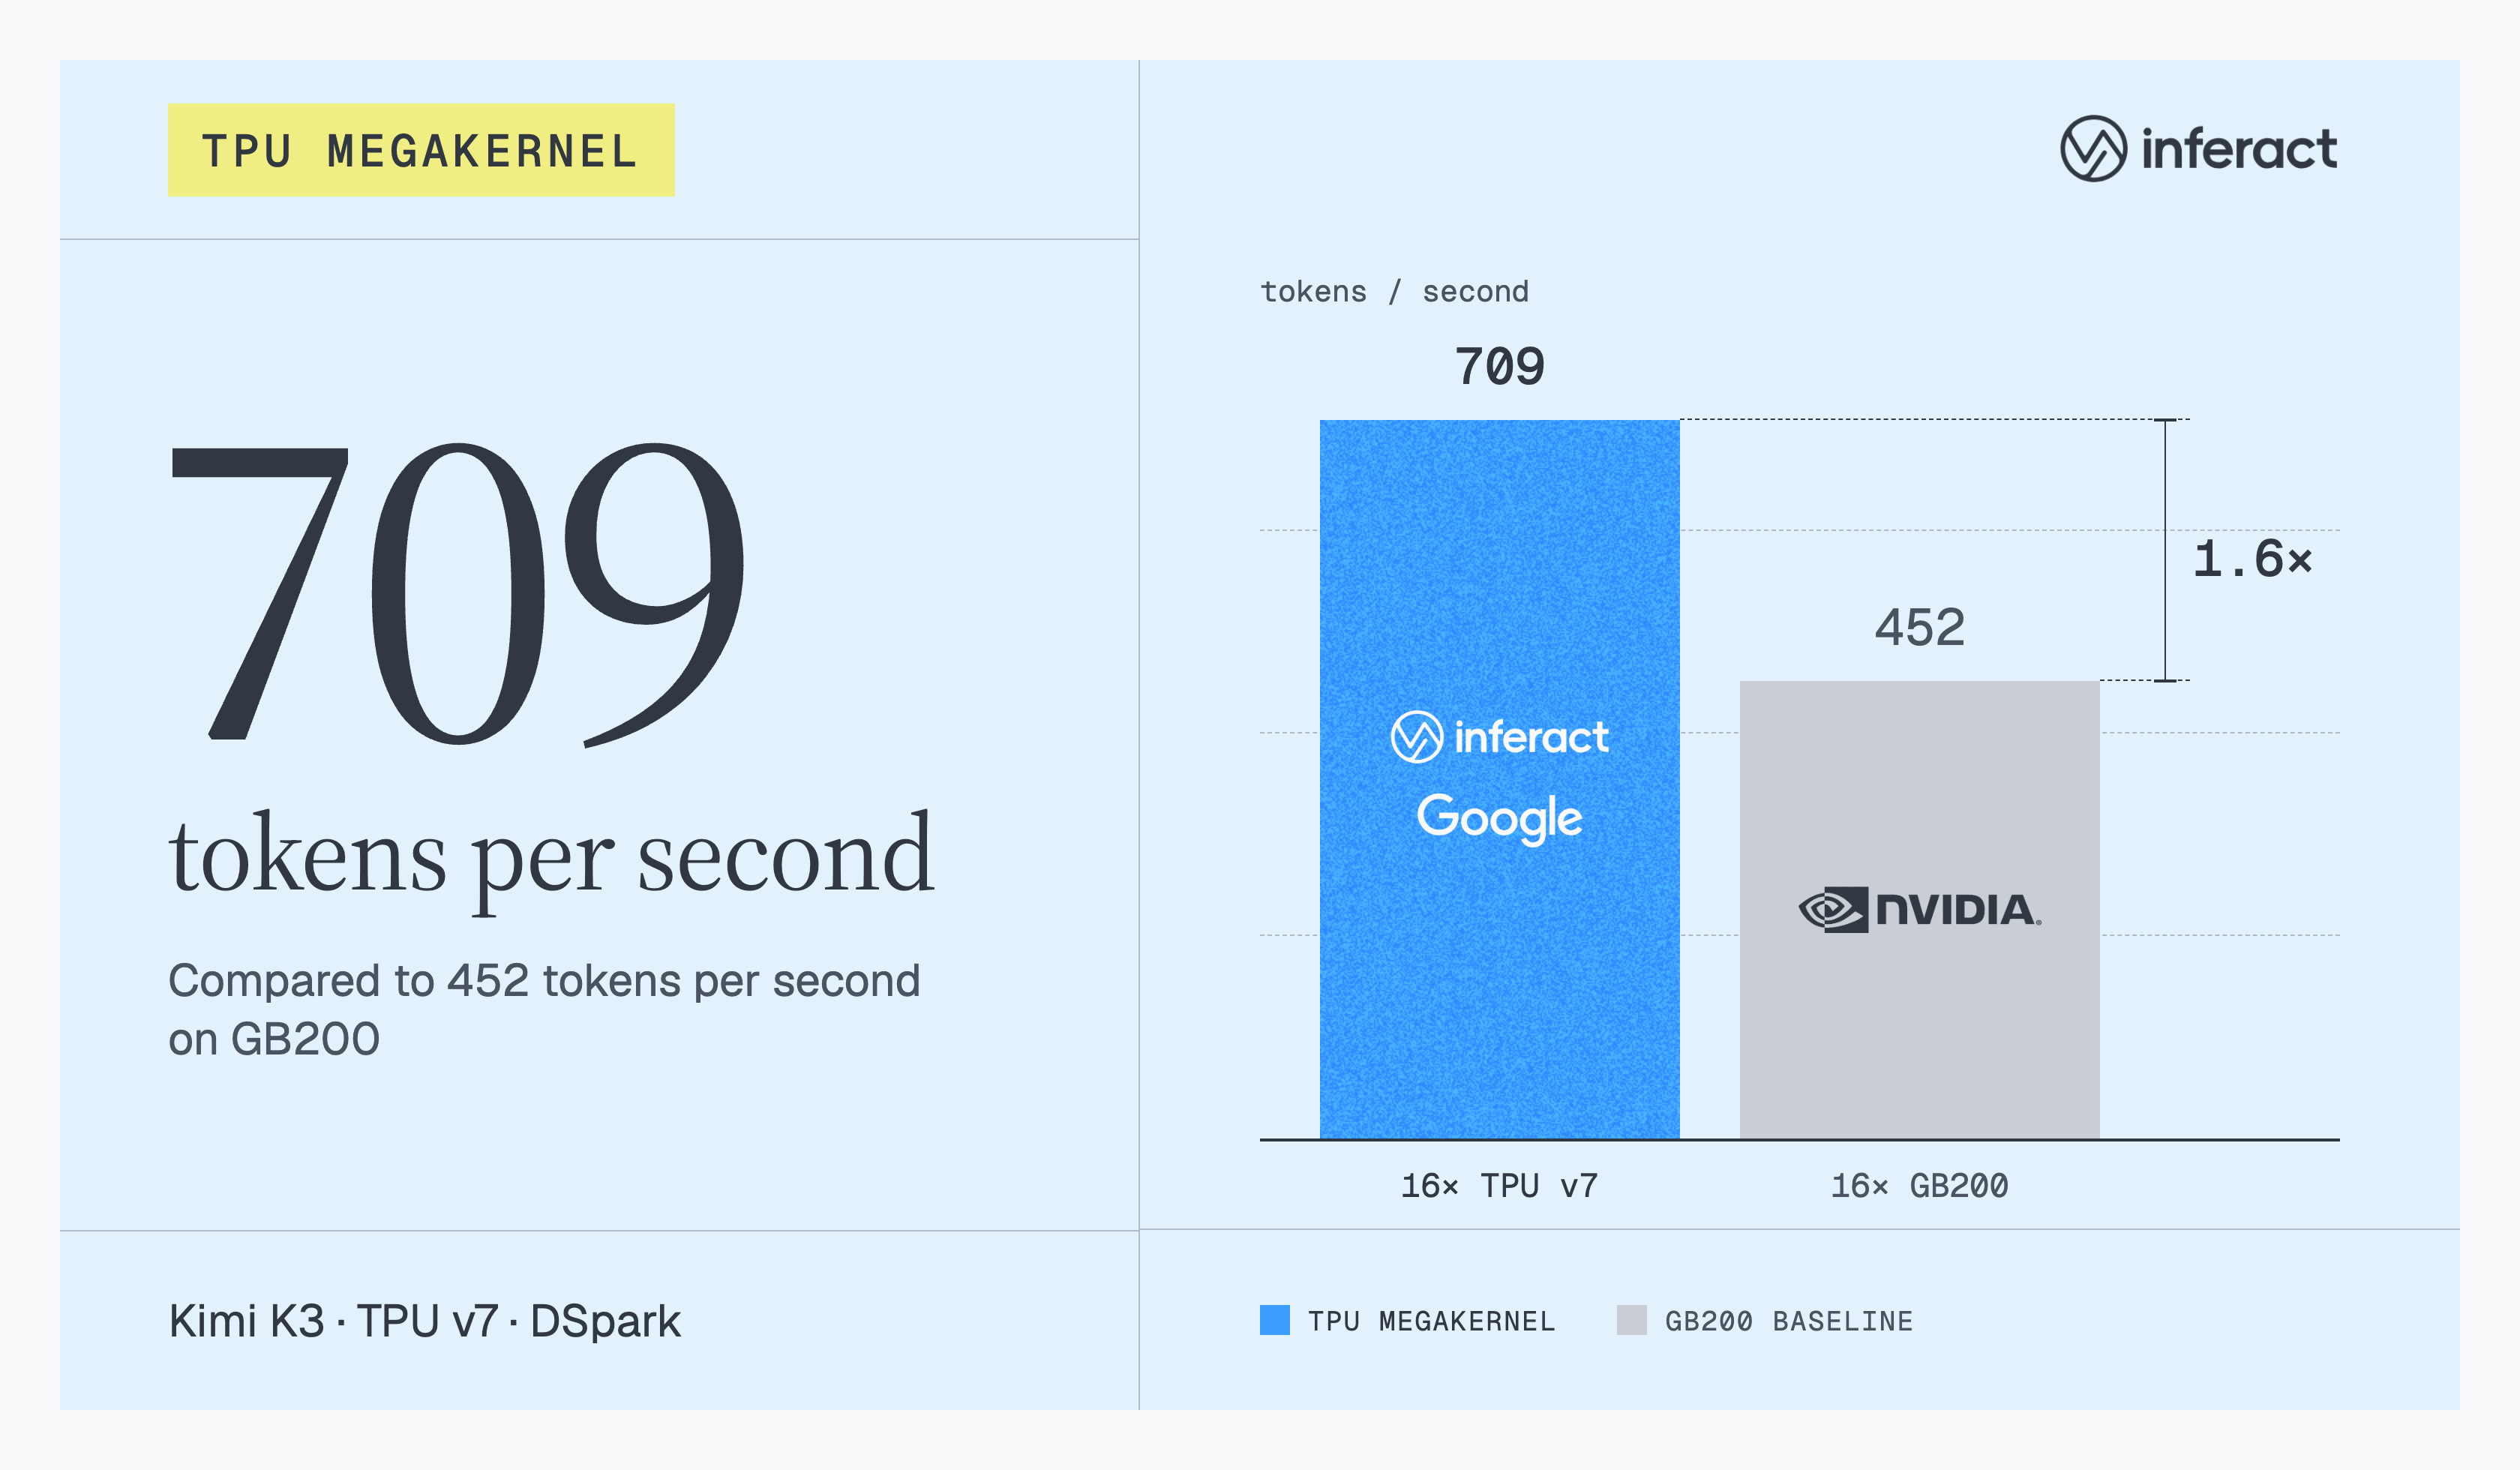
163Inferact/tpu-megakernels · PythonA companion research repo with fused 'megakernel' decode implementations for two models on Google TPUs: Kimi K3 with DSpark speculative decoding, and Qwen3.8-27B with DFlash2 speculative decoding, written to accompany the blog post '700 TPS on Kimi K3: A Case for TPU Megakernels'.
- 56
DMI
62ProjectDMX/DMI · PythonDMI is a decoupled, asynchronous observability stack that gives real-time access to a running LLM's internal state — residual streams, attention patterns, MLP outputs, KV-cache slices, logits — during inference or training, with minimal overhead.
Related topics
Often tagged together