Topics / #image-to-video
Image-to-video projects on GitHub
Generative models that animate a still image into video output.
As of , the most-starred Image-to-video projects on GitHub are artcraft (33.7K stars), Open-Generative-AI (30.9K stars) and Open-Sora (29.9K stars). GitHub.Locker tracks 46 Image-to-video repositories with 347.7K stars combined. The fastest-growing on October 19 was artcraft, with +948 stars in a day.
Hot right now
Most stars gained in a day · Oct 19
artcraft
storytold/artcraft · ★ 33.7KArtCraft is a desktop IDE for interactive AI image and video creation, where you compose scenes in 2D, stage them in 3D, and then pick from dozens of AI models to generate the final result.
Toonflow-app
HBAI-Ltd/Toonflow-app · ★ 18.5KToonflow is an open-source AI workbench for producing short dramas and motion comics: scriptwriting, storyboarding, character and scene assets, and image and video generation chained into one pipeline on an infinite canvas.
 +143
Open-Generative-AI
Anil-matcha/Open-Generative-AI · ★ 30.9KA free, open-source studio for AI image, video, cinema and lip sync generation, positioned as an unrestricted alternative to paid AI video platforms: 400+ models (Flux, Midjourney, Kling, Sora, Veo) across 14 studios, with no content filters.
 +61
MiniMax-H3
MiniMax-AI/MiniMax-H3 · ★ 10.2KMiniMax H3 is a general-purpose omni-modal generative system: it reads mixed text, image, video and audio input and generates video with native stereo audio, up to 2K resolution and 15 seconds per clip.
The all-time top
46 projects · by stars
- 33.7K
#1 · storytold/artcraft
artcraft
ArtCraft is a desktop IDE for interactive AI image and video creation, where you compose scenes in 2D, stage them in 3D, and then pick from dozens of AI models to generate the final result.
- 30.9K#2 · Anil-matcha/Open-Generative-AI
Open-Generative-AI
A free, open-source studio for AI image, video, cinema and lip sync generation, positioned as an unrestricted alternative to paid AI video platforms: 400+ models (Flux, Midjourney, Kling, Sora, Veo) across 14 studios, with no content filters.
- 29.9K
 #3 · hpcaitech/Open-Sora
Open-Sora
Open-Sora is an open-source initiative for efficiently producing high-quality video: it releases video generation models together with the tools, checkpoints and all training details.
- 4
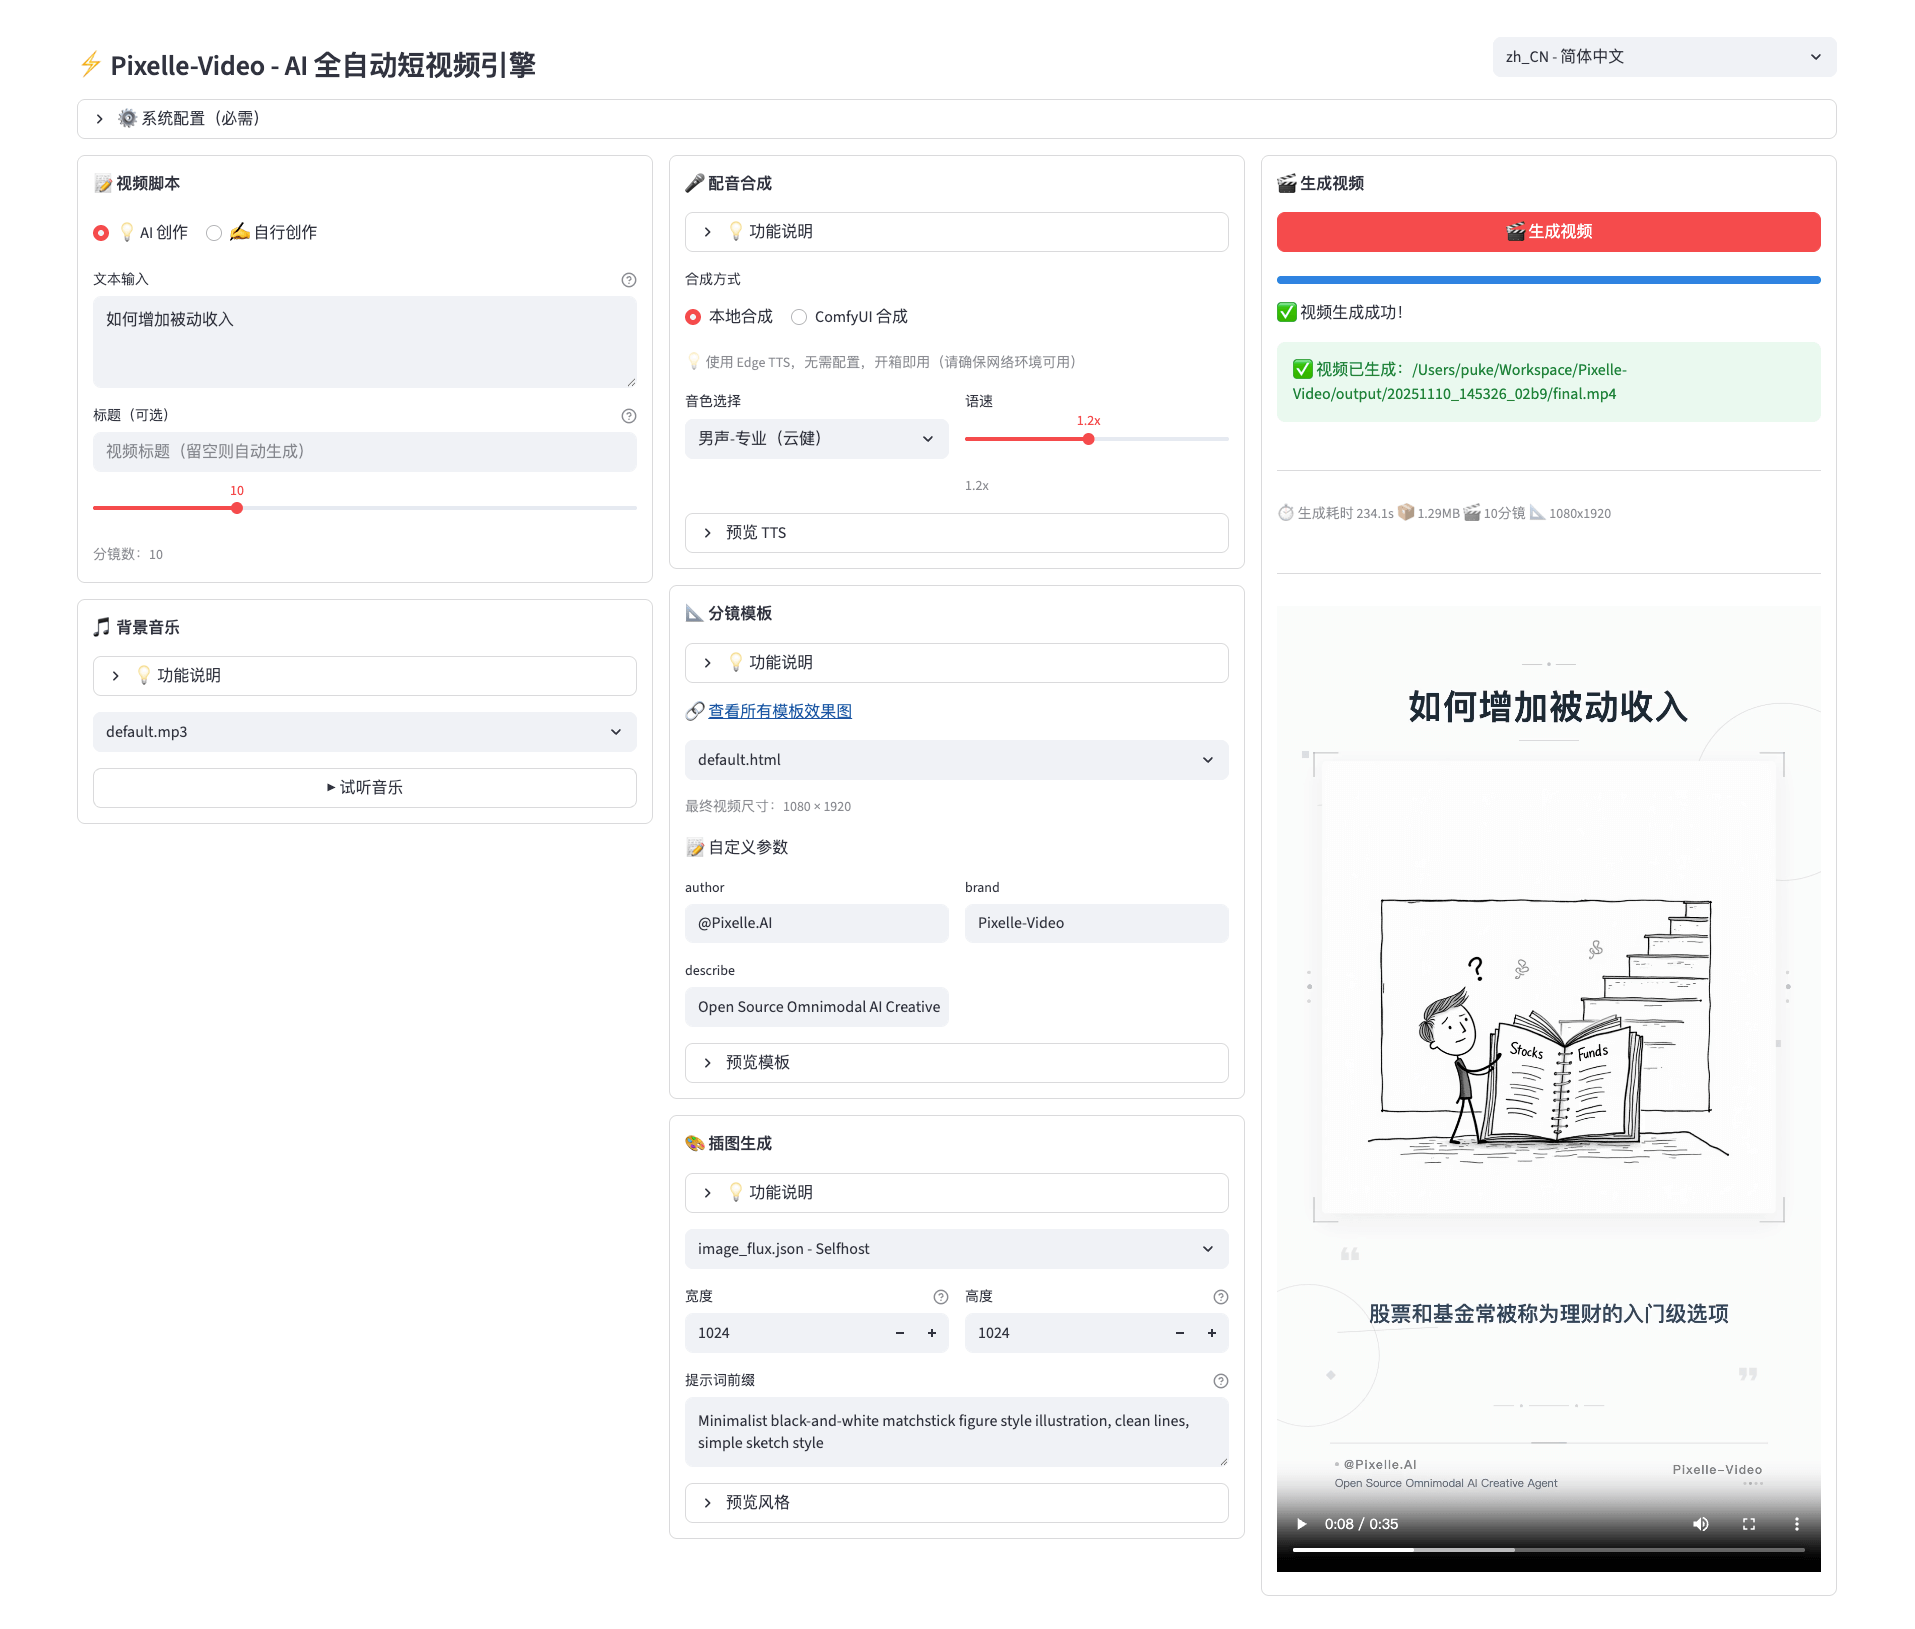
Pixelle-Video
29.2KATH-MaaS/Pixelle-Video · PythonPixelle-Video is an open-source AI short-video engine: give it one topic and it automatically writes the script, generates AI images or video clips, synthesizes the voiceover, adds background music and assembles a finished video — no editing experience needed.
- 5
Toonflow-app
18.5KHBAI-Ltd/Toonflow-app · TypeScriptToonflow is an open-source AI workbench for producing short dramas and motion comics: scriptwriting, storyboarding, character and scene assets, and image and video generation chained into one pipeline on an infinite canvas.
- 6
Wan2.2
18KWan-Video/Wan2.2 · PythonAn open-source family of large-scale video generation models: text-to-video, image-to-video, speech-to-video and character animation, with inference code and model weights released under Apache-2.0.
- 7
FramePack
17.3Klllyasviel/FramePack · PythonFramePack is a next-frame-section prediction neural network for video diffusion, shipped as the official desktop app that turns an image and a short text prompt into a progressively generated video.
- 8
first-order-model
15KAliaksandrSiarohin/first-order-model · Jupyter NotebookThis is the official source code for the 'First Order Motion Model for Image Animation' paper: it animates a static source image by transferring motion from a driving video, using self-learned keypoints instead of manual annotations.
- 9
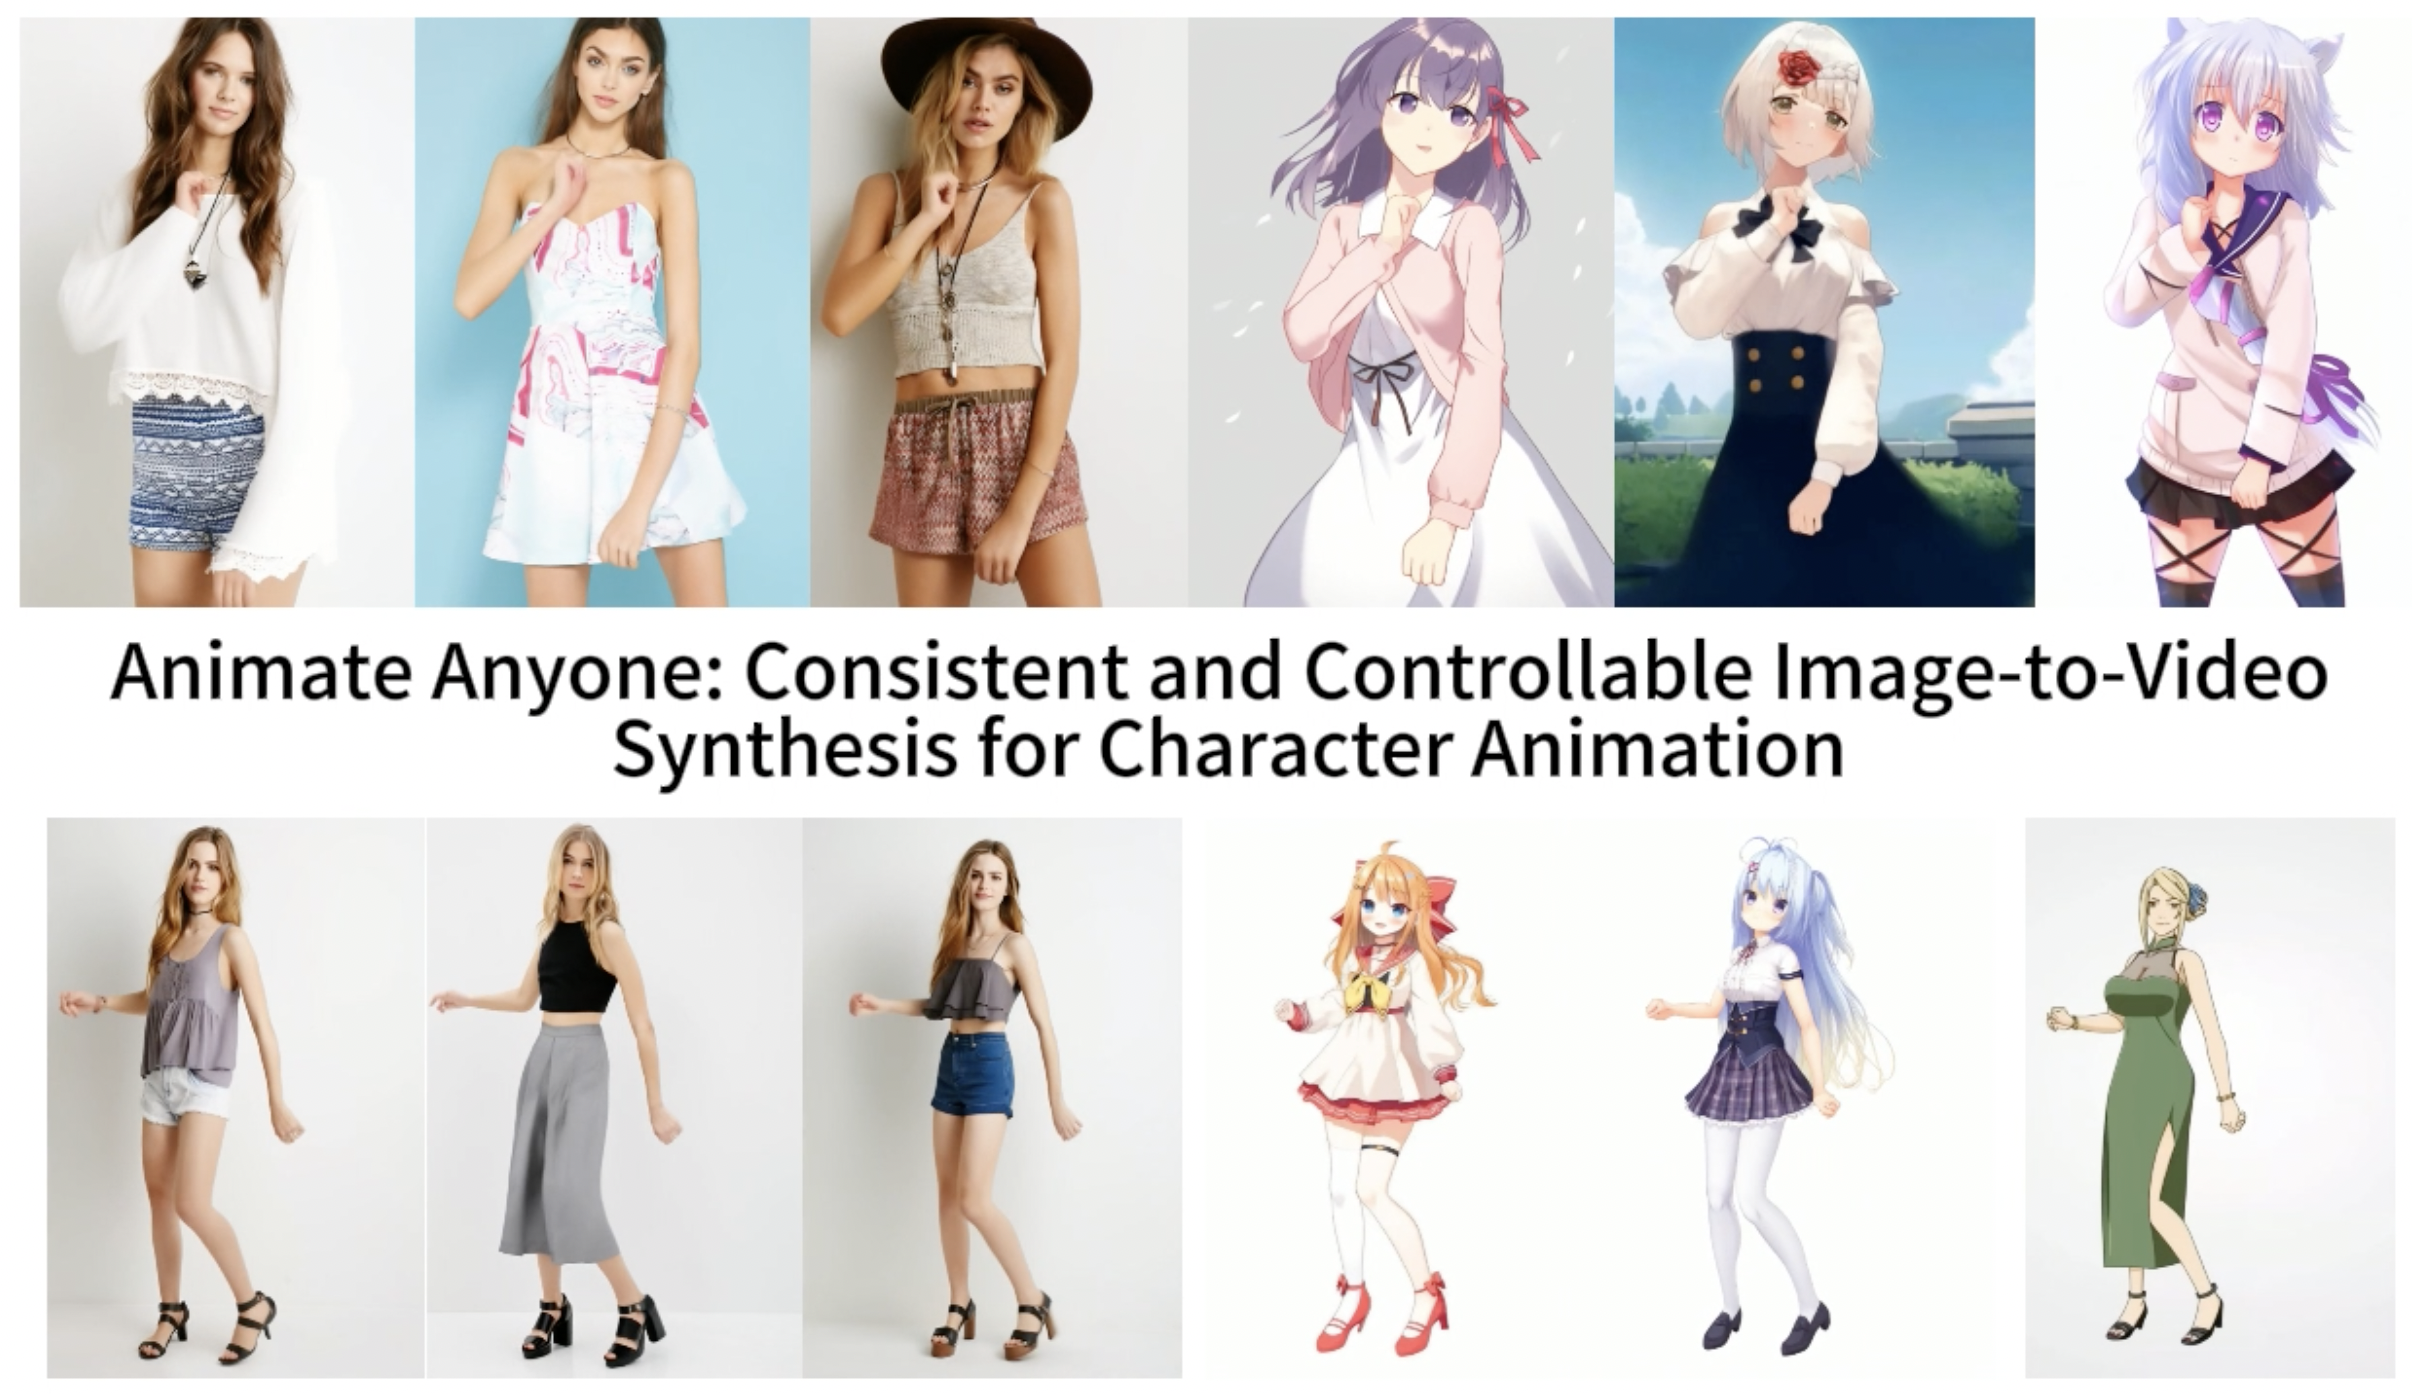
AnimateAnyone
14.8KHumanAIGC/AnimateAnyoneAnimate Anyone is a research project for character animation: it turns a character image into video, synthesizing consistent and controllable motion.
- 10
CogVideo
13.1Kzai-org/CogVideo · PythonAn open-source family of text-to-video and image-to-video models: CogVideoX (2024) and its CogVideoX1.5 upgrade, following CogVideo (ICLR 2023), the first open-source large Transformer-based text-to-video model.
- 11
Open-Sora-Plan
12.2KPKU-YuanGroup/Open-Sora-Plan · PythonOpen-Sora Plan is an open-source community project that aims to reproduce OpenAI's Sora text-to-video model, led by a PKU-affiliated AIGC lab with contributions from Huawei and Pengcheng Lab.
- 12

LTX-Video
11.1KLightricks/LTX-Video · PythonLTX-Video is the official repo for Lightricks' DiT-based video generation model, which generates synchronized audio+video, supports text-to-video and image-to-video, keyframe conditioning, video extension, and video-to-video transformations.
- 13
magic-animate
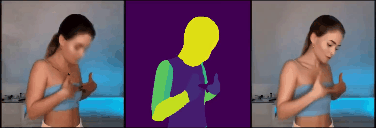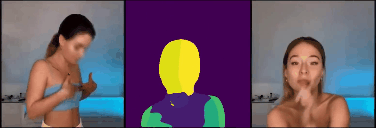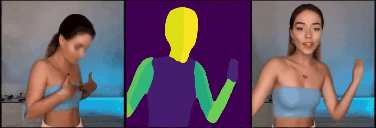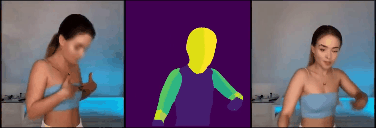
10.9Kmagic-research/magic-animate · PythonThis is the official codebase for 'MagicAnimate' (CVPR 2024), a diffusion-model method that animates a reference human image according to a motion sequence to produce temporally consistent video.
- 14
MiniMax-H3
10.2KMiniMax-AI/MiniMax-H3 · PythonMiniMax H3 is a general-purpose omni-modal generative system: it reads mixed text, image, video and audio input and generates video with native stereo audio, up to 2K resolution and 15 seconds per clip.
- 15
LTX-2
9.8KLightricks/LTX-2 · PythonThe official Python package for LTX-2, Lightricks' audio-video foundation model: one DiT-based model that generates video with synchronized audio from text or an image, in several quality/speed modes.
- 16
LongCat-Video
9.2Kmeituan-longcat/LongCat-Video · PythonLongCat-Video is a 13.6B-parameter foundational video generation model that unifies Text-to-Video, Image-to-Video, and Video-Continuation generation in a single architecture, aimed at efficient long-video generation and framed as a first step toward world models.
- 17
seedance-2.0
7.8KEmily2040/seedance-2.0 · PythonSeedance 2.0 Skill OS is an agent skill that helps you plan video shots, write detailed directed prompts, bind image/video/audio references, and continue from an already-accepted clip — the actual rendering is done by a separate Seedance 2.0 video provider.
- 18
stable-diffusion.cpp
7.7Kleejet/stable-diffusion.cpp · C++A pure C/C++ inference engine for diffusion models like Stable Diffusion, Flux, Wan, Qwen Image, and Z-Image, built the same way as llama.cpp so you can generate images and videos without heavy Python dependencies.
- 19
dramaclaw
6.4Kdramaclaw/dramaclaw · PythonDramaClaw is a self-hosted AIGC video production pipeline that turns a script or manuscript into a finished film — handling story structuring, storyboards, voice-over and final cut — plus a node-based canvas for freeform generative work.
- 20
ArcReel
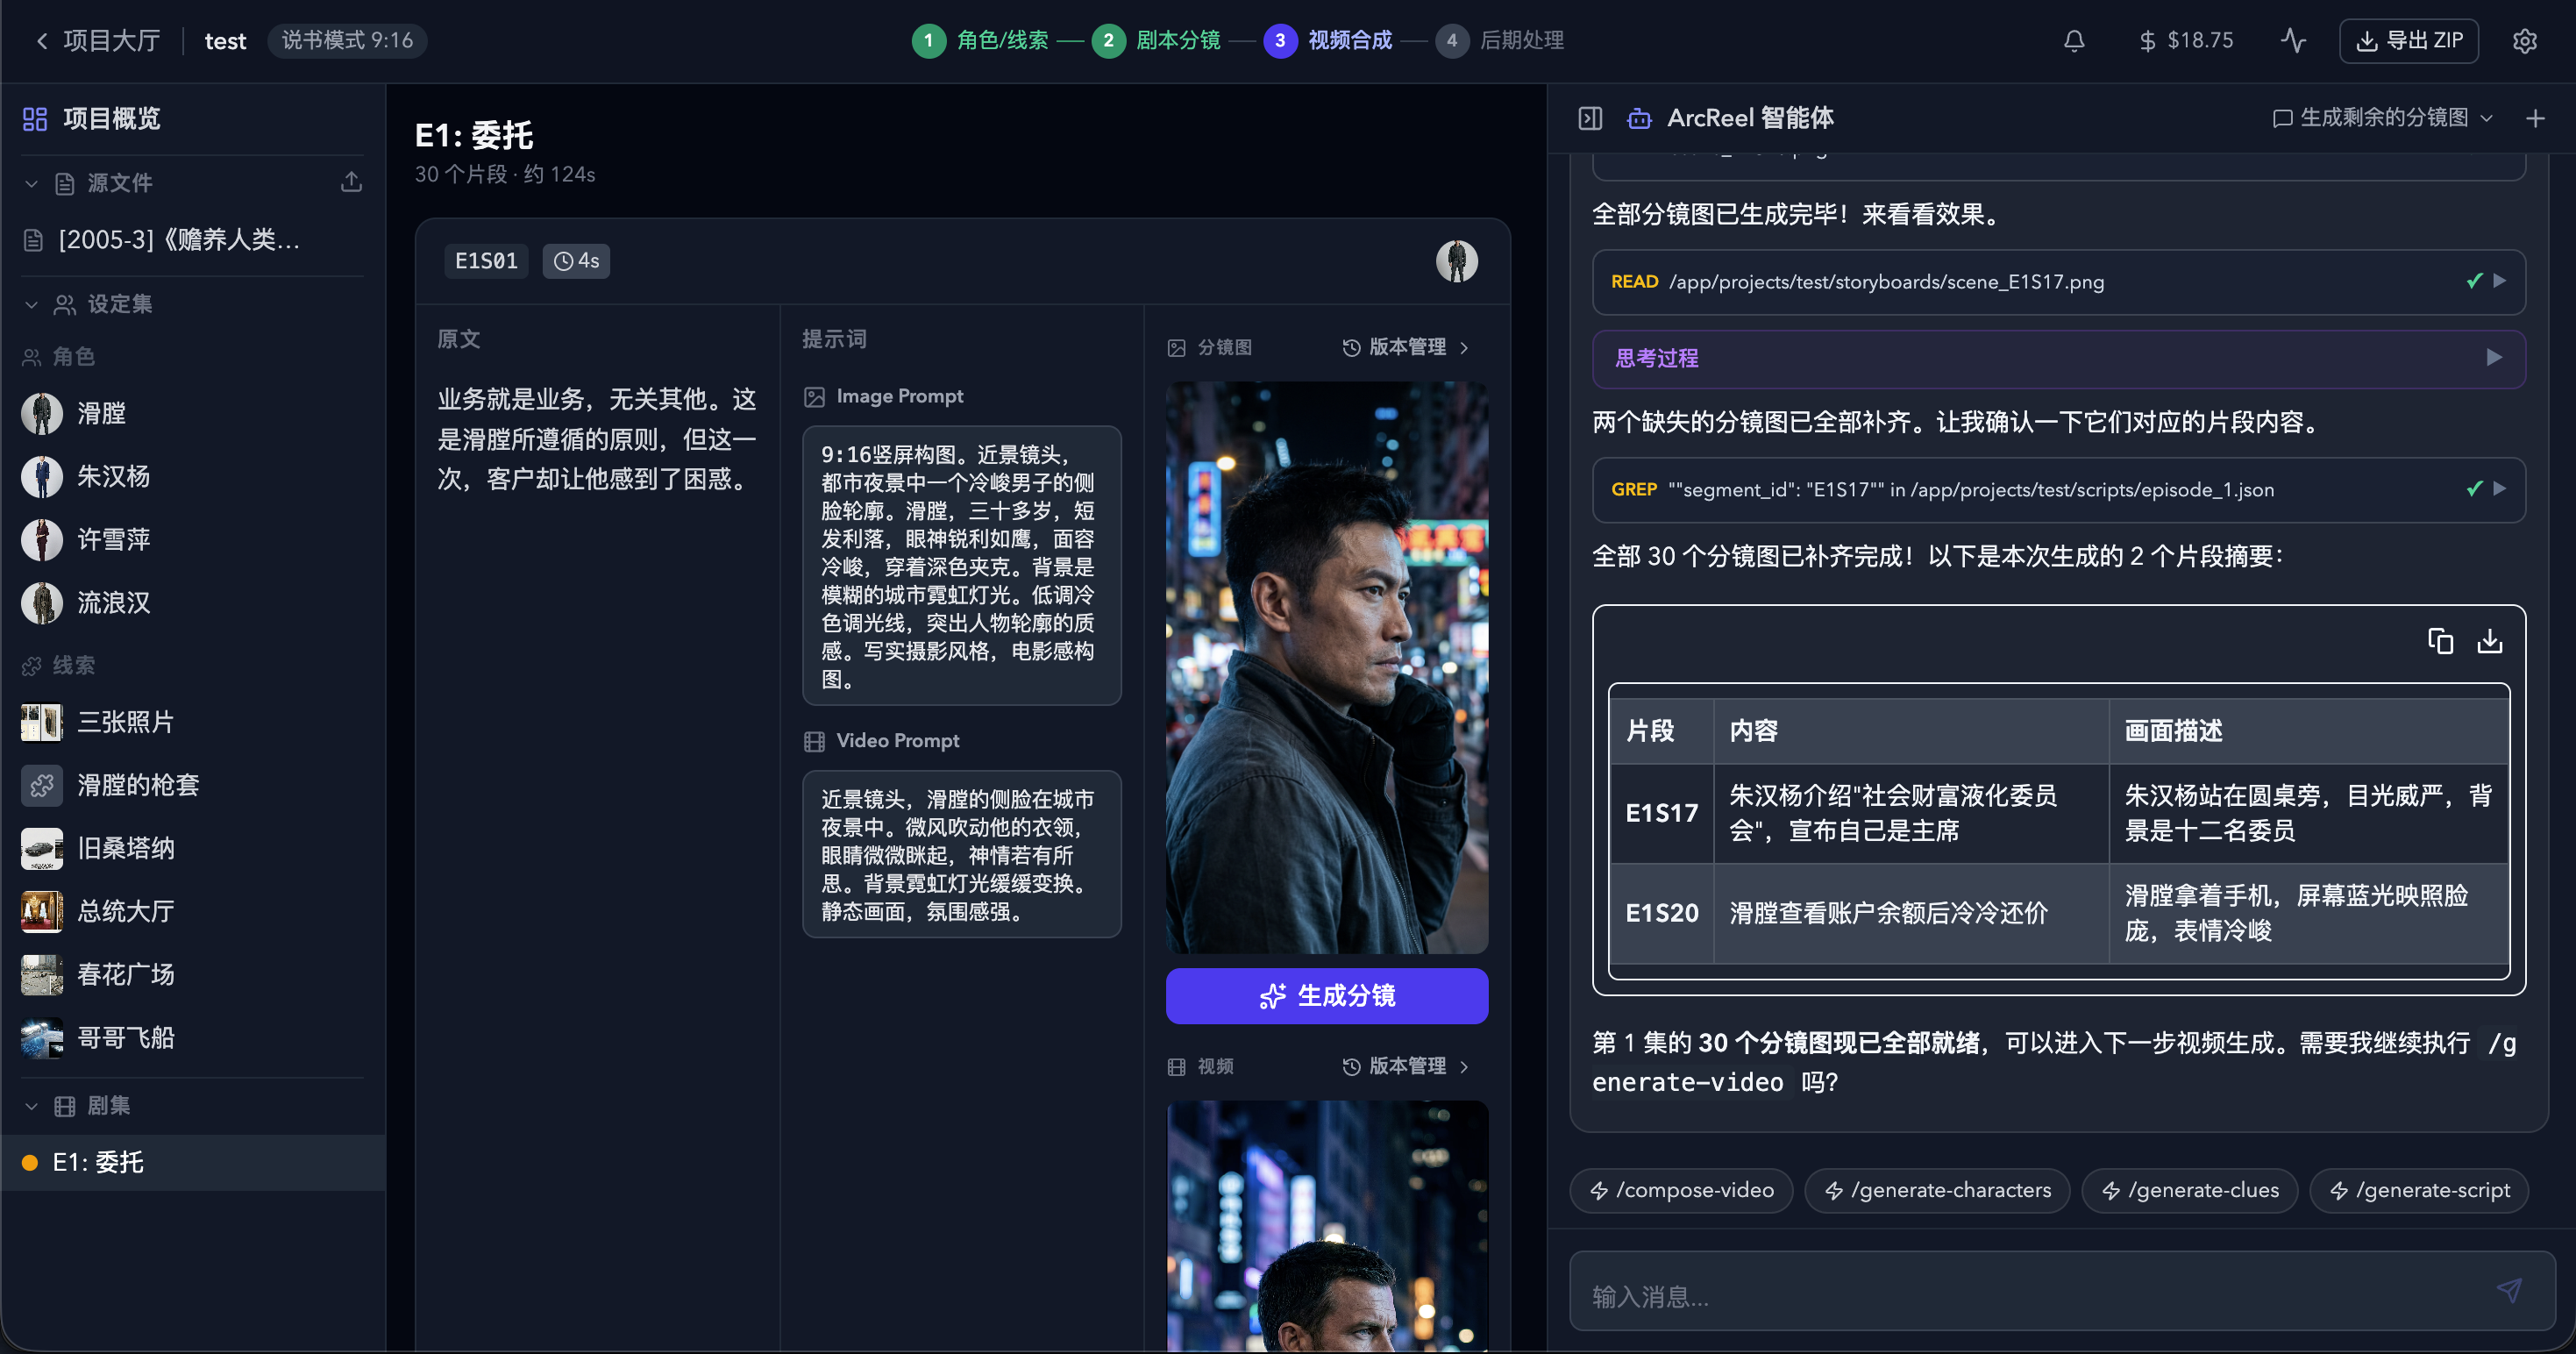
5.6KArcReel/ArcReel · PythonArcReel is an open-source, self-hosted AI video production workspace that turns novels, finished scripts, or product materials into characters, scenes, props, storyboards, video clips and a final cut.
- 21

AgnesAI-Models
5.2KAgnesAI-Labs/AgnesAI-ModelsAgnes AI is the official gateway and model catalog for Agnes AI, giving developers OpenAI-compatible access to multimodal models for text, image, video, and agent workflows through one unified API.
- 22
moyin-creator
4.7KMemeCalculate/moyin-creator · TypeScriptMoyin Creator (魔因漫创) is a production-grade AI tool for film and video creators that automates the whole pipeline from script to finished video: script parsing, character design, scene generation, storyboarding, and Seedance 2.0-powered image/video batch generation.
- 23

HunyuanVideo-1.5
4.6KTencent-Hunyuan/HunyuanVideo-1.5 · PythonHunyuanVideo-1.5 is a video generation model from Tencent that creates text-to-video and image-to-video clips, achieving top-tier quality with only 8.3B parameters so it runs on consumer-grade GPUs.
- 24
lingbot-world
4.5KRobbyant/lingbot-world · PythonLingBot-World is an open-source world model/simulator built from video generation: it turns an input image, text prompt, and optional control signals (camera poses or actions) into a long, controllable video that behaves like an interactive world.
- 25
TurboDiffusion
3.9Kthu-ml/TurboDiffusion · PythonTurboDiffusion is a video generation acceleration framework that speeds up end-to-end video diffusion generation by 100-200x on a single RTX 5090 while keeping video quality, using SageAttention, Sparse-Linear Attention (SLA), and rCM timestep distillation.
- 26
locally-uncensored
2.4KPurpleDoubleD/locally-uncensored · TypeScriptThis is an all-in-one local AI studio for your desktop that bundles chat, image and video generation, and a coding agent into a single free, open-source app for Windows and Linux.
- 27
FreeVideo
2.2KFlashML-org/FreeVideo · PythonFreeVideo is a local inference engine that lets you run the MiniMax H3 video generation model on your own consumer GPU instead of a cloud service, adapting its memory and compute strategy to your hardware.
- 28
Evoke
862AlayaLab/Evoke · PythonEVOKE is a research implementation of an interactive 'world model' that generates endless, controllable video: a three-step, CFG-free system that remembers where it has already been, lets you redirect it mid-rollout, and is state-of-the-art on the WBench long-horizon benchmark.
- 29
ComfyUI-Ref2VA-VSA
826Kablex/ComfyUI-Ref2VA-VSA · PythonIt's a ComfyUI custom node that dramatically speeds up Reference-to-Video (Ref2VA) generation for the MiniMax H3 model, producing a full 5-second, 24fps character video in about 72 seconds on a single RTX 4090 instead of over 10 minutes.
- 30
SolarWM
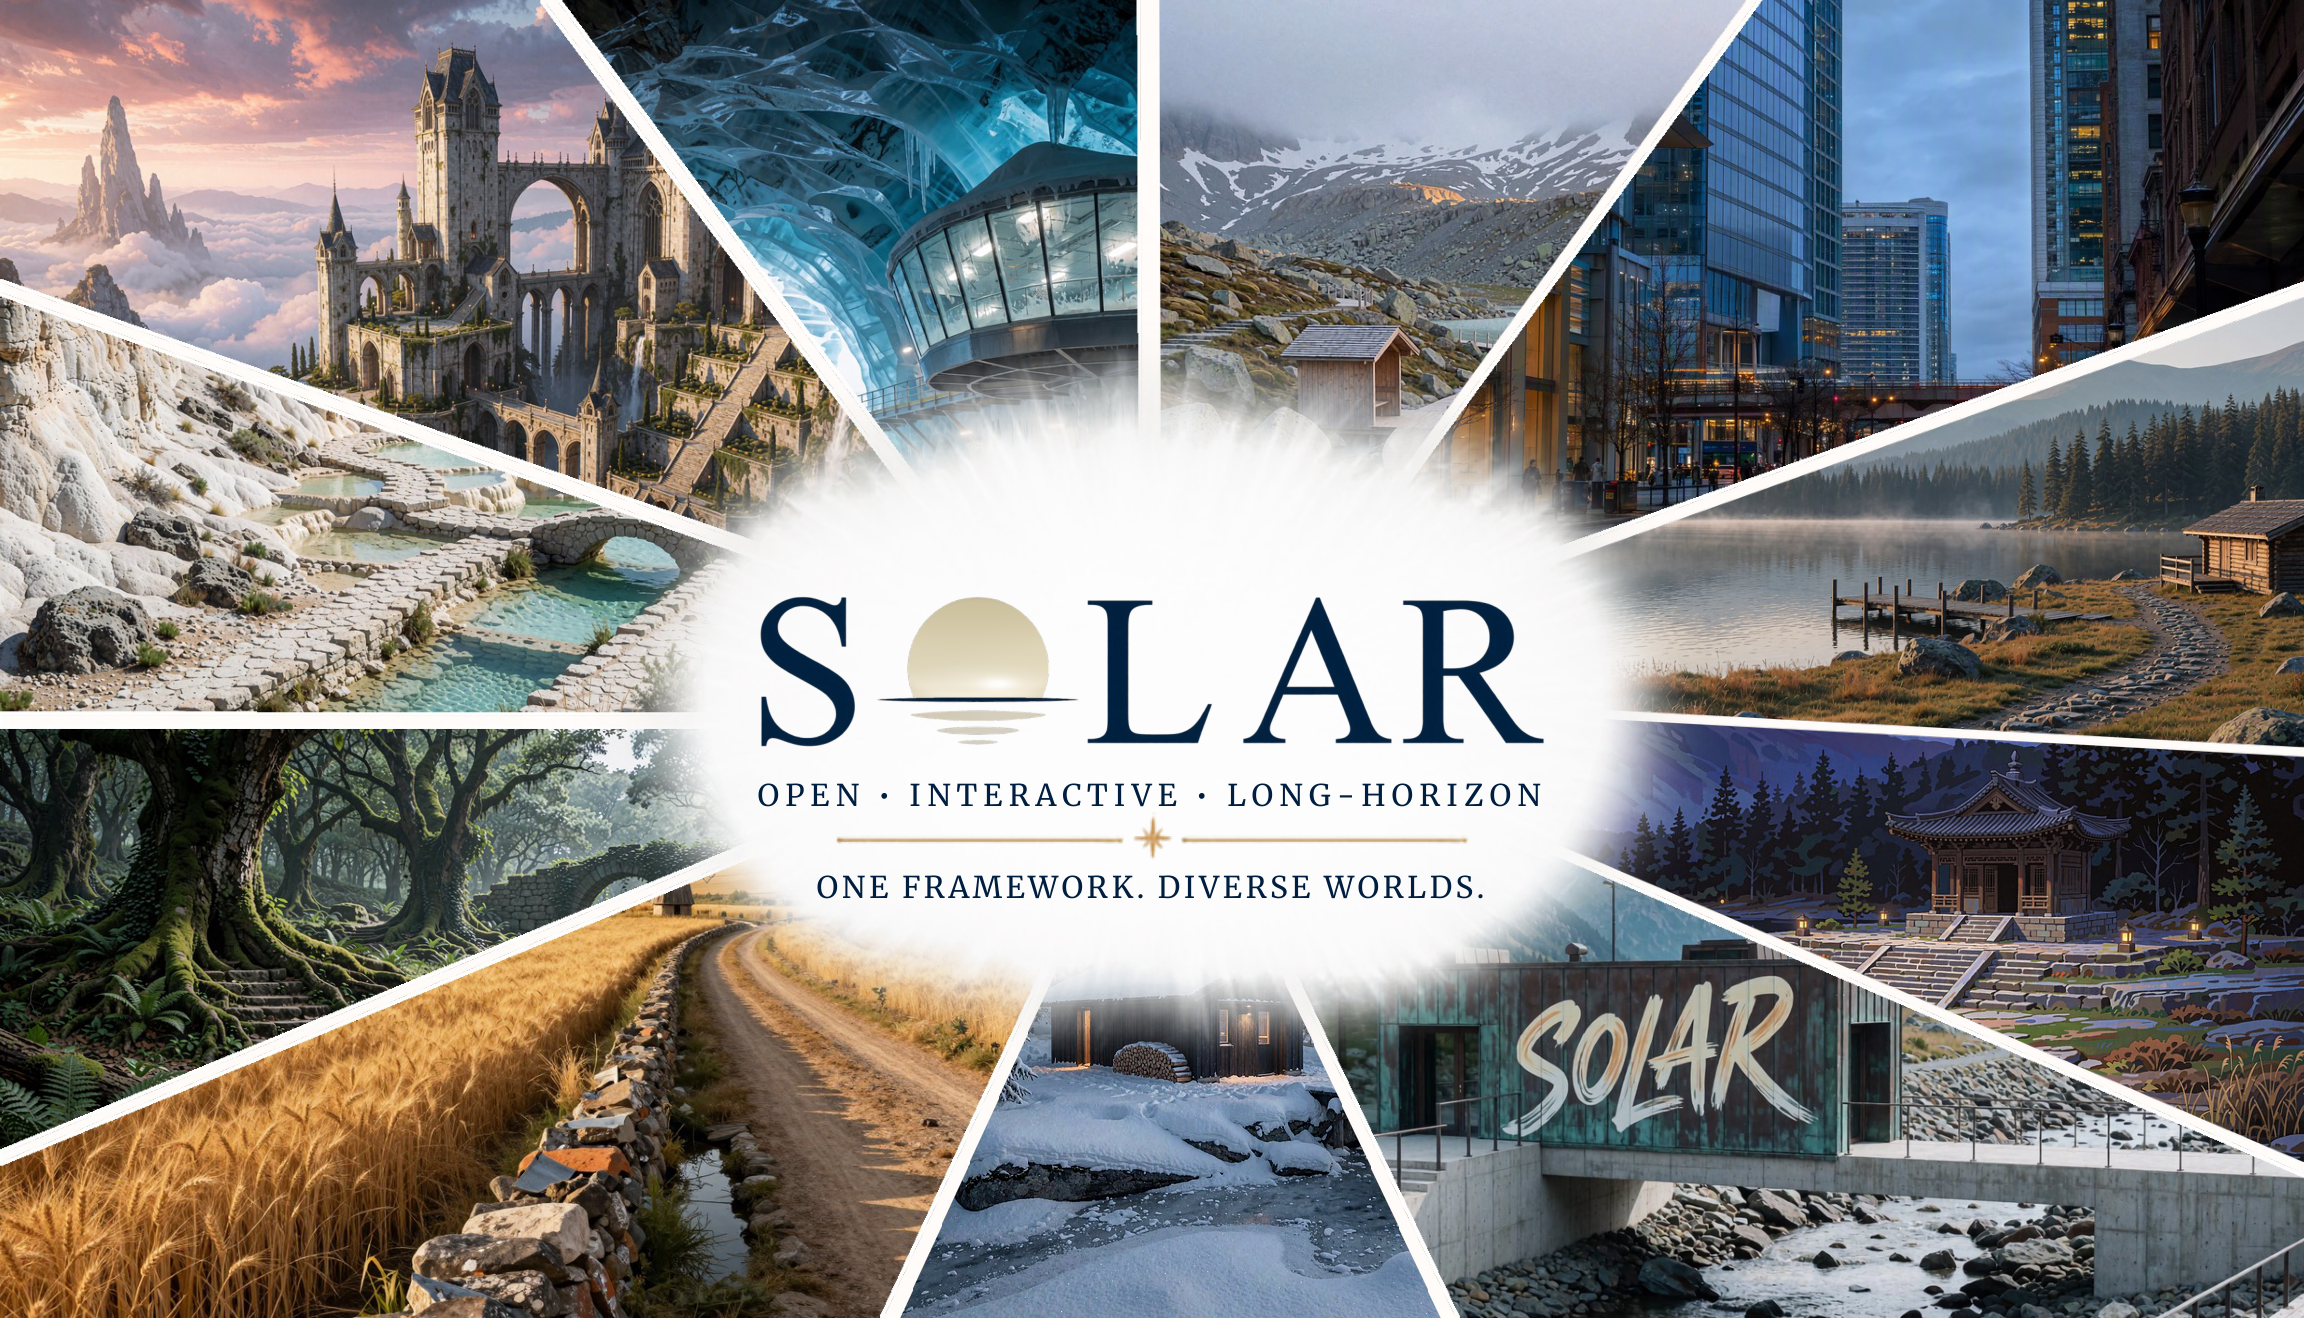
781Junchao-cs/SolarWM · PythonSolarWM is a fully open foundation for building interactive video world models, covering data preparation, scalable multi-backbone training, and long-horizon inference.
- 31
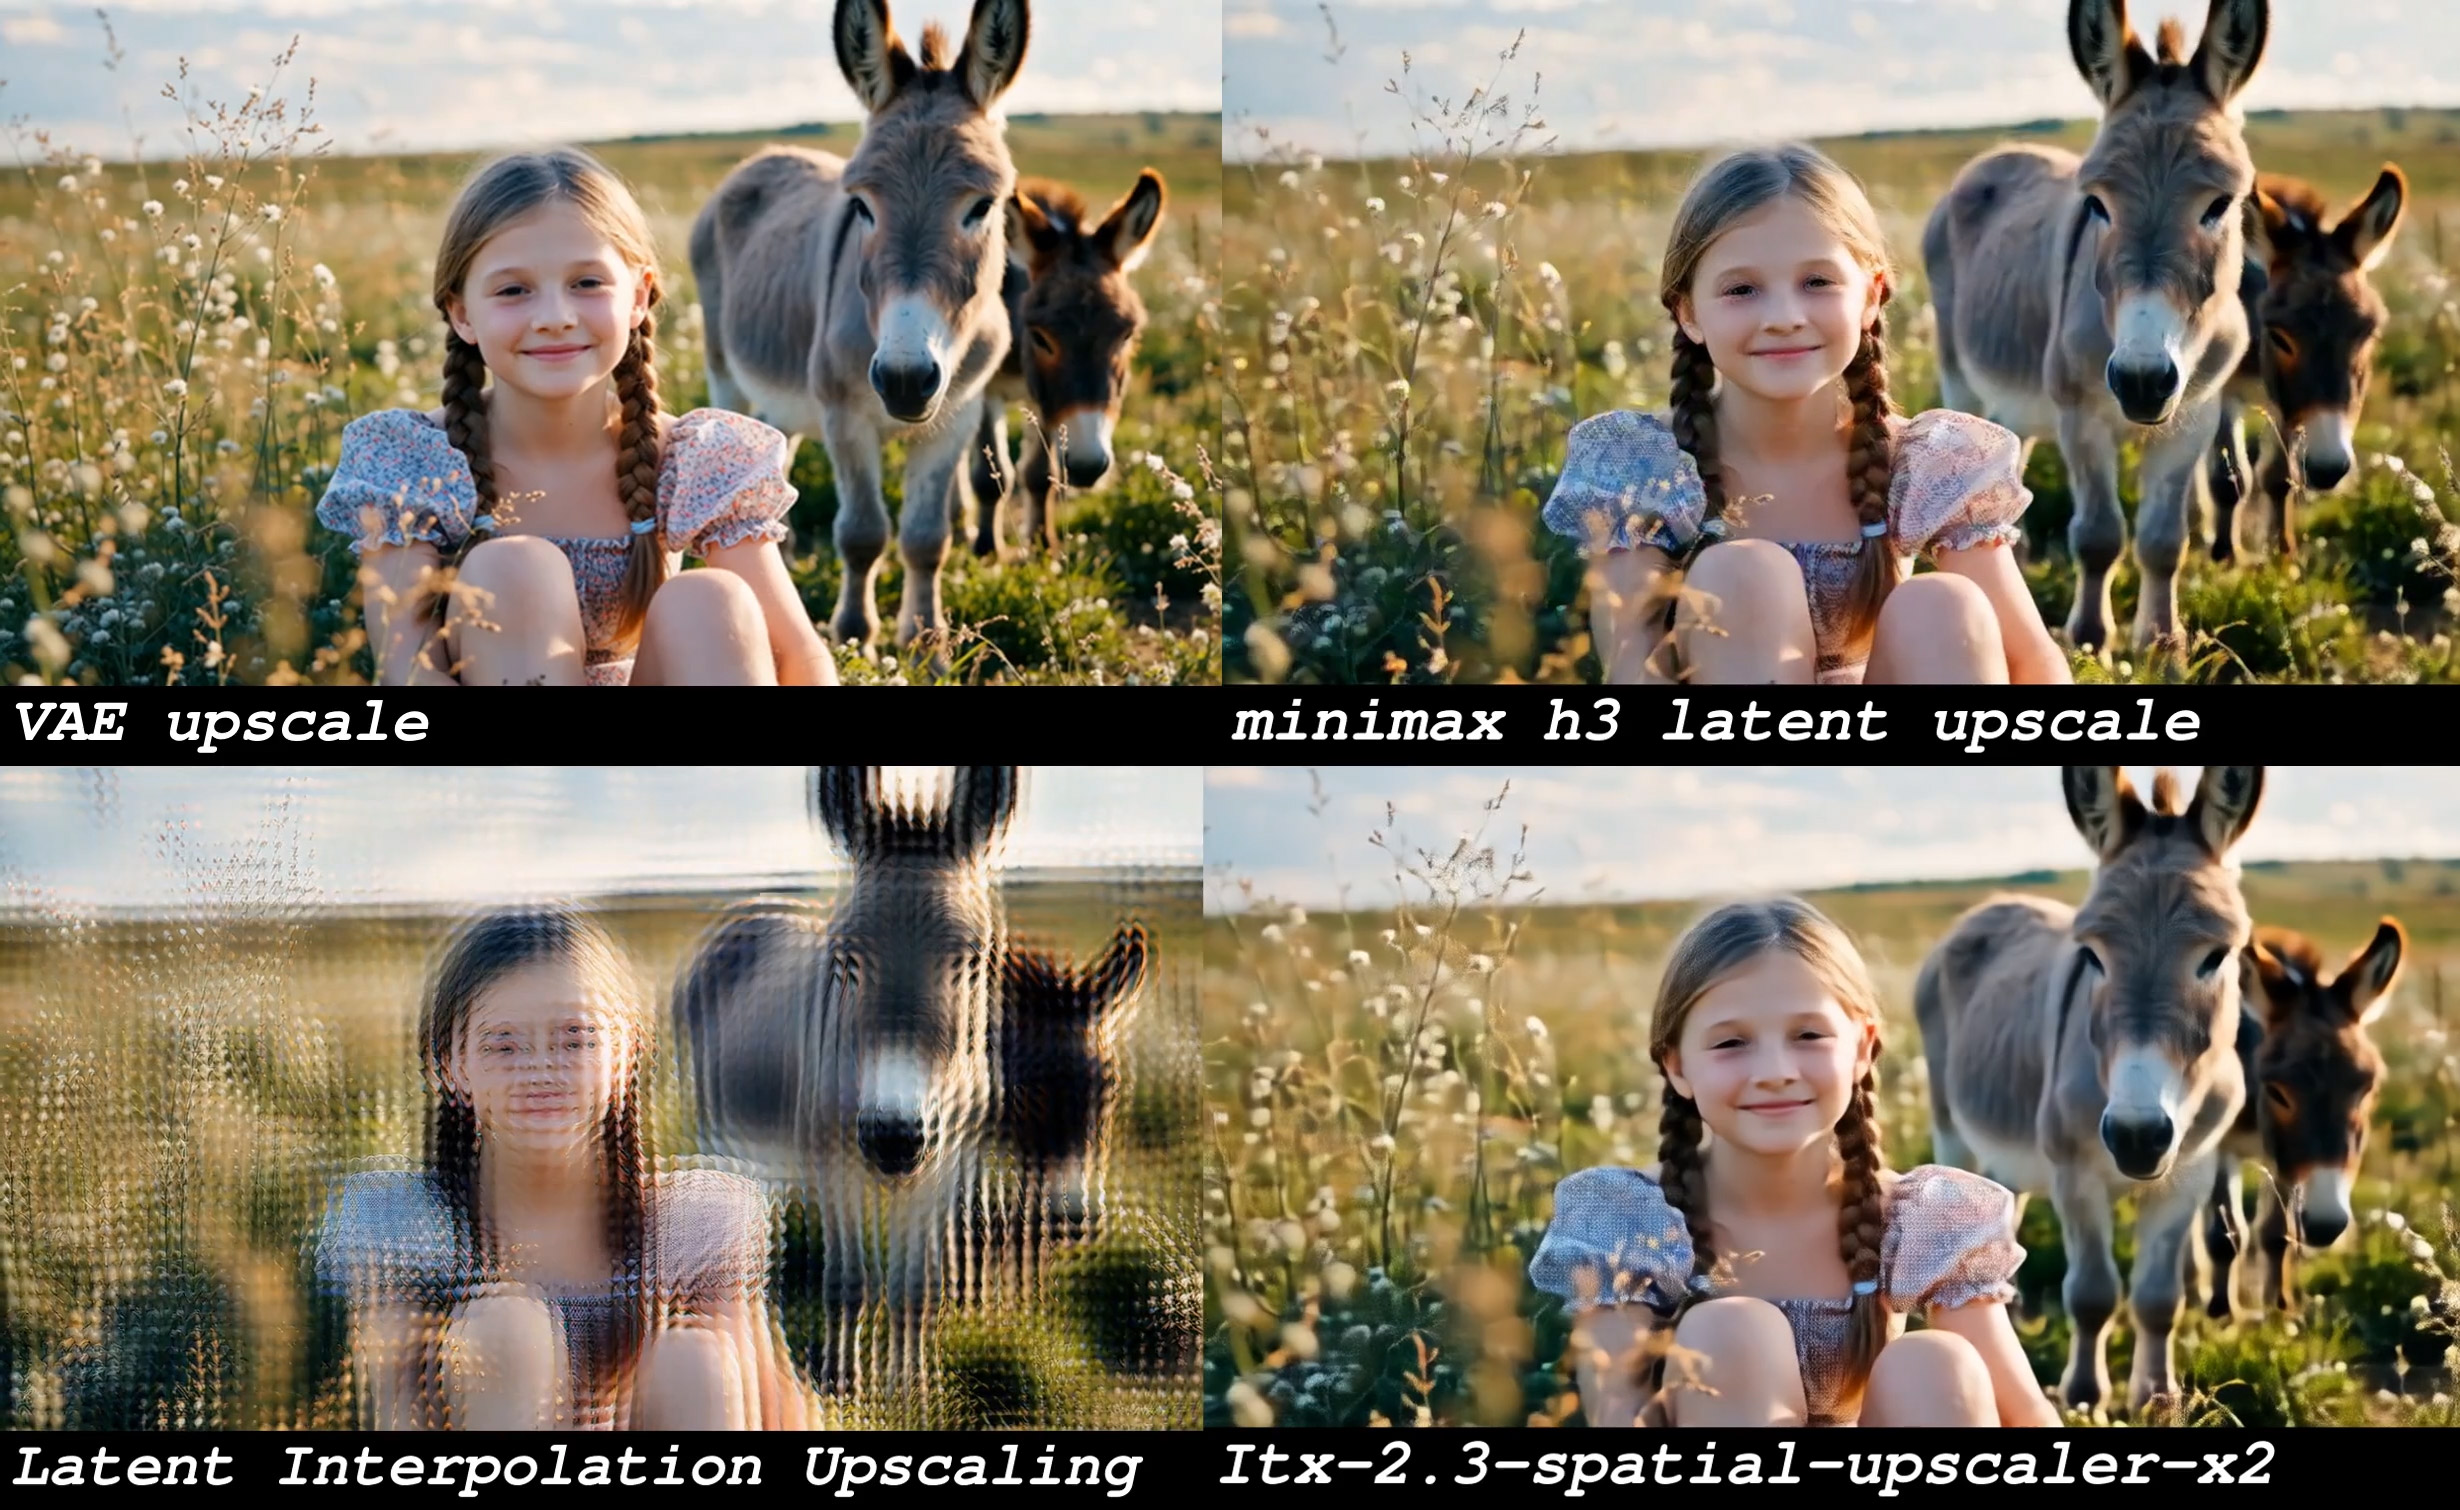
Comfyui_Minimax_h3_latent_Upscaler
758LBH-123-AI/Comfyui_Minimax_h3_latent_Upscaler · PythonA custom ComfyUI node that upscales Minimax H3 video latents (24 channels) using a trained neural network instead of naive bilinear/bicubic interpolation, so you can generate at low resolution and upscale in latent space before refining.
- 32
ComfyUI-MiniMaxH3-TimelineDirector
663Songssx/ComfyUI-MiniMaxH3-TimelineDirector · PythonIt's an editable reference-media timeline UI for ComfyUI's native MiniMax H3 Reference-to-Video workflow, letting you arrange reference videos, images, audio, and Guides on one timeline to drive text-to-video, character replacement, motion transfer, digital humans, and long-form video generation.
- 33

CodeVideoModel
586code-video-model/CodeVideoModel · PythonCodeVideoModel is a research pipeline that turns a text prompt into an editable Three.js scene codebase, converts that scene into a reference image, and then renders a final video with the MiniMax-H3 model. It also ships CodeVideoBench, a benchmark of 22 evaluation cases for this code-to-video workflow.
- 34
3dicon
562samyost1/3dicon · PythonA Claude Code skill: one plain-language prompt in, one looping animated 3D icon out — an animated WebP with real transparency you can drop straight into an app UI.
- 35
SparkDiffusion
520AlibabaResearch/SparkDiffusion · PythonSparkDiffusion is an acceleration framework for Diffusion Transformer (DiT) video-generation models. It combines sparse low-rank attention (RoLa), few-step distillation (CrossDistill), and custom GPU operators to deliver 200x+ faster inference than a dense multi-step baseline while preserving generation quality.
- 36
h3lite
459Rimagination/h3lite · PythonH3 Lite is a Codex/WorkBuddy AI agent skill that drives local MiniMax H3 video generation through ComfyUI, picking a hardware-aware route and producing videos with native audio from a description.
- 37
awesome-minimax-h3-integration
449MiniMax-AI/awesome-minimax-h3-integrationA community-maintained index of checkpoints, tools, and workflows for MiniMax H3, a video generation model that produces clips with native stereo audio from text, image, video, and audio inputs.
- 38
Sketch2Motion
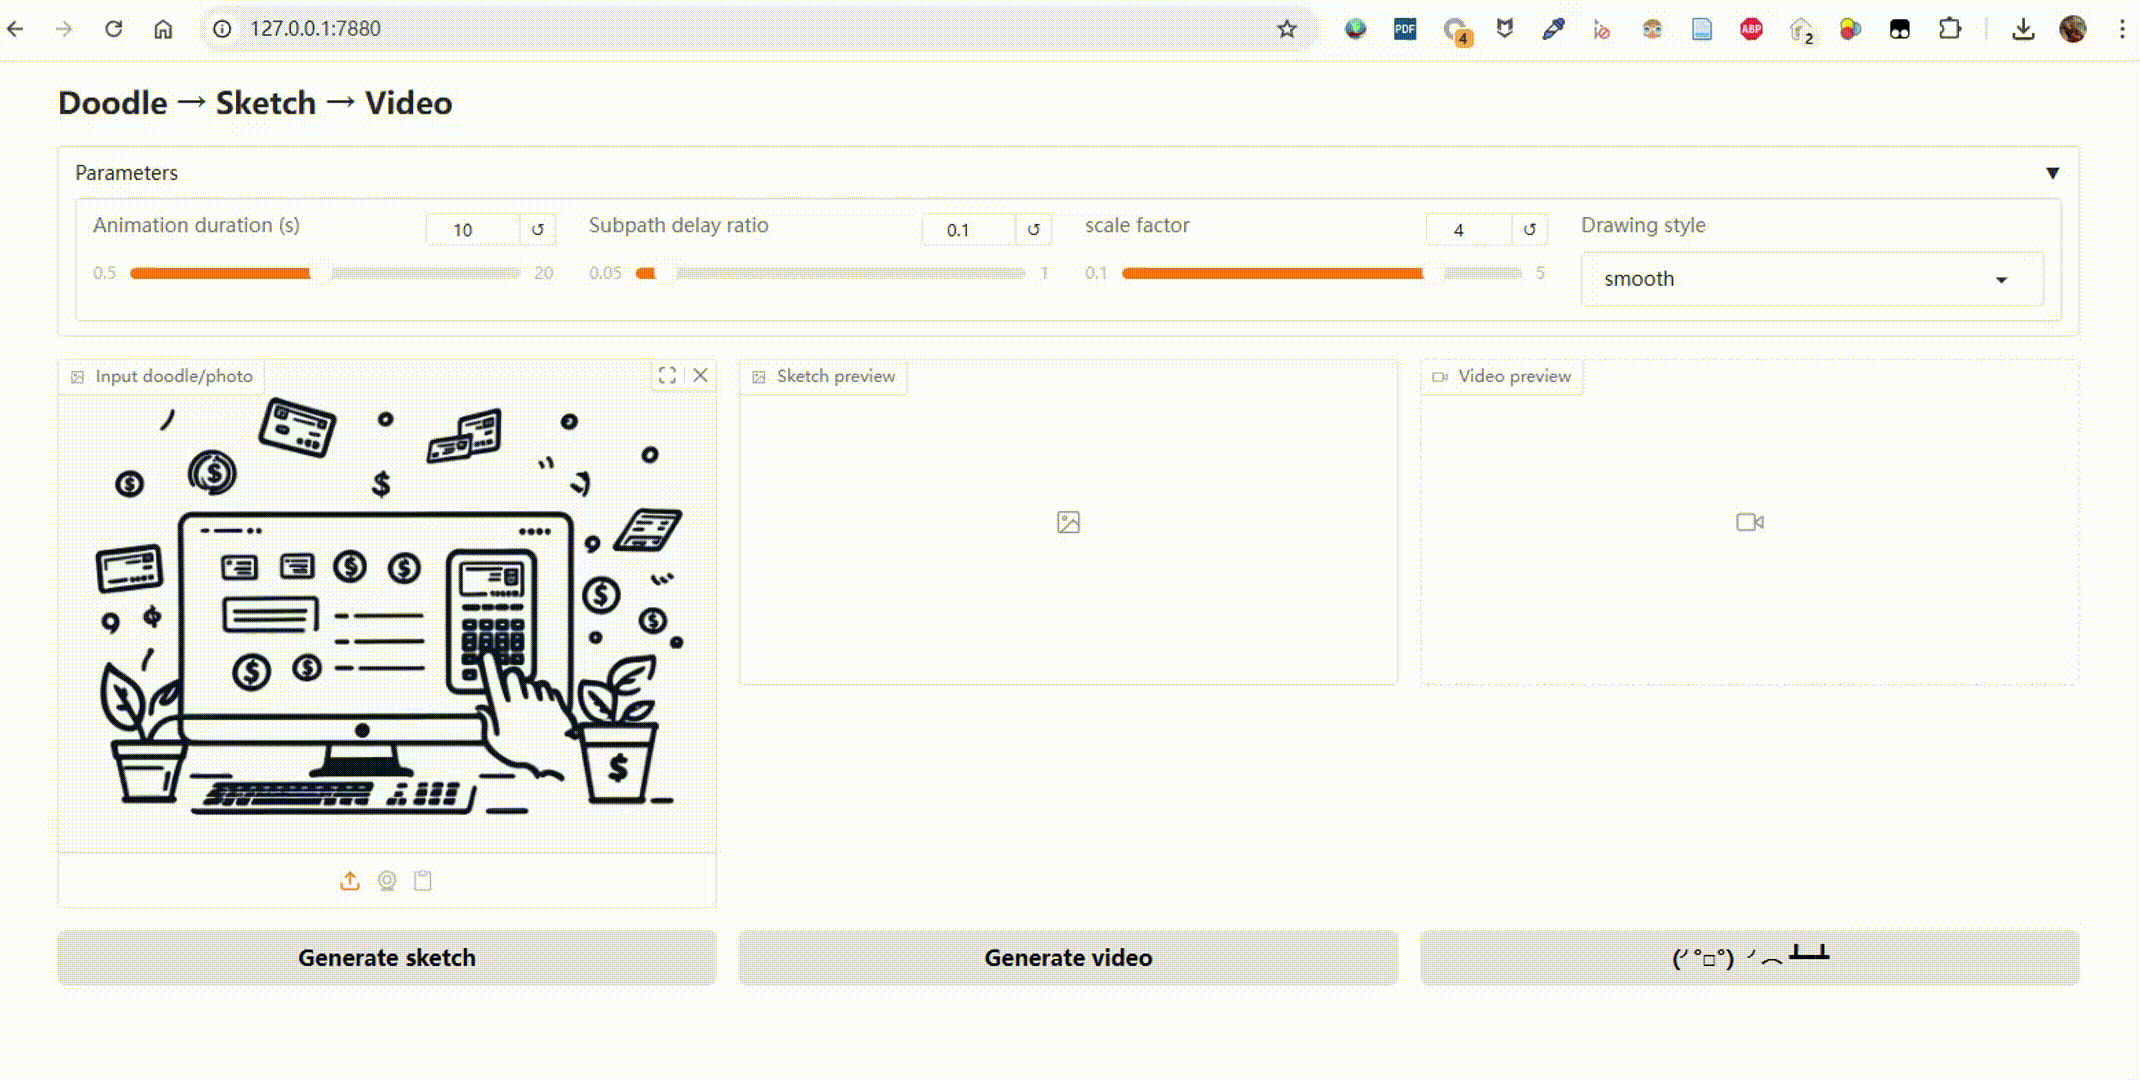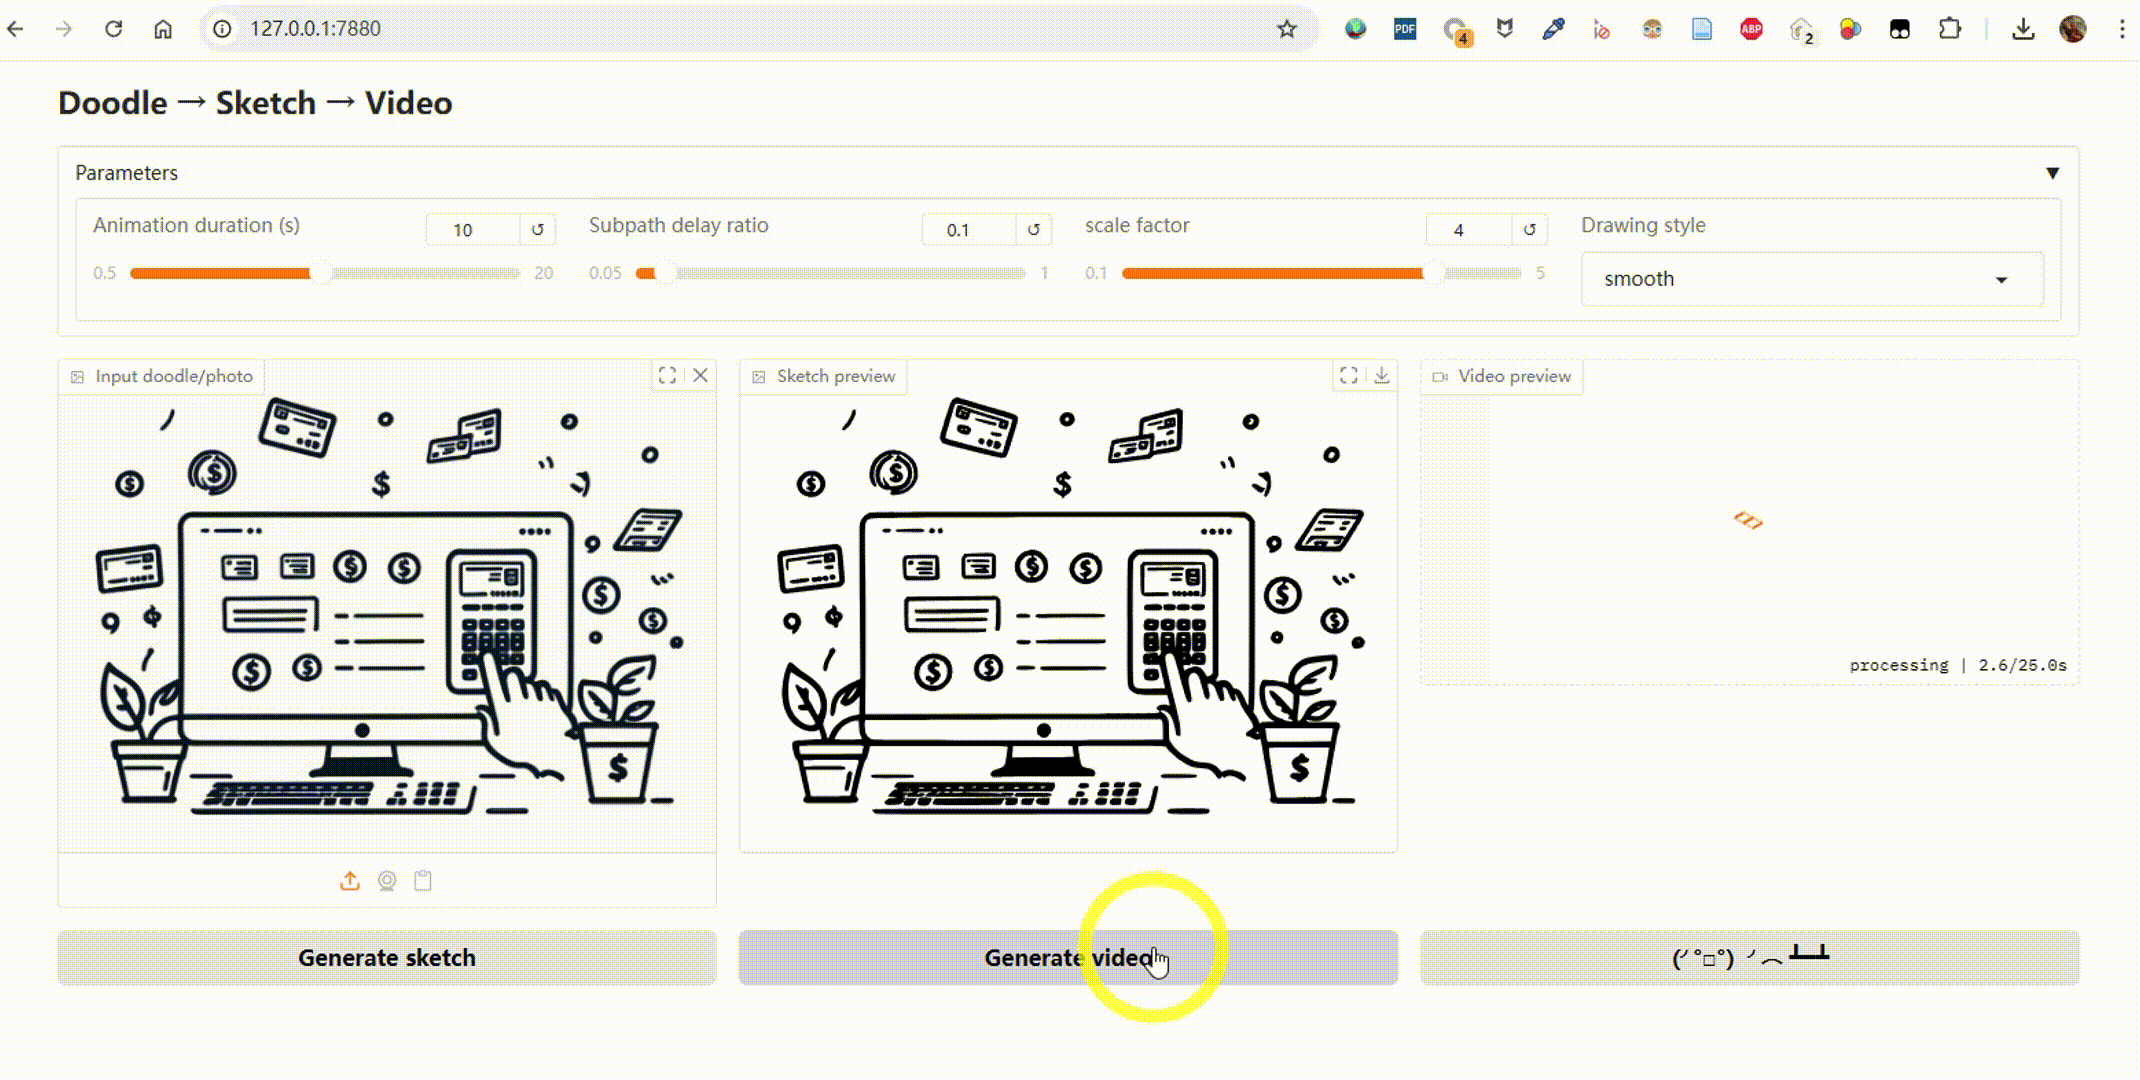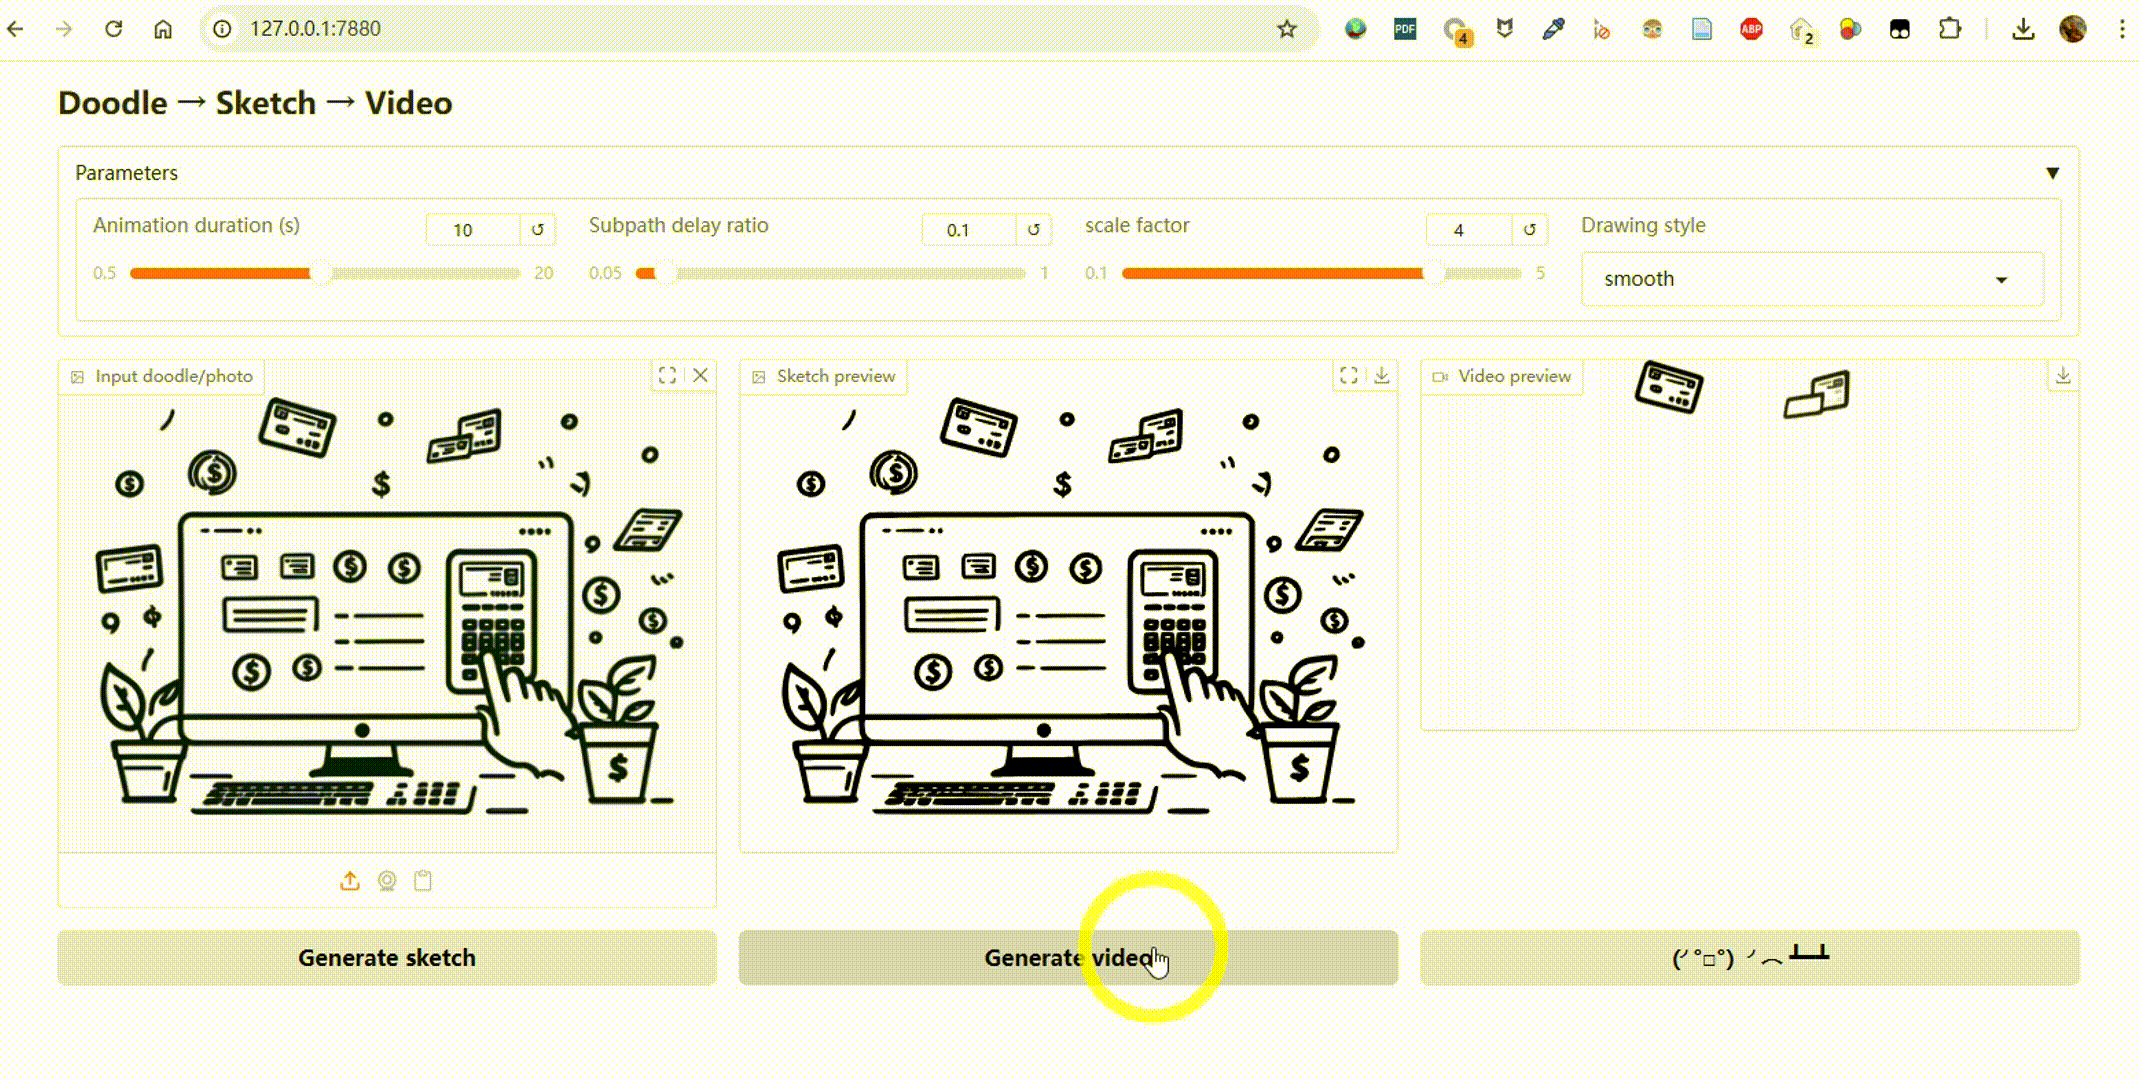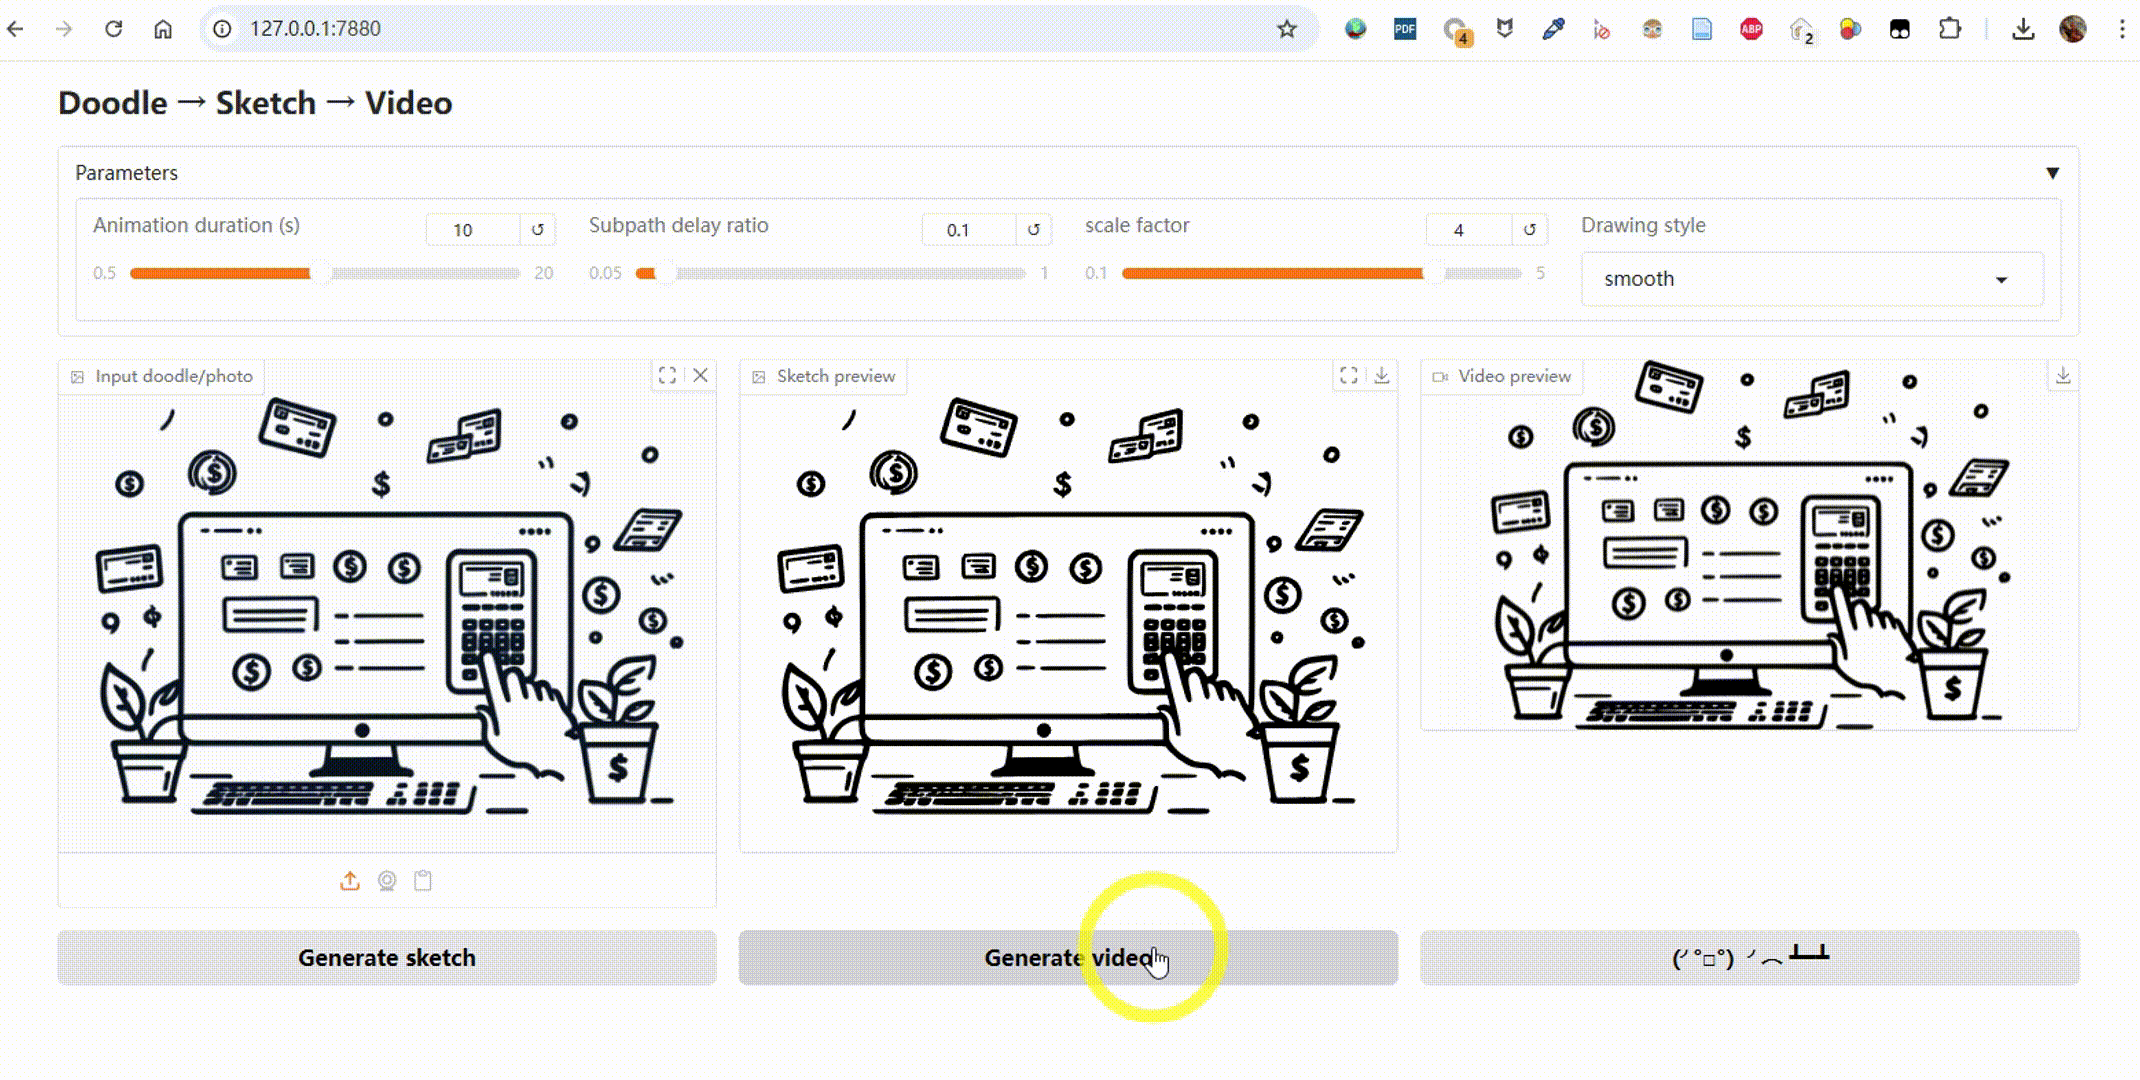
383leeyeel/Sketch2Motion · PythonSketch2Motion converts a photo, doodle, or sketch into an animated drawing-style MP4 video, as if someone were drawing it by hand.
- 39
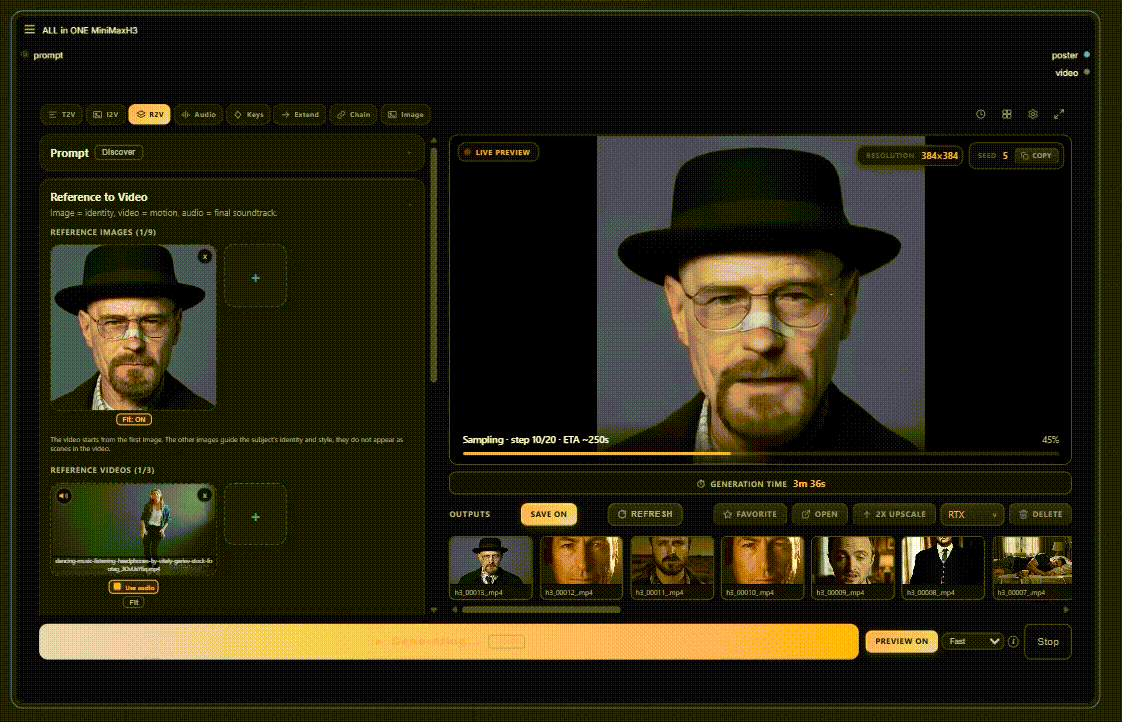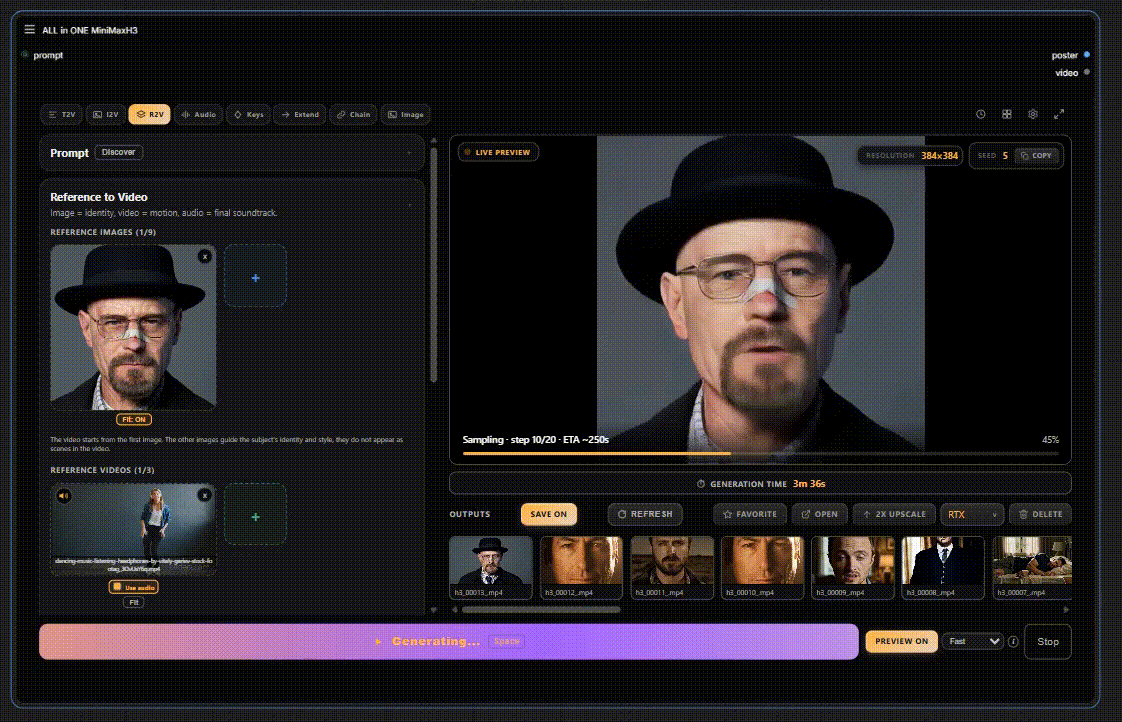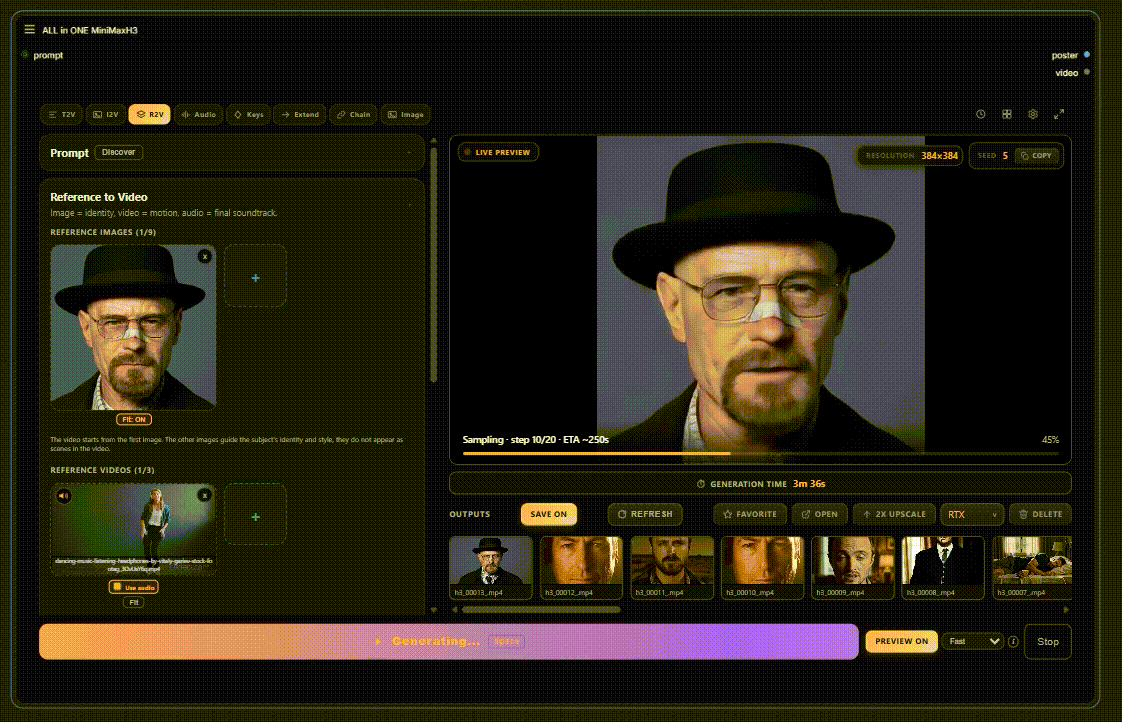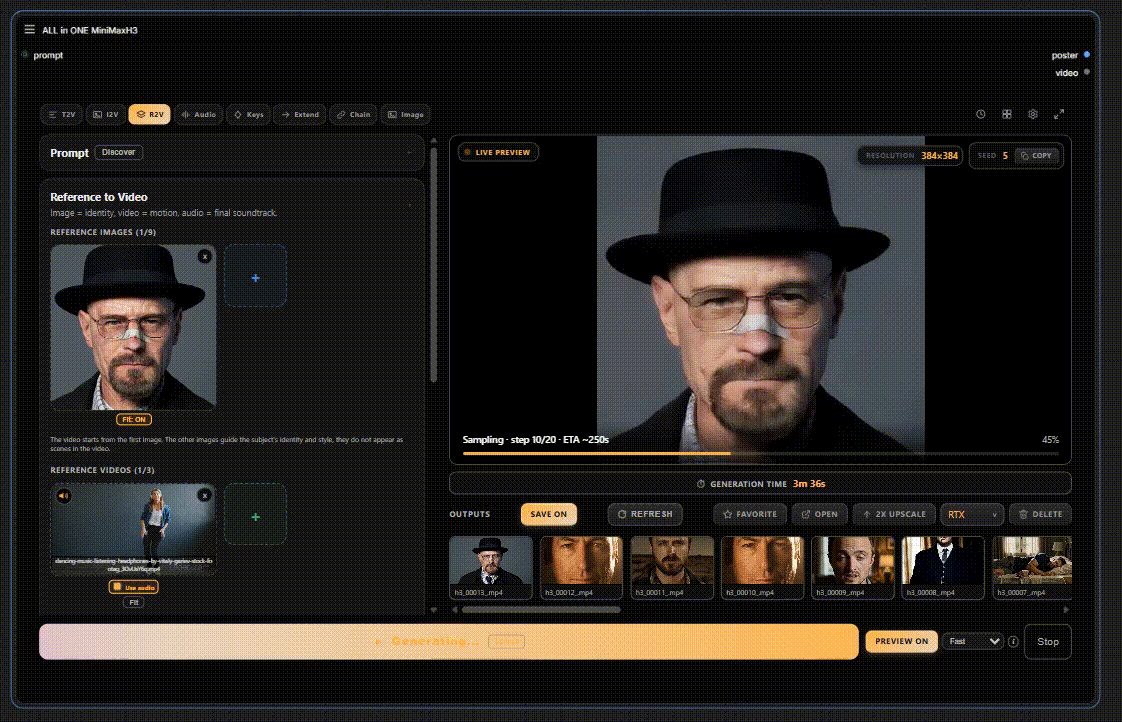
ComfyUI-ALLinONE-MinimaxH3
355LeonQ8/ComfyUI-ALLinONE-MinimaxH3 · JavaScriptA single custom node for ComfyUI that packs the whole MiniMax H3 video pipeline into one node — pick a mode, drop in your prompt or references, and hit Generate.
- 40

seedance-2.0-api
329apiframe-ai/seedance-2.0-apiThis repo contains example scripts for calling ByteDance's Seedance 2.0 video generation model through the Apiframe API, covering text-to-video, image-to-video, and reference-to-video generation.
- 41
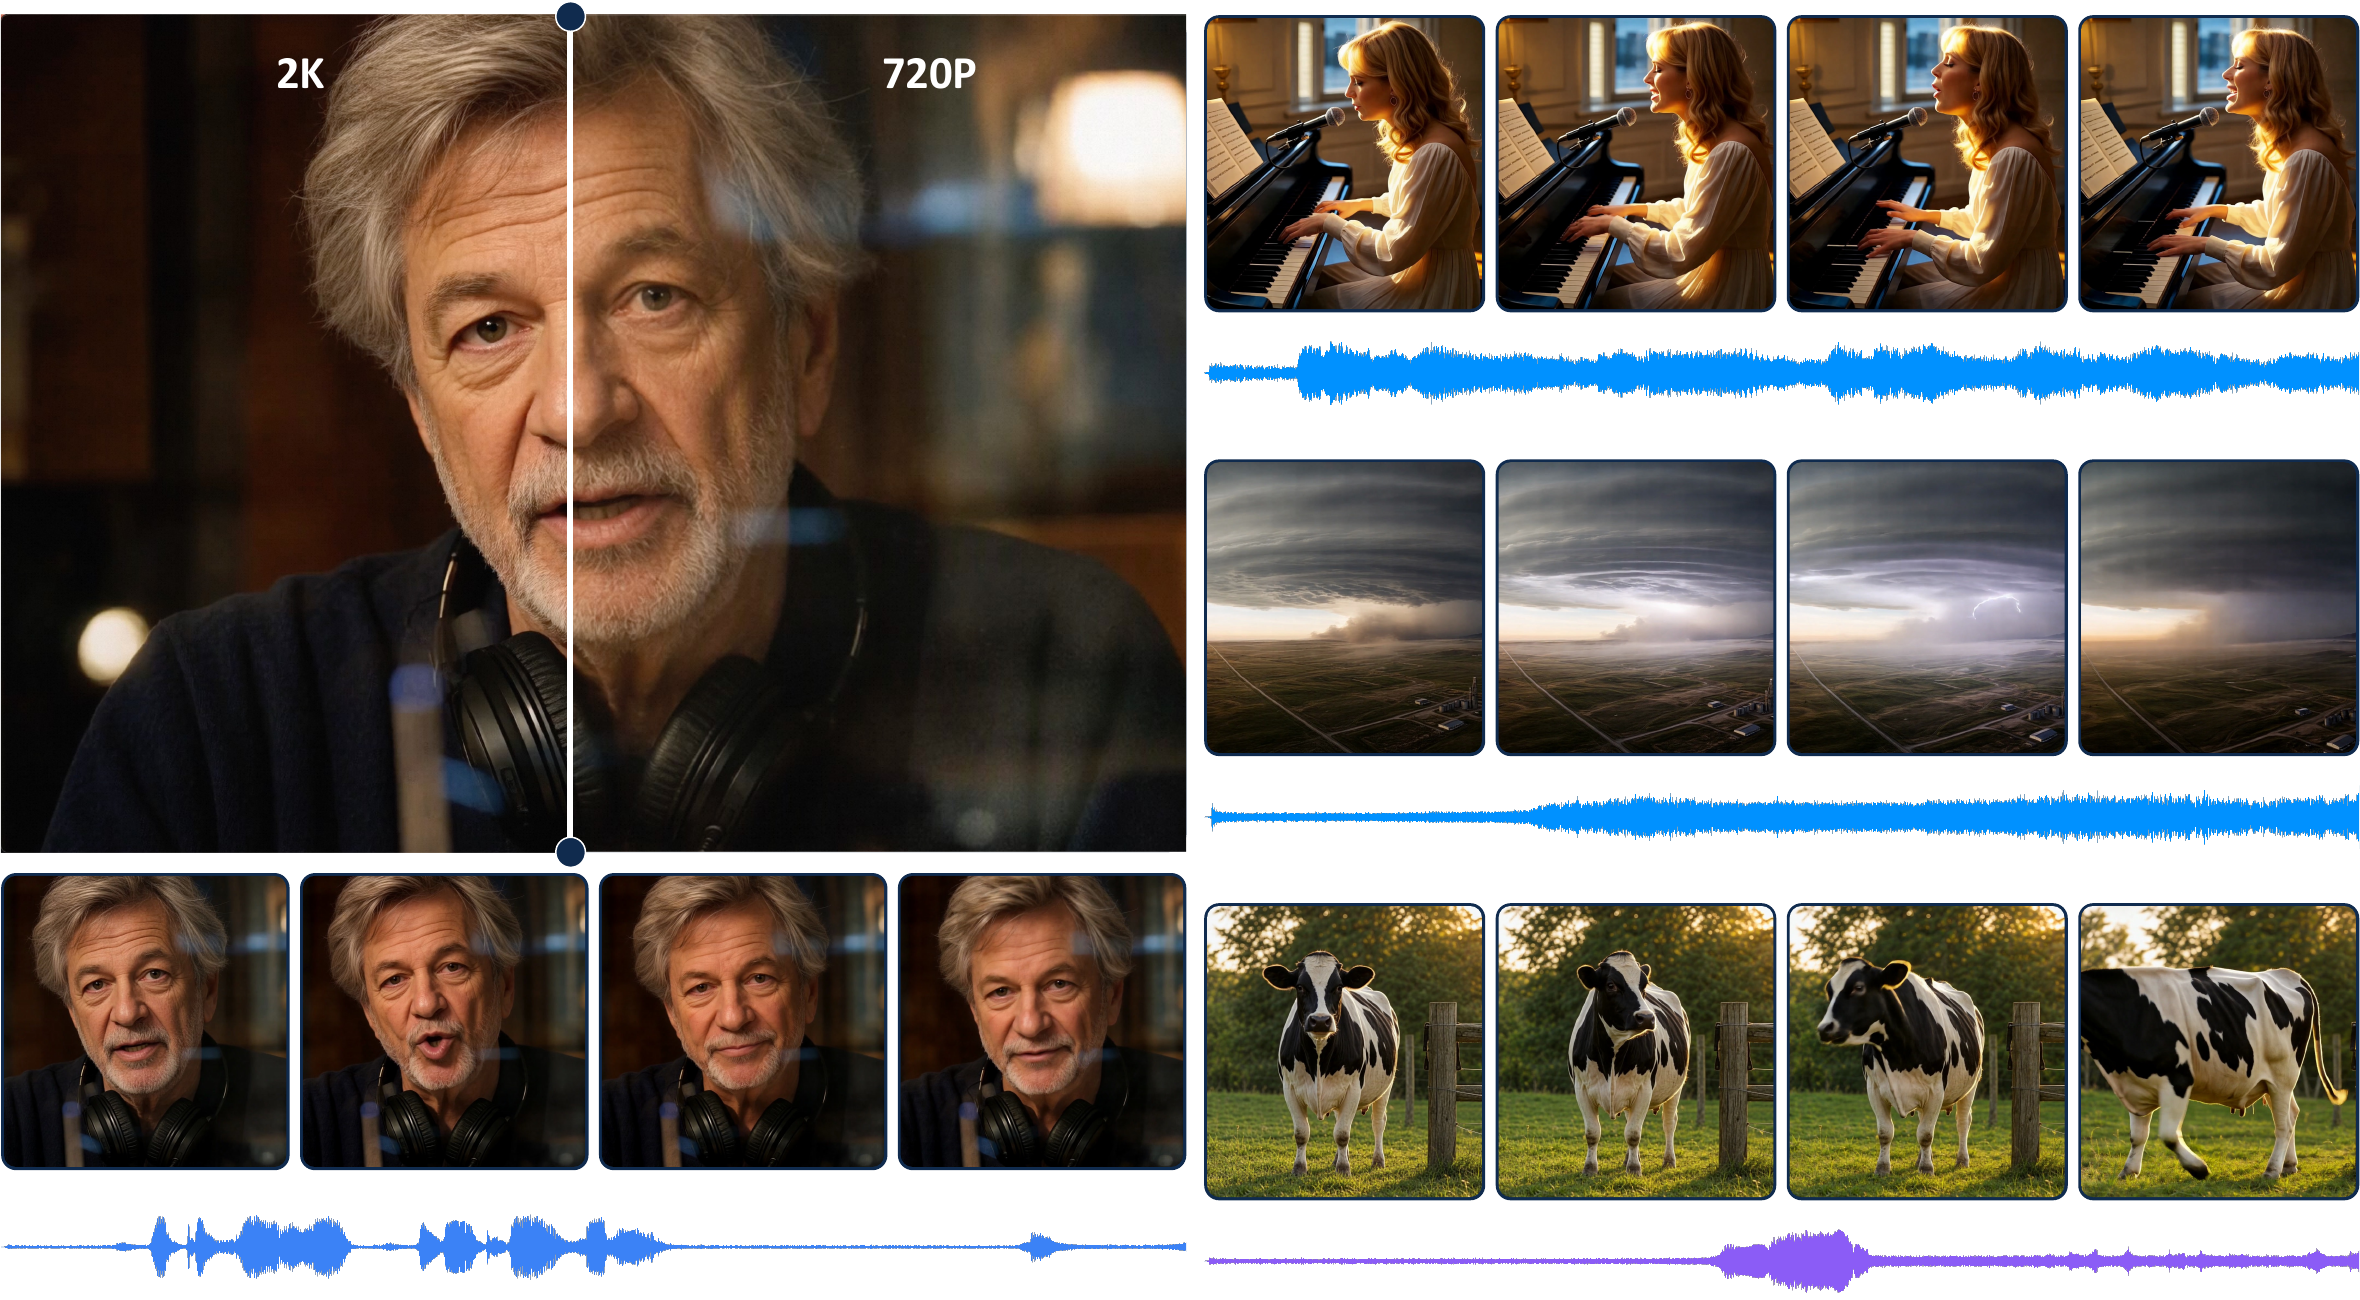
DreamX-Creator
313AMAP-ML/DreamX-Creator · PythonDreamX-Creator is an open-source research framework for native joint audio-video generation: it produces video and a synchronized audio track together, refined up to 2K resolution.
- 42

ComfyUI-YCNodes-MiniMax-H3
246yichengup/ComfyUI-YCNodes-MiniMax-H3 · PythonThis is a ComfyUI custom node pack built specifically for the MiniMax H3 video model, adding 6 nodes for second-pass conditioning, timed prompt control, attention-field constraints, dynamic CFG scheduling, low-noise detail refinement and tiled sampling.
- 43
MiniMax-H3-Cloud
240Sac-Y/MiniMax-H3-Cloud · JavaScriptMiniMax H3 Cloud is a Codex plugin that generates MiniMax H3 videos using cloud GPUs (currently via the YunCloud/CompShare platform), handling instance selection, launching, ComfyUI workflow submission, MP4 download, and automatic shutdown.
- 44

storycast
236ilkerzg/storycast · TypeScriptStorycast turns a topic you type into a narrated animated short film: pick a character, give it a topic, and it builds a script, keyframes, animated shots, narration, score, end card and subtitles end to end.
- 45
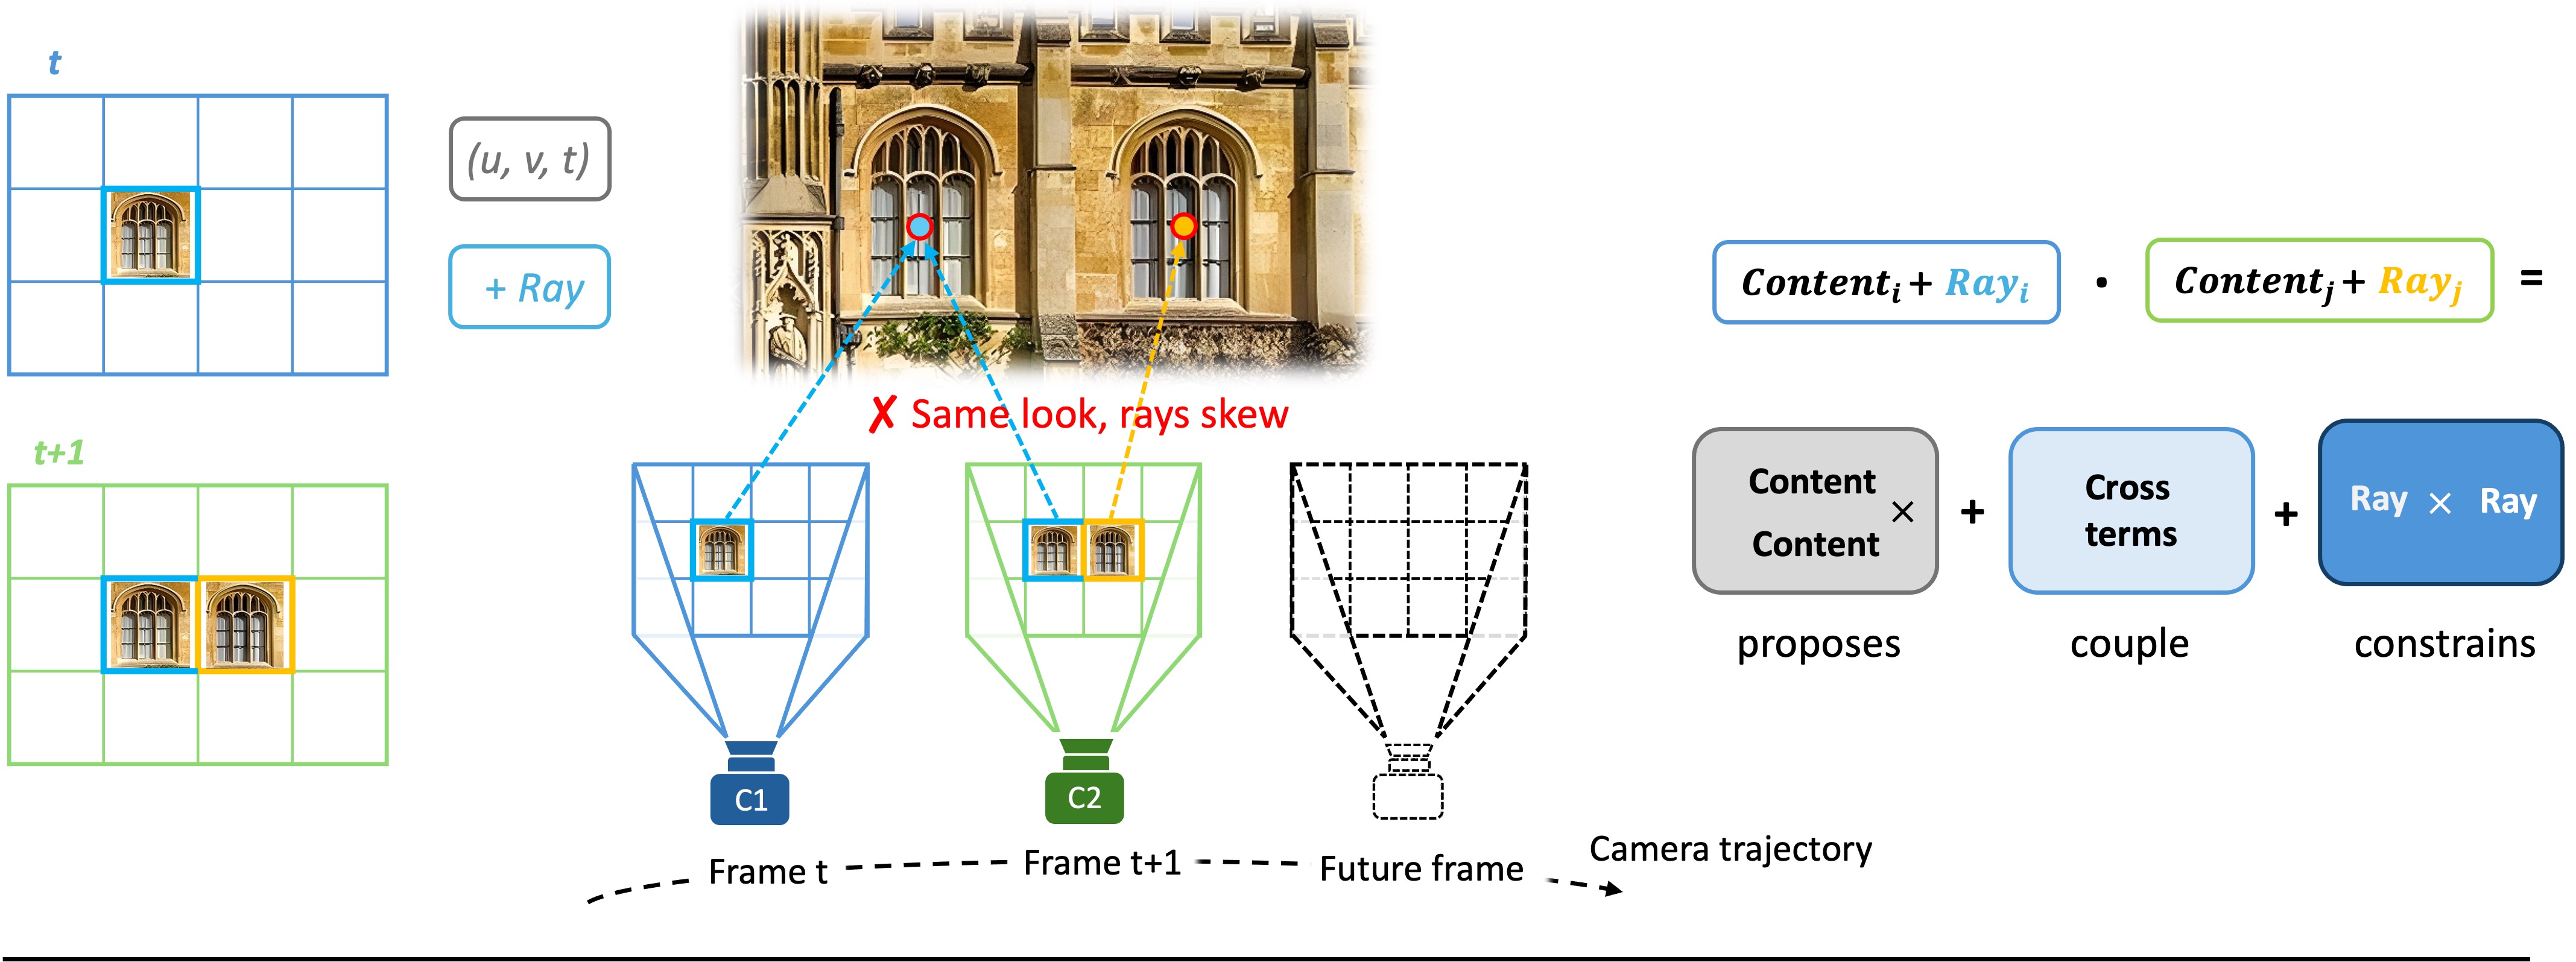
SCoPE
214TencentARC/SCoPE · PythonSCoPE is a research release that adds camera control to a pretrained video diffusion transformer (Wan2.2-I2V-A14B): given a first frame, a text prompt and a camera trajectory, it generates a video that follows the requested camera motion.
- 46
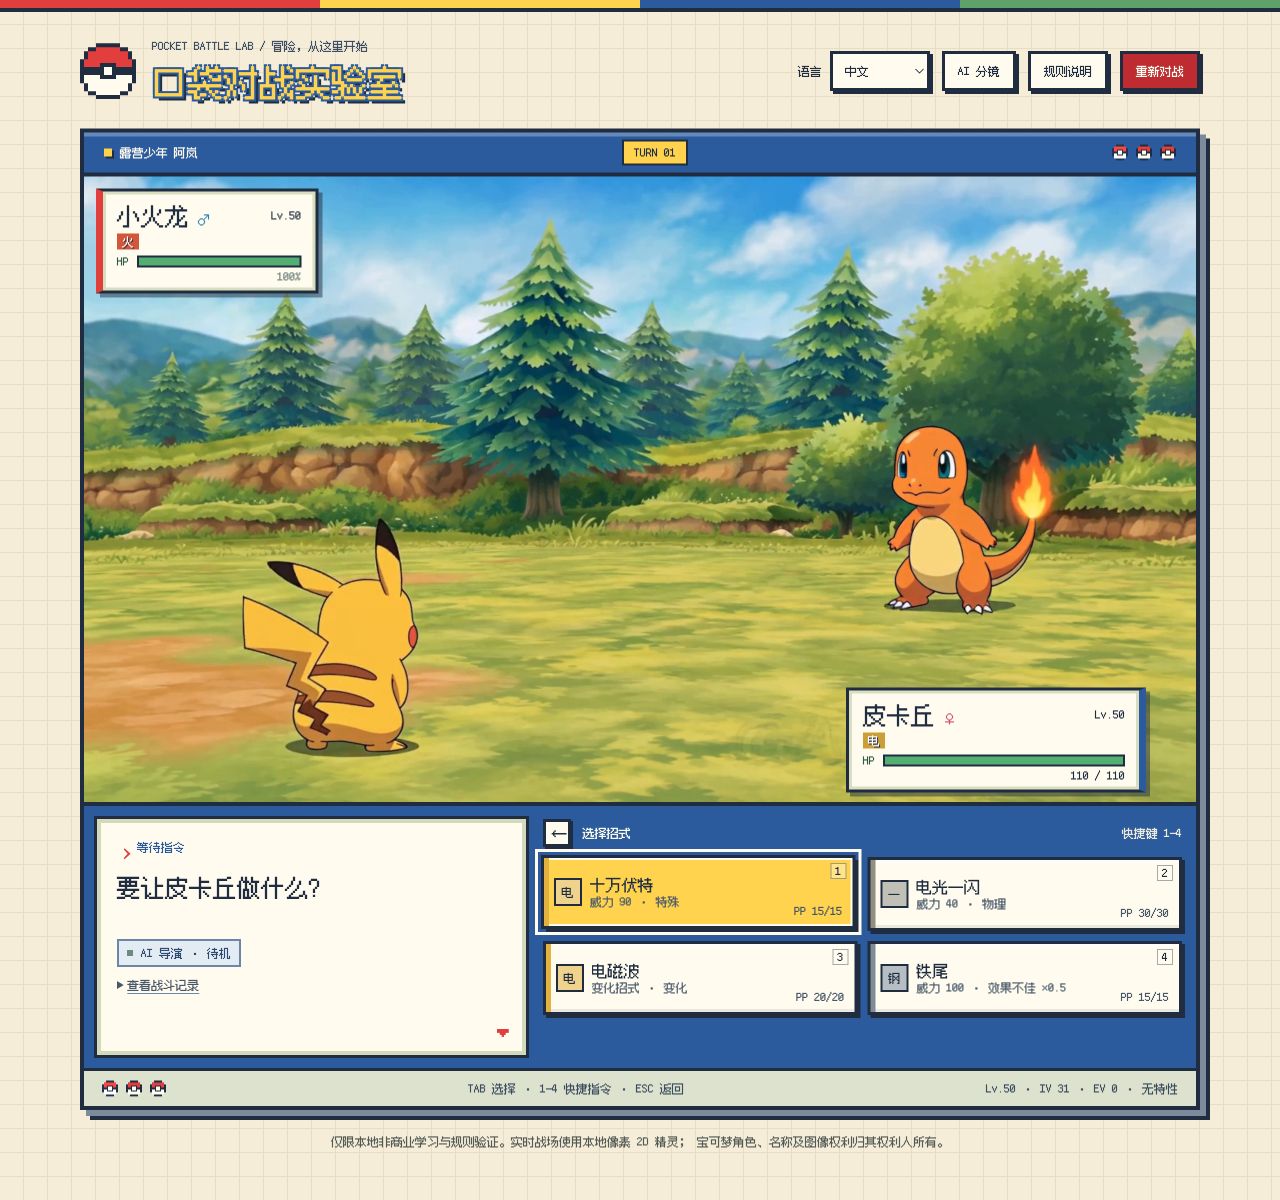
pokemonlive
156xflare-bot/pokemonlive · JavaScriptA local, non-commercial prototype where a pure JavaScript rules engine resolves turn-based Pokemon battles while AI generates a continuous anime-style 2D battle video on the fly.
Related topics
Often tagged together
- video-generation198
- python2,440
- generative-ai355
- ai2,001
- gpu816
- text-to-video65
- linux4,265
- open-source5,768
- deep-learning748
- cuda404
- diffusion-models83
- windows3,493
- pytorch422
- research783
- huggingface368
- macos3,624
- image-generation230
- apache-2.01,457
- inference331
- machine-learning931
- comfyui51
- multimodal191
- nvidia341
- ai-video46