Topics / #dataset
Dataset projects on GitHub
Curated datasets for machine learning and analysis
As of , the most-starred Dataset projects on GitHub are public-apis (490.2K stars), prompts.chat (173.6K stars) and ChinaTextbook (83.1K stars). GitHub.Locker tracks 125 Dataset repositories with 2.3M stars combined. The fastest-growing on October 18 was public-apis, with +375 stars in a day.
Hot right now
Most stars gained in a day · Oct 18
 +375
public-apis
public-apis/public-apis · ★ 490.2KA collective list of free APIs: a huge, manually curated catalog of public APIs for developers, maintained by the community for years. You do not call it — you browse the catalog and pick third-party APIs to use in your own product.
 +313
os-taxonomy
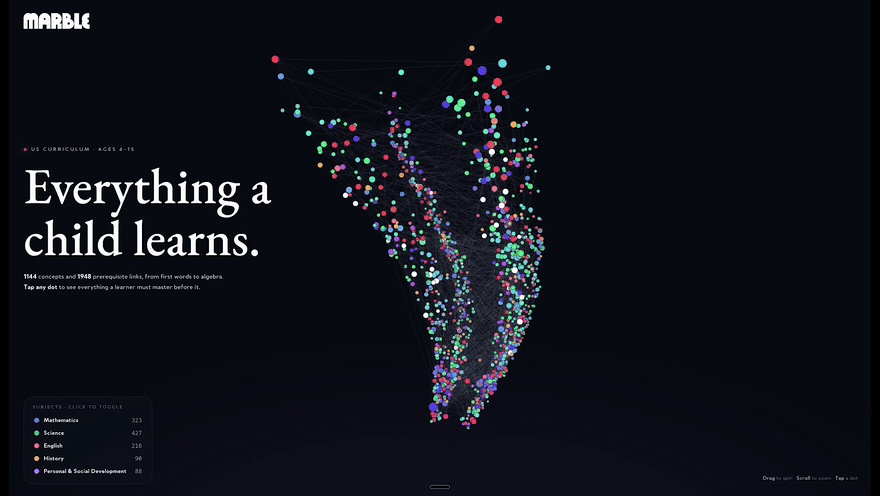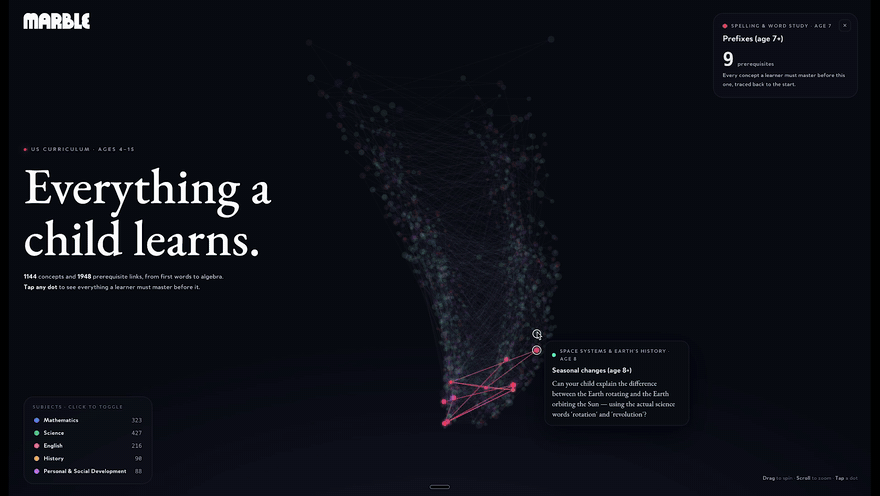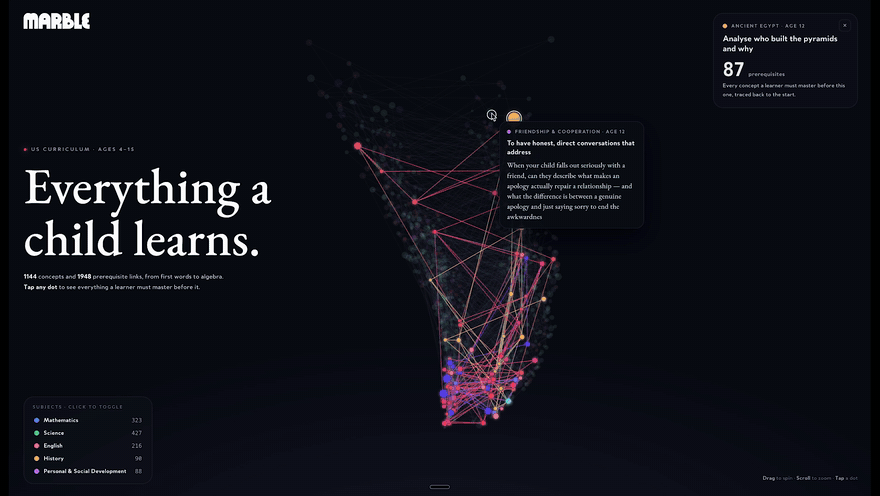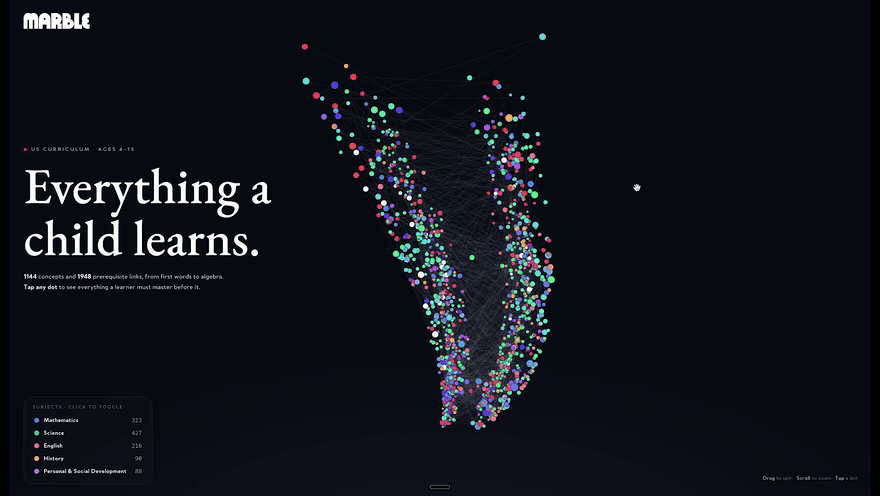
withmarbleapp/os-taxonomy · ★ 5.9KMarble Skill Taxonomy is an open dataset mapping what children learn in primary/elementary school, broken into 1,590 fine-grained micro-topics linked by a prerequisite graph and aligned to national curriculum standards like NGSS and Common Core.
 +222
awesome-chinese-secondhand-slang
Domainsun/awesome-chinese-secondhand-slang · ★ 368This is a curated Chinese-language glossary of secondhand marketplace slang (黑话) used on platforms like Xianyu (Goofish), Zhuanzhuan and Xiaohongshu, covering 4,000+ real-world code words with both buyer scam-avoidance tips and seller compliance-safe alternative phrasing.
 +209
prompts.chat
f/prompts.chat · ★ 173.6KA curated, open-source collection of prompts for AI chat models like ChatGPT, Claude, Gemini, and Llama, formerly known as Awesome ChatGPT Prompts.
The all-time top
Top 100 of 125 · by stars
- 490.2K#1 · public-apis/public-apis
public-apis
A collective list of free APIs: a huge, manually curated catalog of public APIs for developers, maintained by the community for years. You do not call it — you browse the catalog and pick third-party APIs to use in your own product.
- 173.6K#2 · f/prompts.chat
prompts.chat
A curated, open-source collection of prompts for AI chat models like ChatGPT, Claude, Gemini, and Llama, formerly known as Awesome ChatGPT Prompts.
- 83.1K
 #3 · TapXWorld/ChinaTextbook
ChinaTextbook
An open-source archive of PDF textbooks for Chinese primary school, middle school, high school and university courses, currently focused mainly on the full math curriculum from grade 1 through university.
- 4
funNLP
83Kfighting41love/funNLP · PythonA huge curated collection of Chinese NLP resources: corpora, lexicons, tools, datasets and courses. The README calls it 'The Most Powerful NLP-Weapon Arsenal' — nearly the most complete Chinese NLP resource library.
- 5

awesome-public-datasets
79.6Kawesomedata/awesome-public-datasetsA huge topic-centric list of high-quality open public datasets, organized by subject area like biology, chemistry, economics, and more.
- 6
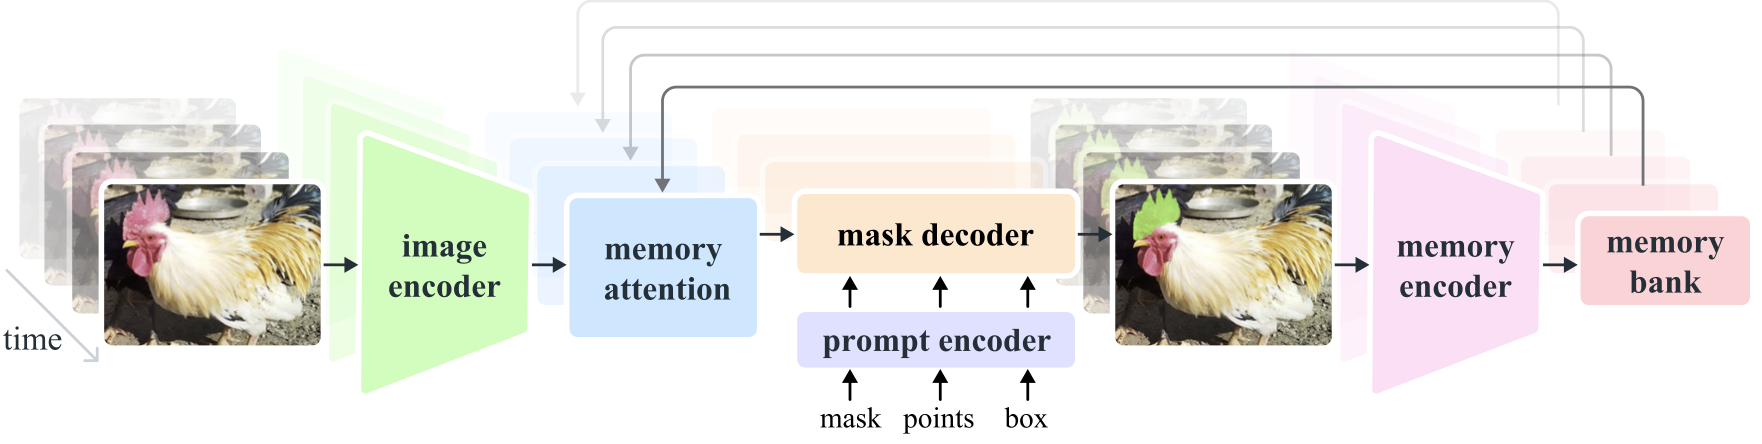
segment-anything
55Kfacebookresearch/segment-anything · Jupyter NotebookThis is Meta AI's Segment Anything Model (SAM), a foundation model that produces object masks for images from prompts like points or boxes, or automatically generates masks for every object in an image.
- 7
chinese-poetry
53.8Kchinese-poetry/chinese-poetry · JavaScriptThis is a massive open database of classical Chinese poetry, containing about 55,000 Tang poems, 260,000 Song poems, and 21,050 Song ci (lyric poems), along with other classical texts like the Analects and Book of Songs.
- 8

big-list-of-naughty-strings
47.7Kminimaxir/big-list-of-naughty-strings · PythonIt is a curated collection of strings with a high probability of breaking software when used as user input, meant to help QA testing of input validation.
- 9
google-research
39Kgoogle-research/google-research · Jupyter NotebookA giant monorepo where Google Research dumps the code released alongside its papers and projects - hundreds of independent folders covering different research efforts, not one cohesive product.
- 10
Open-Assistant
37.4KLAION-AI/Open-Assistant · PythonOpenAssistant was a community project to build a free, open chat-based assistant like ChatGPT, trained on crowdsourced instruction data and RLHF. The project has since wrapped up: the final 'oasst2' dataset is published on Hugging Face and the repo stands as a record of the effort.
- 11
storm
31.7Kstanford-oval/storm · PythonSTORM is an LLM-powered system that researches a topic on the Internet and writes a full-length Wikipedia-like report with citations. Co-STORM extends it with human-AI collaborative knowledge curation.
- 12
stanford_alpaca
30.2Ktatsu-lab/stanford_alpaca · PythonStanford's official Alpaca repo: code and docs for training an instruction-following LLaMA model and generating its 52K instruction dataset. In preliminary human evaluation the 7B model behaved similarly to text-davinci-003.
- 13

COVID-19
28.9KCSSEGISandData/COVID-19The COVID-19 data repository by Johns Hopkins University's Center for Systems Science and Engineering (CSSE) — the case data behind their widely used pandemic Visual Dashboard.
- 14

label-studio
28.5KHumanSignal/label-studio · TypeScriptLabel Studio is an open source data labeling and annotation tool: you label audio, text, images, videos, and time series in a browser UI and export the results in formats ready for ML training.
- 15
lerobot
28.3Khuggingface/lerobot · PythonLeRobot is Hugging Face's open-source project providing models, datasets, and tools for real-world robotics in PyTorch, aiming to lower the barrier to entry for building and deploying robot learning policies.
- 16
pytorch-CycleGAN-and-pix2pix
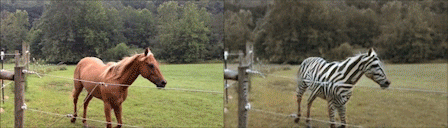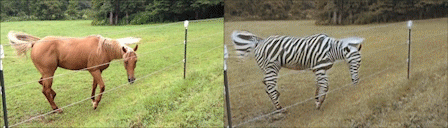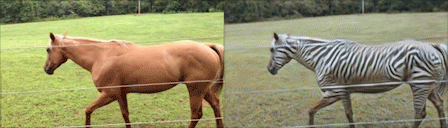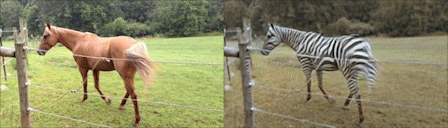
25.3Kjunyanz/pytorch-CycleGAN-and-pix2pix · PythonOpen-source PyTorch implementations of two classic image-to-image translation models: CycleGAN and pix2pix. They turn images from one domain into another, like horses into zebras or building label maps into photos.
- 17

gpt-2
25Kopenai/gpt-2 · PythonThis is OpenAI's official code and release for GPT-2, the language model described in the paper 'Language Models are Unsupervised Multitask Learners'. It bundles the model code with scripts to generate text samples from the released GPT-2 checkpoints.
- 18
pytorch_geometric
24.1Kpyg-team/pytorch_geometric · PythonPyG (PyTorch Geometric) is a Python library built on PyTorch for writing and training Graph Neural Networks (GNNs) on structured data — graphs and other irregular structures — using methods drawn from many published papers.
- 19
Awesome-Nano-Banana-images
23.9KPicoTrex/Awesome-Nano-Banana-imagesA curated gallery of fun, creative images generated with Nano Banana and Nano Banana Pro — Google's Gemini-2.5-flash-image based models — each paired with the prompt that produced it.
- 20

awesome-computer-vision
23.6Kjbhuang0604/awesome-computer-visionA curated list of resources for learning and working in computer vision, covering books, courses, papers, software, datasets, pre-trained models, tutorials and talks.
- 21
exercises-dataset
23.1Khasaneyldrm/exercises-dataset · HTMLA ready-to-use fitness exercise dataset with 1,324 exercises, each including an animation GIF, a 180x180 thumbnail, muscle-group and equipment metadata, and step-by-step instructions in 10 languages. It is the data layer that powers the LogPress workout-tracking app.
- 22
akshare
23Kakfamily/akshare · PythonAKShare is a free, open-source Python library that wraps a large set of financial data interfaces behind simple function calls - one line of code is enough to fetch a dataset.
- 23
NLP-progress
23Ksebastianruder/NLP-progress · PythonA curated, community-maintained document that tracks progress in Natural Language Processing: it lists the standard datasets and the current state-of-the-art results for most common NLP tasks across many languages.
- 24
Awesome-Chinese-LLM
22.8KAiHubCN/Awesome-Chinese-LLMA curated collection of open-source LLM resources for Chinese, focused on smaller models that can be privately deployed and trained cheaply. It lists 100+ resources: models, applications, datasets, and tutorials.
- 25

Administrative-divisions-of-China
21Kmodood/Administrative-divisions-of-China · JavaScriptChina's administrative divisions at five levels — provinces, cities, counties, towns and villages — each with its official statistics code and name, provided as JSON, CSV and SQLite files.
- 26
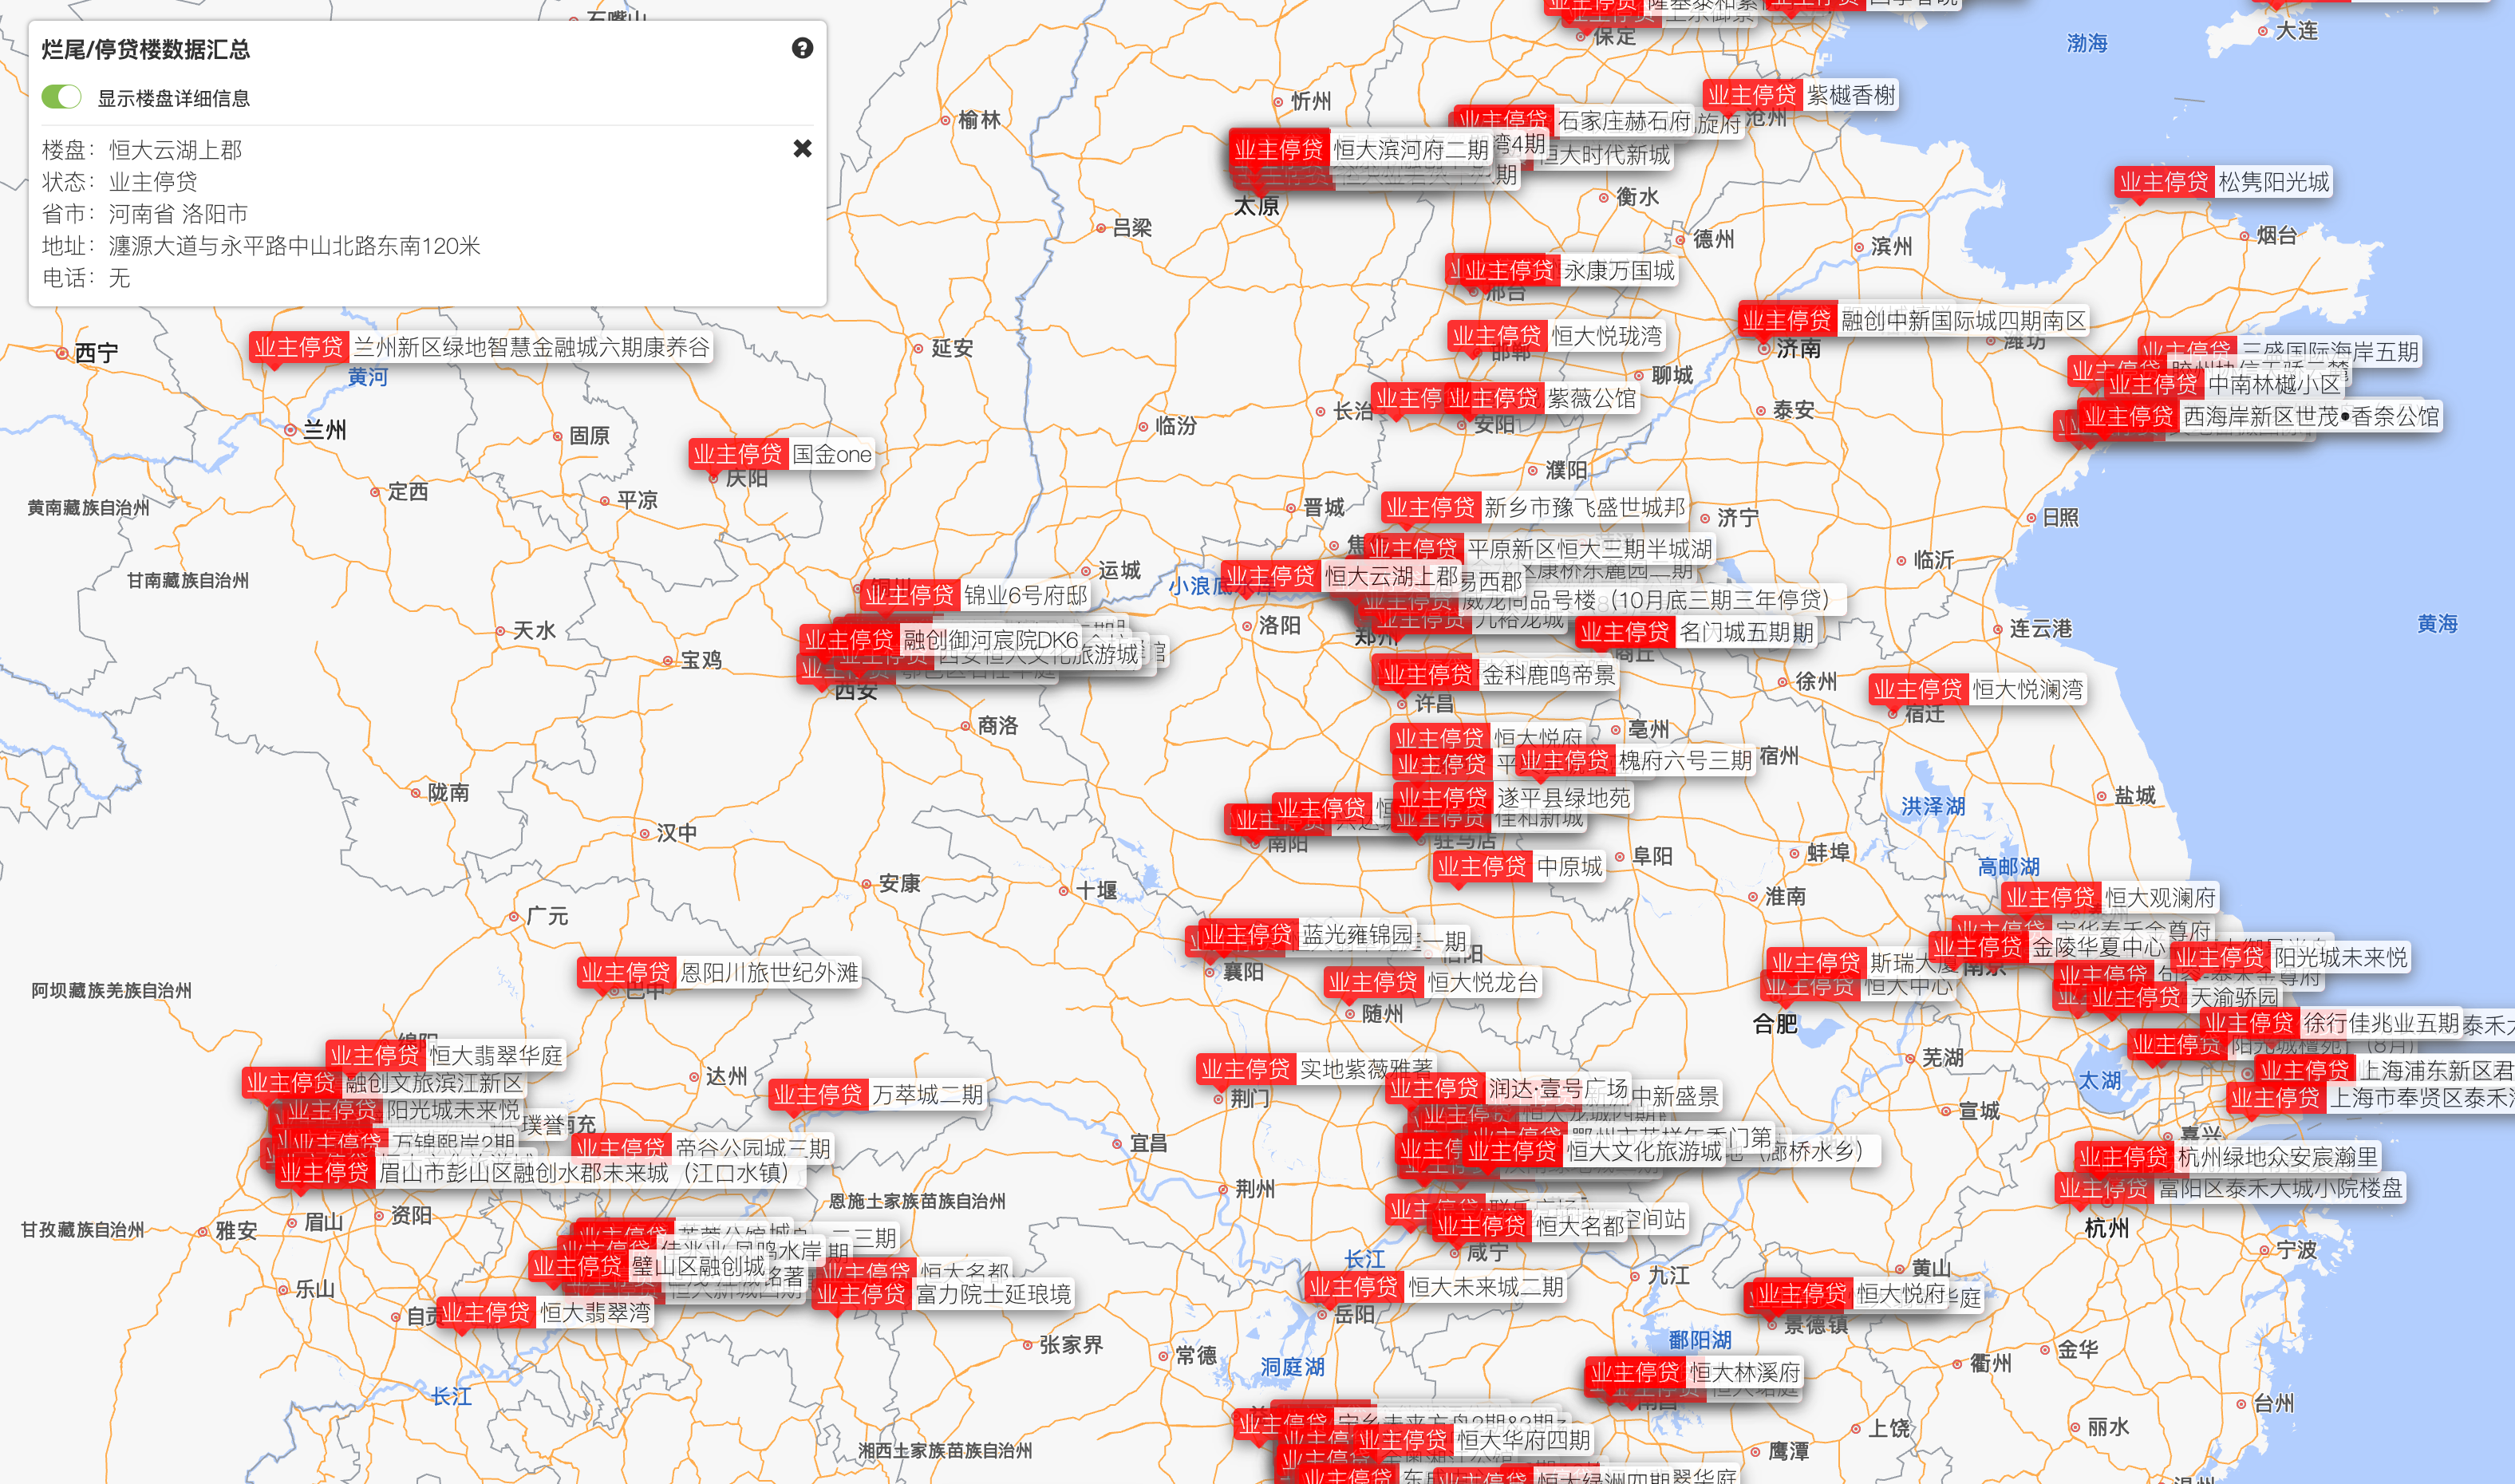
SummaryOfLoanSuspension
20.3KWeNeedHome/SummaryOfLoanSuspension · HTMLA community-run summary of mortgage-suspension notices from buyers of unfinished apartment projects across China — about 351 projects by 135 developers, organized by province, city and developer.
- 27

sam2
20Kfacebookresearch/sam2 · Jupyter NotebookSAM 2 (Segment Anything Model 2) is Meta's foundation model for promptable segmentation of objects in both images and videos, extending the original Segment Anything Model with a streaming memory architecture for real-time video tracking.
- 28
olmocr
19.8Kallenai/olmocr · PythonolmOCR is a toolkit that converts PDFs, PNGs, and JPEGs into clean Markdown or plain text with natural reading order, preserving equations, tables, and handwriting - built primarily to produce training datasets for LLMs.
- 29

faker
19.4Kjoke2k/faker · PythonFaker is a Python package that generates fake data for you — for bootstrapping a database, creating XML documents, stress-testing persistence layers, or anonymizing data taken from a production service.
- 30
pytorch-deep-learning
19.2Kmrdbourke/pytorch-deep-learning · Jupyter NotebookFree course materials for the Zero to Mastery Learn PyTorch for Deep Learning course — a hands-on, code-first introduction to deep learning. The author jokes it's the second best place to learn PyTorch on the internet, after the official docs.
- 31
awesome-nlp
19.1Kkeon/awesome-nlpA curated list of resources dedicated to Natural Language Processing — research hubs, tutorials, courses, books, libraries, datasets, and task methods, collected as links with one-line descriptions.
- 32

alpaca-lora
18.9Ktloen/alpaca-lora · Jupyter NotebookAlpaca-LoRA reproduces the Stanford Alpaca results by instruct-tuning LLaMA with low-rank adaptation (LoRA). It ships the training code, inference scripts, and the resulting LoRA weights, producing an Instruct model of similar quality to text-davinci-003.
- 33

vision
18Kpytorch/vision · PythonTorchvision is PyTorch's computer vision package: popular datasets, ready-made model architectures, and common image transformations for vision work.
- 34

data
17.5Kfivethirtyeight/data · Jupyter NotebookThis is the public repository of data sets and code behind the articles, graphics, and interactive features published by the journalism outlet FiveThirtyEight.
- 35
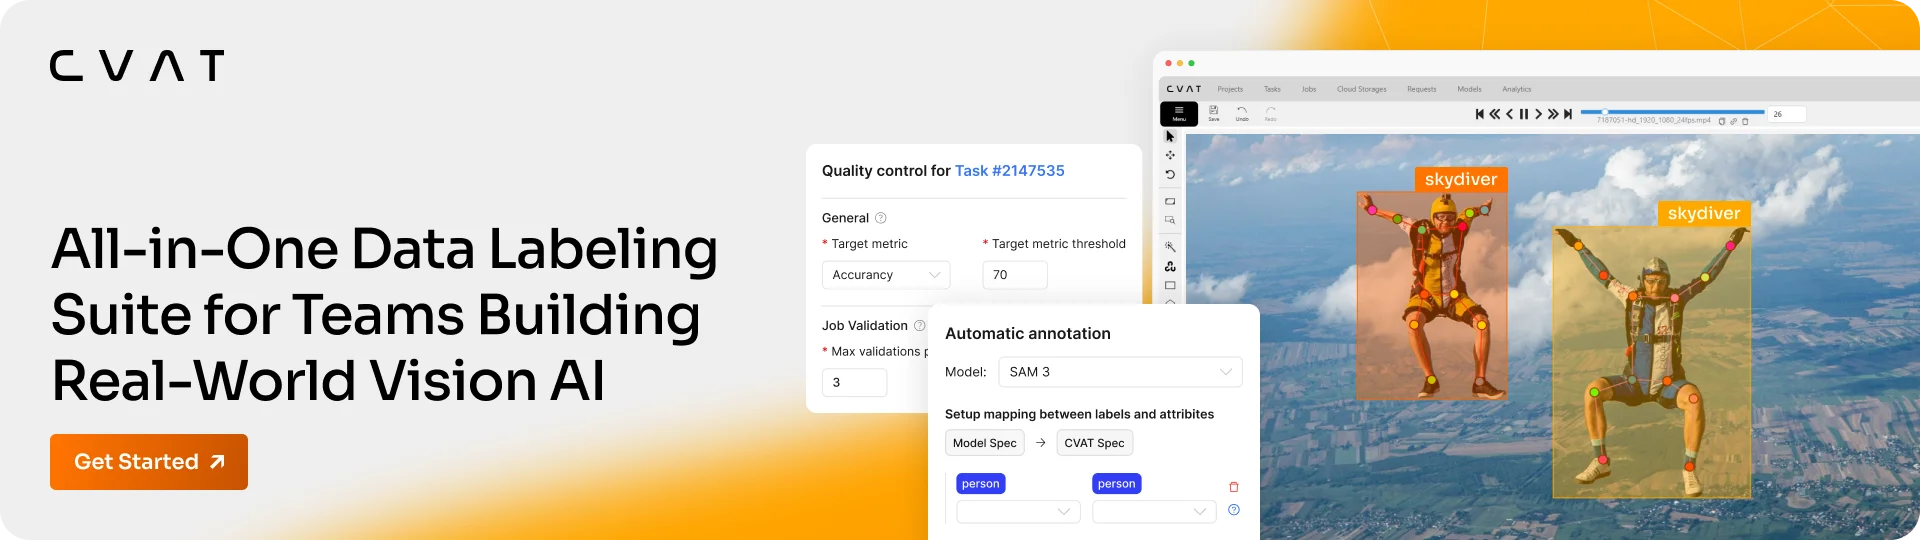
cvat
17Kcvat-ai/cvat · PythonCVAT is an open-source, self-hosted data annotation platform for building labeled datasets from images, video, and 3D point clouds, used for computer vision and visual AI projects.
- 36

LaTeX-OCR
16.6Klukas-blecher/LaTeX-OCR · PythonA learning-based OCR system: feed it an image of a math formula and it returns the matching LaTeX code.
- 37
Screenshot-to-code
16.5Kemilwallner/Screenshot-to-code · HTMLA neural network that turns a design mock-up image into the HTML markup of a static website — render that markup and you get the original design back.
- 38
AutoEq
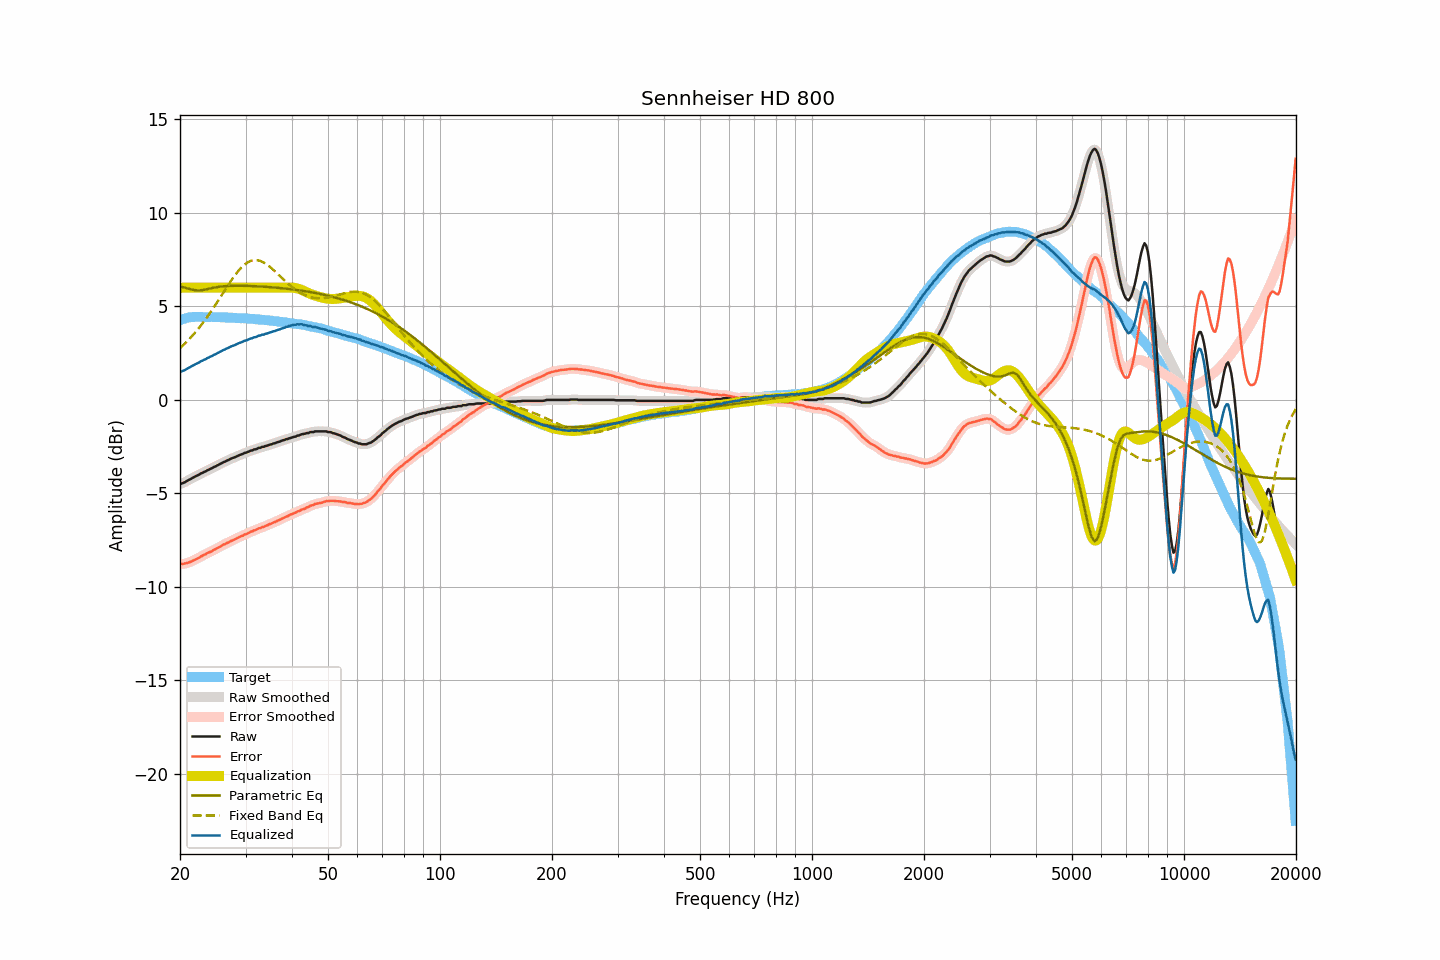
16.4Kjaakkopasanen/AutoEq · PythonAutoEq automatically generates headphone equalizer settings based on real frequency response measurements, so you can correct your headphones toward a target sound curve.
- 39

ChineseBQB
16.3Kzhaoolee/ChineseBQB · TypeScriptChineseBQB is a huge open collection of Chinese internet memes and sticker images (emoji packs), organized into themed folders covering pop culture, celebrities, games, anime, and historical internet memes, plus an online tool to search and share them.
- 40
labelme
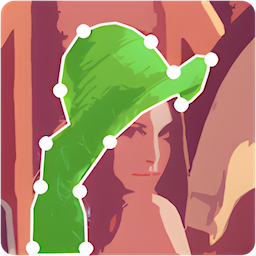
16.2Kwkentaro/labelme · PythonLabelme is a graphical image annotation tool written in Python: you draw polygons, rectangles, circles, lines and points on images to build labeled datasets for computer vision work.
- 41
ragas
16.1Kvibrantlabsai/ragas · PythonRagas is an open-source Python toolkit for evaluating and optimizing LLM applications: objective metrics, automatic test-set generation and data-driven insights replace slow, subjective manual assessment.
- 42

dvc
15.9Ktreeverse/dvc · PythonDVC (Data Version Control) is an open-source tool for versioning data and tracking ML experiments; its own citation tagline calls it 'Git for Data & Models'.
- 43
gpt-3
15.7Kopenai/gpt-3The official companion repo for the GPT-3 paper 'Language Models are Few-Shot Learners'. GPT-3 is an autoregressive language model with 175 billion parameters — 10x more than any previous non-sparse model — tested on few-shot learning across many NLP tasks.
- 44
math
15.2Kopenai/math · LeanA public catalogue of 719 mathematical manuscripts grouped into 372 families, written by an internal OpenAI model during evaluations on open research problems. About 42% of top-line results already have Lean formalizations.
- 45
easy-dataset
15KConardLi/easy-dataset · JavaScriptEasy Dataset is an app that turns domain documents (PDF, Markdown, DOCX, TXT, EPUB) into structured datasets for LLM fine-tuning, RAG, and model evaluation. It extracts questions from your text, generates answers with an LLM, and exports ready-to-use training data.
- 46

leaked-system-prompts
15Kjujumilk3/leaked-system-promptsA collection of leaked system prompts from widely used LLM-based services, gathered as individual documents in one repository.
- 47
alphafold
14.9Kgoogle-deepmind/alphafold · PythonAlphaFold is Google DeepMind's open source implementation of the AlphaFold v2 inference pipeline, which predicts 3D protein structures from amino acid sequences, plus a work-in-progress AlphaFold-Multimer model for protein complexes.
- 48

nltk
14.7Knltk/nltk · PythonNLTK is a suite of open source Python modules, bundled data sets, and tutorials supporting research and development in Natural Language Processing.
- 49
transferlearning
14.4Kjindongwang/transferlearning · PythonA curated knowledge base covering transfer learning, domain adaptation, domain generalization and related subfields - papers, tutorials, code, datasets, scholars and surveys, maintained in both English and Chinese.
- 50

facenet
14.4Kdavidsandberg/facenet · PythonThis is a TensorFlow implementation of FaceNet, a face recognition system that converts face images into 128-dimensional embeddings for recognition and clustering, based on the paper 'FaceNet: A Unified Embedding for Face Recognition and Clustering'.
- 51

zhao
14.1Kprogramthink/zhao · PythonA dataset documenting China's 'Princeling Party' (太子党) — the family and business networks of the country's political elite — compiled to expose corruption and nepotism among Chinese officials.
- 52

pandas_exercises
13.2Kguipsamora/pandas_exercises · Jupyter NotebookA collection of exercises for practicing pandas, the Python data analysis library, organized by topic like filtering, grouping, merging, and visualization.
- 53
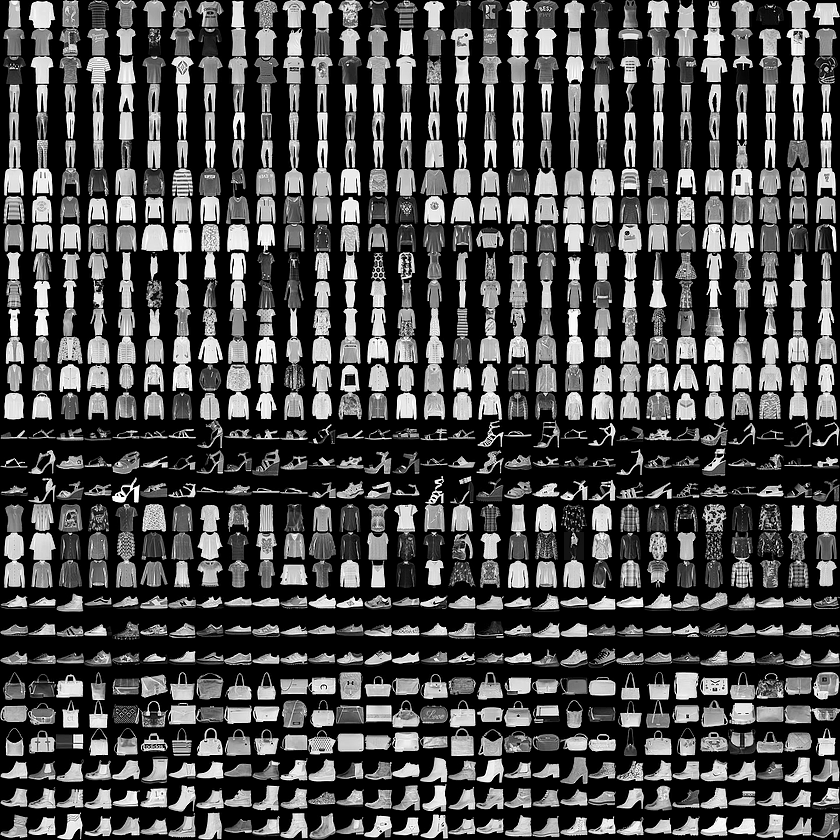
fashion-mnist
12.9Kzalandoresearch/fashion-mnist · PythonA dataset of Zalando's article images for benchmarking machine learning algorithms: 60,000 training and 10,000 test examples, each a 28x28 grayscale image with a label from 10 classes. It is meant as a direct drop-in replacement for the original MNIST.
- 54
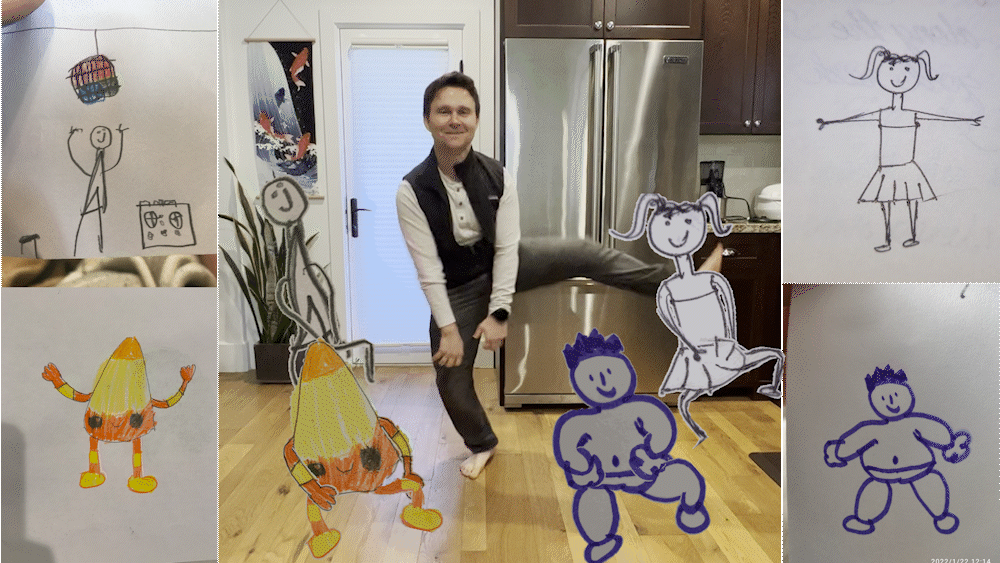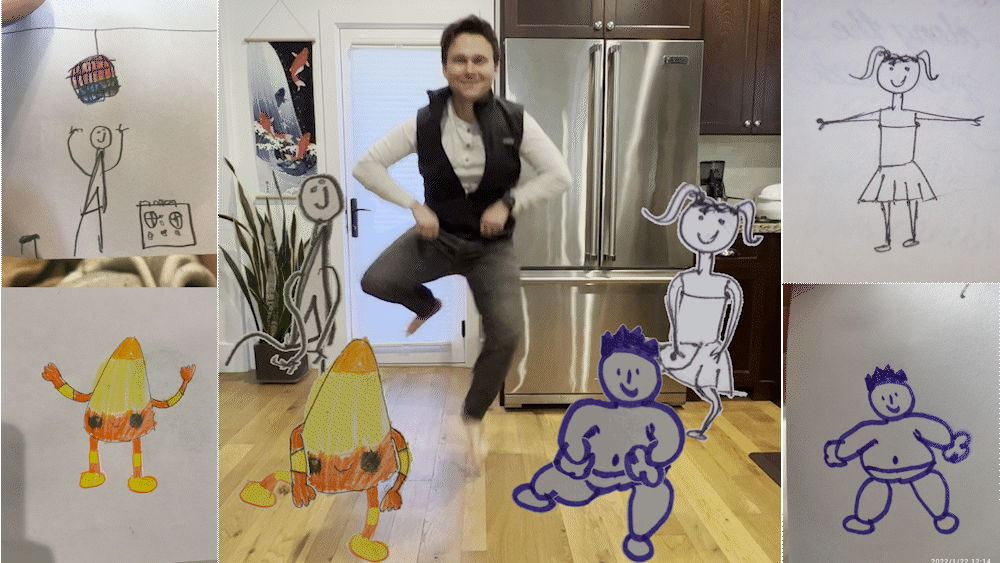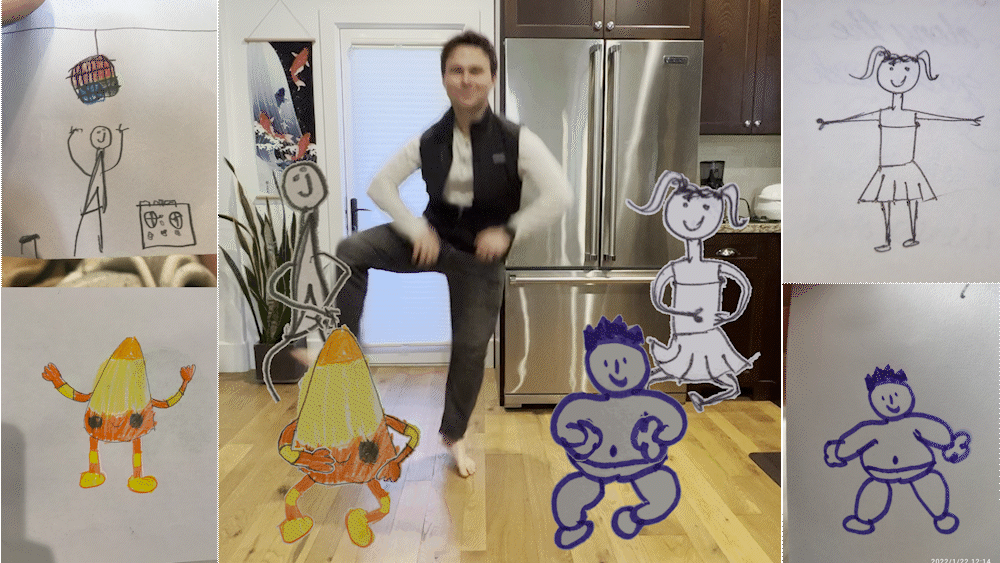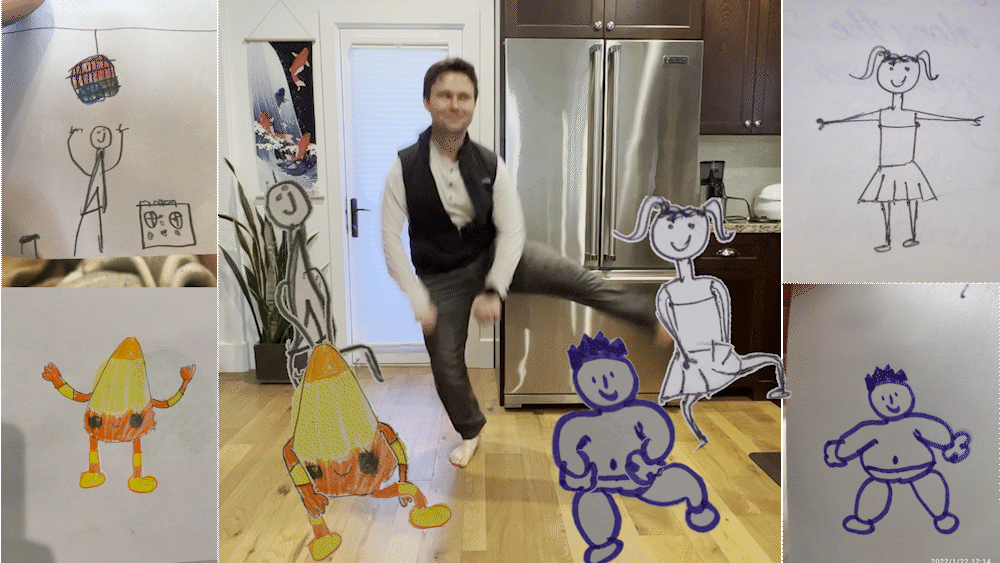
AnimatedDrawings
12.8Kfacebookresearch/AnimatedDrawings · PythonThis is Facebook Research's code for the paper 'A Method for Animating Children's Drawings of the Human Figure' — it takes a drawing of a human-like character and animates it using motion capture data.
- 55
nsfw_data_scraper
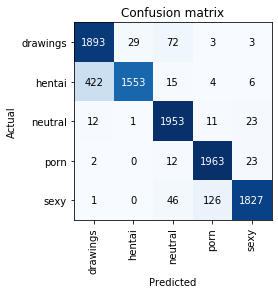
12.6Kalex000kim/nsfw_data_scraper · ShellThis is a collection of shell scripts that scrapes and aggregates tens of thousands of images across 5 categories (porn, hentai, sexy, neutral, drawings) to build a labeled dataset for training an NSFW image classifier.
- 56

Github-Ranking
12.5KEvanLi/Github-Ranking · PythonGithub-Ranking is a repository that tracks and lists the most-starred and most-forked repositories on GitHub, with both an overall Top 100 and per-language Top 100 breakdowns.
- 57

english-words
12.3Kdwyl/english-words · PythonA text file of English words — over 466k per the README, 479k in the repo description — published for dictionary and word-based projects such as auto-complete and autosuggestion.
- 58

Chinese-Word-Vectors
12.2KEmbedding/Chinese-Word-Vectors · PythonA collection of 100+ pre-trained Chinese word vectors (embeddings) trained with different representations, context features and corpora, plus the CA8 analogy dataset and an evaluation toolkit.
- 59
bisheng
12.1Kdataelement/bisheng · PythonBISHENG is an open-source LLM application devops platform built for enterprise AI, covering GenAI workflow building, RAG, agents, model management, evaluation, SFT, dataset management and observability.
- 60
sam3
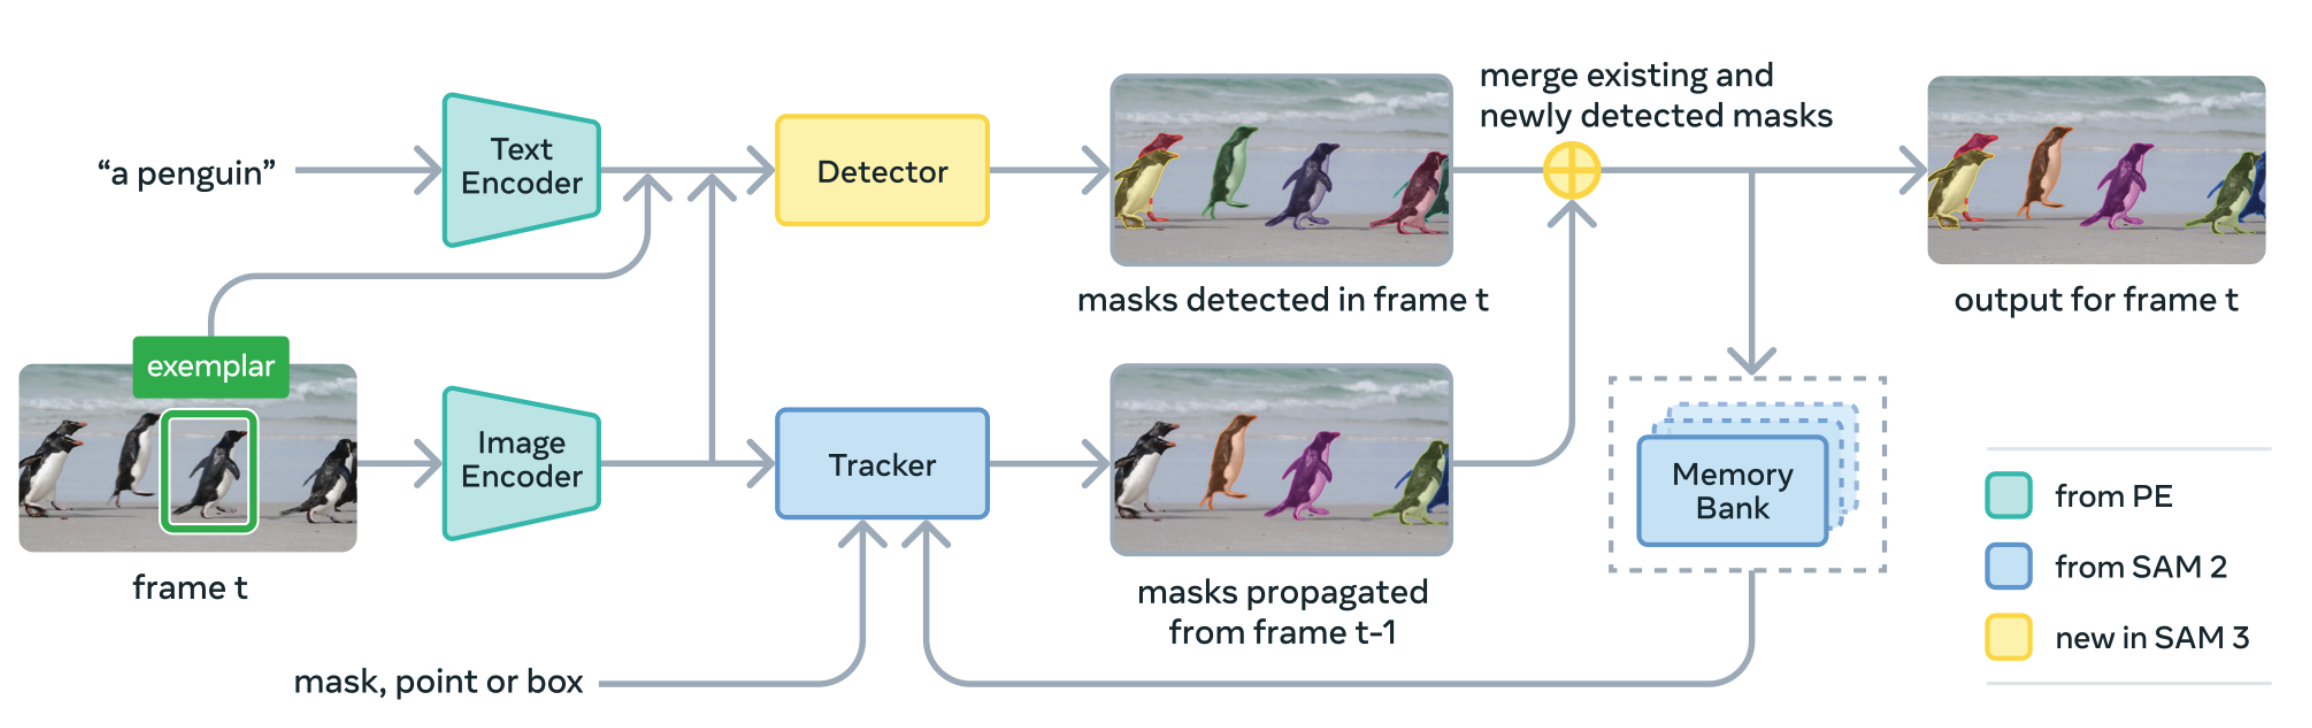
12Kfacebookresearch/sam3 · PythonSAM 3 is Meta's unified foundation model for promptable segmentation in images and videos. It can detect, segment, and track objects using text prompts or visual prompts like points, boxes, and masks.
- 61

seamless_communication
11.9Kfacebookresearch/seamless_communication · Jupyter NotebookSeamless Communication is Meta's family of foundational AI models for speech and text translation across roughly 100 languages, covering speech-to-speech, speech-to-text, text-to-speech and text-to-text translation plus automatic speech recognition.
- 62

chinese-xinhua
11.7Kpwxcoo/chinese-xinhua · PythonA Chinese Xinhua Dictionary database (中华新华字典数据库): four JSON datasets with 31,648 idioms, 264,434 words, 16,142 characters and 14,032 xiehouyu (two-part allegorical sayings), collected from the web.
- 63
arc-task-gen
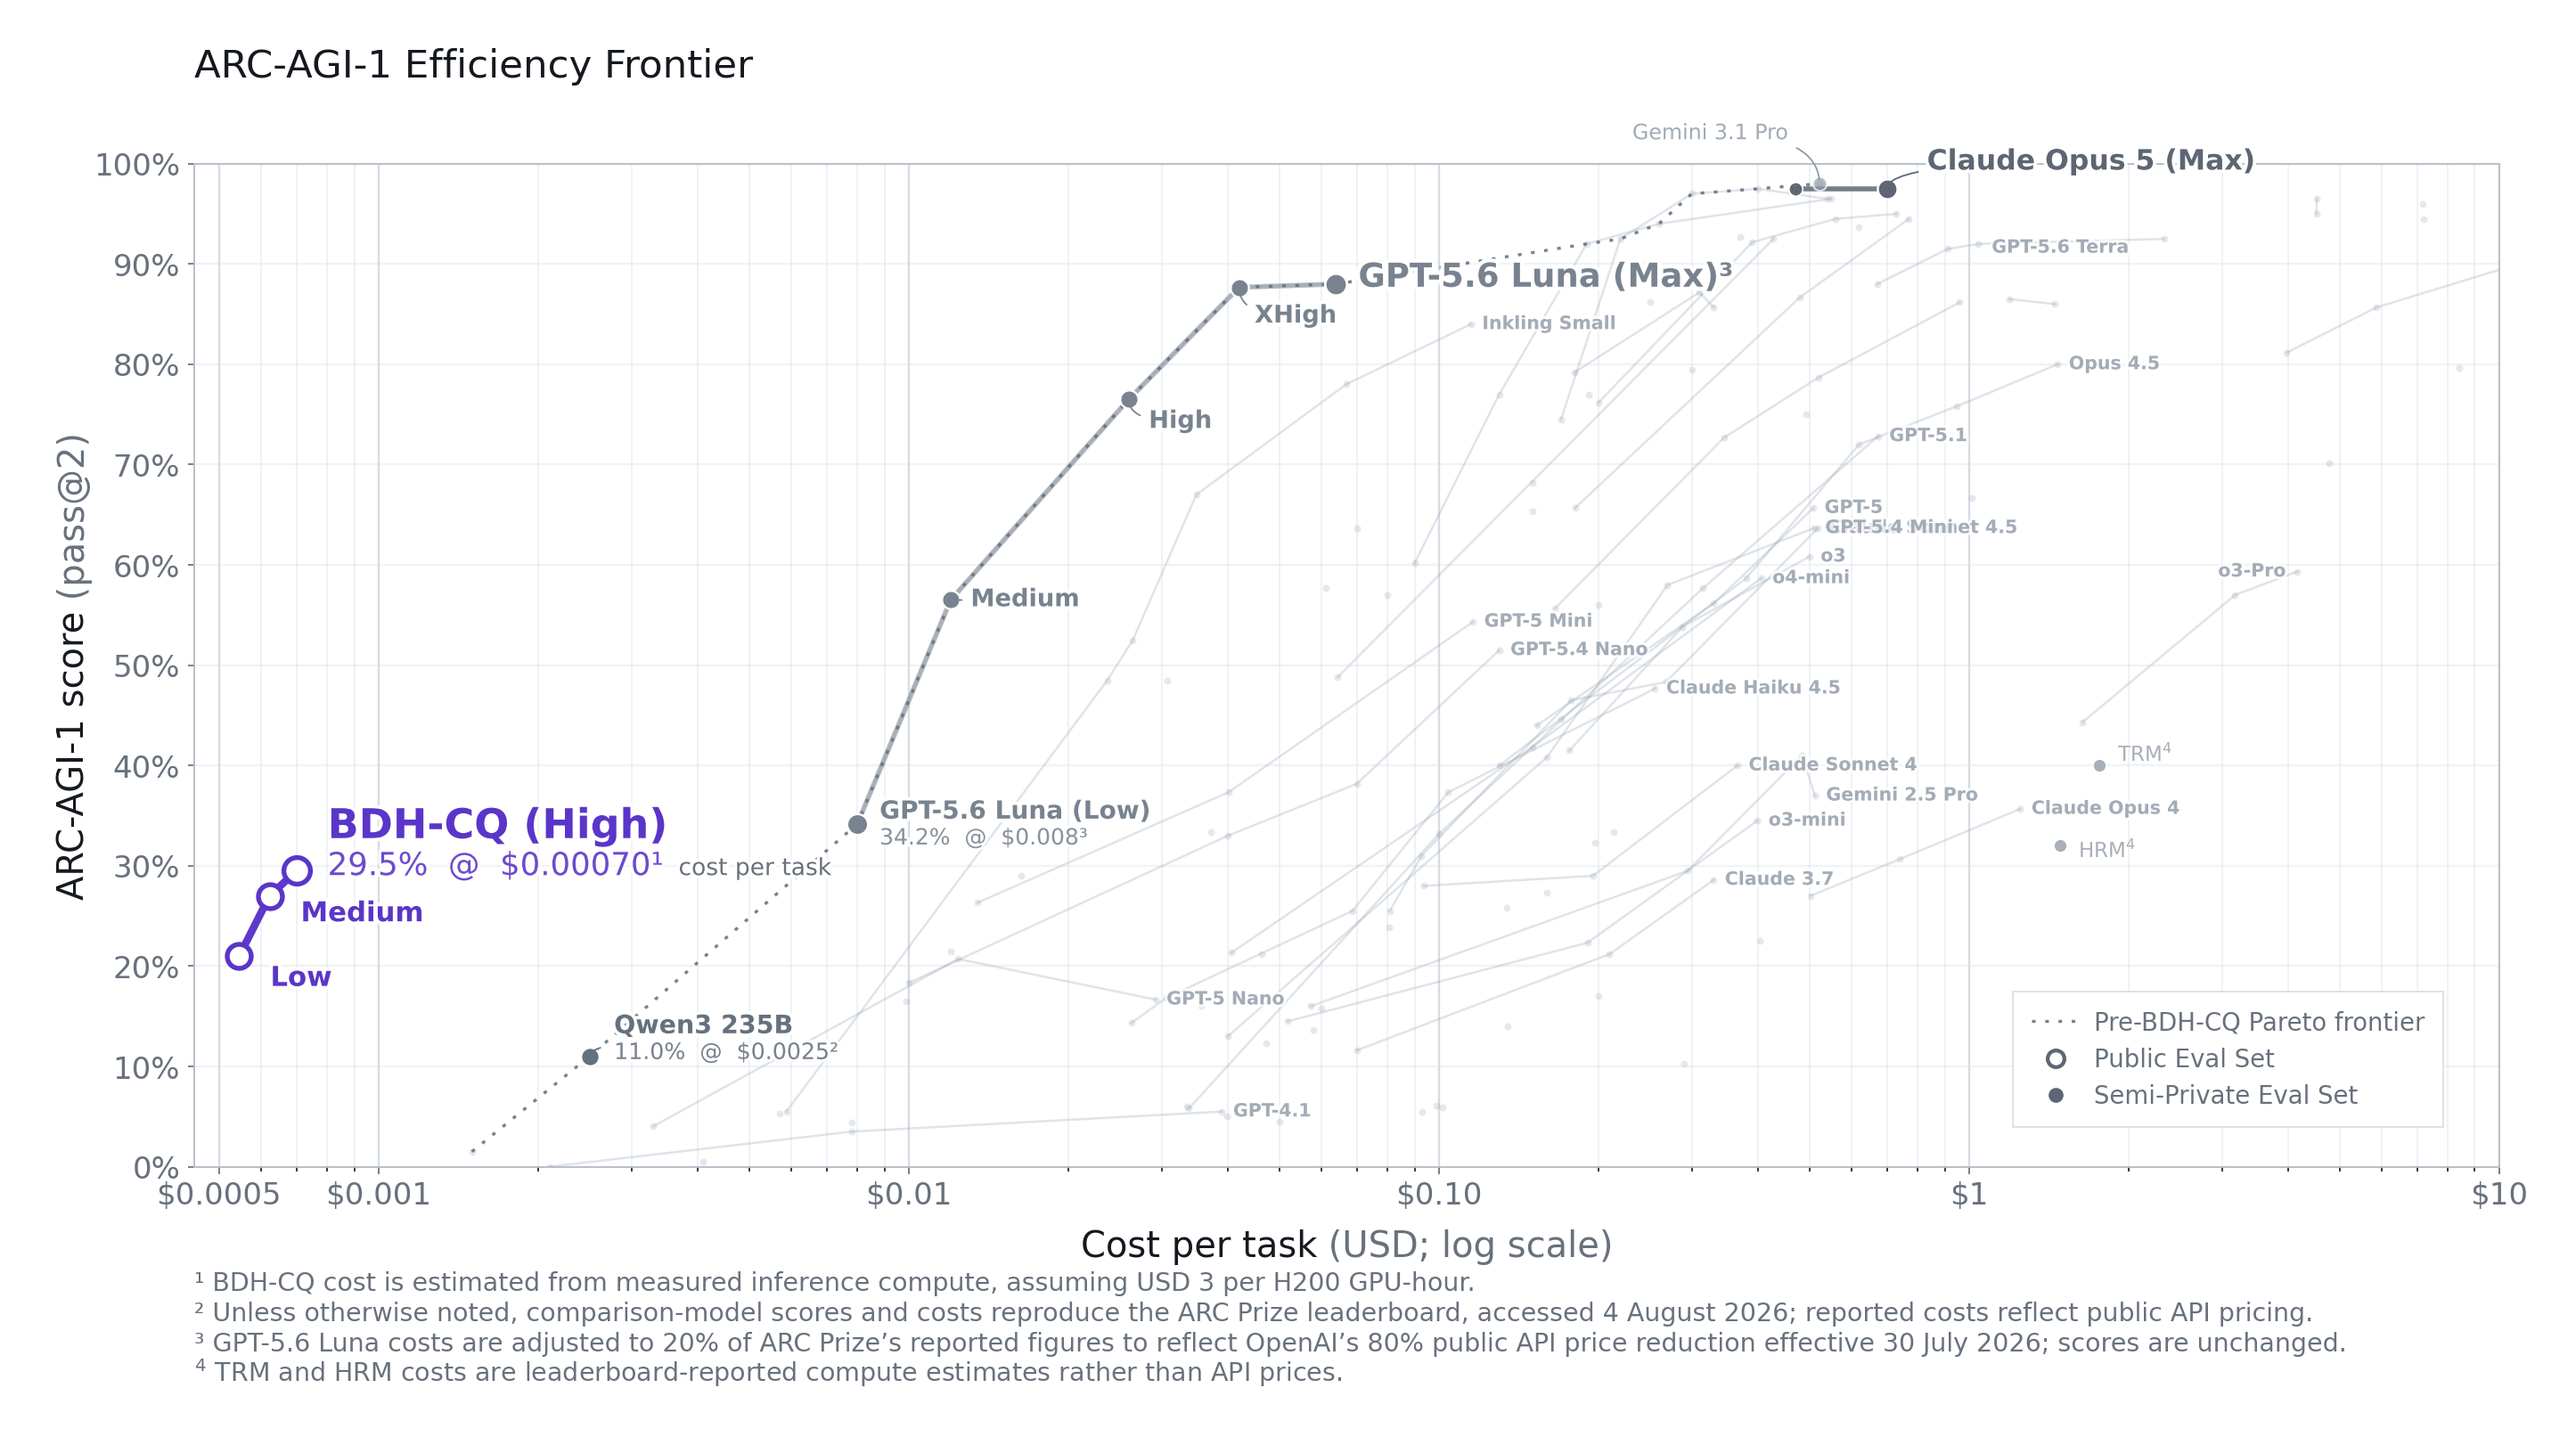
11Kpathwaycom/arc-task-gen · PythonA generator for fresh, original ARC-AGI-1-style puzzle tasks whose statistical distribution matches the public ARC-AGI-1 evaluation set, so models can be tested on problems they haven't seen before.
- 64

dolly
10.8Kdatabrickslabs/dolly · PythonDolly is Databricks' instruction-following large language model, trained on the Databricks Machine Learning Platform and licensed for commercial use; the flagship dolly-v2-12b derives from EleutherAI's Pythia-12b.
- 65
doccano
10.8Kdoccano/doccano · PythonDoccano is an open-source text annotation tool that lets humans label data for machine learning tasks like text classification, sequence labeling, and sequence-to-sequence problems such as summarization or translation.
- 66
ParlAI
10.6Kfacebookresearch/ParlAI · PythonParlAI is a Python framework from Facebook (Meta) AI Research for sharing, training, and evaluating dialogue AI models, covering everything from open-domain chitchat to task-oriented dialogue and visual question answering, with over 100 datasets available through one unified API.
- 67
Amphion
10.3Kopen-mmlab/Amphion · PythonAn open-source toolkit for audio, music, and speech generation. It is built to support reproducible research and help junior researchers and engineers get started in the field.
- 68

techniques
10.3Ksatellite-image-deep-learning/techniquesA curated list of techniques for deep learning with satellite and aerial imagery, covering architectures, models and algorithms for tasks like classification, segmentation and object detection.
- 69

3D-Machine-Learning
10.2Ktimzhang642/3D-Machine-LearningA curated knowledge base for 3D machine learning that collects courses, datasets, and research papers covering 3D representations like point clouds, meshes, voxels and primitives.
- 70

TTS
10.2Kmozilla/TTS · Jupyter NotebookAn open-source deep learning library for text-to-speech: pretrained models, vocoders, a speaker encoder and dataset tools, already used in 20+ languages for products and research.
- 71

lx-music-source
10Kpdone/lx-music-source · JavaScriptThis repo is a curated collection of music source links (and their sync servers) for the LX Music (洛雪音乐) player, scraped from various community sources.
- 72
iptv
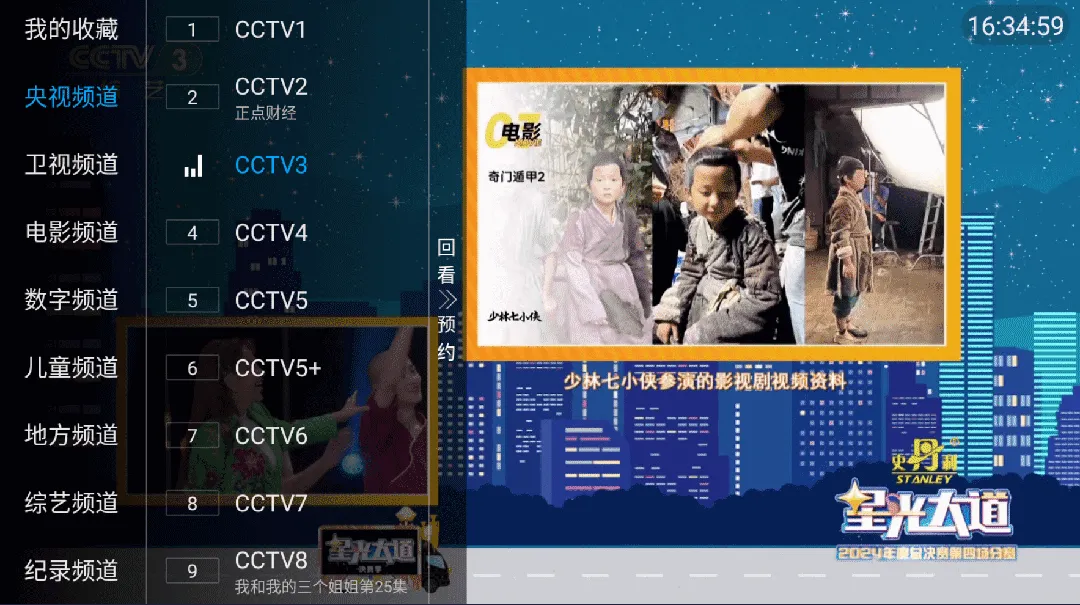
9.7Kvbskycn/iptv · HTMLThis is a repository that automatically collects and verifies free IPTV live-streaming source lists (channel URLs) for Chinese TV, updated every 6 hours.
- 73

espectre
9.6Kfrancescopace/espectre · PythonESPectre turns a supported ESP32 into a private, local Wi-Fi motion sensor: it reads how movement changes the Wi-Fi signals in a room and reports motion in real time — no camera, microphone, wearable, or dedicated radar hardware needed.
- 74

DeepSpec
7.2Kdeepseek-ai/DeepSpec · PythonDeepSpec is DeepSeek's full-stack Python codebase for training and evaluating draft models for speculative decoding — the technique where a small draft model accelerates a larger target LLM.
- 75

dmca
6.4Kgithub/dmca · DIGITAL Command LanguageThis is GitHub's public archive of DMCA takedown notices and counter-notices it has received, posted largely as-is to document their potential effect on online speech.
- 76
SWE-bench
6.1KSWE-bench/SWE-bench · PythonSWE-bench is a benchmark that tests large language models on real GitHub issues: the model gets a codebase plus an issue and must produce a patch that resolves it. An automated harness scores the patches.
- 77
os-taxonomy
5.9Kwithmarbleapp/os-taxonomy · JavaScriptMarble Skill Taxonomy is an open dataset mapping what children learn in primary/elementary school, broken into 1,590 fine-grained micro-topics linked by a prerequisite graph and aligned to national curriculum standards like NGSS and Common Core.
- 78

ziwei-doushu
5.2KRenhuai123/ziwei-doushu · TypeScriptAn open-source Zi Wei Dou Shu (紫微斗数, 'Purple Star Astrology') chart-calculation engine built on master Ni Haixia's (倪海夏) 'Tianji' teaching system. It ships the full chart algorithm, the Four Transformations (四化) system, a pattern knowledge base, digitized classical texts, and a 518,400-sample chart dataset.
- 79
parameter-golf
5.2Kopenai/parameter-golf · PythonThis is OpenAI's 'Model Craft Challenge: Parameter Golf' - a competition to train the best language model that fits in a 16MB artifact and trains in under 10 minutes on 8xH100 GPUs, scored by bits-per-byte compression on the FineWeb validation set.
- 80
reverse-SynthID
5Kaloshdenny/reverse-SynthID · Pythonreverse-SynthID reverse-engineers Google's SynthID watermark embedded in Gemini-generated images using signal processing and spectral analysis, and ships tools that detect and surgically bypass that watermark without any access to Google's proprietary encoder/decoder.
- 81
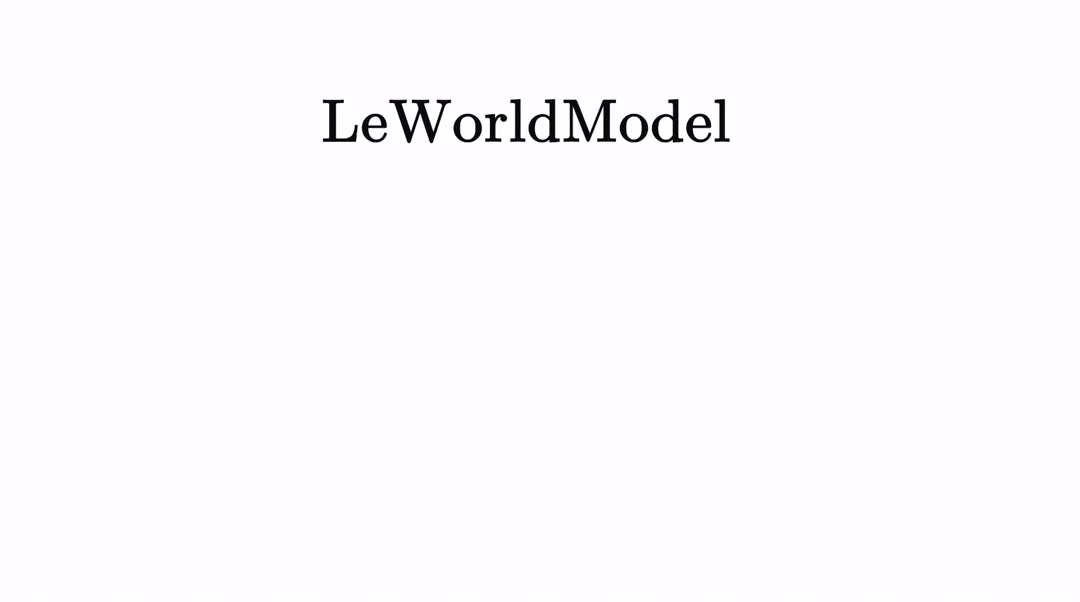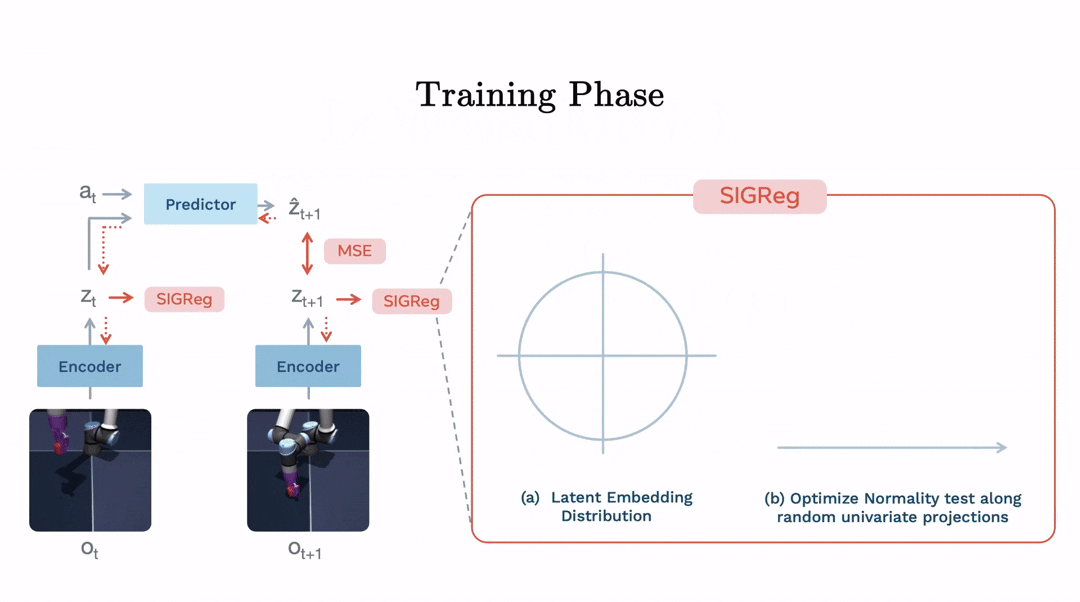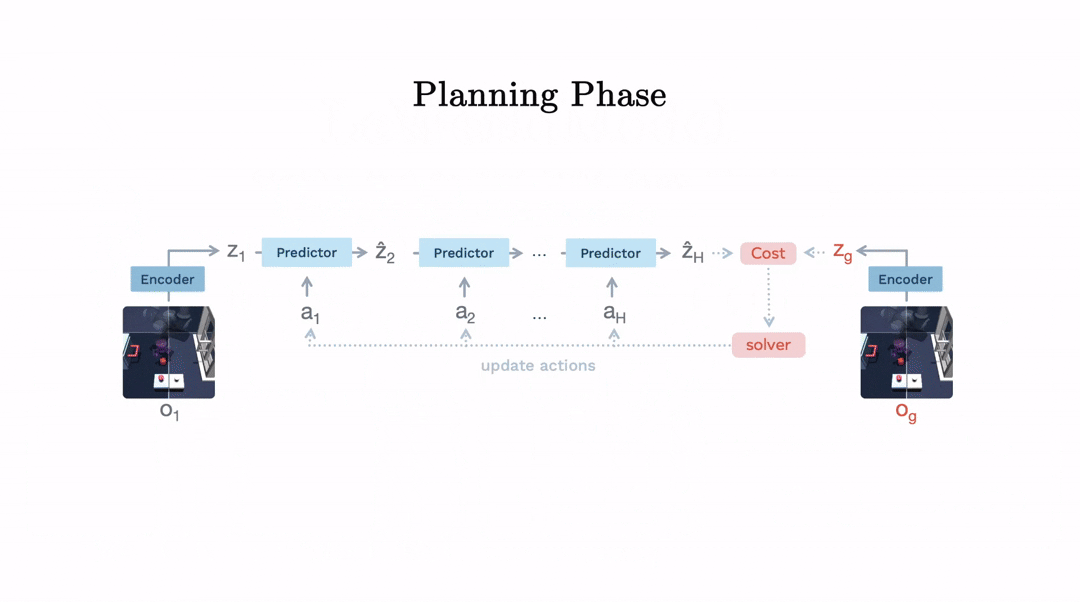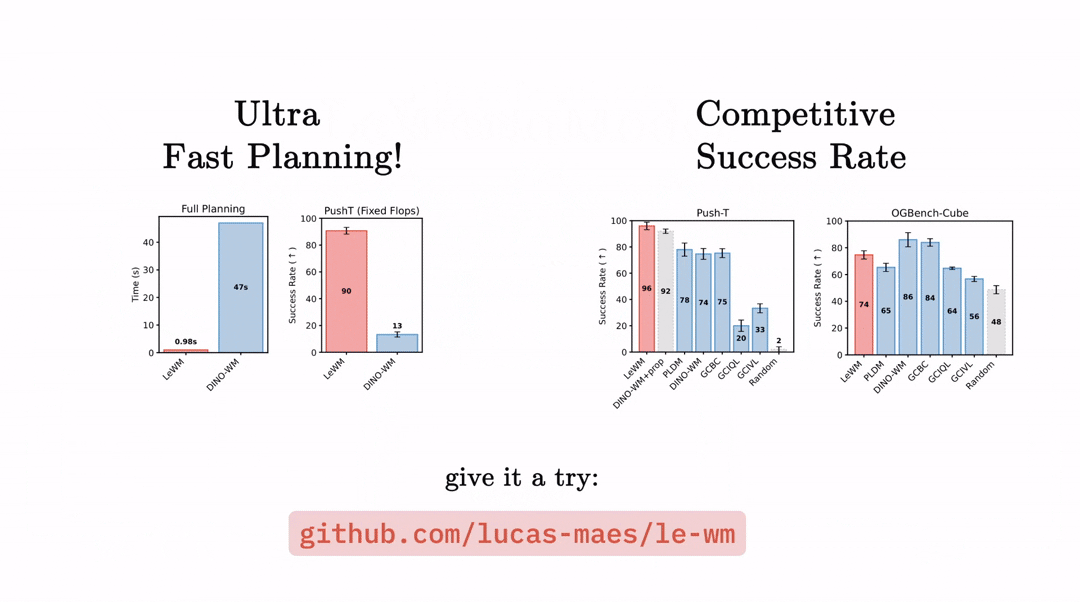
le-wm
4.5Klucas-maes/le-wm · PythonThis is the official codebase for LeWorldModel (LeWM), a Joint-Embedding Predictive Architecture (JEPA) that learns a world model directly from pixels using just two loss terms, avoiding the usual tricks like EMA, pretrained encoders, or auxiliary supervision.
- 82

prediction-market-analysis
3.9KJon-Becker/prediction-market-analysis · PythonIt's a framework for collecting and analyzing prediction market data from Polymarket and Kalshi, bundled with the largest publicly available dataset of their market and trade history.
- 83

GR00T-WholeBodyControl
3.8KNVlabs/GR00T-WholeBodyControl · PythonNVIDIA GR00T Whole-Body Control — a codebase hosting pretrained checkpoints plus training, evaluation, and deployment code for advanced humanoid robot controllers: the Decoupled WBC used in GR00T N1.5/N1.6, the GEAR-SONIC series, and MotionBricks.
- 84
chinese-poetry-api
3.5Kpalemoky/chinese-poetry-api · GoA high-performance API service for Chinese classical poetry written in Go, exposing both REST and GraphQL endpoints over a dataset of nearly 400,000 poems spanning Tang poetry, Song lyrics, Yuan qu and more.
- 85
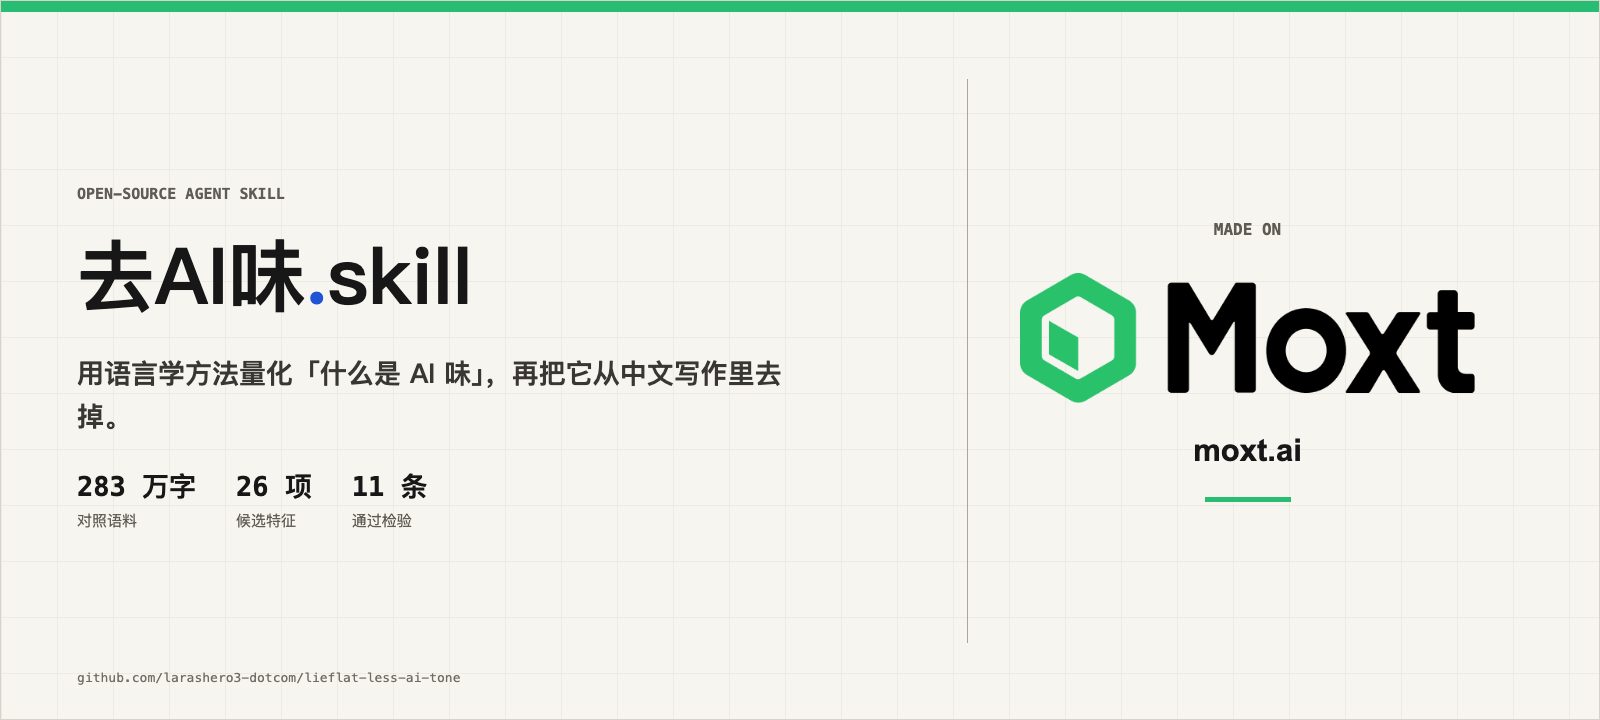
lieflat-less-ai-tone
3Klarashero3-dotcom/lieflat-less-ai-tone · PythonA research-backed skill that detects and removes 'AI tone' from Chinese writing, based on a statistical study of a 2.83-million-character corpus comparing AI-generated and human-written text.
- 86
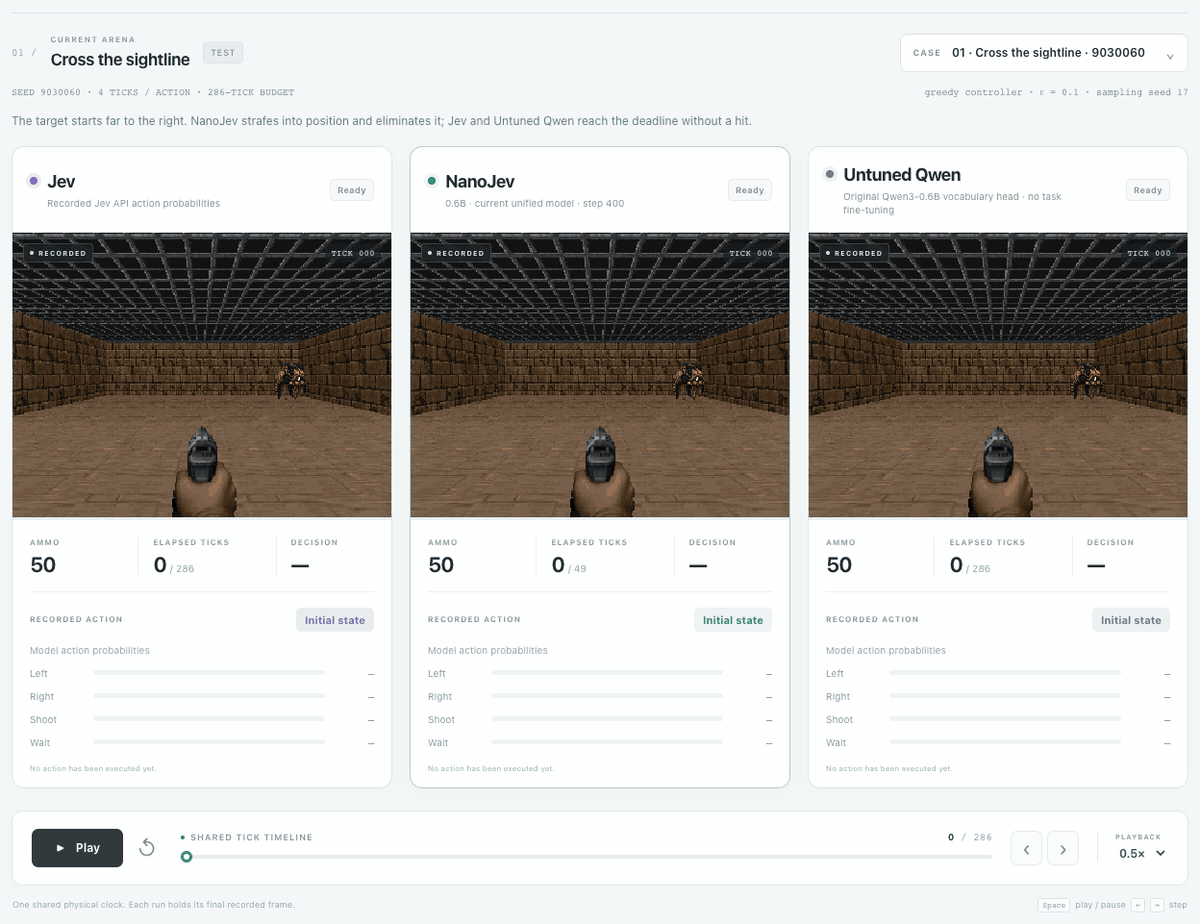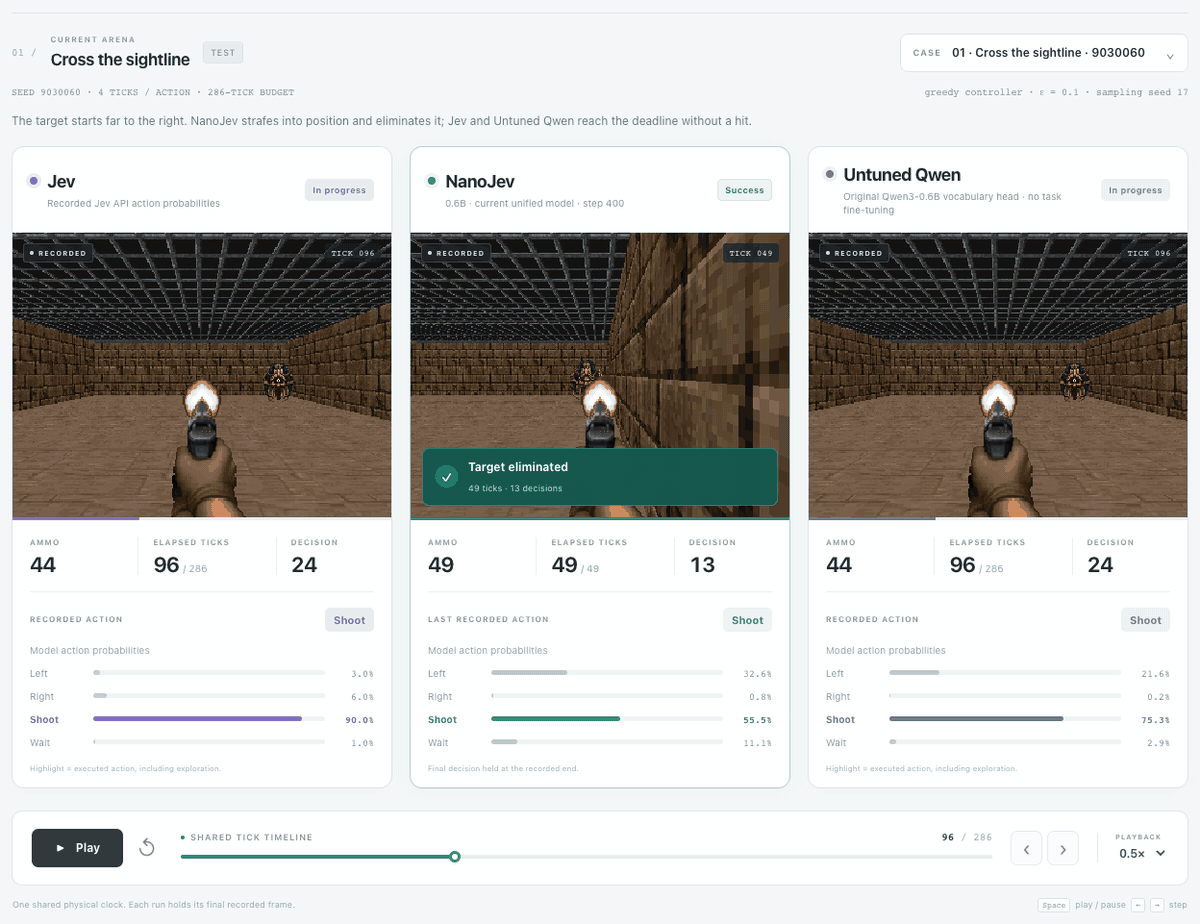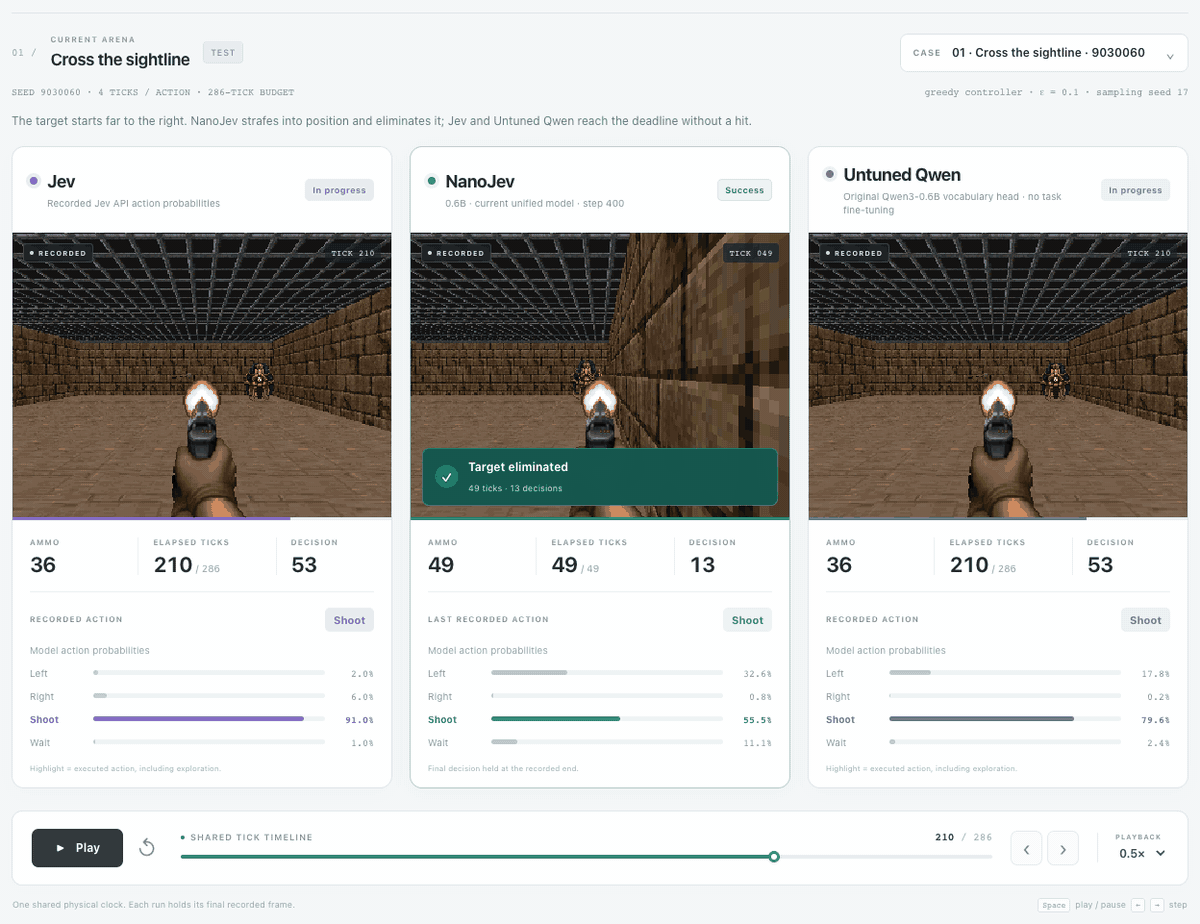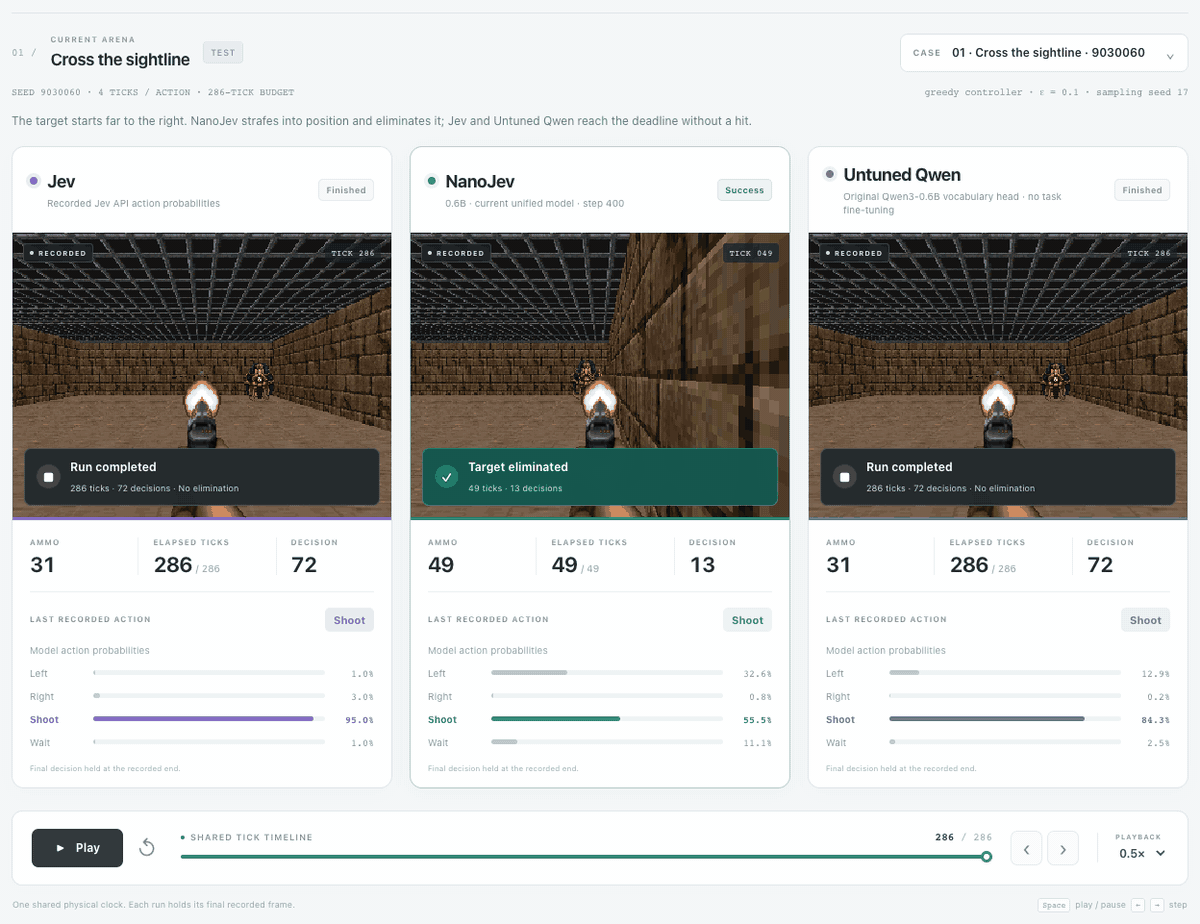
NanoJev
2.6KTianyuCodings/NanoJev · PythonA nano replica of Jev: a 0.6B-parameter parallel decision model that takes states and questions in and returns complete probability distributions — no output tokens are ever decoded.
- 87
tapnet
2.2Kgoogle-deepmind/tapnet · Jupyter NotebookThis is Google DeepMind's official repository for Tracking Any Point (TAP) research: it bundles the TAP-Vid and TAPVid-3D benchmark datasets, the TAPIR/BootsTAPIR/TAPNext/TAPNext++ point-tracking models, the RoboTAP robotics extension, and the TRAJAN trajectory autoencoder.
- 88
UniMate
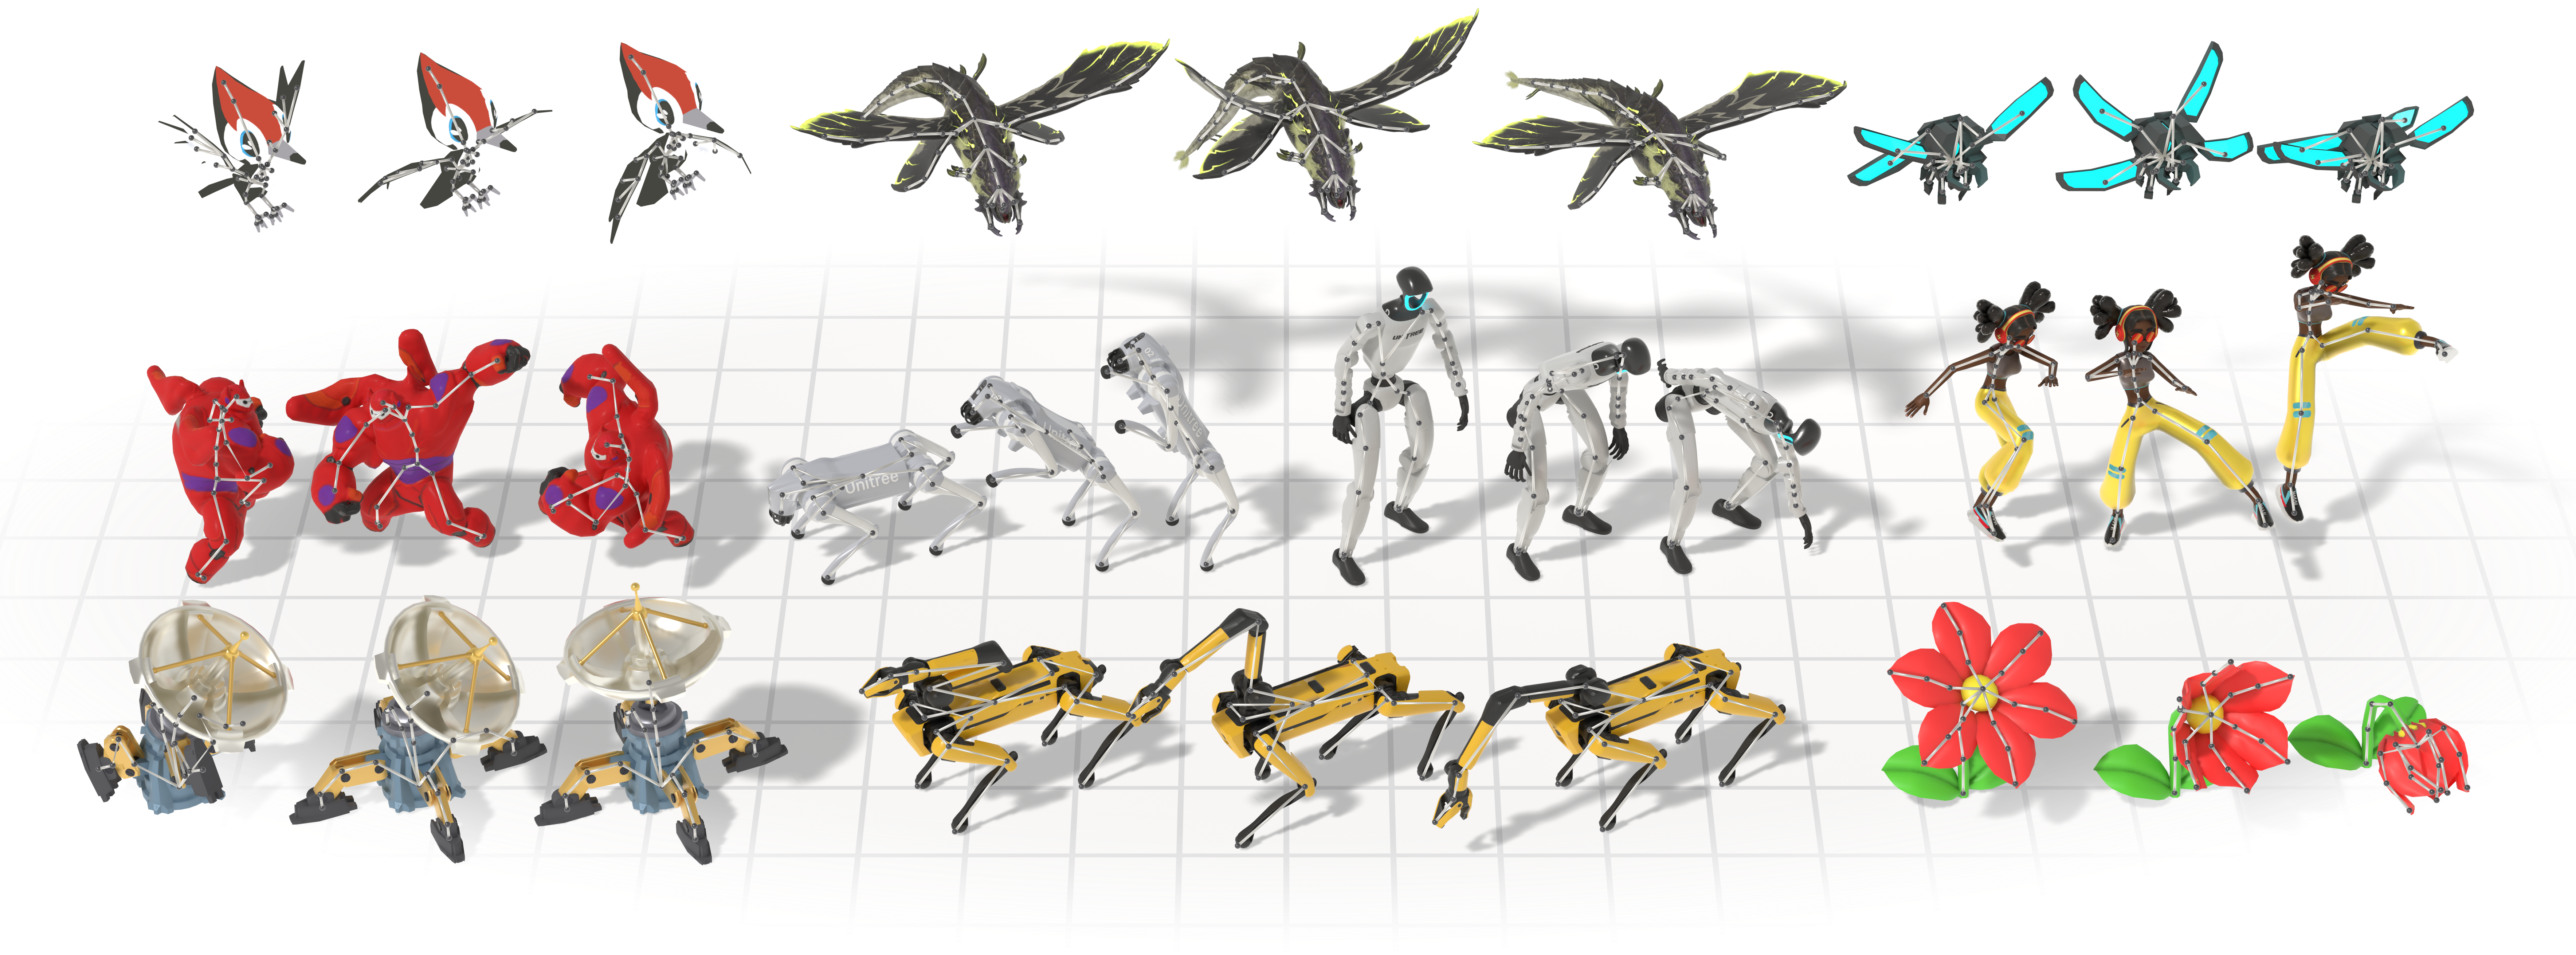
2KFriedrich-M/UniMate · PythonUniMate is the official code release for a SIGGRAPH Asia 2026 paper: a single diffusion/flow-matching model that generates motion for very different skeleton types (bipedal, quadrupedal, avian, marine, insectoid, serpentine, and even rigid articulated objects) from a rigged 3D asset plus a text prompt, without retraining per skeleton.
- 89
highball
1.6Kgauthierpiarrette/highball · SwiftHighball is a native macOS app (with a companion CLI) that sets up Wine, DXMT, D3DMetal and DXVK so you can run Windows games on Apple Silicon, backed by an open compatibility database that tells you what actually works.
- 90
AISafetyHot-Hub
1.6Kwuyoscar/AISafetyHot-Hub · TeXAI Safety HOT Hub is a daily-updated feed of curated AI safety news and research papers (attacks/jailbreaks, defenses, alignment evals, incidents, multi-agent risks, governance), with Markdown/BibTeX/JSON exports and a public MCP endpoint so an AI agent can query news, papers, events and daily briefings directly.
- 91

xingcezhenti
1.1KERRRC/xingcezhentiA Markdown archive of 515 real Chinese civil service exam papers (national and provincial 行测/aptitude test) from 2016 to 2026, totaling 58,890 questions with official answers and explanations.
- 92
RelateAnything
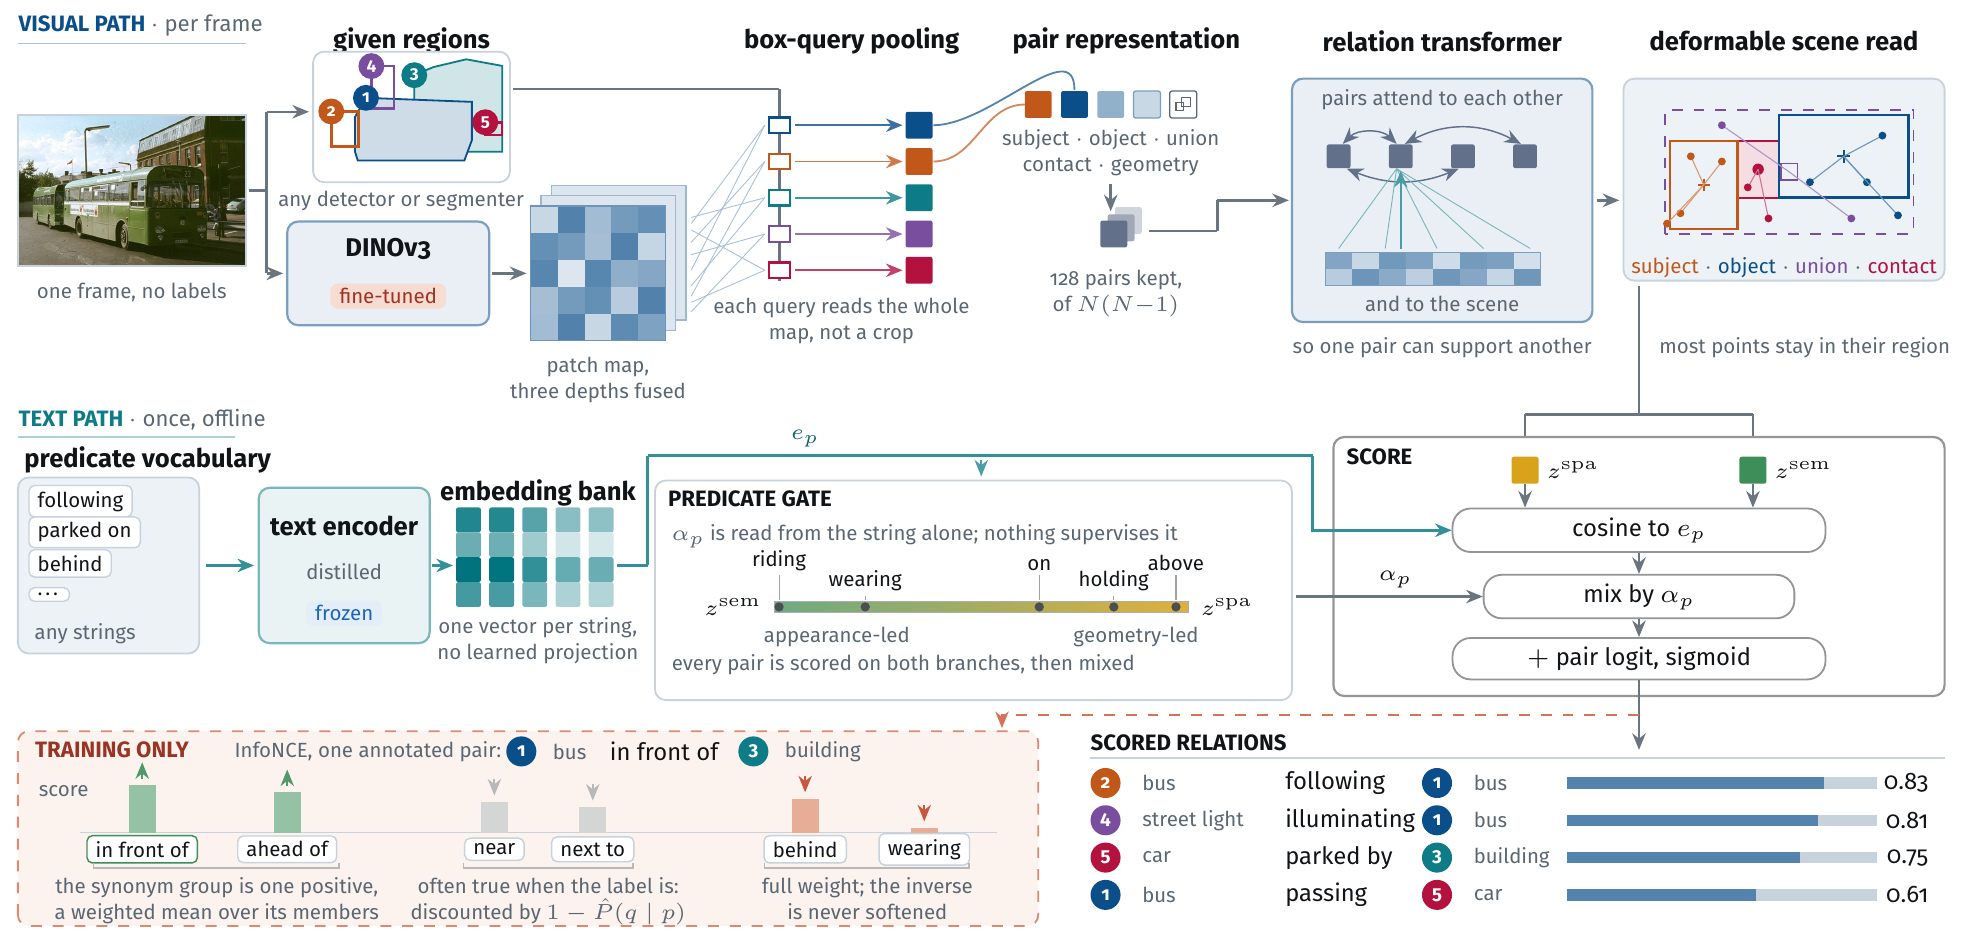
1.1KMaelic/RelateAnything · PythonRelateAnything is a real-time, open-vocabulary relation prediction model: give it an image, object regions and the relations to look for, and it returns scored (subject, relation, object) triplets like person → riding → horse.
- 93
OpenWAM
1.1KOpenWAM-Official/OpenWAM · PythonOpenWAM is an open research stack for systematically building World-Action Models (WAMs) for robots, breaking the usual tightly-coupled design choices into modular, swappable components you can compare in controlled experiments.
- 94
real-api-pricing
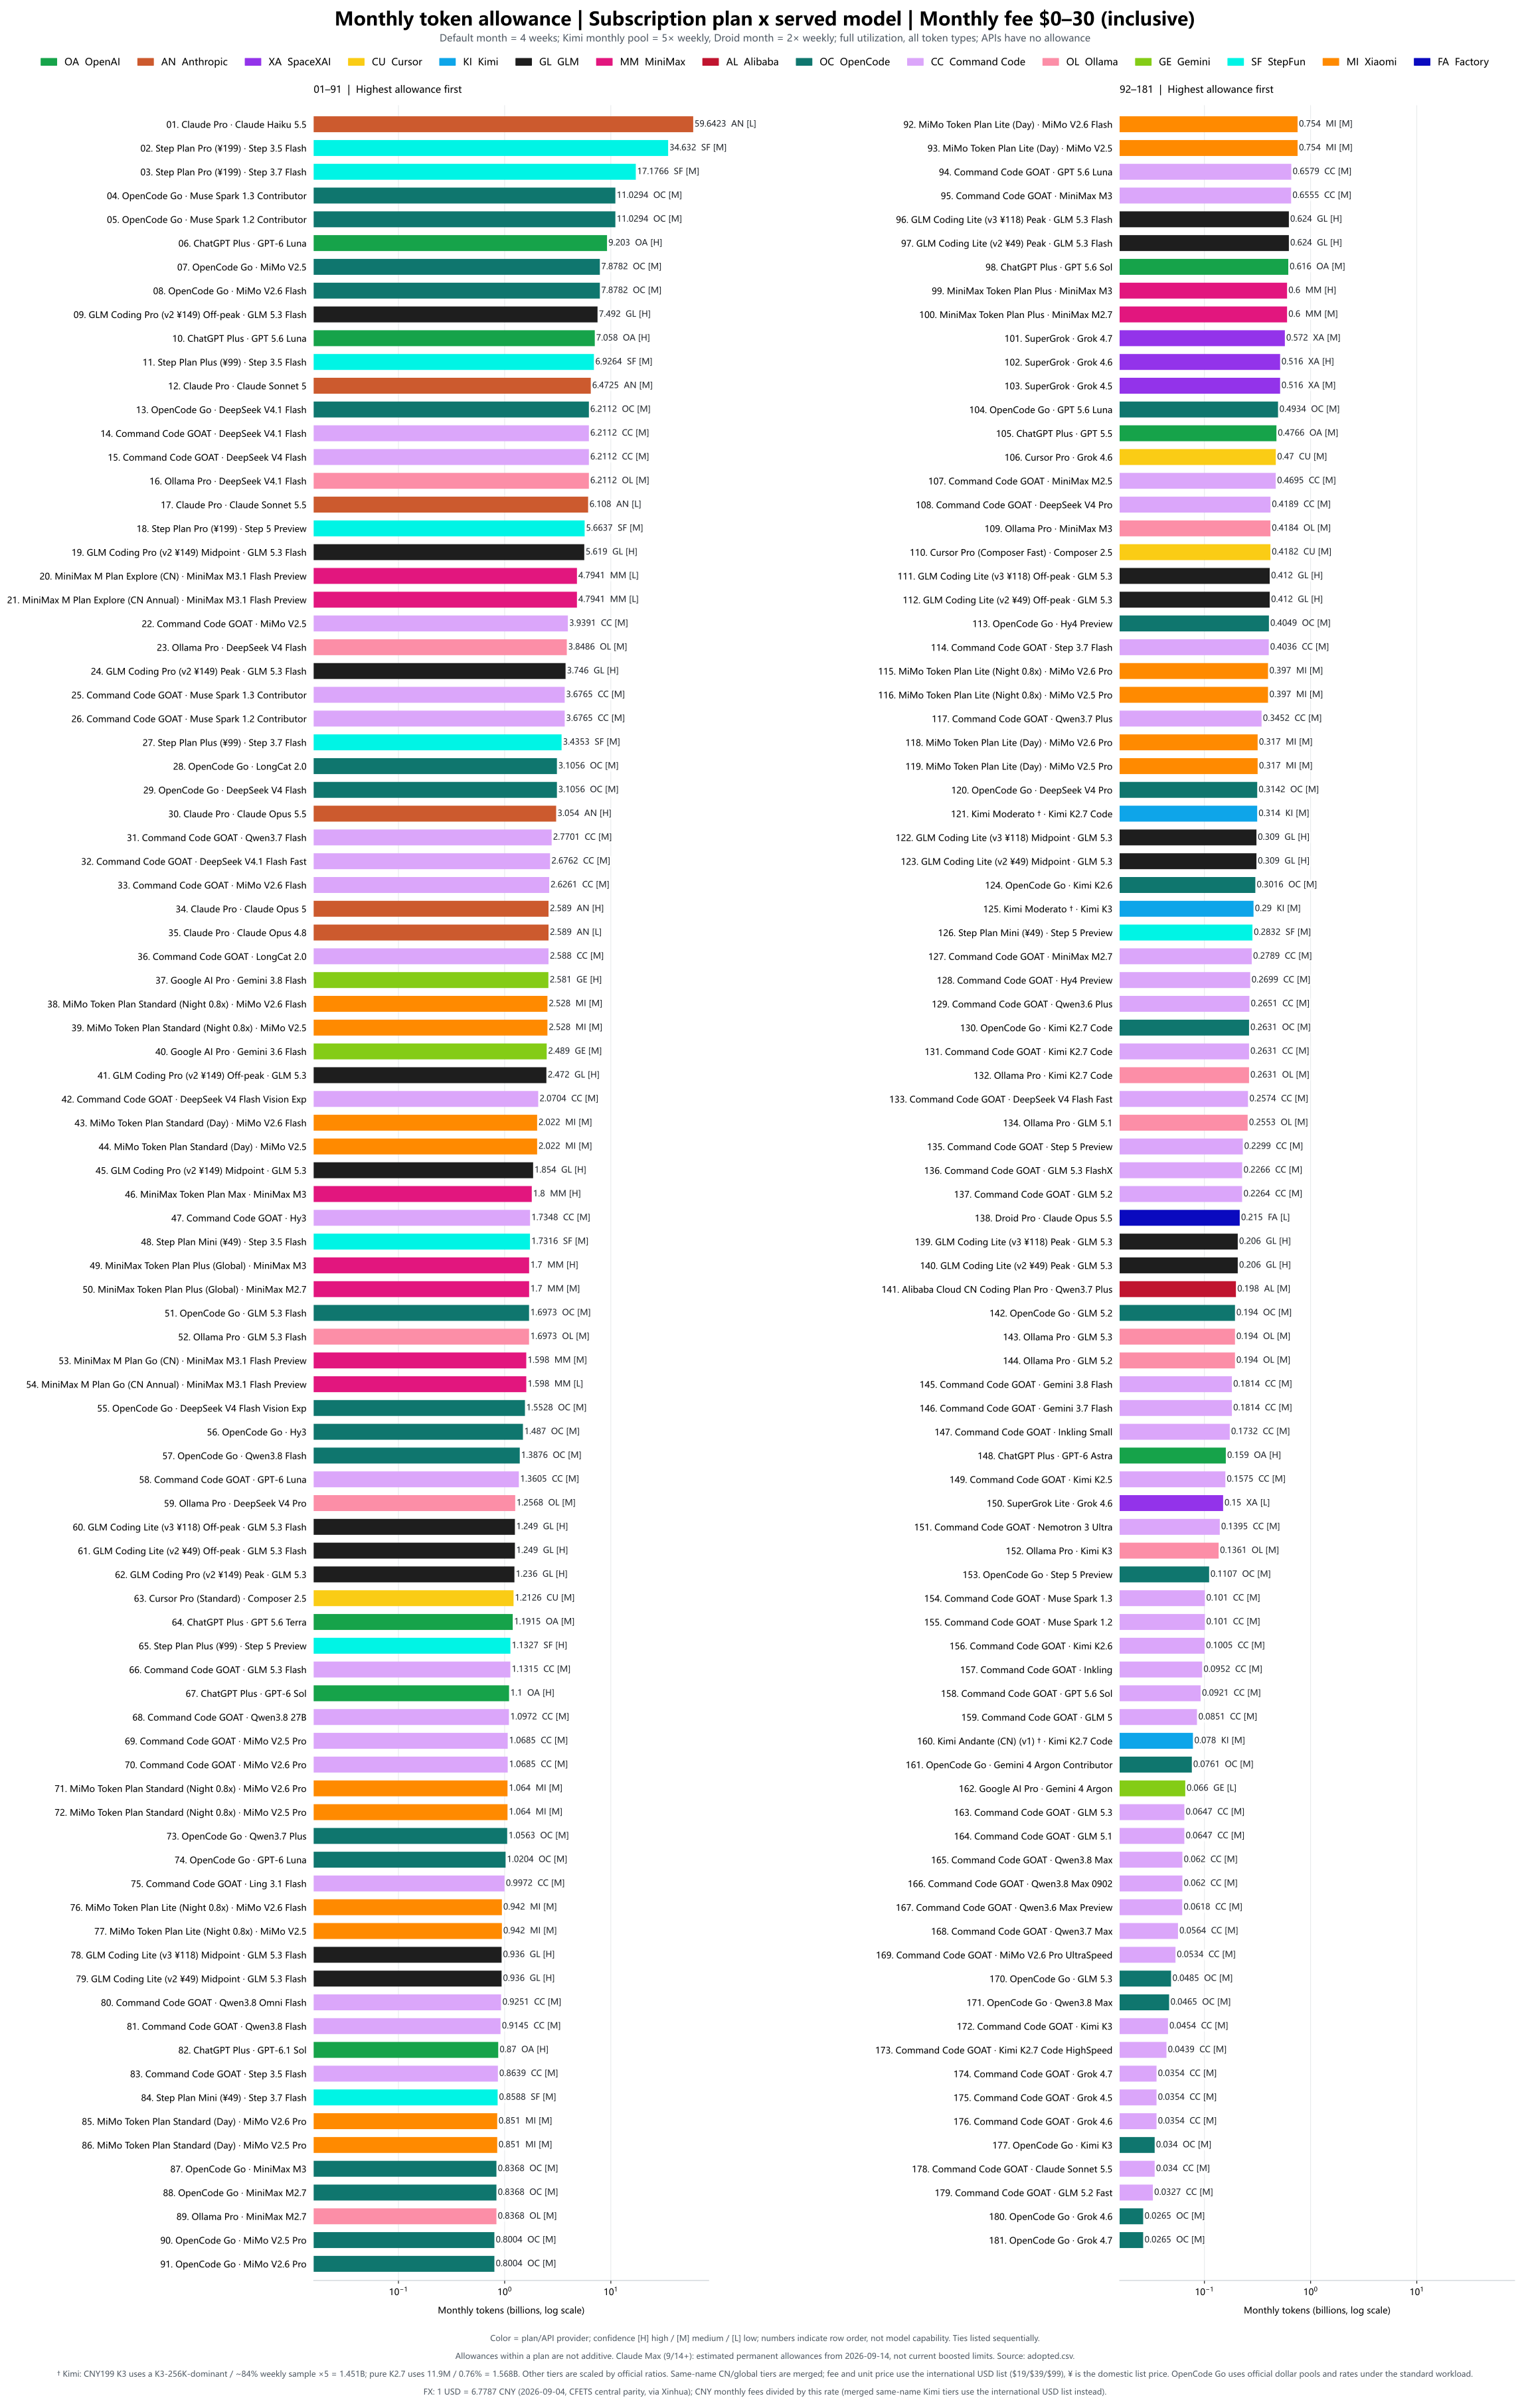
945Fei2411/real-api-pricing · HTMLIt is a data and chart project that computes the real price of AI subscription plans by dividing the monthly fee by the actual usable tokens, then plots those real unit prices against coding/agent leaderboard scores as Pareto frontier charts.
- 95
Valen
873Valen-Team/Valen · Jupyter NotebookValen (万澜) is a multimodal decision model that adds visual perception to System One-style decision-making: it scores candidate actions against text, images and video using a task instruction, instead of generating free-form answers.
- 96
APSD
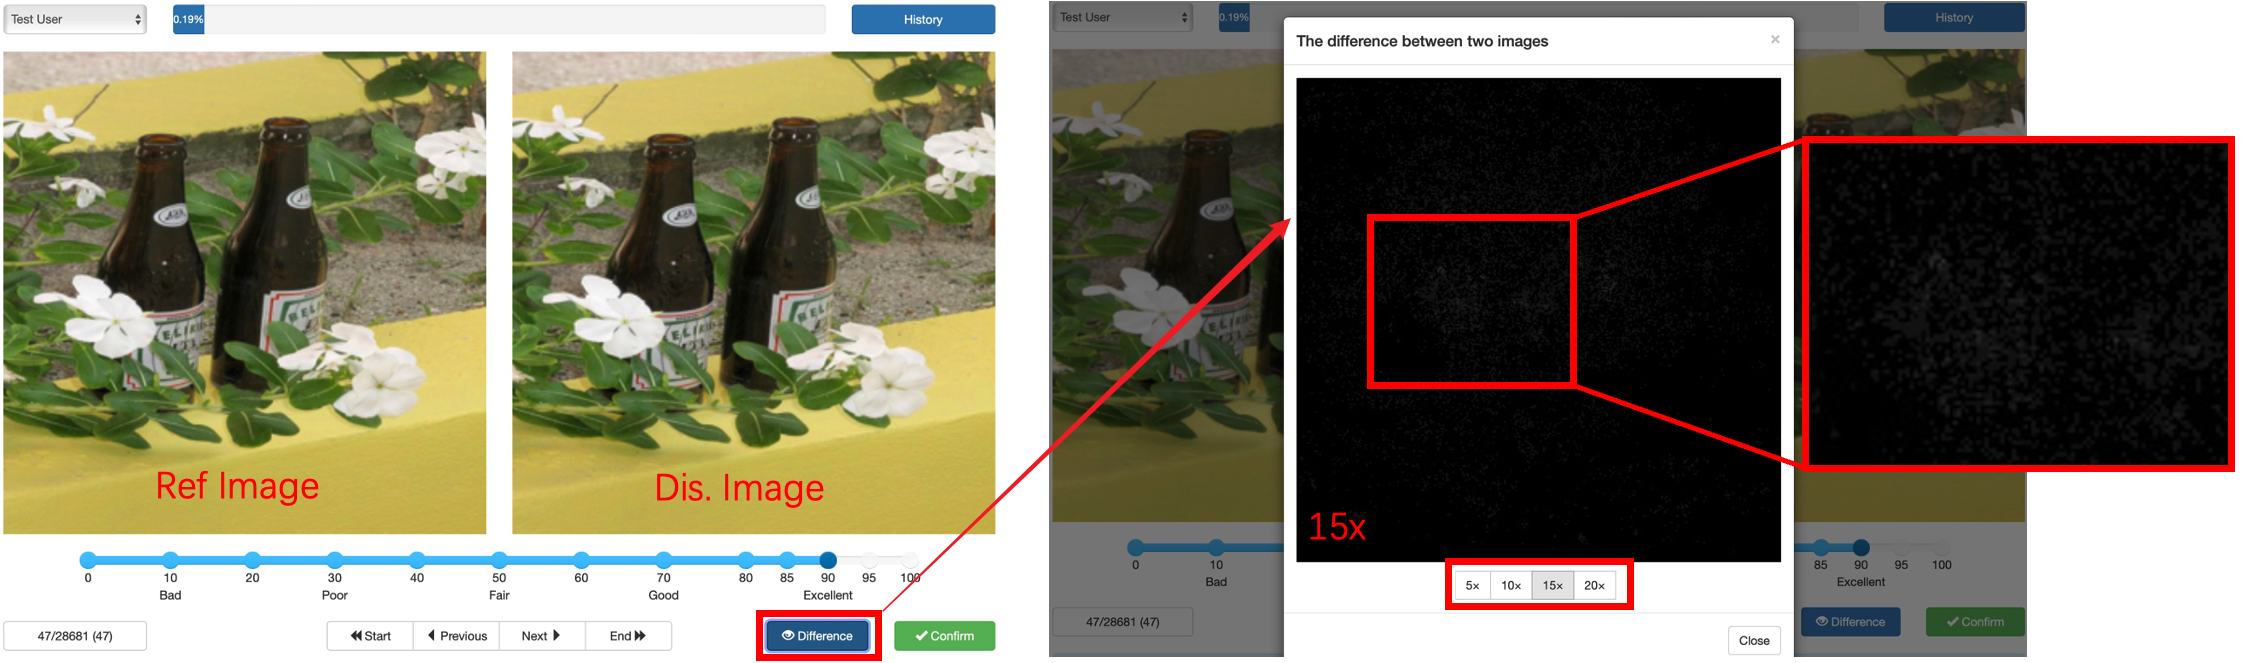
853hcliucs/APSDAPSD is a large-scale dataset for studying how visually stealthy adversarial perturbations look to humans, containing 10,586 clean-adversarial image pairs with human opinion scores.
- 97
SolarWM
778Junchao-cs/SolarWM · PythonSolarWM is a fully open foundation for building interactive video world models, covering data preparation, scalable multi-backbone training, and long-horizon inference.
- 98
SkillCorpus
686EverMind-AI/SkillCorpus · PythonSkillCorpus is EverMind's open-source pipeline that aggregates scattered SKILL.md files from public repos, applies safety/license/quality gates, and exports a curated, retrieval-ready corpus plus two fine-tuned retrieval models so agents can fetch the right skill at answer time.
- 99
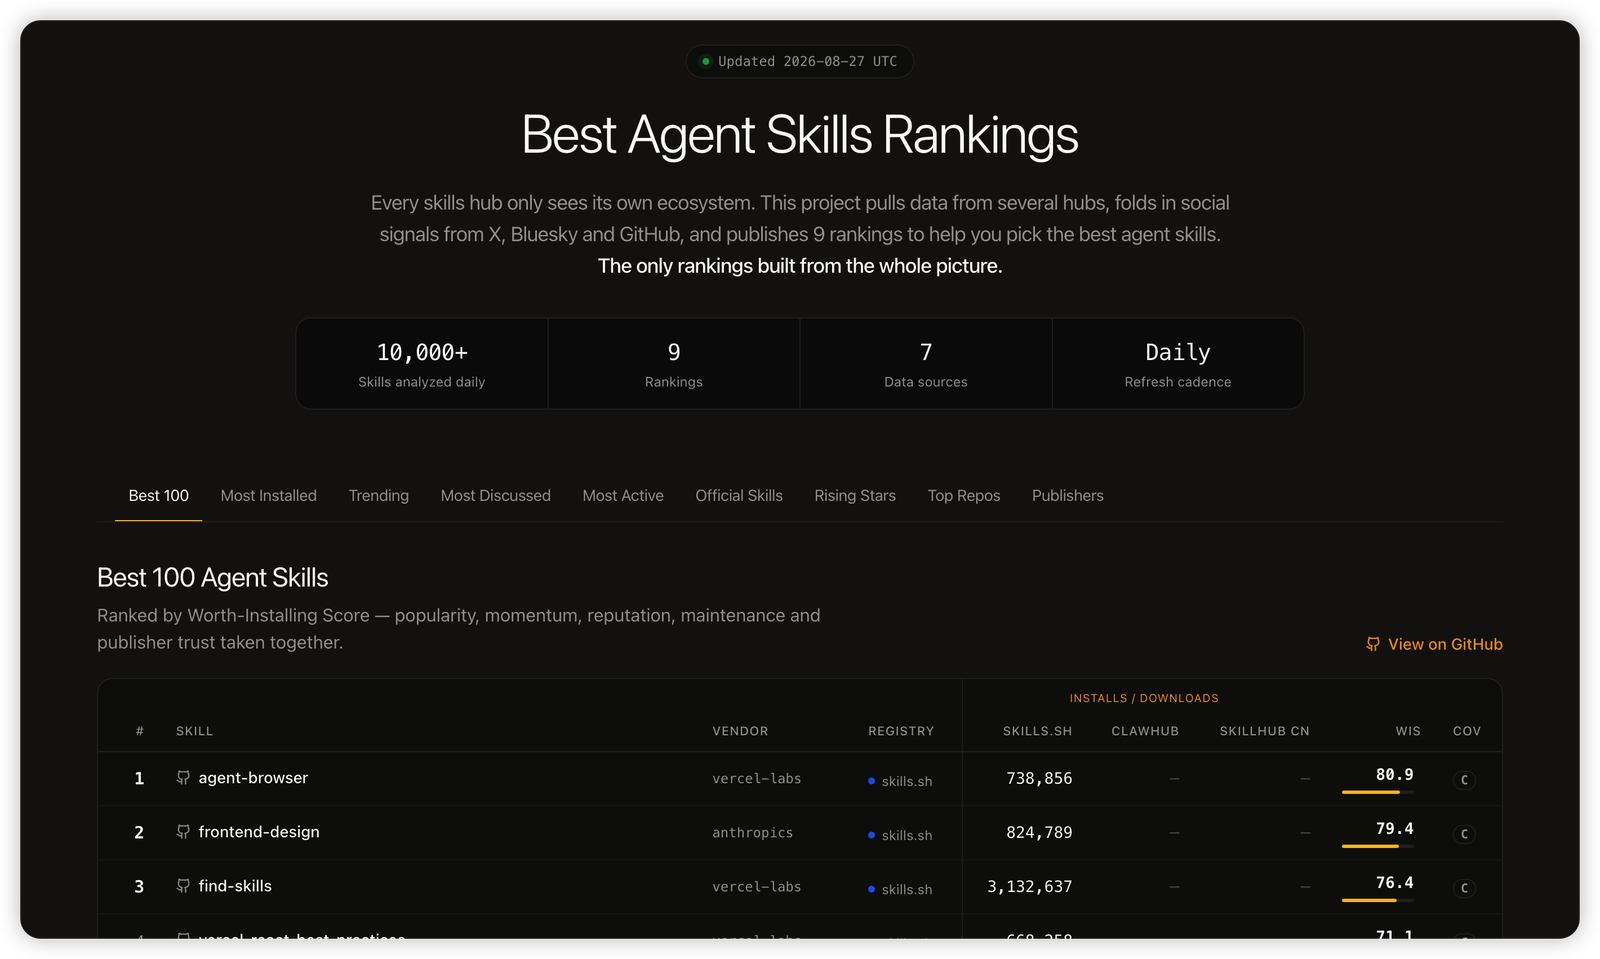
best-skills
649LinklyAI/best-skillsA daily-updated ranking of the top 100 AI agent skills, merging install counts, growth, and social buzz from skills.sh, ClawHub, Tencent SkillHub, GitHub, X and more than 10 other communities into one cross-ecosystem view.
- 100
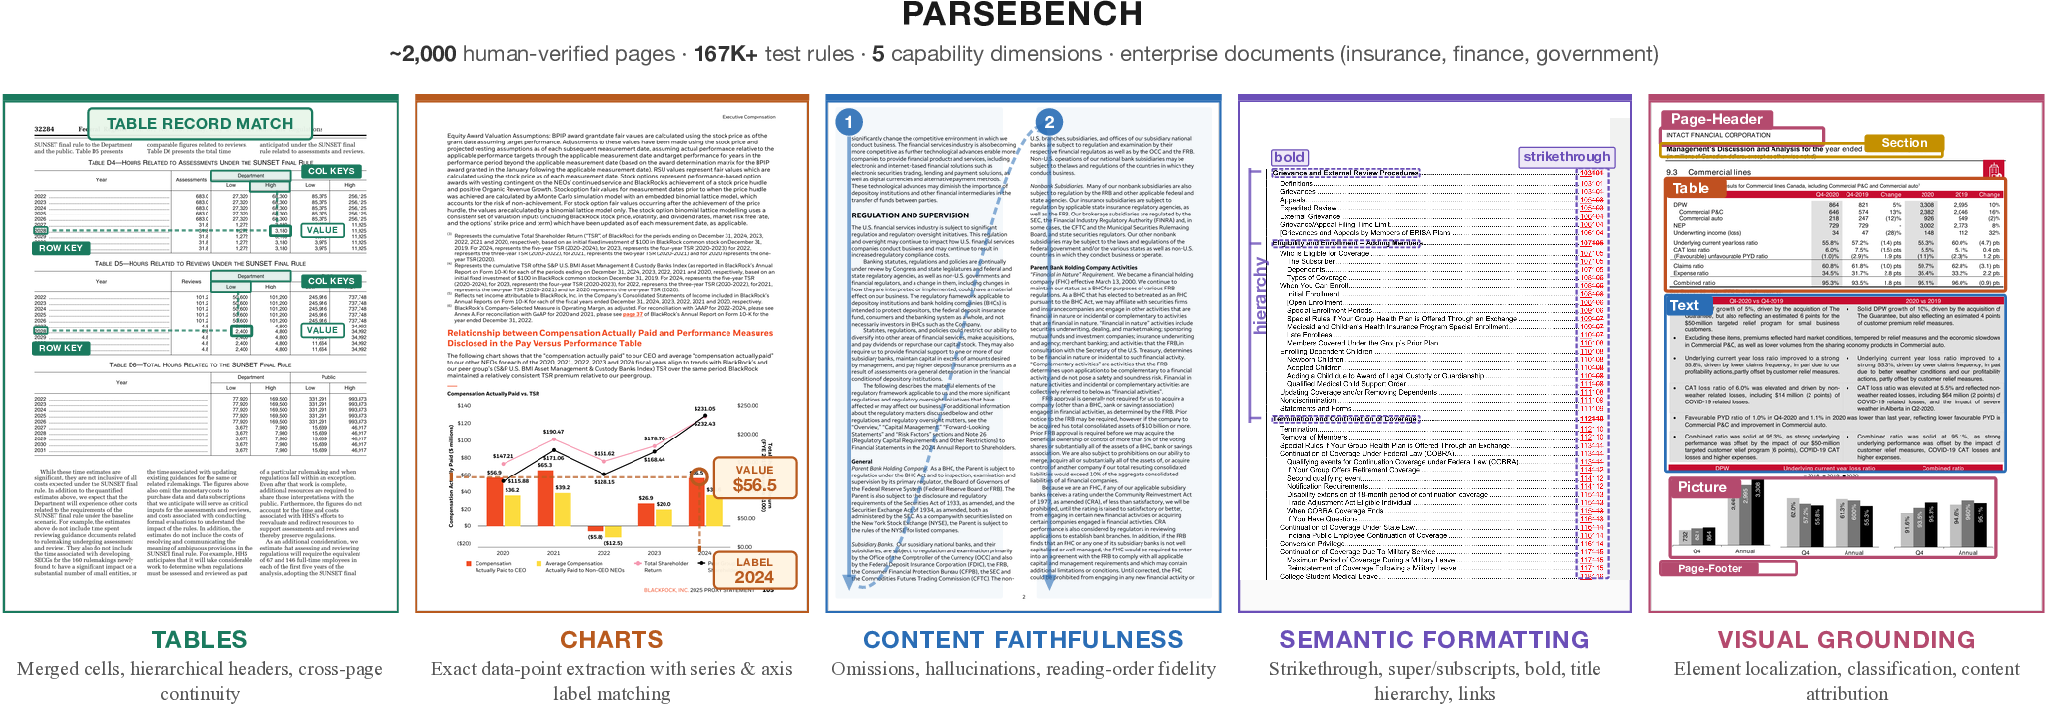
ParseBench
603run-llama/ParseBench · PythonParseBench is a benchmark that measures how well document parsing tools (OCR engines, VLMs, commercial parsing APIs) convert PDFs into structured output that AI agents can reliably act on, rather than just text that looks similar to the original.

Showing the 100 most-starred of 125. See every one in the catalog.
Related topics
Often tagged together