Topics / #rocm
Rocm projects on GitHub
AMD GPU compute ecosystem for machine learning workloads on Radeon hardware.
As of , the most-starred Rocm projects on GitHub are ComfyUI (137.9K stars), pytorch (104.8K stars) and vllm (94K stars). GitHub.Locker tracks 31 Rocm repositories with 770.5K stars combined. The fastest-growing on October 16 was ComfyUI, with +205 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
ComfyUI
Comfy-Org/ComfyUI · ★ 137.9KComfyUI is a node-based graph interface for building and running diffusion model workflows: image, video, 3D, and audio generation, editing, and more, all without writing code.
 +73
vllm
vllm-project/vllm · ★ 94KvLLM is a library for fast LLM inference and serving, built around PagedAttention for efficient memory management of attention keys and values.
 +58
project-maya
mw00/project-maya · ★ 954Project Maya lets you run GLM-5.3-Flash, a 321-billion-parameter mixture-of-experts AI model, on your own NVIDIA GPU(s) by streaming the model's experts across VRAM, RAM and NVMe SSD as the conversation needs them.
 +35
pytorch
pytorch/pytorch · ★ 104.8KPyTorch is a Python package providing fast tensor computation with strong GPU acceleration and deep neural networks built on a tape-based autograd system, serving as both a NumPy-like GPU library and a flexible deep learning research platform.
The all-time top
31 projects · by stars
- 137.9K
#1 · Comfy-Org/ComfyUI
ComfyUI
ComfyUI is a node-based graph interface for building and running diffusion model workflows: image, video, 3D, and audio generation, editing, and more, all without writing code.
- 104.8K#2 · pytorch/pytorch
pytorch
PyTorch is a Python package providing fast tensor computation with strong GPU acceleration and deep neural networks built on a tape-based autograd system, serving as both a NumPy-like GPU library and a flexible deep learning research platform.
- 94K#3 · vllm-project/vllm
vllm
vLLM is a library for fast LLM inference and serving, built around PagedAttention for efficient memory management of attention keys and values.
- 4

faceswap
57.6Kdeepfakes/faceswap · PythonFaceSwap is a Python tool that uses deep learning to recognize and swap faces in pictures and videos.
- 5
textgen
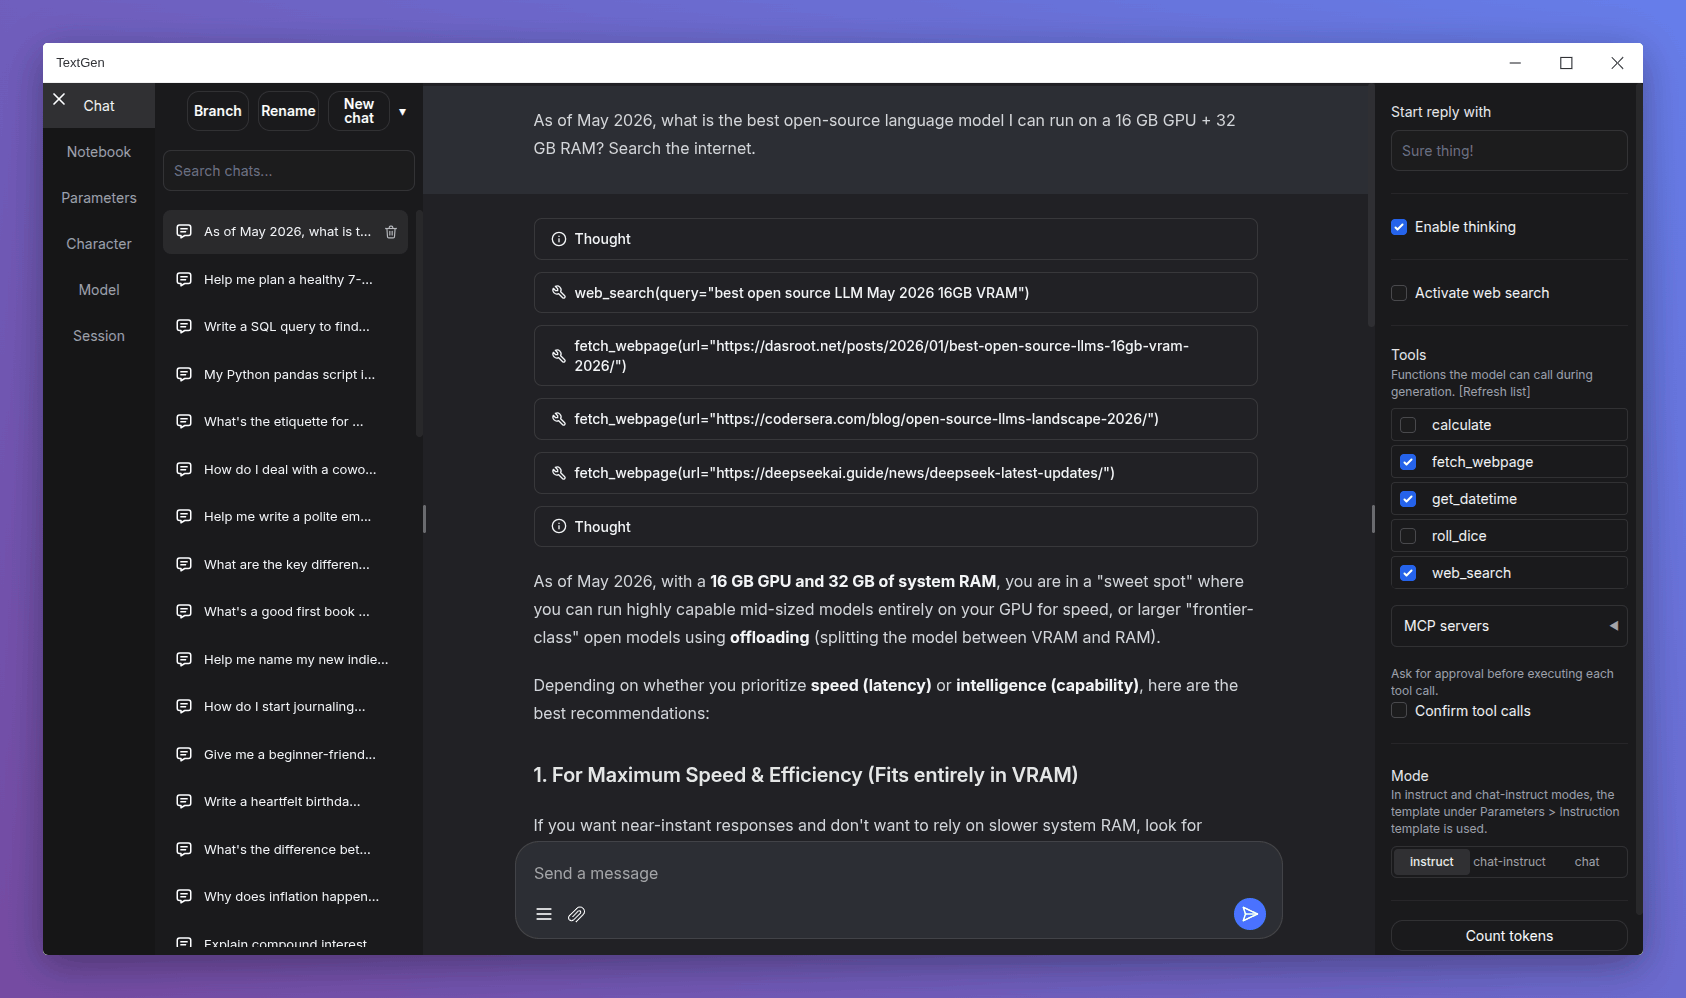
47.7Koobabooga/textgen · PythonTextGen is an open-source desktop app for running local LLMs with text, vision, tool-calling, and an OpenAI/Anthropic-compatible API, built to be 100% private with no telemetry.
- 6
DeepSpeed
43.2Kdeepspeedai/DeepSpeed · PythonDeepSpeed is a deep learning optimization library that makes distributed training and inference of very large models easy, efficient and effective — it powered models like MT-530B and BLOOM.
- 7
btop
35Karistocratos/btop · C++A terminal resource monitor that shows usage and stats for processor, memory, disks, network and processes. It is the C++ version and continuation of bashtop and bpytop.
- 8
self-llm
32.5Kdatawhalechina/self-llm · Jupyter NotebookSelf-llm is a Chinese-language tutorial collection that teaches beginners how to configure environments, deploy, and fine-tune (full-parameter or LoRA) 50+ open-source large language models and multimodal models on Linux.
- 9

apollo
26.9KApolloAuto/apollo · C++An open autonomous driving platform from Baidu: a high-performance, flexible software stack covering perception, prediction, planning and control, for developing, testing and deploying self-driving vehicles.
- 10
ds4
23.9Kantirez/ds4 · CDwarfStar (ds4) is a small, self-contained local inference engine specialized for running DeepSeek V4 Flash and PRO, plus GLM 5.2/5.3, on consumer hardware like high-memory Macs, NVIDIA GPUs, and AMD Strix Halo systems.
- 11

mlc-llm
23.2Kmlc-ai/mlc-llm · PythonMLC LLM is a machine learning compiler and high-performance deployment engine that lets you run large language models natively on almost any platform, from servers to phones to the browser.
- 12
ktransformers
19.6Kkvcache-ai/ktransformers · PythonKTransformers is a research framework for efficient inference and fine-tuning of large language models through CPU-GPU heterogeneous computing, letting huge MoE models run on hardware that doesn't have enough VRAM to hold them entirely on GPU.
- 13
mamba
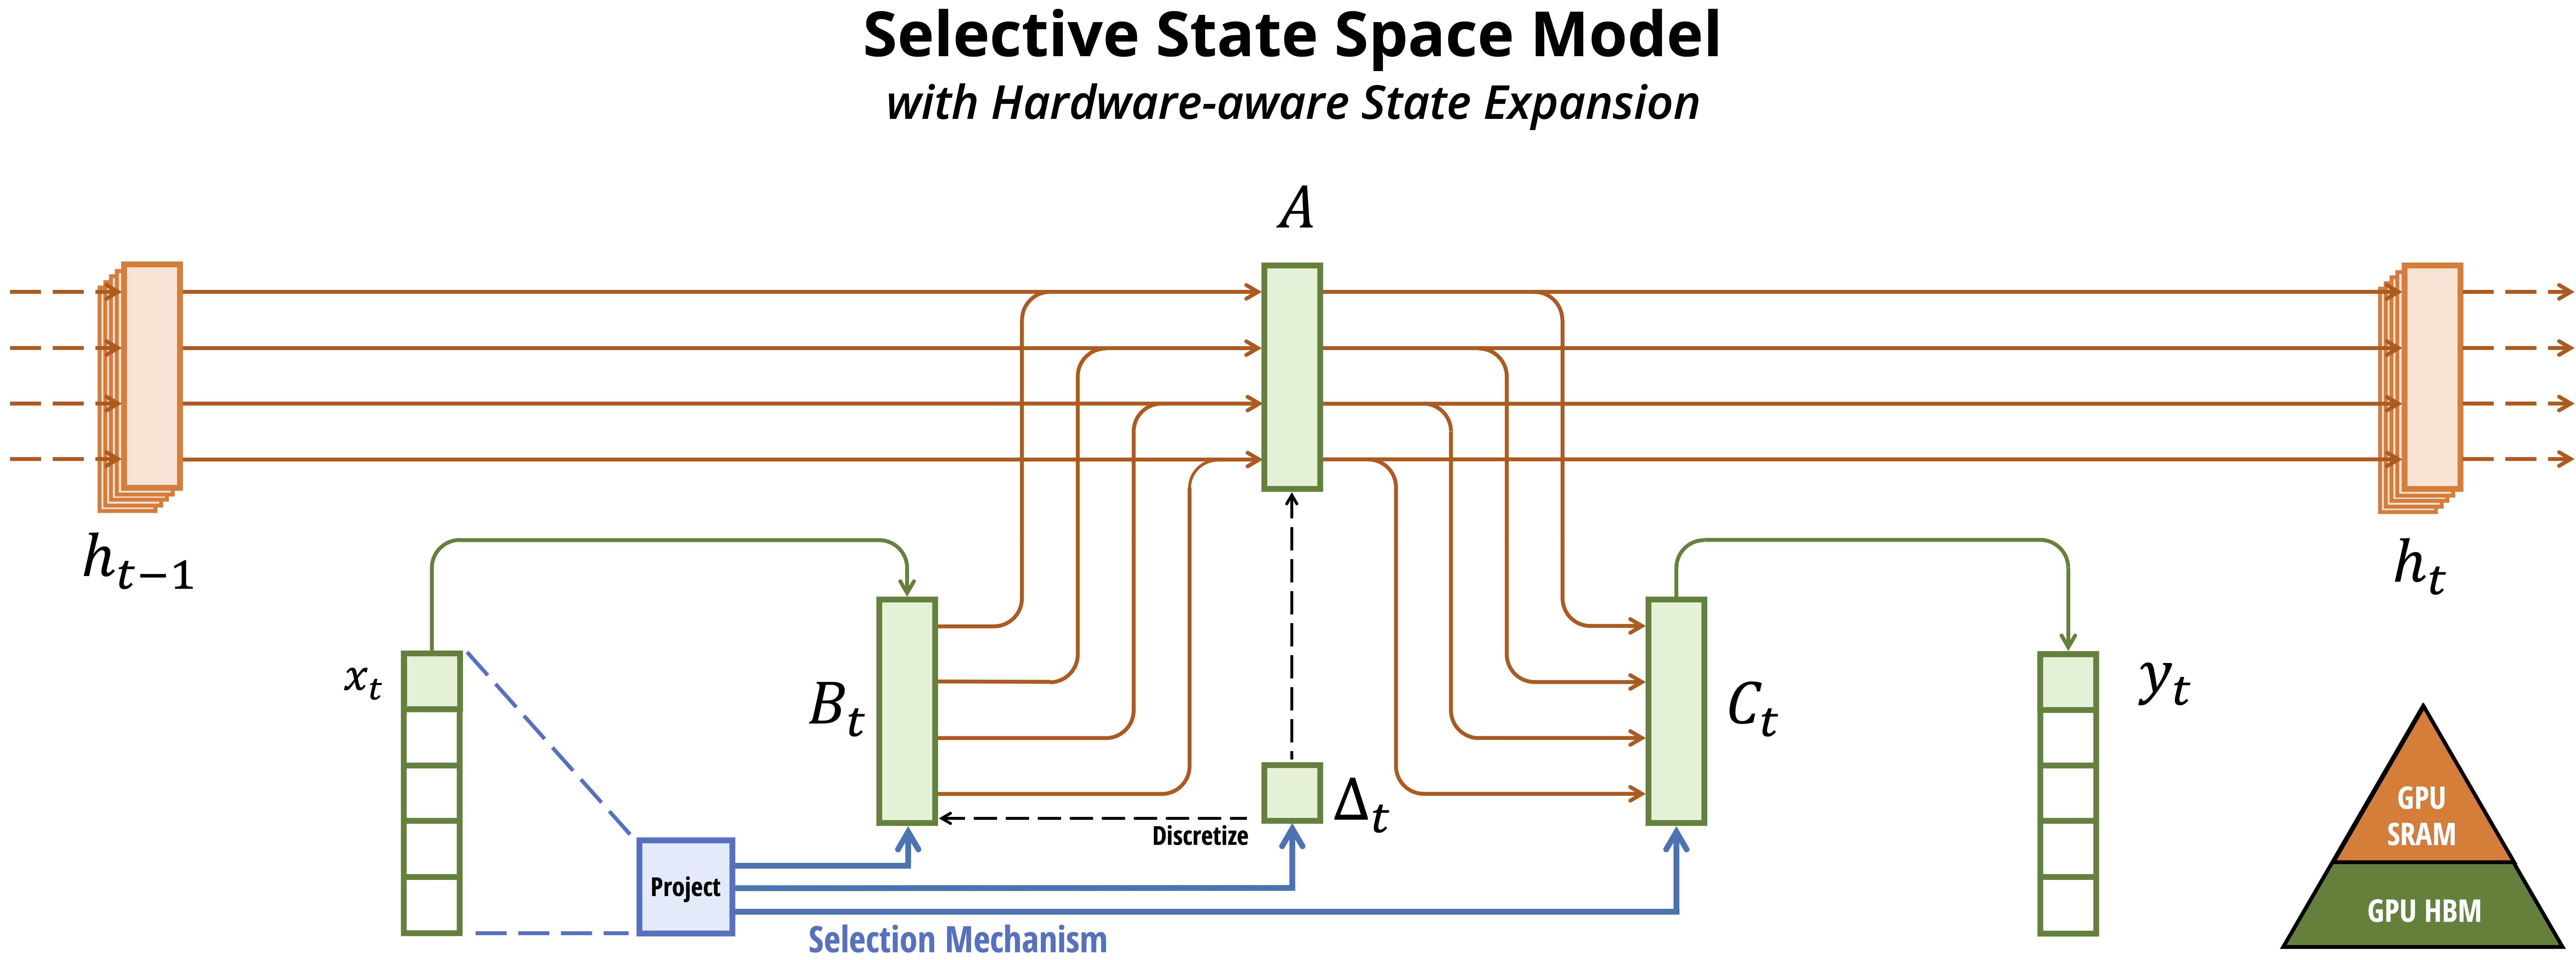
18.9Kstate-spaces/mamba · PythonMamba is a state space model architecture for sequence modeling with linear-time scaling. It shows promising performance on information-dense data like language modeling, where earlier subquadratic models fell short of Transformers; this repo is its PyTorch implementation.
- 14
burn
16.1Ktracel-ai/burn · RustBurn is a Rust tensor library and deep learning framework for both training and inference, so the same code takes a model from prototype to production on everything from GPU clusters to the browser.
- 15

CorridorKey
14.8Knikopueringer/CorridorKey · PythonCorridorKey is a neural network tool that keys green or blue screen footage, predicting the true un-multiplied foreground color and a clean linear alpha channel for every pixel, including semi-transparent ones like motion blur or out-of-focus edges.
- 16

tvm
13.8Kapache/tvm · PythonApache TVM is an open machine learning compiler framework that turns trained models into optimized, deployable code for a wide range of hardware targets.
- 17
cupy
12.4Kcupy/cupy · PythonCuPy is a NumPy/SciPy-compatible array library for GPU-accelerated computing with Python: you write ordinary Python array code, and it executes on NVIDIA or AMD GPUs.
- 18
LMCache
12.1KLMCache/LMCache · PythonLMCache is a KV cache management layer for LLM inference that turns the KV cache from a temporary, per-process state into reusable, persistent 'AI-native knowledge' that can be shared across serving engines, reducing time-to-first-token and boosting throughput for long-context, multi-turn, and RAG workloads.
- 19
text-generation-inference
10.9Khuggingface/text-generation-inference · PythonText Generation Inference (TGI) is a toolkit for deploying and serving large language models — a Rust, Python and gRPC server that powers Hugging Chat, the Inference API and Inference Endpoints at Hugging Face.
- 20

xformers
10.6Kfacebookresearch/xformers · PythonxFormers is Meta's (Facebook Research) toolbox of hackable, optimized Transformer building blocks that you compose together — reusable pieces for your own models rather than a monolithic framework.
- 21
koharu
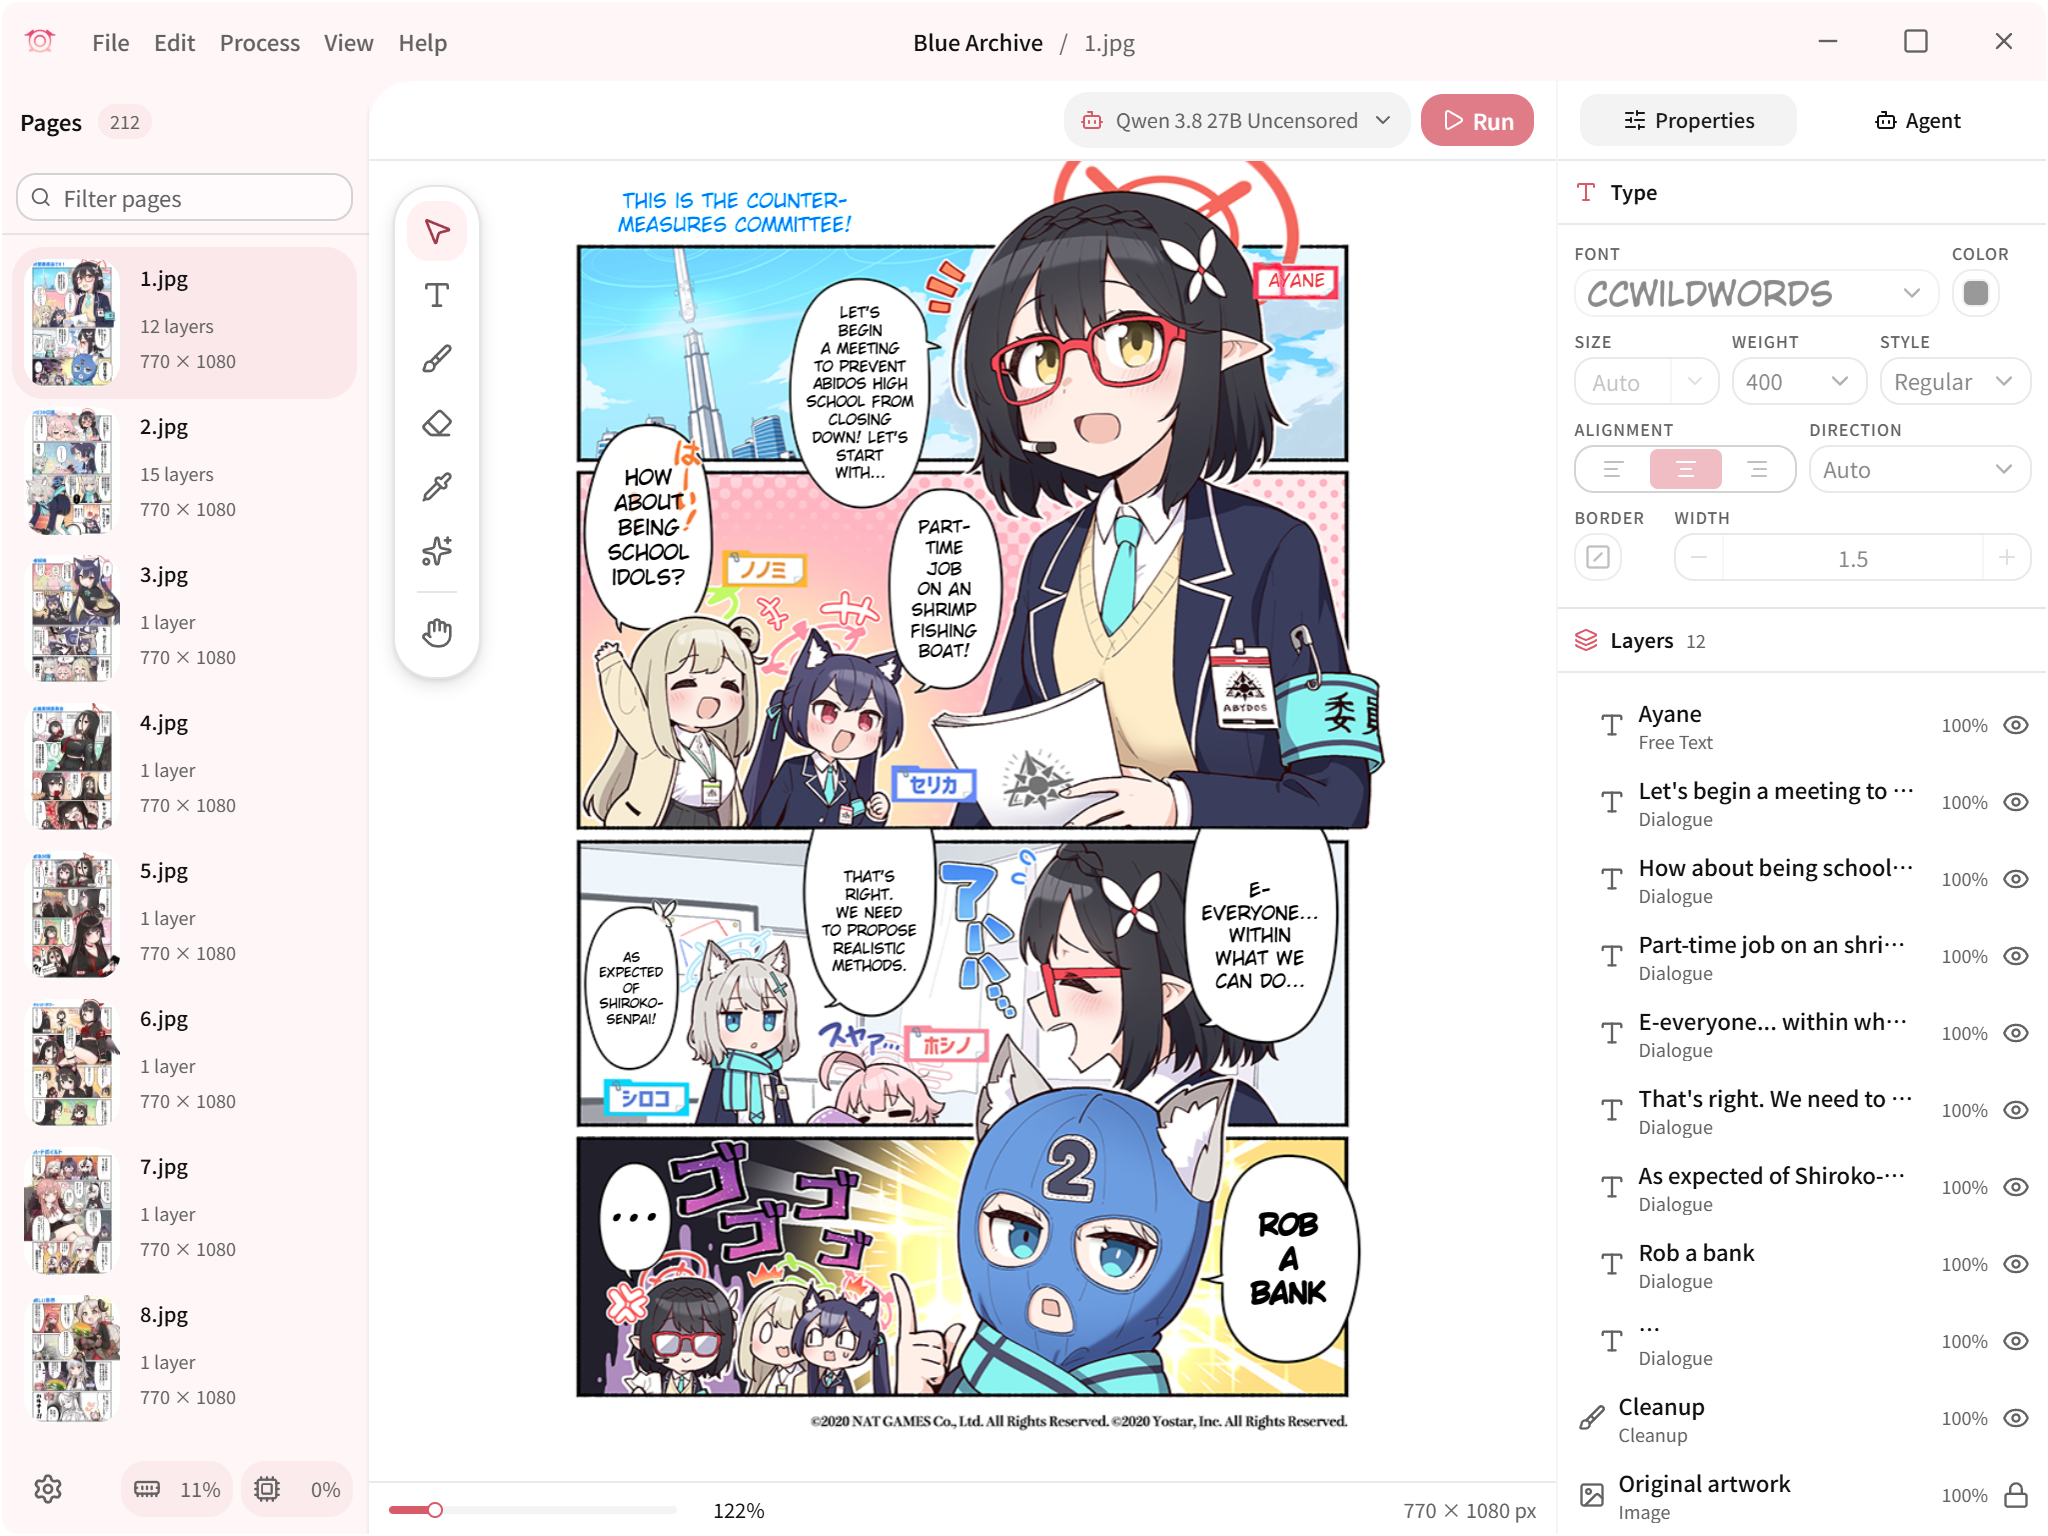
6.4Kkoharu-rs/koharu · RustKoharu is an ML-powered manga translator written in Rust that combines object detection, OCR, inpainting, and LLMs to automate translating manga pages while running everything locally.
- 22

Bonsai-demo
3.4KPrismML-Eng/Bonsai-demo · ShellBonsai Demo is a local-inference demo for Bonsai 2 27B, a ternary-weight large language model that runs on a laptop or single GPU via llama.cpp or MLX, with chat, vision, and agentic tool-calling support out of the box.
- 23
halogen-flash-server
1Kpeonist-ai/halogen-flash-server · Shellhalogen-flash-server is a purpose-built inference server for running the Qwen3.8-Flash-Next model as fast as possible on AMD's Strix Halo (gfx1151) GPU, exposing an OpenAI-compatible API.
- 24
project-maya
954mw00/project-maya · C++Project Maya lets you run GLM-5.3-Flash, a 321-billion-parameter mixture-of-experts AI model, on your own NVIDIA GPU(s) by streaming the model's experts across VRAM, RAM and NVMe SSD as the conversation needs them.
- 25
gufo
781gufo-org/gufo · C++Gufo is a local inference engine built specifically for AMD Strix Halo hardware (Ryzen AI MAX+ 395 with Radeon 8060S / gfx1151, up to 128 GiB unified memory), serving text, speech, image and video models through an OpenAI-compatible API.
- 26
verl
716XiaomiMiMo/verl · Pythonverl is an open-source RL post-training framework for large language models, started by ByteDance Seed as the open-source version of the HybridFlow paper. This XiaomiMiMo fork adds agentic RL training code for MiMo, with reproduction code for five RL environments on top of verl 0.9.0.dev.
- 27

qwen38-mtp
363sudoingX/qwen38-mtp · PythonThis repo documents a single llama.cpp server flag that unlocks multi-token-prediction (MTP) speculative decoding for Qwen3.8-27B, giving +33% to +145% faster decode on consumer GPUs. It bundles the exact launch command, a crowdsourced benchmark table across dozens of GPUs, and a probe.py script for measuring the gain yourself.
- 28

CUDA-for-AMD-Windows
321Speedstu/CUDA-for-AMD-Windows · PythonA Windows compatibility stack that runs CUDA-targeted applications on AMD GPUs via ZLUDA plus AMD ROCm/HIP, with tooling to verify the work truly executes on the GPU instead of silently falling back to CPU or producing wrong results.
- 29

d4r
288countervolts/d4r · C++d4r runs NVIDIA's official DLSS Super Resolution library inside Windows games on AMD Radeon GPUs under Linux and Proton, translating the DLSS network through ZLUDA (CUDA on ROCm/HIP) and replacing the heaviest kernels with hand-written RDNA3/RDNA4 code. It supports the DLSS 3 CNN model and the DLSS 4/4.5 transformer models; DLSS 5 is not supported.
- 30
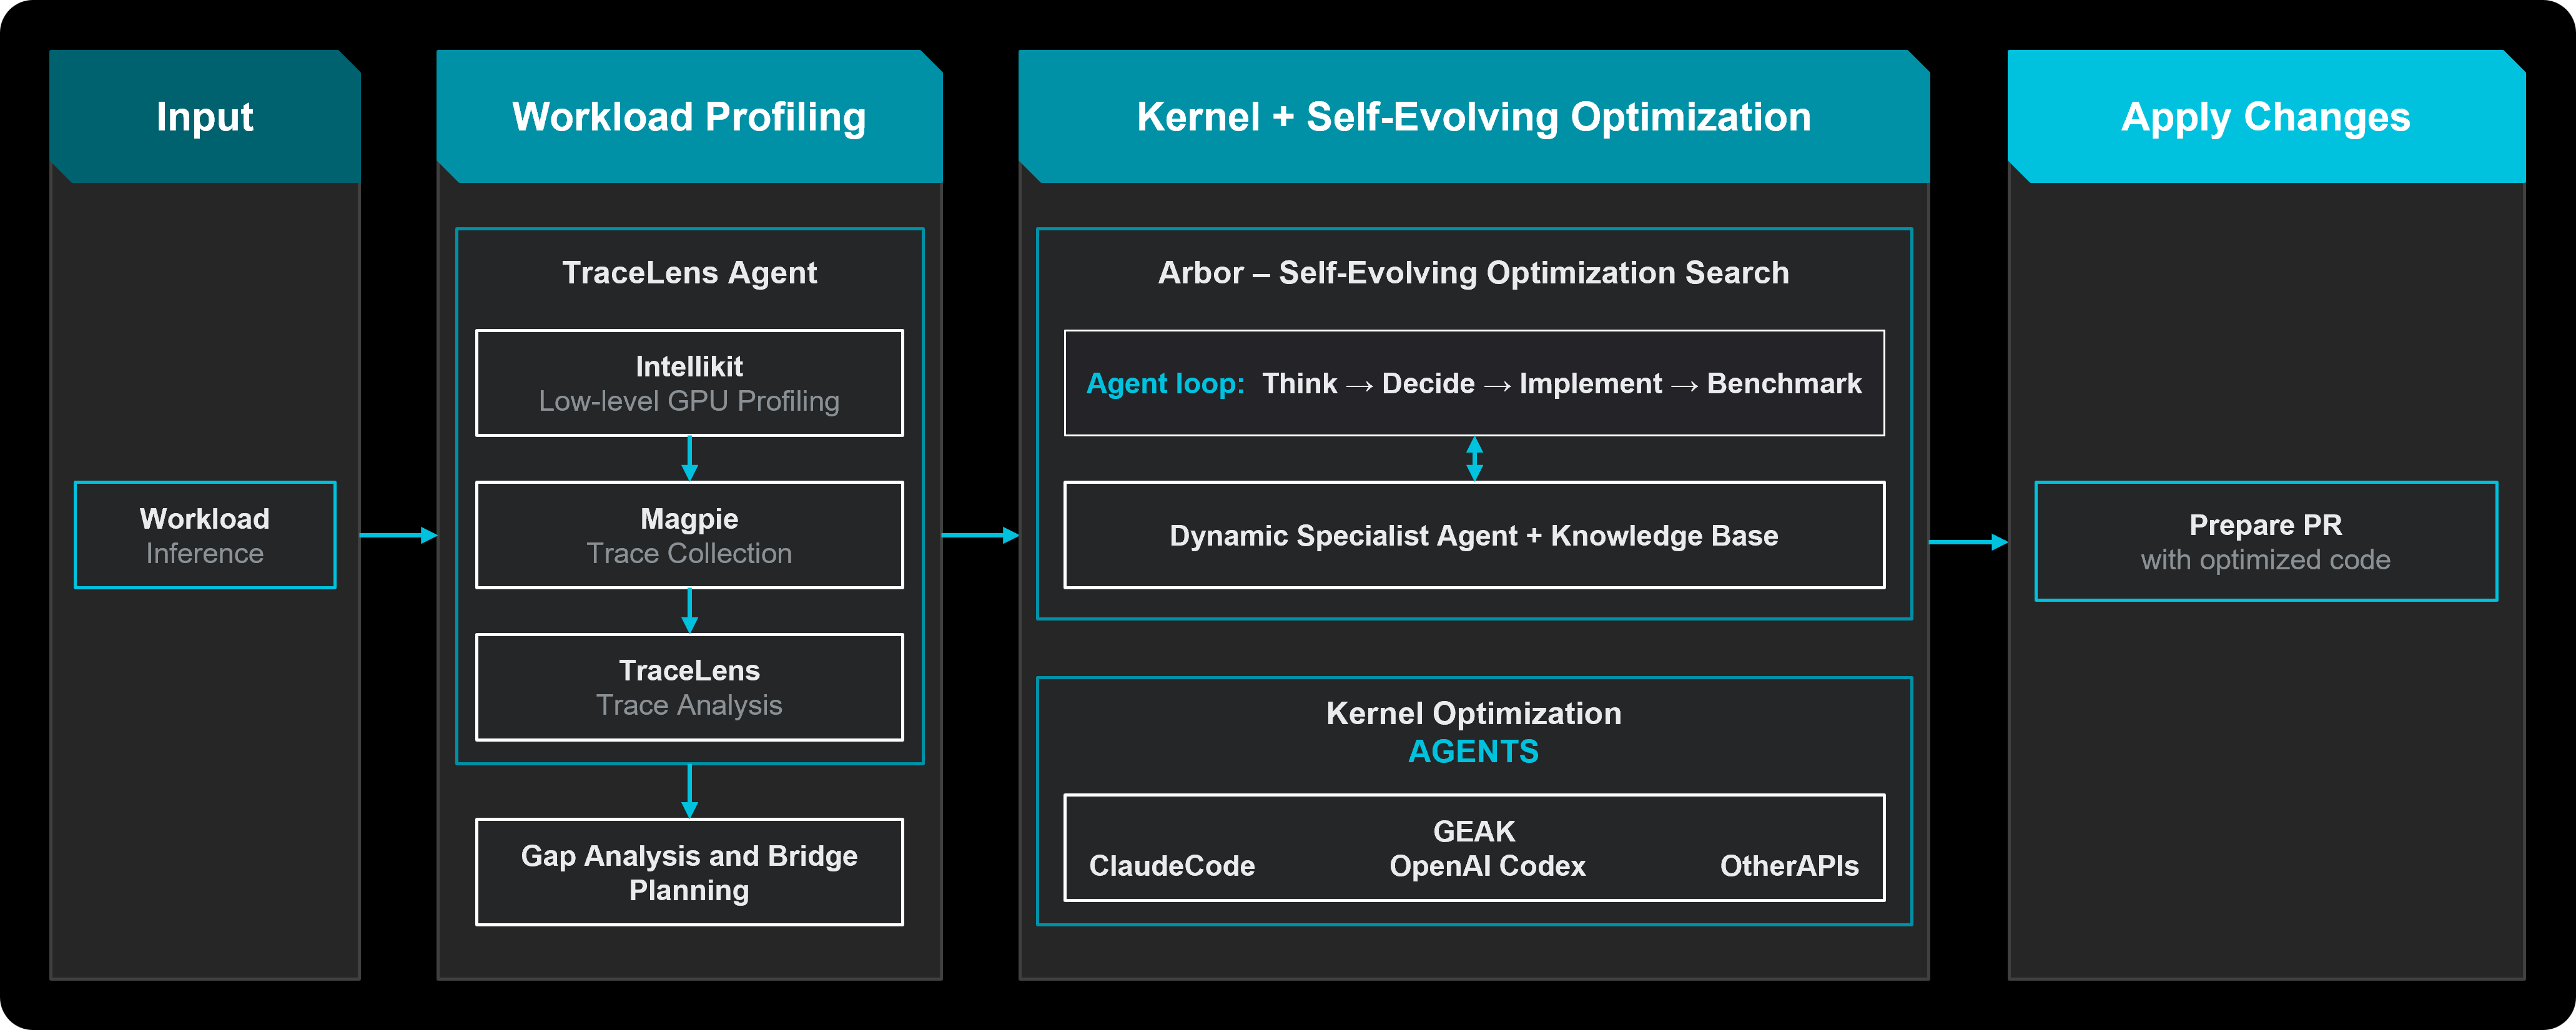
Hyperloom
241AMD-AGI/Hyperloom · PythonA multi-agent harness that autonomously optimizes LLM inference on AMD Instinct GPUs: it profiles your workload, searches framework and GPU-kernel optimizations, validates every candidate end to end, and saves proven results into a recipe knowledge base.
- 31
Bud-Decision-Studio
110BudEcosystem/Bud-Decision-Studio · HTMLBud Decision Studio is a cross-platform desktop app and local serving system for 'decision models' (Jev-like 'System One' models): you give it a situation and typed questions, and it returns a calibrated probability for every allowed answer instead of generated text.
Related topics
Often tagged together