Topics / #attention
Attention projects on GitHub
The attention operation that lets models weigh input context dynamically.
As of , the most-starred Attention projects on GitHub are annotated_deep_learning_paper_implementations (67.6K stars), LLM101n (37.5K stars) and sglang (37.2K stars). GitHub.Locker tracks 19 Attention repositories with 296.4K stars combined. The fastest-growing on October 16 was sglang, with +38 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +38
sglang
sgl-project/sglang · ★ 37.2KSGLang is a high-performance serving framework for large language models and multimodal models, built to deliver low-latency, high-throughput inference from a single GPU up to large distributed clusters.
 +10
zero-to-sglang
datawhalechina/zero-to-sglang · ★ 1.5KThe official SGLang x Datawhale course on LLM inference: it teaches how inference engines work, has you build a mini-sglang from scratch, and then digs into the real SGLang source code.
 +6
Attention-Residuals
MoonshotAI/Attention-Residuals · ★ 3.5KAttnRes (Attention Residuals) is a drop-in replacement for standard residual connections in Transformers, letting each layer use learned, input-dependent attention over all previous layer outputs instead of simple additive accumulation.
 +6
mini-AGI
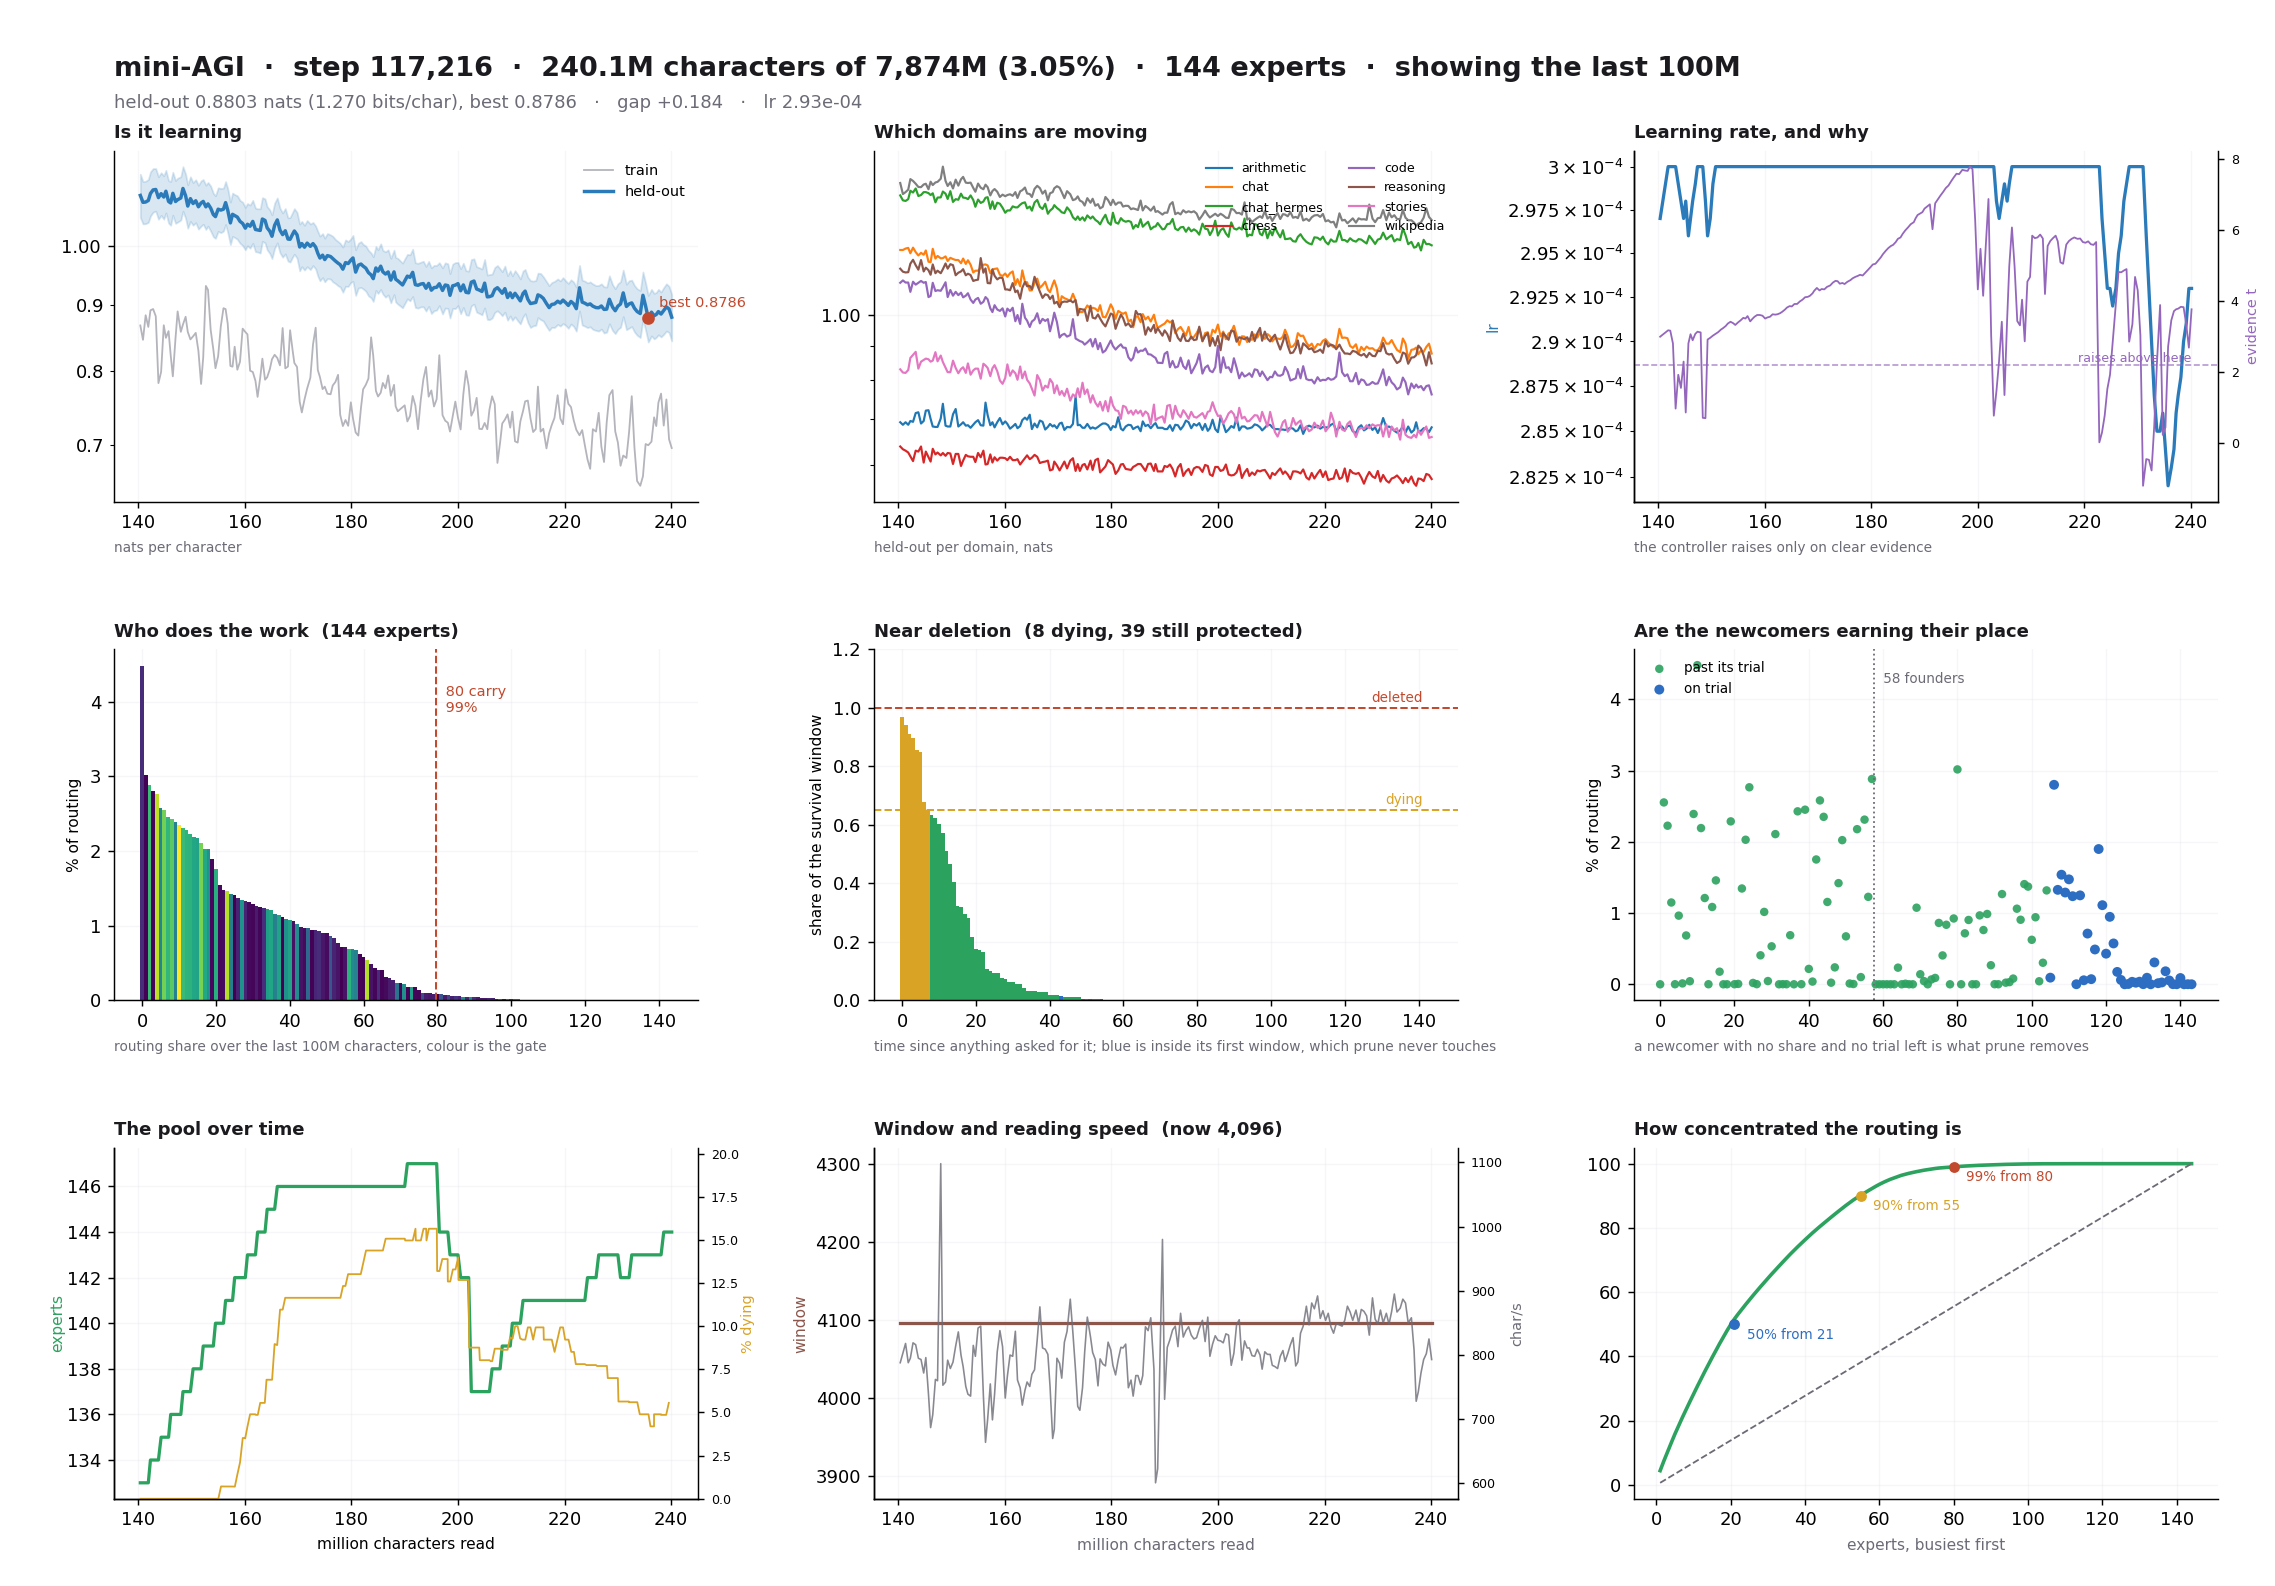
volotat/mini-AGI · ★ 1.2Kmini-AGI is a continual learning, byte-level language model that assembles its own architecture, trains from scratch on a single 8GB VRAM GPU, and keeps learning from everything it reads, without a separate fine-tuning phase.
The all-time top
19 projects · by stars
- 67.6K
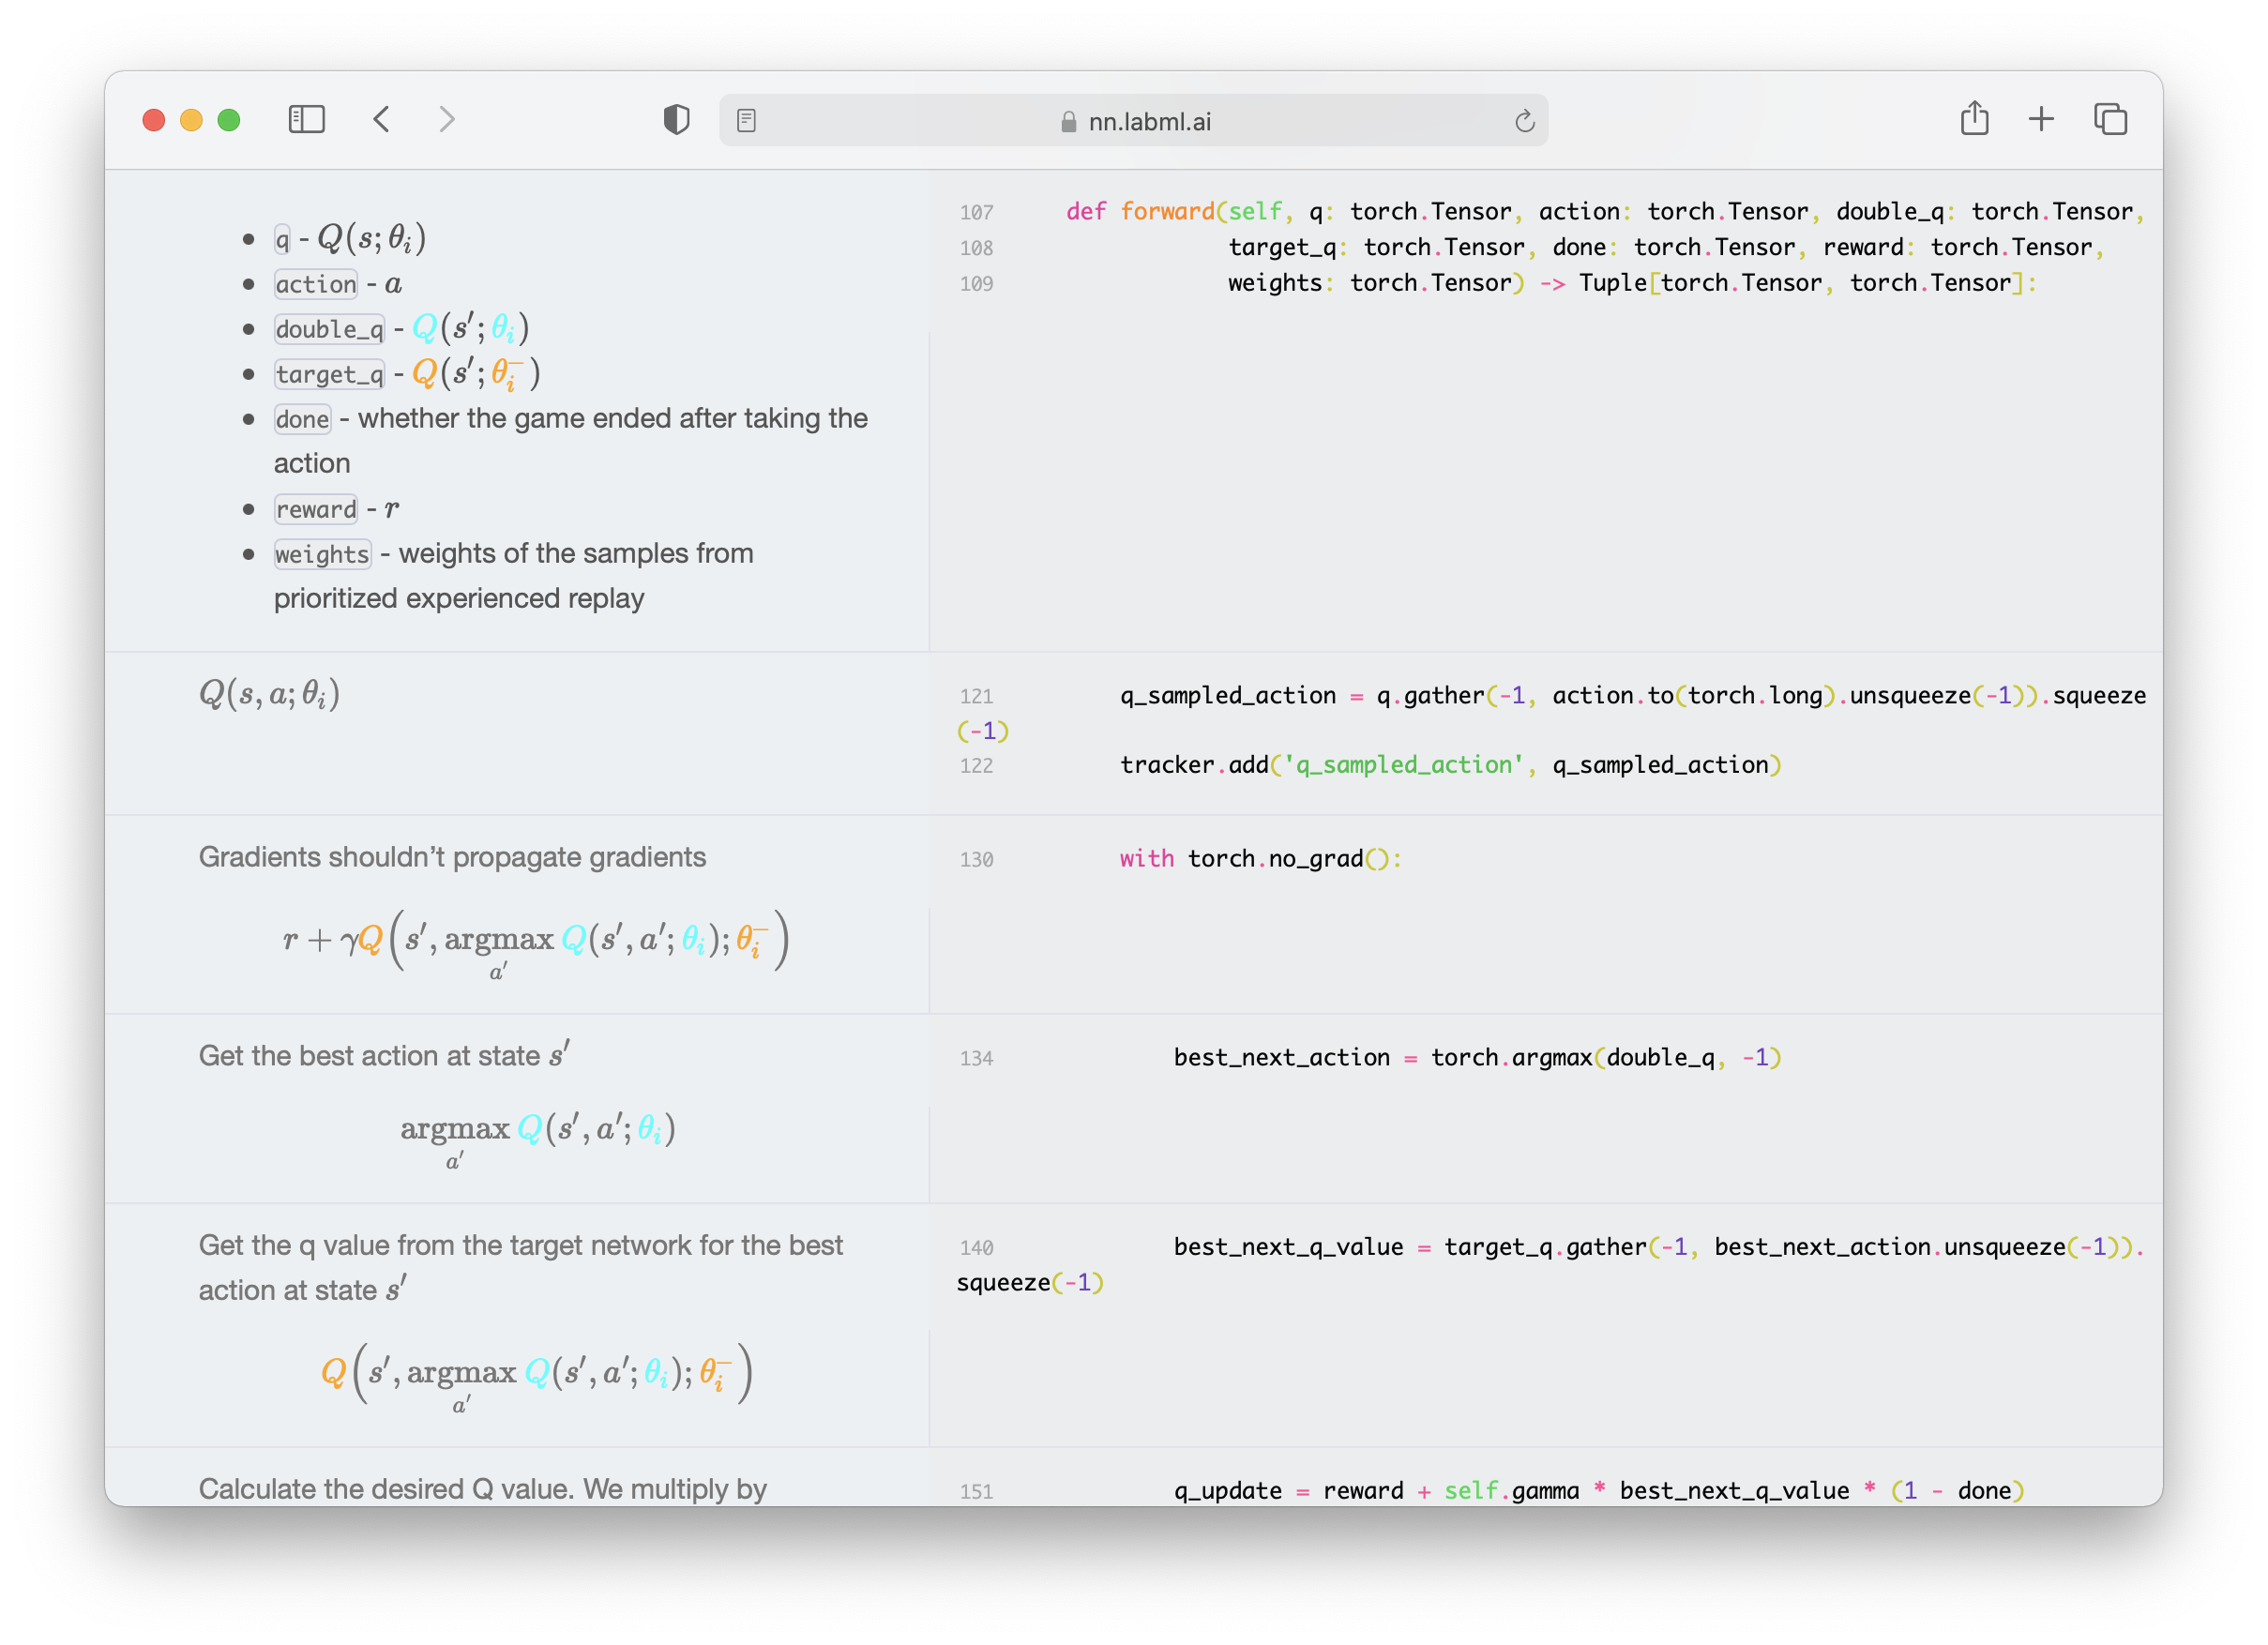 #1 · labmlai/annotated_deep_learning_paper_implementations
annotated_deep_learning_paper_implementations
A collection of 60+ PyTorch implementations of deep learning papers, each annotated with side-by-side explanatory notes so you can read the code and the math/explanation together.
- 37.5K
 #2 · karpathy/LLM101n
LLM101n
LLM101n is a planned course by Andrej Karpathy that walks through building a 'Storyteller' AI language model end-to-end, from basics all the way to a ChatGPT-like web app, implemented from scratch in Python, C and CUDA.
- 37.2K#3 · sgl-project/sglang
sglang
SGLang is a high-performance serving framework for large language models and multimodal models, built to deliver low-latency, high-throughput inference from a single GPU up to large distributed clusters.
- 4
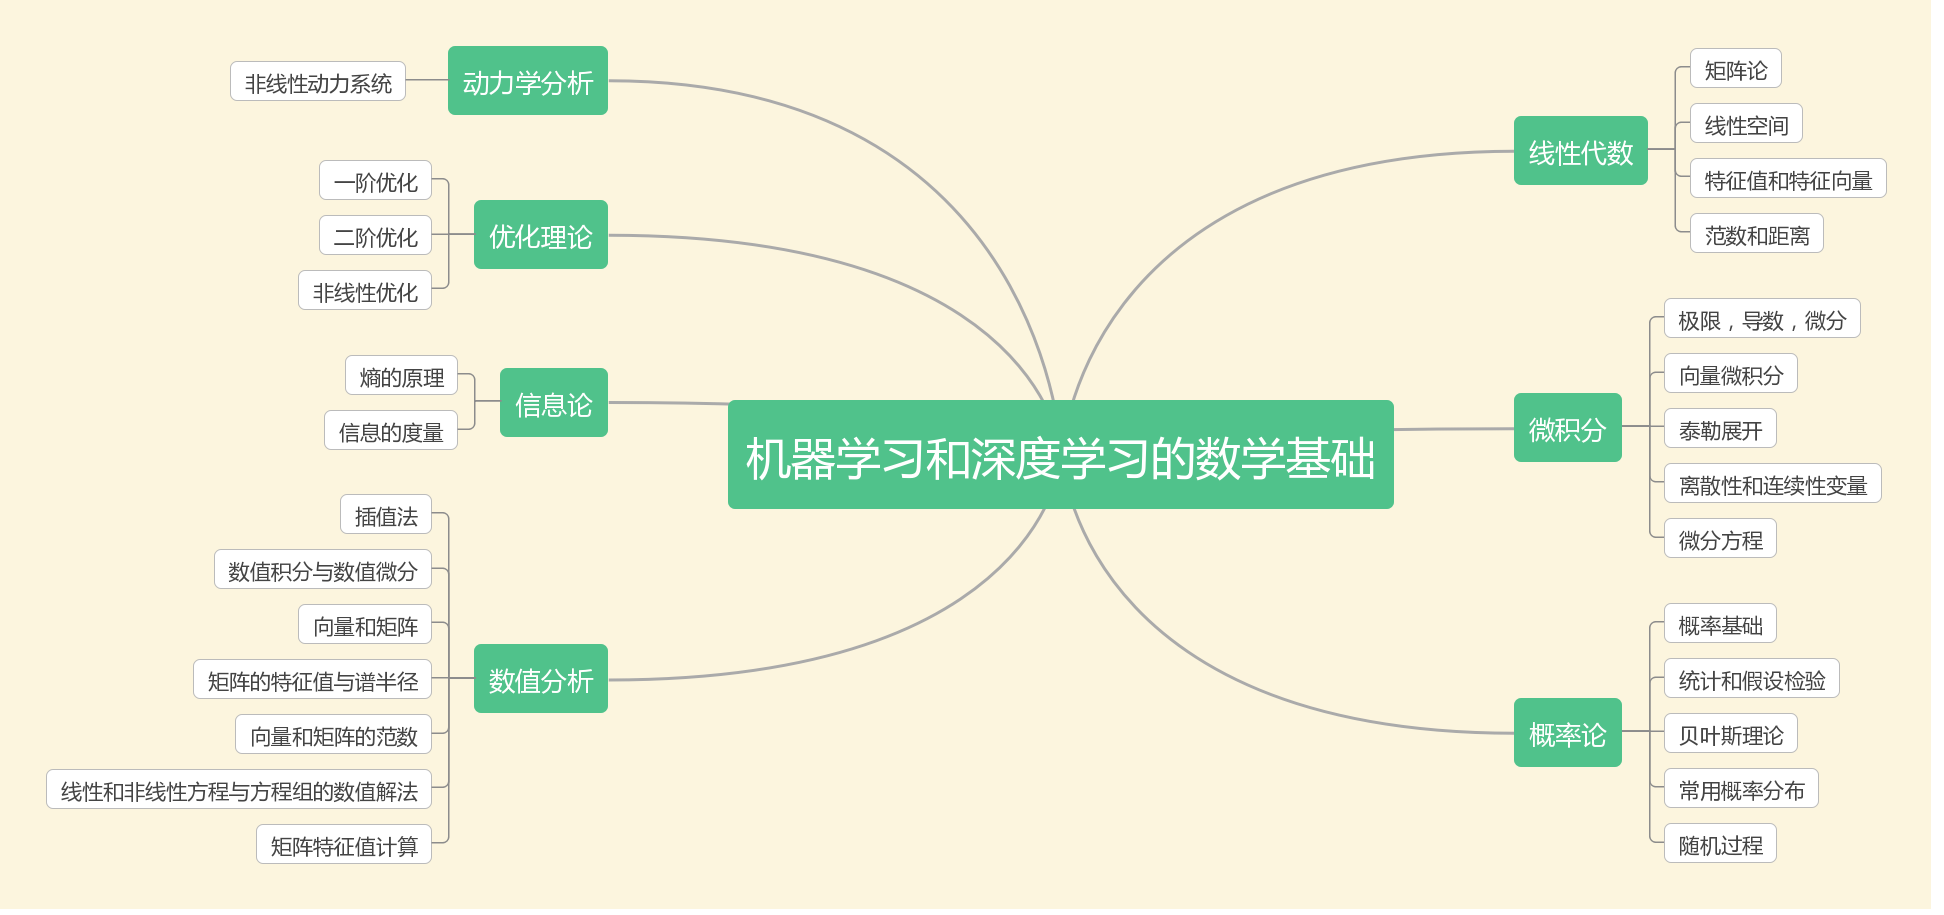
DeepLearning
17.8KMikoto10032/DeepLearning · Jupyter NotebookA Chinese-language deep learning tutorial — a huge curated collection of links to courses, books, lecture notes, surveys and code, taking you from math basics through CNNs, GANs, RNNs and GNNs to Kaggle practice and interview prep.
- 5

numpy-ml
16.3Kddbourgin/numpy-ml · PythonA collection of machine learning algorithms — Gaussian mixture models, HMMs, neural networks, tree ensembles, reinforcement learning agents and more — implemented from scratch in pure NumPy.
- 6

lectures
15.9Koxford-cs-deepnlp-2017/lecturesThe lecture slides and course description for the Deep Natural Language Processing course offered in Hilary Term 2017 at the University of Oxford: an advanced, applied NLP course organised by Phil Blunsom and delivered in partnership with the DeepMind Natural Language Research Group.
- 7

llama3-from-scratch
15.2Knaklecha/llama3-from-scratch · Jupyter NotebookA Jupyter notebook that implements Llama3 entirely from scratch, building up every matrix multiplication by hand instead of calling pre-built transformer modules.
- 8

nlp-tutorial
14.9Kgraykode/nlp-tutorial · Jupyter NotebookA collection of short PyTorch implementations covering core NLP and deep learning models, from word embeddings to Transformers and BERT, meant as a study resource.
- 9

OpenMythos
14.9Kkyegomez/OpenMythos · PythonOpenMythos is an open-source, speculative PyTorch implementation that tries to reconstruct the internal architecture of Anthropic's Claude ('Mythos') purely from publicly available research papers, not from any leaked or official Anthropic code.
- 10
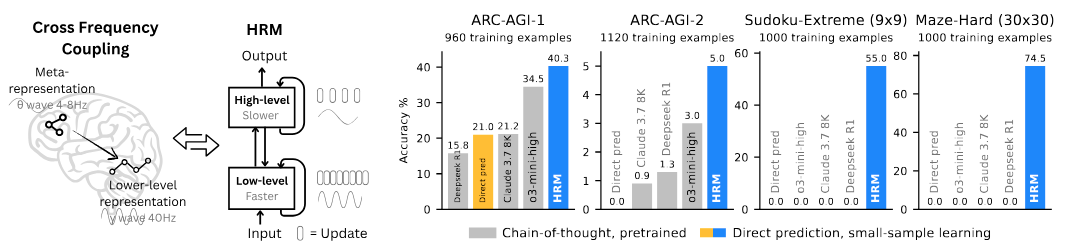
HRM
12.7Ksapientinc/HRM · PythonThe official release of the Hierarchical Reasoning Model (HRM): a brain-inspired recurrent architecture that reaches significant computational depth with only 27 million parameters, trained on ~1000 examples without pretraining or chain-of-thought data.
- 11
Open-Sora-Plan
12.2KPKU-YuanGroup/Open-Sora-Plan · PythonOpen-Sora Plan is an open-source community project that aims to reproduce OpenAI's Sora text-to-video model, led by a PKU-affiliated AIGC lab with contributions from Huawei and Pengcheng Lab.
- 12
External-Attention-pytorch
12.2Kxmu-xiaoma666/External-Attention-pytorch · PythonA PyTorch collection of Attention, Backbone, MLP, Re-parameter, and Convolution implementations from research papers, meant to help you understand papers by seeing their mechanisms coded up.
- 13

xformers
10.6Kfacebookresearch/xformers · PythonxFormers is Meta's (Facebook Research) toolbox of hackable, optimized Transformer building blocks that you compose together — reusable pieces for your own models rather than a monolithic framework.
- 14
Attention-Residuals
3.5KMoonshotAI/Attention-ResidualsAttnRes (Attention Residuals) is a drop-in replacement for standard residual connections in Transformers, letting each layer use learned, input-dependent attention over all previous layer outputs instead of simple additive accumulation.
- 15
MSA
3.5KEverMind-AI/MSA · PythonMSA (Memory Sparse Attention) is an end-to-end trainable, scalable latent-memory framework that lets LLMs handle context windows up to 100M tokens, replacing RAG or fixed-size RNN-style memory with a differentiable sparse-attention memory bank.
- 16
zero-to-sglang
1.5Kdatawhalechina/zero-to-sglang · PythonThe official SGLang x Datawhale course on LLM inference: it teaches how inference engines work, has you build a mini-sglang from scratch, and then digs into the real SGLang source code.
- 17
jevlike
1.4Kvinnylarouge/jevlike · PythonA small research model that reads a piece of text plus a list of options and returns a probability for each option in one pass, instead of writing an answer token by token.
- 18
mini-AGI
1.2Kvolotat/mini-AGI · Pythonmini-AGI is a continual learning, byte-level language model that assembles its own architecture, trains from scratch on a single 8GB VRAM GPU, and keeps learning from everything it reads, without a separate fine-tuning phase.
- 19

LeVJEPA
270MLO-lab/LeVJEPA · Jupyter NotebookThe official implementation of LeVJEPA — a self-supervised video encoder trained with LeJEPA's collapse-free objective. Unlike V-JEPA or VideoMAE it needs no EMA target encoder, stop-gradient, predictor, or pixel-reconstruction decoder: just an encoder, a small projector, and one loss hyperparameter.
Related topics
Often tagged together
- deep-learning737
- python2,383
- machine-learning916
- transformer212
- research764
- ai1,955
- pytorch419
- gpu789
- nlp214
- llm1,483
- cuda396
- education933
- open-source5,666
- attention-mechanism53
- mit3,312
- neural-network166
- large-language-models213
- reinforcement-learning149
- artificial-intelligence267
- neural-networks57
- tutorial626
- academic-research209
- benchmark431
- chinese1,159