Topics / #voice-activity-detection
Voice-activity-detection projects on GitHub
Models and tools that detect speech presence in audio streams.
As of , the most-starred Voice-activity-detection projects on GitHub are FunASR (20.7K stars), WhisperLiveKit (11.1K stars) and Whisper (10.7K stars). GitHub.Locker tracks 9 Voice-activity-detection repositories with 85.9K stars combined. The fastest-growing on October 17 was FunASR, with +17 stars in a day.
Hot right now
Most stars gained in a day · Oct 17
FunASR
modelscope/FunASR · ★ 20.7KFunASR is an open-source industrial speech recognition toolkit covering ASR, VAD, punctuation, speaker diarization, and emotion/audio-event models, deployable offline, in streaming mode, on edge devices, or behind an OpenAI-compatible API.
 +8
pyannote-audio
pyannote/pyannote-audio · ★ 10.7KAn open-source Python toolkit for speaker diarization - working out who spoke when in an audio recording. It is built on PyTorch and ships state-of-the-art pretrained models and pipelines.
 +4
WhisperLiveKit
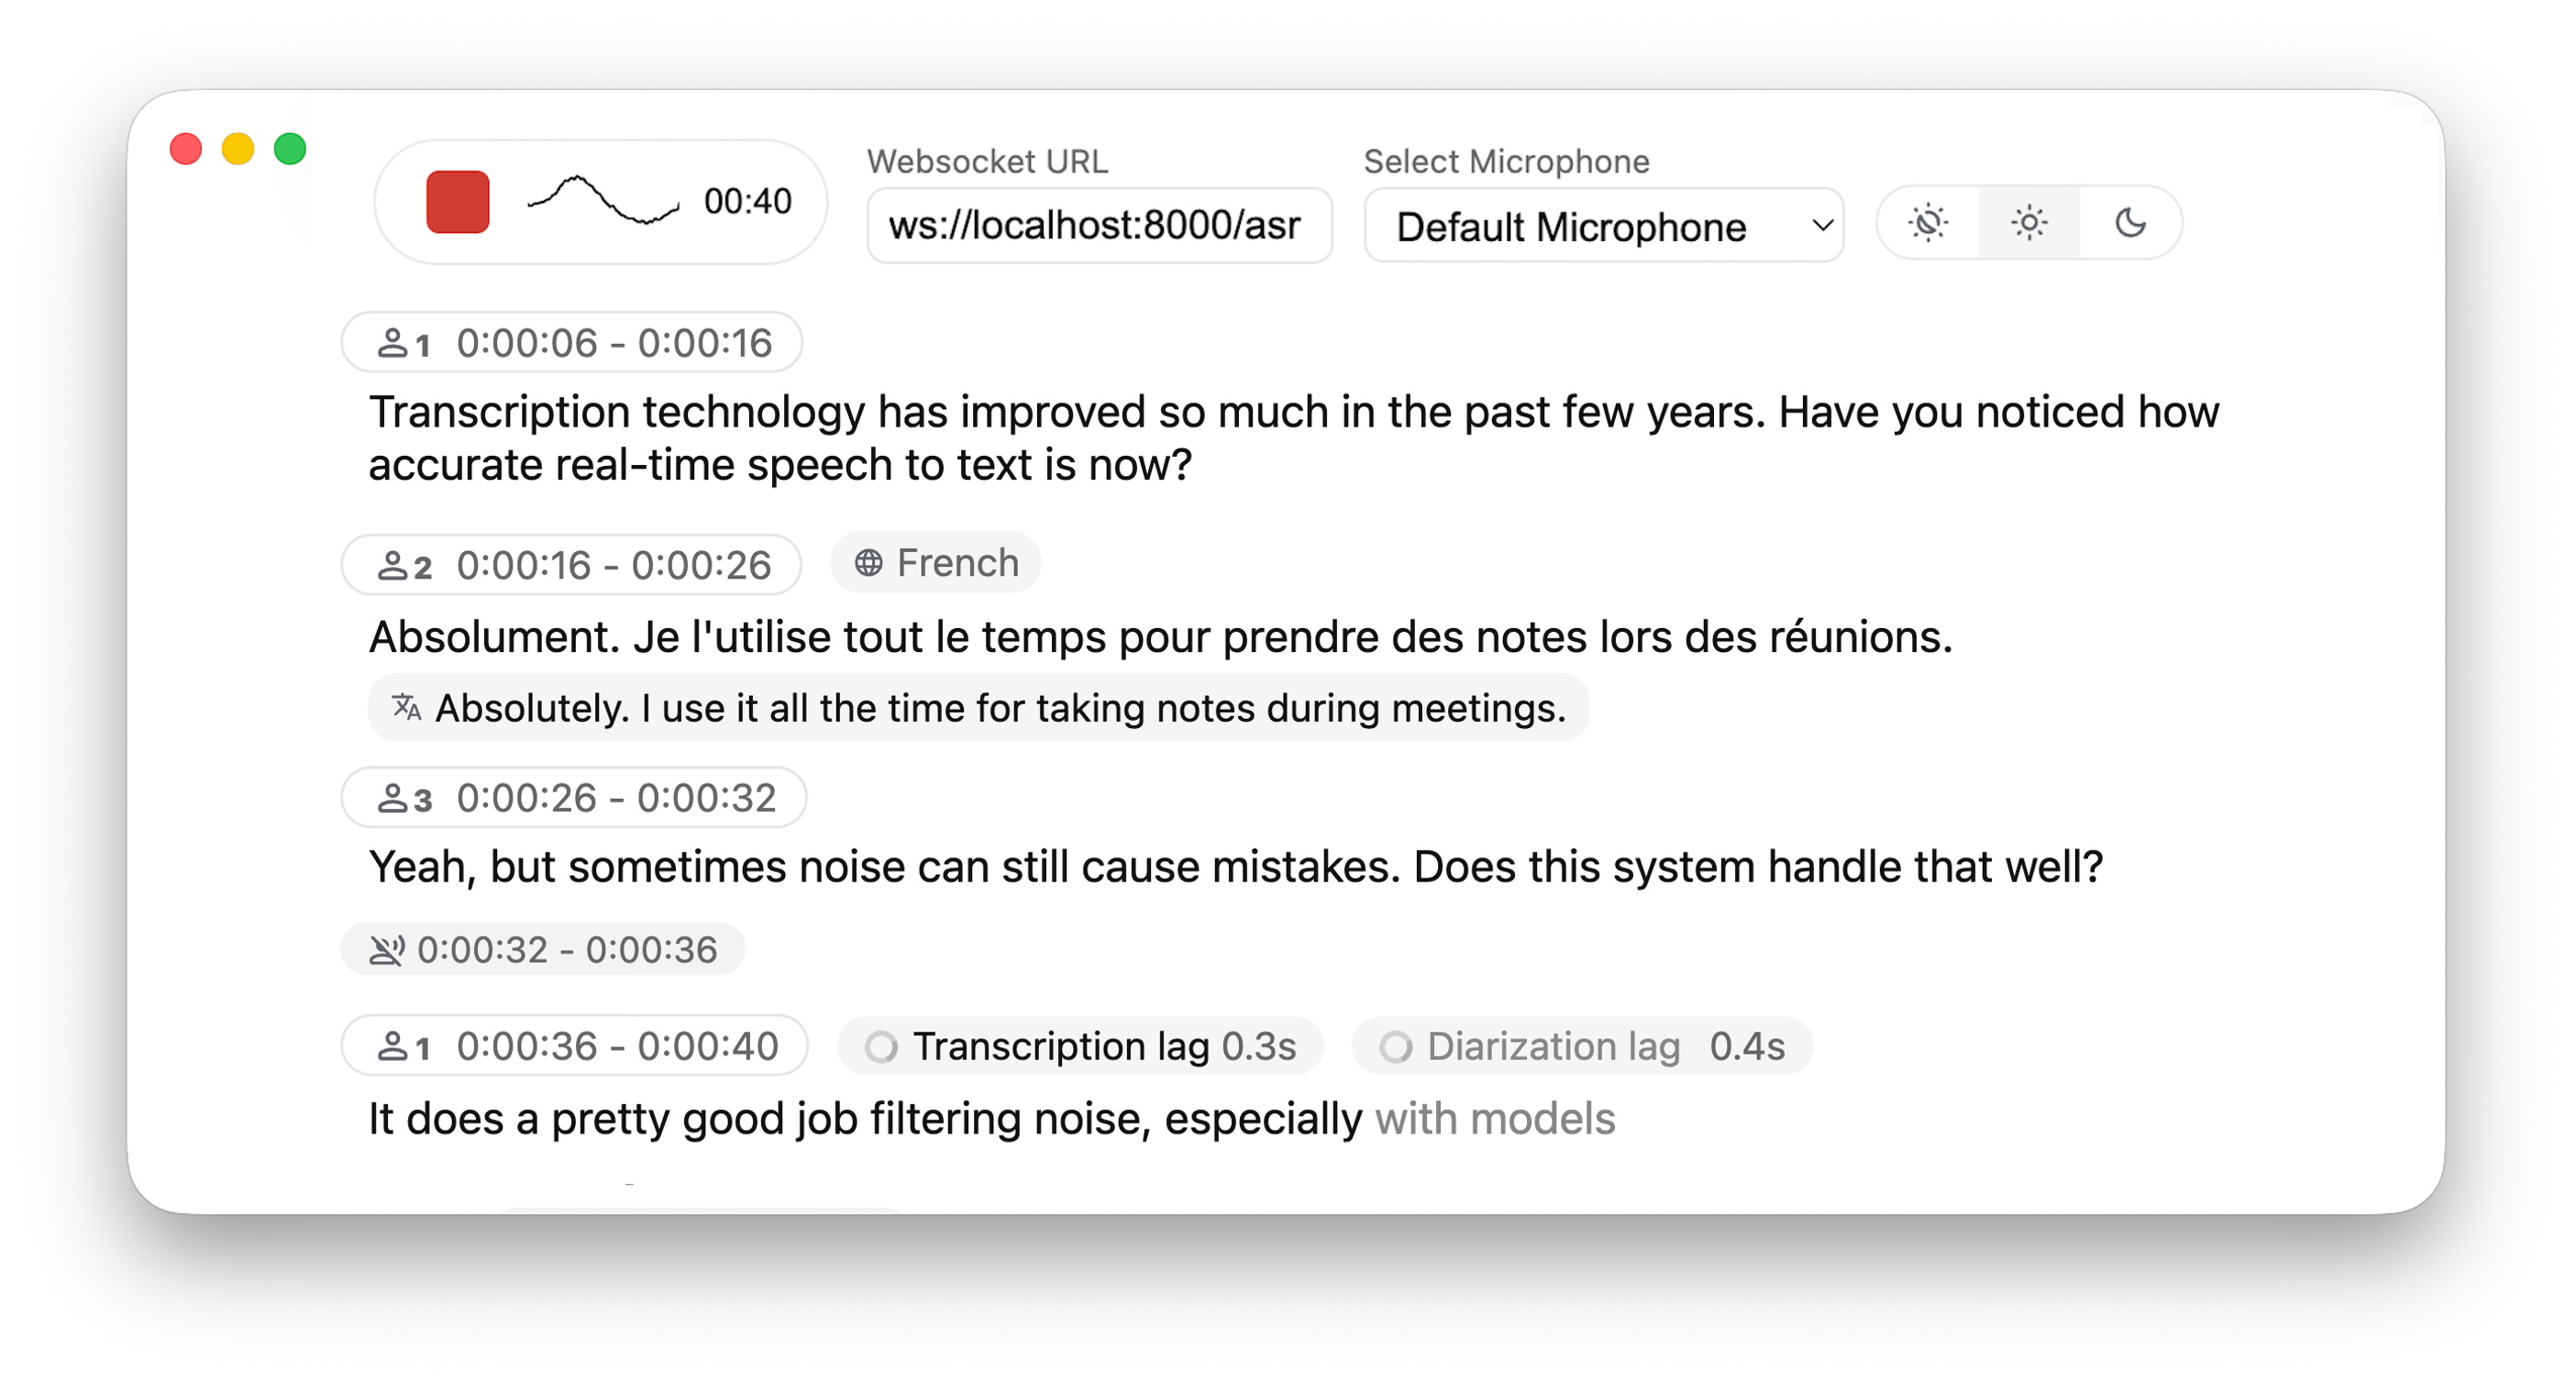
QuentinFuxa/WhisperLiveKit · ★ 11.1KWhisperLiveKit is a self-hosted pipeline for real-time, local speech-to-text with streaming ASR, speaker diarization, live translation, and OpenAI/Deepgram-compatible APIs.
 +4
silero-vad
snakers4/silero-vad · ★ 10.5KSilero VAD is a pre-trained, enterprise-grade Voice Activity Detector: a compact model that tells you which parts of an audio stream contain speech.
The all-time top
9 projects · by stars
- 20.7K
#1 · modelscope/FunASR
FunASR
FunASR is an open-source industrial speech recognition toolkit covering ASR, VAD, punctuation, speaker diarization, and emotion/audio-event models, deployable offline, in streaming mode, on edge devices, or behind an OpenAI-compatible API.
- 11.1K#2 · QuentinFuxa/WhisperLiveKit
WhisperLiveKit
WhisperLiveKit is a self-hosted pipeline for real-time, local speech-to-text with streaming ASR, speaker diarization, live translation, and OpenAI/Deepgram-compatible APIs.
- 10.7K
 #3 · Const-me/Whisper
Whisper
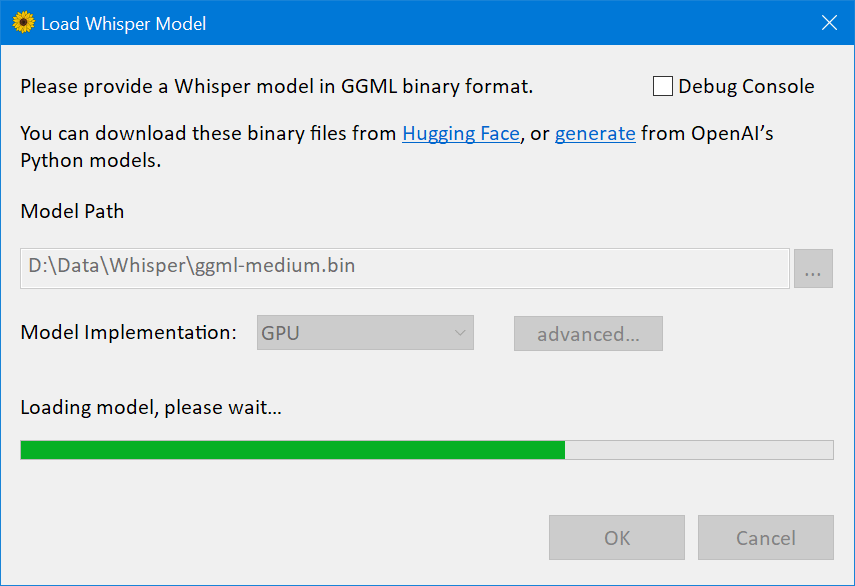
A Windows port of OpenAI's Whisper speech-recognition model that runs inference on the GPU using DirectCompute instead of CUDA, delivering much faster transcription than the official PyTorch implementation.
- 4
pyannote-audio
10.7Kpyannote/pyannote-audio · Jupyter NotebookAn open-source Python toolkit for speaker diarization - working out who spoke when in an audio recording. It is built on PyTorch and ships state-of-the-art pretrained models and pipelines.
- 5
silero-vad
10.5Ksnakers4/silero-vad · PythonSilero VAD is a pre-trained, enterprise-grade Voice Activity Detector: a compact model that tells you which parts of an audio stream contain speech.
- 6
NoiseTorch
10.3Knoisetorch/NoiseTorch · GoA Linux app that creates a virtual microphone with real-time noise suppression (RNNoise). Select it as input in Discord, OBS, Mumble or any app, and it filters out keyboard, fan and background noise.
- 7

RealtimeSTT
10.2KKoljaB/RealtimeSTT · PythonA Python speech-to-text library that turns microphone or streamed audio into text with low latency: voice activity detection, optional wake words, live partial text, and final transcripts in a few lines of code.
- 8
speech-swift
1.2Ksoniqo/speech-swift · SwiftLocal Speech AI on a MacBook — watch the 4-minute open-source library tour on YouTube
- 9
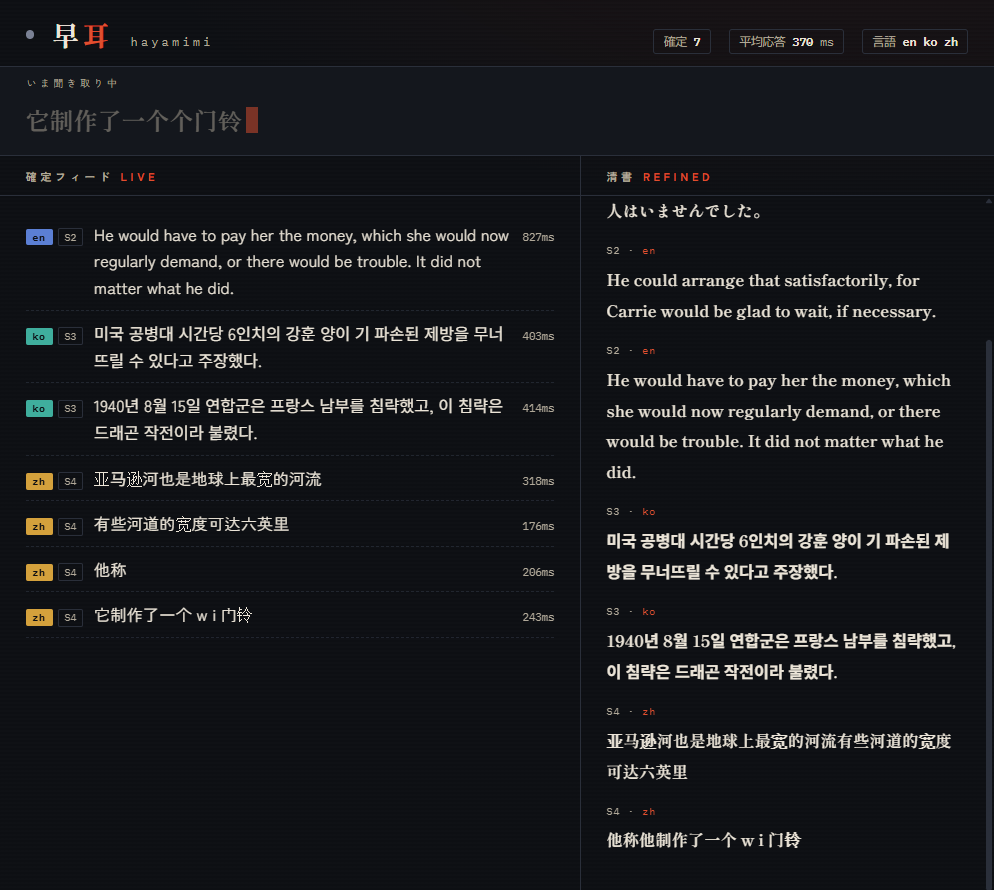
hayamimi
446oboroge0/hayamimi · Pythonhayamimi is a real-time, multilingual speech-to-text tool that runs entirely on CPU, giving you live subtitles, a browser dashboard, speaker labels, and on-the-fly translation without a GPU or cloud API.
Related topics
Often tagged together
- speech-recognition100
- gpu788
- machine-learning915
- python2,396
- asr33
- audio249
- open-source5,666
- speaker-diarization14
- deep-learning736
- library1,587
- linux4,181
- macos3,544
- mit3,311
- pytorch419
- real-time240
- self-hosted1,926
- speech-to-text89
- transcription45
- ai1,954
- api1,094
- audio-processing64
- cli2,227
- inference326
- multilingual214