Topics / #attention-mechanism
Attention-mechanism projects on GitHub
Attention mechanisms behind transformers and modern sequence models.
As of , the most-starred Attention-mechanism projects on GitHub are LLMs-from-scratch (106.8K stars), vllm (94K stars) and happy-llm (34.4K stars). GitHub.Locker tracks 53 Attention-mechanism repositories with 618.1K stars combined. The fastest-growing on October 17 was ComfyUI-Ref2VA-VSA, with +173 stars in a day.
Hot right now
Most stars gained in a day · Oct 17
 +173
ComfyUI-Ref2VA-VSA
Kablex/ComfyUI-Ref2VA-VSA · ★ 743It's a ComfyUI custom node that dramatically speeds up Reference-to-Video (Ref2VA) generation for the MiniMax H3 model, producing a full 5-second, 24fps character video in about 72 seconds on a single RTX 4090 instead of over 10 minutes.
 +82
llm-architecture-from-scratch
YeonwooSung/llm-architecture-from-scratch · ★ 961A collection of PyTorch implementations of modern LLM architectures (GPT-2, Llama 3/3.2, Llama 4, OLMo 2, Phi-4, DeepSeek v3, Gemma 3, xLSTM, Mistral 3.1) built from scratch to understand how they work internally.
 +72
LLMs-from-scratch
rasbt/LLMs-from-scratch · ★ 106.8KThis is the official code repository for the book 'Build a Large Language Model (From Scratch)', which teaches you to implement a GPT-like LLM in PyTorch step by step, from tokenization through pretraining and finetuning.
 +69
vllm
vllm-project/vllm · ★ 94KvLLM is a library for fast LLM inference and serving, built around PagedAttention for efficient memory management of attention keys and values.
The all-time top
53 projects · by stars
- 106.8K#1 · rasbt/LLMs-from-scratch
LLMs-from-scratch
This is the official code repository for the book 'Build a Large Language Model (From Scratch)', which teaches you to implement a GPT-like LLM in PyTorch step by step, from tokenization through pretraining and finetuning.
- 94K#2 · vllm-project/vllm
vllm
vLLM is a library for fast LLM inference and serving, built around PagedAttention for efficient memory management of attention keys and values.
- 34.4K
 #3 · datawhalechina/happy-llm
happy-llm
Happy-LLM is Datawhale's free open-source LLM course: a systematic tutorial that goes from NLP basics and the Transformer architecture to building and training your first large language model, then applying it with RAG and agents.
- 4

deep-learning-for-image-processing
26.4KWZMIAOMIAO/deep-learning-for-image-processing · PythonA video-based deep learning course that walks through classic computer-vision architectures for image classification, object detection, segmentation and keypoint detection, pairing each network with a lecture and runnable code.
- 5
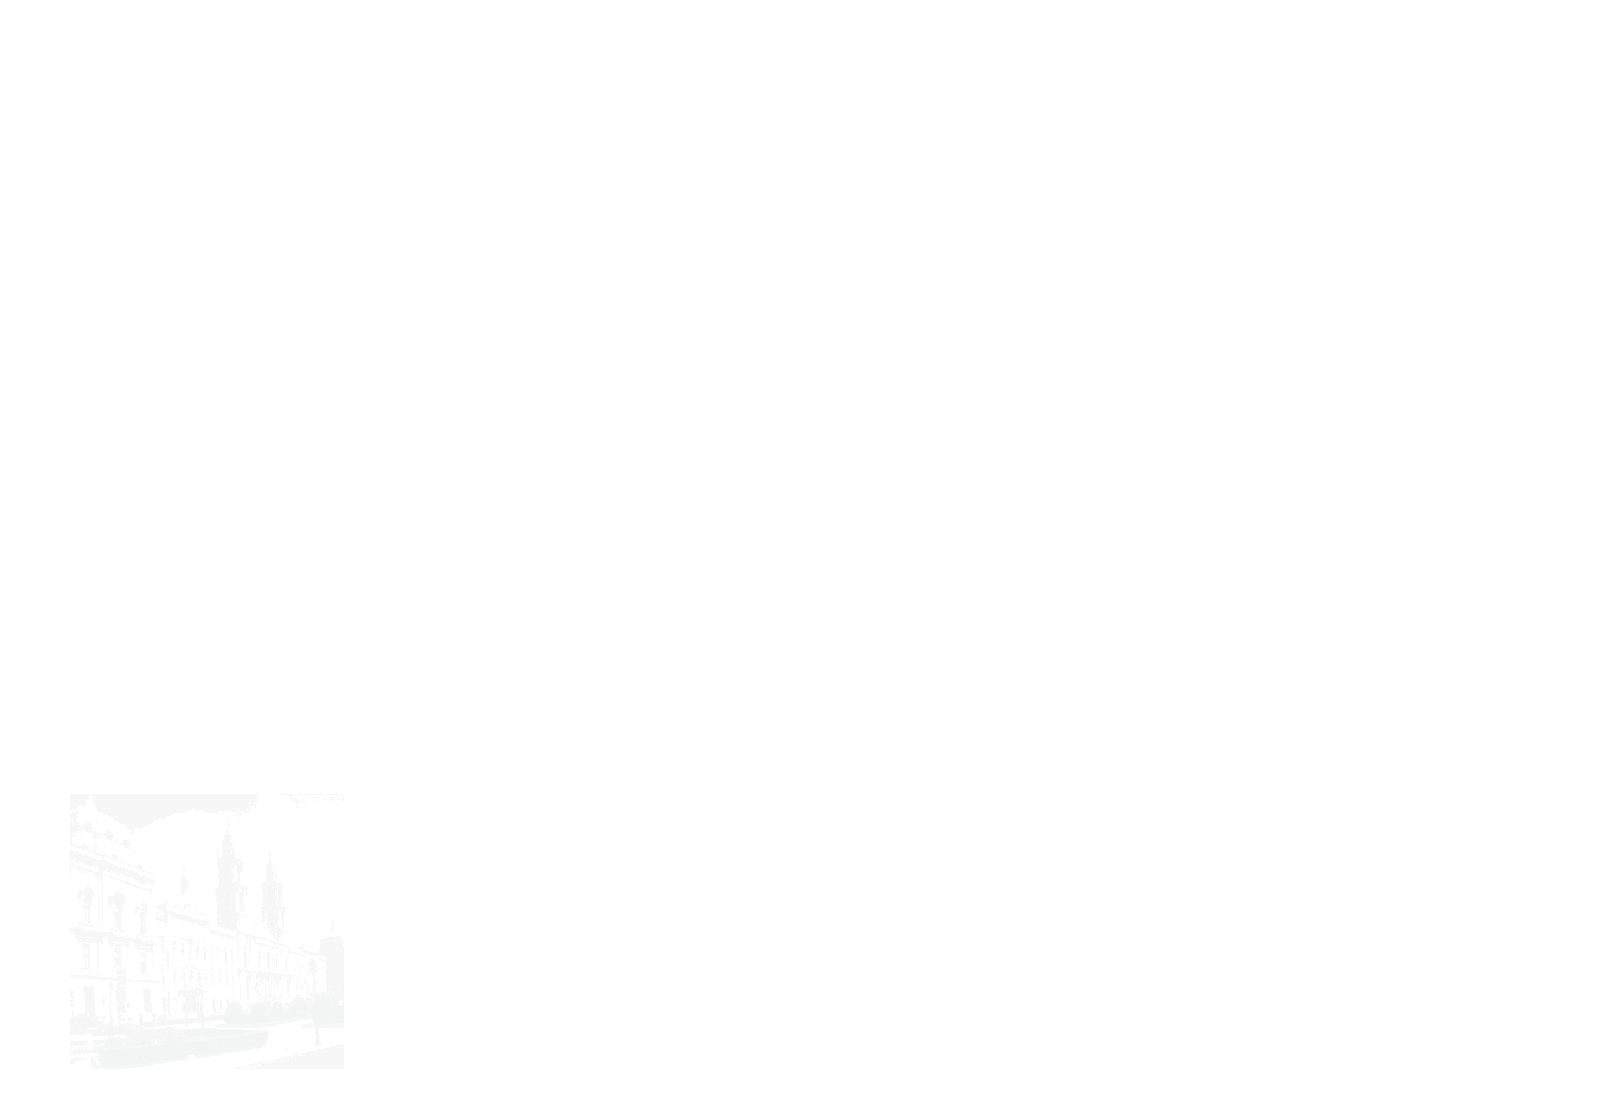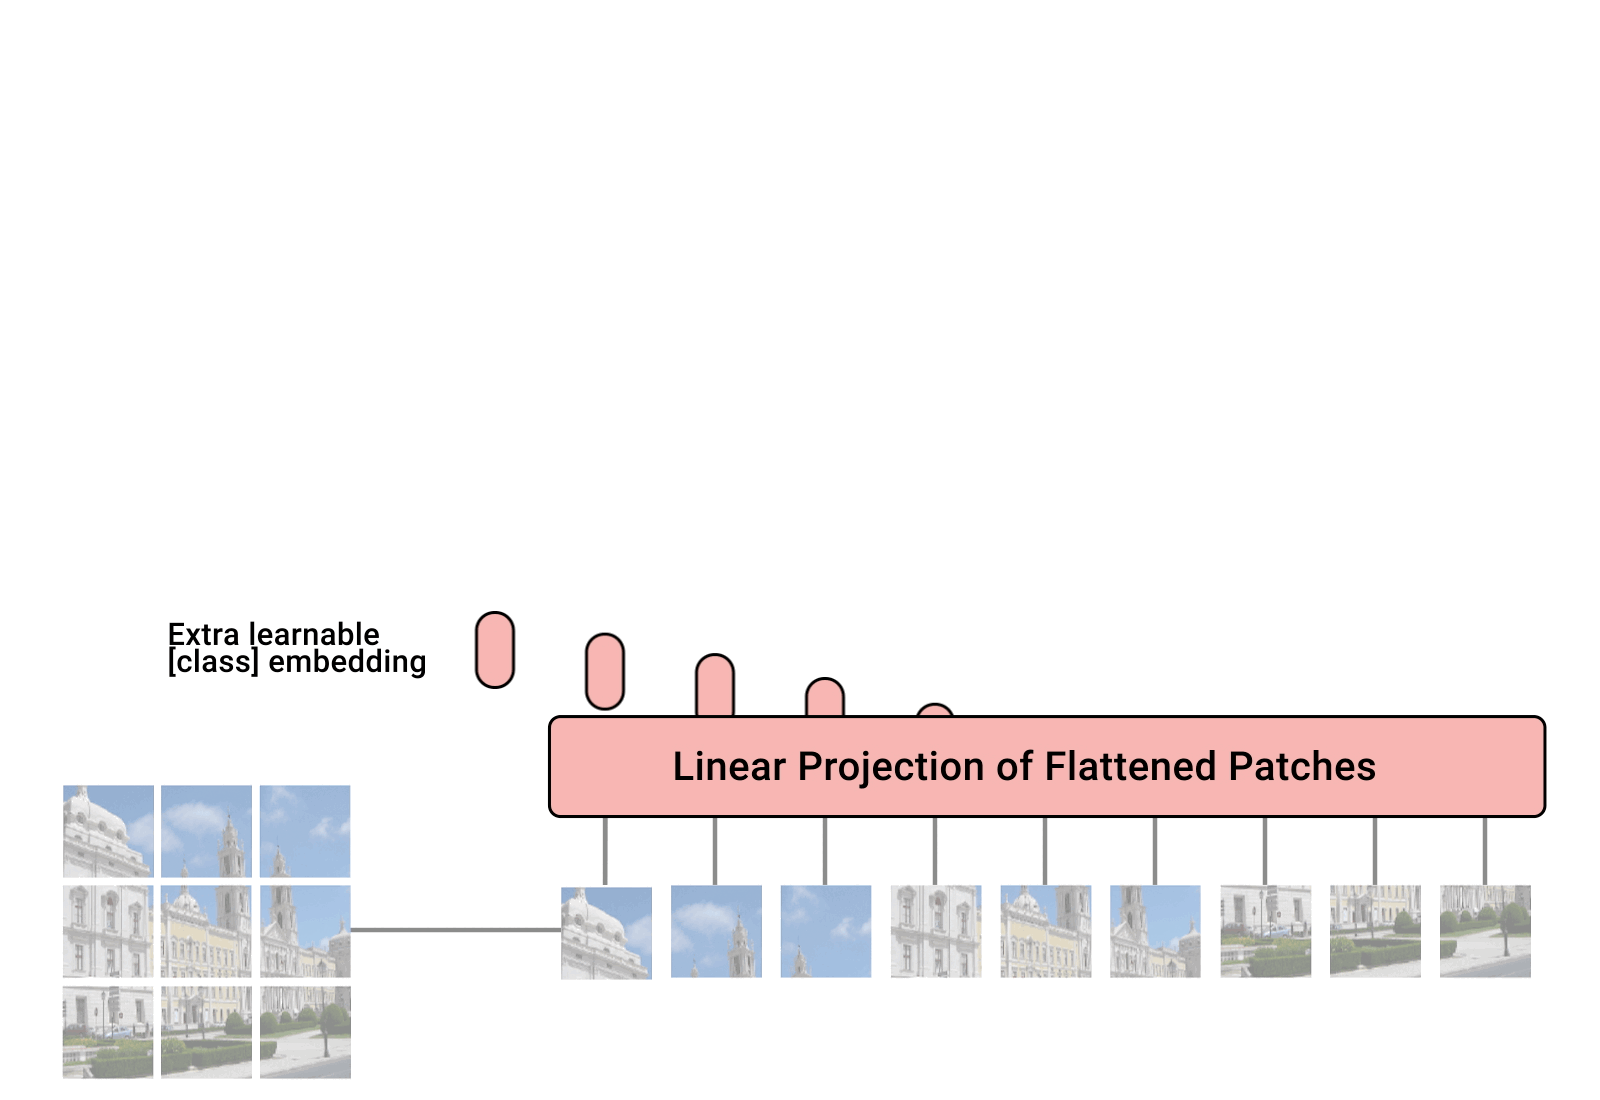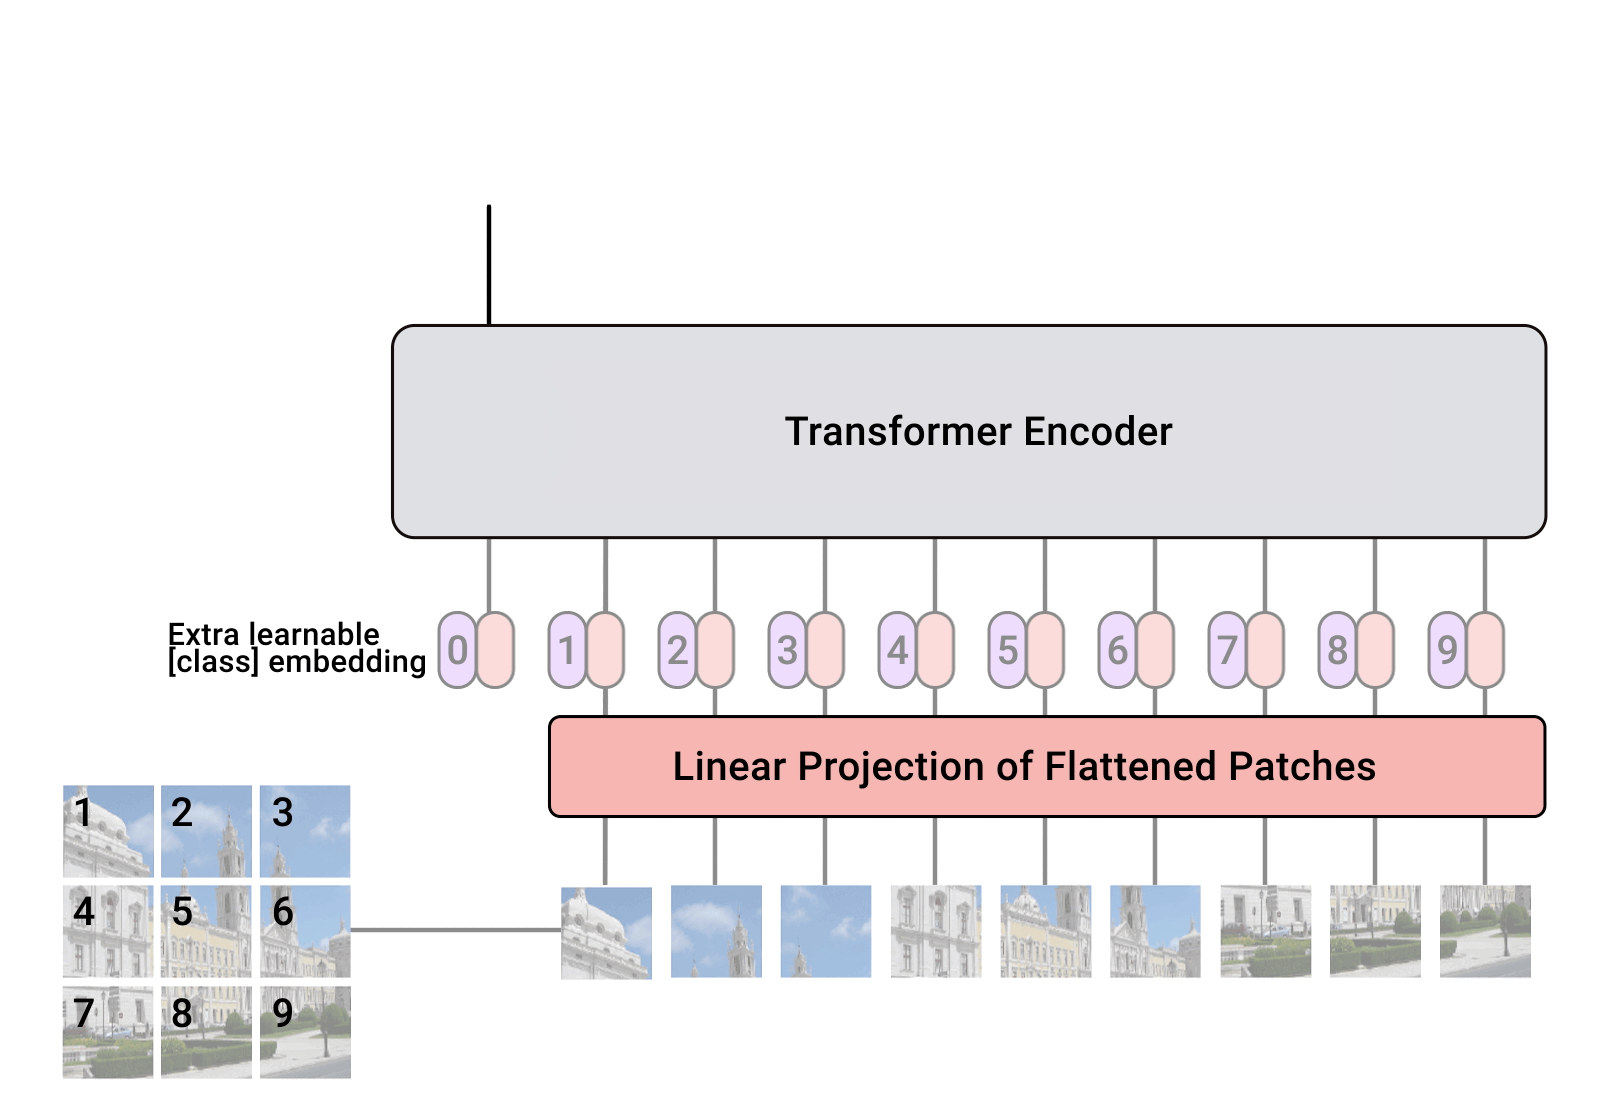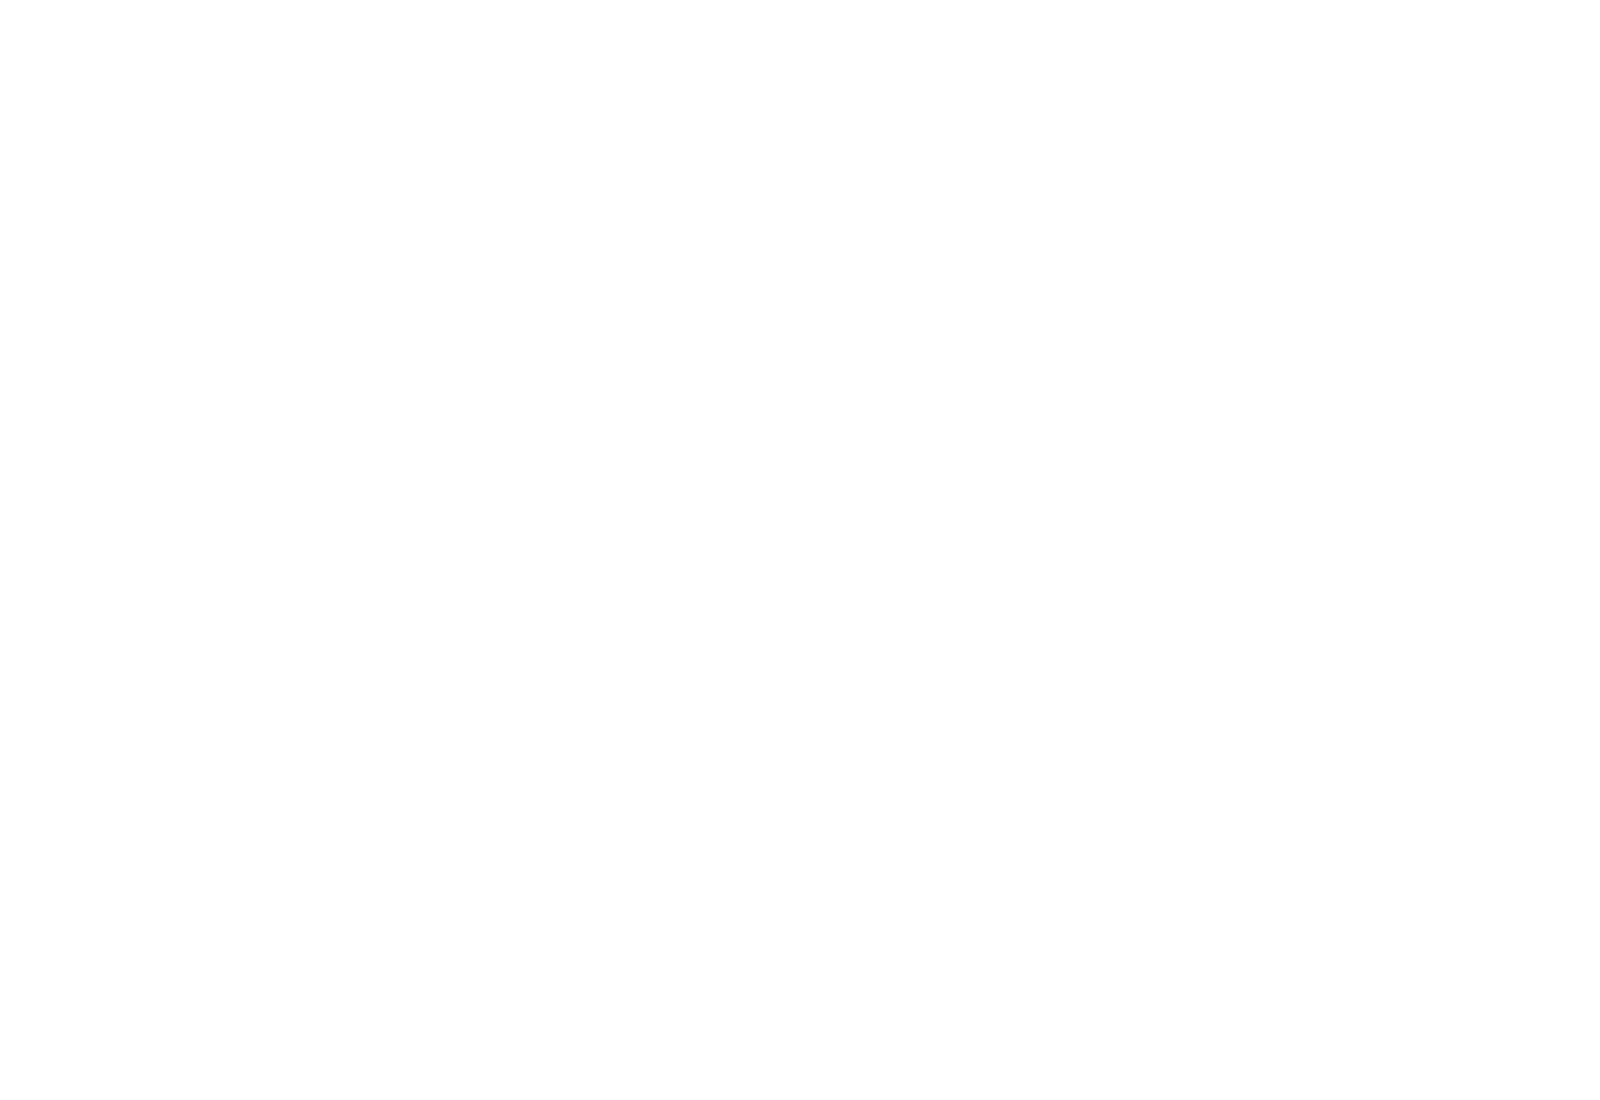
vit-pytorch
25.6Klucidrains/vit-pytorch · PythonA PyTorch implementation of the Vision Transformer (ViT), an image classification model that reaches SOTA results using just a single transformer encoder instead of convolutions.
- 6
flash-attention
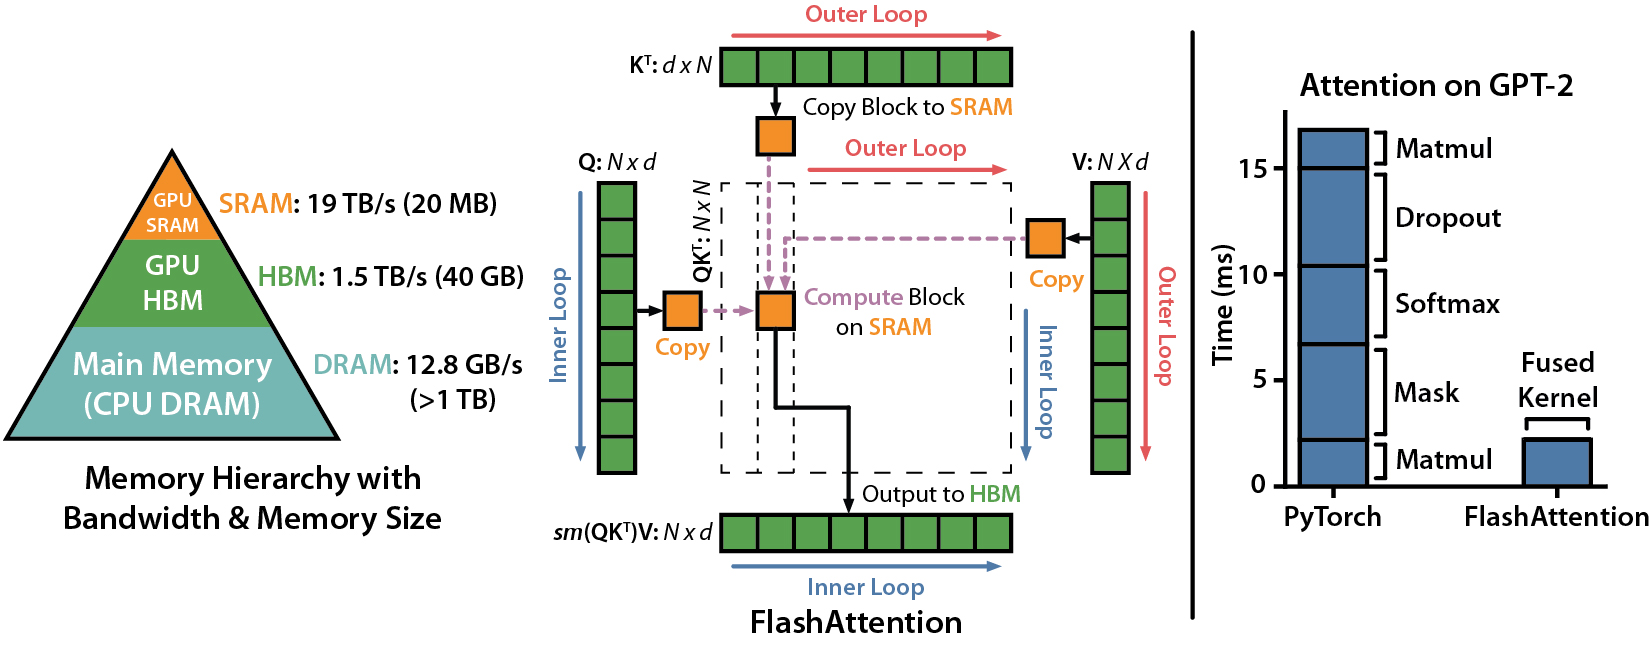
25.2KDao-AILab/flash-attention · PythonThe official implementation of FlashAttention and FlashAttention-2 — GPU kernels that compute exact attention faster and with less memory than standard PyTorch attention.
- 7
minGPT
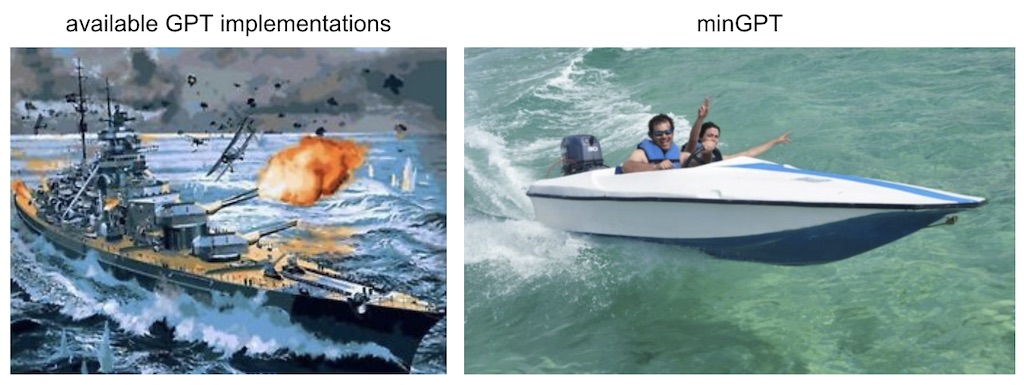
25Kkarpathy/minGPT · PythonminGPT is a minimal PyTorch re-implementation of OpenAI's GPT, covering both training and inference, written to be small and easy to read rather than production-optimized.
- 8

nn-zero-to-hero
24.8Kkarpathy/nn-zero-to-hero · Jupyter NotebookA course by Andrej Karpathy that teaches neural networks from the absolute basics, built around a series of YouTube lectures with accompanying Jupyter notebooks coded live in the videos.
- 9

deeplearning_ai_books
21.2Kfengdu78/deeplearning_ai_books · HTMLA Chinese-language collection of notes covering Andrew Ng's (吴恩达) Deep Learning Specialization on Coursera — five courses on neural networks, hyperparameter tuning, structuring ML projects, CNNs, and sequence models.
- 10
Dive-into-DL-PyTorch
19.5KShusenTang/Dive-into-DL-PyTorch · Jupyter NotebookThe Chinese book 'Dive into Deep Learning' with its MXNet code examples rewritten in PyTorch — a free, open-source deep-learning tutorial pairing runnable Jupyter notebooks with online docs.
- 11
nndl
19.4Knndl/nndlThe official home of Qiu Xipeng's Chinese textbook 'Neural Network and Deep Learning': it hosts free e-book PDFs, chapter listings, learning resources and errata for the 2nd edition and the new general-audience edition.
- 12

numpy-ml
16.3Kddbourgin/numpy-ml · PythonA collection of machine learning algorithms — Gaussian mixture models, HMMs, neural networks, tree ensembles, reinforcement learning agents and more — implemented from scratch in pure NumPy.
- 13

llama3-from-scratch
15.2Knaklecha/llama3-from-scratch · Jupyter NotebookA Jupyter notebook that implements Llama3 entirely from scratch, building up every matrix multiplication by hand instead of calling pre-built transformer modules.
- 14

OpenMythos
14.9Kkyegomez/OpenMythos · PythonOpenMythos is an open-source, speculative PyTorch implementation that tries to reconstruct the internal architecture of Anthropic's Claude ('Mythos') purely from publicly available research papers, not from any leaked or official Anthropic code.
- 15
RWKV-LM
14.8KBlinkDL/RWKV-LM · PythonRWKV (pronounced 'RwaKuv') is an RNN architecture with transformer-level LLM performance that can also be trained in parallel like GPT. The current generation, RWKV-7 'Goose', is 100% attention-free, linear-time and constant-memory (no kv-cache).
- 16

FlashMLA
13.1Kdeepseek-ai/FlashMLA · C++FlashMLA is DeepSeek's library of highly optimized CUDA attention kernels (Multi-head Latent Attention) that power the DeepSeek-V3 and DeepSeek-V3.2 models, covering both dense and sparse attention for prefill and decoding.
- 17
External-Attention-pytorch
12.2Kxmu-xiaoma666/External-Attention-pytorch · PythonA PyTorch collection of Attention, Backbone, MLP, Re-parameter, and Convolution implementations from research papers, meant to help you understand papers by seeing their mechanisms coded up.
- 18
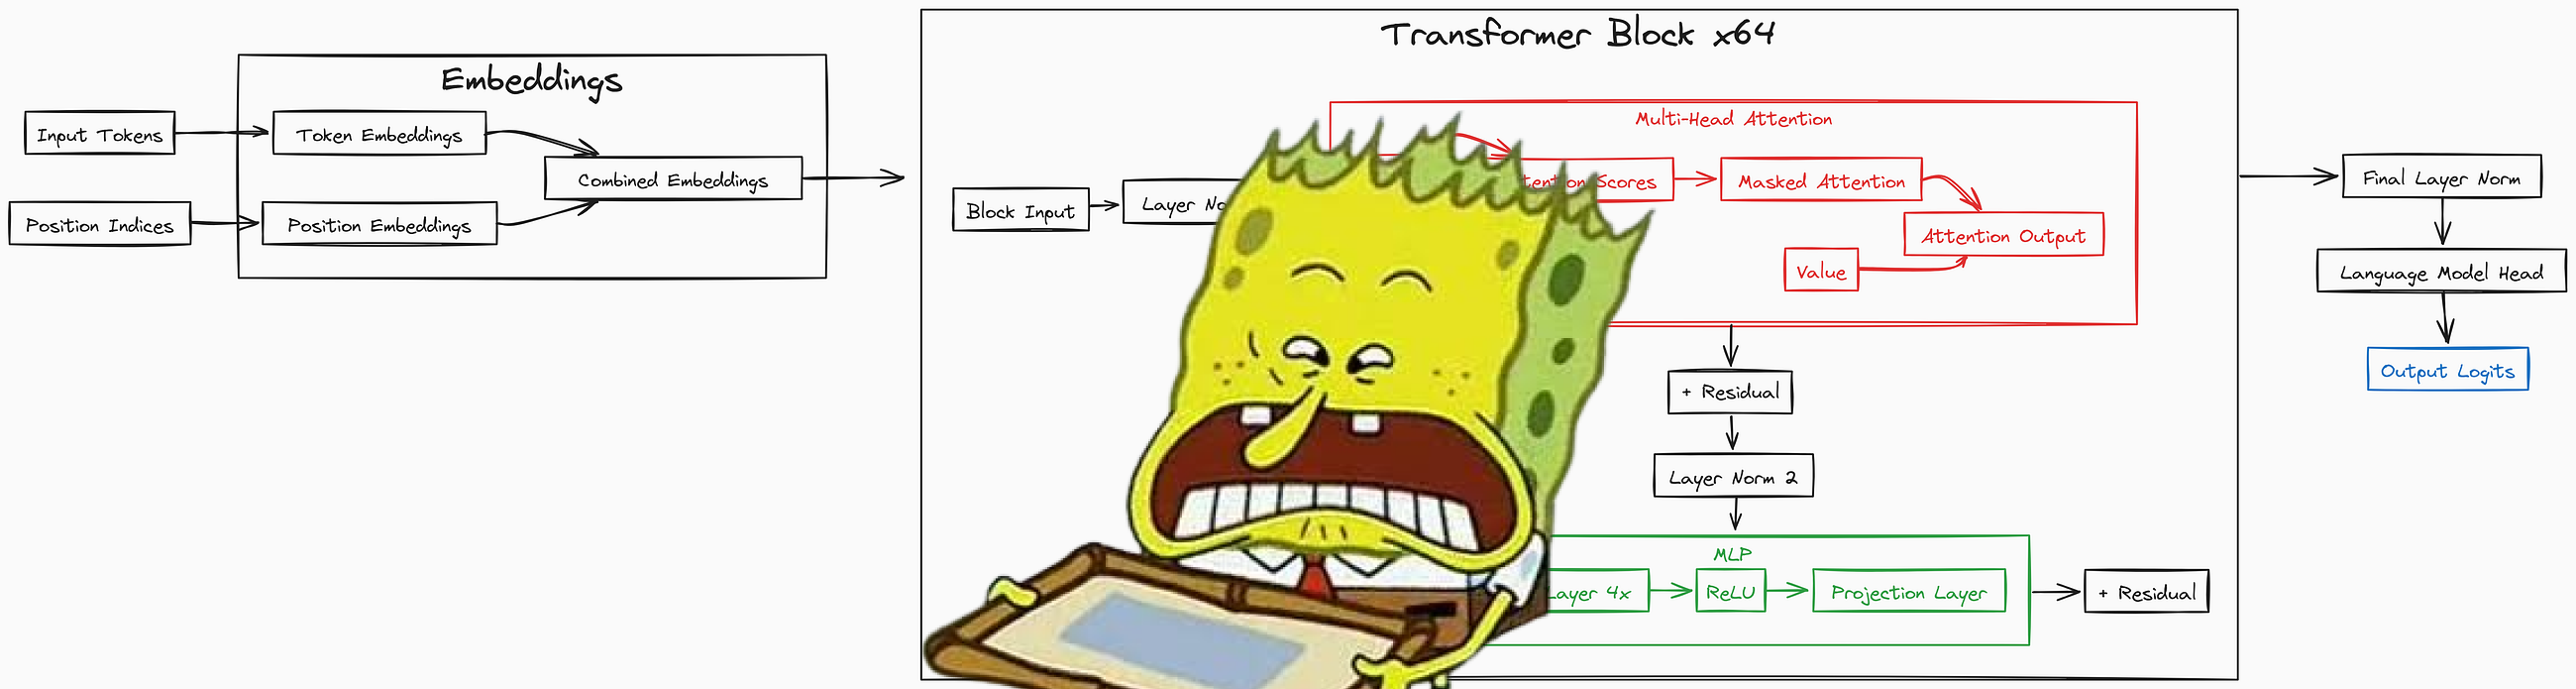
train-llm-from-scratch
12.2KFareedKhan-dev/train-llm-from-scratch · PythonA from-scratch tutorial and codebase for training your own LLM end to end: tokenizing raw text, pretraining a GPT-style Transformer, and then post-training it with SFT, a reward model, DPO/ORPO/KTO, PPO and GRPO into an aligned, reasoning-style assistant.
- 19

nlp_course
10.7Kyandexdataschool/nlp_course · Jupyter NotebookThis is the Yandex School of Data Analysis (YSDA) Natural Language Processing course: a full set of lecture slides, seminar notebooks, and homework assignments organized by week, covering NLP from word embeddings through modern LLM topics.
- 20

xformers
10.6Kfacebookresearch/xformers · PythonxFormers is Meta's (Facebook Research) toolbox of hackable, optimized Transformer building blocks that you compose together — reusable pieces for your own models rather than a monolithic framework.
- 21
DeepGEMM
9Kdeepseek-ai/DeepGEMM · CudaDeepGEMM is a unified CUDA kernel library that provides high-performance tensor core GEMM operations (FP8, FP4, BF16), fused MoE kernels, and attention-indexer kernels used in large language models such as DeepSeek.
- 22

GLM-5
7.3Kzai-org/GLM-5GLM-5 is a family of large open-weight language models from Z.ai built for agentic engineering and complex, long-horizon coding tasks, scaling up to 744B parameters with sparse attention for efficient long-context serving.
- 23

lectures
6.9Kgpu-mode/lectures · Jupyter NotebookThis is the supplementary material repository for the GPU MODE lectures YouTube channel — a growing collection of notebooks, slides and code from each numbered lecture on GPU and CUDA programming.
- 24
parameter-golf
5.2Kopenai/parameter-golf · PythonThis is OpenAI's 'Model Craft Challenge: Parameter Golf' - a competition to train the best language model that fits in a 16MB artifact and trains in under 10 minutes on 8xH100 GPUs, scored by bits-per-byte compression on the FineWeb validation set.
- 25

sutskever-30-implementations
5.2Kpageman/sutskever-30-implementations · Jupyter NotebookIt is a from-scratch NumPy implementation suite covering all 30 deep learning papers from Ilya Sutskever's famous reading list, the one he told John Carmack would teach '90% of what matters' in the field.
- 26

Engram
4.8Kdeepseek-ai/Engram · PythonThis is the official code release for the DeepSeek paper 'Conditional Memory via Scalable Lookup', introducing Engram, a module that gives Transformers a native knowledge-lookup primitive by modernizing classic N-gram embeddings for O(1) retrieval, as a complement to Mixture-of-Experts sparsity.
- 27
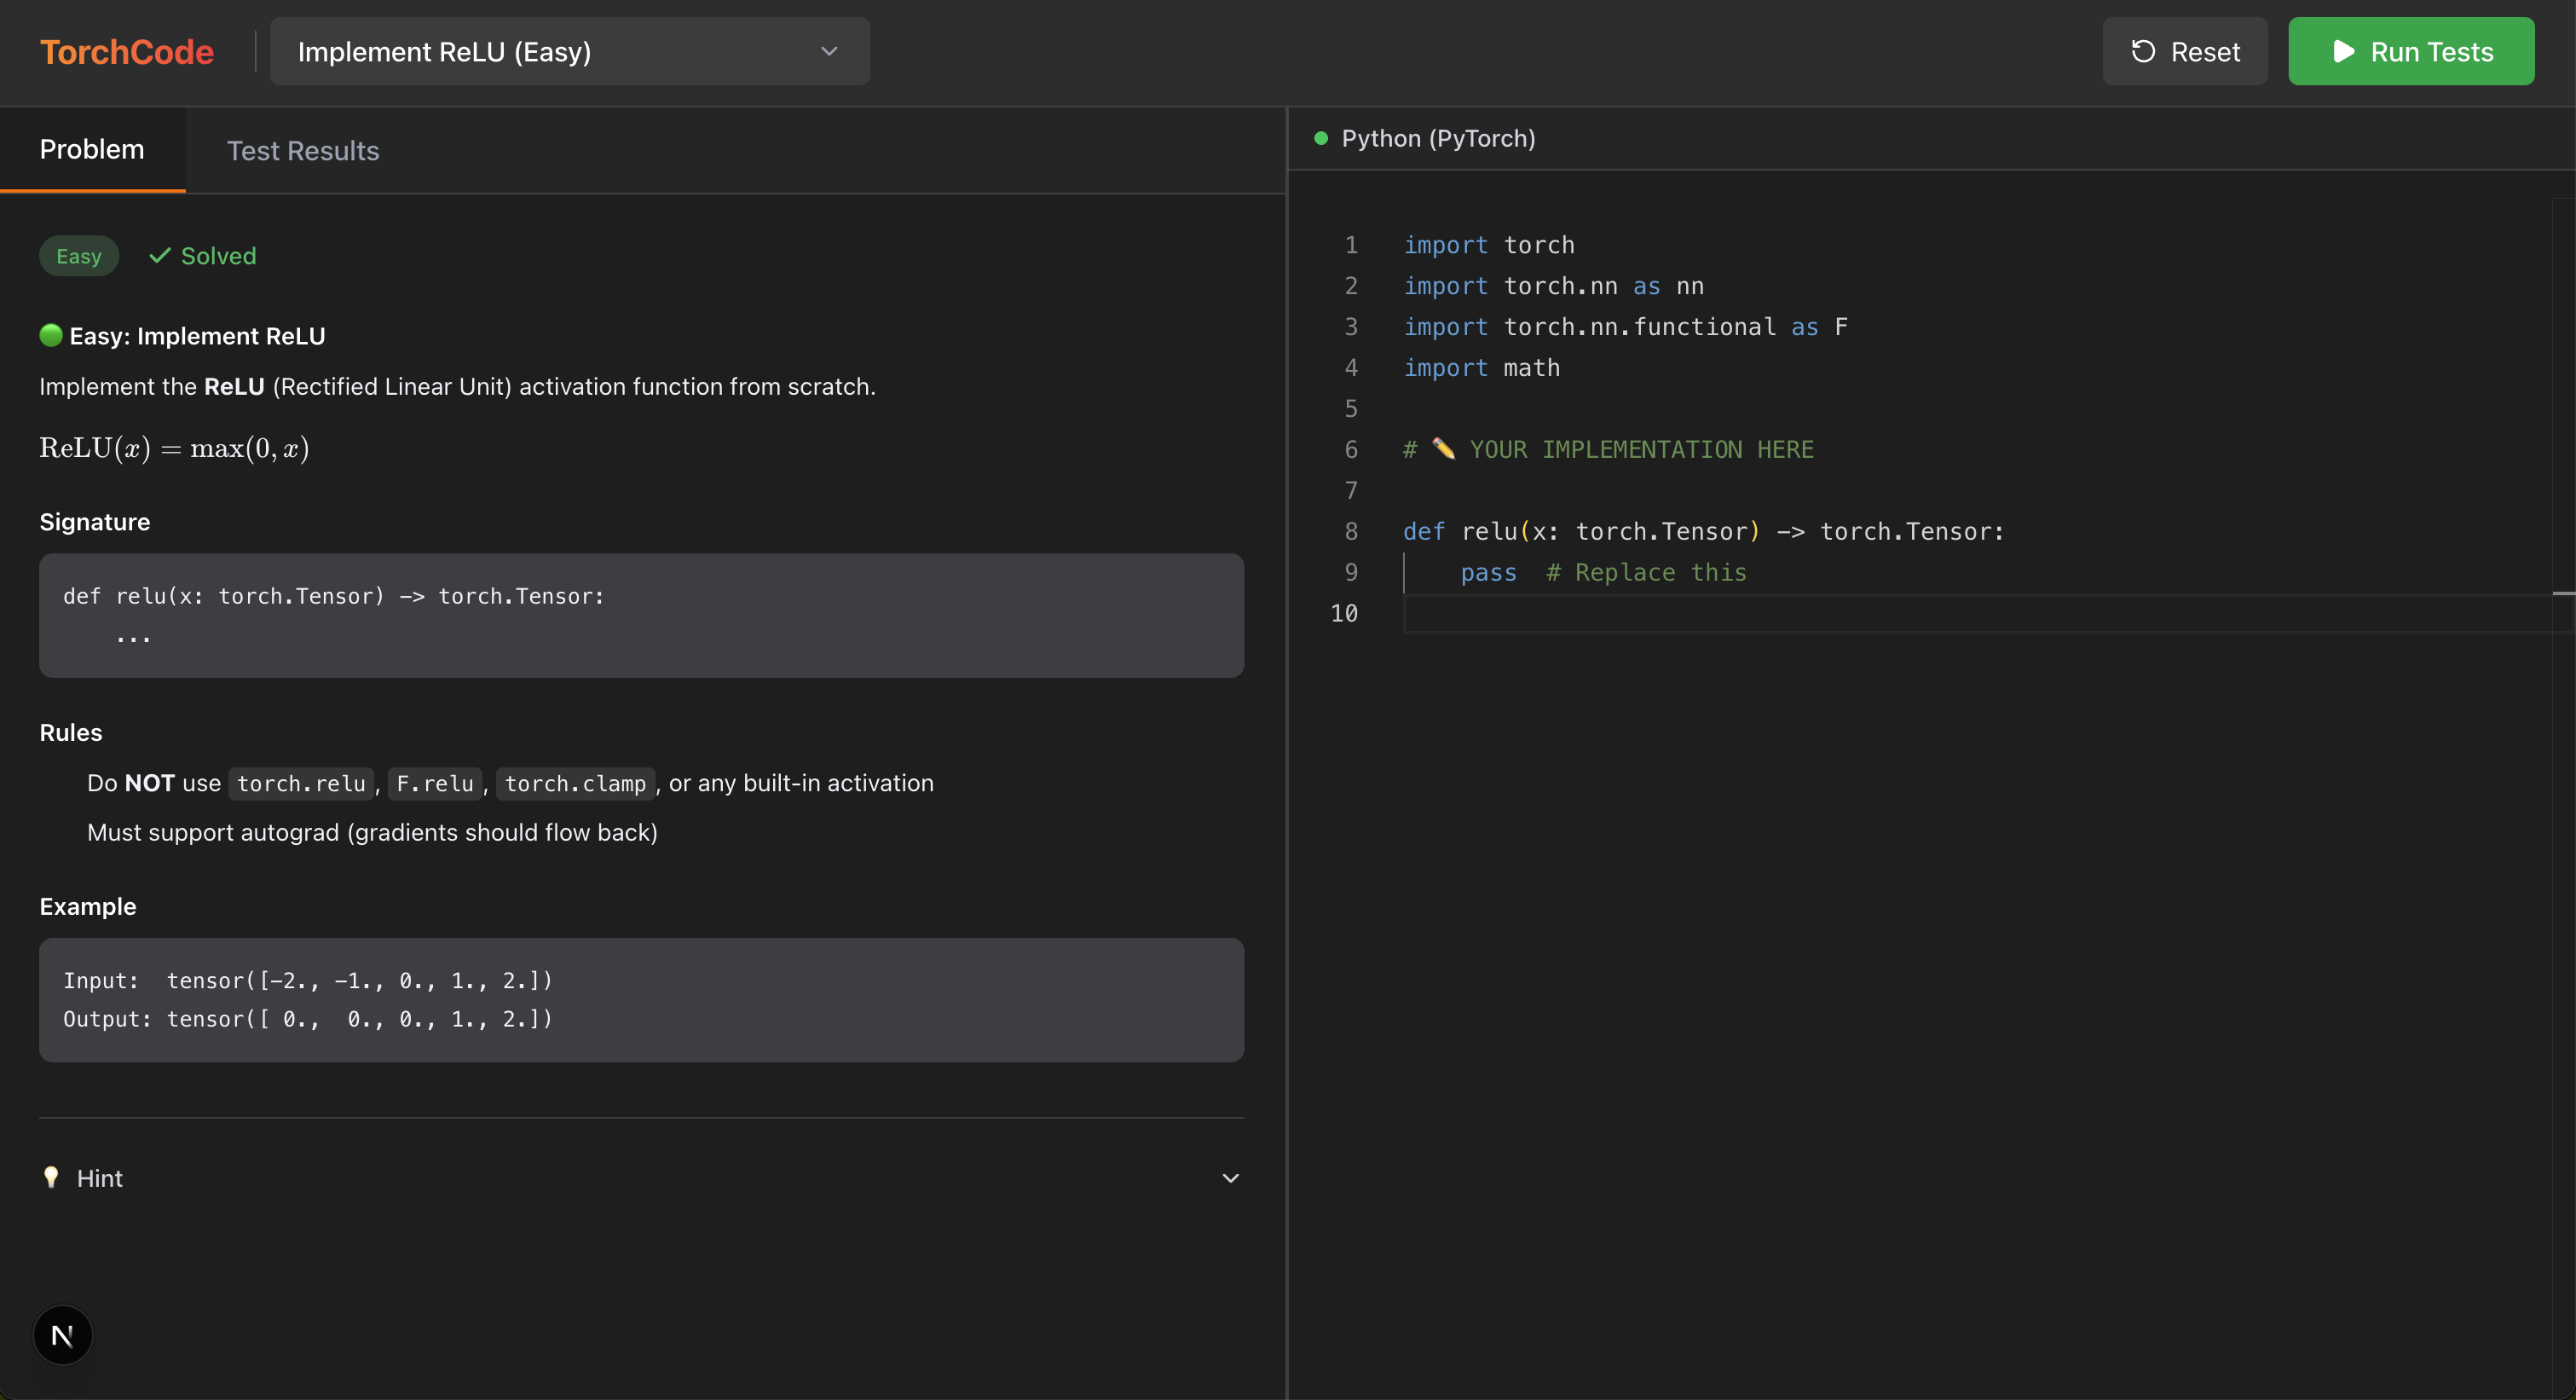
TorchCode
4.7Kduoan/TorchCode · Jupyter NotebookTorchCode is a LeetCode-style practice platform for PyTorch: it gives you 41 curated coding problems where you implement ML operators and architectures (softmax, attention, GPT-2 blocks, etc.) from scratch inside Jupyter notebooks, with an automated judge that checks correctness, gradients, and timing instantly.
- 28
RuVector
4.6Kruvnet/RuVector · RustRuVector is a Rust-native persistent memory substrate for AI agents, combining local vector embeddings, graph relationships, feedback-driven learning, and memory lifecycle controls so agents can remember across sessions.
- 29

InfraTech
4.2KCalvinXKY/InfraTech · Jupyter NotebookInfraTech is a collection of Jupyter notebooks and articles sharing AI Infra knowledge: training/inference frameworks (PyTorch, vLLM/SGLang, slime/vime), performance acceleration, deep learning fundamentals and AI hardware/software basics.
- 30
TurboDiffusion
3.9Kthu-ml/TurboDiffusion · PythonTurboDiffusion is a video generation acceleration framework that speeds up end-to-end video diffusion generation by 100-200x on a single RTX 5090 while keeping video quality, using SageAttention, Sparse-Linear Attention (SLA), and rCM timestep distillation.
- 31
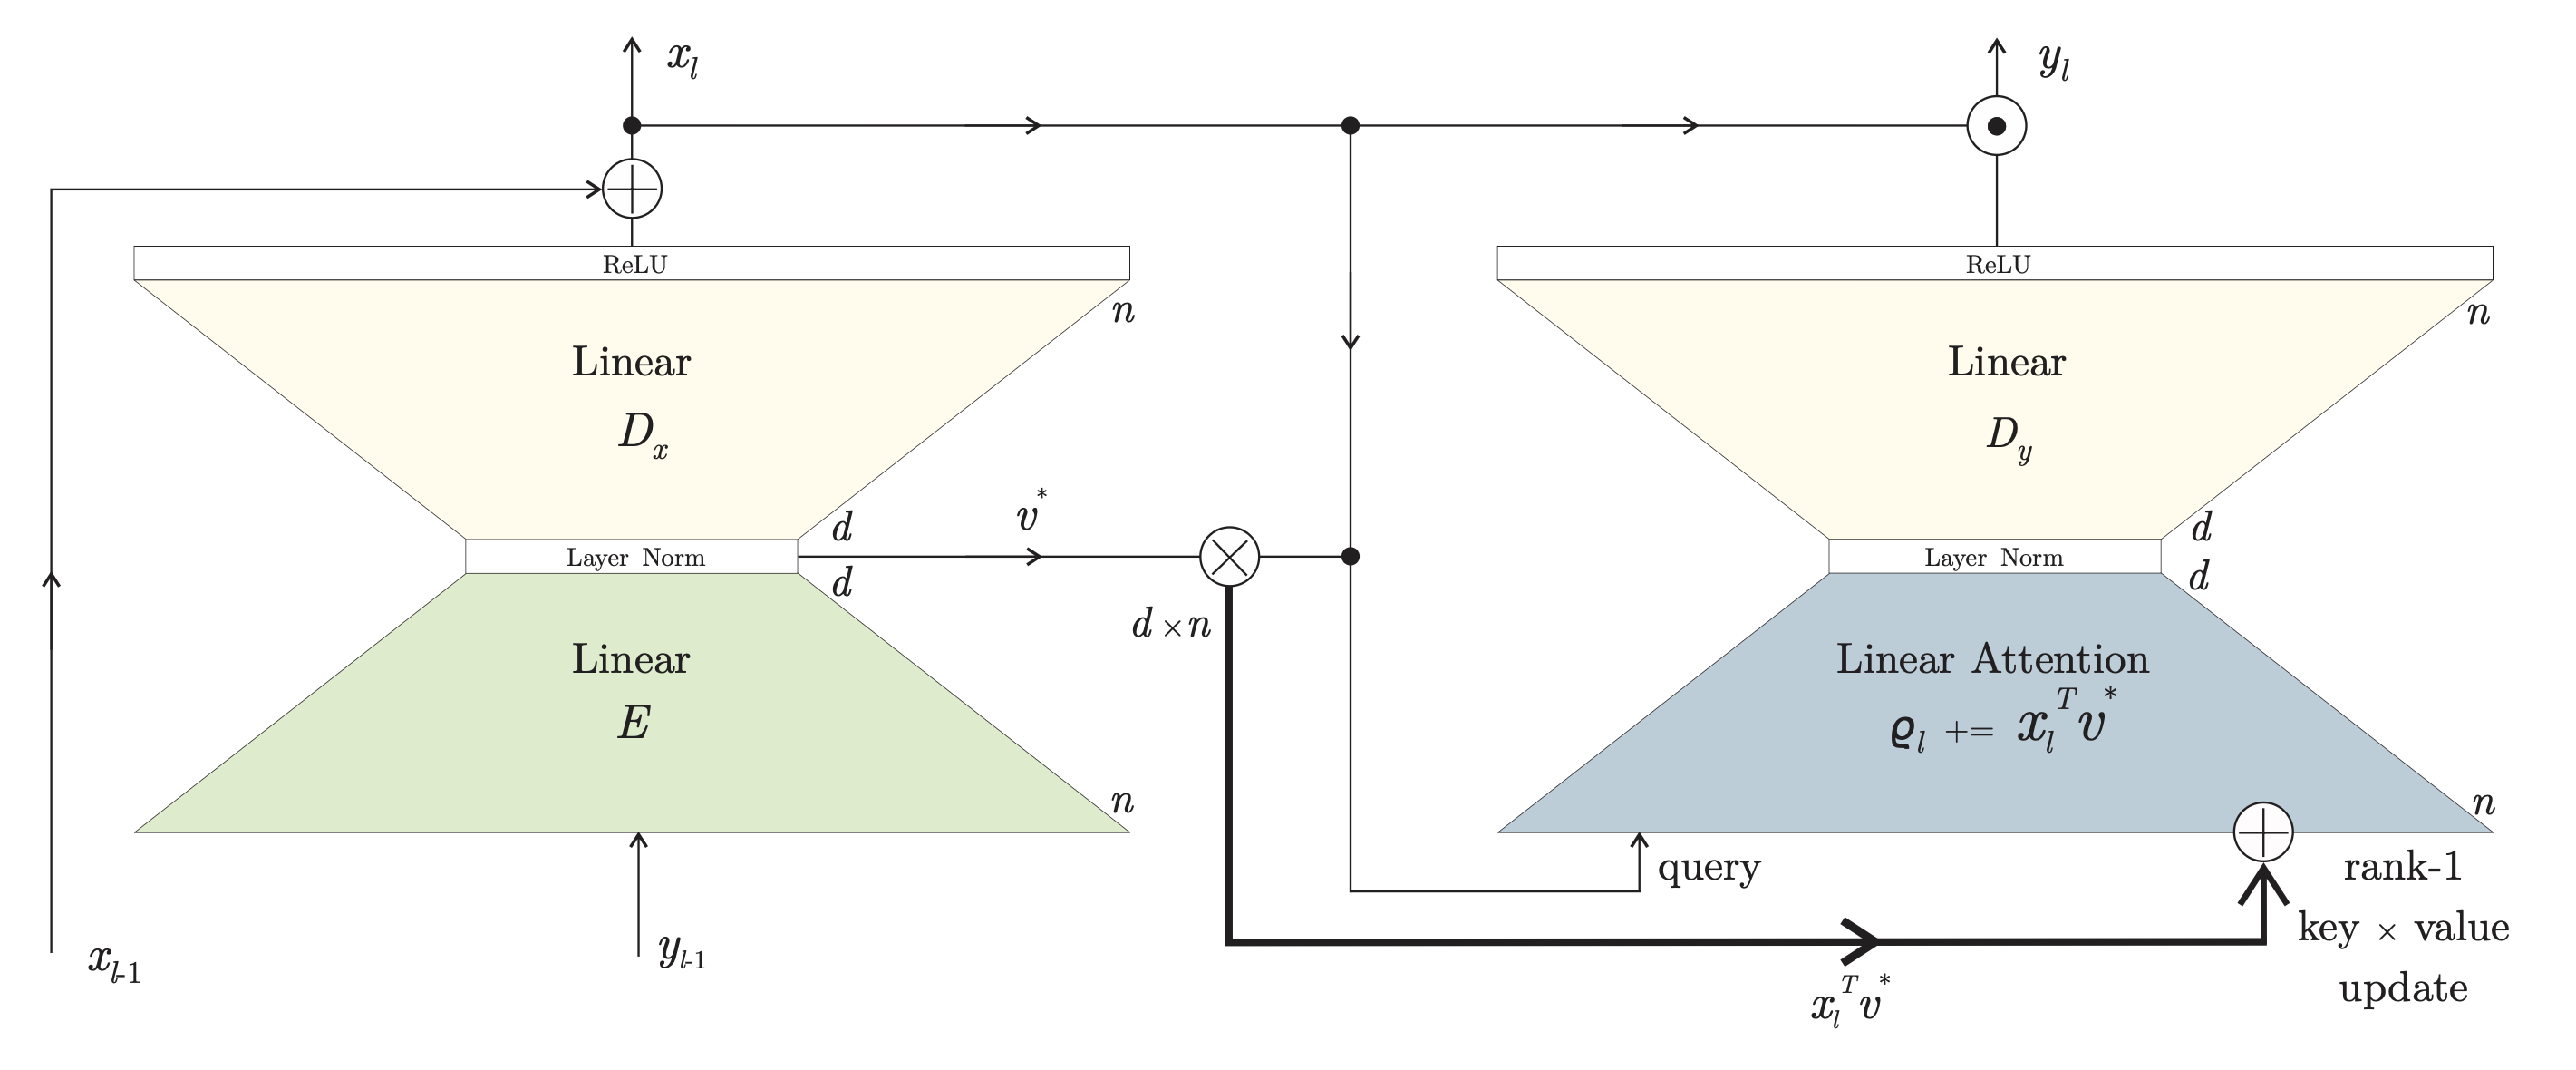
bdh
3.6Kpathwaycom/bdh · PythonBDH (Dragon Hatchling) is a biologically inspired large language model architecture that connects deep learning with neuroscience, aiming to explain how reasoning and generalization emerge in AI systems at the level of individual neuron interactions.
- 32
Attention-Residuals
3.5KMoonshotAI/Attention-ResidualsAttnRes (Attention Residuals) is a drop-in replacement for standard residual connections in Transformers, letting each layer use learned, input-dependent attention over all previous layer outputs instead of simple additive accumulation.
- 33
MSA
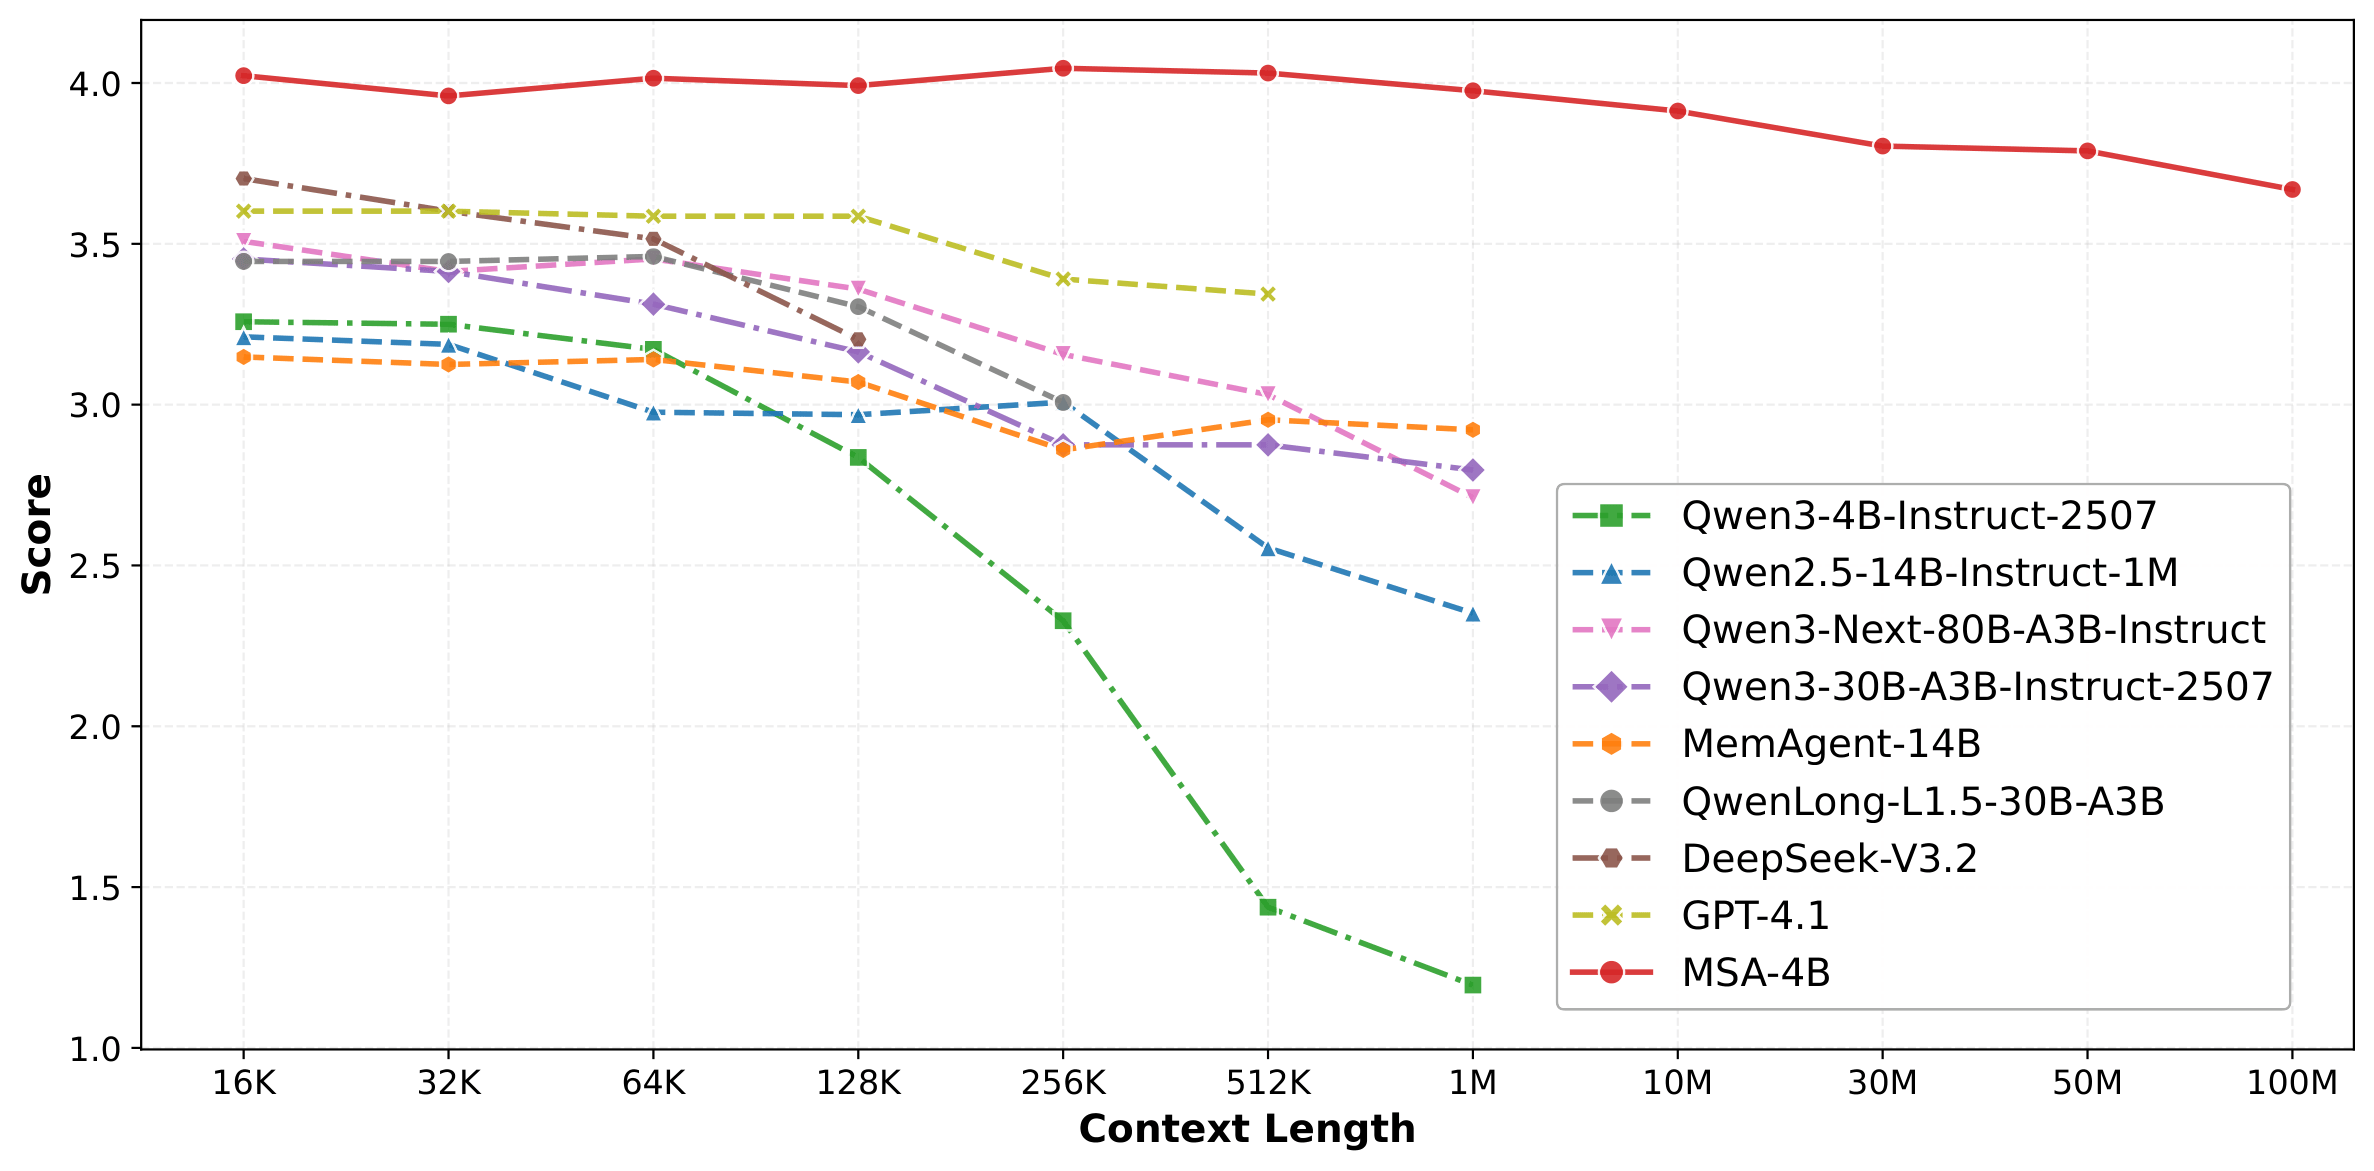
3.5KEverMind-AI/MSA · PythonMSA (Memory Sparse Attention) is an end-to-end trainable, scalable latent-memory framework that lets LLMs handle context windows up to 100M tokens, replacing RAG or fixed-size RNN-style memory with a differentiable sparse-attention memory bank.
- 34
OpenWAM
1.1KOpenWAM-Official/OpenWAM · PythonOpenWAM is an open research stack for systematically building World-Action Models (WAMs) for robots, breaking the usual tightly-coupled design choices into modular, swappable components you can compare in controlled experiments.
- 35
llm-architecture-from-scratch
961YeonwooSung/llm-architecture-from-scratch · PythonA collection of PyTorch implementations of modern LLM architectures (GPT-2, Llama 3/3.2, Llama 4, OLMo 2, Phi-4, DeepSeek v3, Gemma 3, xLSTM, Mistral 3.1) built from scratch to understand how they work internally.
- 36
OpenDLSS-NR
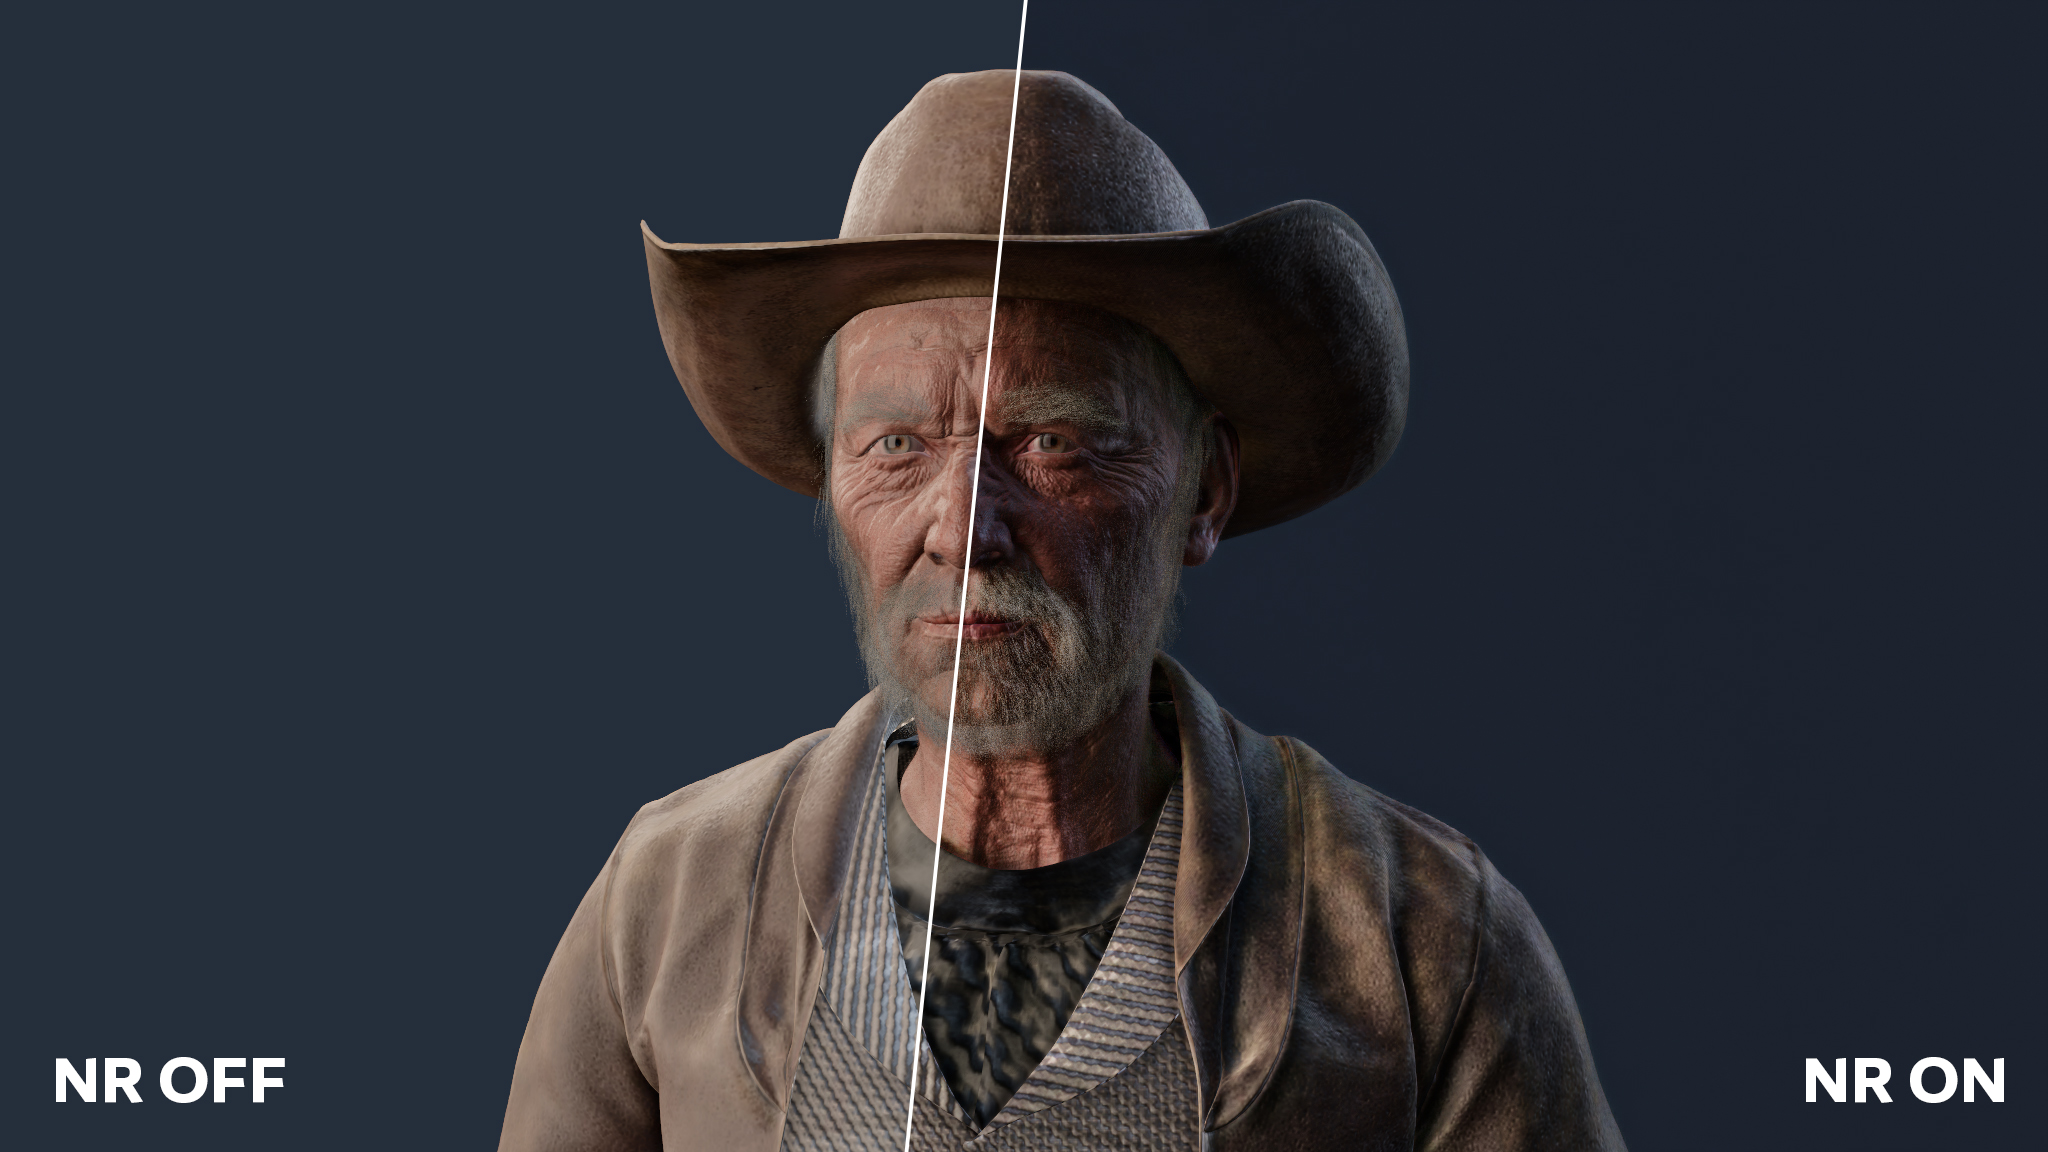
929maanHimself/OpenDLSS-NR · JavaScriptOpenDLSS-NR is a from-scratch Vulkan reimplementation of NVIDIA's DLSS 5 Neural Rendering network, matching the original bit-exactly down to every internal block boundary, not just the final image.
- 37
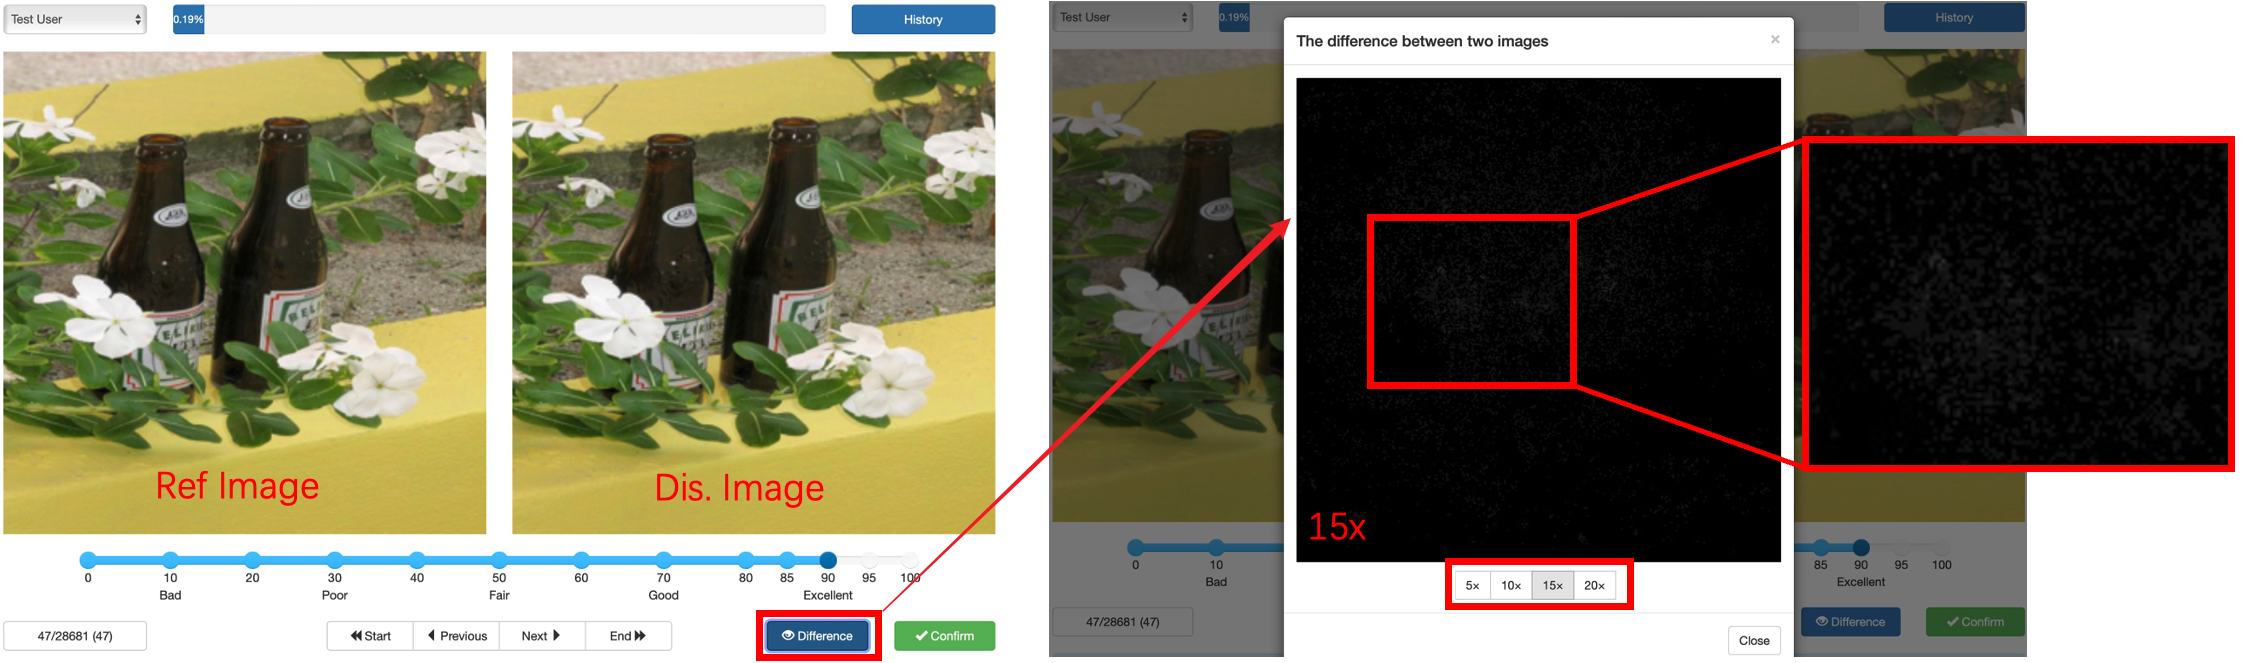
APSD
897hcliucs/APSDAPSD is a large-scale dataset for studying how visually stealthy adversarial perturbations look to humans, containing 10,586 clean-adversarial image pairs with human opinion scores.
- 38
Evoke
861AlayaLab/Evoke · PythonEVOKE is a research implementation of an interactive 'world model' that generates endless, controllable video: a three-step, CFG-free system that remembers where it has already been, lets you redirect it mid-rollout, and is state-of-the-art on the WBench long-horizon benchmark.
- 39
ComfyUI-Ref2VA-VSA
743Kablex/ComfyUI-Ref2VA-VSA · PythonIt's a ComfyUI custom node that dramatically speeds up Reference-to-Video (Ref2VA) generation for the MiniMax H3 model, producing a full 5-second, 24fps character video in about 72 seconds on a single RTX 4090 instead of over 10 minutes.
- 40
vdn-minimax-h3
618OpenVDN/vdn-minimax-h3 · PythonVDN-Minimax-H3 is a hybrid-attention video generation model built on MiniMax H3 that renders video faster than it plays, supporting text-to-video-audio, image-to-video-audio, first/last-frame-to-video and more from one checkpoint.
- 41
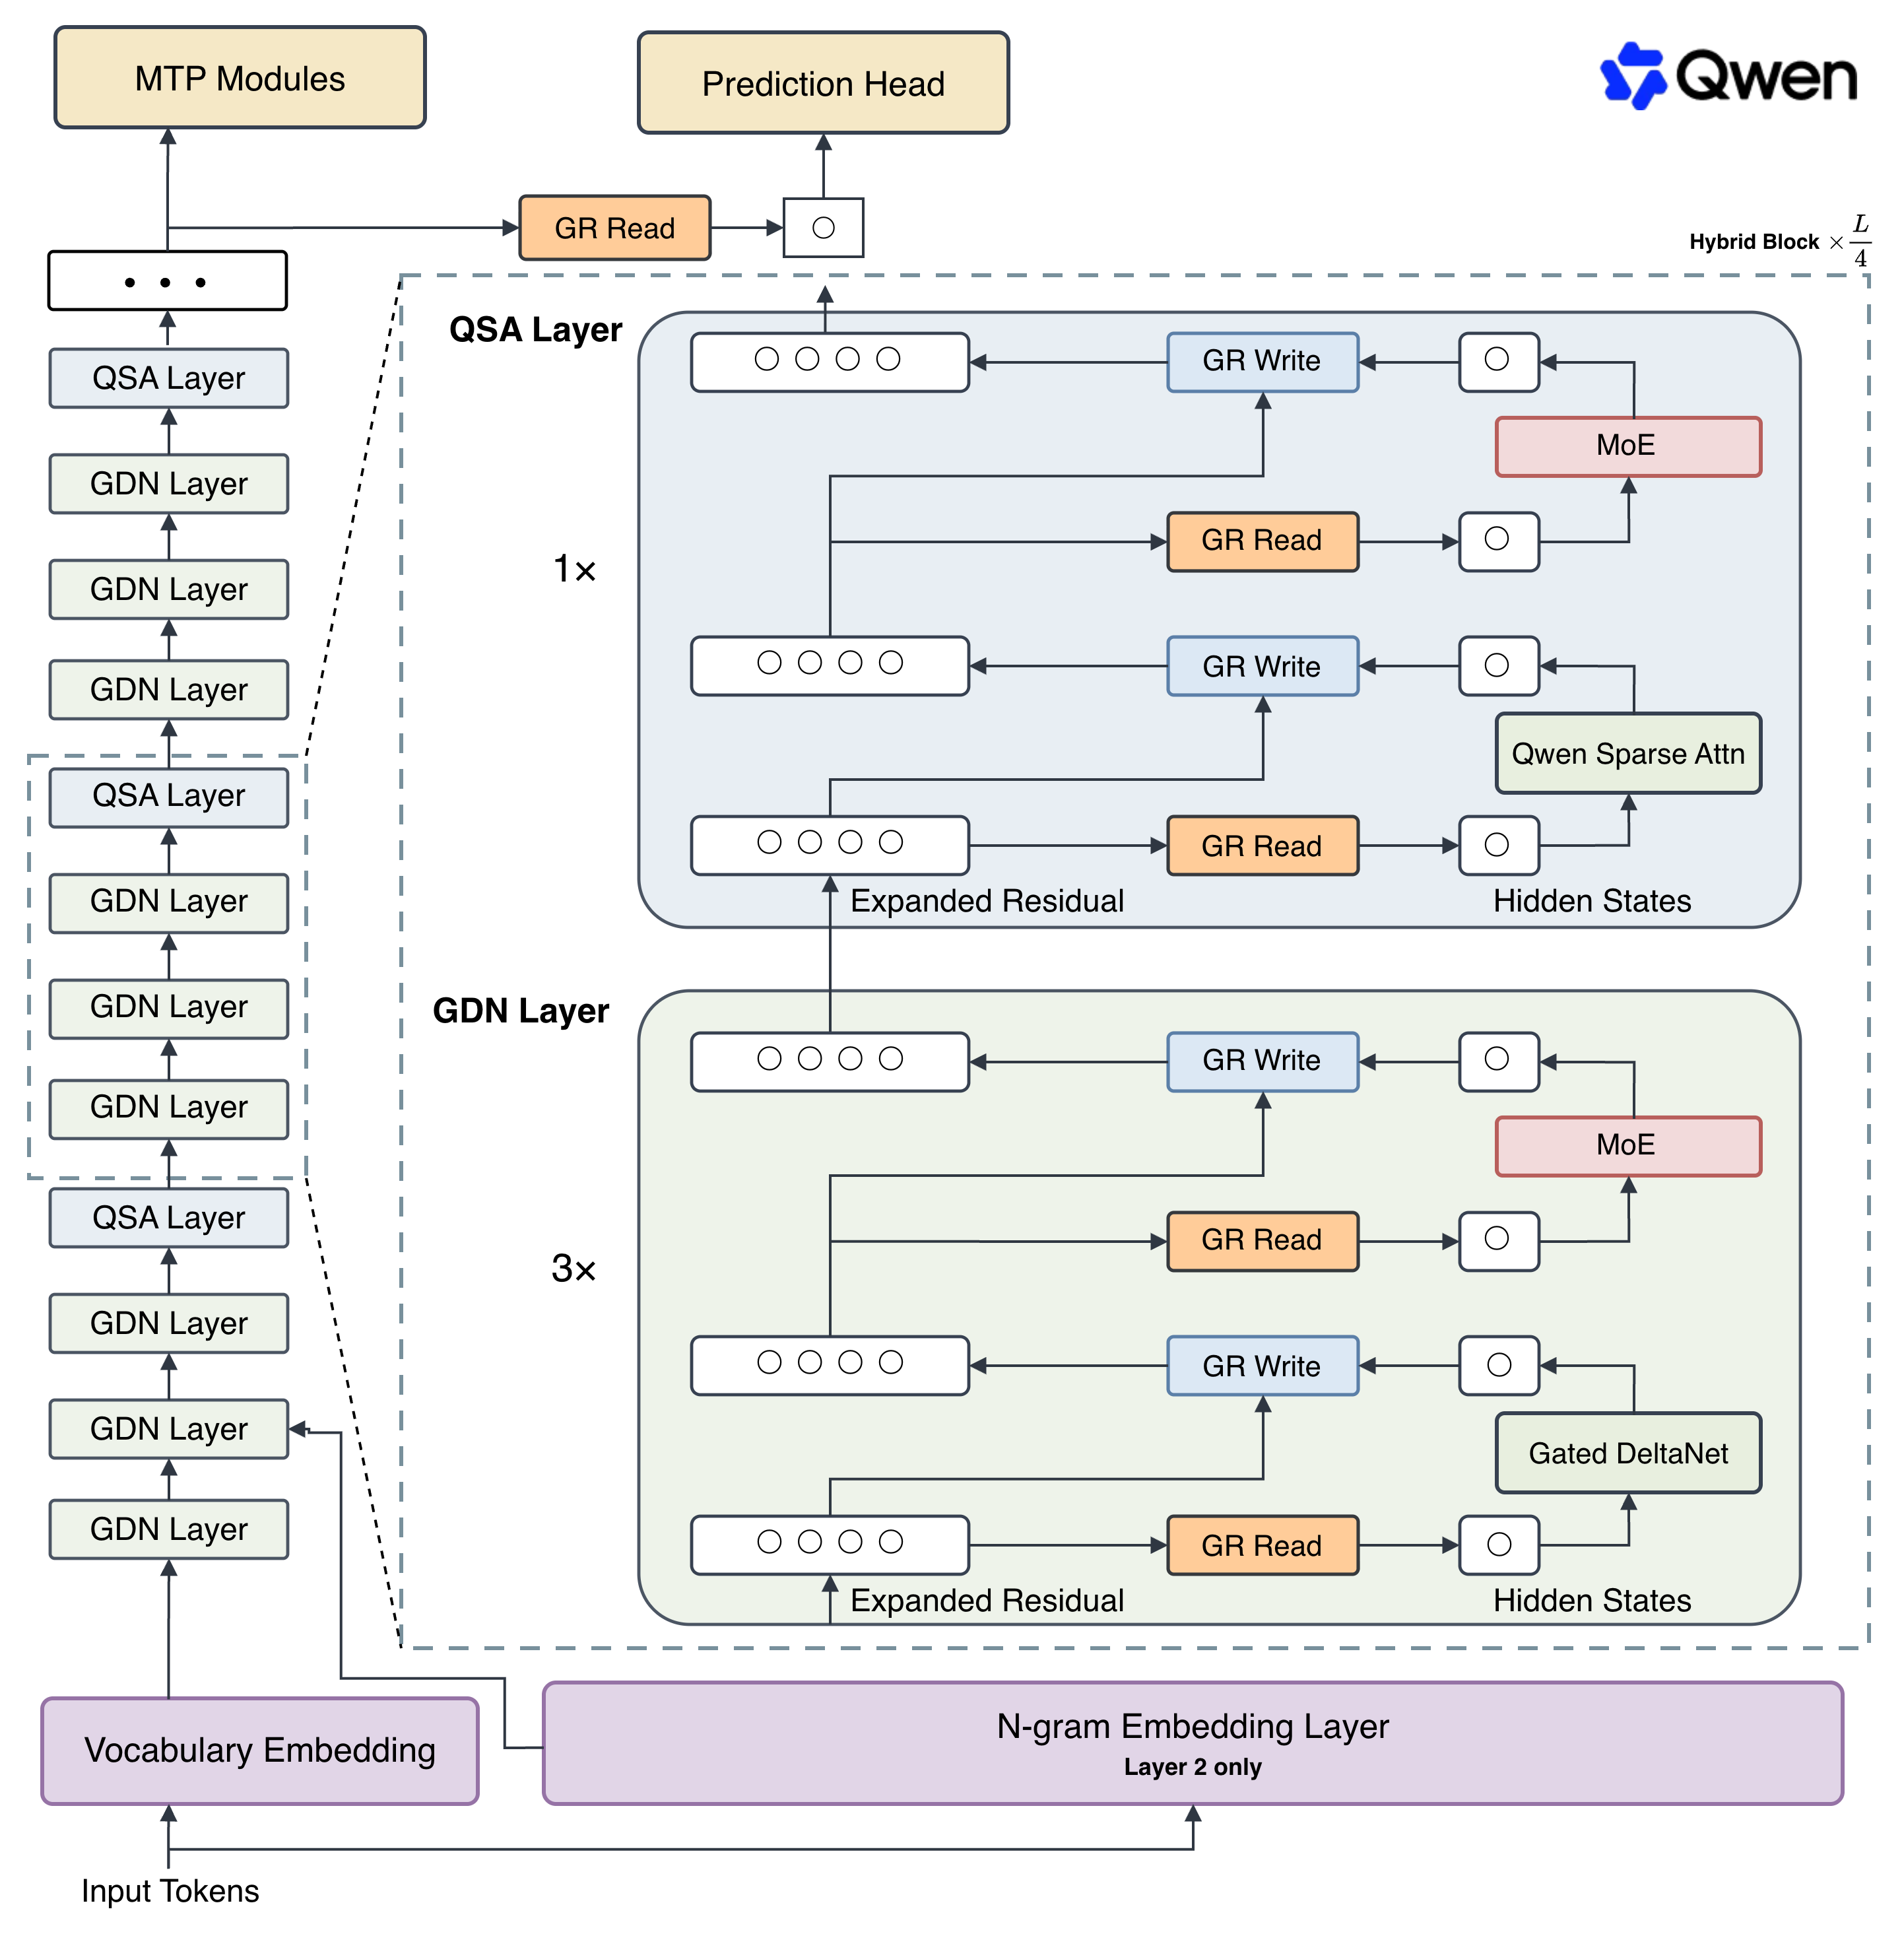
Qwen3.8-Flash-Next
433QwenLM/Qwen3.8-Flash-NextQwen3.8-Flash-Next is an open-weight multimodal Mixture-of-Experts foundation model from Alibaba's Qwen Team, also serving as an early preview of the architecture Alibaba plans to use for the upcoming Qwen4 model family.
- 42

OpenArch
426anuj0456/OpenArch · PythonA set of hand-written PyTorch implementations of modern open-source LLM architectures (Llama, Qwen, DeepSeek, Gemma, GPT-OSS, Kimi and more), written from scratch for readability and learning.
- 43
Hy4-preview
395Tencent-Hunyuan/Hy4-preview · PythonHy4 preview is Tencent Hunyuan's newest open-source large language model, a 770B-parameter Mixture-of-Experts model (49B active per token) built for coding, office/data analysis, game development, and scientific research tasks.
- 44

nnUNet_att_position_correction
354qpuchen/nnUNet_att_position_correction · PythonThis is the official PyTorch code for the MICCAI 2023 STS Challenge (3D tooth segmentation from CBCT scans) by team sdkxd, which extends nn-UNet with axial attention and a positional correction module to clean up abnormal segmentation points.
- 45
llm-inference-engineering
348amitshekhariitbhu/llm-inference-engineering · MarkdownA free, continuously growing blog series that teaches LLM inference engineering step by step, covering KV cache, PagedAttention, continuous batching, speculative decoding, and serving engines like vLLM, SGLang, TensorRT-LLM, and GGUF.
- 46

H3-World
319Danzer1xxxxChan/H3-World · PythonH3-World is an interactive world model built on MiniMax-H3: give it one initial frame and it generates video you steer with keyboard actions, like driving a game world with your keys.
- 47
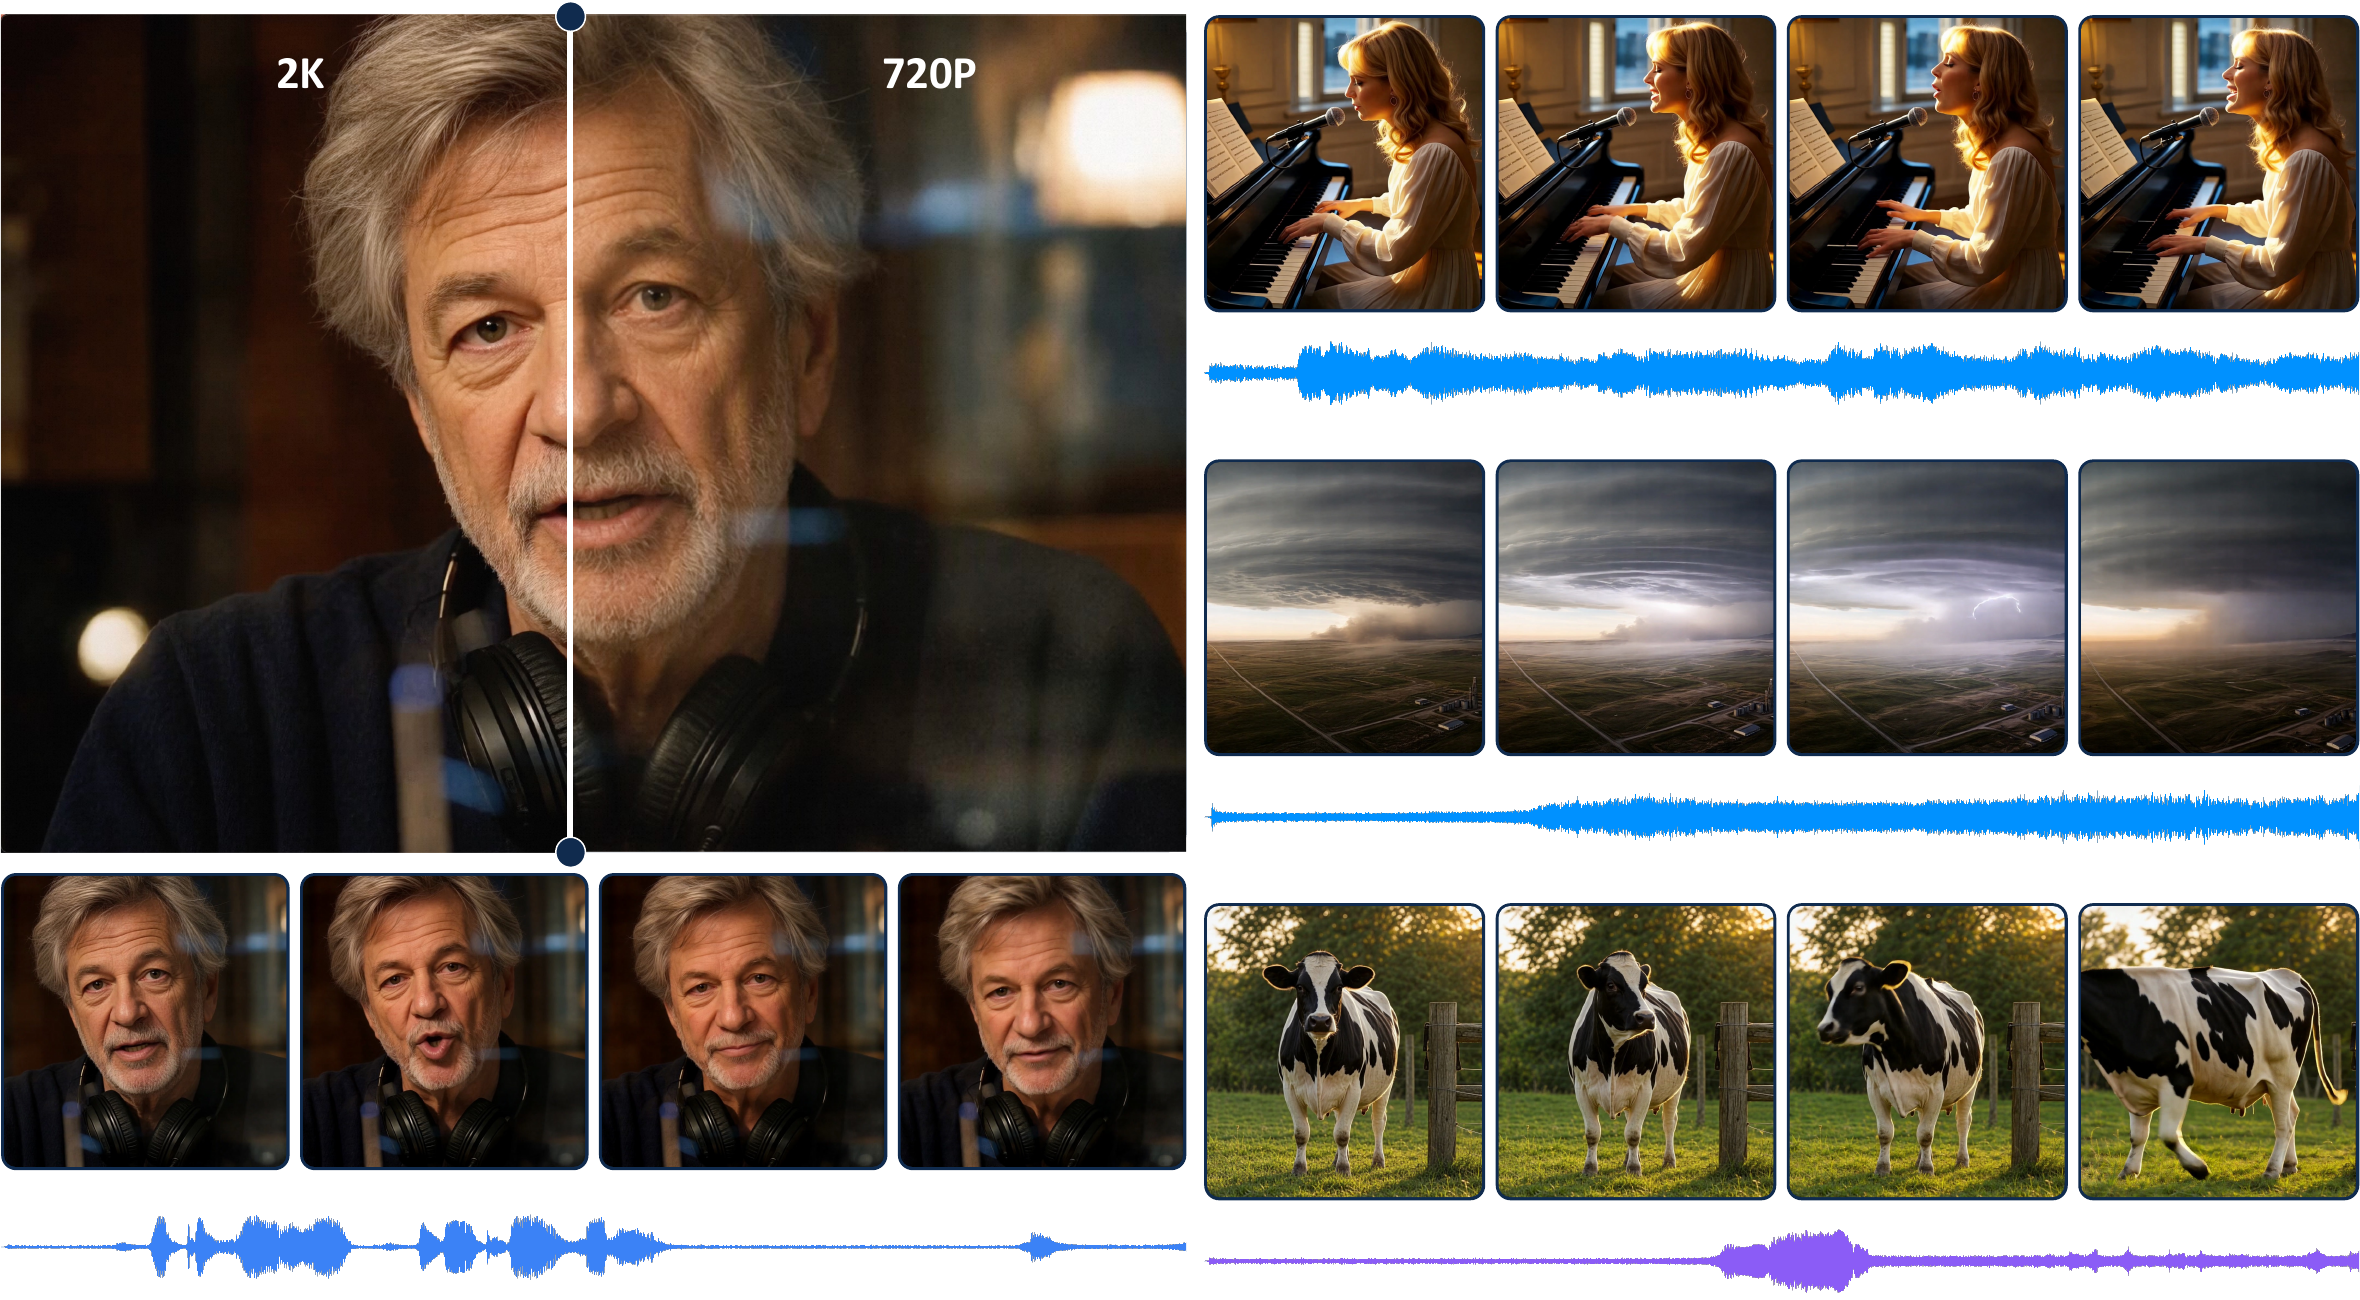
DreamX-Creator
312AMAP-ML/DreamX-Creator · PythonDreamX-Creator is an open-source research framework for native joint audio-video generation: it produces video and a synchronized audio track together, refined up to 2K resolution.
- 48
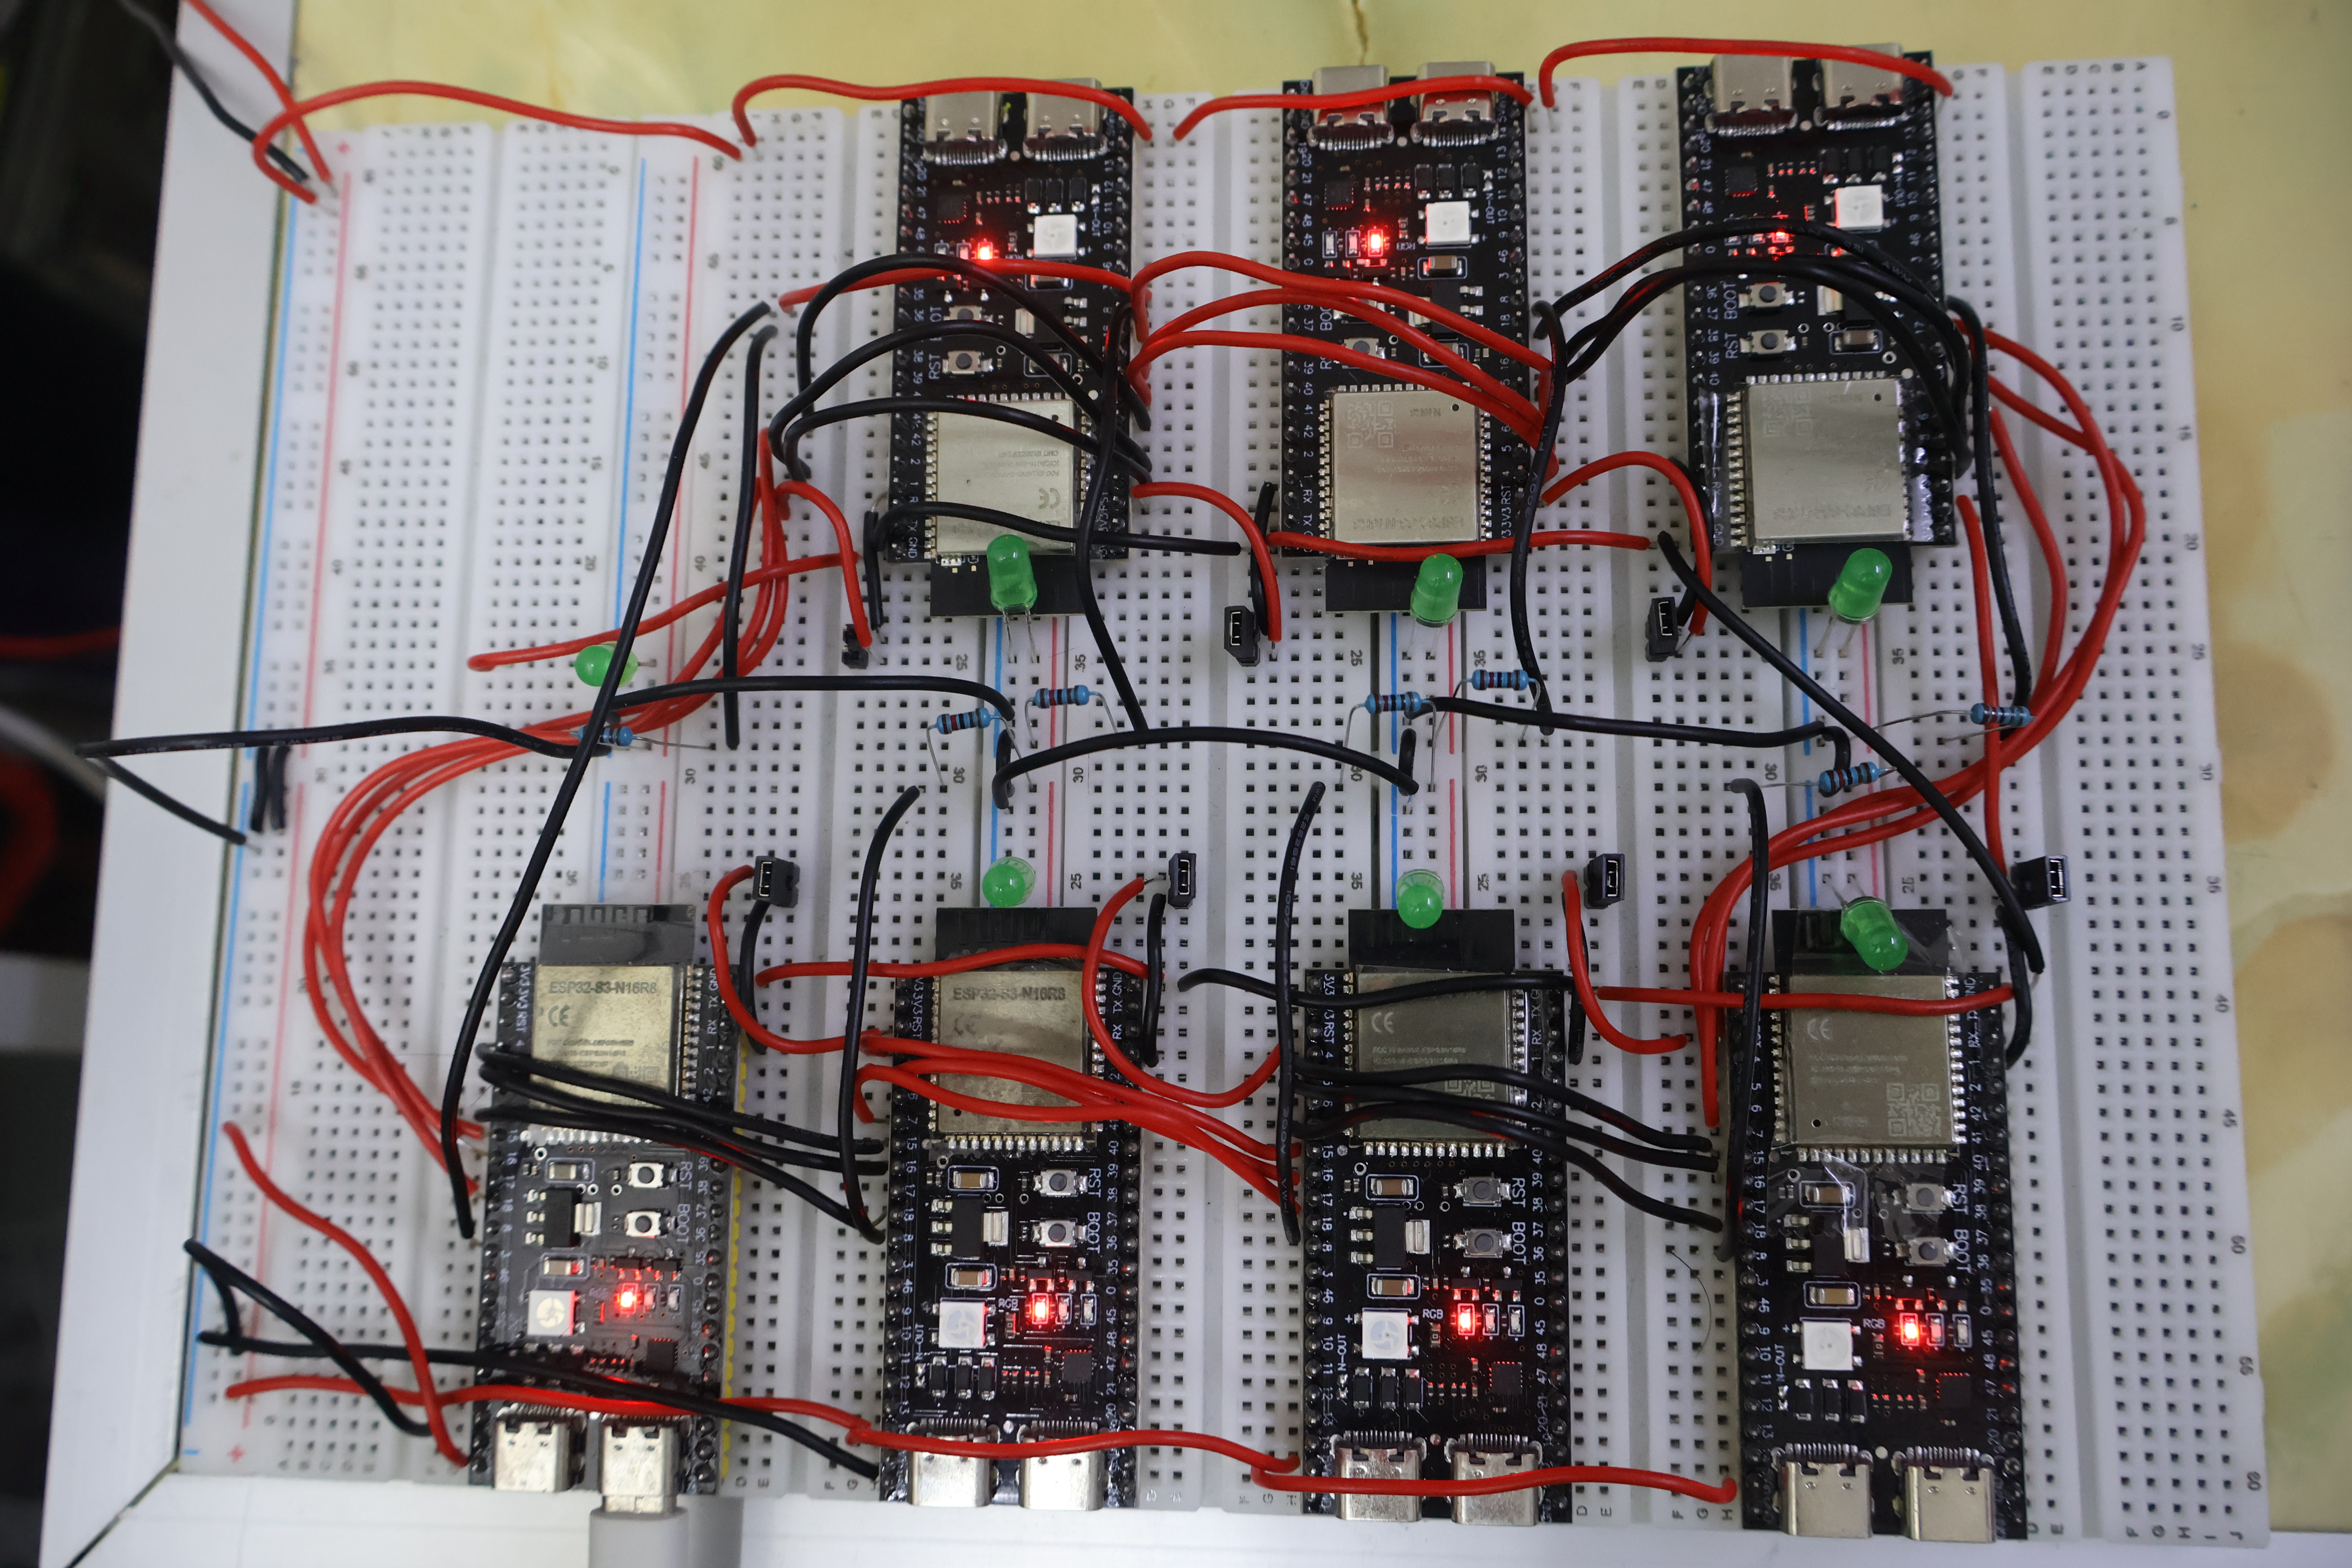
ESP32s3-LLM-Cluster
243Low-Zi-Hong/ESP32s3-LLM-Cluster · C++This project is a distributed inference engine that runs a 0.5B-parameter LLM, quantized to 1.58-bit (BitNet) ternary weights, split across a cluster of 7 ESP32-S3 microcontrollers connected via SPI.
- 49

ComfyUI-YCNodes-MiniMax-H3
243yichengup/ComfyUI-YCNodes-MiniMax-H3 · PythonThis is a ComfyUI custom node pack built specifically for the MiniMax H3 video model, adding 6 nodes for second-pass conditioning, timed prompt control, attention-field constraints, dynamic CFG scheduling, low-noise detail refinement and tiled sampling.
- 50
StreamPI
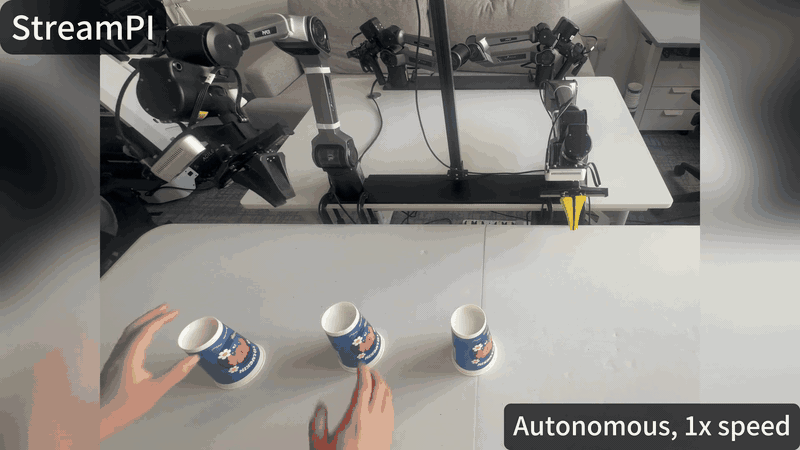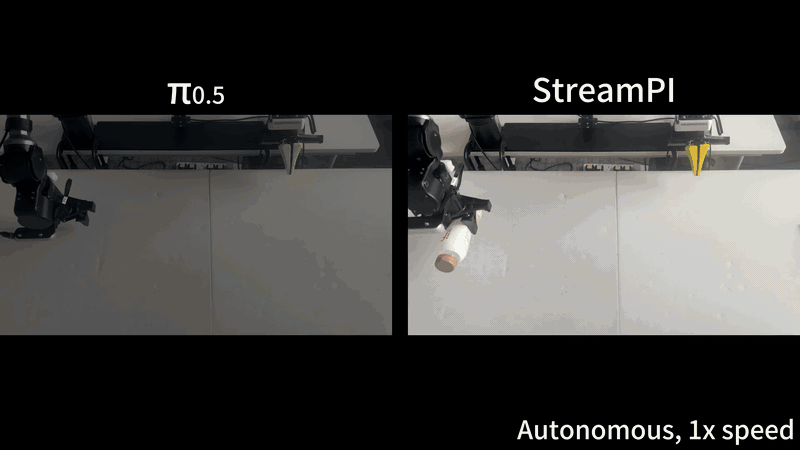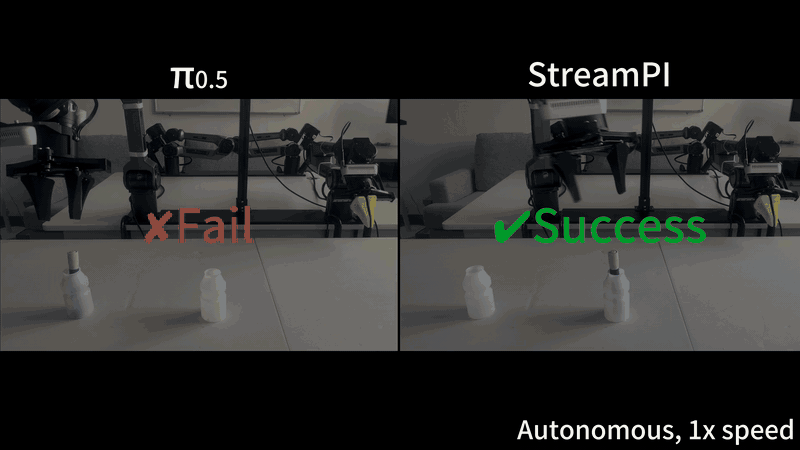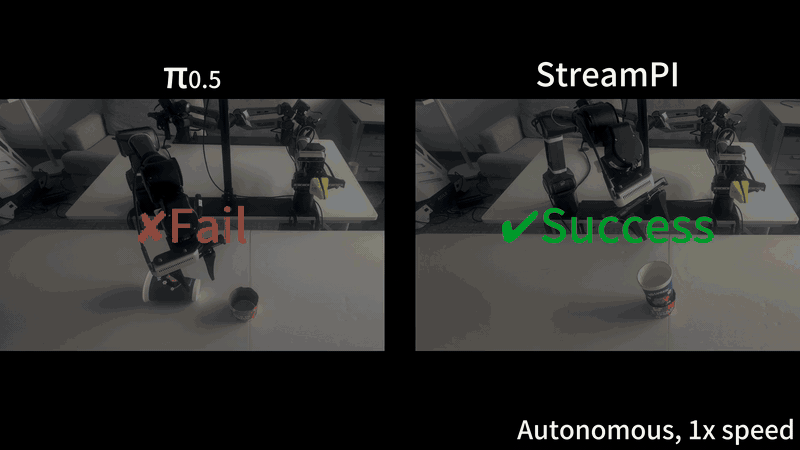
211hku-sail/StreamPI · PythonOfficial code of StreamPI (NeurIPS 2026, from HKU and ACE Robotics): a streaming temporal modeling framework that gives VLA robot policies like pi0.5 memory of past frames and multi-frame perception without adding any new parameters.
- 51
tpu-megakernels
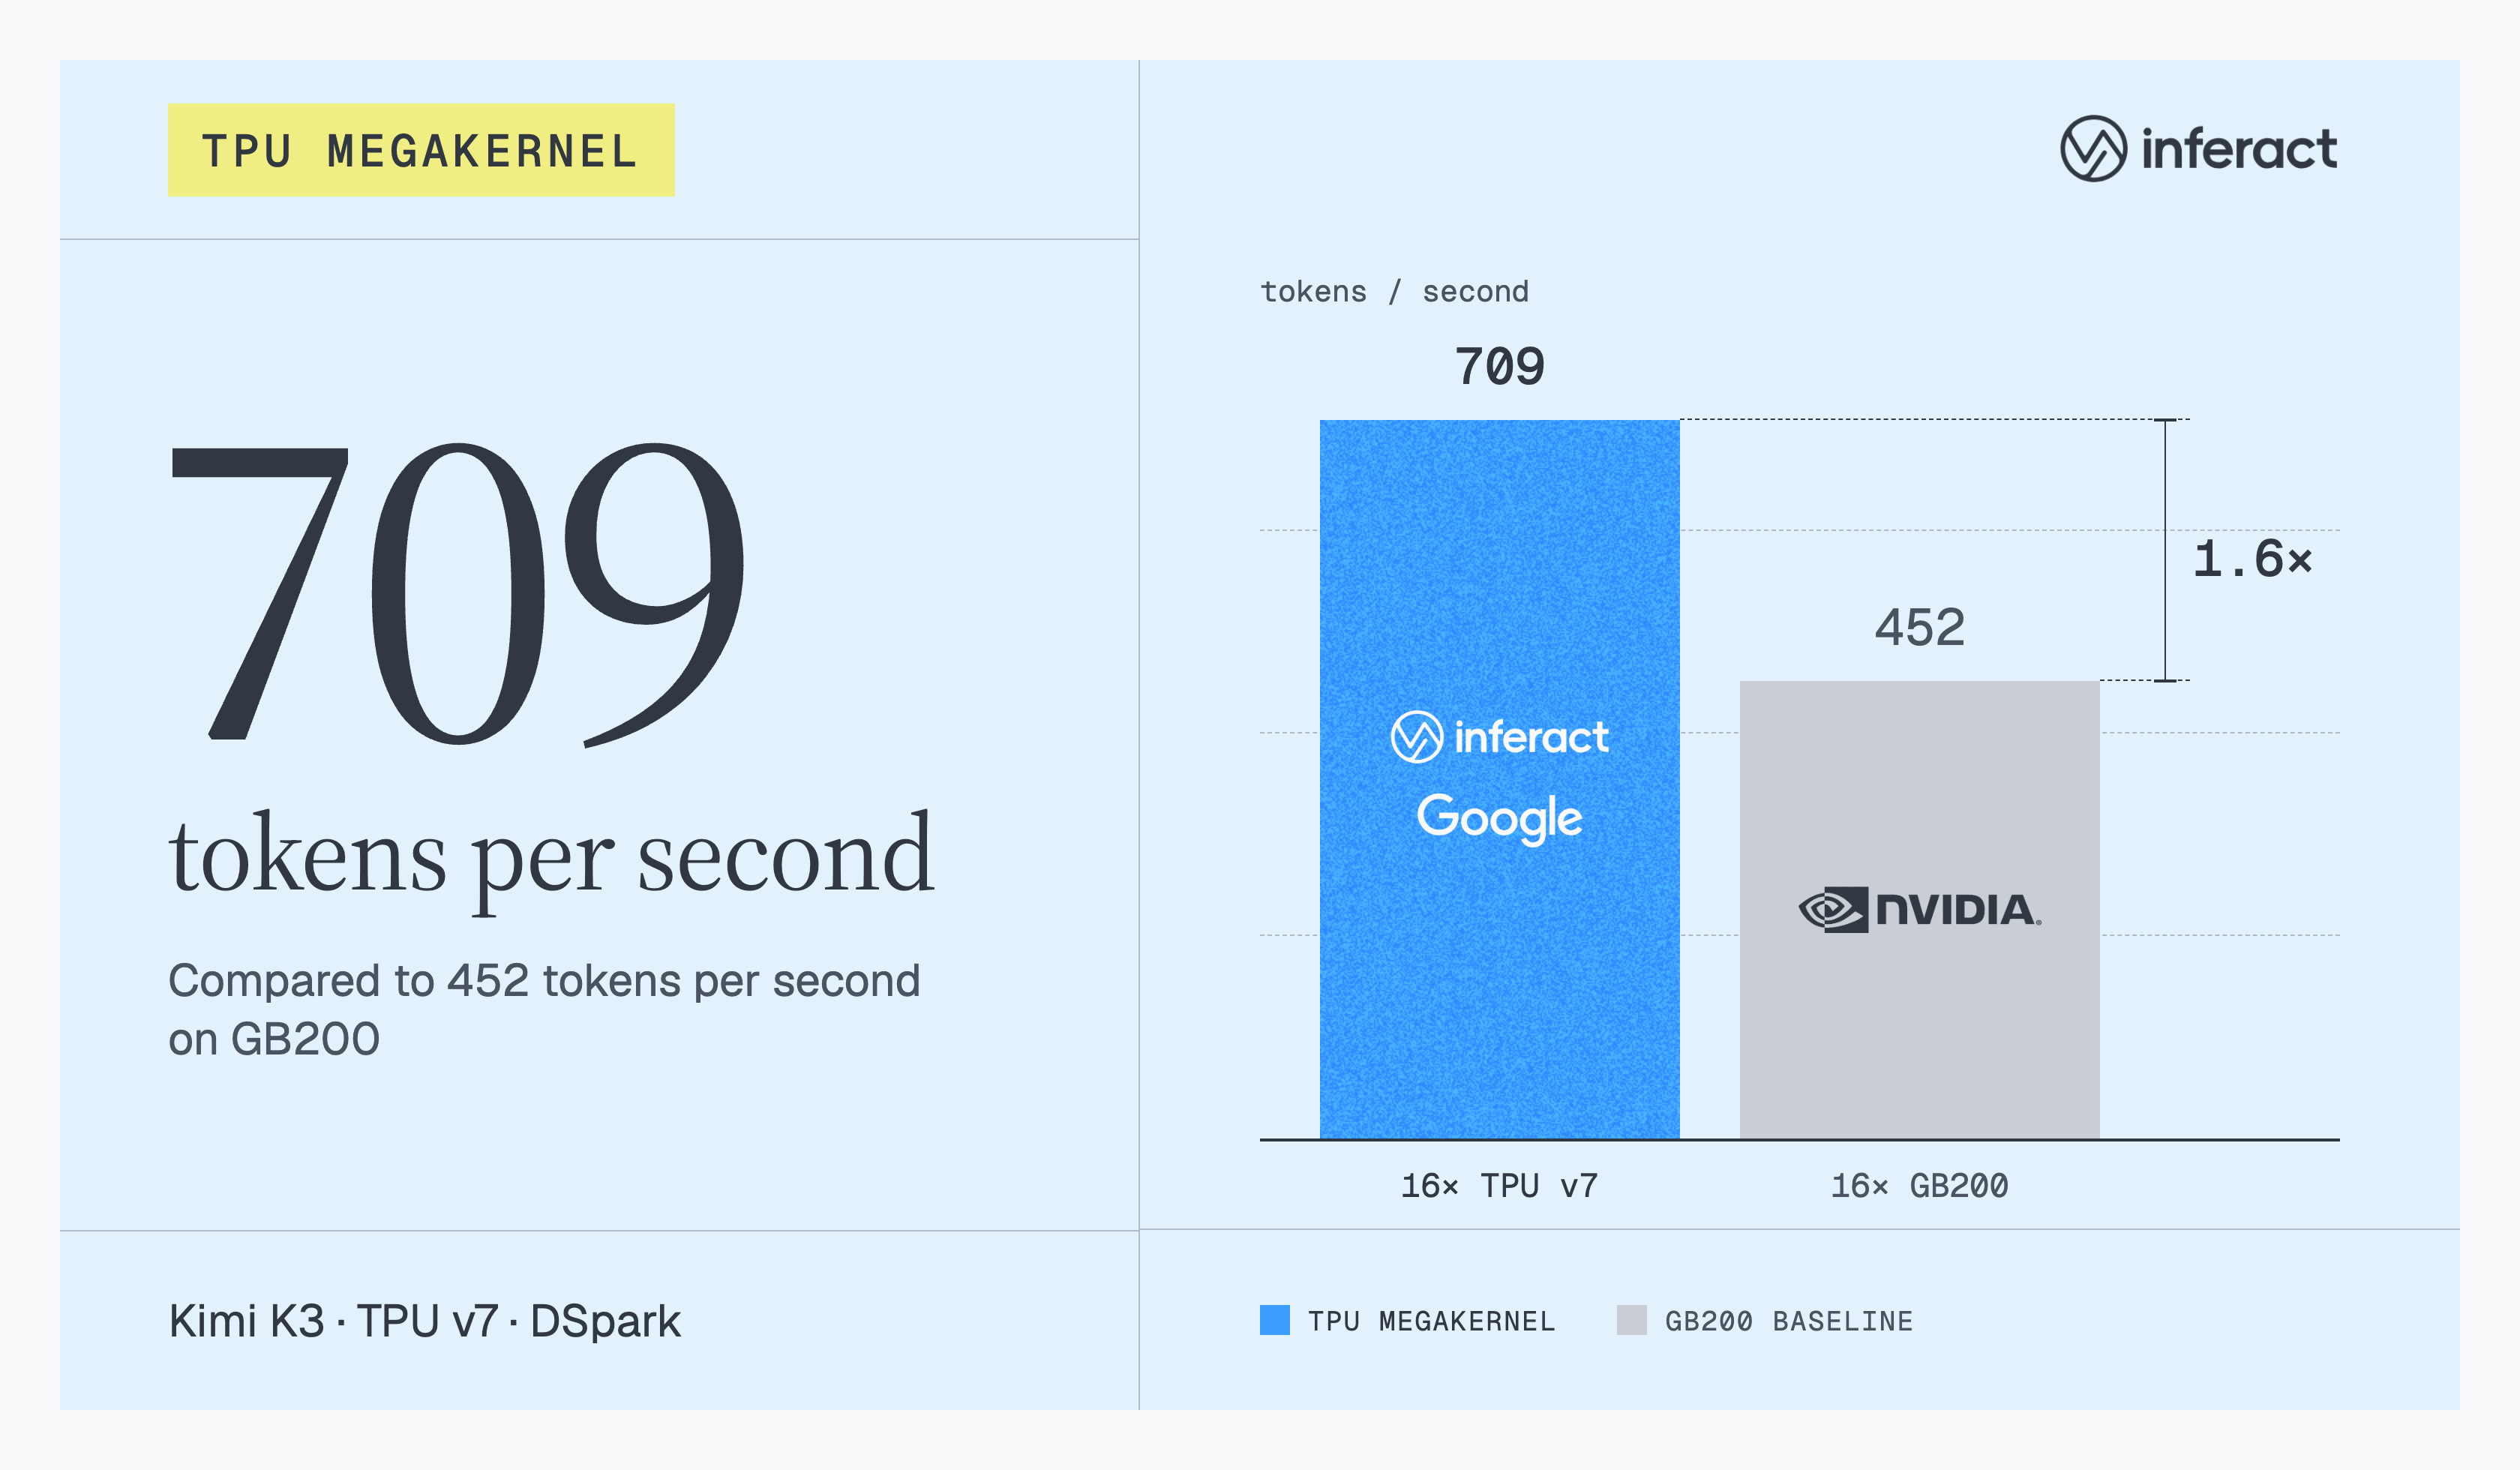
163Inferact/tpu-megakernels · PythonA companion research repo with fused 'megakernel' decode implementations for two models on Google TPUs: Kimi K3 with DSpark speculative decoding, and Qwen3.8-27B with DFlash2 speculative decoding, written to accompany the blog post '700 TPS on Kimi K3: A Case for TPU Megakernels'.
- 52

hyperflow
146Video-Rebirth/hyperflow · PythonAn 8-step LoRA adapter for MiniMax-H3, a video+audio generation model, trained by data-free flow self-distillation. This repository holds the loader and example scripts that run it on the diffusers Modular Pipeline.
- 53
DMI
65ProjectDMX/DMI · PythonDMI is a decoupled, asynchronous observability stack that gives real-time access to a running LLM's internal state — residual streams, attention patterns, MLP outputs, KV-cache slices, logits — during inference or training, with minimal overhead.
Related topics
Often tagged together