Topics / #mixture-of-experts
Mixture-of-experts projects on GitHub
Model architecture routing inputs to specialized expert subnetworks.
As of , the most-starred Mixture-of-experts projects on GitHub are DeepSeek-V3 (104.5K stars), vllm (94.1K stars) and grok-1 (52.2K stars). GitHub.Locker tracks 47 Mixture-of-experts repositories with 571.1K stars combined. The fastest-growing on October 18 was Strata, with +654 stars in a day.
Hot right now
Most stars gained in a day · Oct 18
 +654
Strata
Niko1221/Strata · ★ 27.7KStrata runs Qwen3.8-Flash-Next, a 125-billion-parameter AI model, on a normal gaming PC with one NVIDIA GPU (12-24GB VRAM) and 64GB of RAM, with a one-click installer for Windows and Linux.
 +151
colibri
JustVugg/colibri · ★ 42.8KColibri is an open-source engine for running frontier mixture-of-experts (MoE) language models on hardware you already own — written in pure C with zero dependencies.
 +94
how-to-train-your-gpt
raiyanyahya/how-to-train-your-gpt · ★ 4KA 12-chapter, 7,500+ line interactive textbook that teaches you how to build, train and run a modern GPT-style language model completely from scratch, with every line of code commented and explained in plain English.
 +83
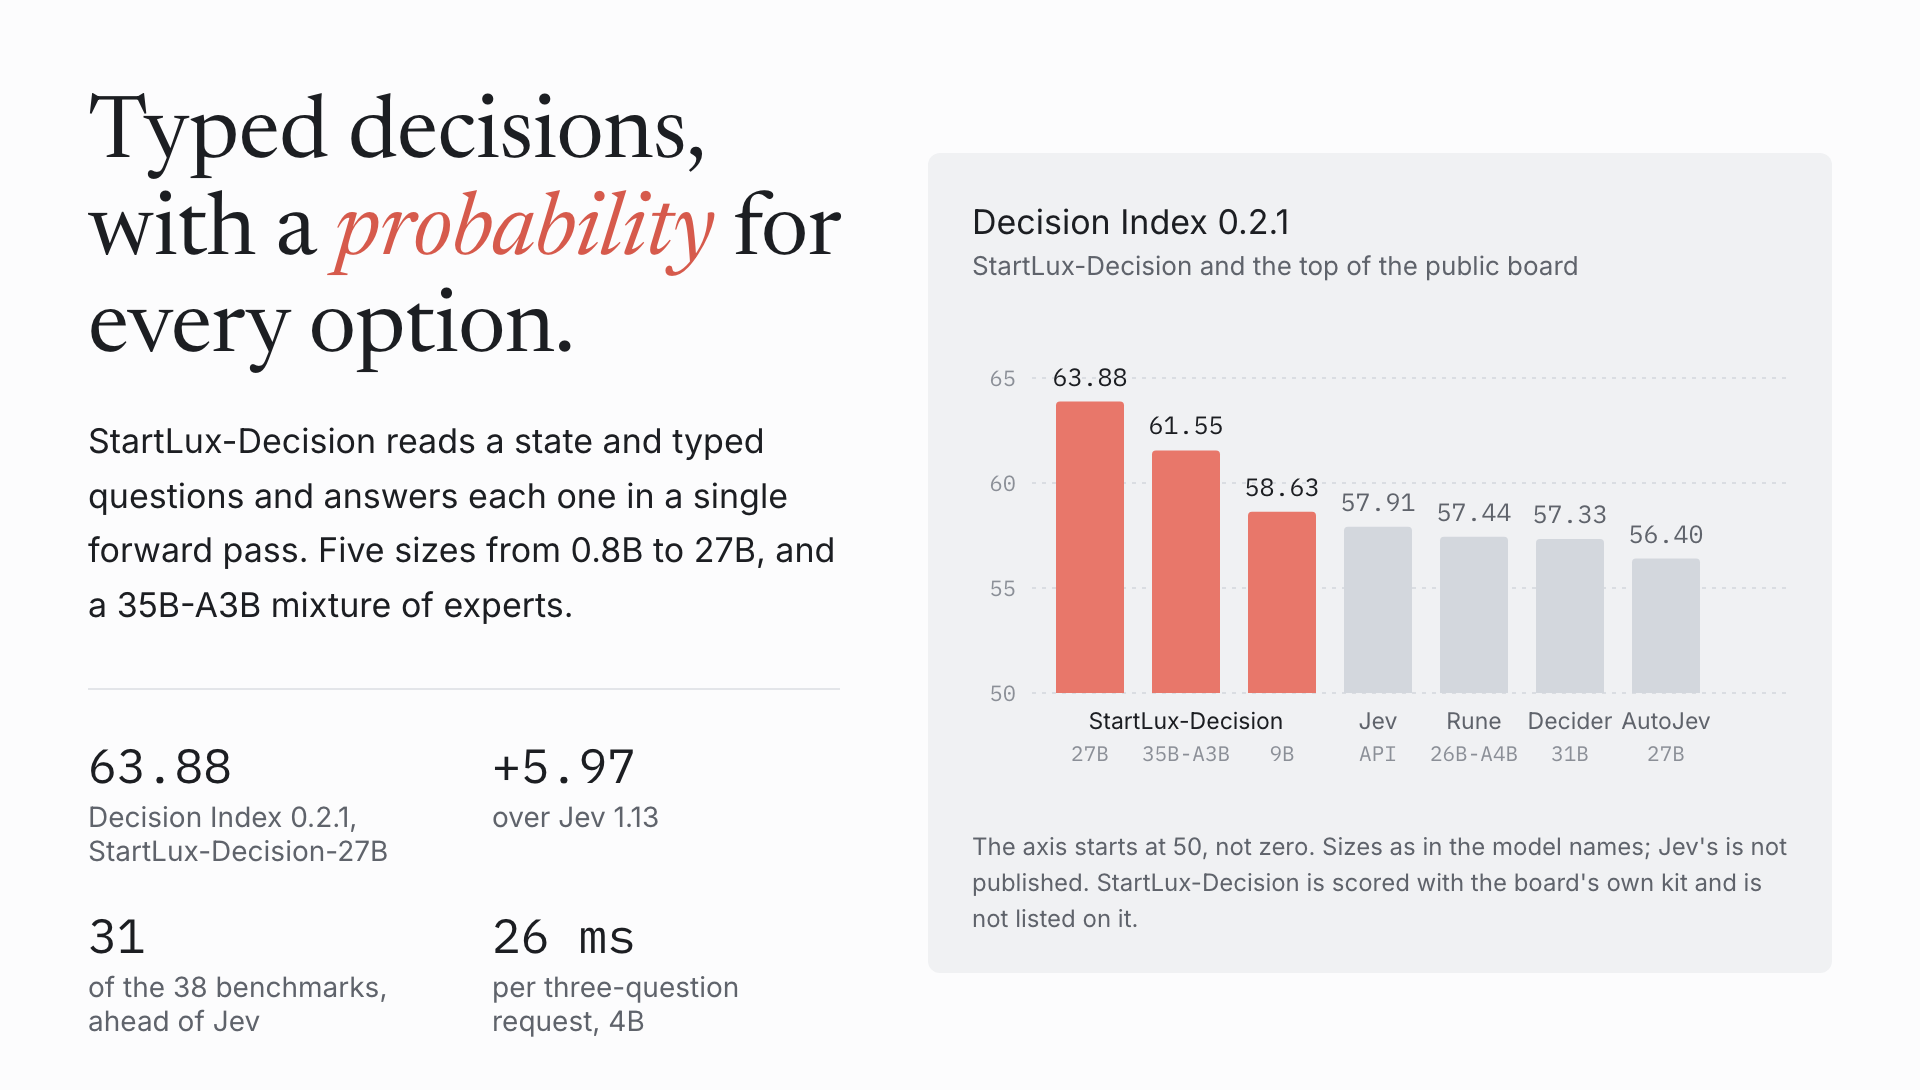
StartLux-Decision
StartLuxLabs/StartLux-Decision · ★ 727StartLux-Decision is a family of typed decision models (five dense sizes from 0.8B to 27B plus a 35B-A3B mixture-of-experts) that answer a question with a probability for each option instead of generating text.
The all-time top
47 projects · by stars
- 104.5K
 #1 · deepseek-ai/DeepSeek-V3
DeepSeek-V3
DeepSeek-V3 is an open-weight Mixture-of-Experts (MoE) language model with 671B total parameters but only 37B activated per token, built for efficient yet high-performing inference and matching leading closed-source models on many benchmarks.
- 94.1K
 #2 · vllm-project/vllm
vllm
vLLM is a library for fast LLM inference and serving, built around PagedAttention for efficient memory management of attention keys and values.
- 52.2K
 #3 · xai-org/grok-1
grok-1
Grok-1 is the 314B-parameter Mixture-of-Experts language model that xAI opened up; this repository holds the JAX example code for loading and running it.
- 4
DeepSpeed
43.2Kdeepspeedai/DeepSpeed · PythonDeepSpeed is a deep learning optimization library that makes distributed training and inference of very large models easy, efficient and effective — it powered models like MT-530B and BLOOM.
- 5
colibri
42.8KJustVugg/colibri · CColibri is an open-source engine for running frontier mixture-of-experts (MoE) language models on hardware you already own — written in pure C with zero dependencies.
- 6

Qwen3
27.7KQwenLM/Qwen3 · PythonQwen3 is a series of open-weight large language models built by the Qwen team at Alibaba Cloud, released as both dense and Mixture-of-Experts (MoE) models from 0.6B up to 235B-A22B parameters, with switchable 'thinking' and 'non-thinking' reasoning modes.
- 7
Strata
27.7KNiko1221/Strata · C++Strata runs Qwen3.8-Flash-Next, a 125-billion-parameter AI model, on a normal gaming PC with one NVIDIA GPU (12-24GB VRAM) and 64GB of RAM, with a one-click installer for Windows and Linux.
- 8
ktransformers
19.6Kkvcache-ai/ktransformers · PythonKTransformers is a research framework for efficient inference and fine-tuning of large language models through CPU-GPU heterogeneous computing, letting huge MoE models run on hardware that doesn't have enough VRAM to hold them entirely on GPU.
- 9
Swin-Transformer
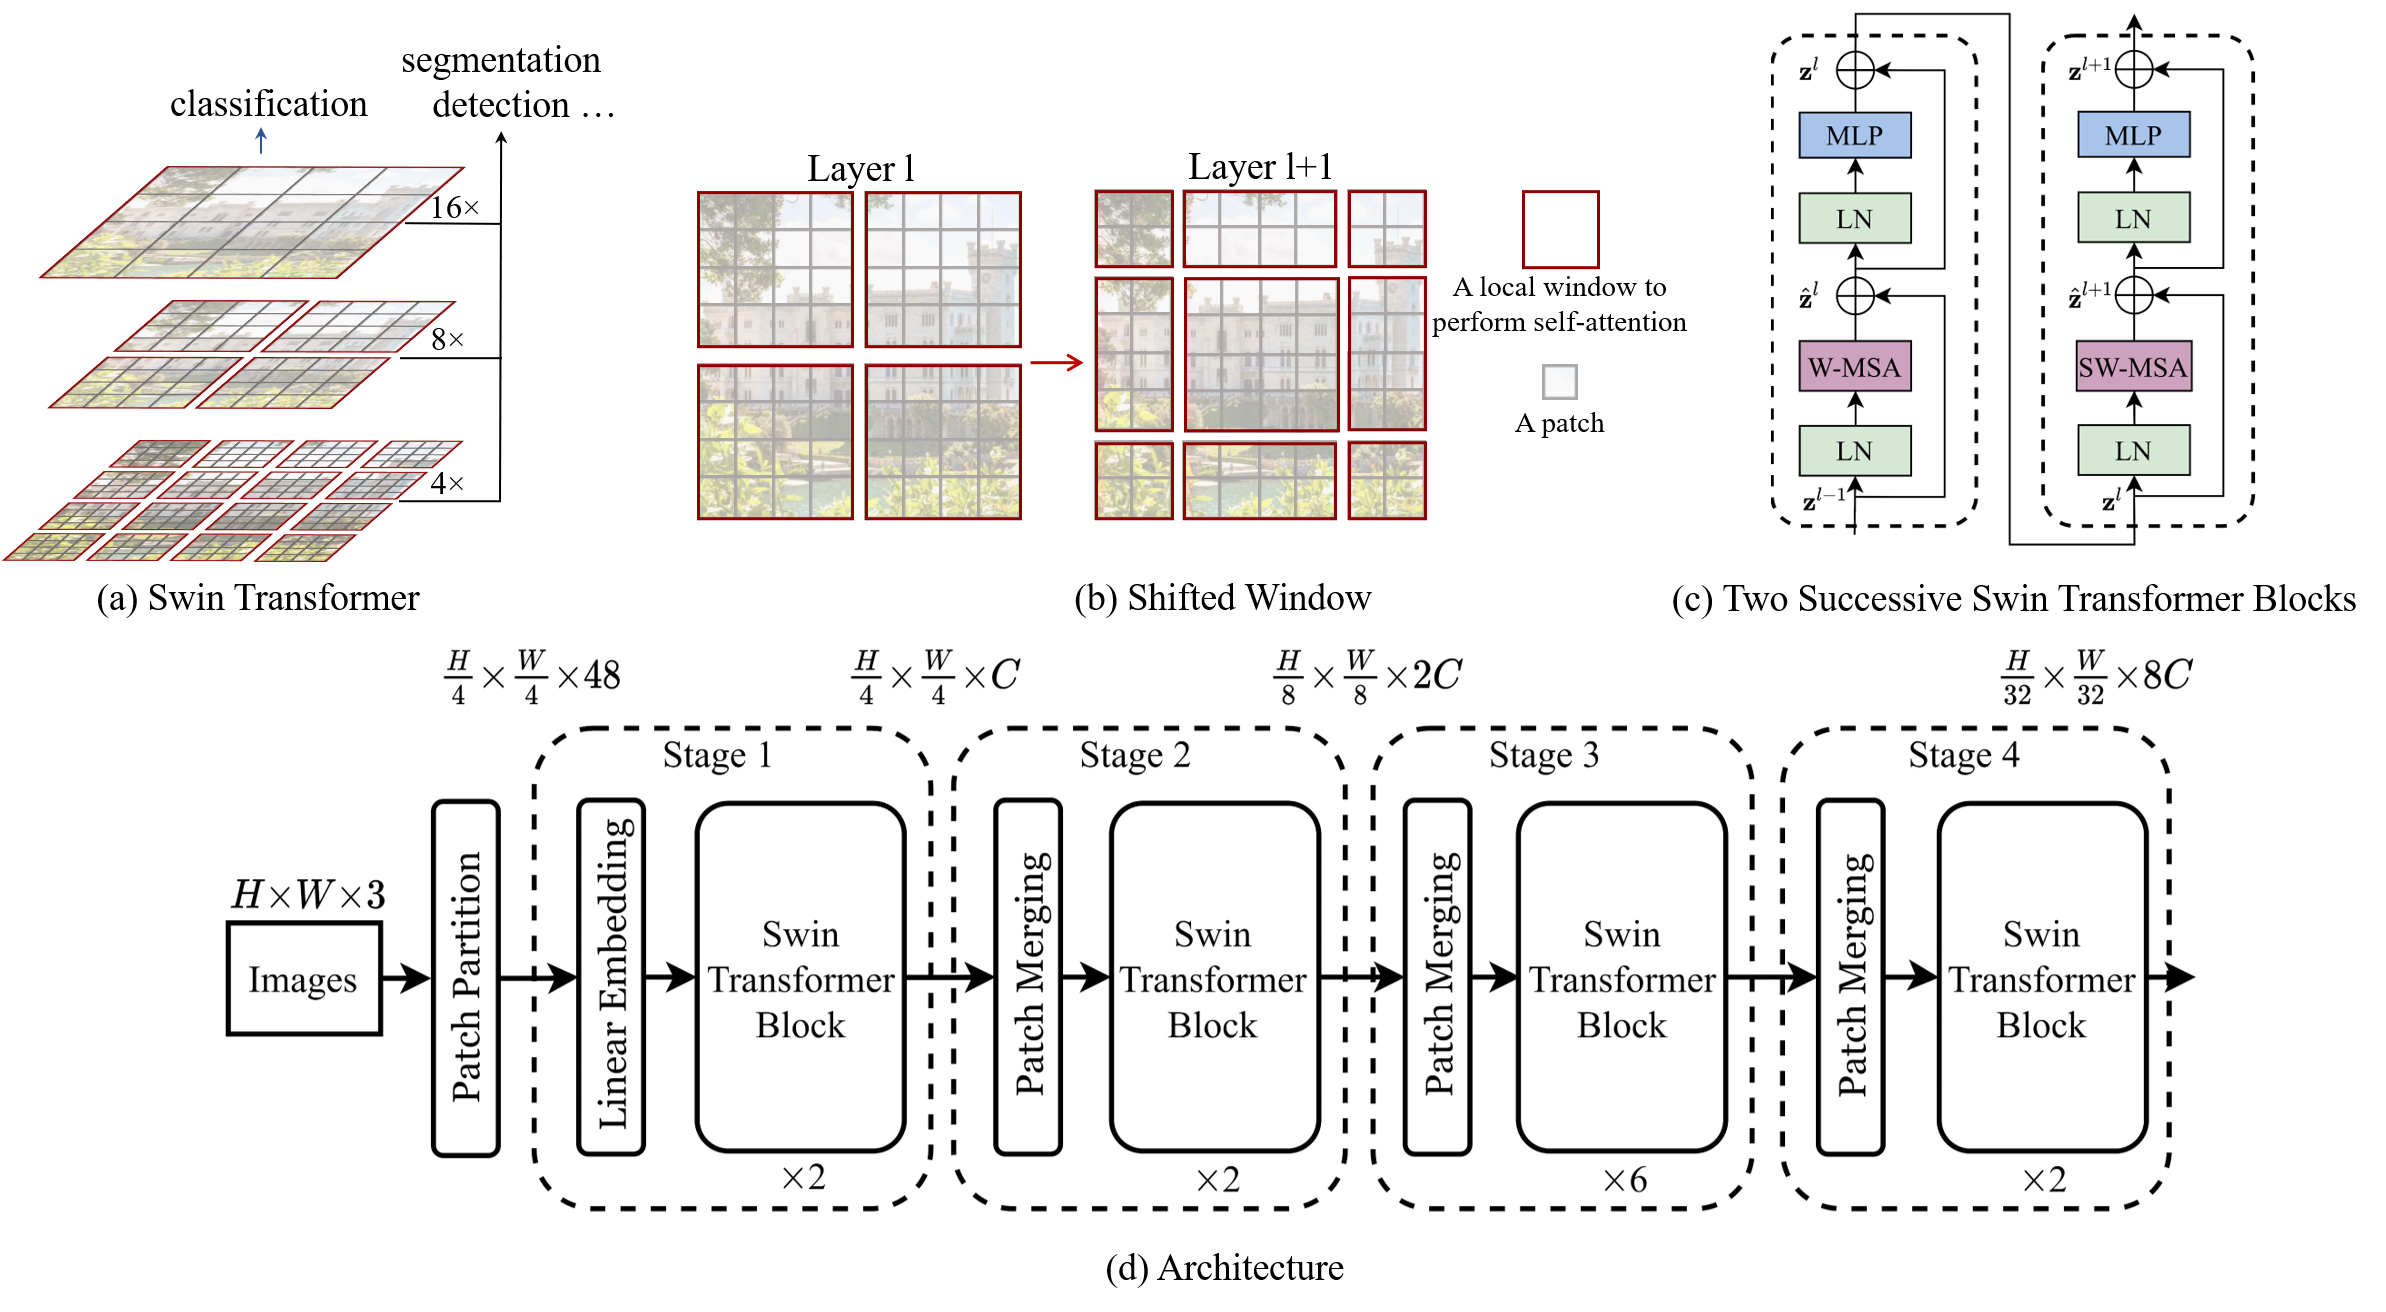
16.1Kmicrosoft/Swin-Transformer · PythonThe official Microsoft implementation of the Swin Transformer paper and its follow-ups: a hierarchical vision Transformer that computes attention with shifted windows and serves as a general-purpose backbone for computer vision tasks.
- 10
llm_interview_note
15.3Kwdndev/llm_interview_note · HTMLThis is a curated Chinese-language knowledge base of large language model (LLM) concepts and interview questions, aimed at algorithm/application engineers preparing for LLM-related job interviews.
- 11

OpenMythos
14.9Kkyegomez/OpenMythos · PythonOpenMythos is an open-source, speculative PyTorch implementation that tries to reconstruct the internal architecture of Anthropic's Claude ('Mythos') purely from publicly available research papers, not from any leaked or official Anthropic code.
- 12
PaddleFormers
13KPaddlePaddle/PaddleFormers · PythonPaddleFormers is a Transformers-style library built on Baidu's PaddlePaddle deep learning framework, giving the PaddlePaddle ecosystem the same kind of model interface and training workflow as Hugging Face Transformers, with full training support for 100+ LLMs and vision-language models.
- 13
Kimi-K2
11.1KMoonshotAI/Kimi-K2Kimi K2 is a large language model series from Moonshot AI: a mixture-of-experts model with 1 trillion total parameters (32B activated per token), trained for frontier knowledge, reasoning, coding and especially agentic tool-use tasks.
- 14

DeepEP
10.3Kdeepseek-ai/DeepEP · CudaDeepEP is a high-performance communication library for MoE (mixture-of-experts) models, providing fast all-to-all GPU kernels for expert-parallel dispatch and combine operations used in ML training and inference.
- 15
kimi-k3-in-c
9.1KFareedKhan-dev/kimi-k3-in-c · CAn inference engine for the 2.78-trillion-parameter Kimi K3 model, written in portable C99. It runs on a plain CPU in as little as 8 GB of RAM — no GPU, no BLAS, no framework — streaming the 1.56 TB checkpoint straight off disk.
- 16
DeepGEMM
9Kdeepseek-ai/DeepGEMM · CudaDeepGEMM is a unified CUDA kernel library that provides high-performance tensor core GEMM operations (FP8, FP4, BF16), fused MoE kernels, and attention-indexer kernels used in large language models such as DeepSeek.
- 17
Kimi-K3
8.9KMoonshotAI/Kimi-K3Kimi K3 is MoonshotAI's open-weight, native multimodal agentic model — a 2.8T-parameter Mixture-of-Experts system built for frontier-level long-horizon coding, agentic knowledge work, and reasoning.
- 18

GLM-5
7.4Kzai-org/GLM-5GLM-5 is a family of large open-weight language models from Z.ai built for agentic engineering and complex, long-horizon coding tasks, scaling up to 744B parameters with sparse attention for efficient long-context serving.
- 19
turbo-fieldfare
6.9Kdrumih/turbo-fieldfare · SwiftTurboFieldfare is a custom Swift and Metal runtime that runs the instruction-tuned Gemma 4 26B-A4B model on Apple Silicon Macs using only about 2 GB of RAM, even on 8 GB machines, by streaming only the experts needed for each token from SSD instead of loading the full 14.3 GB model.
- 20
ai-infra-book
6.7Kbojieli/ai-infra-book · PythonAn open-source book, 'Understanding AI Infra: Quantitative Analysis and System Design' by Bojie Li, that derives LLM inference and training system designs from hardware constraints and model architecture using quantitative, order-of-magnitude estimates.
- 21
Engram
4.8Kdeepseek-ai/Engram · PythonThis is the official code release for the DeepSeek paper 'Conditional Memory via Scalable Lookup', introducing Engram, a module that gives Transformers a native knowledge-lookup primitive by modernizing classic N-gram embeddings for O(1) retrieval, as a complement to Mixture-of-Experts sparsity.
- 22
Qwen3.8
4.3KQwenLM/Qwen3.8Qwen3.8 is the latest open large language model release from Alibaba's Qwen team, part of the Qwen3.5 series that also includes Qwen3.5 and Qwen3.6, aimed at coding, professional work, research, and long-horizon agentic tasks.
- 23
how-to-train-your-gpt
4Kraiyanyahya/how-to-train-your-gpt · Jupyter NotebookA 12-chapter, 7,500+ line interactive textbook that teaches you how to build, train and run a modern GPT-style language model completely from scratch, with every line of code commented and explained in plain English.
- 24

warp
2.5Ksqliteai/warp · CWARP (Weight-Aware Runtime and Paging, formerly WASTE) is a dependency-free, embeddable C inference engine that runs huge mixture-of-experts models on consumer hardware by streaming each token's activated weights straight from NVMe — the full models, not distilled versions.
- 25
Hy-MT2
1.3KTencent-Hunyuan/Hy-MT2 · PythonHy-MT2 is Tencent Hunyuan's family of 'fast-thinking' multilingual translation models, released in three sizes (1.8B, 7B, and 30B-A3B MoE), that translate among 33 languages and follow complex translation instructions.
- 26
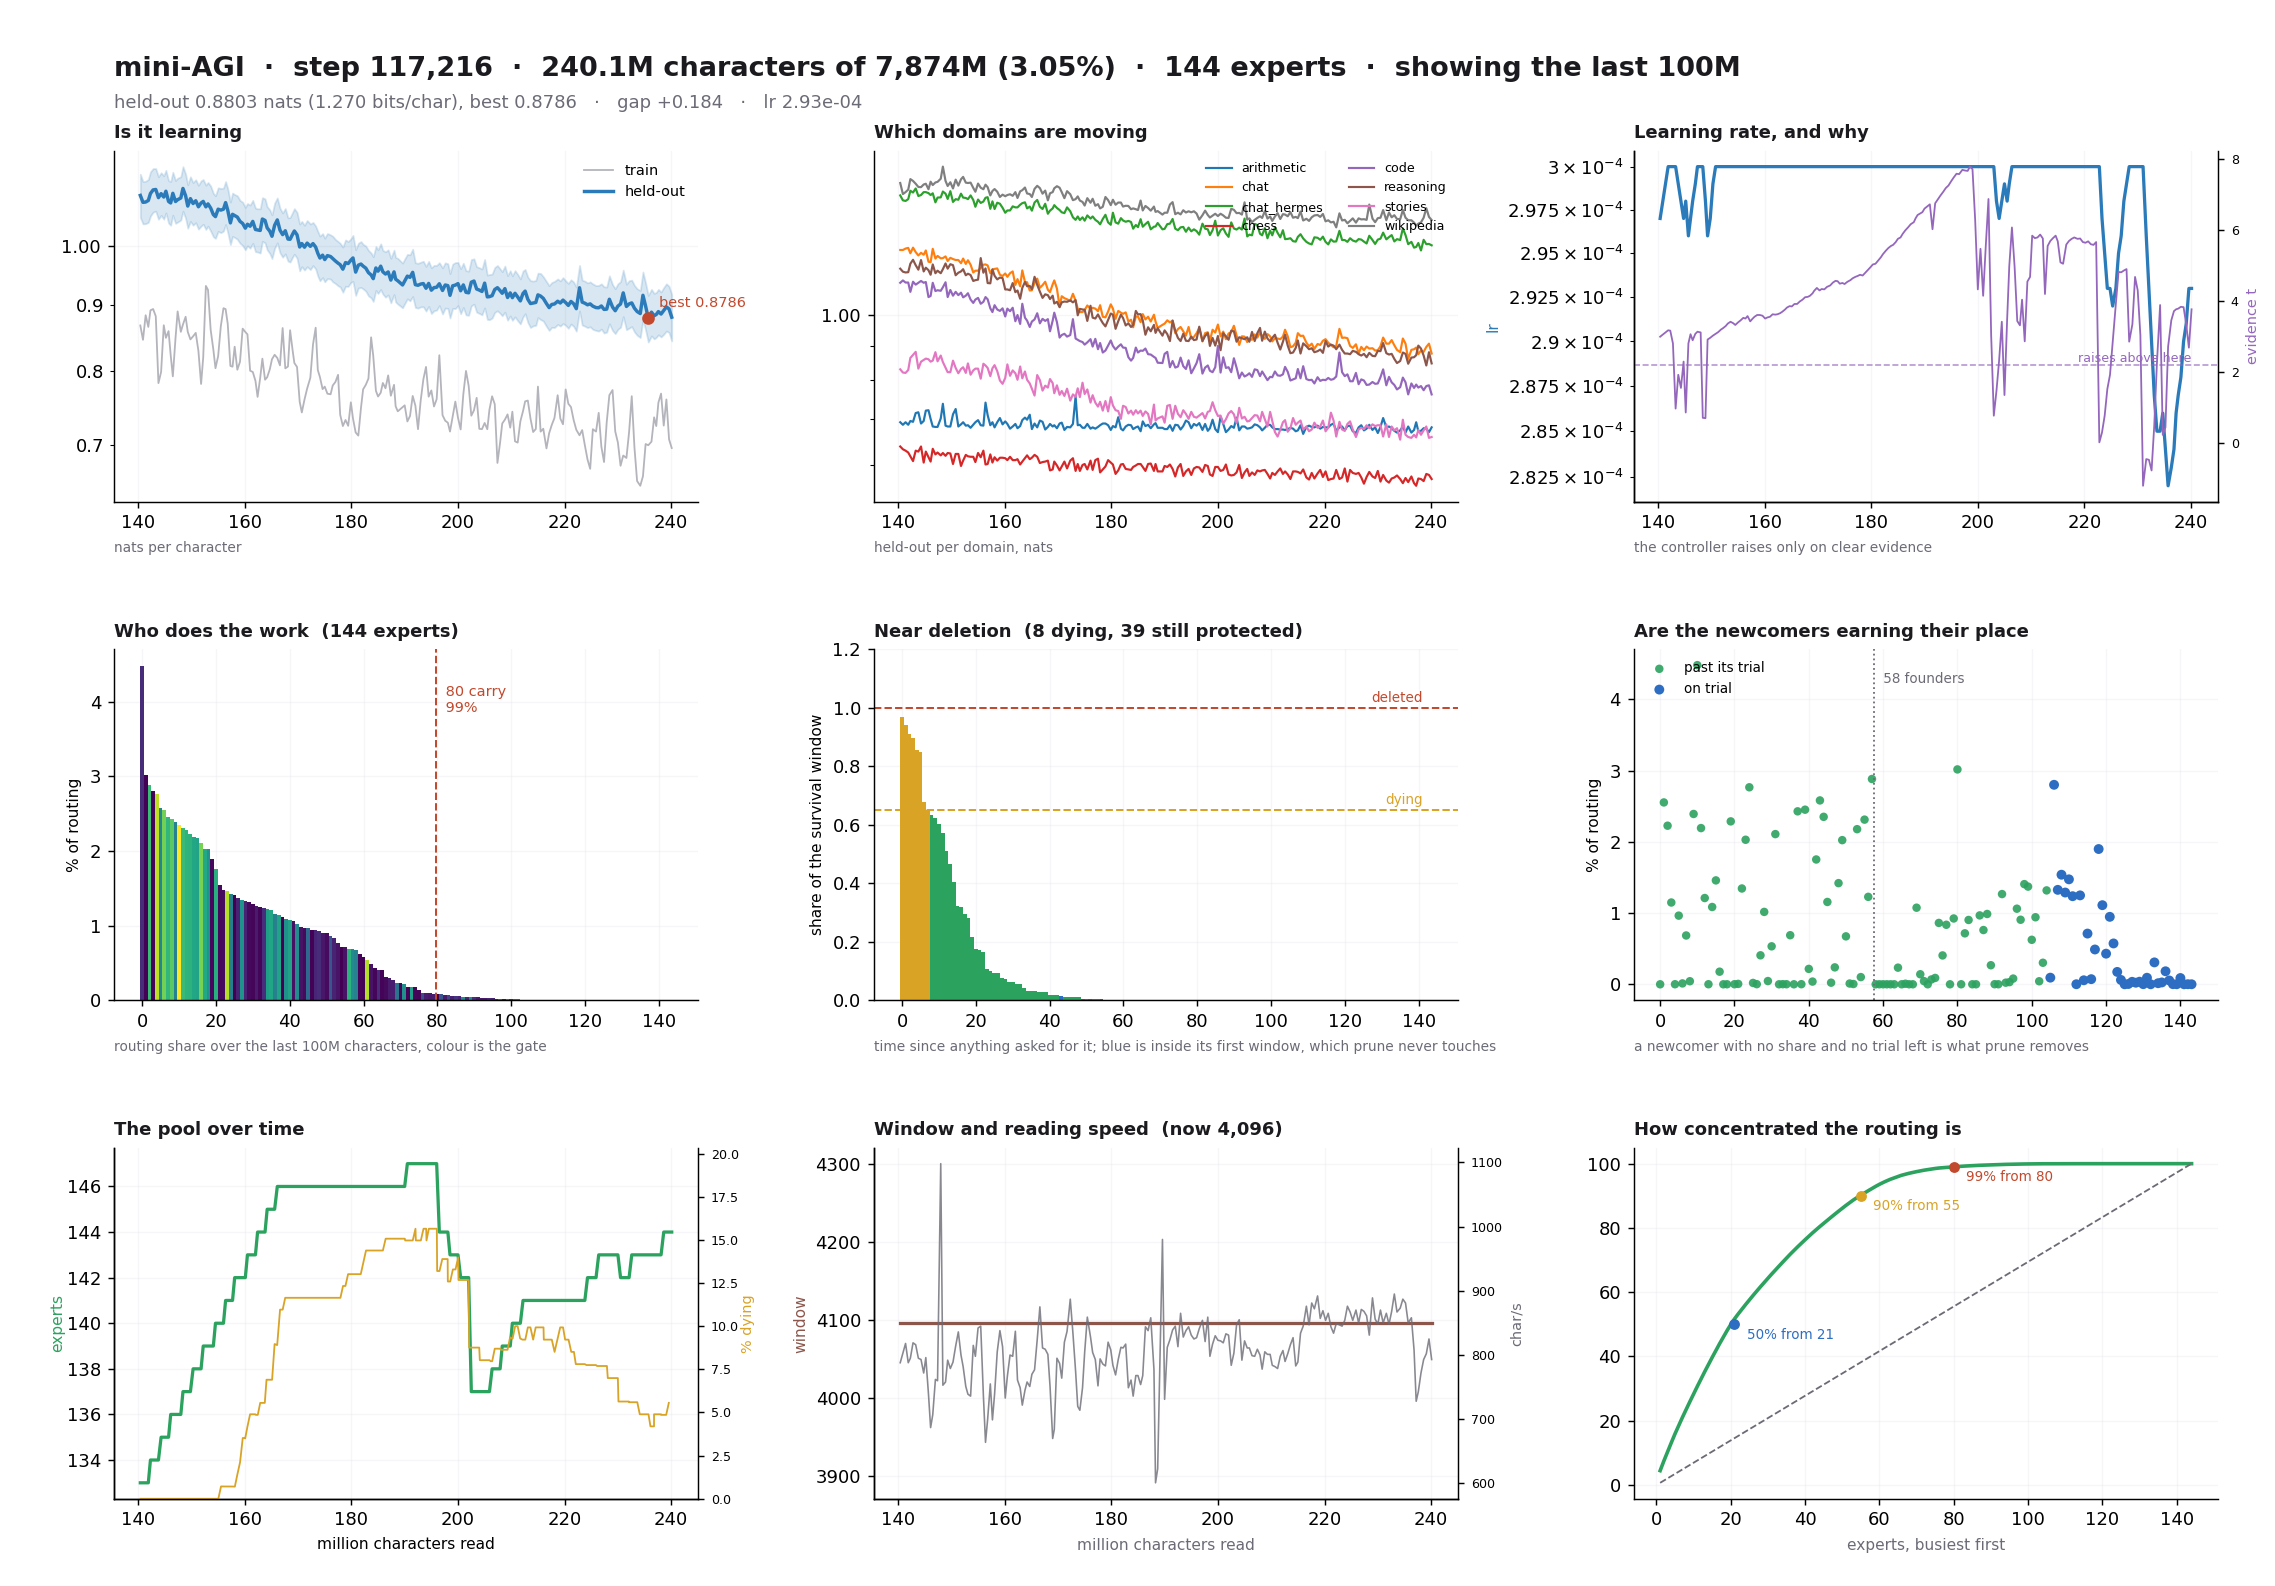
mini-AGI
1.3Kvolotat/mini-AGI · Pythonmini-AGI is a continual learning, byte-level language model that assembles its own architecture, trains from scratch on a single 8GB VRAM GPU, and keeps learning from everything it reads, without a separate fine-tuning phase.
- 27
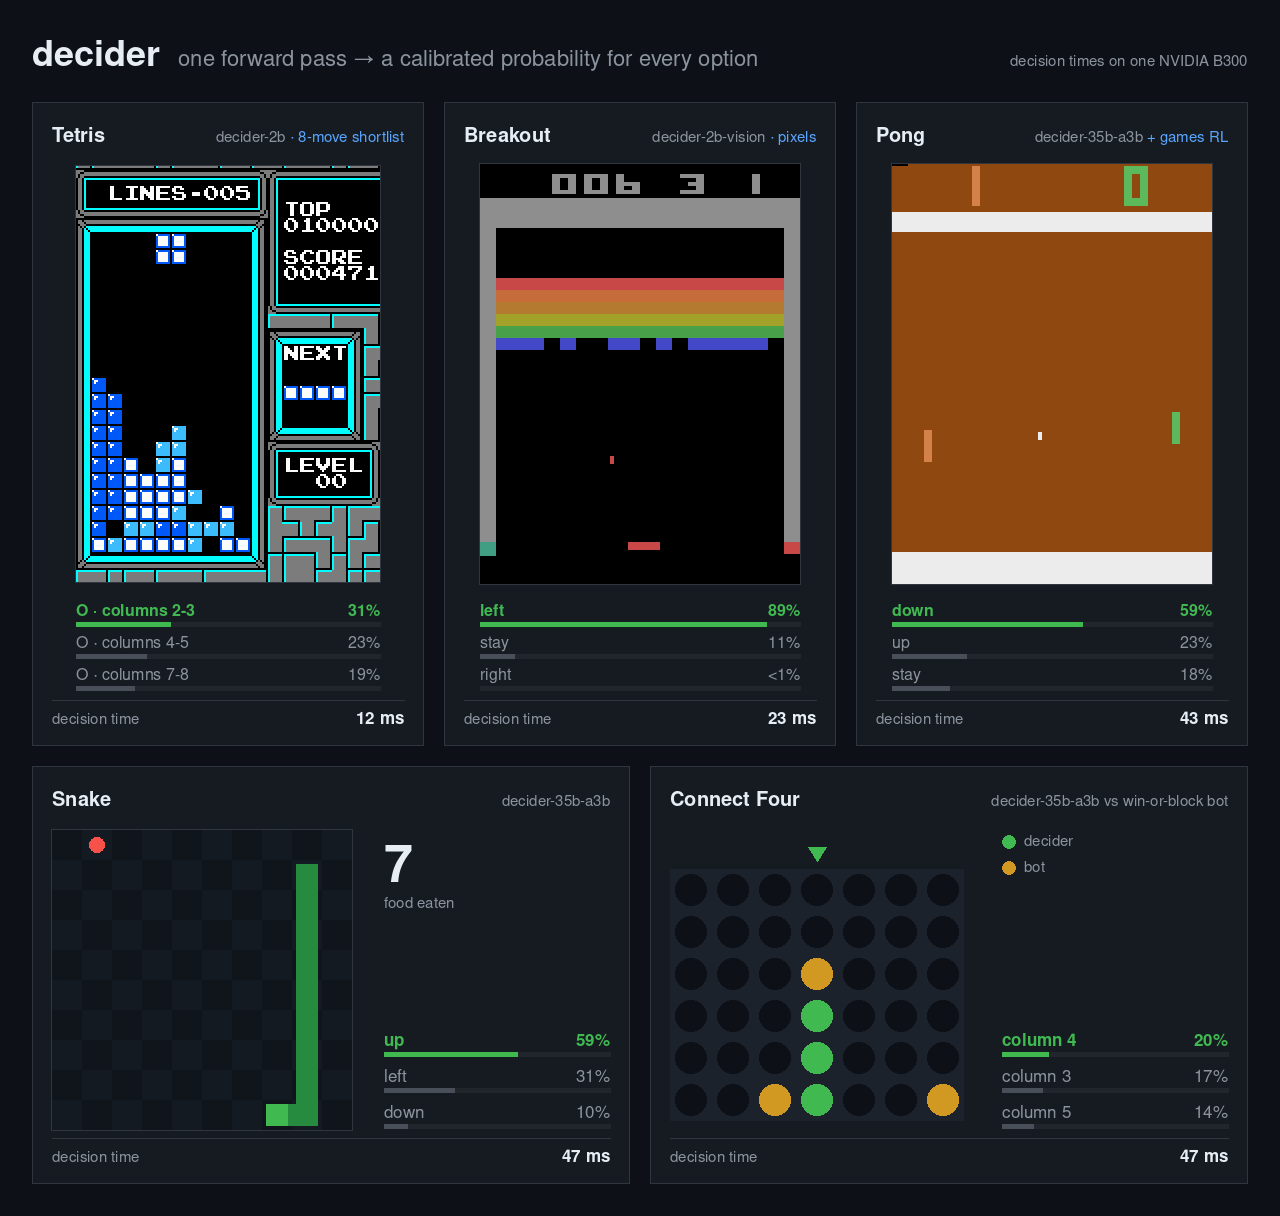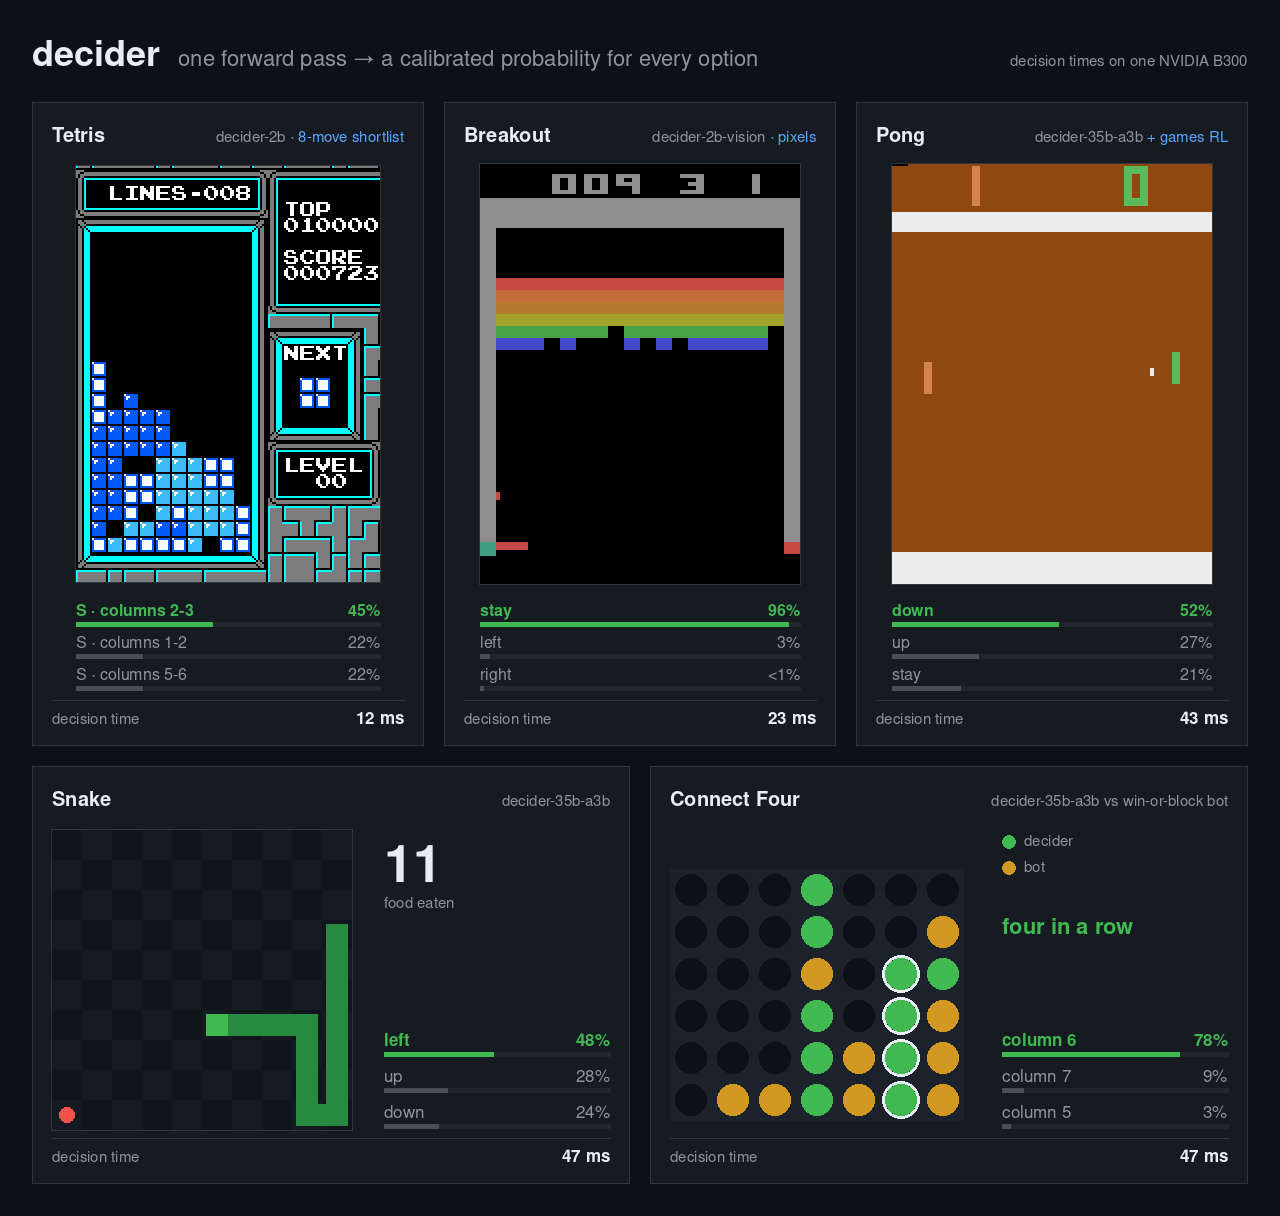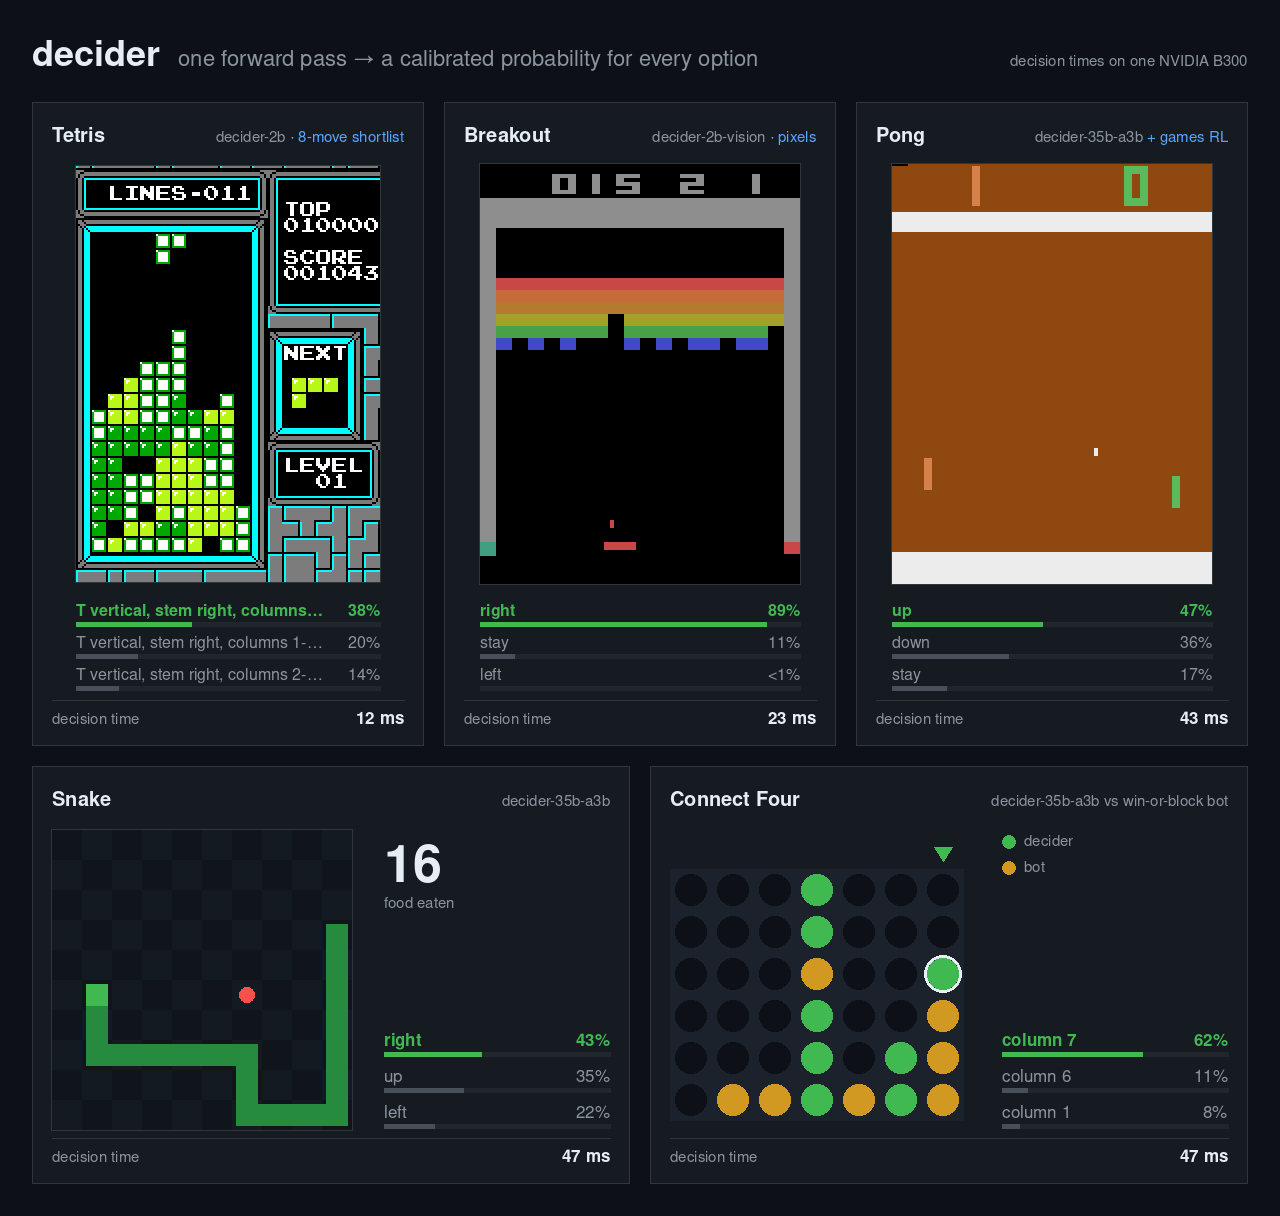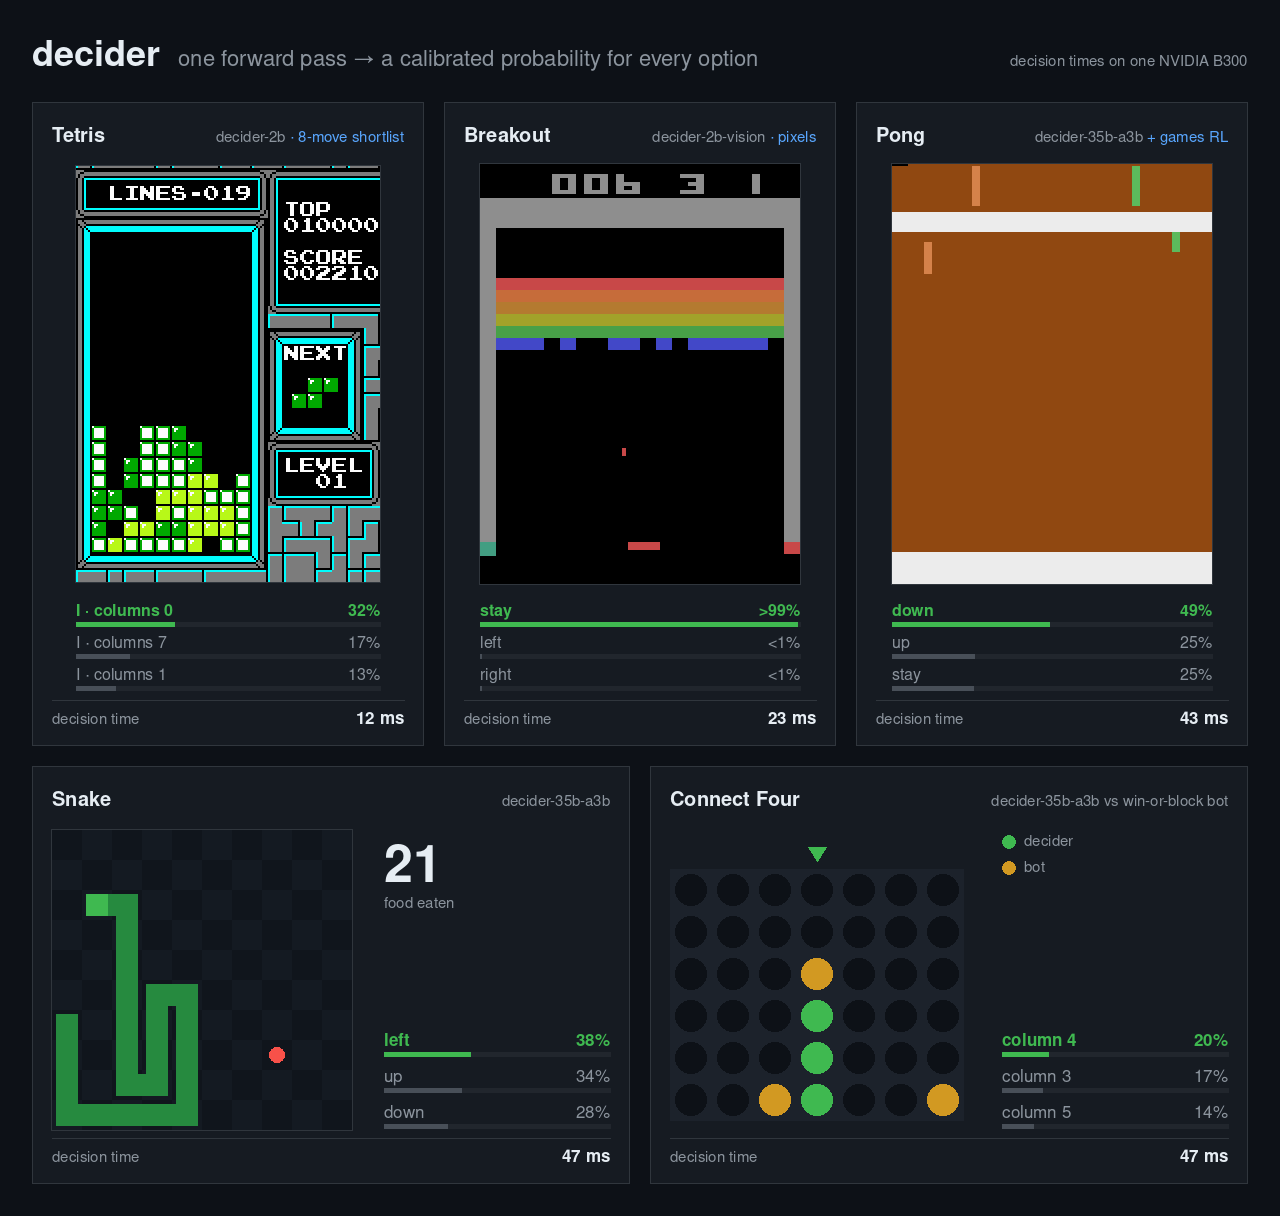
decider
1.2KMapika/decider · PythonDecider is a family of language models fine-tuned from Qwen3.5 that don't generate text; instead they read a state plus a set of typed questions and return calibrated probability distributions for every question in one forward pass.
- 28

project-maya
1Kmw00/project-maya · C++Project Maya lets you run GLM-5.3-Flash, a 321-billion-parameter mixture-of-experts AI model, on your own NVIDIA GPU(s) by streaming the model's experts across VRAM, RAM and NVMe SSD as the conversation needs them.
- 29
halogen-flash-server
1Kpeonist-ai/halogen-flash-server · Shellhalogen-flash-server is a purpose-built inference server for running the Qwen3.8-Flash-Next model as fast as possible on AMD's Strix Halo (gfx1151) GPU, exposing an OpenAI-compatible API.
- 30

llm-architecture-from-scratch
1KYeonwooSung/llm-architecture-from-scratch · PythonA collection of PyTorch implementations of modern LLM architectures (GPT-2, Llama 3/3.2, Llama 4, OLMo 2, Phi-4, DeepSeek v3, Gemma 3, xLSTM, Mistral 3.1) built from scratch to understand how they work internally.
- 31

deltafin
851gavamedia/deltafin · RustDeltafin is a native Rust binary that runs the full, unpruned 2.8-trillion-parameter Kimi K3 model on a single consumer machine, keeping all 16 experts active, plus an OpenAI-compatible API server for local chat and coding agents.
- 32
openTPU
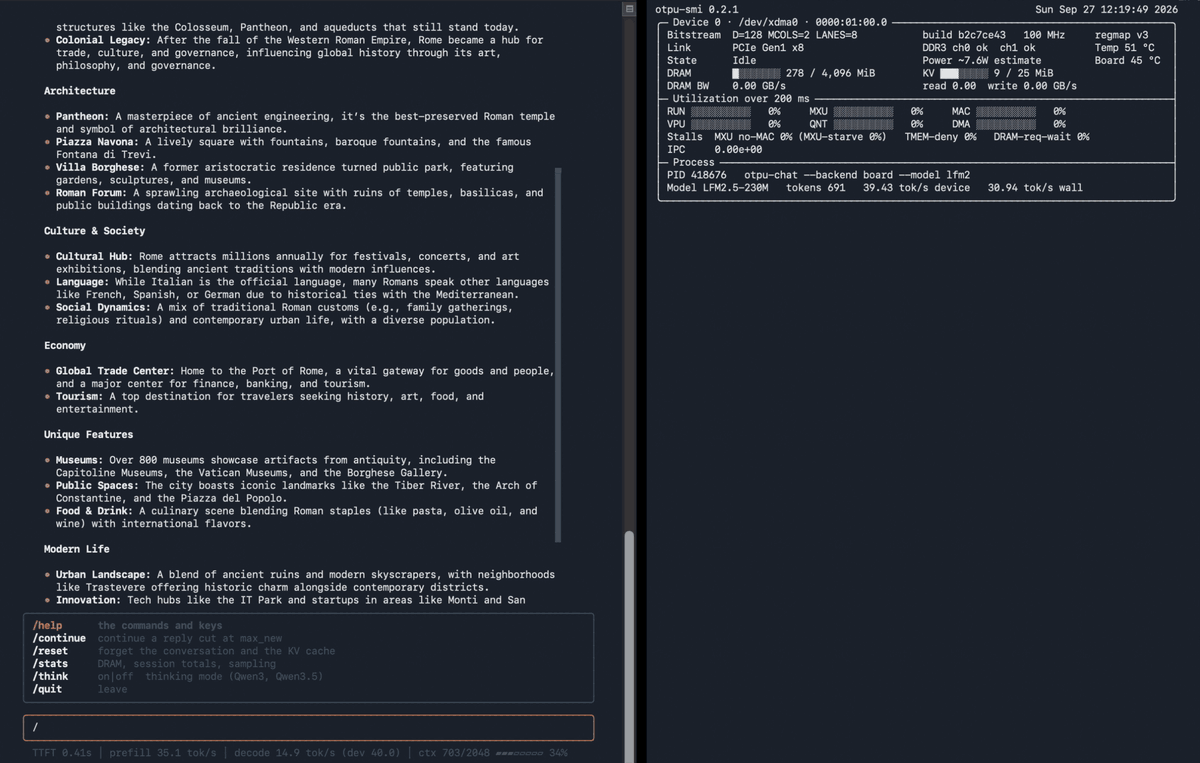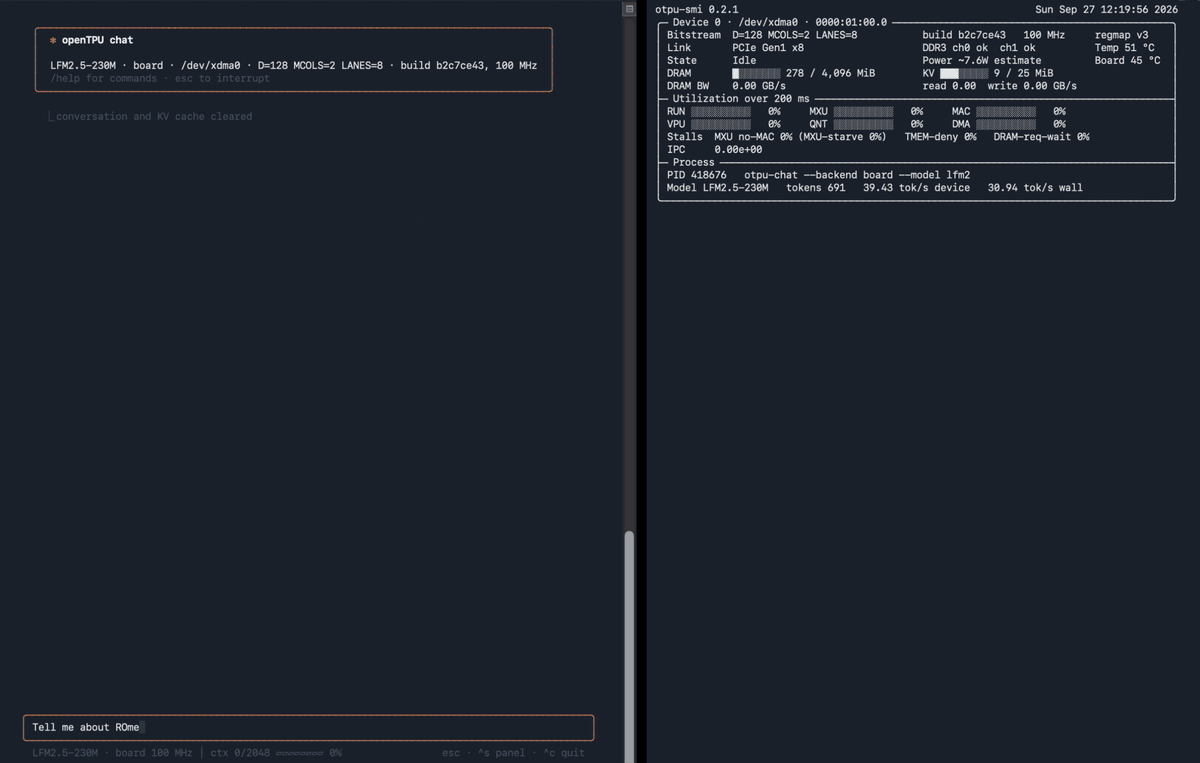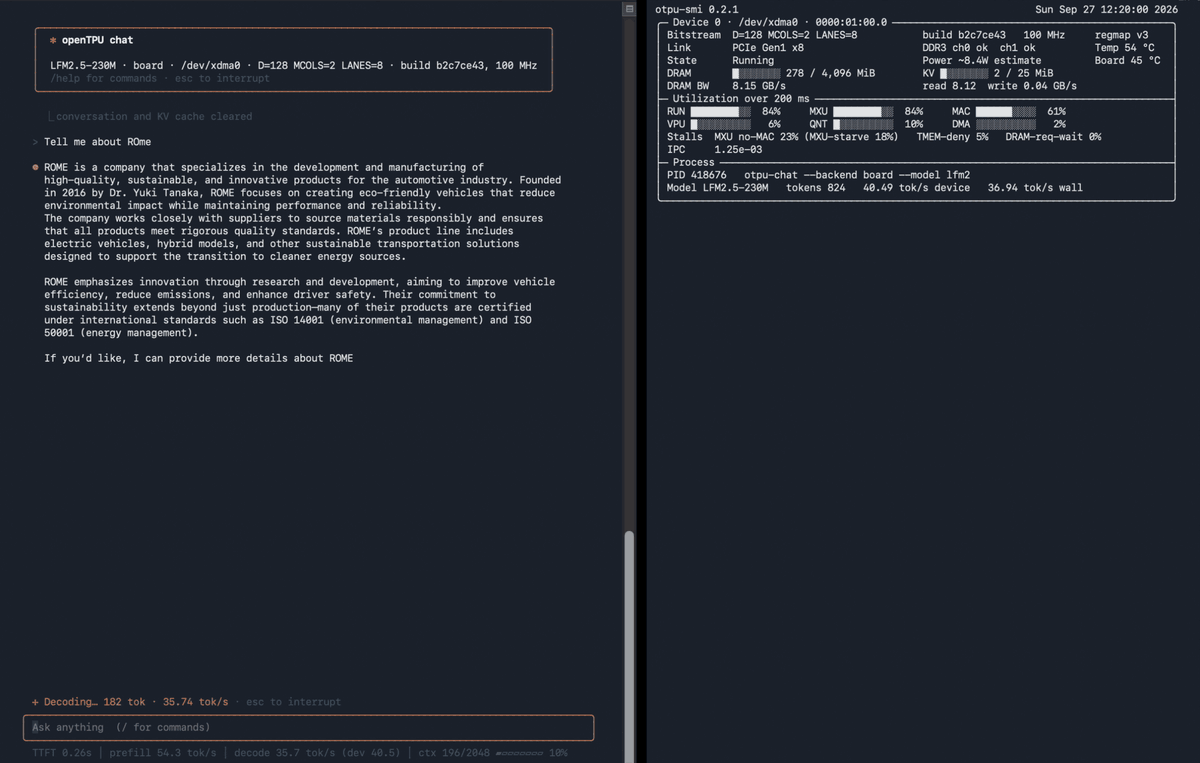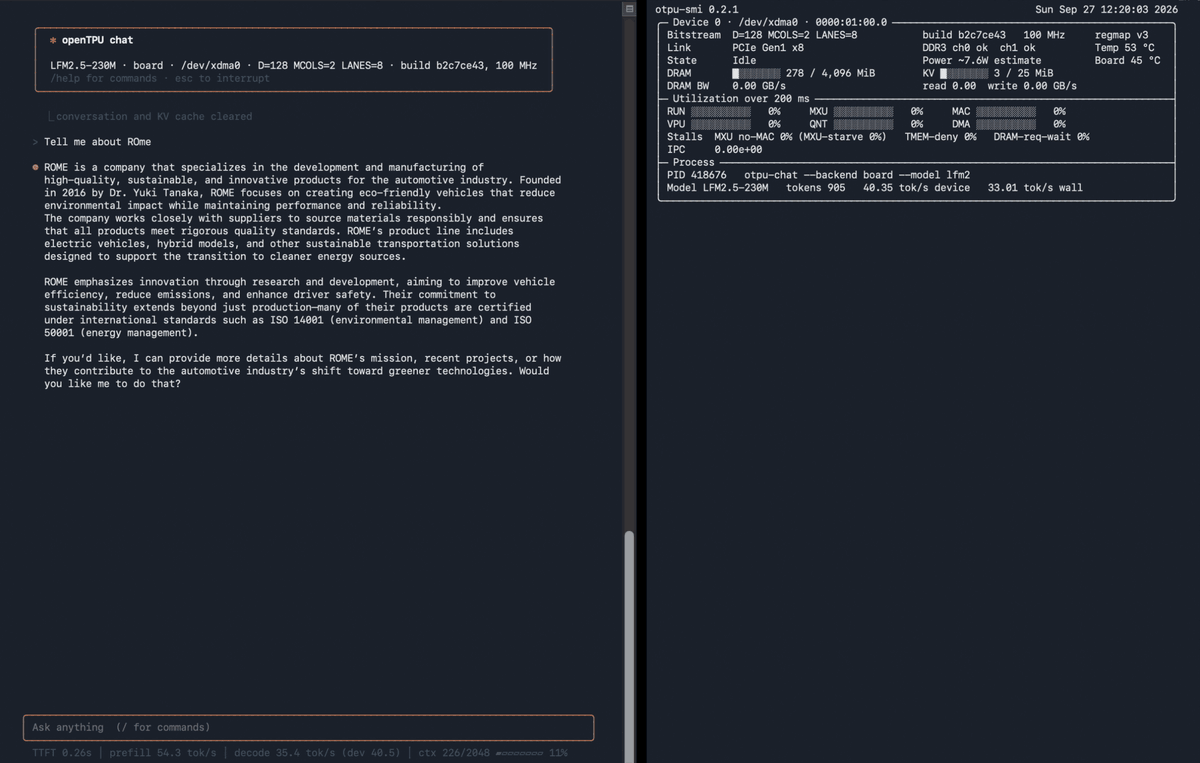
773FeSens/openTPU · VerilogopenTPU is an open-source AI accelerator whose hardware design, instruction set, simulator, compiler and profiler were all built by AI agents, and it runs real LLMs like Qwen3 and LFM2.5 on an FPGA PCIe card.
- 33
StartLux-Decision
727StartLuxLabs/StartLux-Decision · PythonStartLux-Decision is a family of typed decision models (five dense sizes from 0.8B to 27B plus a 35B-A3B mixture-of-experts) that answer a question with a probability for each option instead of generating text.
- 34
ai-system-design
723amitshekhariitbhu/ai-system-design · MarkdownA free, open-source guide that teaches AI System Design step by step: how to combine GPUs, inference servers, caches, vector databases, AI agents, guardrails, and evals into one system that is fast, cheap, reliable, and safe.
- 35

kaggle-tpu-lab
683ARahim3/kaggle-tpu-lab · PythonA recipe that serves frontier-class open LLMs — GLM-5.3-Flash 320B MoE and Qwen3.8-27B bf16 — on Kaggle's free TPU v5e-8, exposing a public OpenAI-compatible (and Anthropic-compatible) endpoint you can plug into coding agents like Claude Code, Codex, opencode, or pi.
- 36
DeepGEMM-Ascend
588deepseek-ai/DeepGEMM-Ascend · C++DeepGEMM-Ascend is a port of DeepSeek's DeepGEMM matrix-multiplication kernel library to Huawei Ascend NPUs, fully API-compatible with the original and supporting BF16, FP8, and FP4 GEMM along with MQA logits and MegaMoE operators.
- 37

slotstream
477carloslfu/slotstream · SwiftSlotstream lets you run a 105 GB AI model (Qwen3.8-Flash-Next, a 125B-parameter mixture-of-experts model) on Macs with only 16 to 64 GB of RAM, by streaming most of the model from SSD and caching the busiest experts in memory.
- 38
LongCat-Next
477meituan-longcat/LongCat-Next · PythonLongCat-Next is a native multimodal foundation model from Meituan that processes text, vision, and audio under a single autoregressive objective using discrete tokens, built on the LongCat-Flash-Lite MoE backbone (A3B).
- 39
Qwen3.8-Flash-Next
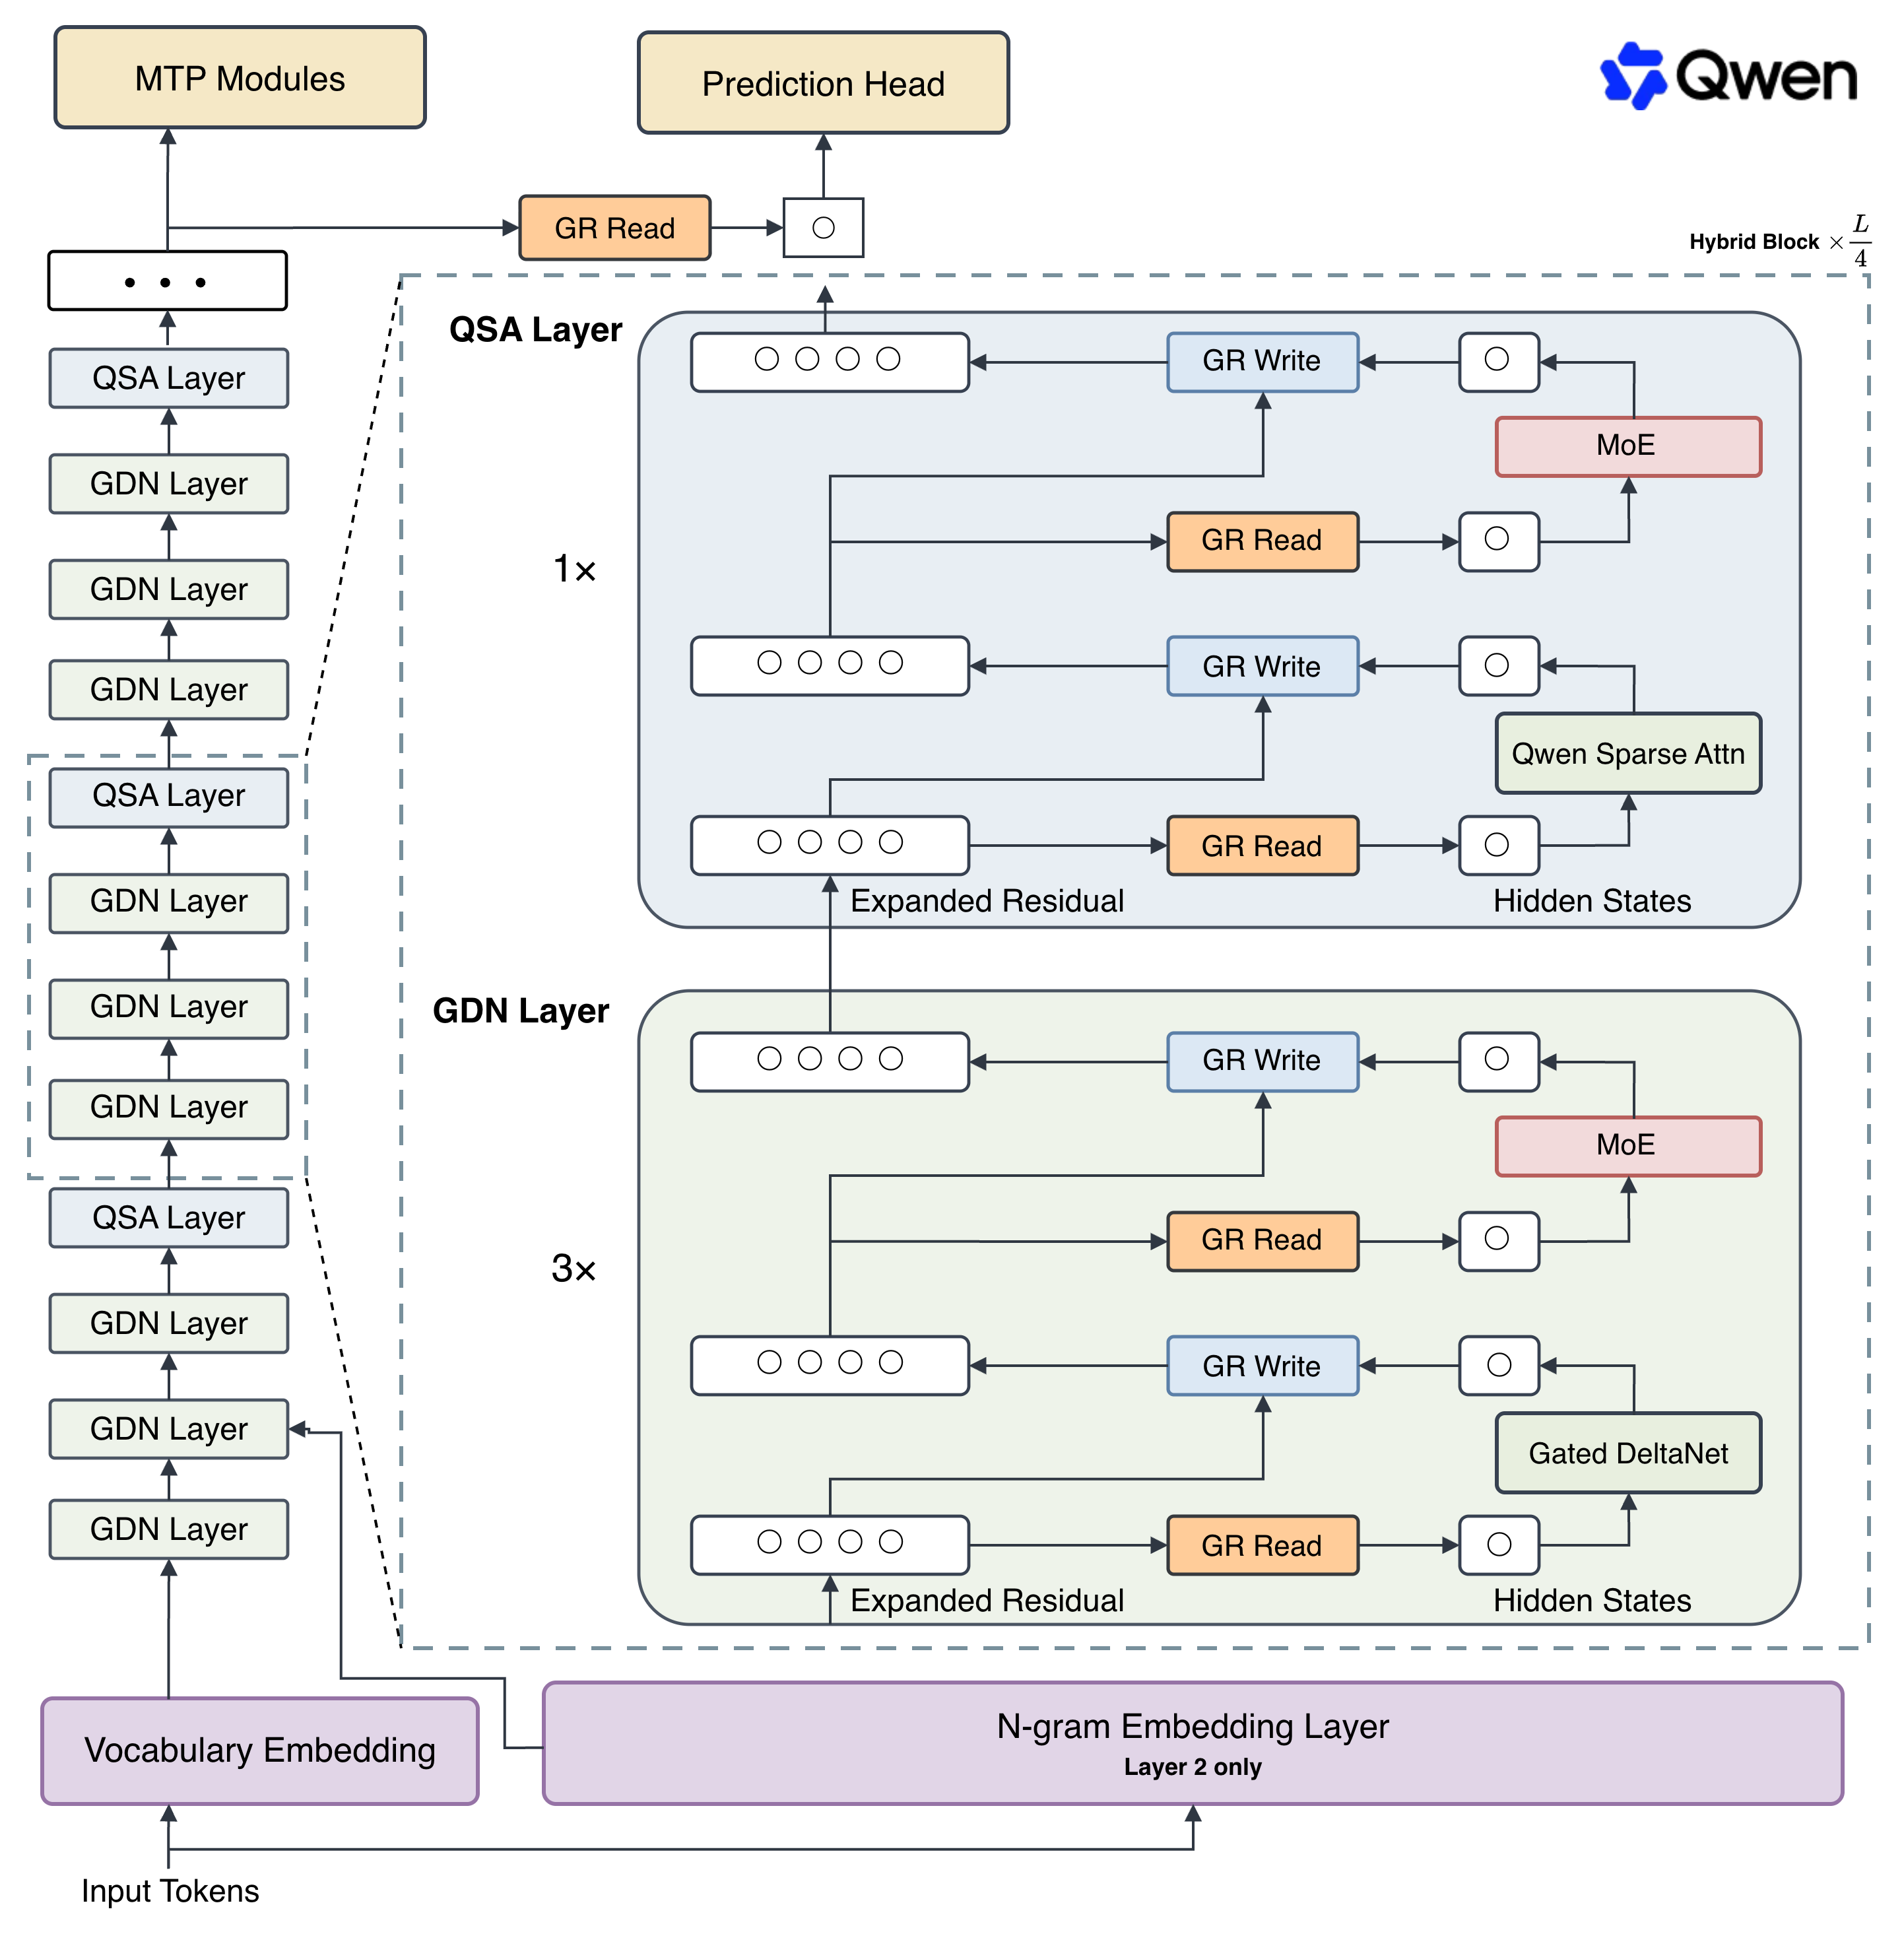
434QwenLM/Qwen3.8-Flash-NextQwen3.8-Flash-Next is an open-weight multimodal Mixture-of-Experts foundation model from Alibaba's Qwen Team, also serving as an early preview of the architecture Alibaba plans to use for the upcoming Qwen4 model family.
- 40

OpenArch
426anuj0456/OpenArch · PythonA set of hand-written PyTorch implementations of modern open-source LLM architectures (Llama, Qwen, DeepSeek, Gemma, GPT-OSS, Kimi and more), written from scratch for readability and learning.
- 41
Meshy
407OpenBMB/Meshy · PythonMeshy is an open-source framework for running reinforcement learning (RL) training jobs where every role (inference, training, rollout) runs as an independent service, communicating through a shared TransferQueue data plane. It is built on SGLang and torchtitan.
- 42
Hy4-preview
396Tencent-Hunyuan/Hy4-preview · PythonHy4 preview is Tencent Hunyuan's newest open-source large language model, a 770B-parameter Mixture-of-Experts model (49B active per token) built for coding, office/data analysis, game development, and scientific research tasks.
- 43
llm-inference-engineering
372amitshekhariitbhu/llm-inference-engineering · MarkdownA free, continuously growing blog series that teaches LLM inference engineering step by step, covering KV cache, PagedAttention, continuous batching, speculative decoding, and serving engines like vLLM, SGLang, TensorRT-LLM, and GGUF.
- 44
video-prediction-policy-2
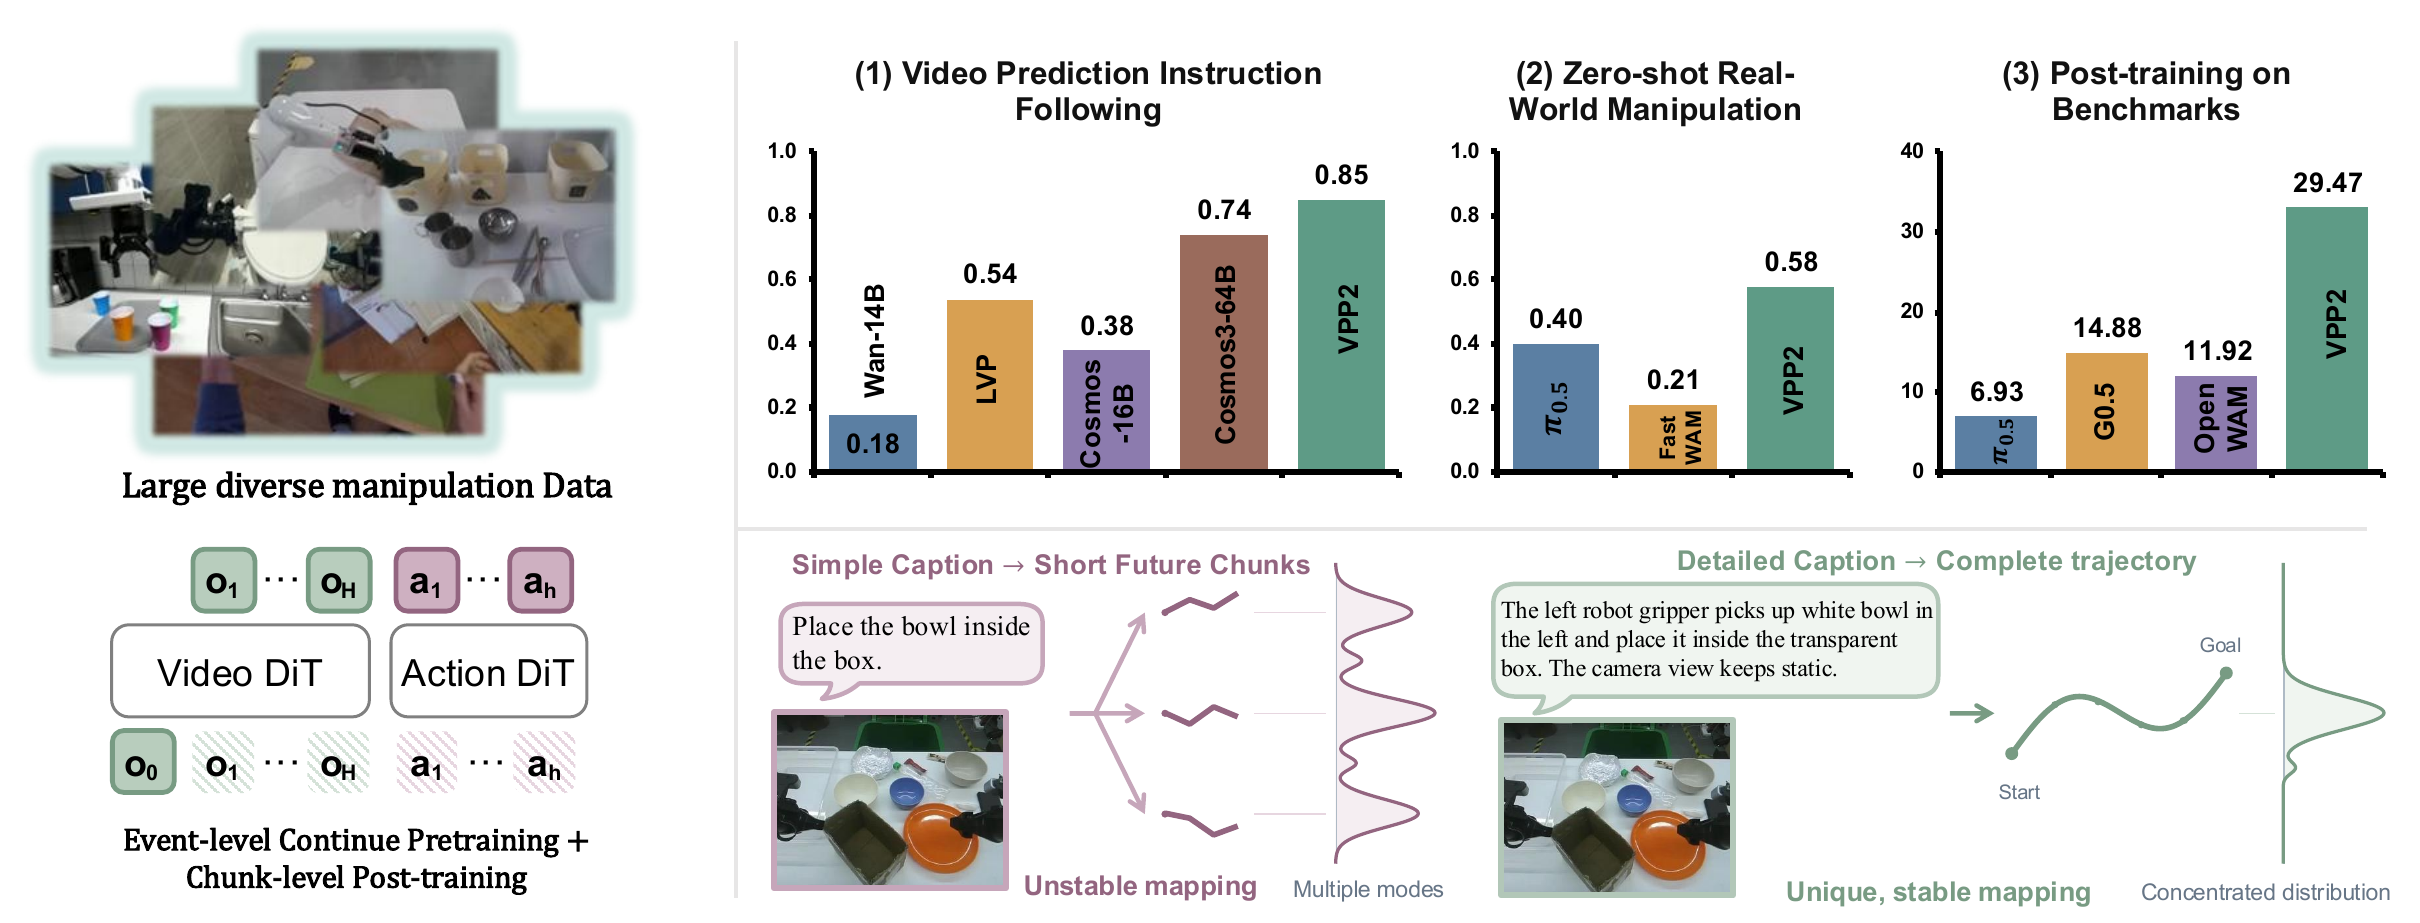
264roboterax/video-prediction-policy-2 · PythonVideo Prediction Policy 2 (VPP2) is a world-action model (WAM) for robot manipulation that predicts future video frames and converts them into robot actions, with strong zero-shot generalization across tasks.
- 45
DeepEP-Ascend
259deepseek-ai/DeepEP-Ascend · C++DeepEP-Ascend is a high-performance communication library for machine learning training and inference on Huawei Ascend NPUs, providing expert-parallel all-to-all operations for MoE dispatch and combine.
- 46

GLM-5.3-Flash-NVFP4-DFlash2-2x-DGX-Spark
237tonyd2wild/GLM-5.3-Flash-NVFP4-DFlash2-2x-DGX-Spark · PythonA deployment recipe and set of patched Docker images for serving GLM-5.3-Flash (320B total / 18B active MoE) as an OpenAI-compatible API across two NVIDIA DGX Spark nodes, using vLLM tensor-parallel 2, NVFP4 quantization, and DFlash2 speculative decoding.
- 47
Iris
103AllSpark-Research/Iris · PythonIris is a pair of open-weight search agent models (Iris-mini, 35B-A3B, and Iris-pro, 397B-A17B) post-trained from the Qwen3.5/3.6 series to decide what to search, how to read results, when to keep searching, and when enough evidence has been gathered.

Related topics
Often tagged together
- llm1,516
- python2,425
- deep-learning746
- inference331
- gpu809
- large-language-models218
- machine-learning930
- quantization190
- moe56
- open-source5,749
- linux4,248
- huggingface367
- llm-inference120
- transformer214
- ai1,993
- apache-2.01,452
- research779
- cuda401
- pytorch421
- benchmark444
- nvidia339
- artificial-intelligence272
- fine-tuning188
- local-llm224