Topics / #kv-cache
Kv-cache projects on GitHub
Techniques for caching attention key-value states to speed up LLM inference.
As of , the most-starred Kv-cache projects on GitHub are ds4 (23.9K stars), Agent-Skills-for-Context-Engineering (18.2K stars) and LMCache (12.1K stars). GitHub.Locker tracks 14 Kv-cache repositories with 81.3K stars combined. The fastest-growing on October 17 was ai-infra-book, with +35 stars in a day.
Hot right now
Most stars gained in a day · Oct 17
 +35
ai-infra-book
bojieli/ai-infra-book · ★ 6.7KAn open-source book, 'Understanding AI Infra: Quantitative Analysis and System Design' by Bojie Li, that derives LLM inference and training system designs from hardware constraints and model architecture using quantitative, order-of-magnitude estimates.
 +18
ds4
antirez/ds4 · ★ 23.9KDwarfStar (ds4) is a small, self-contained local inference engine specialized for running DeepSeek V4 Flash and PRO, plus GLM 5.2/5.3, on consumer hardware like high-memory Macs, NVIDIA GPUs, and AMD Strix Halo systems.
 +17
TensorFold
ashhart/TensorFold · ★ 1.4KTensorFold is an LLM inference engine that serves open-weight language models through an OpenAI-compatible API, running them on Apple Silicon via MLX or on NVIDIA GPUs via CUDA.
Agent-Skills-for-Context-Engineering
muratcankoylan/Agent-Skills-for-Context-Engineering · ★ 18.2KA curated collection of Agent Skills that teach context engineering, multi-agent architecture, and production agent system design, so an AI agent can load the right skill when it needs to manage context, memory, evaluation, or harness design.
The all-time top
14 projects · by stars
- 23.9K#1 · antirez/ds4
ds4
DwarfStar (ds4) is a small, self-contained local inference engine specialized for running DeepSeek V4 Flash and PRO, plus GLM 5.2/5.3, on consumer hardware like high-memory Macs, NVIDIA GPUs, and AMD Strix Halo systems.
- 18.2K
#2 · muratcankoylan/Agent-Skills-for-Context-Engineering
Agent-Skills-for-Context-Engineering
A curated collection of Agent Skills that teach context engineering, multi-agent architecture, and production agent system design, so an AI agent can load the right skill when it needs to manage context, memory, evaluation, or harness design.
- 12.1K
 #3 · LMCache/LMCache
LMCache
LMCache is a KV cache management layer for LLM inference that turns the KV cache from a temporary, per-process state into reusable, persistent 'AI-native knowledge' that can be shared across serving engines, reducing time-to-first-token and boosting throughput for long-context, multi-turn, and RAG workloads.
- 4
3FS
10.3Kdeepseek-ai/3FS · C++3FS (Fire-Flyer File System) is a high-performance distributed file system built by DeepSeek to handle AI training and inference storage workloads at scale, pooling thousands of SSDs and hundreds of storage nodes behind RDMA networking into one shared storage layer.
- 5
ai-infra-book
6.7Kbojieli/ai-infra-book · PythonAn open-source book, 'Understanding AI Infra: Quantitative Analysis and System Design' by Bojie Li, that derives LLM inference and training system designs from hardware constraints and model architecture using quantitative, order-of-magnitude estimates.
- 6
MSA
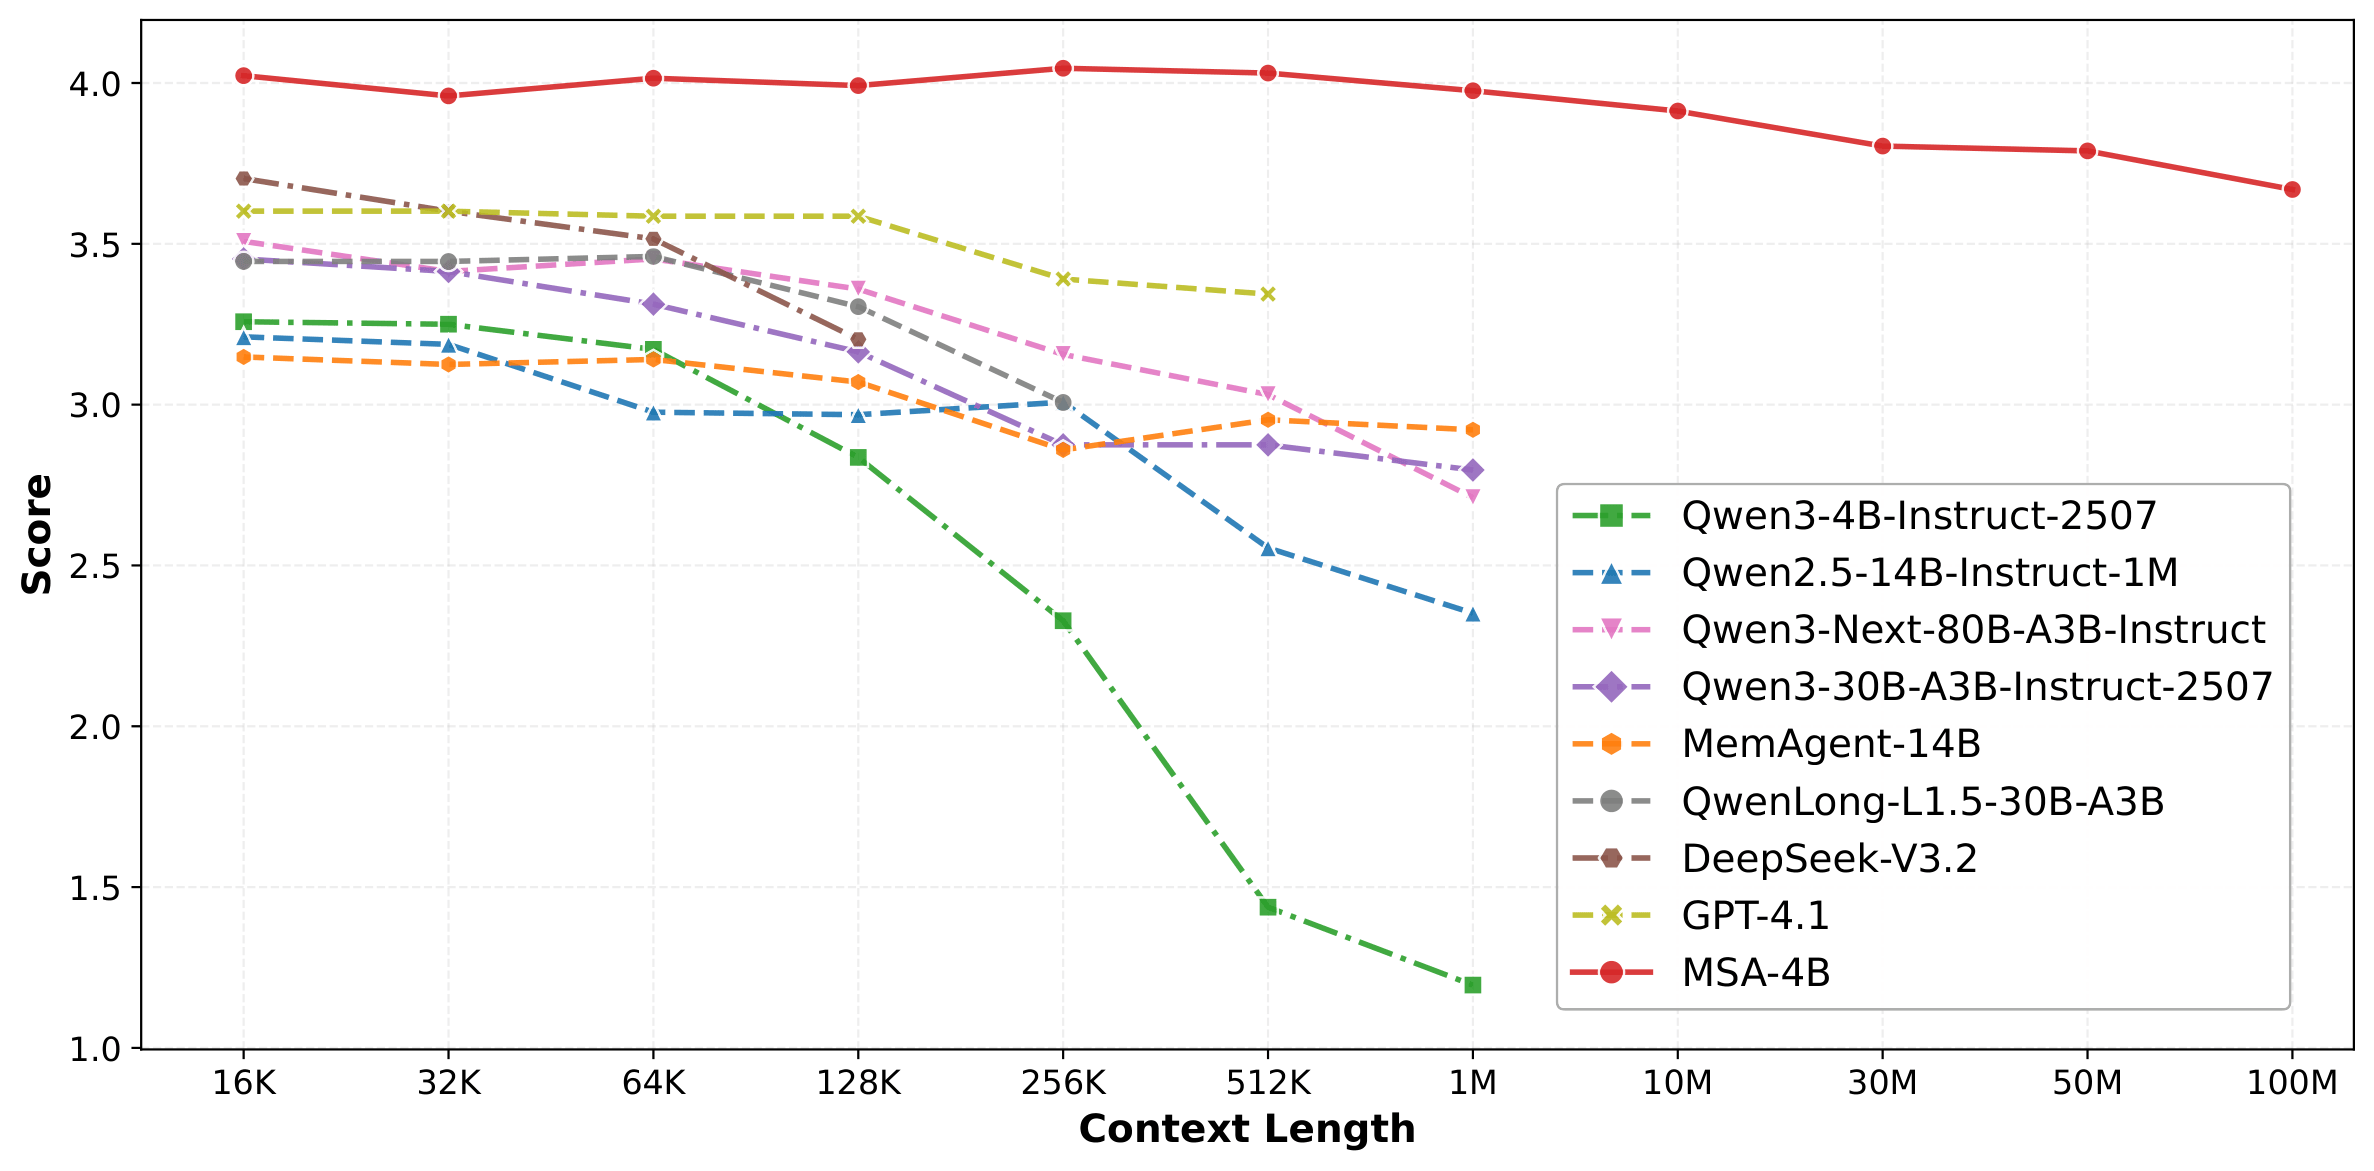
3.5KEverMind-AI/MSA · PythonMSA (Memory Sparse Attention) is an end-to-end trainable, scalable latent-memory framework that lets LLMs handle context windows up to 100M tokens, replacing RAG or fixed-size RNN-style memory with a differentiable sparse-attention memory bank.
- 7

HyperQwen
2.1Ksyv-ai/HyperQwen · PythonHyperQwen is a self-hosted serving setup that runs the Qwen3.8-27B model on a single 24 GB consumer GPU (like an RTX 3090) using vLLM, exposing it through an OpenAI-compatible API.
- 8
zero-to-sglang
1.5Kdatawhalechina/zero-to-sglang · PythonThe official SGLang x Datawhale course on LLM inference: it teaches how inference engines work, has you build a mini-sglang from scratch, and then digs into the real SGLang source code.
- 9
TensorFold
1.4Kashhart/TensorFold · ZigTensorFold is an LLM inference engine that serves open-weight language models through an OpenAI-compatible API, running them on Apple Silicon via MLX or on NVIDIA GPUs via CUDA.
- 10
TypeLLM
960TypeLLM/TypeLLM · PythonTypeLLM adds type-safe, schema-guaranteed output generation to existing open autoregressive LLMs, without changing their weights or architecture, letting models still think freely while returning typed JSON Schema-constrained answers.
- 11
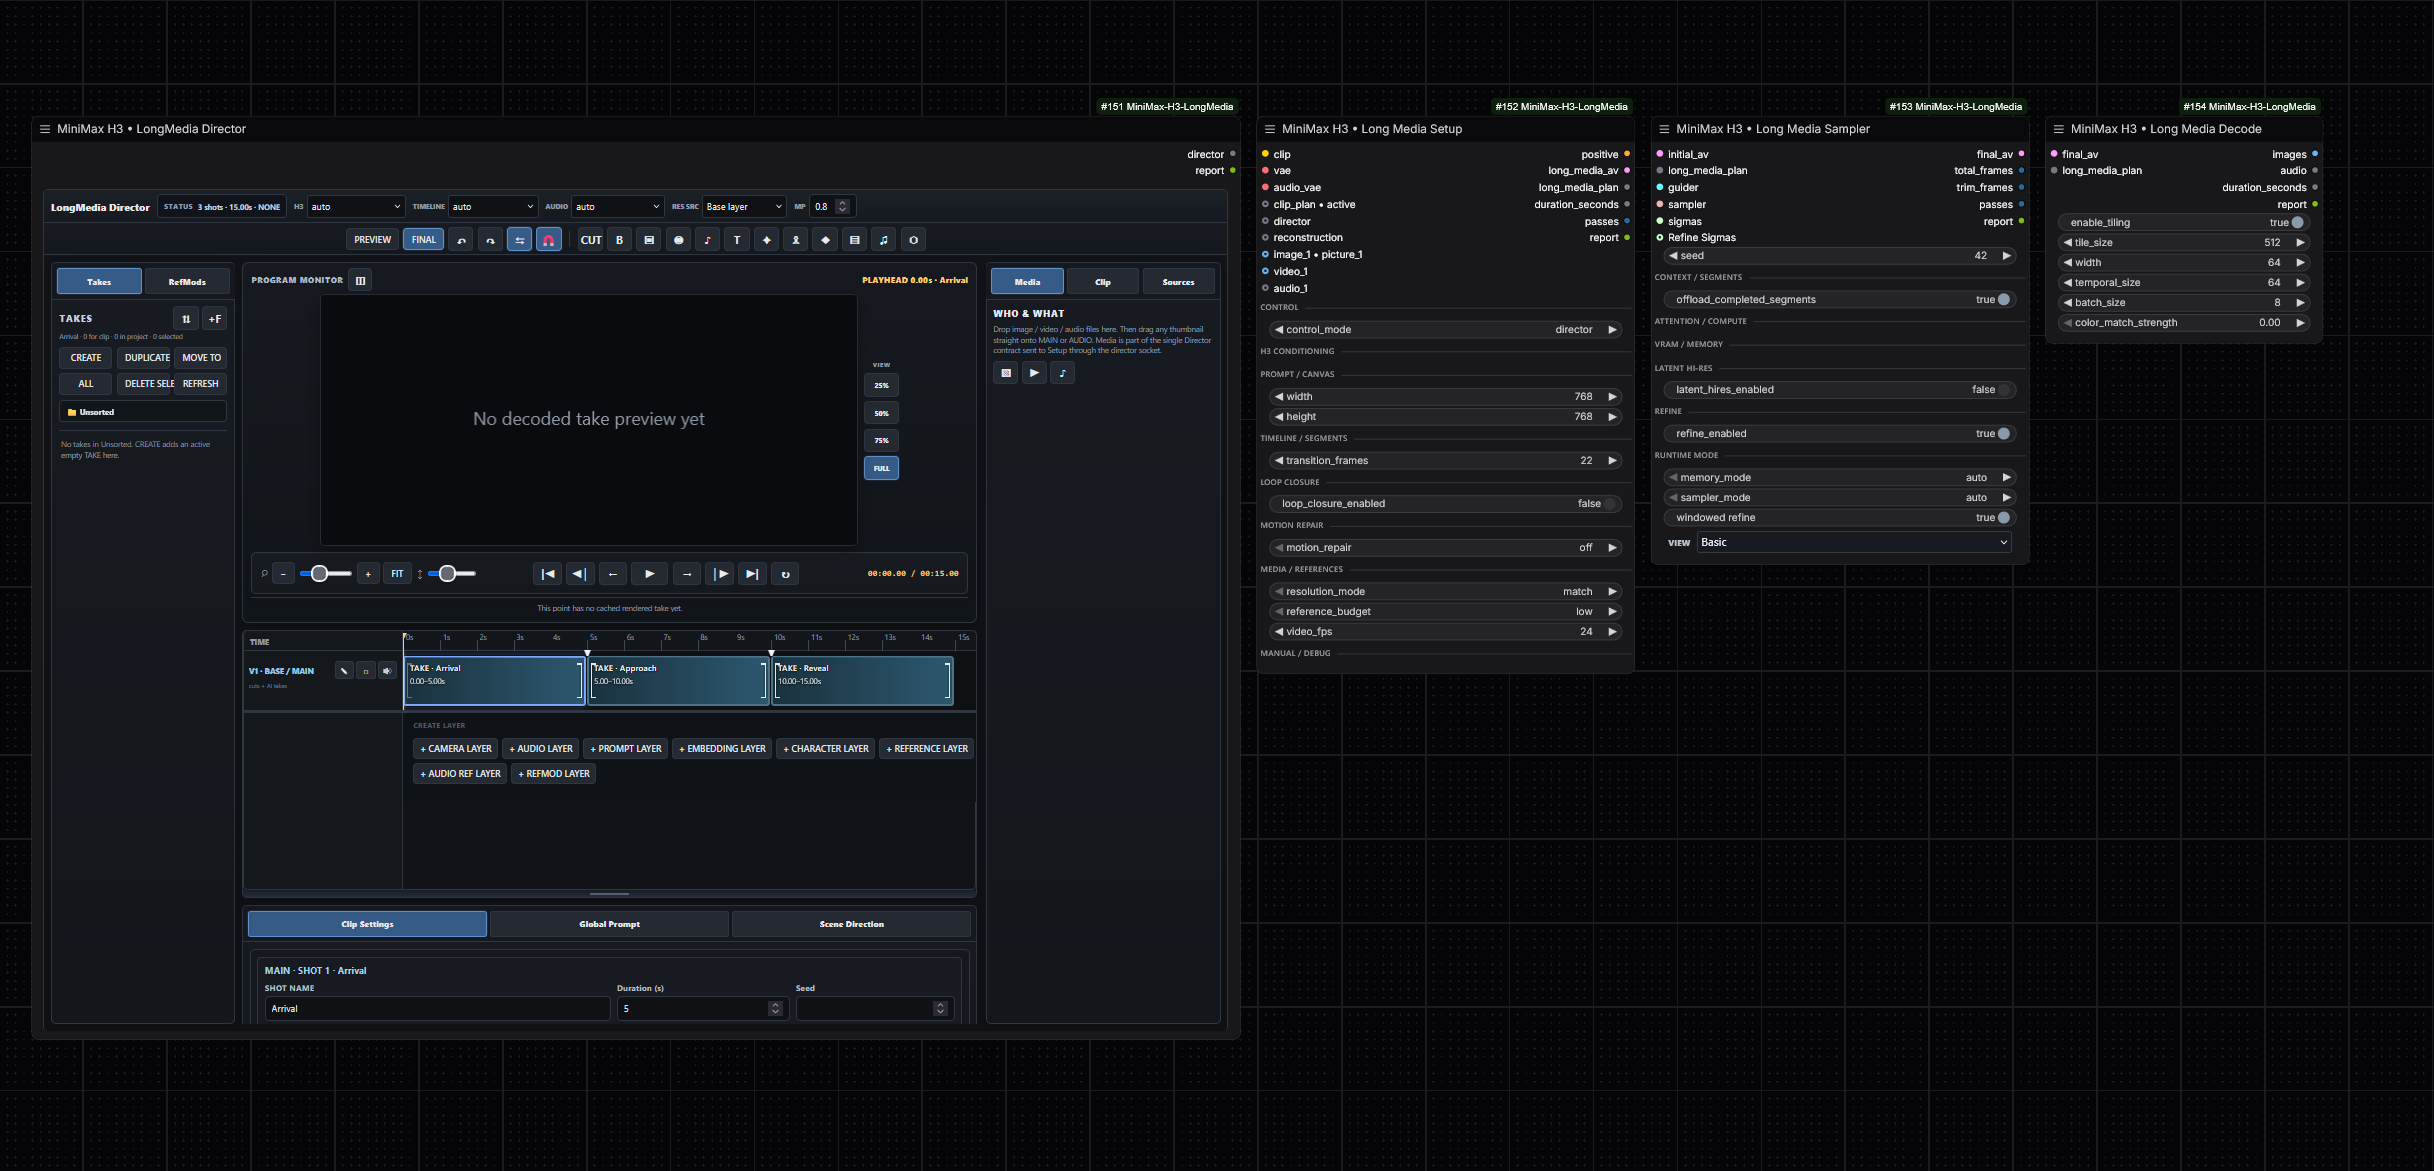
ComfyUI-MiniMax-H3-LongMedia
295vizart-vj/ComfyUI-MiniMax-H3-LongMedia · PythonA set of production-oriented custom nodes for ComfyUI that run MiniMax H3 for long-form video and audio generation: reference editing, MultiClip planning, camera direction, fixed segmentation, lip-sync and redubbing, latent hi-res refinement, and low-VRAM-safe execution.
- 12
InstinctFlash
200General-Instinct/InstinctFlash · PythonInstinctFlash is a high-performance serving runtime for robotics foundation models - it loads checkpoints like GR00T, Cosmos3, pi0.5, LingBot-VA/VLA and DreamZero, applies acceleration (FP8, fused Triton kernels, caching) and serves them over Python or WebSocket, reporting up to 33.78x speedup on Jetson Thor.
- 13
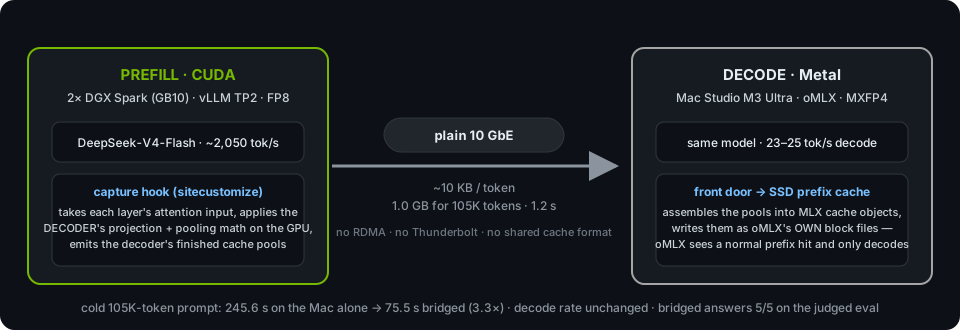
pd-bridge
151chadhurley25075-png/pd-bridge · Pythonpd-bridge serves one DeepSeek-V4-Flash request across two machines: prefill runs on NVIDIA DGX Sparks (CUDA/vLLM), decode on a Mac Studio (Metal/oMLX), linked by ordinary 10GbE Ethernet.
- 14
open-jev
134daseinlabs/open-jev · PythonAn open implementation of Jev: a local Gemma 3 4B (via MLX) scores a list of pre-written options against a context in one batched forward pass on Apple silicon — no text generation, just log-probabilities per option.
Related topics
Often tagged together
- python2,396
- gpu788
- llm1,483
- open-source5,666
- ai1,954
- inference326
- linux4,181
- llm-inference118
- cuda395
- nvidia327
- macos3,544
- quantization183
- apache-2.01,434
- machine-learning915
- self-hosted1,926
- benchmark430
- deep-learning736
- developer-tools2,927
- gpu-acceleration144
- inference-engine45
- llm-serving29
- local-llm218
- model-serving46
- research764