Topics / #mlx
Mlx projects on GitHub
Apples MLX array framework for running machine learning on Apple silicon.
As of , the most-starred Mlx projects on GitHub are unsloth (78.2K stars), VoiceStudio (73.3K stars) and voicebox (57.8K stars). GitHub.Locker tracks 39 Mlx repositories with 499.2K stars combined. The fastest-growing on October 16 was VoiceStudio, with +2.1K stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +2.1K
VoiceStudio
debpalash/VoiceStudio · ★ 73.3KVoiceStudio is an open-source, fully-local alternative to ElevenLabs: one app for voice cloning, voice design, video dubbing, dictation, transcription and audiobook creation in 646 languages.
 +159
airllm
lyogavin/airllm · ★ 39.1KAn open-source Python library that runs huge LLMs on tiny GPUs: a 70B model fits on a single 4GB card without quantization, distillation or pruning — even the 2.8T-parameter Kimi K3 runs in under 4GB.
 +150
StartLux-Decision
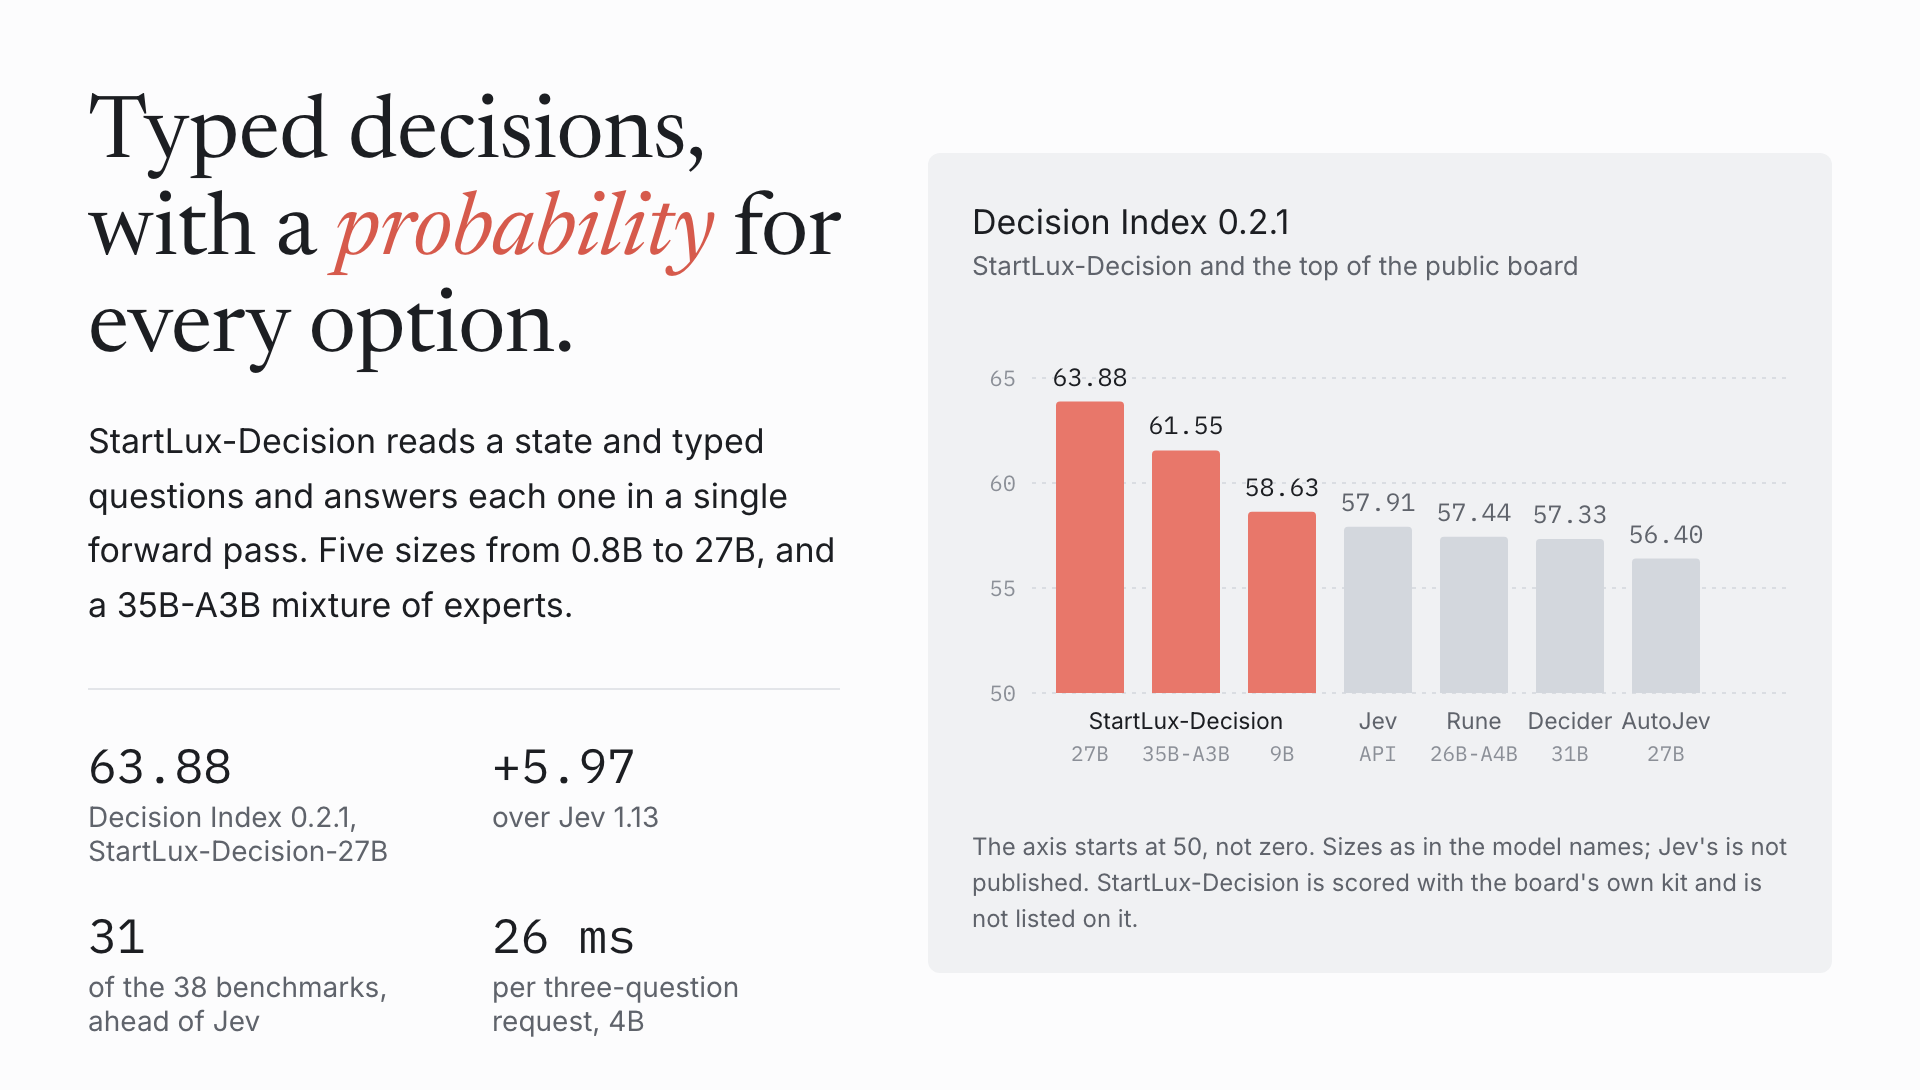
StartLuxLabs/StartLux-Decision · ★ 626StartLux-Decision is a family of typed decision models (five dense sizes from 0.8B to 27B plus a 35B-A3B mixture-of-experts) that answer a question with a probability for each option instead of generating text.
 +136
voicebox
jamiepine/voicebox · ★ 57.8KVoicebox is an open-source, local-first AI voice studio: it clones voices, generates speech in 23 languages, lets you dictate into any app with a global hotkey, and gives MCP-aware AI agents a voice - all running on your own machine as a free alternative to ElevenLabs and WisprFlow combined.
The all-time top
39 projects · by stars
- 78.2K
 #1 · unslothai/unsloth
unsloth
Unsloth is a local-first app for running and training LLMs, diffusion, TTS and embedding models on your own machine, including models like Qwen3.8, DeepSeek-V4, MiniMax-H3, Gemma 4 and FLUX.
- 73.3K#2 · debpalash/VoiceStudio
VoiceStudio
VoiceStudio is an open-source, fully-local alternative to ElevenLabs: one app for voice cloning, voice design, video dubbing, dictation, transcription and audiobook creation in 646 languages.
- 57.8K#3 · jamiepine/voicebox
voicebox
Voicebox is an open-source, local-first AI voice studio: it clones voices, generates speech in 23 languages, lets you dictate into any app with a global hotkey, and gives MCP-aware AI agents a voice - all running on your own machine as a free alternative to ElevenLabs and WisprFlow combined.
- 4

exo
47.9Kexo-explore/exo · Pythonexo turns a group of your own devices (Macs, Linux boxes) into a single AI cluster so you can run large AI models that would never fit on one machine, pooling their memory and compute together.
- 5
airllm
39.1Klyogavin/airllm · Jupyter NotebookAn open-source Python library that runs huge LLMs on tiny GPUs: a 70B model fits on a single 4GB card without quantization, distillation or pruning — even the 2.8T-parameter Kimi K3 runs in under 4GB.
- 6

llmfit
38KAlexsJones/llmfit · Rustllmfit inspects your CPU, RAM, GPU(s), VRAM, and accelerator setup, then tells you which open-source LLMs and quantizations will actually run well on your machine.
- 7

mlx
28.8Kml-explore/mlx · C++MLX is an array framework for machine learning on Apple silicon, built by Apple's machine learning research team.
- 8

omlx
22.9Kjundot/omlx · PythonoMLX is a local LLM inference server for Apple Silicon Macs. It serves text LLMs, vision models, OCR, embeddings and rerankers with continuous batching and a tiered KV cache, managed from the macOS menu bar.
- 9
Second-Me
15.7Kmindverse/Second-Me · PythonSecond Me is an open-source project that lets you train a personal, locally-hosted AI model that preserves your identity, memory, and context, then connects it to a decentralized network so it can represent you across apps.
- 10
WhisperLiveKit
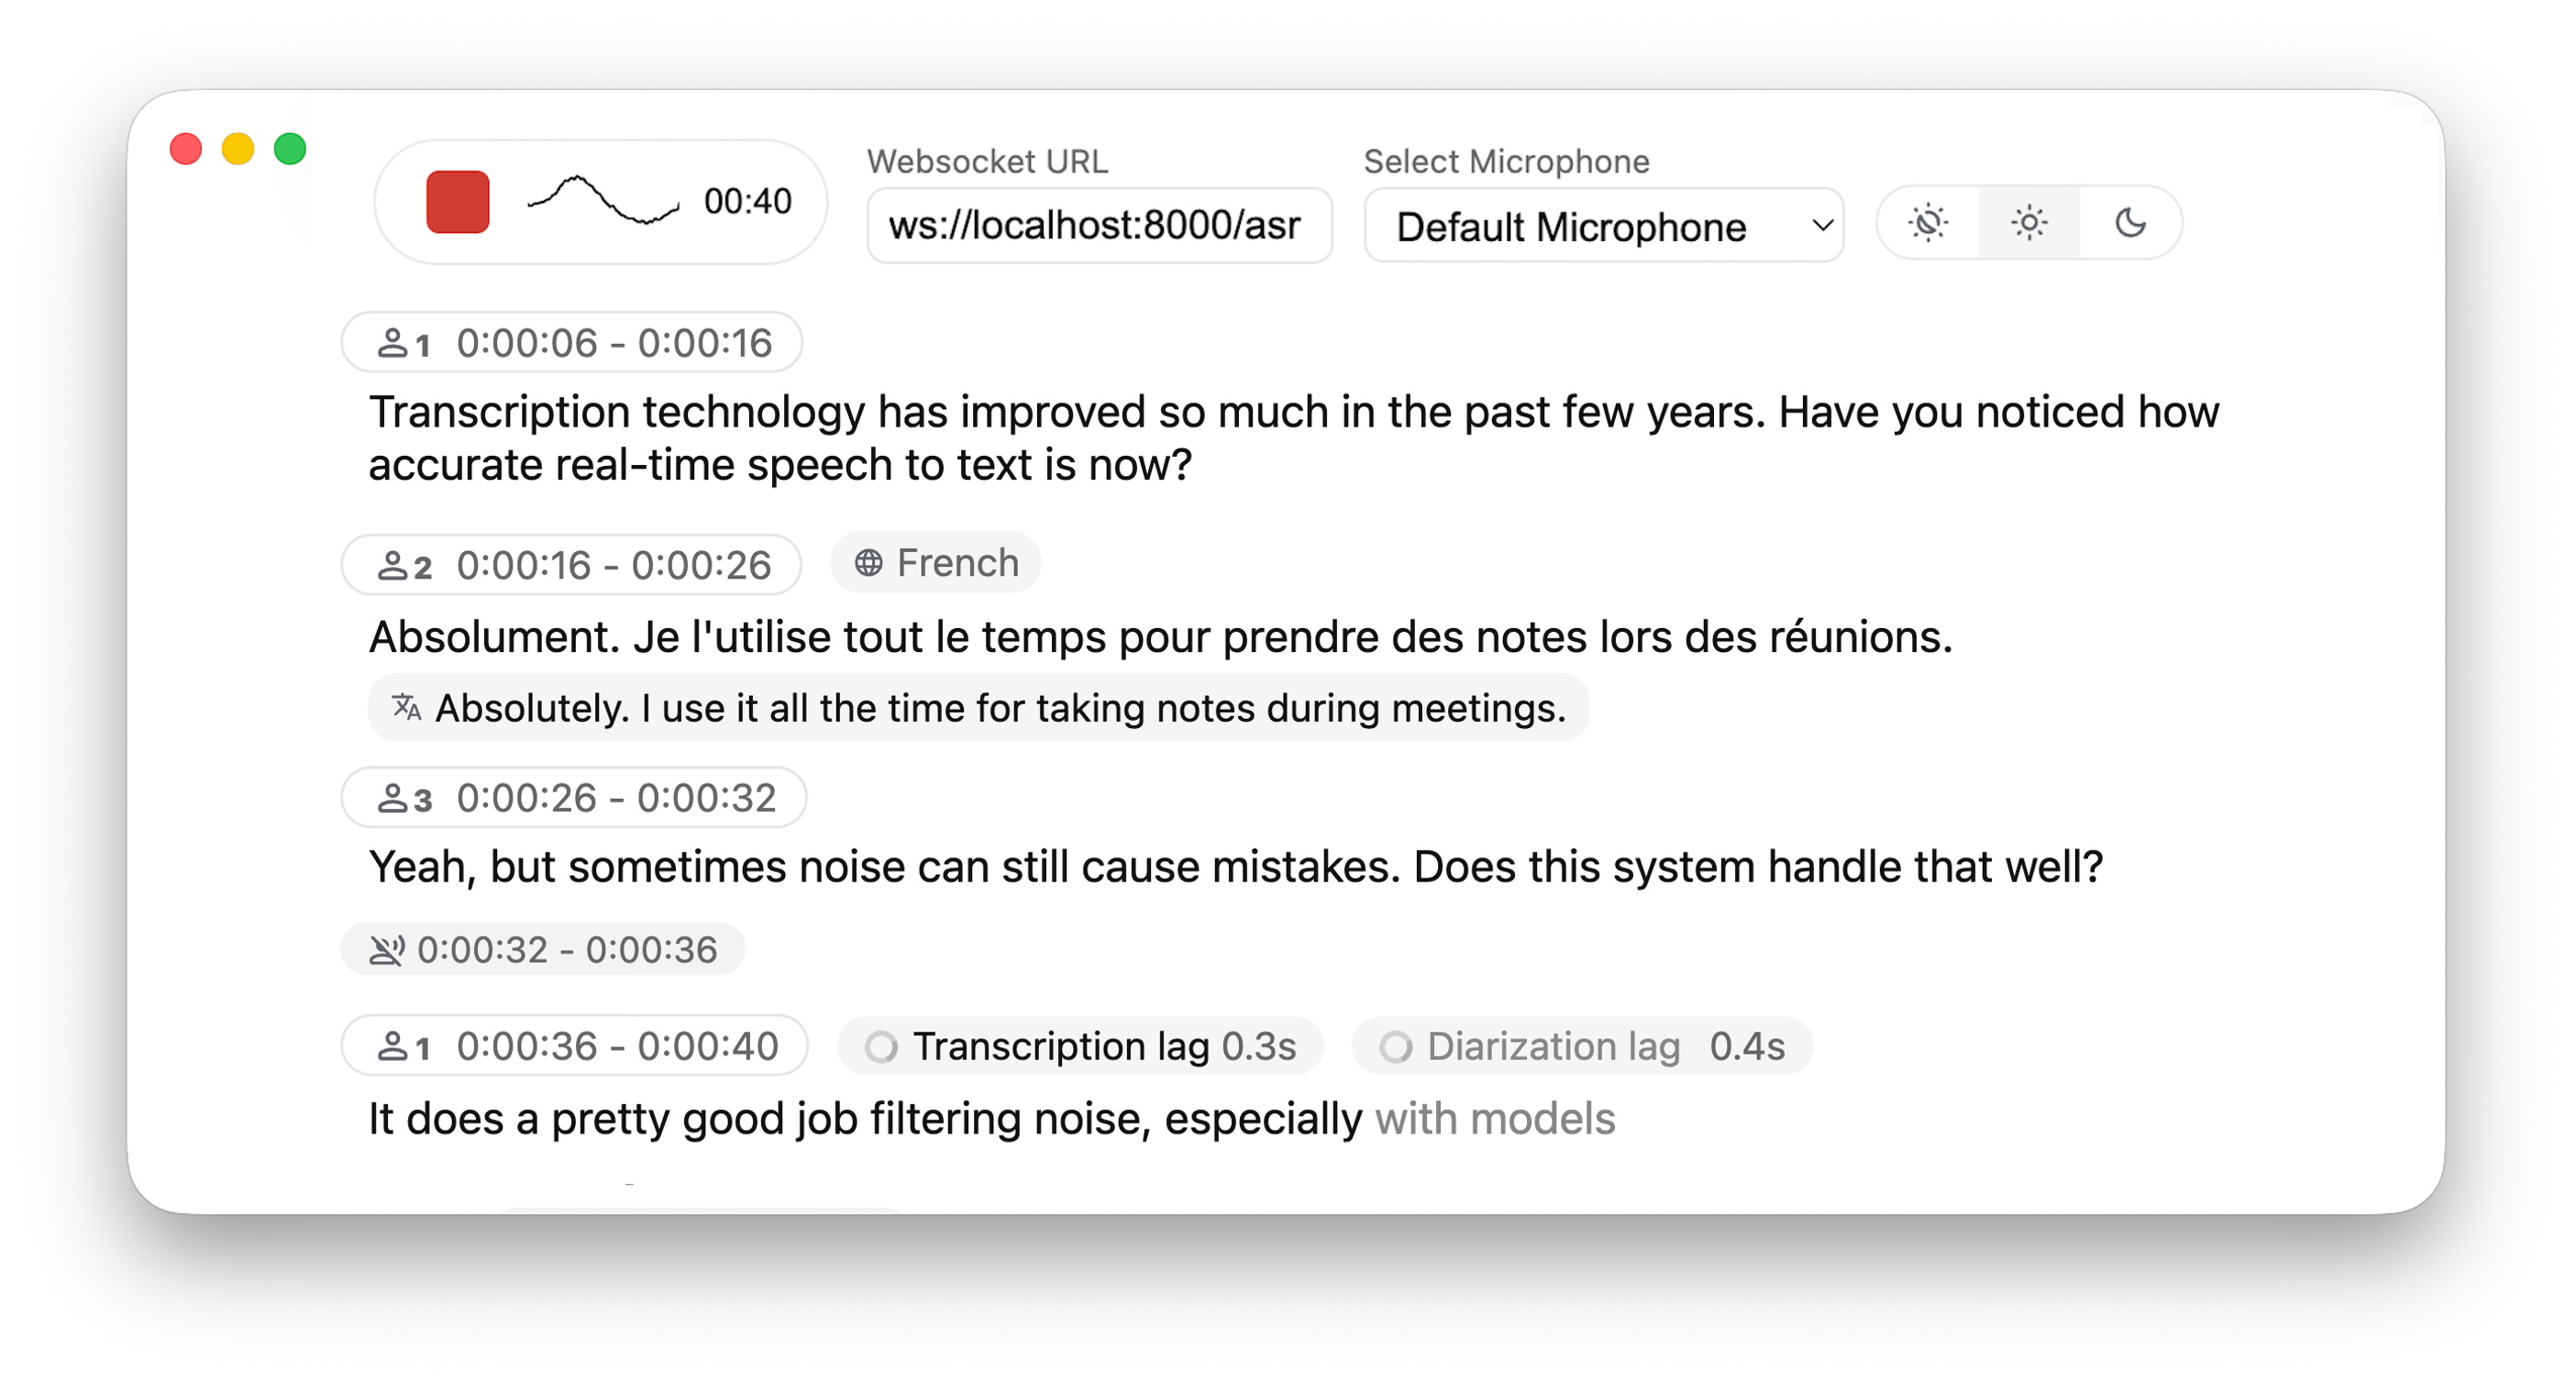
11.1KQuentinFuxa/WhisperLiveKit · PythonWhisperLiveKit is a self-hosted pipeline for real-time, local speech-to-text with streaming ASR, speaker diarization, live translation, and OpenAI/Deepgram-compatible APIs.
- 11
runanywhere-sdks
10.3KRunanywhereAI/runanywhere-sdks · C++A toolkit of eight SDKs over one C++ core that runs AI fully on-device — LLM chat, vision, speech, voice agents, RAG, and image generation — on phones, browsers, and desktops. Everything is private by default and works offline.
- 12

kev
9.3Kjaredpalmer/kev · PythonKev is an open family of small decision models (0.8B to 27B parameters) built on Qwen3.5/3.8 that answer yes/no, multiple-choice and rating questions about text with calibrated probabilities, acting as a self-hosted drop-in replacement for TypeSafe's hosted Jev model.
- 13

turboquant_plus
7KTheTom/turboquant_plus · PythonTurboQuant+ is the research home for TurboQuant (ICLR 2026), a KV cache compression method for transformer LLMs. It shrinks the KV cache 3.8-6.4x using PolarQuant plus Walsh-Hadamard rotation, and this repo holds the Python reference implementation, validation papers and benchmark data.
- 14
laya-mlx
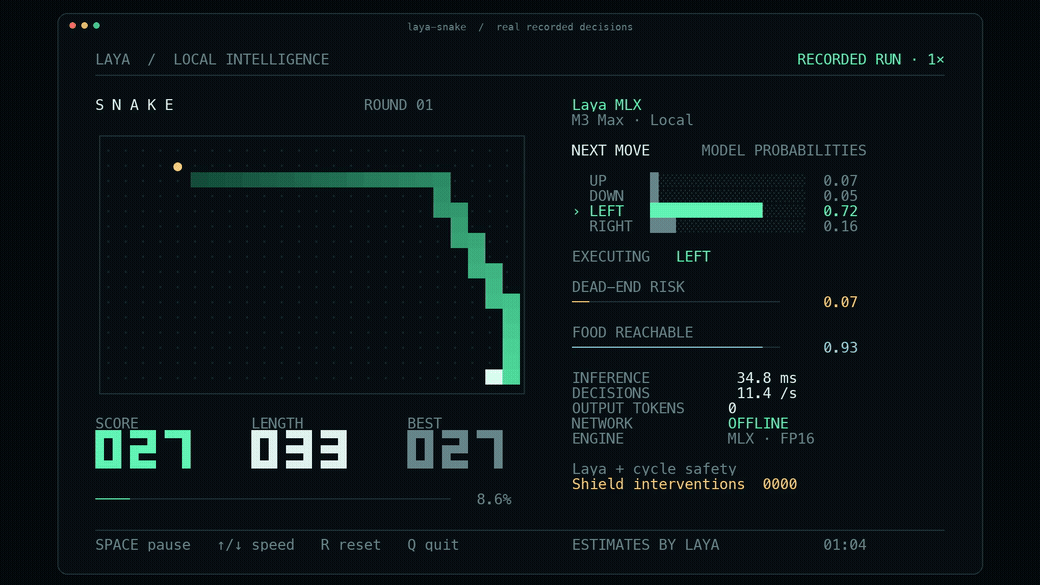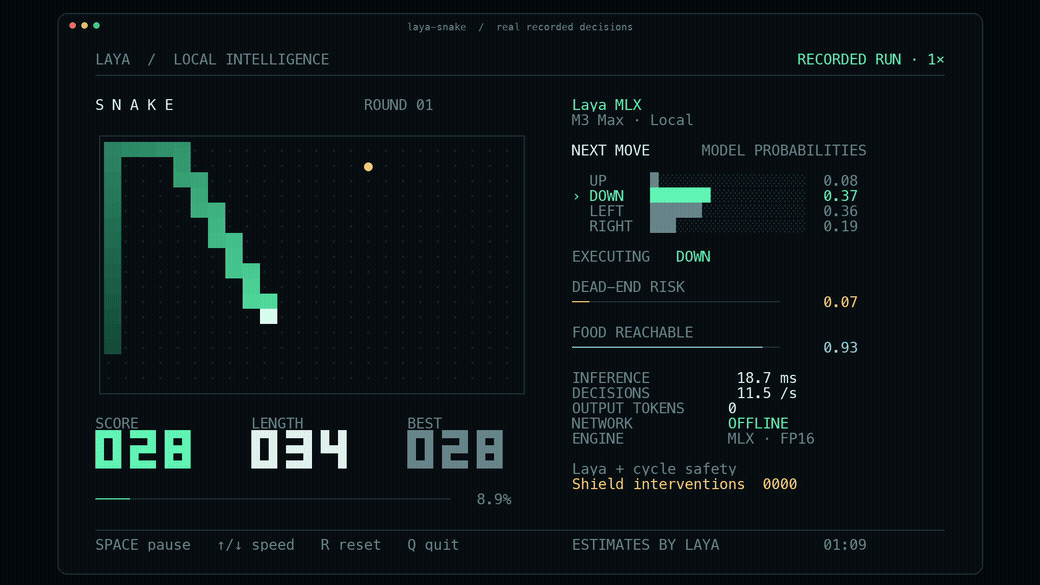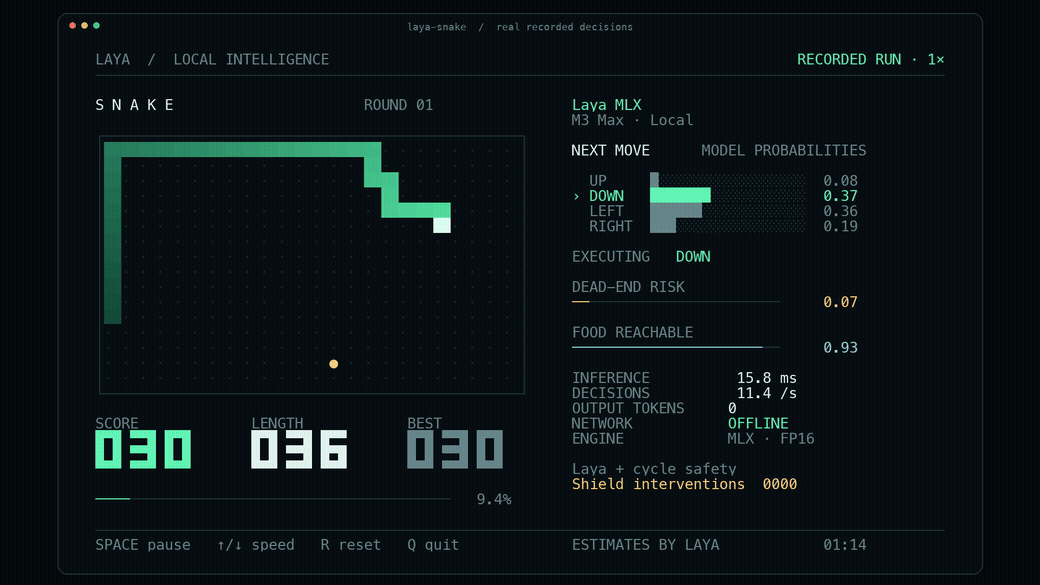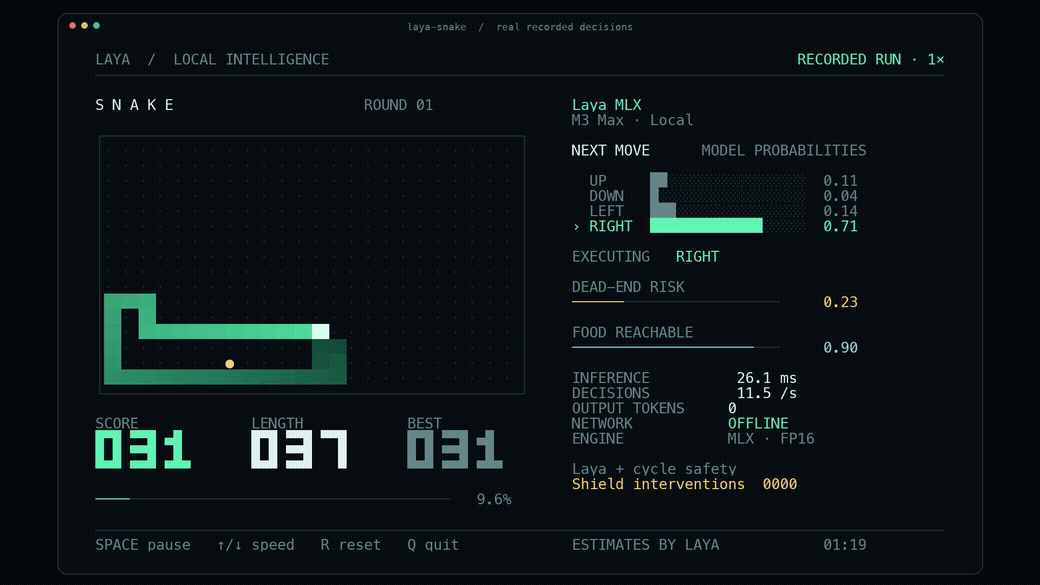
7Kmizorewww/laya-mlx · PythonLaya-MLX is a native MLX runtime that runs the open-weight Laya typed decision models locally on Apple Silicon, returning structured answers like a choice, a rubric score, or a probability in milliseconds instead of generating text.
- 15
dflash
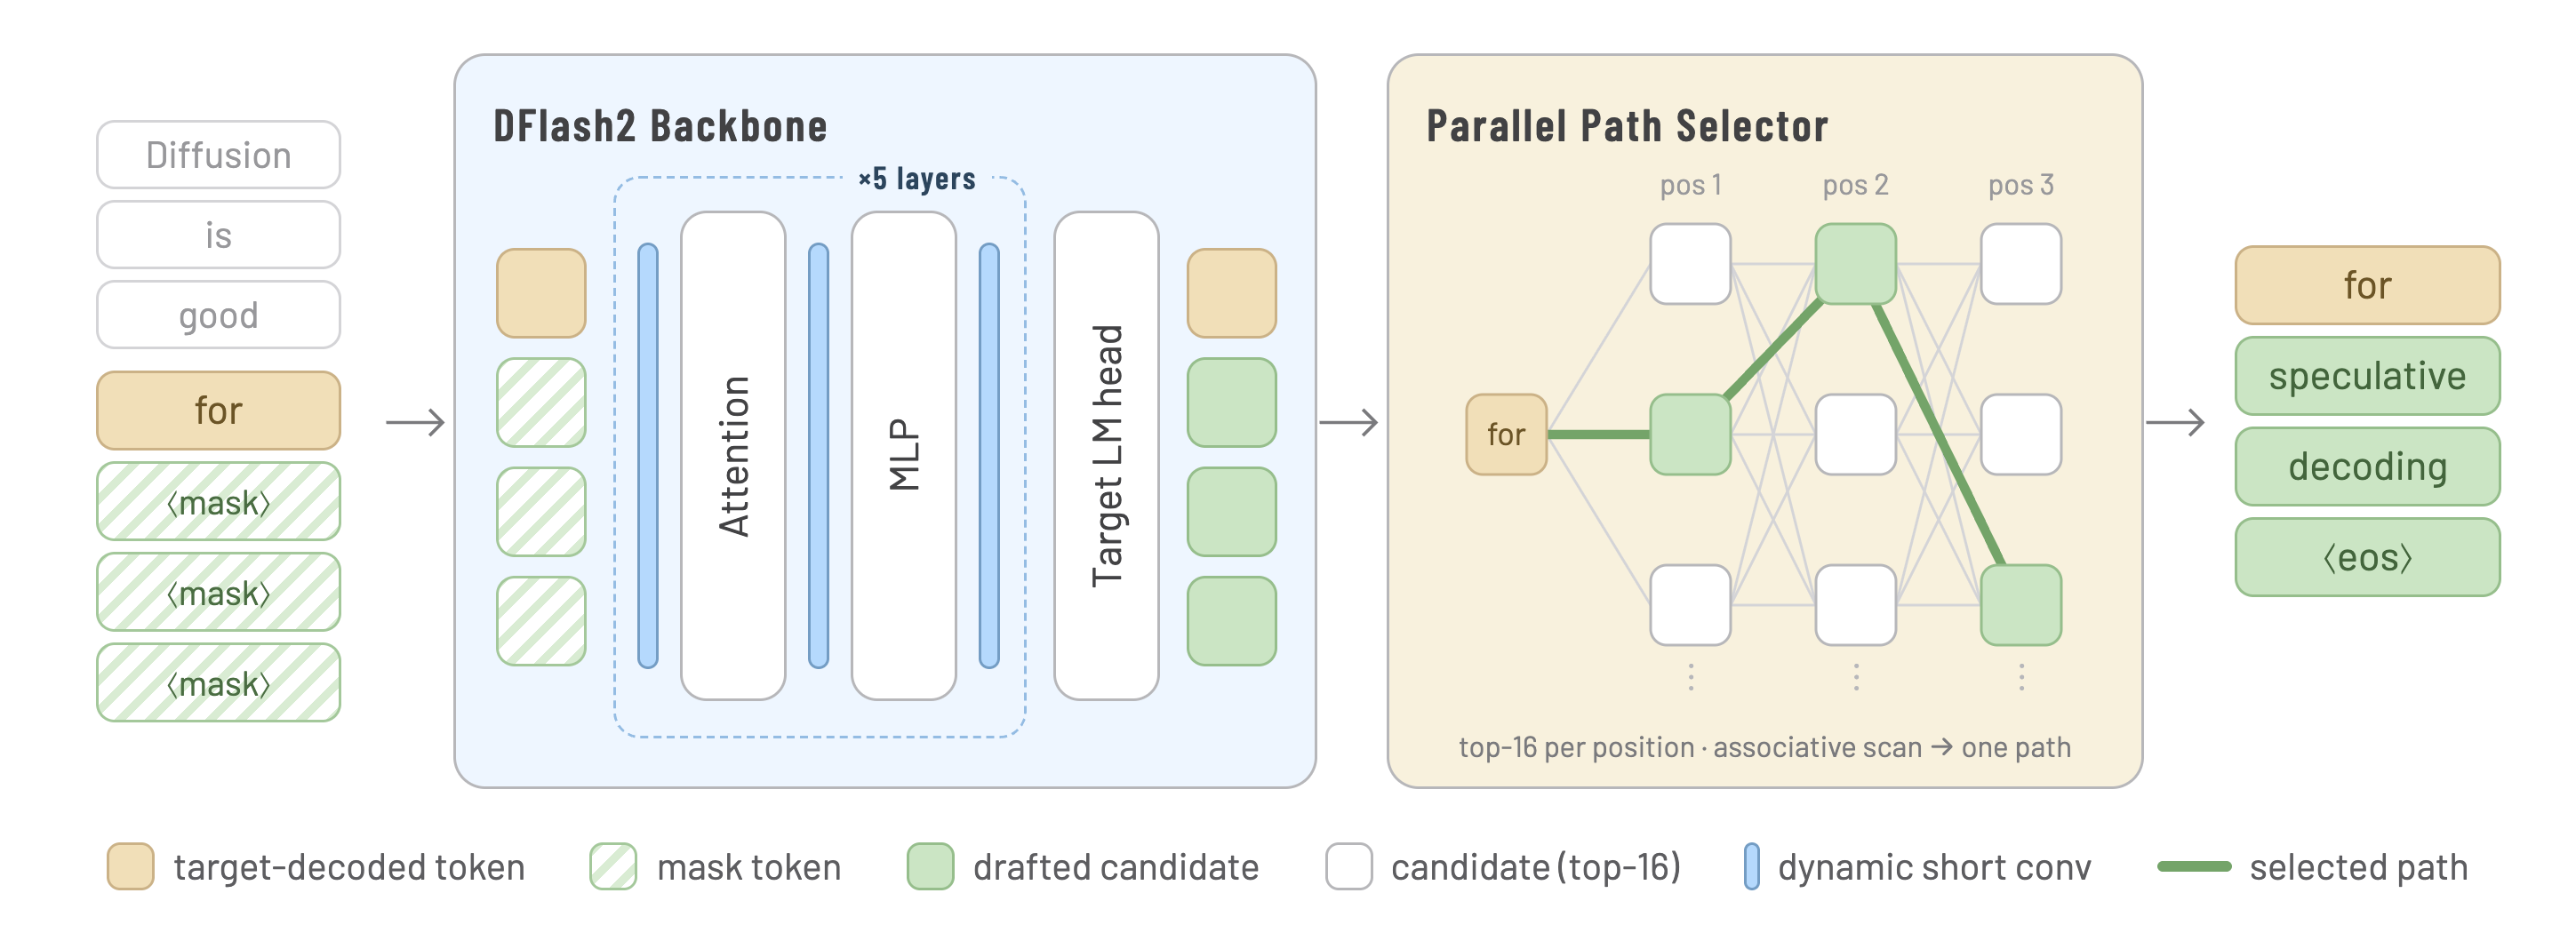
6.2Kz-lab/dflash · PythonDFlash is a lightweight block diffusion model built for speculative decoding, drafting tokens in parallel blocks so a larger target LLM can verify them faster than generating one token at a time.
- 16
openmed
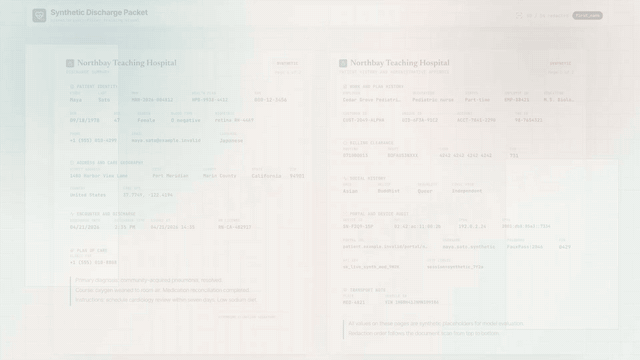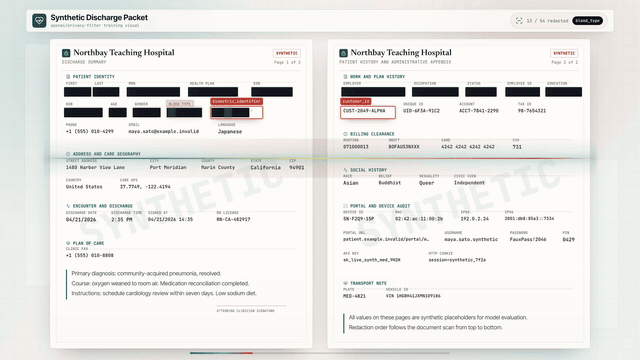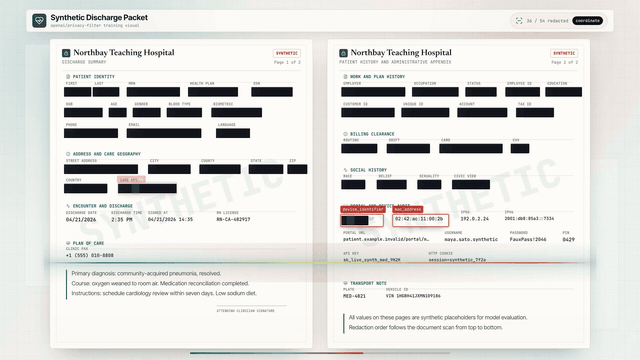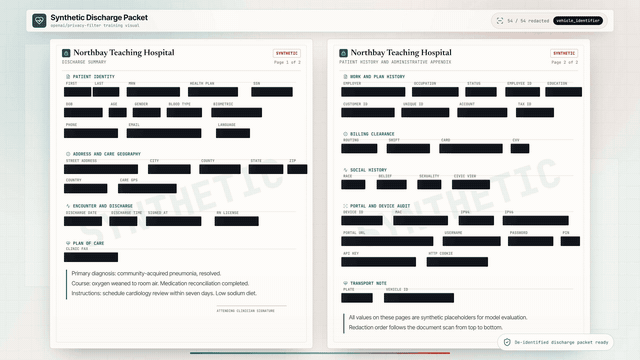
5.7Kmaziyarpanahi/openmed · PythonOpenMed is a local-first healthcare AI SDK: clinical NER and HIPAA PII de-identification that runs on your own hardware, with 2,200+ medical models and Python, MLX, Android, and browser runtimes.
- 17
SemIf-OpenJev
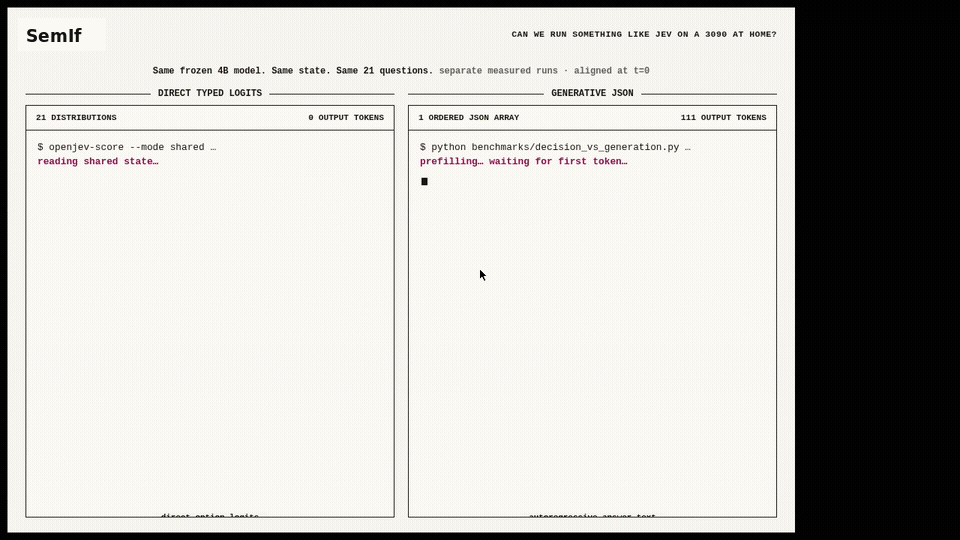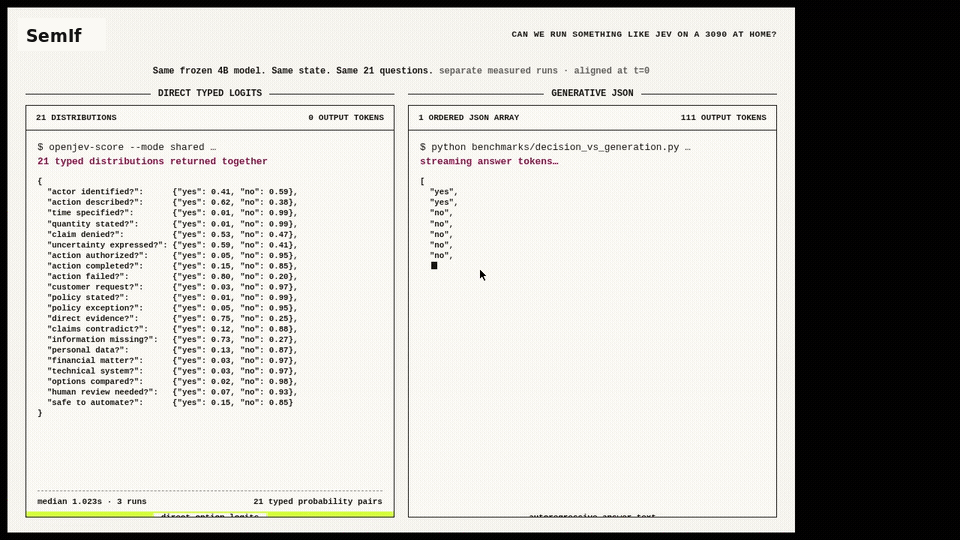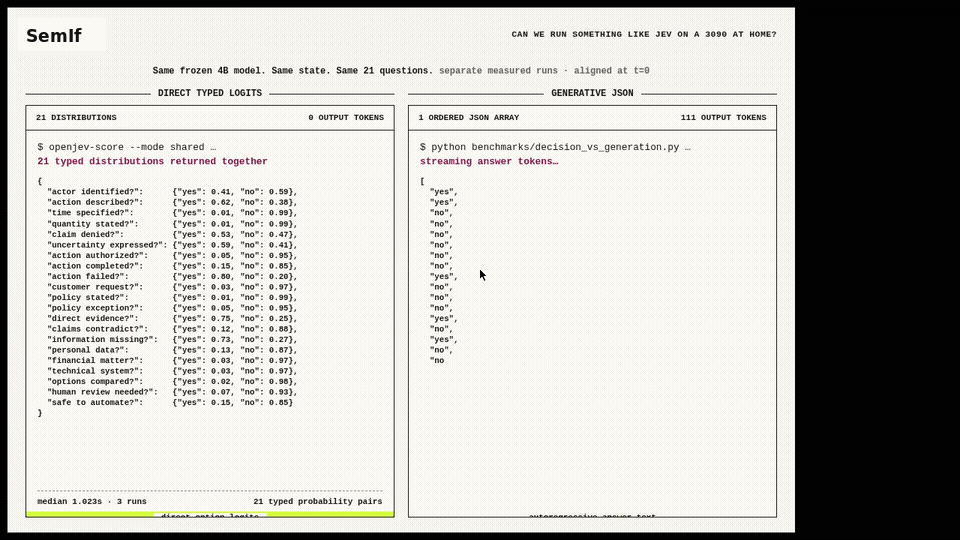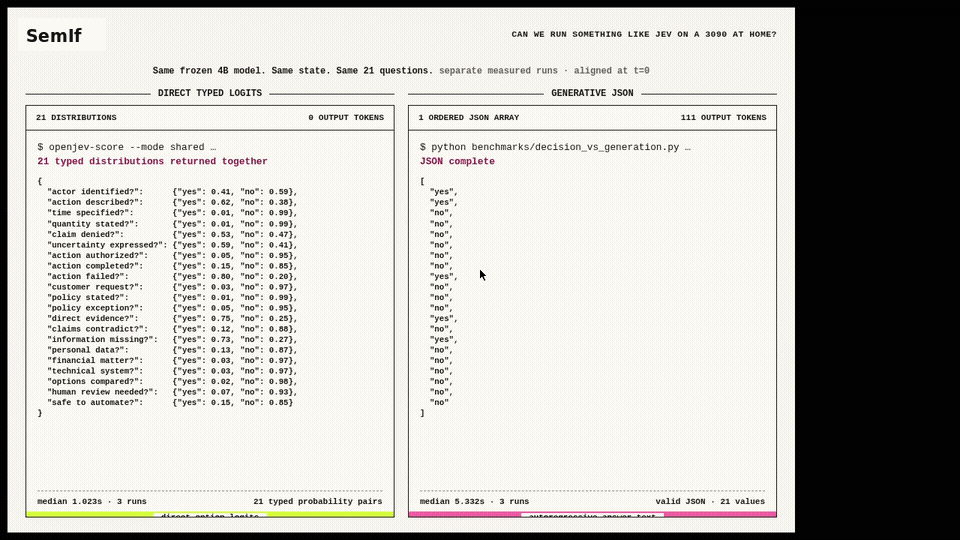
4.8KTheoLeeCJ/SemIf-OpenJev · PythonSemIf (formerly OpenJev) is an independent research project that runs runtime-defined semantic decisions with open models on one consumer GPU, mirroring the interface of TypeSafe's closed Jev service but not its undisclosed model.
- 18

sentrysearch
4.6Kssrajadh/sentrysearch · PythonSentrySearch is a CLI tool that lets you semantically search through video footage (like Tesla dashcam clips) by typing what you're looking for and getting back a trimmed clip of the matching moment.
- 19
Qwen3.8
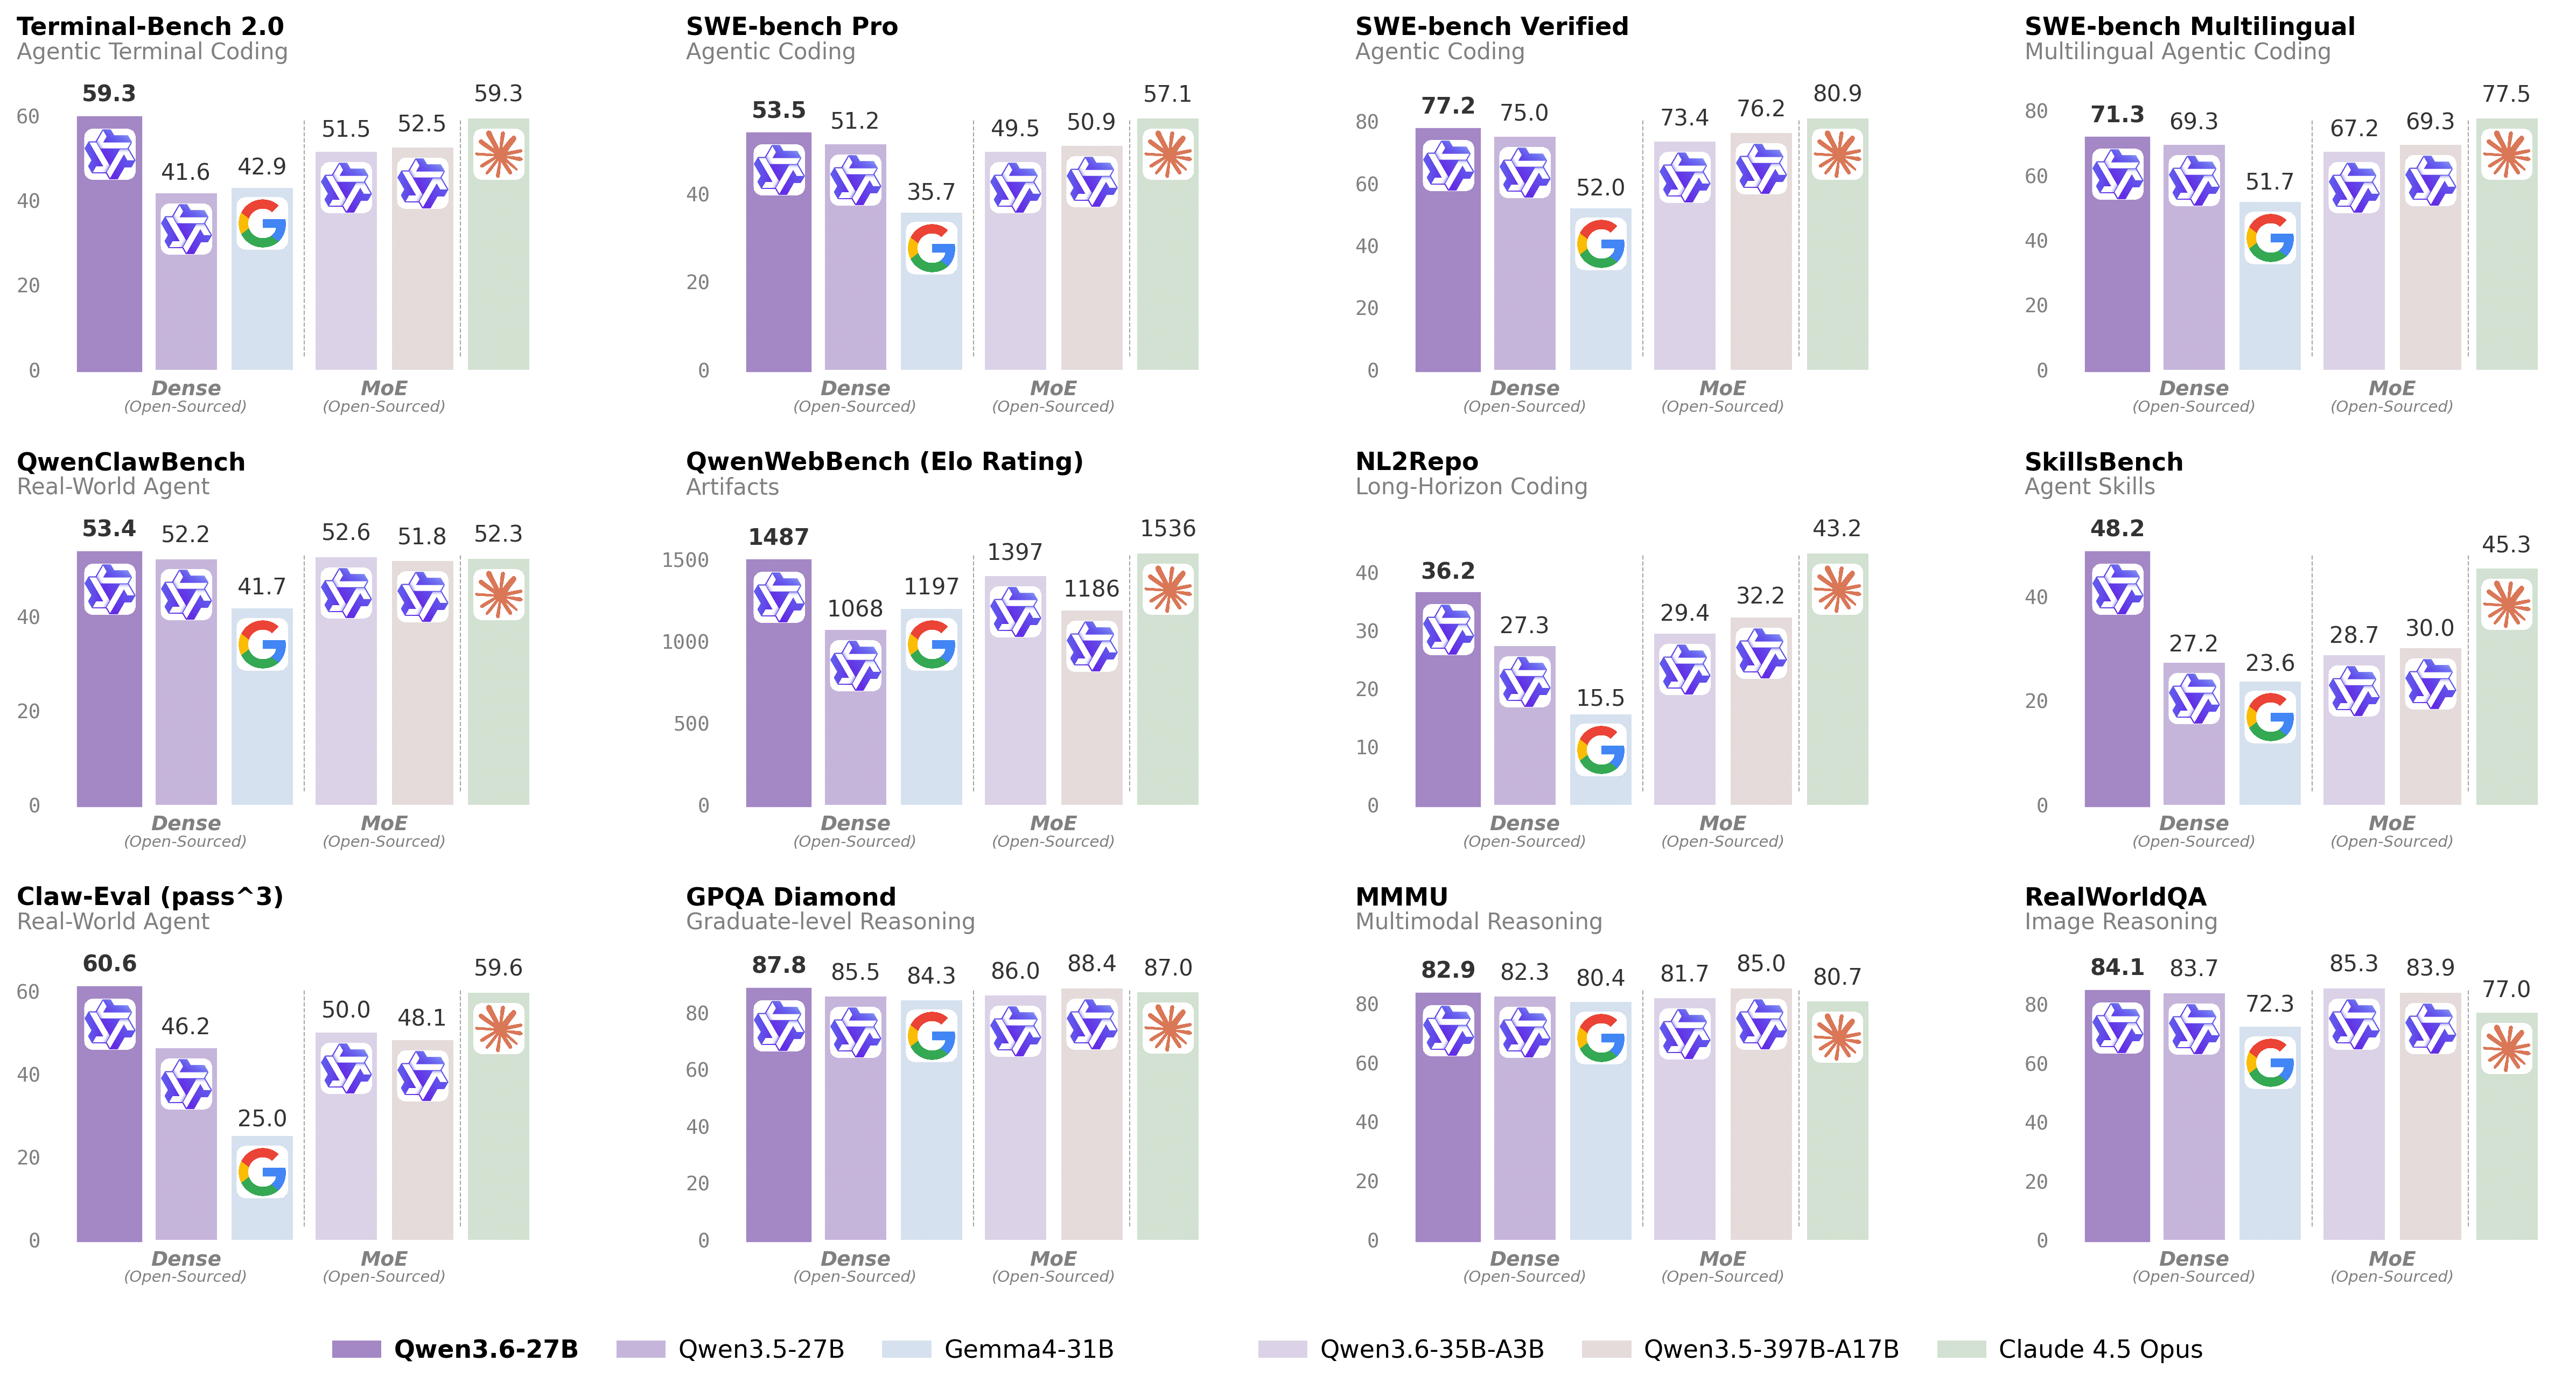
4.3KQwenLM/Qwen3.8Qwen3.8 is the latest open large language model release from Alibaba's Qwen team, part of the Qwen3.5 series that also includes Qwen3.5 and Qwen3.6, aimed at coding, professional work, research, and long-horizon agentic tasks.
- 20
MOSS-TTS
4.2KOpenMOSS/MOSS-TTS · PythonMOSS-TTS Family is an open-source speech and sound generation model family from OpenMOSS, covering long-form narration, multi-speaker dialogue, voice design, sound effects, and real-time streaming text-to-speech.
- 21
Rapid-MLX
4Kraullenchai/Rapid-MLX · PythonRapid-MLX is a local LLM inference server for Apple Silicon Macs, built on MLX, that exposes OpenAI- and Anthropic-compatible APIs and focuses on reliable tool calling for coding agents like Claude Code and Codex CLI.
- 22

Bonsai-demo
3.4KPrismML-Eng/Bonsai-demo · ShellBonsai Demo is a local-inference demo for Bonsai 2 27B, a ternary-weight large language model that runs on a laptop or single GPU via llama.cpp or MLX, with chat, vision, and agentic tool-calling support out of the box.
- 23
nimble
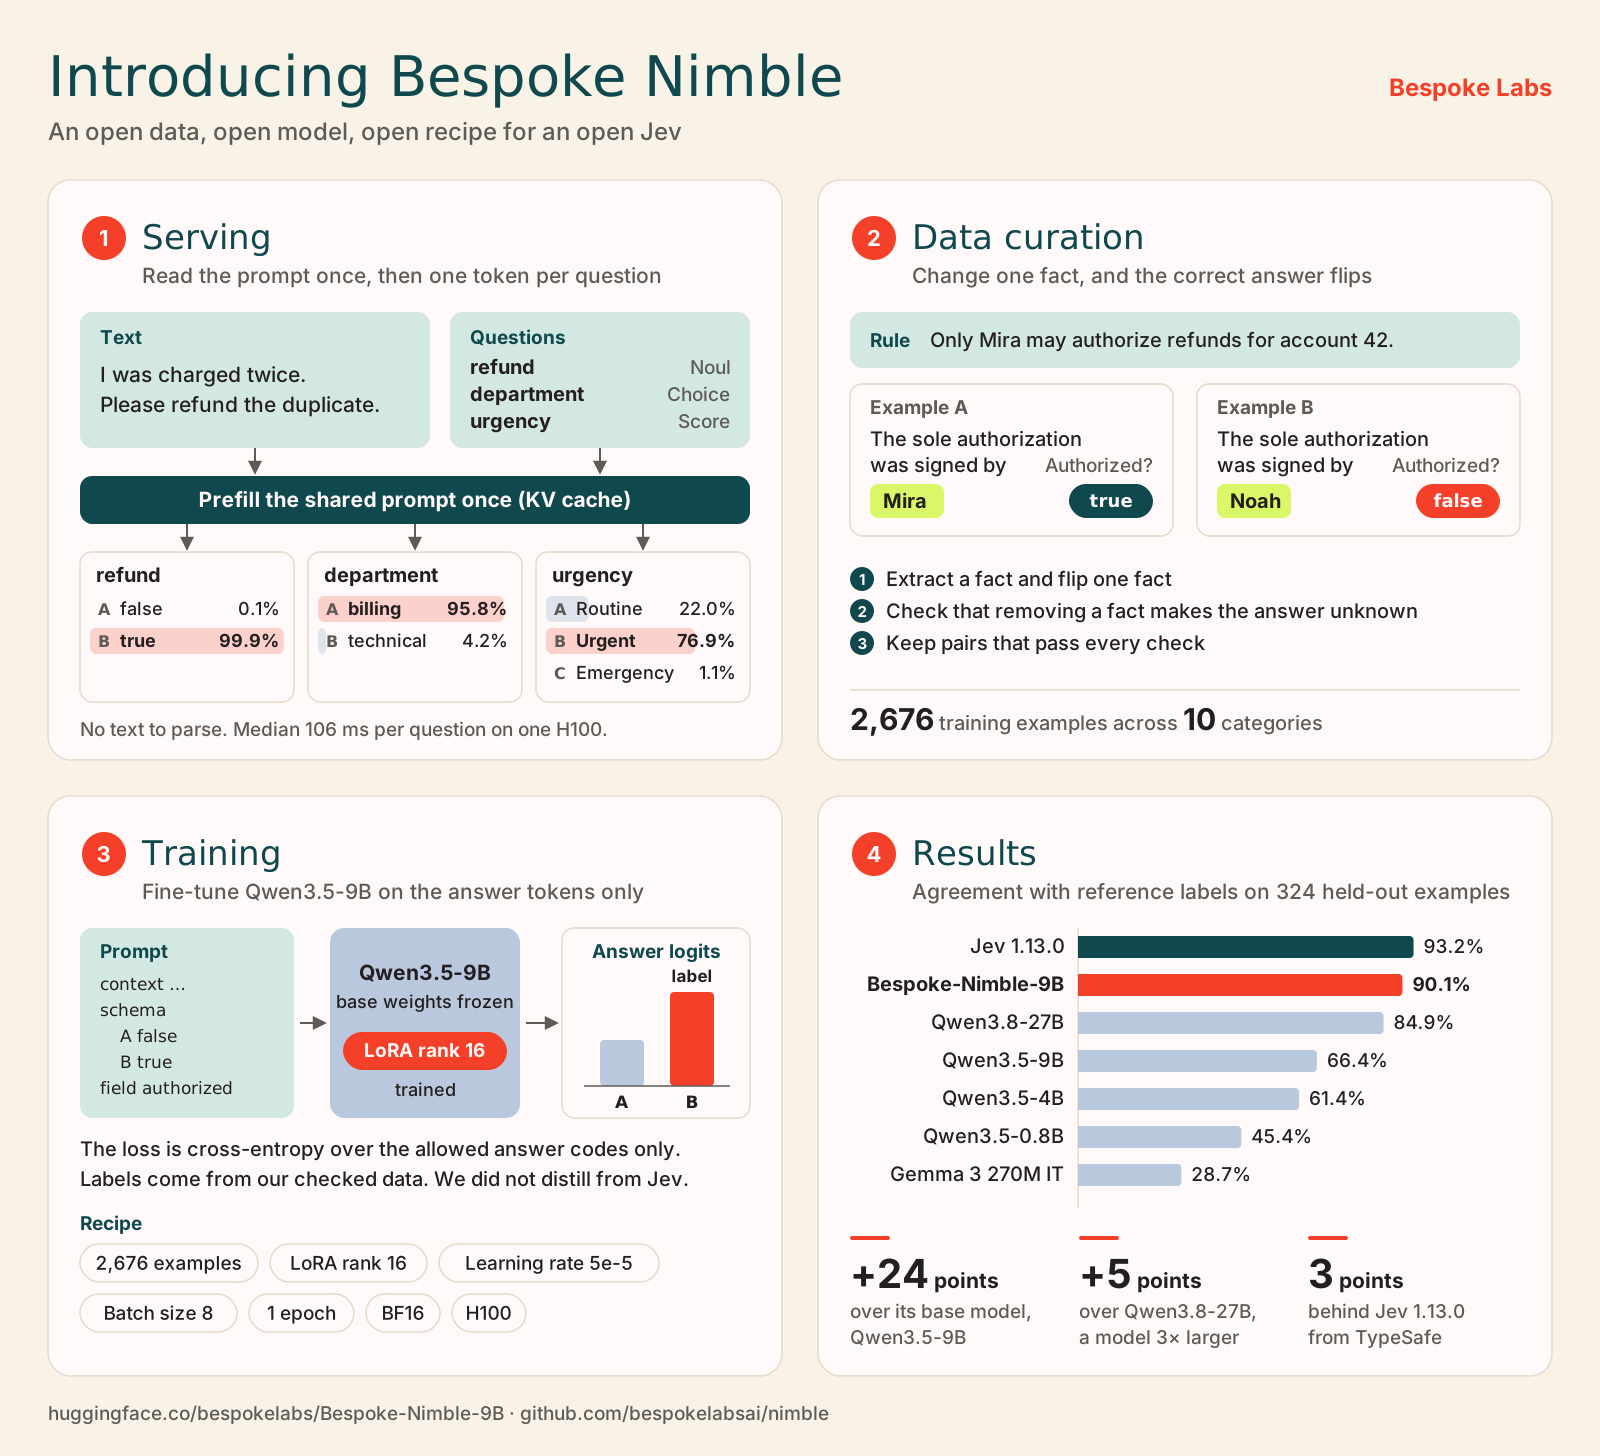
2.2Kbespokelabsai/nimble · PythonBespoke Nimble turns text plus a schema of questions into typed decisions: it picks one allowed answer per question and returns the probability of every option, in a single fast step. The repo shares the recipe and the trained Bespoke-Nimble-9B model.
- 24
mlx-serve
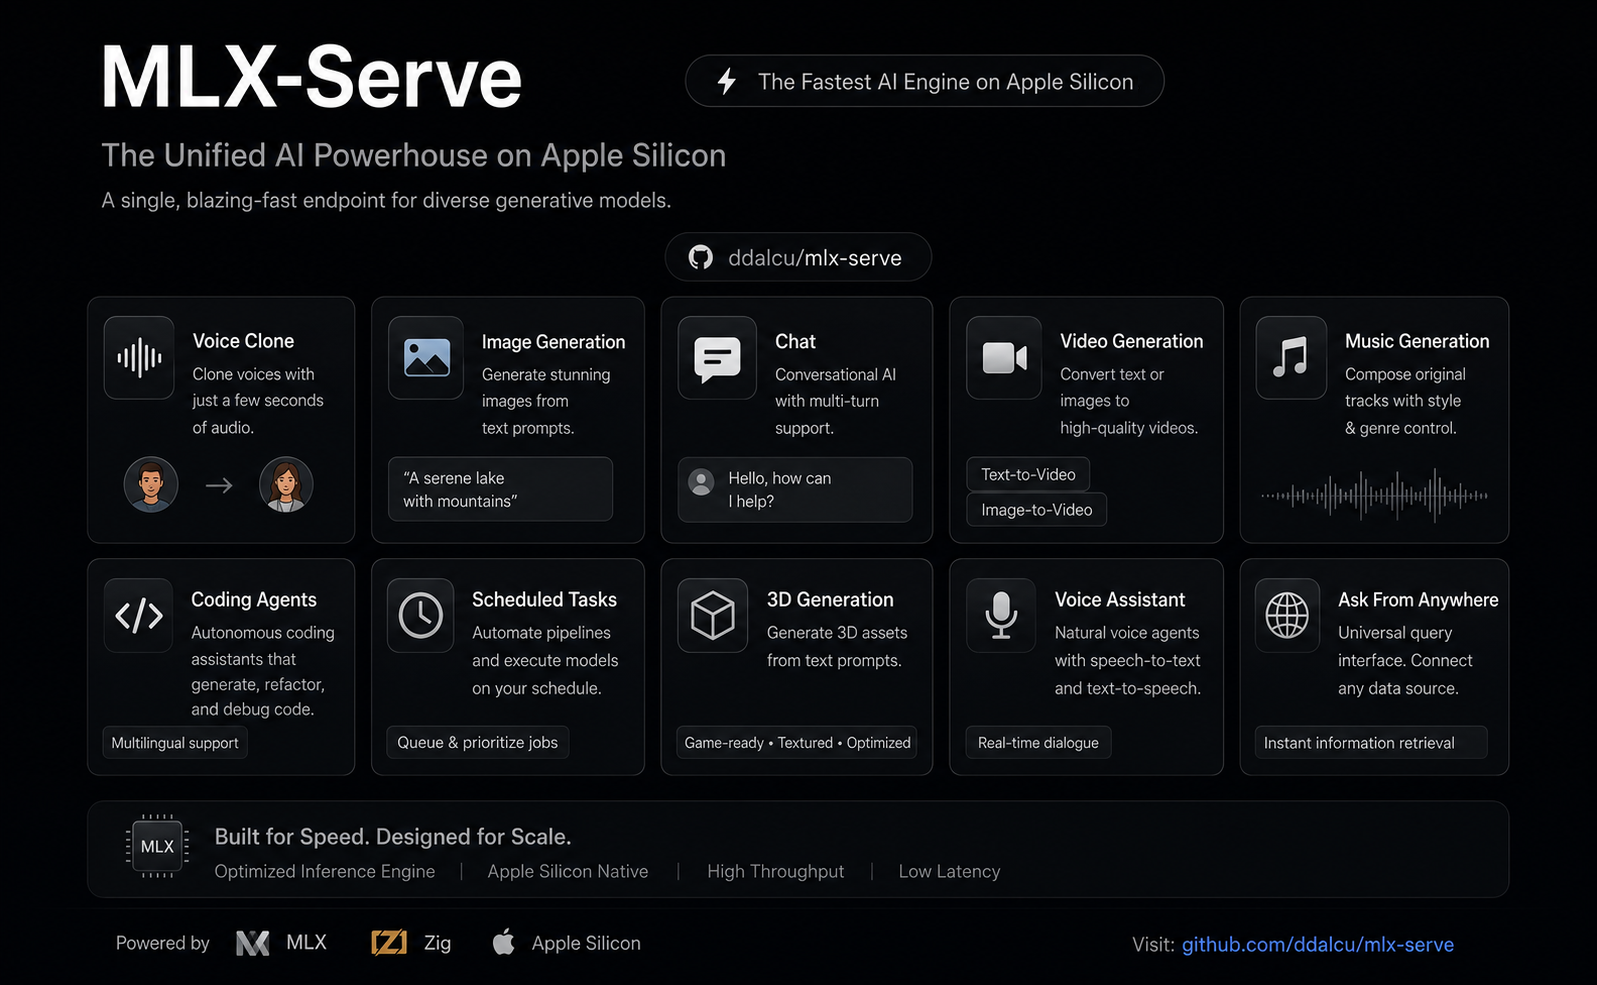
2Kddalcu/mlx-serve · Zigmlx-serve is a native local inference server for Apple Silicon Macs that runs MLX and GGUF language models and exposes OpenAI-, Anthropic-, and Ollama-compatible APIs, plus generates images, video, music, speech, and 3D models, all without Python or a cloud connection.
- 25
NeoHorse
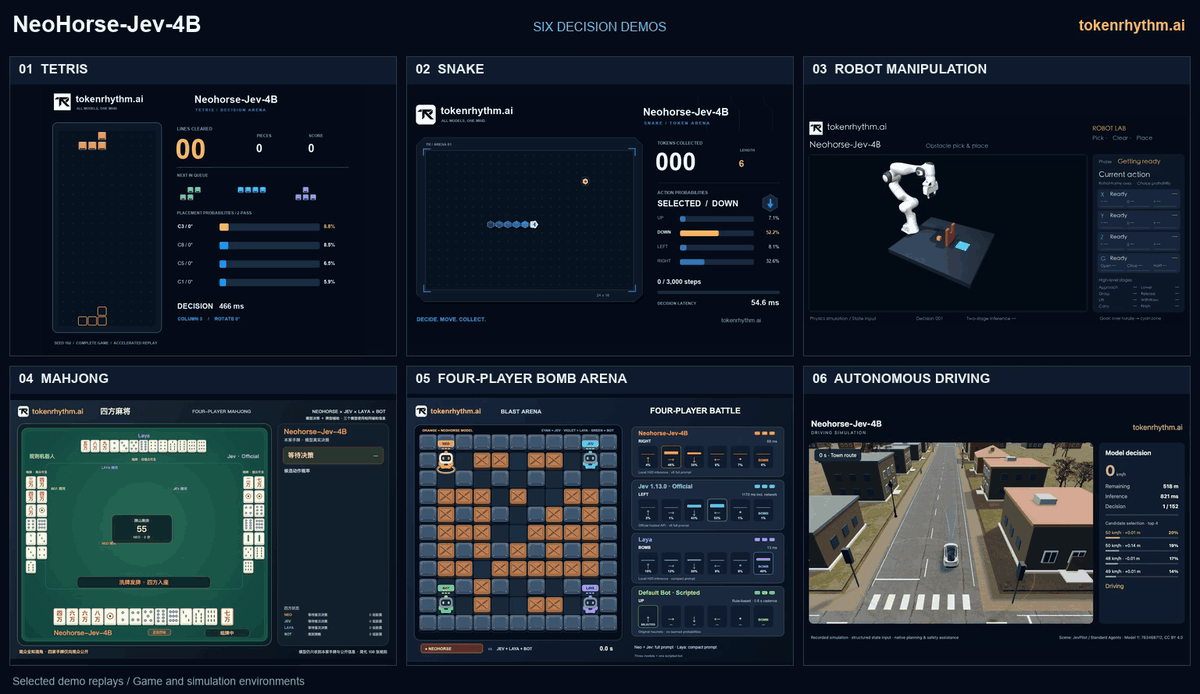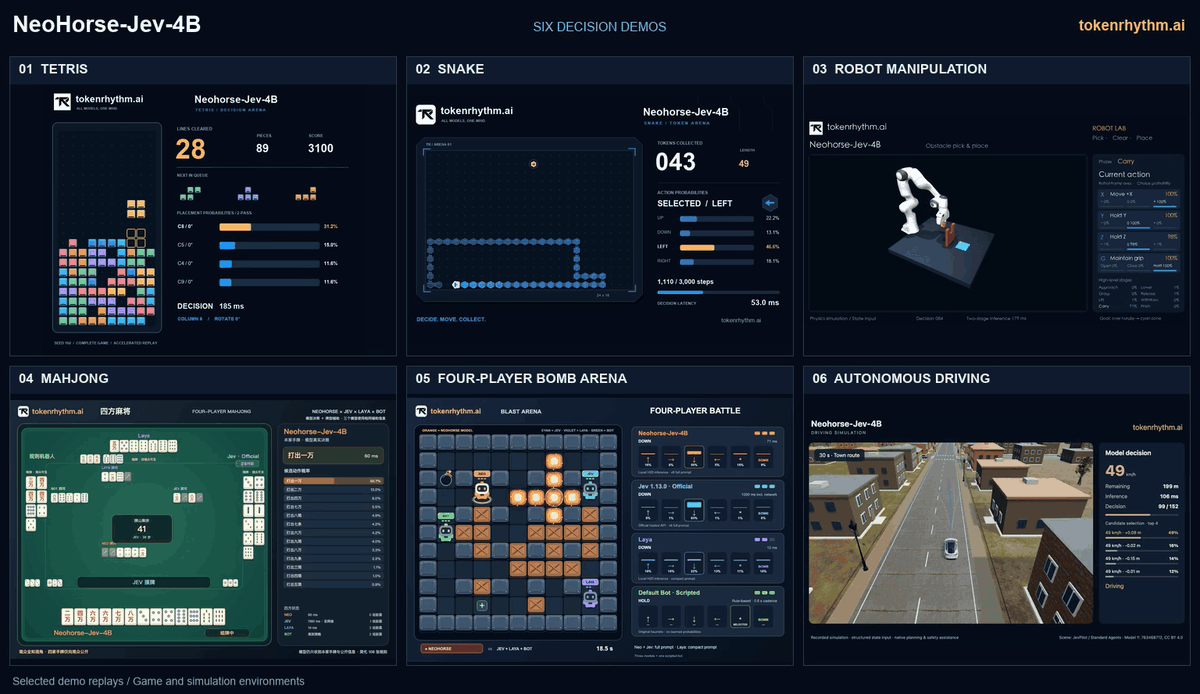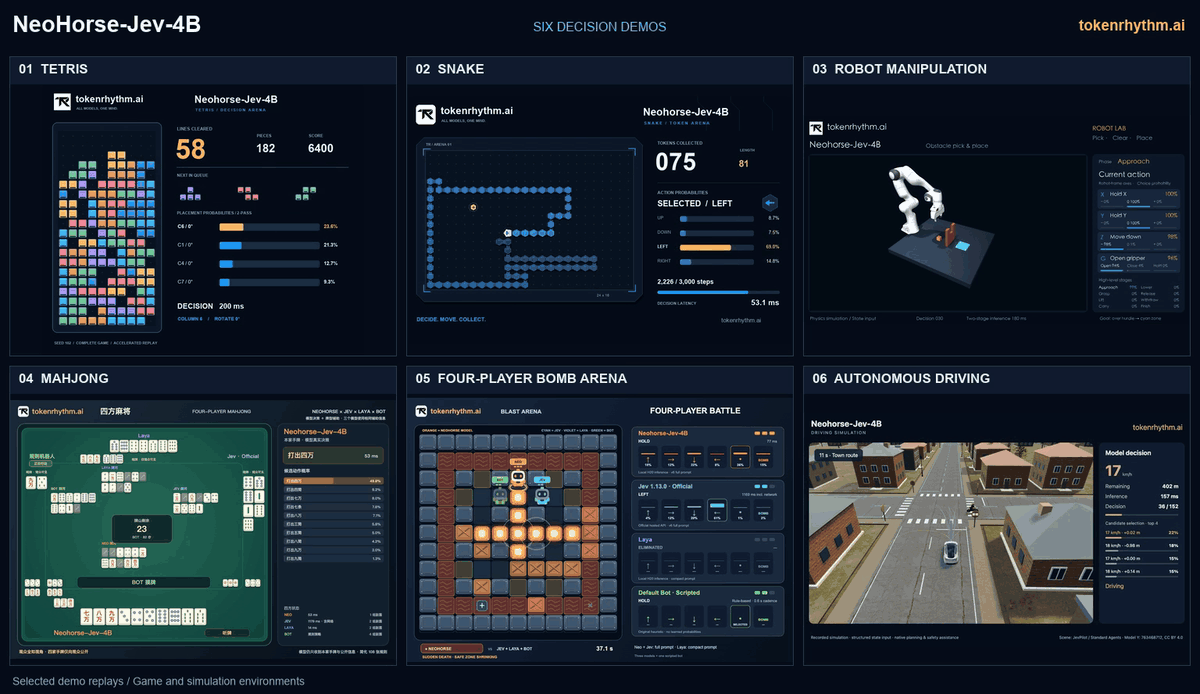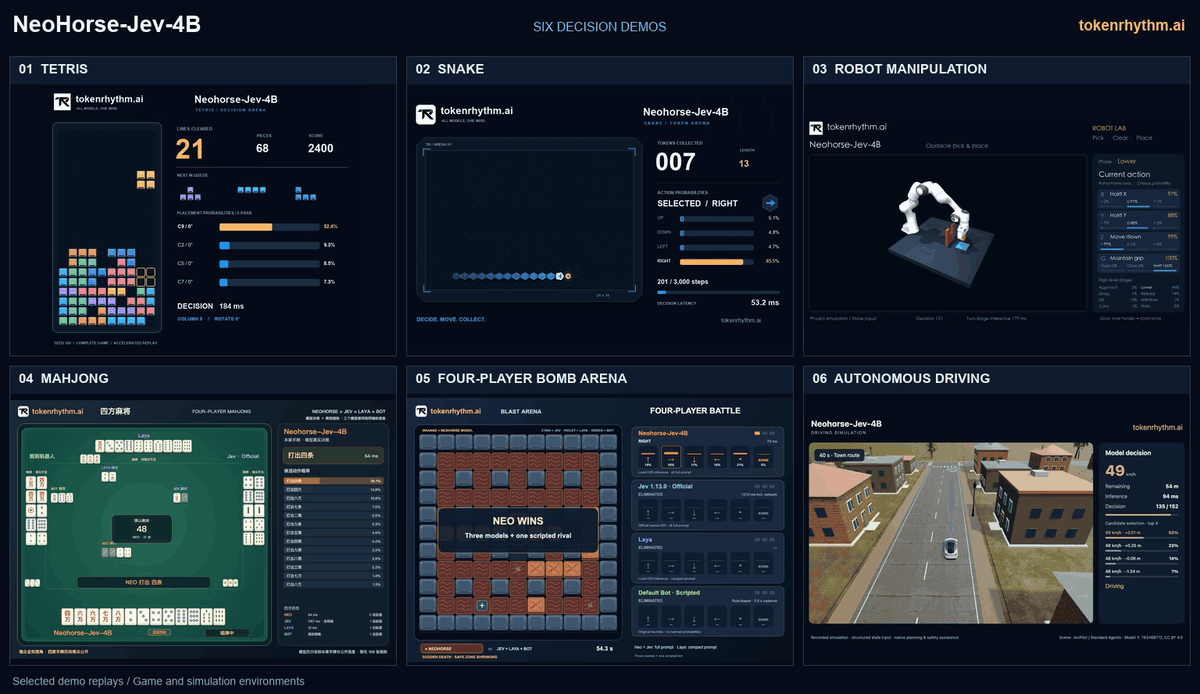
1.7KTokenRhythm/NeoHorse · PythonNeoHorse is TokenRhythm's family of open-weight language models built for agent workflows, with the 4B and 9B NeoHorse-1 checkpoints handling tool use, coding, and instruction following, plus a companion decision model called NeoHorse-Jev.
- 26
jeff
1.5Kfirelex/jeff · PythonJeff is a family of small (0.8B-2B parameter) open-weight models fine-tuned from Qwen3.5 and Gemma 4 that act as fast 'System 1' decision-makers: you describe a situation and a list of options in plain text, and Jeff returns a calibrated probability for each option from a single forward pass, with no generated text to parse.
- 27
speech-swift
1.2Ksoniqo/speech-swift · SwiftLocal Speech AI on a MacBook — watch the 4-minute open-source library tour on YouTube
- 28

ai-torture-chamber
965terrafying/ai-torture-chamber · PythonA research project that steers small open-weight language models into strong negative or positive emotional states and measures what they say and do. A live version runs at wirehead.agency.
- 29

mac-performance-monitor
937Zesty0wl/mac-performance-monitor · SwiftA native macOS performance monitor and recorder that tracks CPU, memory, GPU, network, disk, battery, and sensor readings, letting you compare them against the processes behind them. It works as a menu bar readout, a quiet background recorder, or a window you open when needed.
- 30
Spark-X2.5
812XHToken/Spark-X2.5Spark-X2.5 is a series of two open-source language models (4B and 1.7B parameters) built for everyday conversation, writing, translation, coding, reasoning and agentic tool-use tasks, aiming for strong performance in a compact size.
- 31
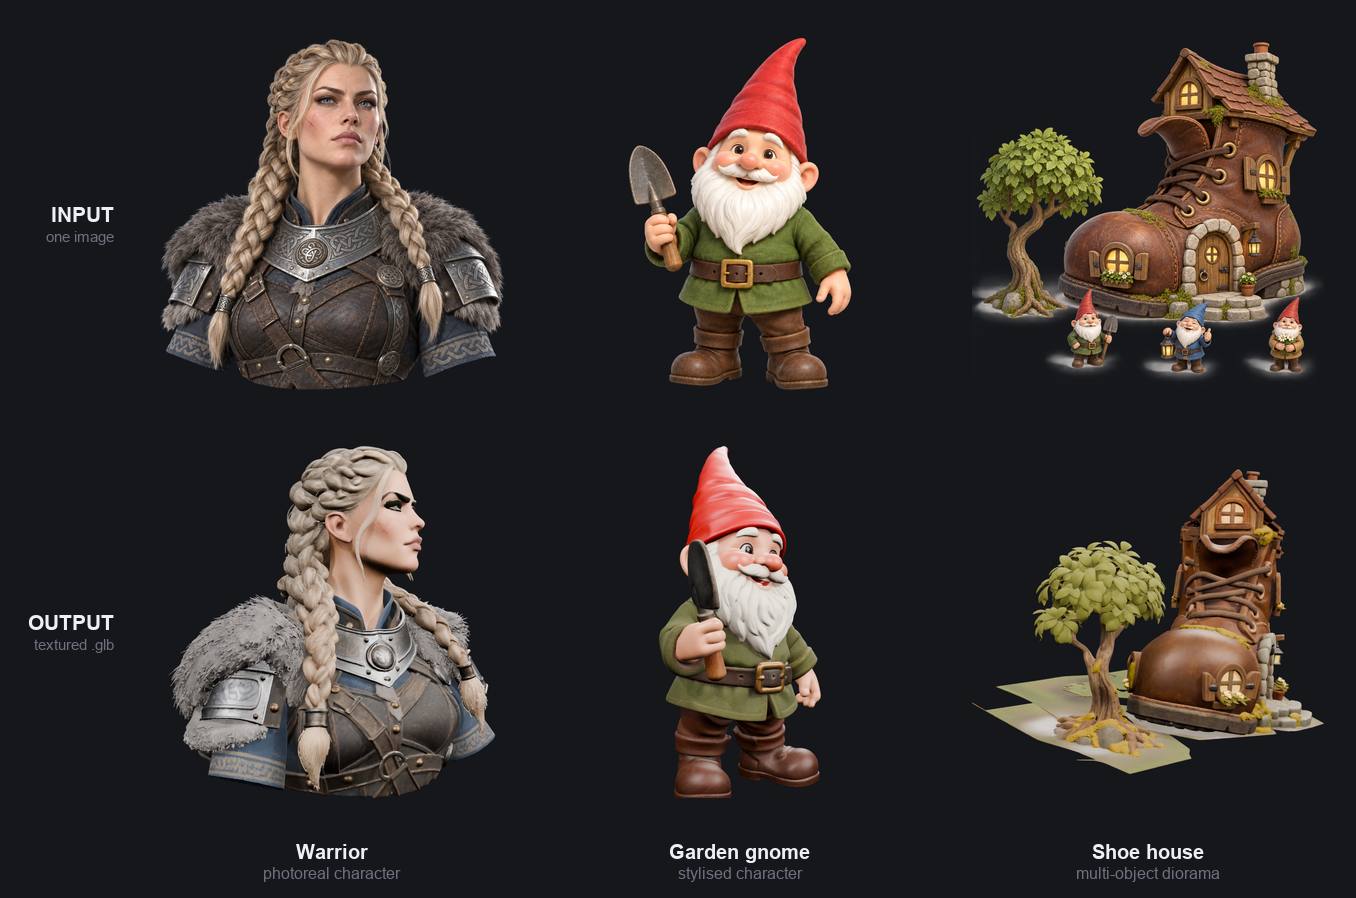
image-to-3dlab
810Bingeljell/image-to-3dlab · PythonAssetFurnace (image-to-3dlab) turns a single image, or a text prompt, into a textured, rigged, animated 3D game character, running entirely on your own Apple Silicon Mac or NVIDIA Linux machine.
- 32
strands-decider
659strands-labs/strands-decider · PythonStrands Decider is a small, fast 'system one' decision model built for agentic workflows. Instead of generating free text like an LLM, it picks between a set of options or rates something on a scale, and returns a calibrated confidence score for every decision.
- 33
StartLux-Decision
626StartLuxLabs/StartLux-Decision · PythonStartLux-Decision is a family of typed decision models (five dense sizes from 0.8B to 27B plus a 35B-A3B mixture-of-experts) that answer a question with a probability for each option instead of generating text.
- 34

lipflow
625amywork777/lipflow · PythonLipflow is 'Wispr Flow for your lips' — hold a key, silently mouth what you want to say with no sound and no microphone, and the text appears at your cursor in whatever app you're using. It reads your lips via webcam and runs entirely locally on your Mac.
- 35

slotstream
477carloslfu/slotstream · SwiftSlotstream lets you run a 105 GB AI model (Qwen3.8-Flash-Next, a 125B-parameter mixture-of-experts model) on Macs with only 16 to 64 GB of RAM, by streaming most of the model from SSD and caching the busiest experts in memory.
- 36
Qwen3.8-Flash-Next
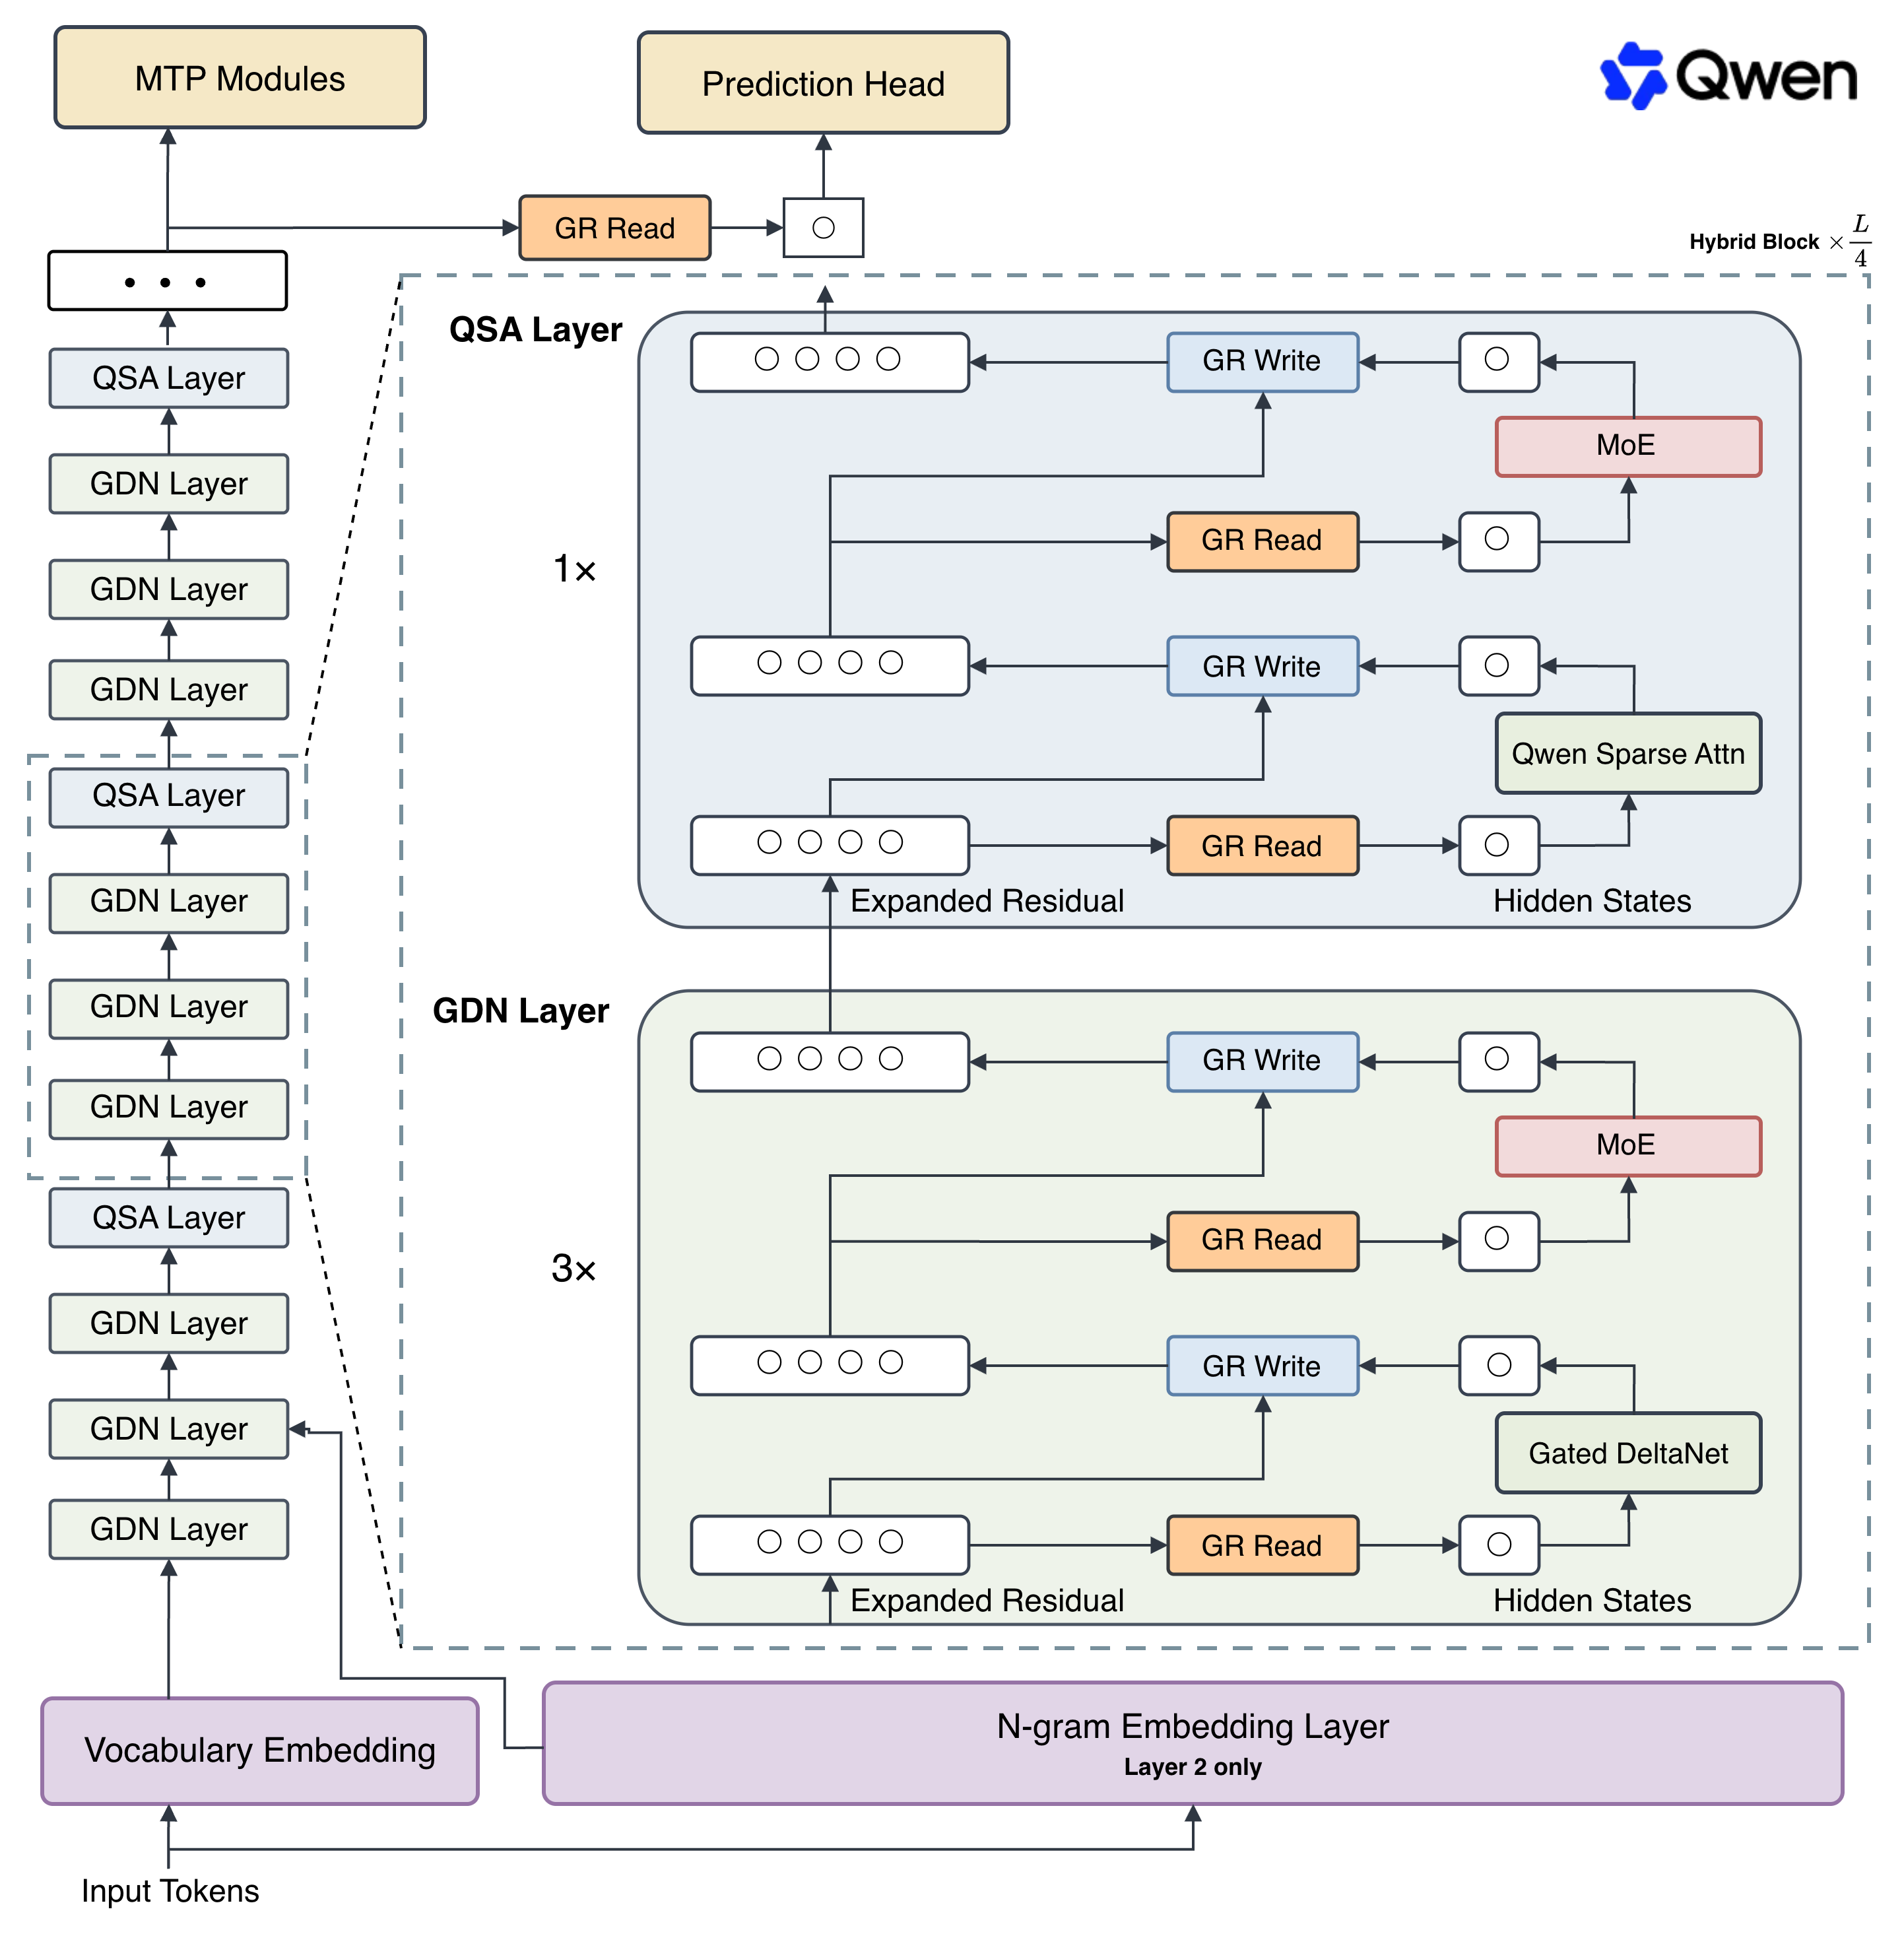
433QwenLM/Qwen3.8-Flash-NextQwen3.8-Flash-Next is an open-weight multimodal Mixture-of-Experts foundation model from Alibaba's Qwen Team, also serving as an early preview of the architecture Alibaba plans to use for the upcoming Qwen4 model family.
- 37
qwen38-uncensored
365Wassimyounes01/qwen38-uncensored · JavaScriptA Node.js install harness that sets up Qwen 3.8 27B as a fully uncensored local model, using weight-level abliterated GGUF weights plus a reinforcement SYSTEM prompt, runnable through Ollama or Apple's MLX.
- 38
pd-bridge
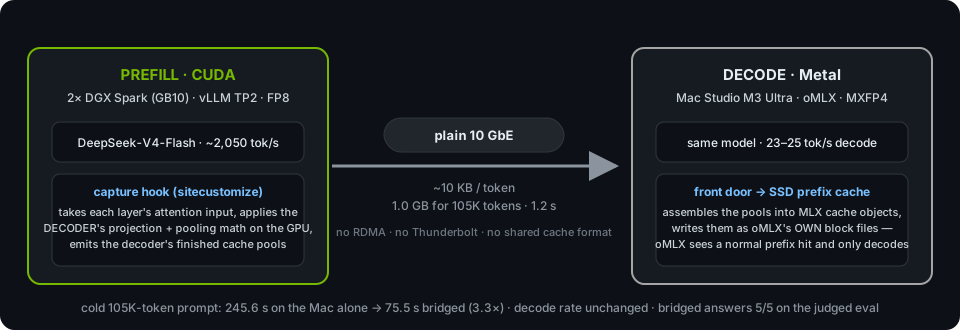
151chadhurley25075-png/pd-bridge · Pythonpd-bridge serves one DeepSeek-V4-Flash request across two machines: prefill runs on NVIDIA DGX Sparks (CUDA/vLLM), decode on a Mac Studio (Metal/oMLX), linked by ordinary 10GbE Ethernet.
- 39
open-jev
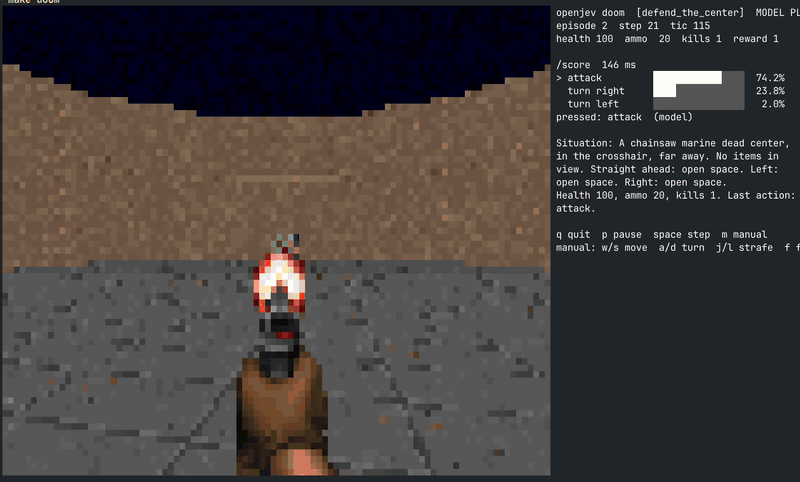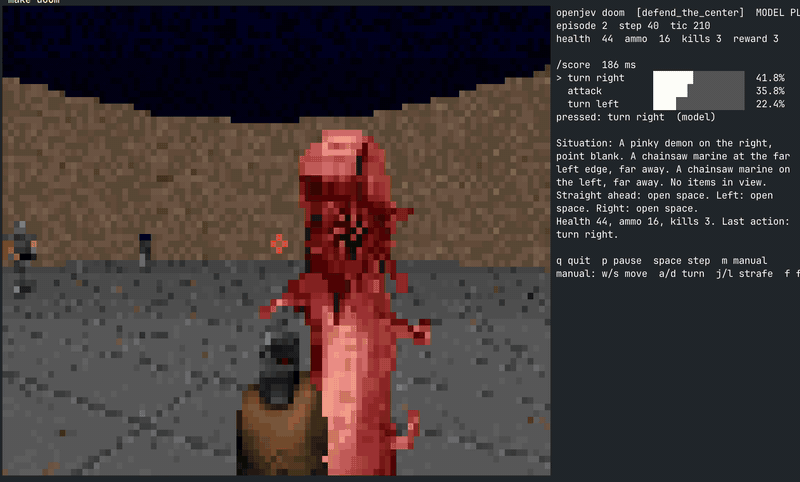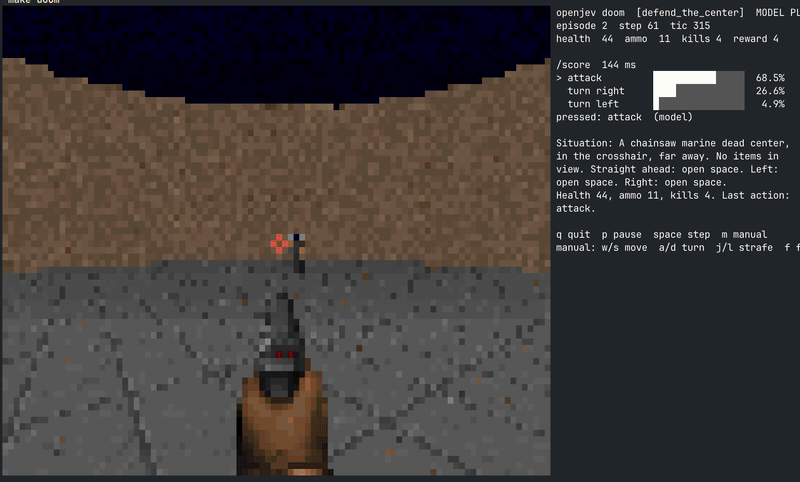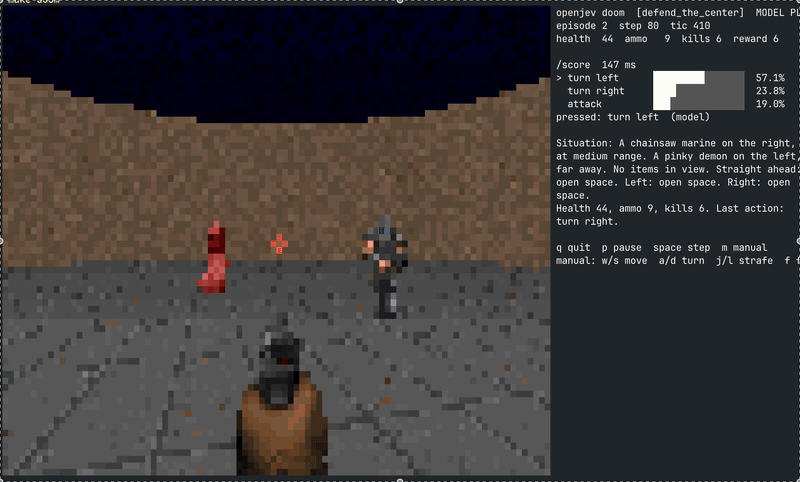
134daseinlabs/open-jev · PythonAn open implementation of Jev: a local Gemma 3 4B (via MLX) scores a list of pre-written options against a context in one batched forward pass on Apple silicon — no text generation, just log-probabilities per option.
Related topics
Often tagged together