Topics / #inference-engine
Inference-engine projects on GitHub
Serving runtimes optimized for running large language models efficiently in production.
As of , the most-starred Inference-engine projects on GitHub are llama.cpp (131.4K stars), colibri (42.5K stars) and airllm (39.1K stars). GitHub.Locker tracks 45 Inference-engine repositories with 474K stars combined. The fastest-growing on October 16 was Strata, with +718 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +718
Strata
Niko1221/Strata · ★ 26.4KStrata runs Qwen3.8-Flash-Next, a 125-billion-parameter AI model, on a normal gaming PC with one NVIDIA GPU (12-24GB VRAM) and 64GB of RAM, with a one-click installer for Windows and Linux.
 +222
colibri
JustVugg/colibri · ★ 42.5KColibri is an open-source engine for running frontier mixture-of-experts (MoE) language models on hardware you already own — written in pure C with zero dependencies.
 +159
airllm
lyogavin/airllm · ★ 39.1KAn open-source Python library that runs huge LLMs on tiny GPUs: a 70B model fits on a single 4GB card without quantization, distillation or pruning — even the 2.8T-parameter Kimi K3 runs in under 4GB.
 +150
StartLux-Decision
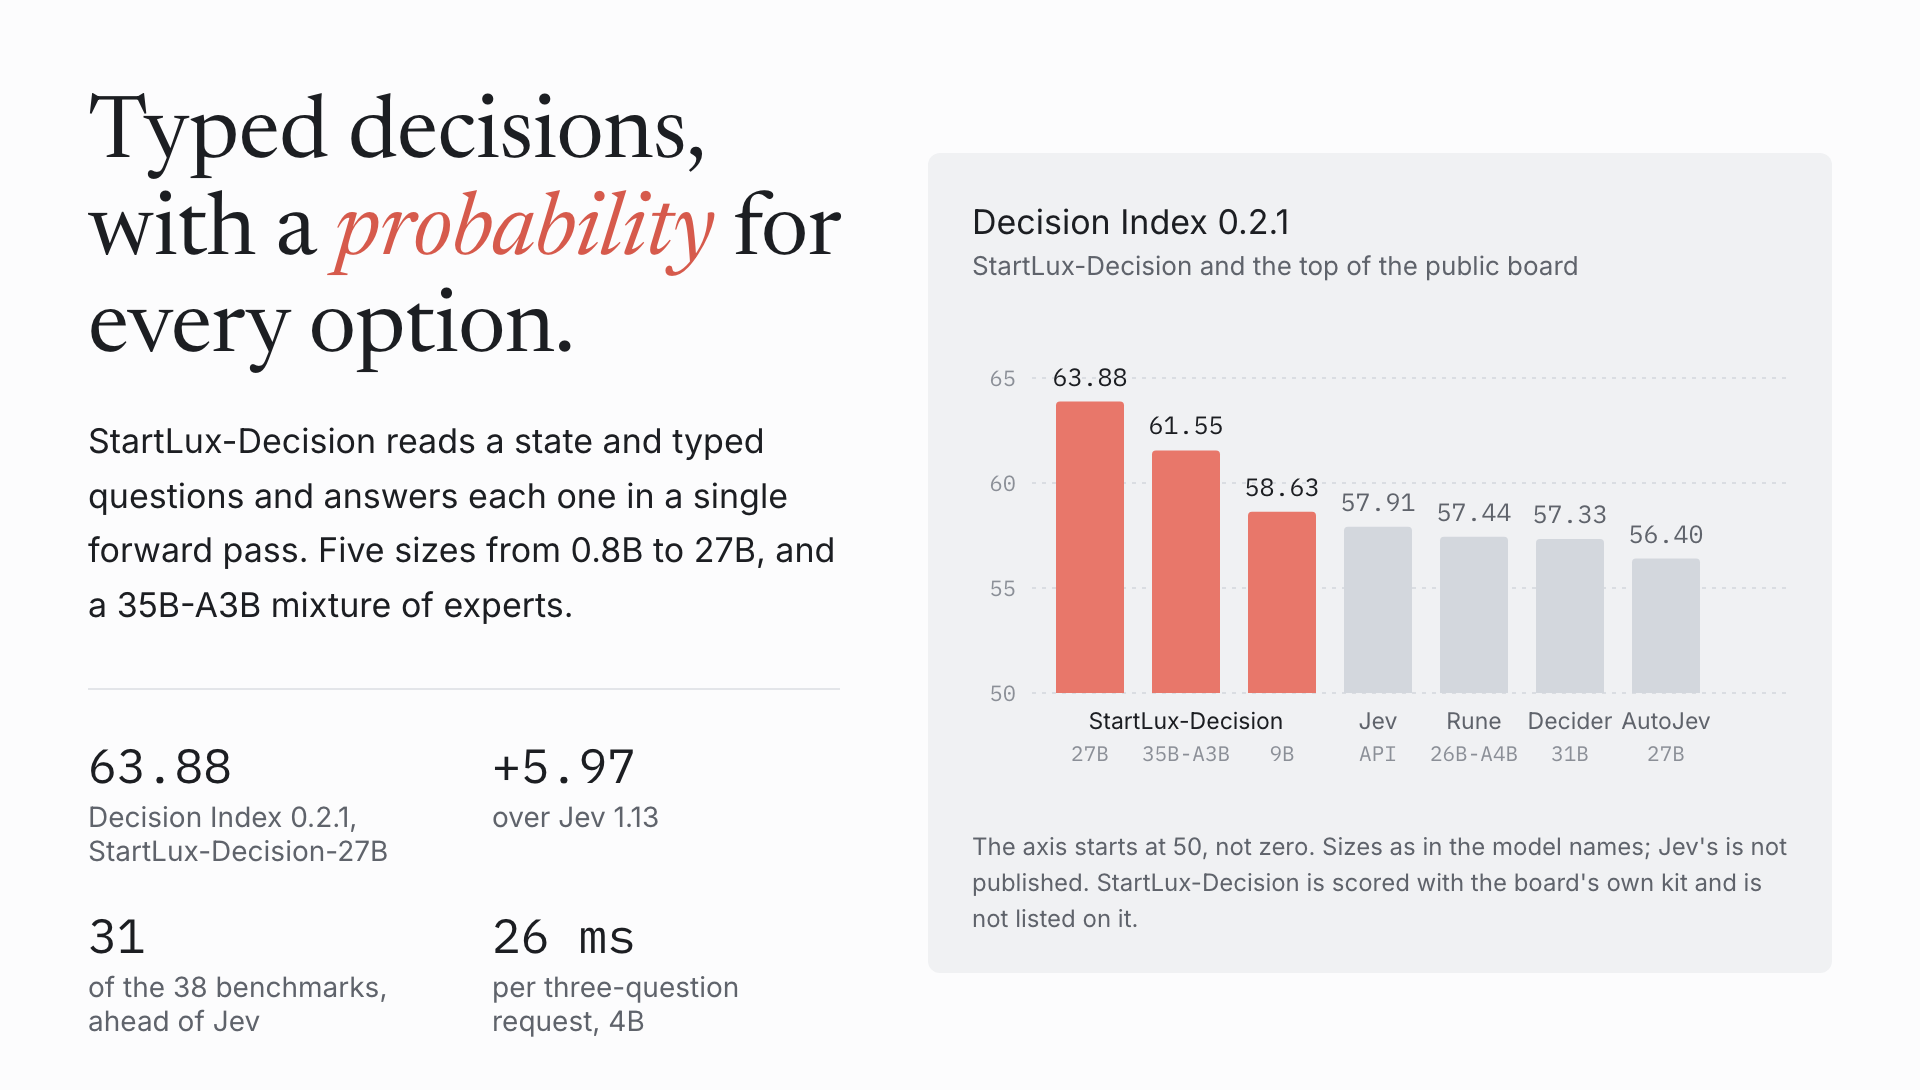
StartLuxLabs/StartLux-Decision · ★ 552StartLux-Decision is a family of typed decision models (five dense sizes from 0.8B to 27B plus a 35B-A3B mixture-of-experts) that answer a question with a probability for each option instead of generating text.
The all-time top
45 projects · by stars
- 131.4K
 #1 · ggml-org/llama.cpp
llama.cpp
llama.cpp is a plain C/C++ implementation for running LLM (and VLM) inference with minimal setup and state-of-the-art performance, either locally or in the cloud.
- 42.5K#2 · JustVugg/colibri
colibri
Colibri is an open-source engine for running frontier mixture-of-experts (MoE) language models on hardware you already own — written in pure C with zero dependencies.
- 39.1K#3 · lyogavin/airllm
airllm
An open-source Python library that runs huge LLMs on tiny GPUs: a 70B model fits on a single 4GB card without quantization, distillation or pruning — even the 2.8T-parameter Kimi K3 runs in under 4GB.
- 4
sglang
37.2Ksgl-project/sglang · PythonSGLang is a high-performance serving framework for large language models and multimodal models, built to deliver low-latency, high-throughput inference from a single GPU up to large distributed clusters.
- 5
Strata
26.4KNiko1221/Strata · C++Strata runs Qwen3.8-Flash-Next, a 125-billion-parameter AI model, on a normal gaming PC with one NVIDIA GPU (12-24GB VRAM) and 64GB of RAM, with a one-click installer for Windows and Linux.
- 6
ds4
23.9Kantirez/ds4 · CDwarfStar (ds4) is a small, self-contained local inference engine specialized for running DeepSeek V4 Flash and PRO, plus GLM 5.2/5.3, on consumer hardware like high-memory Macs, NVIDIA GPUs, and AMD Strix Halo systems.
- 7
onnxruntime
22.1Kmicrosoft/onnxruntime · C++ONNX Runtime is a cross-platform, high performance ML accelerator for inference and training. It runs models from PyTorch, TensorFlow/Keras and classical ML libraries like scikit-learn, LightGBM and XGBoost.
- 8

web-llm
19.3Kmlc-ai/web-llm · TypeScriptWebLLM runs large language models directly in the browser, accelerated by WebGPU — no server involved. It exposes the OpenAI API, so standard OpenAI-style code works against open models running locally.
- 9
AISystem
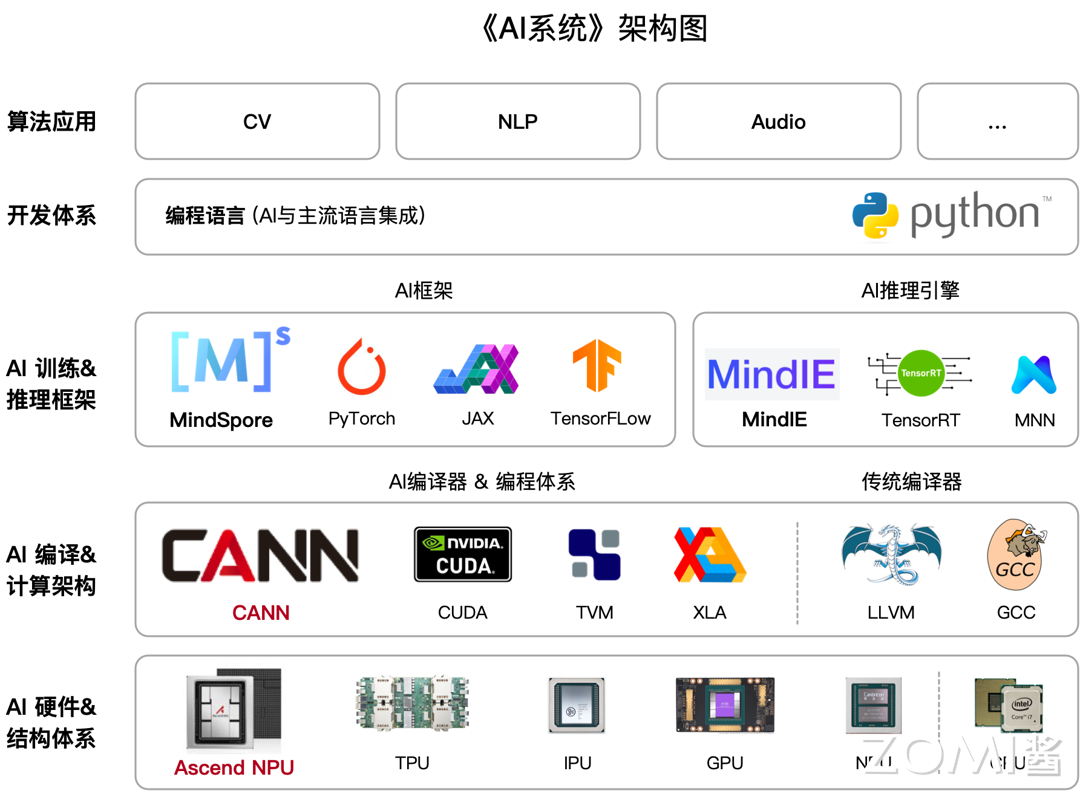
18KInfrasys-AI/AISystem · Jupyter NotebookAISystem (AISys) is an open-source course covering the full AI stack: AI chip architecture, AI compilers, inference systems/engines, and training framework internals.
- 10
MNN
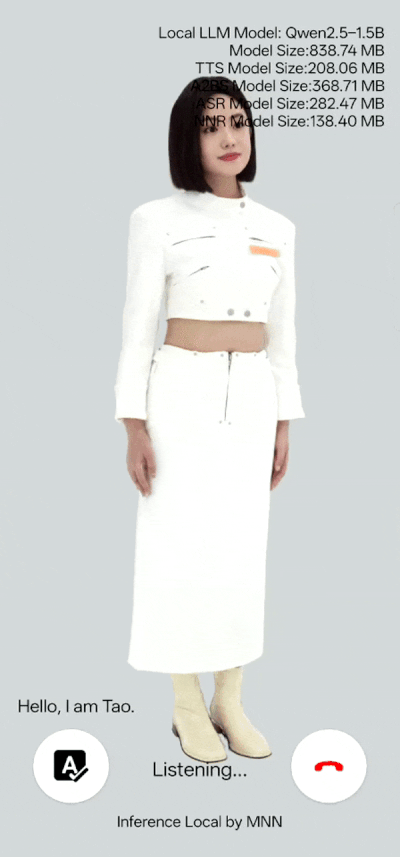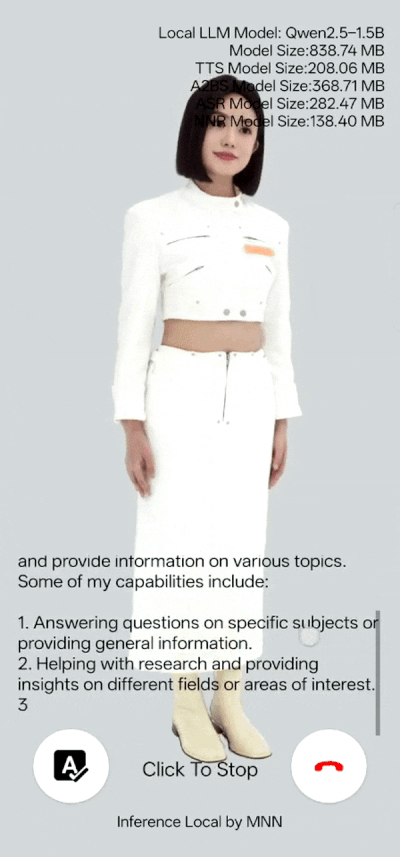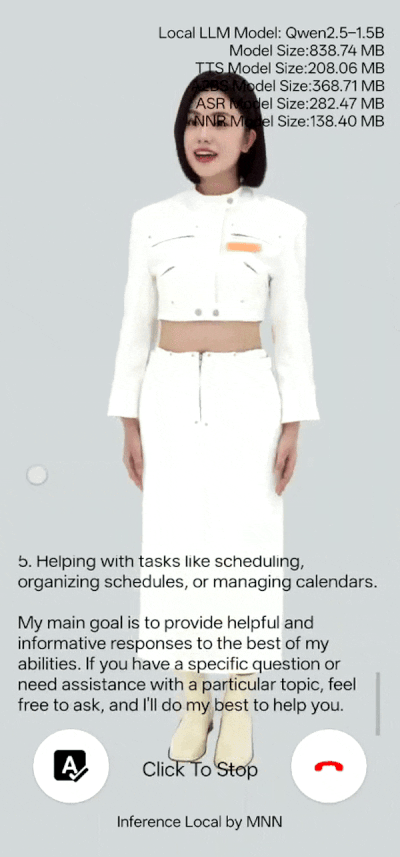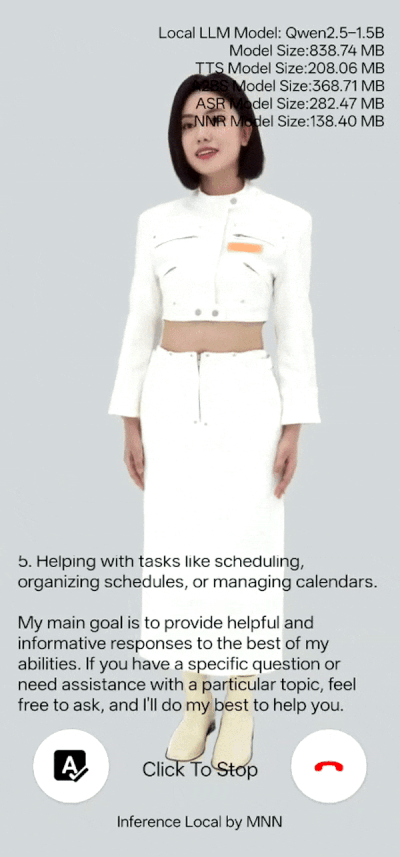
16.2Kalibaba/MNN · C++MNN is a lightweight, high-performance deep learning inference (and training) engine built by Alibaba, used to run models like LLMs, diffusion models, and CNNs efficiently on mobile, embedded, and edge devices.
- 11
nano-vllm
15.9KGeeeekExplorer/nano-vllm · PythonNano-vLLM is a lightweight, from-scratch reimplementation of the vLLM inference engine for running large language models, built in roughly 1,200 lines of readable Python.
- 12
FreeToken
14.5KFlashML-org/FreeToken · PythonFreeToken is an edge-native Mixture-of-Experts (MoE) serving engine built to run frontier-scale open-weight models, including 290B+ parameter models, on consumer hardware like gaming PCs.
- 13
Halfrost-Field
13.2Khalfrost/Halfrost-Field · GoHalfrost-Field is a personal technical blog archive by halfrost containing long-form deep-dive articles on source code analysis, system design, and engineering topics such as Go internals, vLLM/LLM serving, machine learning notes, and network protocols.
- 14

server
11.1Ktriton-inference-server/server · PythonTriton Inference Server is an open source serving system for deploying trained AI models from frameworks like TensorRT, PyTorch, ONNX, OpenVINO, Python and RAPIDS FIL, running inference requests over HTTP/REST or gRPC.
- 15
openvino
11Kopenvinotoolkit/openvino · C++OpenVINO is Intel's open-source toolkit for optimizing and deploying AI inference — it takes trained deep learning models for vision, speech, NLP, and generative AI and runs them faster, from edge devices to cloud servers.
- 16
kimi-k3-in-c
9.1KFareedKhan-dev/kimi-k3-in-c · CAn inference engine for the 2.78-trillion-parameter Kimi K3 model, written in portable C99. It runs on a plain CPU in as little as 8 GB of RAM — no GPU, no BLAS, no framework — streaming the 1.56 TB checkpoint straight off disk.
- 17

warp
2.5Ksqliteai/warp · CWARP (Weight-Aware Runtime and Paging, formerly WASTE) is a dependency-free, embeddable C inference engine that runs huge mixture-of-experts models on consumer hardware by streaming each token's activated weights straight from NVMe — the full models, not distilled versions.
- 18
uzu
2.4Ktrymirai/uzu · Rustuzu is a high-performance inference engine for AI models that lets you run LLMs directly inside your app with zero latency, full data privacy, and no per-request inference costs.
- 19
FreeVideo
2KFlashML-org/FreeVideo · PythonFreeVideo is a local inference engine that lets you run the MiniMax H3 video generation model on your own consumer GPU instead of a cloud service, adapting its memory and compute strategy to your hardware.
- 20
nobodywho
1.6Knobodywho-ooo/nobodywho · RustNobodyWho is an open-source inference engine that runs LLMs locally and offline on phones, desktops and even Apple Watch — no API keys, no cloud calls. Under the hood it is powered by llama.cpp and accelerates through the GPU via Vulkan or Metal.
- 21
zero-to-sglang
1.5Kdatawhalechina/zero-to-sglang · PythonThe official SGLang x Datawhale course on LLM inference: it teaches how inference engines work, has you build a mini-sglang from scratch, and then digs into the real SGLang source code.
- 22

TensorFold
1.4Kashhart/TensorFold · ZigTensorFold is an LLM inference engine that serves open-weight language models through an OpenAI-compatible API, running them on Apple Silicon via MLX or on NVIDIA GPUs via CUDA.
- 23
halogen-flash-server
1Kpeonist-ai/halogen-flash-server · Shellhalogen-flash-server is a purpose-built inference server for running the Qwen3.8-Flash-Next model as fast as possible on AMD's Strix Halo (gfx1151) GPU, exposing an OpenAI-compatible API.
- 24
MiniMax-Music3
961MiniMax-AI/MiniMax-Music3MiniMax Music 3 is a music generation model that creates complete songs up to five minutes long from lyrics and a music description, producing 32 kHz 16-bit stereo WAV audio with coherent structure and expressive vocals.
- 25
TypeLLM
956TypeLLM/TypeLLM · PythonTypeLLM adds type-safe, schema-guaranteed output generation to existing open autoregressive LLMs, without changing their weights or architecture, letting models still think freely while returning typed JSON Schema-constrained answers.
- 26

project-maya
954mw00/project-maya · C++Project Maya lets you run GLM-5.3-Flash, a 321-billion-parameter mixture-of-experts AI model, on your own NVIDIA GPU(s) by streaming the model's experts across VRAM, RAM and NVMe SSD as the conversation needs them.
- 27

deltafin
849gavamedia/deltafin · RustDeltafin is a native Rust binary that runs the full, unpruned 2.8-trillion-parameter Kimi K3 model on a single consumer machine, keeping all 16 experts active, plus an OpenAI-compatible API server for local chat and coding agents.
- 28
gufo
781gufo-org/gufo · C++Gufo is a local inference engine built specifically for AMD Strix Halo hardware (Ryzen AI MAX+ 395 with Radeon 8060S / gfx1151, up to 128 GiB unified memory), serving text, speech, image and video models through an OpenAI-compatible API.
- 29
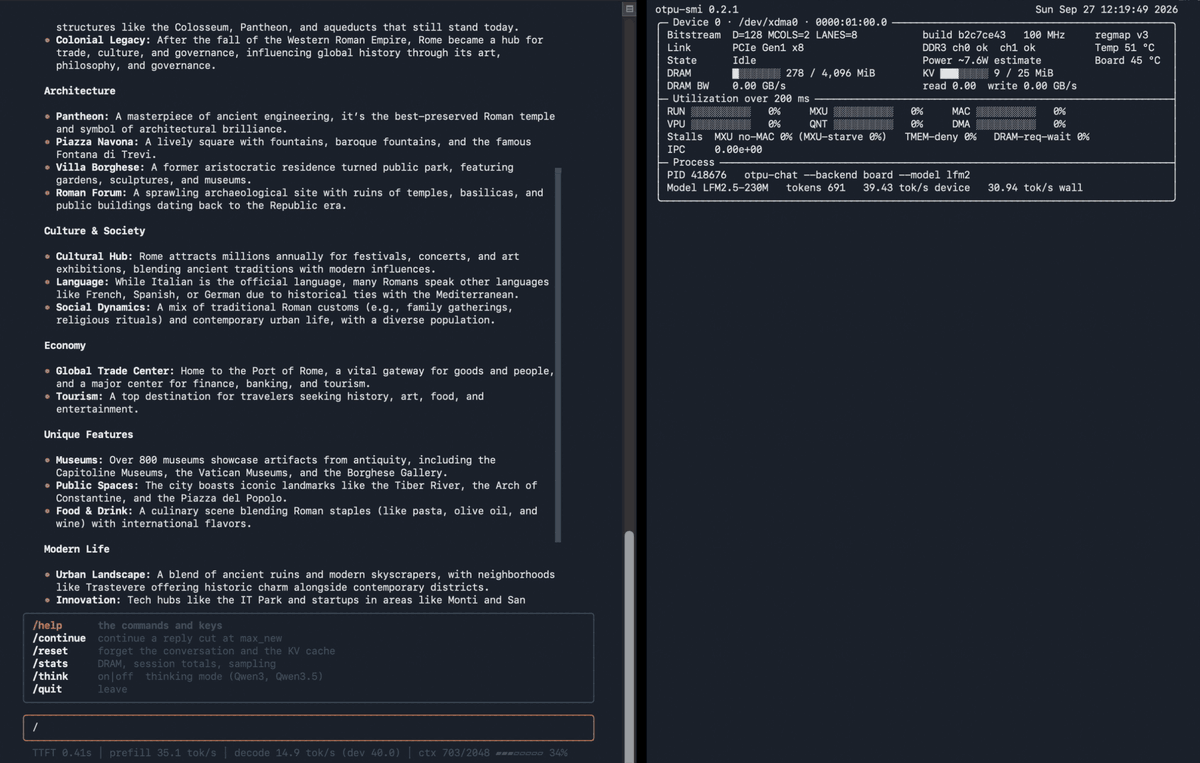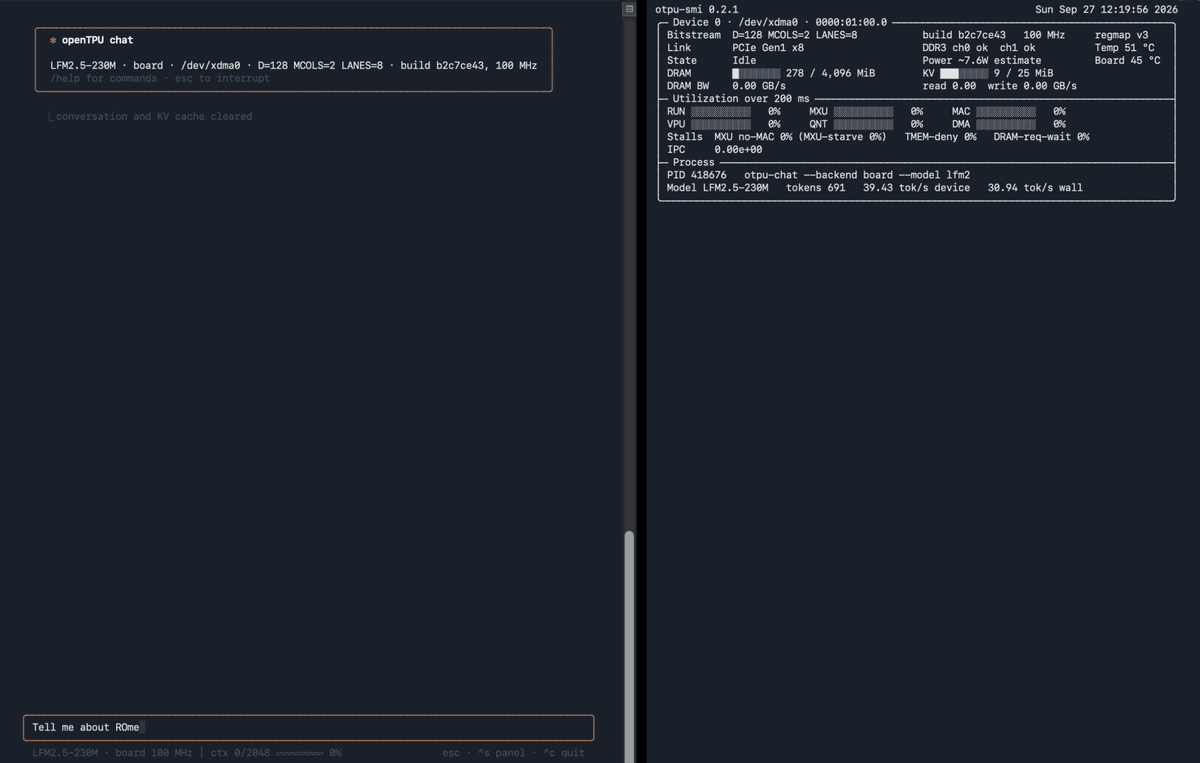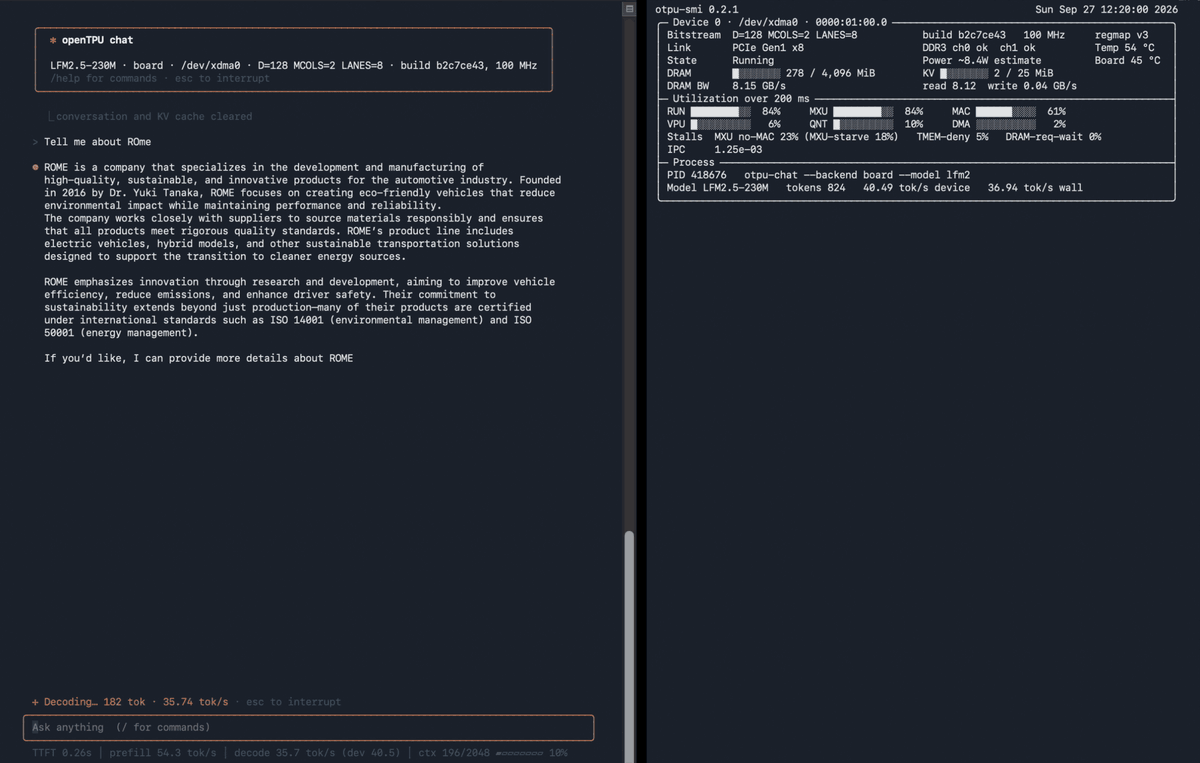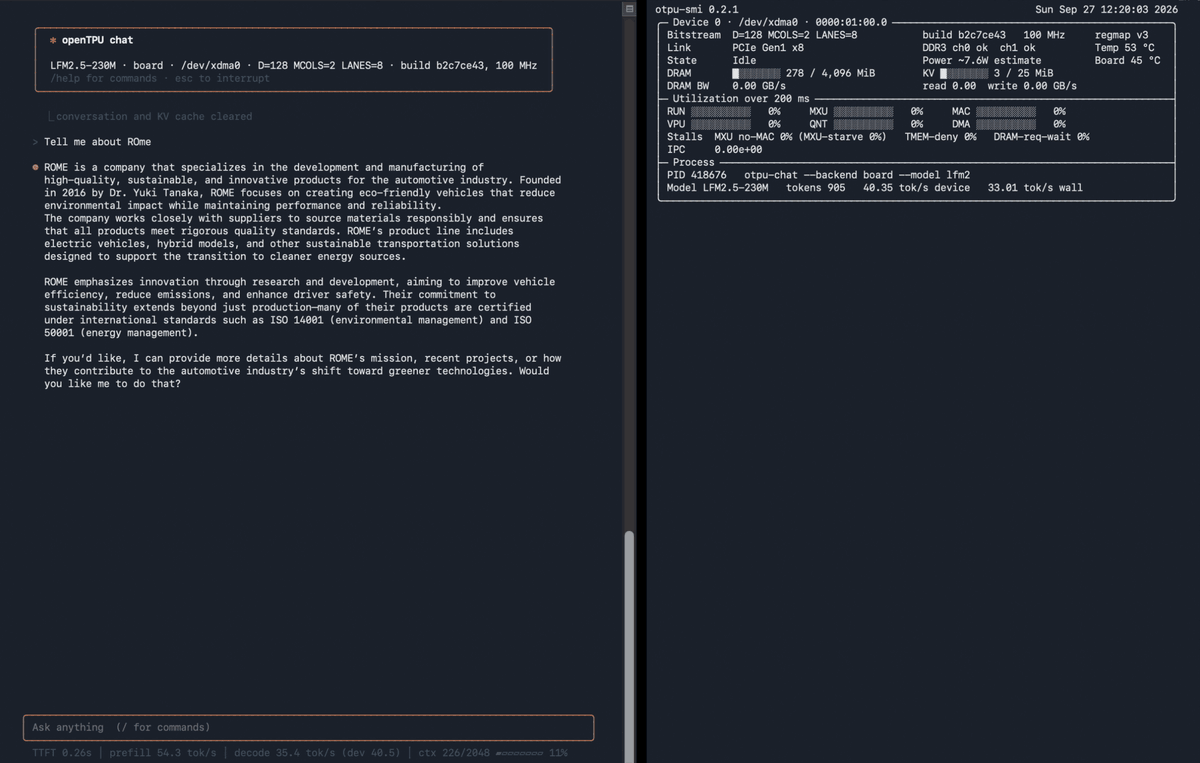
openTPU
753FeSens/openTPU · VerilogopenTPU is an open-source AI accelerator whose hardware design, instruction set, simulator, compiler and profiler were all built by AI agents, and it runs real LLMs like Qwen3 and LFM2.5 on an FPGA PCIe card.
- 30

GLM-5.3-Flash-EXL3-2x-DGX-Sparks
734MiaAI-Lab/GLM-5.3-Flash-EXL3-2x-DGX-Sparks · PythonA deployment recipe and Docker image that serves the GLM-5.3-Flash model as an OpenAI-compatible vLLM endpoint across 2-4 NVIDIA DGX Spark (GB10) kits, using a custom EXL3/TR3 4-bit quantization of the weights.
- 31
StartLux-Decision
552StartLuxLabs/StartLux-Decision · PythonStartLux-Decision is a family of typed decision models (five dense sizes from 0.8B to 27B plus a 35B-A3B mixture-of-experts) that answer a question with a probability for each option instead of generating text.
- 32

slotstream
474carloslfu/slotstream · SwiftSlotstream lets you run a 105 GB AI model (Qwen3.8-Flash-Next, a 125B-parameter mixture-of-experts model) on Macs with only 16 to 64 GB of RAM, by streaming most of the model from SSD and caching the busiest experts in memory.
- 33
Qwen3.8-27B-SGLang-DGX-Spark
474MiaAI-Lab/Qwen3.8-27B-SGLang-DGX-Spark · ShellA set of opinionated, ready-to-run Docker scripts that serve the Qwen3.8-27B model through SGLang on an NVIDIA DGX Spark (GB10, aarch64), offering three swap-in speculative-decoding modes — EAGLE/MTP, DSpark, and DFlash2 — each tuned with on-device measurements rather than guesses.
- 34

qwen3.8-Flash-DGX
453blazux/qwen3.8-Flash-DGX · PythonA recipe (scripts plus a patched Docker image) for serving the ~176B-parameter Qwen3.8-Flash-Next model with vLLM on a single NVIDIA DGX Spark (GB10). It solves the problem that the 126 GiB NVFP4 checkpoint doesn't fit next to a usable KV cache in the Spark's 128 GB unified memory, by streaming a 48 GiB lookup table from NVMe via mmap instead of keeping it resident.
- 35
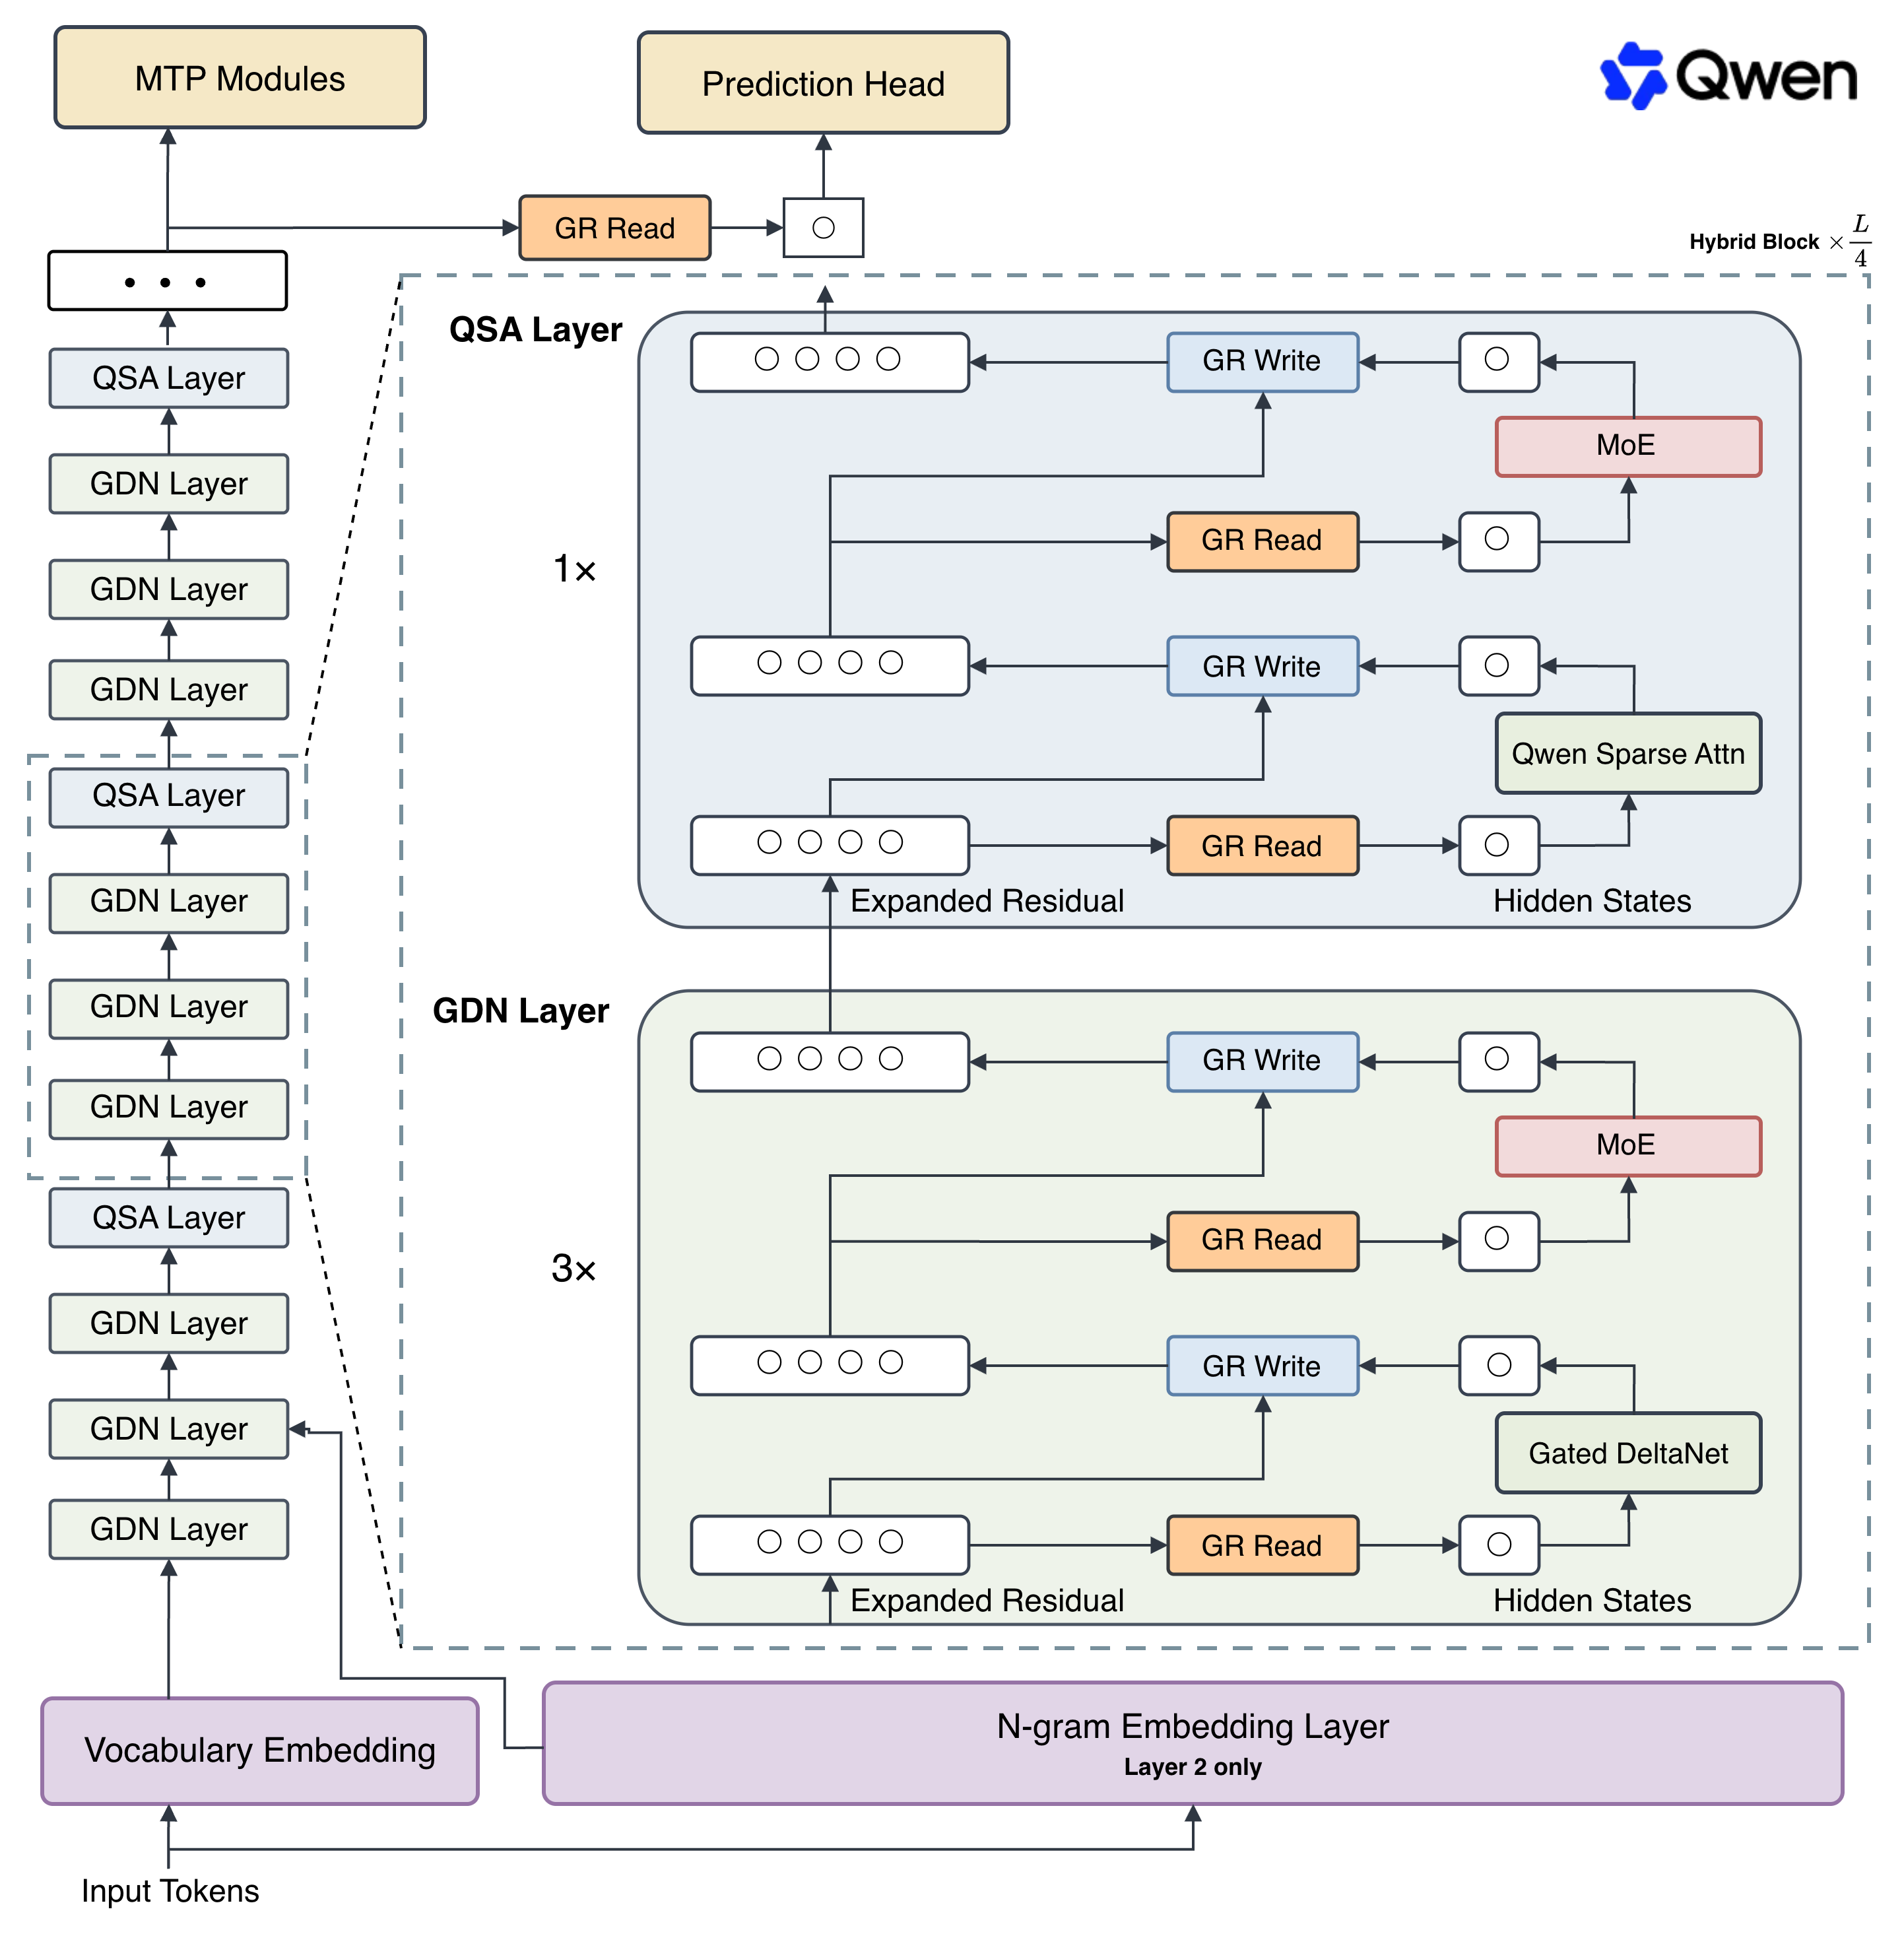
Qwen3.8-Flash-Next
433QwenLM/Qwen3.8-Flash-NextQwen3.8-Flash-Next is an open-weight multimodal Mixture-of-Experts foundation model from Alibaba's Qwen Team, also serving as an early preview of the architecture Alibaba plans to use for the upcoming Qwen4 model family.
- 36
jeeves
425PostHog/jeeves · PythonJeeves is a reasoning-enhanced 'Jev-like' decision model built on Qwen3.5-9B with LoRA. It thinks through a reasoning chain before giving calibrated yes/no, multiple-choice, or rating answers, and ships with a diffusion drafter for faster inference.
- 37
Hy4-preview
395Tencent-Hunyuan/Hy4-preview · PythonHy4 preview is Tencent Hunyuan's newest open-source large language model, a 770B-parameter Mixture-of-Experts model (49B active per token) built for coding, office/data analysis, game development, and scientific research tasks.
- 38
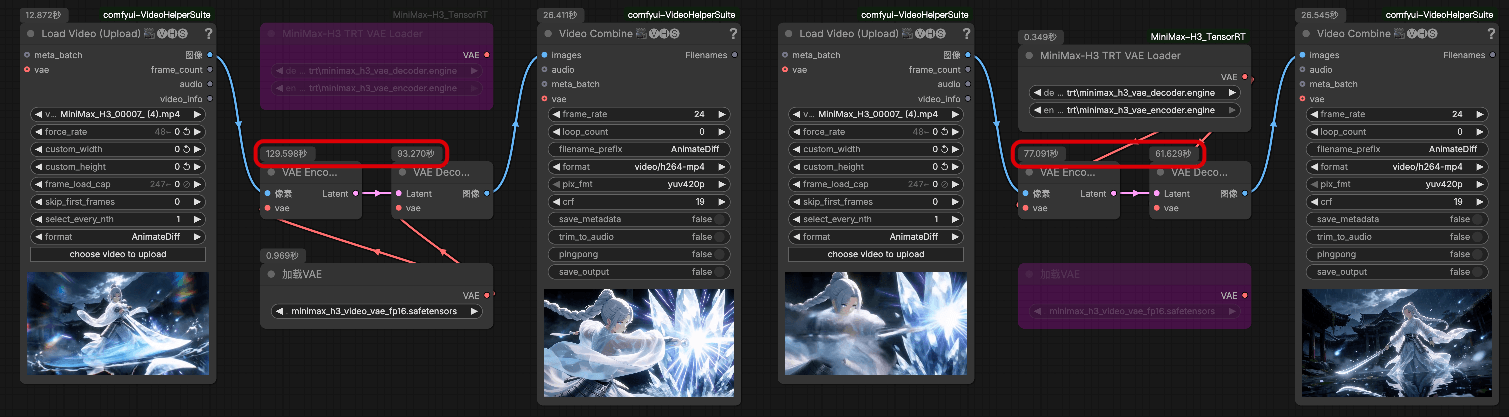
ComfyUI-H3VAE_TRT
254lihaoyun6/ComfyUI-H3VAE_TRT · PythonA ComfyUI custom node that runs the MiniMax-H3 VAE as a compiled TensorRT engine instead of the regular one, making it up to 1.7x faster.
- 39

infinite-livestream
240reactor-team/infinite-livestream · PythonAn end-to-end, chat-driven, never-ending AI video broadcast: viewers type !prompt in Twitch or YouTube chat, an LLM expands the idea into a styled scene, the FastH3 model renders it as a 768p clip with synced audio, and it goes out continuously over RTMP.
- 40
InstinctFlash
200General-Instinct/InstinctFlash · PythonInstinctFlash is a high-performance serving runtime for robotics foundation models - it loads checkpoints like GR00T, Cosmos3, pi0.5, LingBot-VA/VLA and DreamZero, applies acceleration (FP8, fused Triton kernels, caching) and serves them over Python or WebSocket, reporting up to 33.78x speedup on Jetson Thor.
- 41
nari-qwen3-tts
187nari-labs/nari-qwen3-tts · PythonNari Qwen3-TTS is a high-performance serving implementation of the Qwen3-TTS 1.7B CustomVoice model, built to run on a single NVIDIA H100 and exposed as an API with streaming and non-streaming speech generation.
- 42

twinspark
176raullenchai/twinspark · ShellThis is a production-grade deployment recipe for running DeepSeek-V4-Flash-0731 (a 284B-parameter MoE model) across two networked NVIDIA DGX Spark machines, using a self-healing 2-node vLLM cluster tuned for speculative decoding.
- 43

gemma4.c
173qmog-ai/gemma4.c · Cgemma4.c is a CPU inference runtime for Google's Gemma 4 E2B model written in about 700 lines of pure C, built to show how LLM inference actually works under the hood.
- 44

v100-skinny
172dnv2003/v100-skinny · Pythonv100-skinny provides hand-written NVFP4 (W4A16) and FP8 (W8A16) CUDA kernels that let four Tesla V100-SXM2-16GB GPUs run Qwen3.8-27B's published mixed NVFP4/FP8 weights directly, serving the model through an OpenAI-compatible API.
- 45
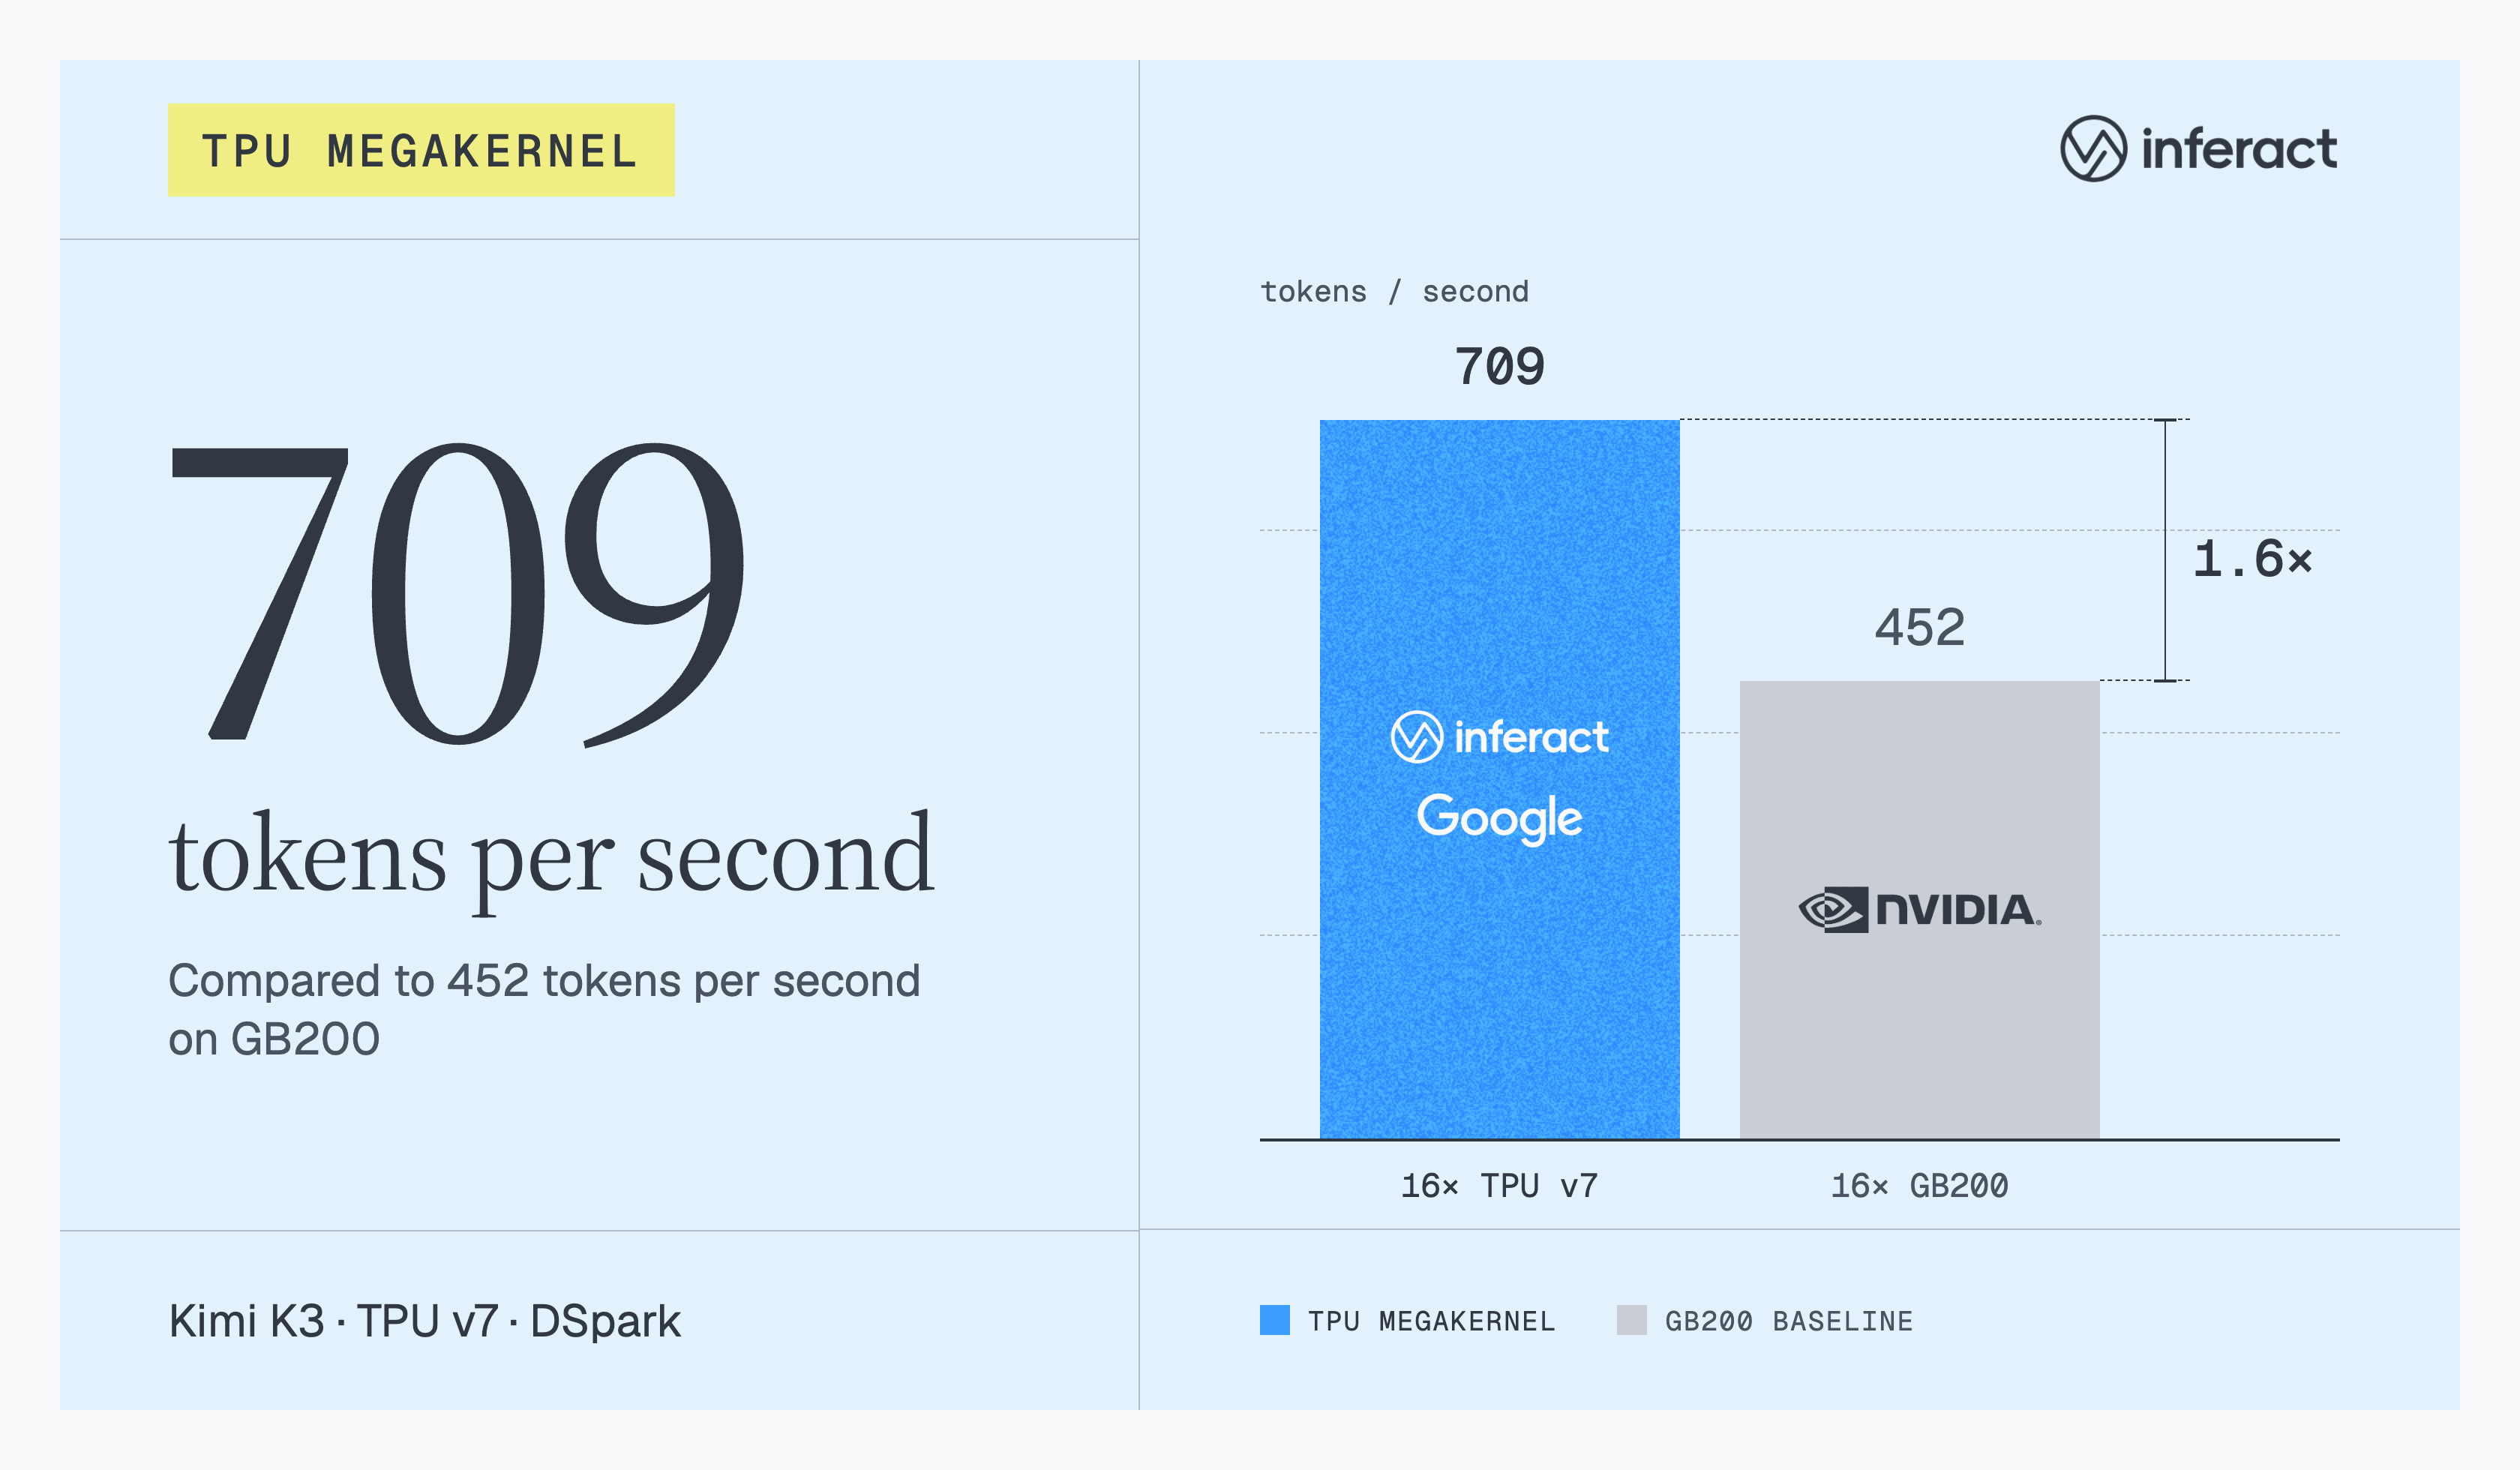
tpu-megakernels
162Inferact/tpu-megakernels · PythonA companion research repo with fused 'megakernel' decode implementations for two models on Google TPUs: Kimi K3 with DSpark speculative decoding, and Qwen3.8-27B with DFlash2 speculative decoding, written to accompany the blog post '700 TPS on Kimi K3: A Case for TPU Megakernels'.
Related topics
Often tagged together