Topics / #cuda-kernels
Cuda-kernels projects on GitHub
Custom CUDA kernel development for GPU acceleration and performance study.
As of , the most-starred Cuda-kernels projects on GitHub are flash-attention (25.2K stars), cupy (12.4K stars) and taskflow (12.2K stars). GitHub.Locker tracks 9 Cuda-kernels repositories with 81.5K stars combined. The fastest-growing on October 17 was VisionHOPE, with +98 stars in a day.
Hot right now
Most stars gained in a day · Oct 17
 +98
VisionHOPE
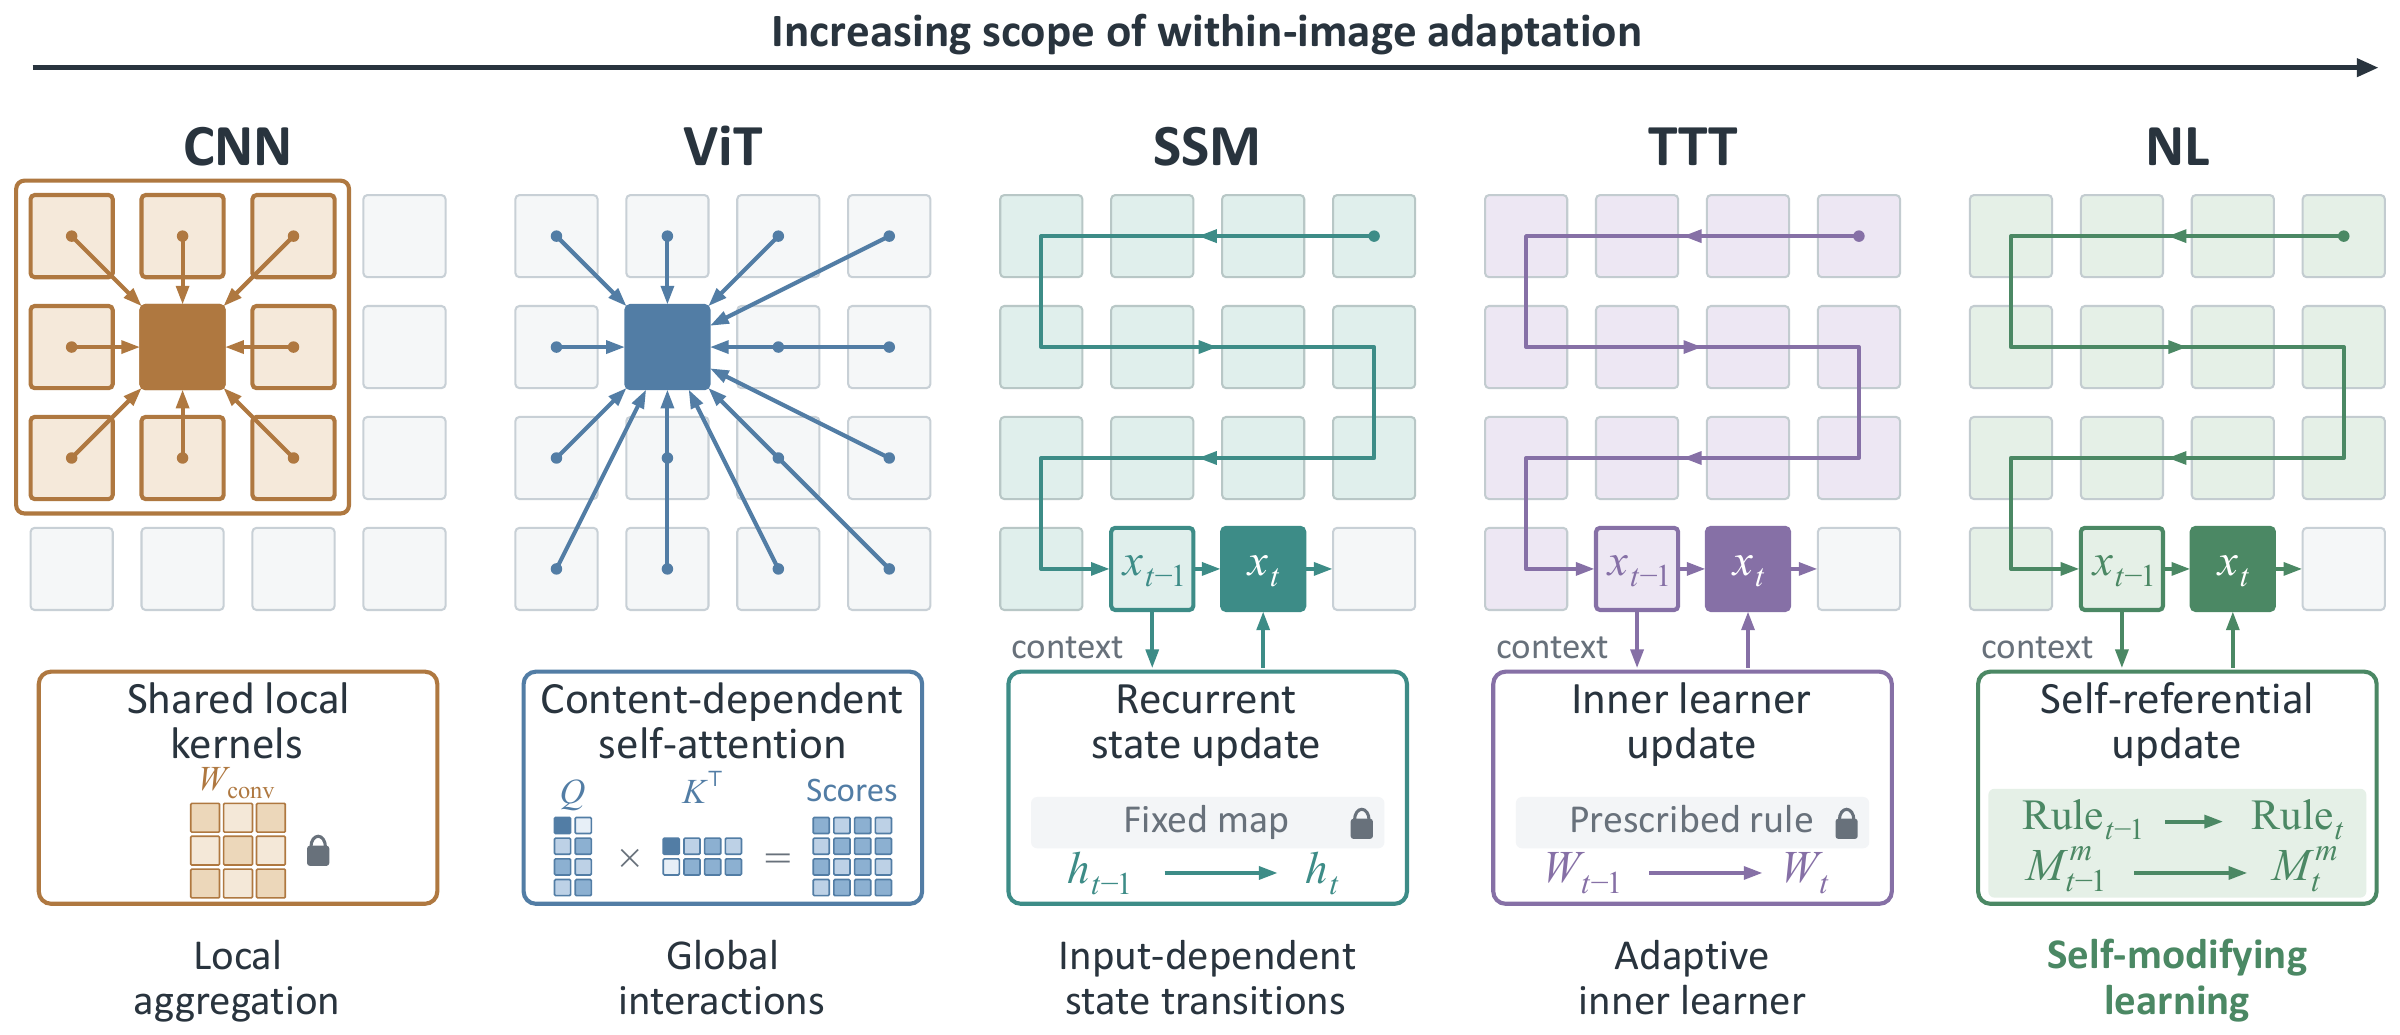
PSRben/VisionHOPE · ★ 1.3KVisionHOPE is the official PyTorch implementation of a visual backbone built on self-referential nested learning (SRNL), supporting ImageNet-1K classification, COCO detection/instance segmentation, and ADE20K semantic segmentation.
 +86
StartLux-Decision
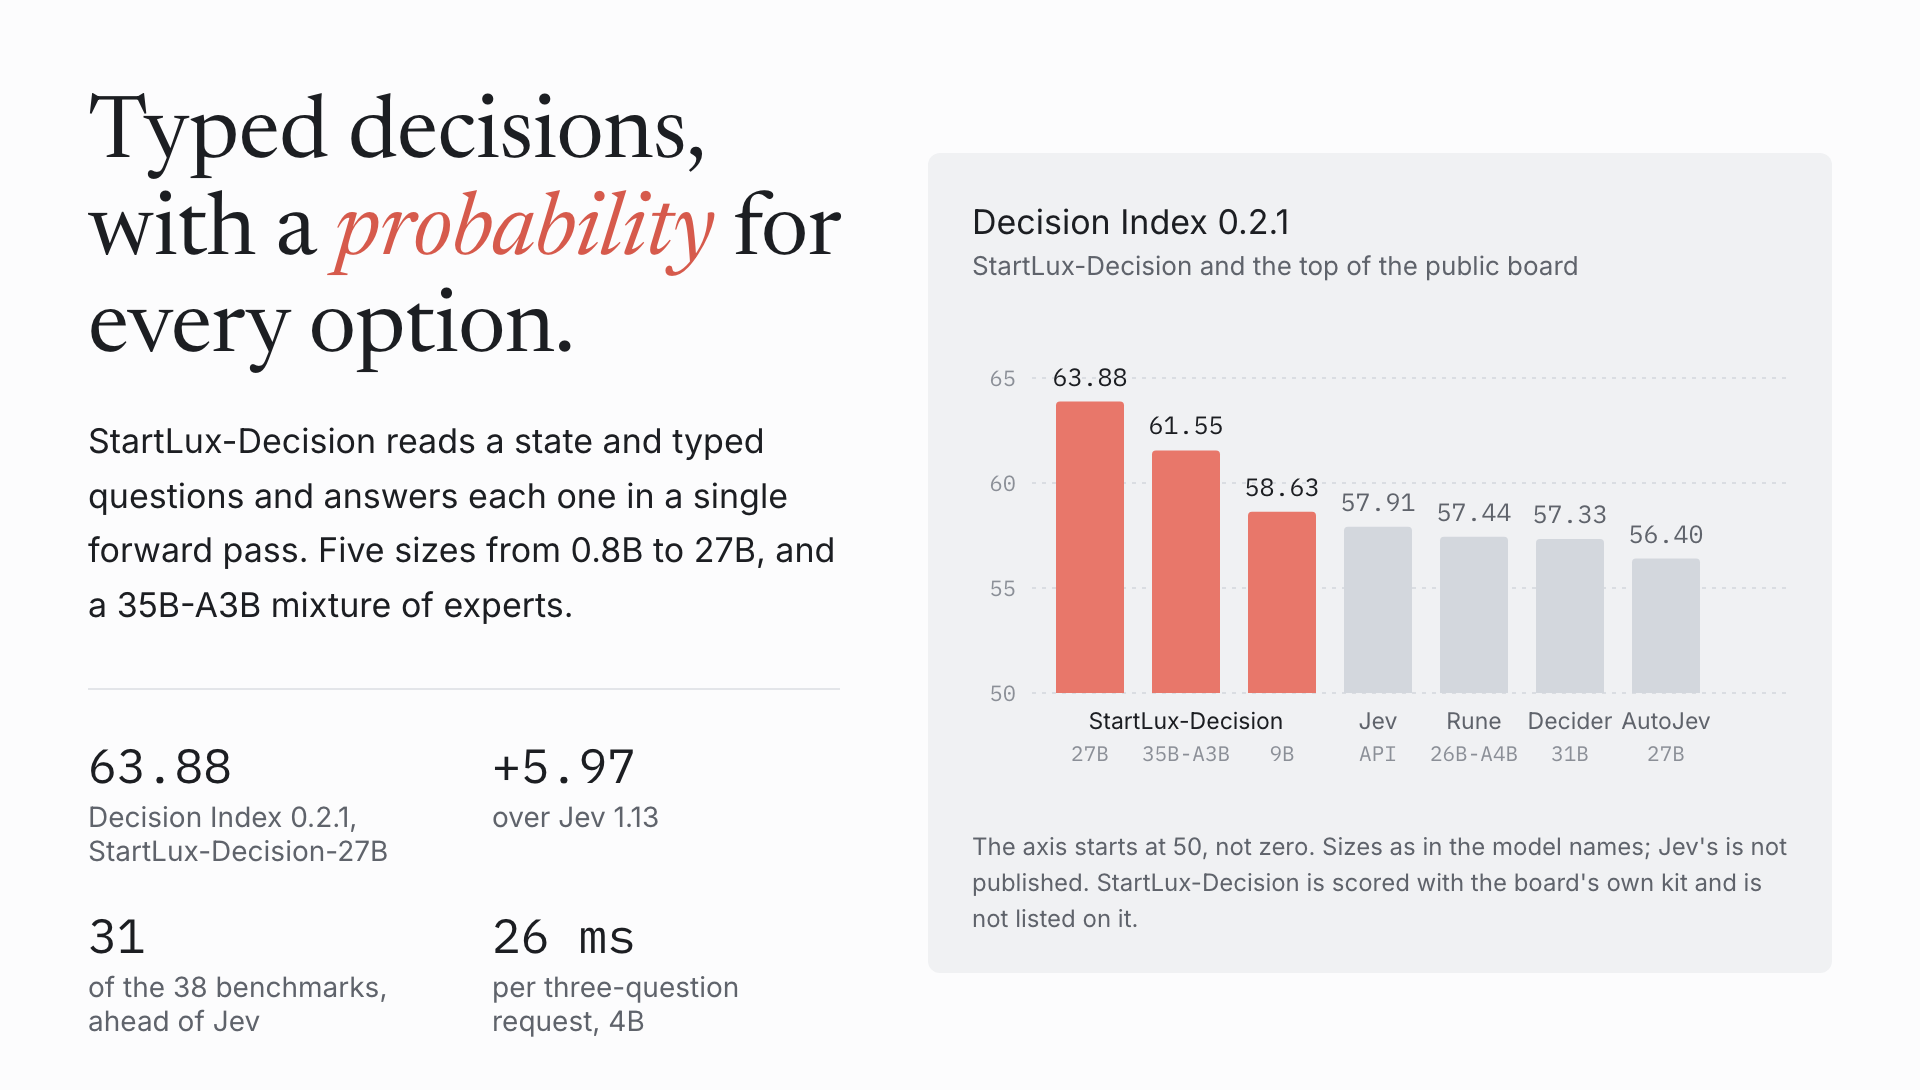
StartLuxLabs/StartLux-Decision · ★ 648StartLux-Decision is a family of typed decision models (five dense sizes from 0.8B to 27B plus a 35B-A3B mixture-of-experts) that answer a question with a probability for each option instead of generating text.
 +7
tilelang
tile-ai/tilelang · ★ 8.6KTileLang (tile-lang) is a domain-specific language for writing high-performance GPU/CPU/NPU kernels like GEMM, Dequant GEMM, FlashAttention, and LinearAttention, using Pythonic syntax backed by a TVM-based compiler.
 +6
flash-attention
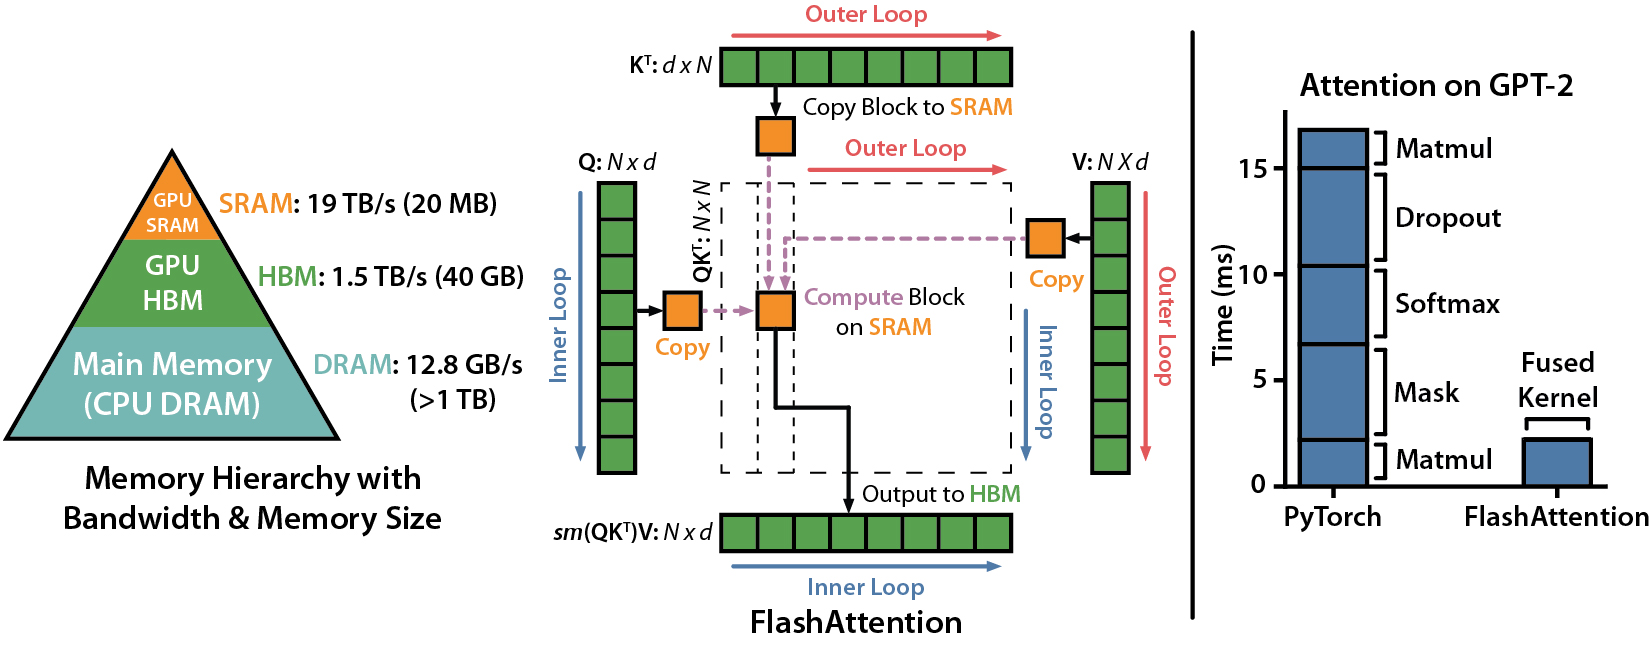
Dao-AILab/flash-attention · ★ 25.2KThe official implementation of FlashAttention and FlashAttention-2 — GPU kernels that compute exact attention faster and with less memory than standard PyTorch attention.
The all-time top
9 projects · by stars
- 25.2K#1 · Dao-AILab/flash-attention
flash-attention
The official implementation of FlashAttention and FlashAttention-2 — GPU kernels that compute exact attention faster and with less memory than standard PyTorch attention.
- 12.4K
 #2 · cupy/cupy
cupy
CuPy is a NumPy/SciPy-compatible array library for GPU-accelerated computing with Python: you write ordinary Python array code, and it executes on NVIDIA or AMD GPUs.
- 12.2K
 #3 · taskflow/taskflow
taskflow
Taskflow is a C++ library that helps you write high-performance task-parallel programs with high programming productivity, letting you build and run graphs of dependent tasks across CPU threads and GPUs.
- 4
LeetCUDA
12.1Kxlite-dev/LeetCUDA · CudaLeetCUDA is an open-source book of CUDA learning notes for beginners, paired with a library of 200+ hand-written CUDA kernels (elementwise ops, HGEMM, Flash-Attention, etc.) and 100+ CUDA/LLM blog posts.
- 5

DeepGEMM
9Kdeepseek-ai/DeepGEMM · CudaDeepGEMM is a unified CUDA kernel library that provides high-performance tensor core GEMM operations (FP8, FP4, BF16), fused MoE kernels, and attention-indexer kernels used in large language models such as DeepSeek.
- 6
tilelang
8.6Ktile-ai/tilelang · PythonTileLang (tile-lang) is a domain-specific language for writing high-performance GPU/CPU/NPU kernels like GEMM, Dequant GEMM, FlashAttention, and LinearAttention, using Pythonic syntax backed by a TVM-based compiler.
- 7
VisionHOPE
1.3KPSRben/VisionHOPE · PythonVisionHOPE is the official PyTorch implementation of a visual backbone built on self-referential nested learning (SRNL), supporting ImageNet-1K classification, COCO detection/instance segmentation, and ADE20K semantic segmentation.
- 8
StartLux-Decision
648StartLuxLabs/StartLux-Decision · PythonStartLux-Decision is a family of typed decision models (five dense sizes from 0.8B to 27B plus a 35B-A3B mixture-of-experts) that answer a question with a probability for each option instead of generating text.
- 9

v100-skinny
174dnv2003/v100-skinny · Pythonv100-skinny provides hand-written NVFP4 (W4A16) and FP8 (W8A16) CUDA kernels that let four Tesla V100-SXM2-16GB GPUs run Qwen3.8-27B's published mixed NVFP4/FP8 weights directly, serving the model through an OpenAI-compatible API.
Related topics
Often tagged together
- cuda395
- gpu788
- nvidia327
- linux4,181
- machine-learning915
- python2,396
- deep-learning736
- gpu-programming28
- inference326
- pytorch419
- benchmark430
- high-performance141
- performance633
- cpp383
- gpu-acceleration144
- library1,587
- llm1,483
- mit3,311
- open-source5,666
- research764
- transformer212
- artificial-intelligence267
- llm-inference118
- quantization183