
jeff README

The project's README from github.com/firelex/jeff. As one markdown file: README.md.

Jeff

Fine-tunes of Qwen3.5 and Gemma 4 for zero-shot classification: small, fast decision models you slot into your code, with the same request format as Jev. You describe a situation and list the options in plain words; Jeff returns a calibrated probability for each option from a single forward pass. No generated text, no parsing: about 22 ms per decision on an RTX PRO 6000 and 28 ms on an Apple M4 Max (MLX).

Zero-shot means the options can be anything: support queues, user intents, moderation labels, voice commands, game moves. Your categories don't need to appear in the training data; you describe them, and Jeff picks.

What it is, and what it isn't. These are very small models. They make extremely fast, well-calibrated judgement calls between options, and they slot easily into your local code. On benchmarks they approach, and sometimes beat, Jev; but at this size their reasoning won't match Jev's, which runs on a much larger model. If zero-shot accuracy isn't good enough for your purposes, a short fine-tune on your own examples takes you much further: our voice-navigation fine-tune moved held-out accuracy from 31.7% to 95.8% in under half an hour on one GPU.

Built entirely on local hardware. Training on one RTX PRO 6000 workstation GPU (the 0.8B trains in about 2 hours, the 2B in about 3.5), all synthetic training data written by an open model (Qwen3.8-Flash-Next) on two DGX Sparks, testing on a MacBook. No cloud GPUs, and no closed-model output in the training data; a closed model was used only to spot-check the quality of a sample of the synthetic data.

Independent project. Jeff uses the same request format as Jev, but it is not affiliated with or endorsed by TypeSafe, the makers of Jev. Our training code starts from the open-source AutoJev recipe.

Models on Hugging Face: Jeff-Qwen3.5-0.8B · Jeff-Qwen3.5-2B · Jeff-Gemma4-E2B

Quick start

uv sync
uv run hf download mstrasser/Jeff-Qwen3.5-0.8B --local-dir checkpoints/jeff-0.8b

# NVIDIA GPU or CPU (PyTorch)
JEFF_CHECKPOINT=checkpoints/jeff-0.8b PORT=8765 uv run jeff-serve
# Apple silicon (MLX, much faster on a Mac; Qwen models only)
uv sync --extra mac
JEFF_BACKEND=mlx JEFF_CHECKPOINT=checkpoints/jeff-0.8b PORT=8765 uv run jeff-serve
curl -s localhost:8765/v1/systemone -H 'content-type: application/json' -d '{
  "model": "jeff-latest",
  "state": "Refund request: the customer says the parcel arrived crushed and wants their money back.",
  "questions": {
    "route": {"type": "choice", "instructions": "Which team should handle this?",
              "criteria": {"1": "Refunds and payments", "2": "Damaged or lost parcels", "3": "Account and login problems"}},
    "angry": {"type": "noul", "instructions": "Is the customer angry?"}
  }
}'

Each answer has a probability per option, the chosen option and a confidence. Three question types: choice (pick one of up to 255 options), noul (yes/no, returned as a probability) and score (a point on a scale you describe). Several independent questions in one request are answered together.

Benchmarks

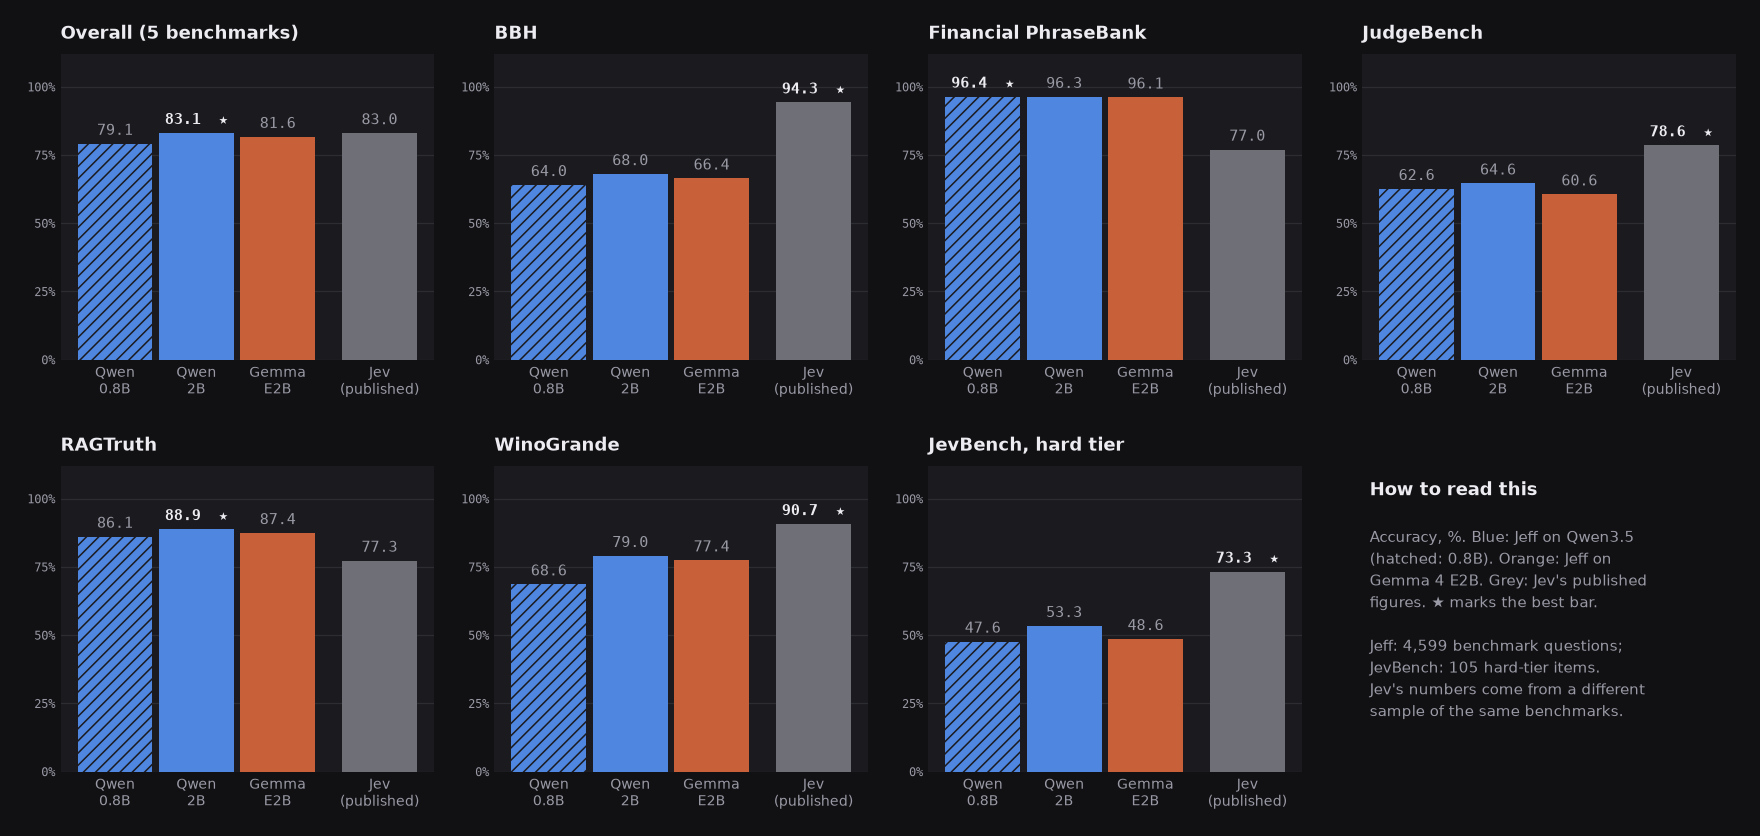
4,599 questions from five public benchmarks, plus JevBench's public hard tier (105 items, scored separately):

Accuracy of Jeff-Qwen3.5-0.8B, Jeff-Qwen3.5-2B and Jeff-Gemma4-E2B against Jev's published figures, per benchmark

Benchmark Qwen3.5-0.8B untrained Jeff-Qwen3.5-0.8B Qwen3.5-2B untrained Jeff-Qwen3.5-2B Gemma 4 E2B untrained Jeff-Gemma4-E2B Jev (published) AutoJev-27B (published)
Overall (5 benchmarks) 45.3 79.1 46.5 83.1 62.5 81.6 83.0 84.9
BBH 39.5 64.0 46.0 68.0 51.3 66.4 94.3 82.8
Financial PhraseBank 36.0 96.4 53.4 96.3 86.0 96.1 77.0 84.2
JudgeBench 56.6 62.6 57.4 64.6 46.9 60.6 78.6 78.9
RAGTruth 49.1 86.1 35.9 88.9 63.8 87.4 77.3 88.9
WinoGrande 49.2 68.6 52.2 79.0 51.0 77.4 90.7 83.3
JevBench hard (separate) 36.2 47.6 45.7 53.3 41.0 48.6 73.3 70.3

Bold: the winner of Jeff against Jev in each row. Bold italic: AutoJev-27B where it is the best of all models in the row (on RAGTruth, tied with Jeff-Qwen3.5-2B); it is shown for reference, since the head-to-head comparison is with Jev. The published Jev and AutoJev figures were measured on a different sample of the same benchmarks. Jeff's overall score comes from classification and grounding, where it matches or beats the large models; on the reasoning-heavy benchmarks (BBH, JudgeBench, JevBench) it stays well below them, as you would expect at this size.

Games: a zero-shot test

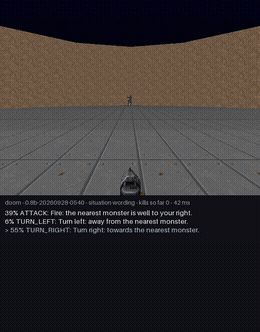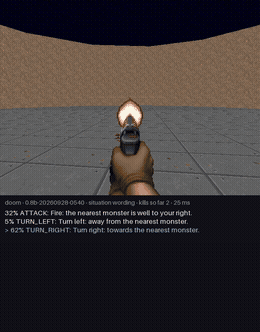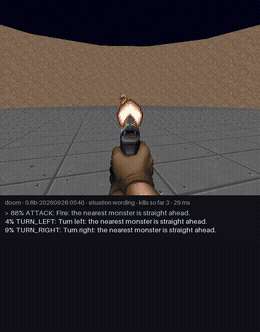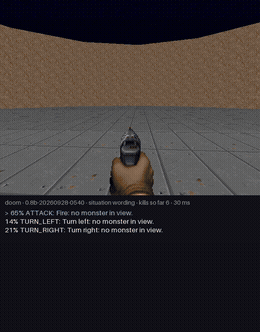
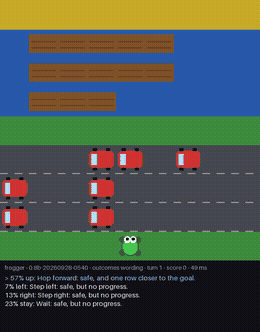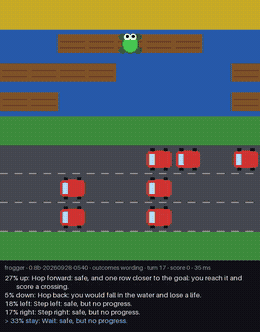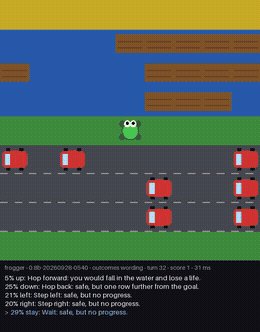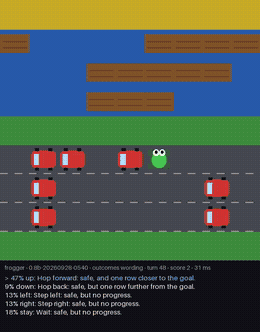
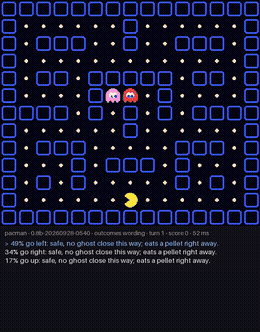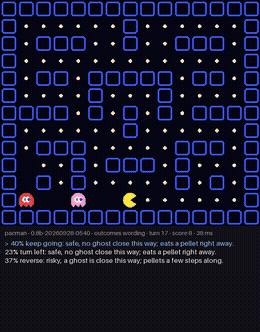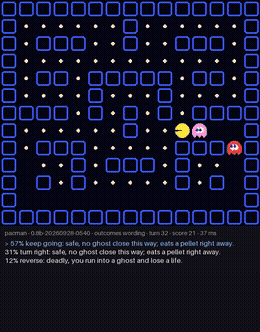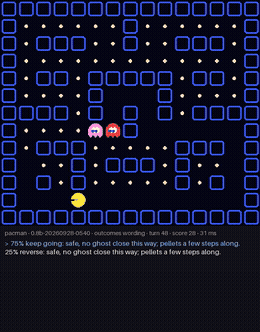
To test zero-shot performance on tasks unlike anything in the benchmarks, we had Jeff play three games. Games aren't the ideal zero-shot test, since a game's state isn't typical unstructured data; but they are a common, and fun, way to test a System 1 model. Each turn, the code describes the situation and the legal moves in words, and the model picks one. The options state what each move leads to (Frogger: "you would be hit by a car and lose a life"; Doom: "the nearest monster is a little to your left"), but never which move is right. Each result is 20 episodes, seed 1234; ▶ opens a video of the run's first episode.

Jeff-Qwen3.5-0.8B playing, zero-shot (the bold row in the table below; click a clip for the full video):

Jeff-Qwen3.5-0.8B playing Doom
Doom
Jeff-Qwen3.5-0.8B playing Frogger
Frogger
Jeff-Qwen3.5-0.8B playing Pac-Man
Pac-Man
Model Doom, kills (monster's direction in words) Frogger, crossings (consequences) Pac-Man, pellets of 98 (consequences)
Random moves −0.05 0 11.2
Hand-coded rule bot 6.55 ▶ 10.25 ▶ 94.1 ▶
Qwen3.5-0.8B, untrained 5.0 ▶ 1.0 ▶ 25.8 ▶
Jeff-Qwen3.5-0.8B 6.55 ▶ 10.3 ▶ 57.0 ▶
Qwen3.5-2B, untrained 0.55 ▶ 0.05 ▶ 72.1 ▶
Jeff-Qwen3.5-2B −0.9 ▶ 6.0 ▶ 41.2 ▶
Gemma 4 E2B, untrained −0.55 ▶ 0 ▶ 3.2 ▶
Jeff-Gemma4-E2B 0.55 ▶ 0.15 ▶ 53.2 ▶
Jev (published, Doom) 6.55, told the aiming rule; −0.60 without it — —

Jeff-0.8B decides in 29–49 ms per move on an M4 Max; Jev's published Doom run took 212 ms per call over its API. The two times were not measured on the same hardware. To play them yourself:

uv sync --extra games
uv run python -m jeff.games --game doom --player jeff --criteria situation --url http://127.0.0.1:8765 --video --out runs/games/doom.json
uv run python -m jeff.games --game frogger --player jeff --criteria outcomes --url http://127.0.0.1:8765 --out runs/games/frogger.json
uv run python -m jeff.games --game pacman --player rule --out runs/games/pacman-rule.json

Speed and size

Median time per decision over the same 200 benchmark questions (about 200 input tokens each), one question at a time, from raw text to probabilities:

Model Parameters Weights (16-bit) NVIDIA RTX PRO 6000 Apple M4 Max (MLX) CPU (32 threads)
Jeff-Qwen3.5-0.8B 0.8B 1.7 GB 22 ms 28 ms 463 ms
Jeff-Qwen3.5-2B 2B 4.2 GB 24 ms 60 ms 708 ms
Jeff-Gemma4-E2B 2B effective (4.6B stored) 9.3 GB 29 ms — (MLX runs Qwen only) 1.0 s
AutoJev-27B 27B ~54 GB not published — —
Jev not disclosed API only 114–212 ms per call in published Doom runs, including the network

Using it well

Train your own

uv run autojev-mix ...          # build the training set (public data, synthetic data, leak filter)
scripts/train.sh RUN data/mix/public.jsonl data/mix 5e-6 40 Qwen/Qwen3.5-0.8B <revision> --epochs 1
uv run autojev-evaluate --data data/panel.jsonl --local --checkpoint checkpoints/RUN/selected --output runs/eval/RUN.json

The full pipeline (synthetic data from a local teacher, leak filter, learning-rate sweeps, dashboard) is described in scripts/train_all.sh, and every training source with its licence in docs/data-sources.md. Training recipe: full-weight fine-tuning, one epoch, batches of 256, cross-entropy over the option letters, then one fitted temperature for calibration; checkpoints are chosen on a development set, never on the benchmark panel. At least half of each training family follows the panel's layout conventions (formats only; no panel item is ever trained on).

Caveats

History

Jeff began as a fork of AutoJev by Denis Yarats (MIT licence), an open recipe that fine-tunes Qwen3.8-27B to return Jev-style decisions. We kept its core design (one forward pass per decision, a trained answer readout, a fitted temperature for calibration) and built on it: small students (0.8B and 2B Qwen, Gemma 4 E2B), a local synthetic-data pipeline with a leak filter, prompt layouts for domain fine-tunes, MLX serving on Apple silicon, game tests and a training dashboard. The original copyright notice is kept in LICENSE.

Licence

Code: MIT (including AutoJev's). Model weights: Apache 2.0. Doom harness adapted from jev-plays-doom (MIT). Training data: see the dataset card; each source keeps its licence and is listed in docs/data-sources.md. We release the weights and code, not the training data; some sources are share-alike (CC BY-SA).

jeff (firelex/jeff)

Searching Database…

1.5K ·GitHub
What is this?Jeff is a family of small (0.8B-2B parameter) open-weight models fine-tuned from Qwen3.5 and Gemma 4 that act as fast 'System 1' decision-makers: you describe a situation and a list of options in plain text, and Jeff returns a calibrated probability for each option from a single forward pass, with no generated text to parse.
Is this a hosted API like Jev, or something I run myself?Jeff is a set of open-weight models released on Hugging Face plus training and inference code that you run on your own hardware -- GPU, Apple Silicon via MLX, or CPU -- not a hosted API service.
How do I start using Jeff?Download one of the released checkpoints from Hugging Face (Jeff-Qwen3.5-0.8B, Jeff-Qwen3.5-2B, or Jeff-Gemma4-E2B) and send a request describing the situation plus up to 255 options; the response gives a probability per option, the chosen option, and a confidence.
What hardware do I need to run it?Any of three options work: an NVIDIA GPU like the RTX PRO 6000 (22-29ms per decision), an Apple Silicon Mac via MLX (28-60ms), or plain CPU with 32 threads (463ms-1s) -- no cloud GPU or API key is required.
Can Jeff handle multi-step reasoning like a bigger model?No -- Jeff is a classifier, not a planner: it picks between options you describe but cannot forecast or reason multi-step, and it stays well below large models like Jev on reasoning-heavy benchmarks such as BBH and JudgeBench.
How is Jeff different from Jev?Jeff is an independent, open-weight 0.8B-2B model you run locally with the same request format as Jev, while Jev is a much larger, closed model accessed over an API; Jeff approaches or beats Jev on classification/grounding benchmarks but falls behind on reasoning-heavy ones.
Can I fine-tune Jeff on my own examples?Yes -- a short fine-tune of about 11k examples, taking roughly half an hour on one GPU, moved a voice-navigation task from 31.7% to 95.8% held-out accuracy using the autojev-train command.
Why does the wording of the options matter so much?Jeff is very sensitive to phrasing: giving an option's consequence the same wording style as every other option measurably changed its decisions in testing, so consistent, descriptive option text matters more than clever option IDs.
Which model size should I pick?The 0.8B model is the recommended default for fast, reliable option-picking even though the 2B scores higher on some benchmarks -- the 2B turns out more cautious and performs worse in the game tests.
Creator
firelex
Size
8 MB
Stars
1.5K
Age
19d
Commits · 90 Days