Topics / #datasets
Datasets projects on GitHub
Public dataset collections and data tooling
As of , the most-starred Datasets projects on GitHub are awesome-public-datasets (79.6K stars), google-research (38.9K stars) and 500-AI-Machine-learning-Deep-learning-Computer-vision-NLP-Projects-with-code (37.3K stars). GitHub.Locker tracks 30 Datasets repositories with 574.1K stars combined. The fastest-growing on October 16 was awesome-public-datasets, with +33 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +33
awesome-public-datasets
awesomedata/awesome-public-datasets · ★ 79.6KA huge topic-centric list of high-quality open public datasets, organized by subject area like biology, chemistry, economics, and more.
 +21
UniMate
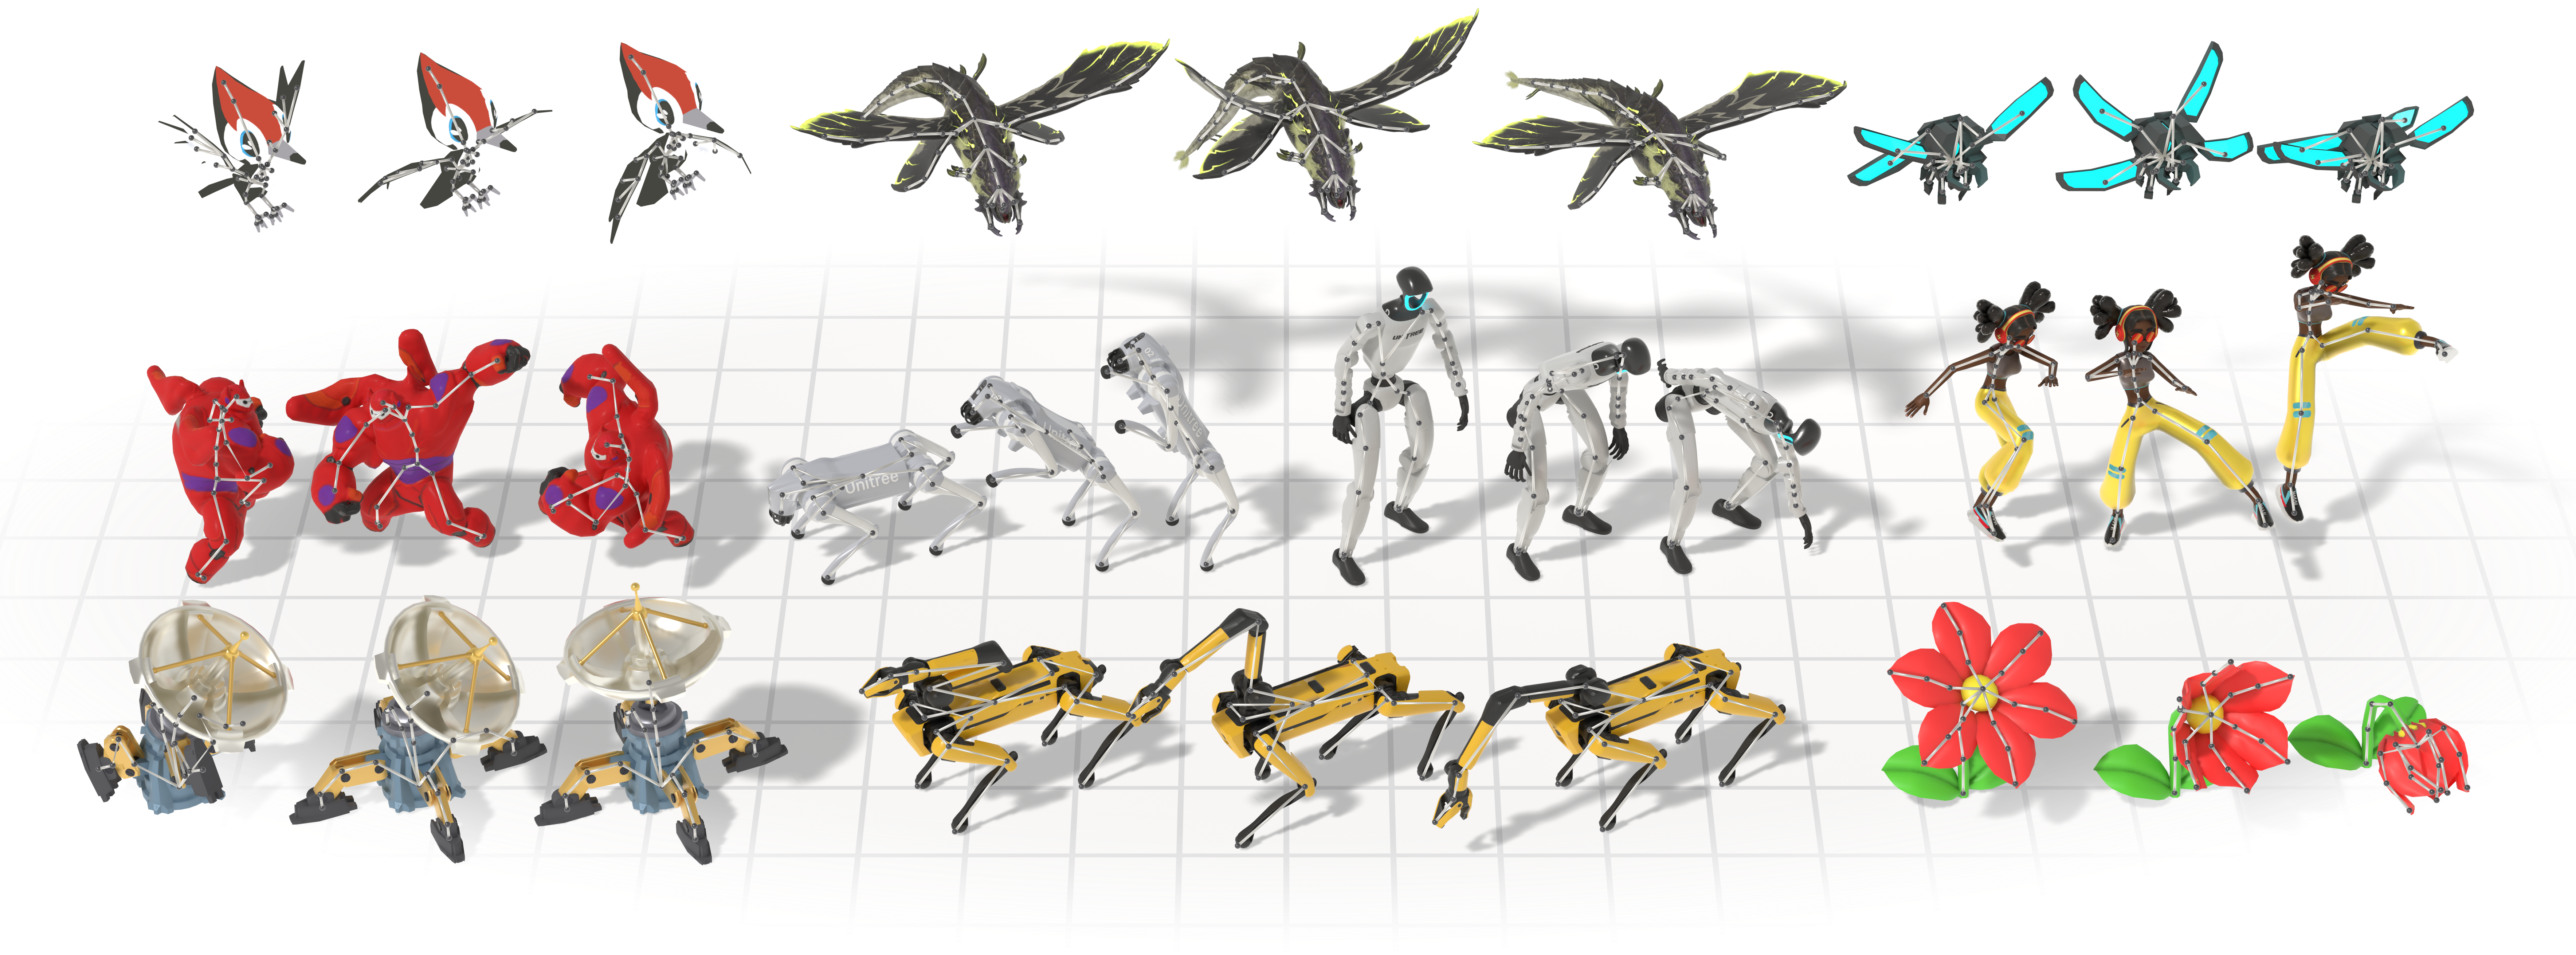
Friedrich-M/UniMate · ★ 1.8KUniMate is the official code release for a SIGGRAPH Asia 2026 paper: a single diffusion/flow-matching model that generates motion for very different skeleton types (bipedal, quadrupedal, avian, marine, insectoid, serpentine, and even rigid articulated objects) from a rigged 3D asset plus a text prompt, without retraining per skeleton.
 +20
500-AI-Machine-learning-Deep-learning-Computer-vision-NLP-Projects-with-code
ashishpatel26/500-AI-Machine-learning-Deep-learning-Computer-vision-NLP-Projects-with-code · ★ 37.3KIt is a curated index linking to over 500 external resources, repositories, and tutorials covering AI, machine learning, deep learning, computer vision, and NLP projects with code.
 +20
akshare
akfamily/akshare · ★ 23KAKShare is a free, open-source Python library that wraps a large set of financial data interfaces behind simple function calls - one line of code is enough to fetch a dataset.
The all-time top
30 projects · by stars
- 79.6K#1 · awesomedata/awesome-public-datasets
awesome-public-datasets
A huge topic-centric list of high-quality open public datasets, organized by subject area like biology, chemistry, economics, and more.
- 38.9K
 #2 · google-research/google-research
google-research
A giant monorepo where Google Research dumps the code released alongside its papers and projects - hundreds of independent folders covering different research efforts, not one cohesive product.
- 37.3K#3 · ashishpatel26/500-AI-Machine-learning-Deep-learning-Computer-vision-NLP-Projects-with-code
500-AI-Machine-learning-Deep-learning-Computer-vision-NLP-Projects-with-code
It is a curated index linking to over 500 external resources, repositories, and tutorials covering AI, machine learning, deep learning, computer vision, and NLP projects with code.
- 4

COVID-19
28.9KCSSEGISandData/COVID-19The COVID-19 data repository by Johns Hopkins University's Center for Systems Science and Engineering (CSSE) — the case data behind their widely used pandemic Visual Dashboard.
- 5

label-studio
28.5KHumanSignal/label-studio · TypeScriptLabel Studio is an open source data labeling and annotation tool: you label audio, text, images, videos, and time series in a browser UI and export the results in formats ready for ML training.
- 6

Faker
26.6Kfzaninotto/Faker · PHPFaker is a PHP library that generates fake data for you, such as names, addresses, phone numbers, emails, and more.
- 7
select2
25.9Kselect2/select2 · JavaScriptSelect2 is a jQuery-based replacement for standard HTML select boxes. It upgrades plain dropdowns with searching, remote data sets, and pagination of results.
- 8
akshare
23Kakfamily/akshare · PythonAKShare is a free, open-source Python library that wraps a large set of financial data interfaces behind simple function calls - one line of code is enough to fetch a dataset.
- 9

datasets
22.1Khuggingface/datasets · PythonA lightweight Python library from Hugging Face that gives one-line dataloaders for a huge catalog of ready-to-use public datasets on the HF Hub, plus fast, reproducible preprocessing for Hub and local data.
- 10
pytorch-deep-learning
19.2Kmrdbourke/pytorch-deep-learning · Jupyter NotebookFree course materials for the Zero to Mastery Learn PyTorch for Deep Learning course — a hands-on, code-first introduction to deep learning. The author jokes it's the second best place to learn PyTorch on the internet, after the official docs.
- 11

awesome-nlp
19.1Kkeon/awesome-nlpA curated list of resources dedicated to Natural Language Processing — research hubs, tutorials, courses, books, libraries, datasets, and task methods, collected as links with one-line descriptions.
- 12

vision
18Kpytorch/vision · PythonTorchvision is PyTorch's computer vision package: popular datasets, ready-made model architectures, and common image transformations for vision work.
- 13

tensor2tensor
17.5Ktensorflow/tensor2tensor · PythonA library of deep learning models and datasets from researchers and engineers on the Google Brain team, built to make deep learning more accessible and speed up ML research.
- 14
ms-swift
15.9Kmodelscope/ms-swift · Pythonms-swift is the ModelScope community's fine-tuning and deployment framework for LLMs and multimodal models, covering training, inference, evaluation, quantization and deployment in one pipeline.
- 15

cesium
15.8KCesiumGS/cesium · JavaScriptCesiumJS is an open-source JavaScript library for creating 3D globes and 2D maps in the browser without a plugin — WebGL provides hardware-accelerated graphics.
- 16

cosmos
13.7KOpenGenus/cosmos · C++Cosmos is OpenGenus's offline collection of algorithms and data structures — a contributor-driven code dataset with solutions in many languages, used in the Quark Search Engine, OpenGenus IQ and OpenGenus Visual Project.
- 17

awesome-iptv
12.7Kiptv-org/awesome-iptvThis is a curated list of resources related to IPTV: providers, EPG sources, players for every platform, supporting tools, and datasets, all organized in a single GitHub README.
- 18

Chinese-Word-Vectors
12.2KEmbedding/Chinese-Word-Vectors · PythonA collection of 100+ pre-trained Chinese word vectors (embeddings) trained with different representations, context features and corpora, plus the CA8 analogy dataset and an evaluation toolkit.
- 19
cosmos
12.1KNVIDIA/cosmos · Jupyter NotebookNVIDIA Cosmos is an open platform of world models, datasets, and tools for building Physical AI — systems that understand and generate the physical world for robots, autonomous vehicles, and smart infrastructure.
- 20

pix2code
12Ktonybeltramelli/pix2code · Pythonpix2code is a research project that trains a deep learning model to generate code from a single GUI screenshot, reporting over 77% accuracy for three different target platforms.
- 21

phoenix
11.9KArize-ai/phoenix · PythonArize Phoenix is an open-source AI observability platform for tracing, evaluating, and troubleshooting LLM applications, agents, and RAG pipelines.
- 22
cleanlab
11.7Kcleanlab/cleanlab · PythonCleanlab is an open-source Python library that automatically finds issues in ML datasets — label errors, outliers, duplicates — using your existing models, so that fixing the data trains better models.
- 23

datasette
11.5Ksimonw/datasette · PythonDatasette is an open-source multi-tool for exploring and publishing data: point it at a SQLite database and it turns the data into an interactive, browsable website with an accompanying JSON API.
- 24
deep_learning_object_detection
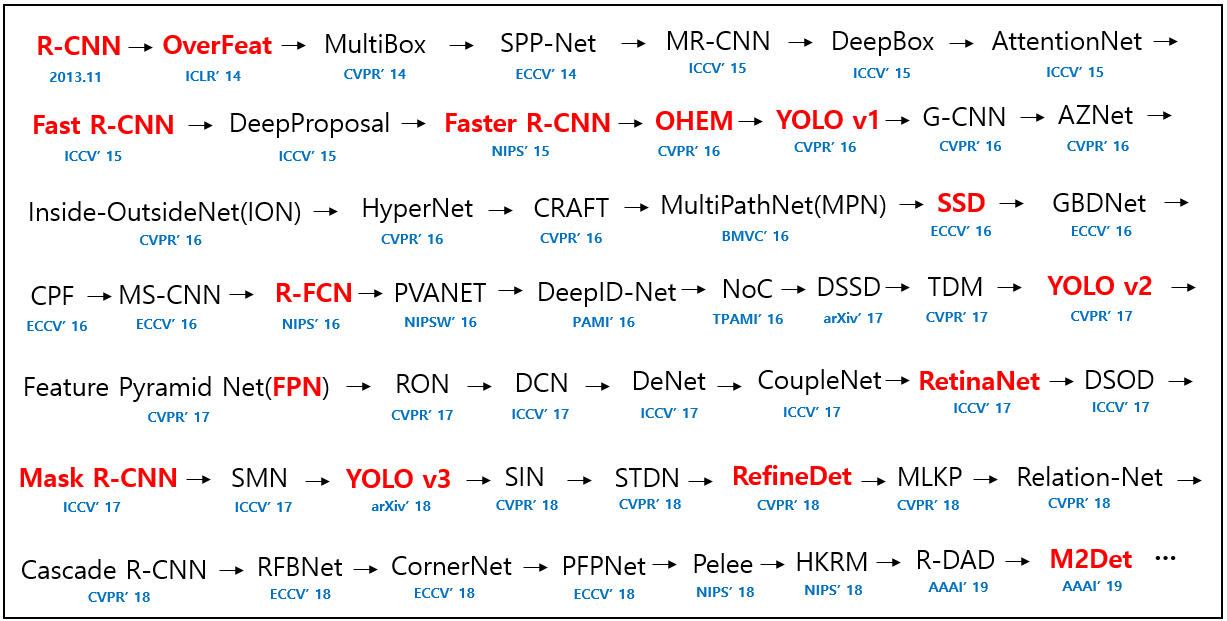
11.4Khoya012/deep_learning_object_detection · PythonA curated paper list of object detection using deep learning, covering the field from 2014 to 2020 with links to each paper's PDF and code.
- 25

skills
11.2Khuggingface/skills · PythonThis repo provides modular 'Agent Skills' — SKILL.md definitions that teach AI coding agents (Claude Code, Codex, Gemini CLI, Cursor) how to do Hugging Face ML tasks like managing models/datasets, training, evaluation, and deploying to Spaces or SageMaker.
- 26
ml-intern
10.8Khuggingface/ml-intern · PythonML Intern was a CLI agent that autonomously researched, wrote, and shipped ML code using the Hugging Face ecosystem, with deep access to docs, papers, datasets, and cloud compute. The repo is now archived — Hugging Face folded this functionality into HuggingChat's ML Intern mode.
- 27
doccano
10.8Kdoccano/doccano · PythonDoccano is an open-source text annotation tool that lets humans label data for machine learning tasks like text classification, sequence labeling, and sequence-to-sequence problems such as summarization or translation.
- 28

techniques
10.3Ksatellite-image-deep-learning/techniquesA curated list of techniques for deep learning with satellite and aerial imagery, covering architectures, models and algorithms for tasks like classification, segmentation and object detection.
- 29

prediction-market-analysis
3.9KJon-Becker/prediction-market-analysis · PythonIt's a framework for collecting and analyzing prediction market data from Polymarket and Kalshi, bundled with the largest publicly available dataset of their market and trade history.
- 30
UniMate
1.8KFriedrich-M/UniMate · PythonUniMate is the official code release for a SIGGRAPH Asia 2026 paper: a single diffusion/flow-matching model that generates motion for very different skeleton types (bipedal, quadrupedal, avian, marine, insectoid, serpentine, and even rigid articulated objects) from a rigged 3D asset plus a text prompt, without retraining per skeleton.
Related topics
Often tagged together
- python2,383
- machine-learning916
- open-source5,666
- deep-learning737
- research764
- dataset124
- data-science231
- apache-2.01,434
- computer-vision384
- linux4,184
- library1,587
- ai1,955
- nlp214
- academic-research209
- curated-list634
- mit3,312
- pytorch419
- windows3,403
- awesome-list495
- macos3,544
- papers71
- resources706
- web2,447
- artificial-intelligence267