Topics / #vision-language-action-model
Vision-language-action-model projects on GitHub
Vision-language-action models for robotics that output actions from images and instructions
As of , the most-starred Vision-language-action-model projects on GitHub are starVLA (3.8K stars), ZDTaichu5.0-9B (3.1K stars) and FluxVLA (749 stars). GitHub.Locker tracks 6 Vision-language-action-model repositories with 8.3K stars combined. The fastest-growing on October 17 was RoboICL, with +4 stars in a day.
Hot right now
Most stars gained in a day · Oct 17
 +4
RoboICL
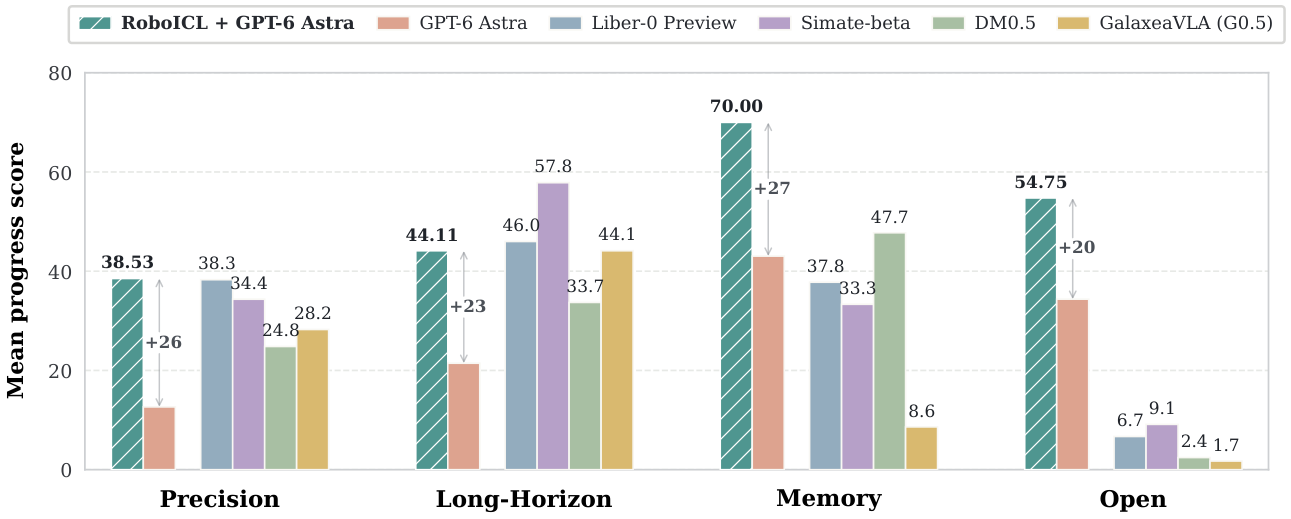
Mosi-AI/RoboICL · ★ 271RoboICL is a research framework that lets a frozen, general-purpose vision-language model (GPT-6 Astra) control a robot in simulation purely through in-context learning, without training a dedicated robot policy.
 +2
starVLA
starVLA/starVLA · ★ 3.8KStarVLA is an open-source, modular research codebase for building Vision-Language-Action (VLA) models that control generalist robots, letting you mix and match backbones, action heads, and training recipes like Lego bricks.
 +2
FluxVLA
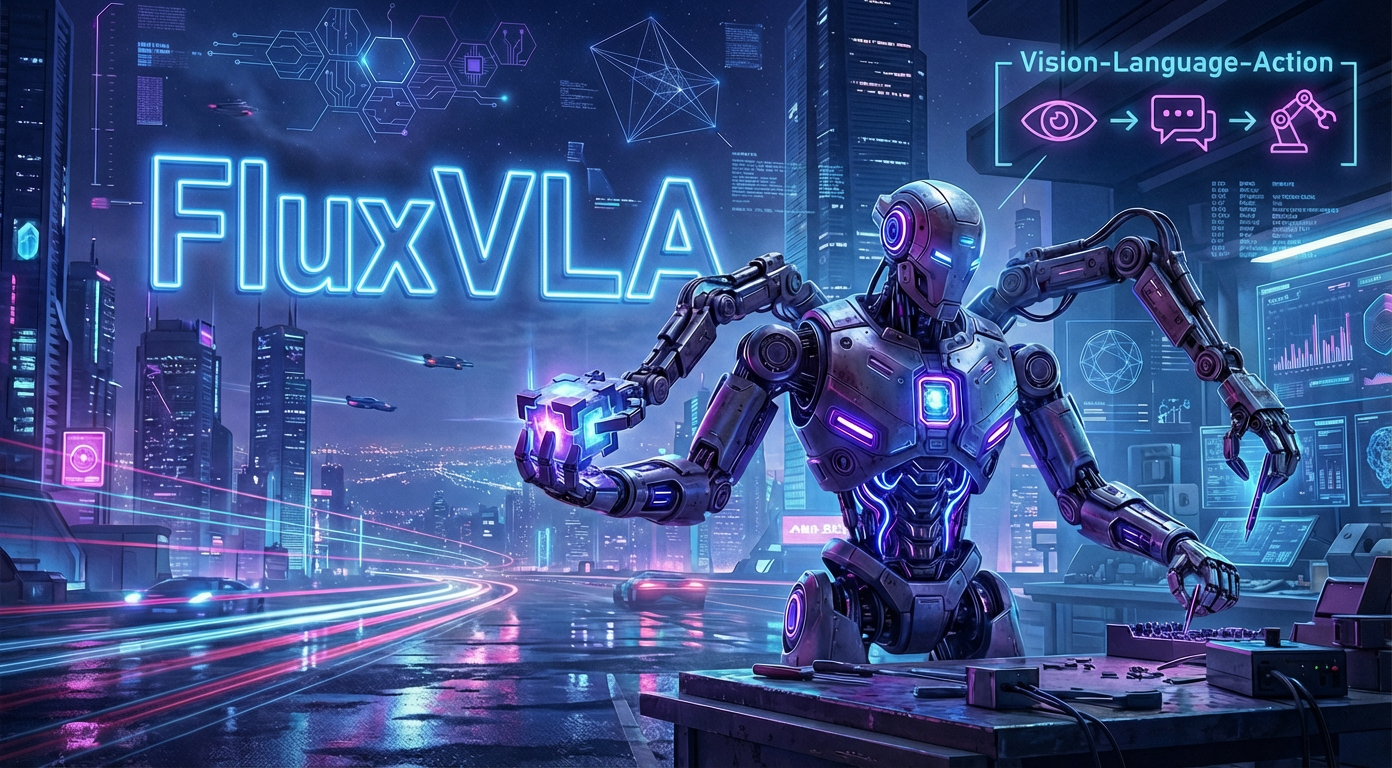
FluxVLA/FluxVLA · ★ 749FluxVLA is a full-stack engineering platform for embodied AI covering the whole loop from data to real-robot deployment for vision-language-action (VLA) models, built to lower the engineering barrier for VLA research and development.
 +1
ZDTaichu5.0-9B
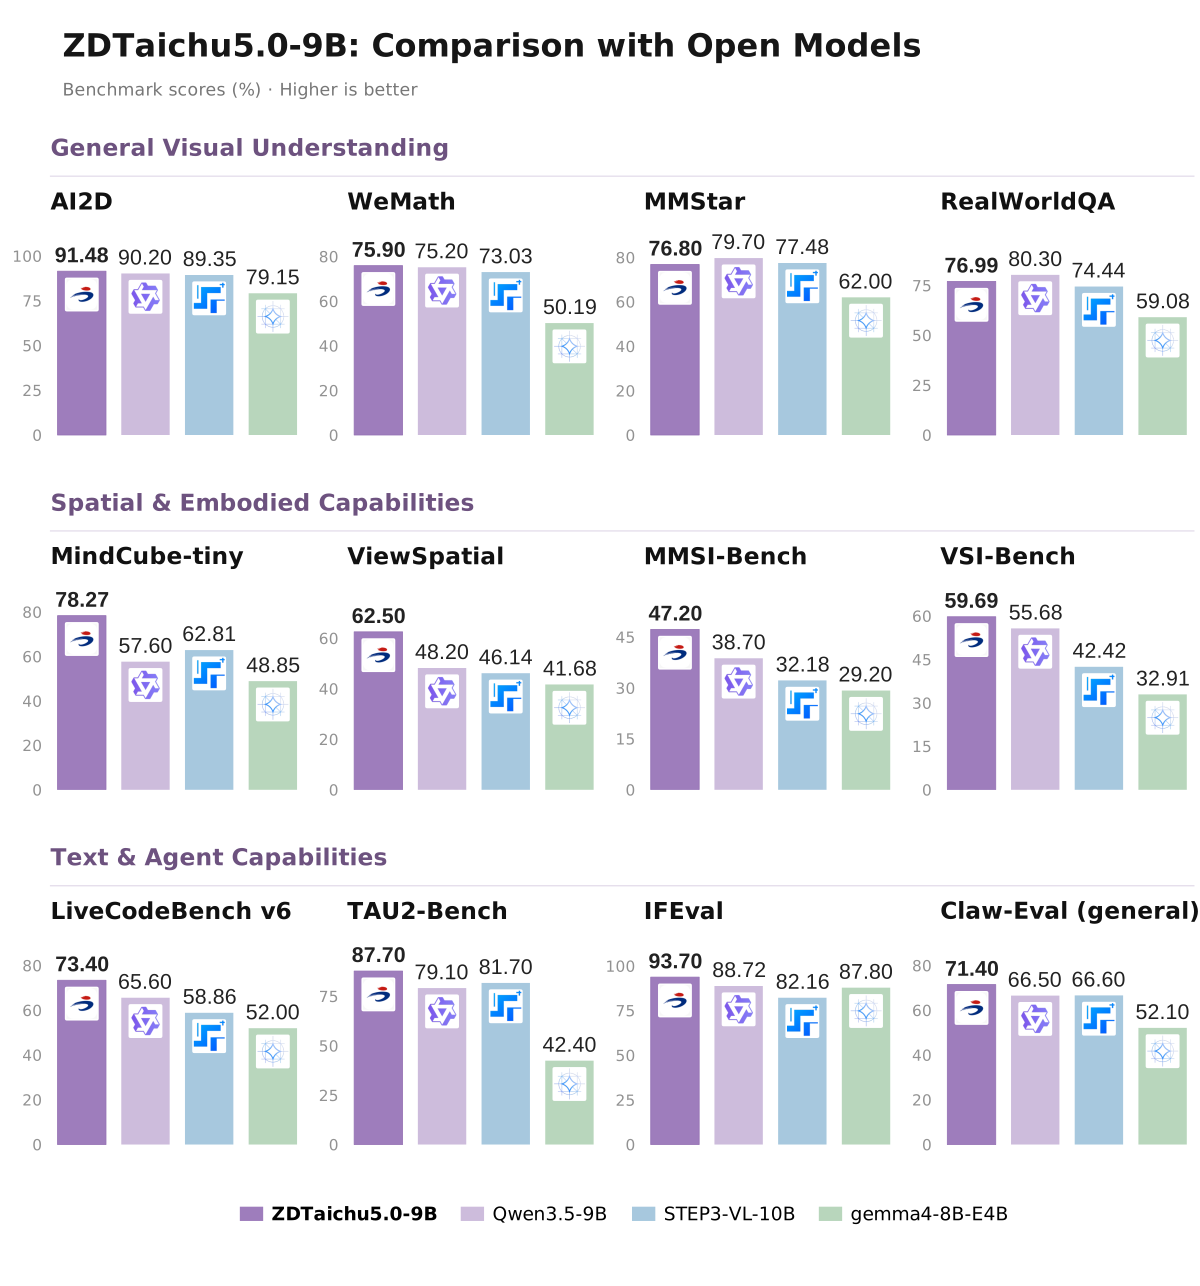
Taichu-AI/ZDTaichu5.0-9B · ★ 3.1KZDTaichu5.0-9B is a multimodal foundation model that combines a Qwen3.5-9B language backbone with a C-RADIOv4-H vision encoder for general visual understanding, spatial reasoning, embodied-AI research and agentic tool use.
The all-time top
6 projects · by stars
- 3.8K#1 · starVLA/starVLA
starVLA
StarVLA is an open-source, modular research codebase for building Vision-Language-Action (VLA) models that control generalist robots, letting you mix and match backbones, action heads, and training recipes like Lego bricks.
- 3.1K#2 · Taichu-AI/ZDTaichu5.0-9B
ZDTaichu5.0-9B
ZDTaichu5.0-9B is a multimodal foundation model that combines a Qwen3.5-9B language backbone with a C-RADIOv4-H vision encoder for general visual understanding, spatial reasoning, embodied-AI research and agentic tool use.
- 749#3 · FluxVLA/FluxVLA
FluxVLA
FluxVLA is a full-stack engineering platform for embodied AI covering the whole loop from data to real-robot deployment for vision-language-action (VLA) models, built to lower the engineering barrier for VLA research and development.
- 4
RoboICL
271Mosi-AI/RoboICL · PythonRoboICL is a research framework that lets a frozen, general-purpose vision-language model (GPT-6 Astra) control a robot in simulation purely through in-context learning, without training a dedicated robot policy.
- 5
StreamPI
211hku-sail/StreamPI · PythonOfficial code of StreamPI (NeurIPS 2026, from HKU and ACE Robotics): a streaming temporal modeling framework that gives VLA robot policies like pi0.5 memory of past frames and multi-frame perception without adding any new parameters.
- 6
InstinctFlash
200General-Instinct/InstinctFlash · PythonInstinctFlash is a high-performance serving runtime for robotics foundation models - it loads checkpoints like GR00T, Cosmos3, pi0.5, LingBot-VA/VLA and DreamZero, applies acceleration (FP8, fused Triton kernels, caching) and serves them over Python or WebSocket, reporting up to 33.78x speedup on Jetson Thor.
Related topics
Often tagged together