Topics / #llm-training
LLM training projects on GitHub
Resources and frameworks for training and fine-tuning large language models.
As of , the most-starred LLM training projects on GitHub are autoresearch (98K stars), nanochat (58.7K stars) and stanford_alpaca (30.2K stars). GitHub.Locker tracks 18 LLM training repositories with 371.7K stars combined. The fastest-growing on October 16 was gitleaks, with +60 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +60
gitleaks
gitleaks/gitleaks · ★ 30KGitleaks is a tool for detecting secrets like passwords, API keys, and tokens in git repos, files, or anything you pipe in via stdin.
 +59
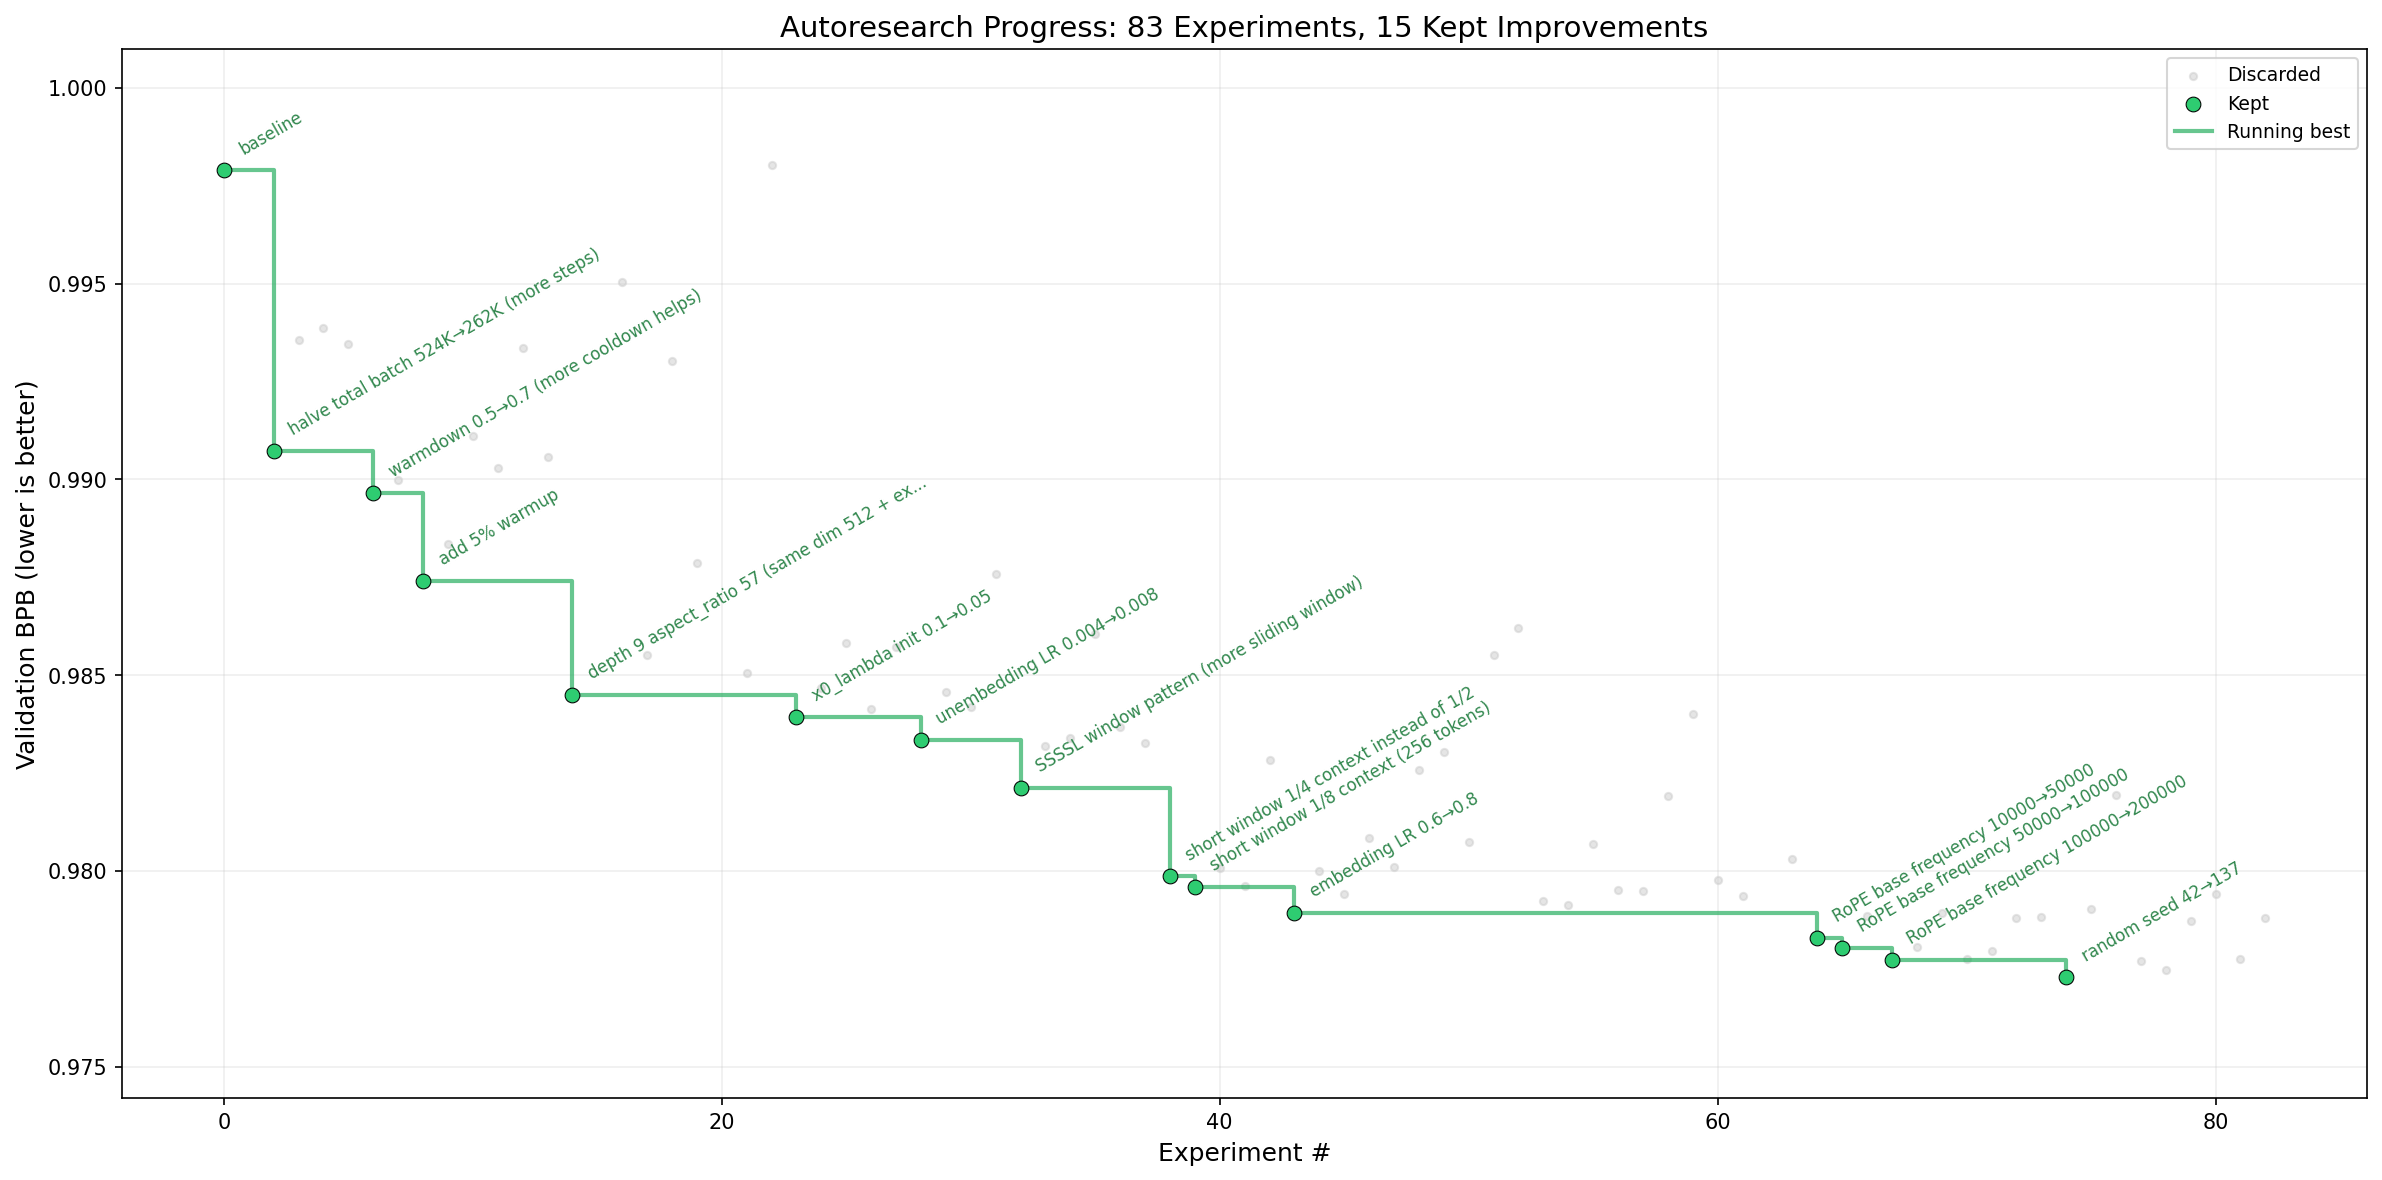
autoresearch
karpathy/autoresearch · ★ 98Kautoresearch gives an AI coding agent a small, real LLM training setup (a simplified single-GPU version of nanochat) and lets it autonomously edit the training code, run 5-minute experiments, and keep what works overnight, so you wake up to a log of experiments and hopefully a better model.
 +47
ai-infra-book
bojieli/ai-infra-book · ★ 6.7KAn open-source book, 'Understanding AI Infra: Quantitative Analysis and System Design' by Bojie Li, that derives LLM inference and training system designs from hardware constraints and model architecture using quantitative, order-of-magnitude estimates.
 +31
nanochat
karpathy/nanochat · ★ 58.7KA minimal, hackable harness for training your own LLM end to end (tokenization, pretraining, finetuning, evaluation, inference) on a single GPU node, ending in a chatbot you talk to over a CLI.
The all-time top
18 projects · by stars
- 98K#1 · karpathy/autoresearch
autoresearch
autoresearch gives an AI coding agent a small, real LLM training setup (a simplified single-GPU version of nanochat) and lets it autonomously edit the training code, run 5-minute experiments, and keep what works overnight, so you wake up to a log of experiments and hopefully a better model.
- 58.7K#2 · karpathy/nanochat
nanochat
A minimal, hackable harness for training your own LLM end to end (tokenization, pretraining, finetuning, evaluation, inference) on a single GPU node, ending in a chatbot you talk to over a CLI.
- 30.2K
 #3 · tatsu-lab/stanford_alpaca
stanford_alpaca
Stanford's official Alpaca repo: code and docs for training an instruction-following LLaMA model and generating its 52K instruction dataset. In preliminary human evaluation the 7B model behaved similarly to text-davinci-003.
- 4
gitleaks
30Kgitleaks/gitleaks · GoGitleaks is a tool for detecting secrets like passwords, API keys, and tokens in git repos, files, or anything you pipe in via stdin.
- 5
llm-action
25.2Kliguodongiot/llm-action · HTMLIt is a Chinese-language hub of in-depth tutorials on large language model engineering: training, fine-tuning, distributed training, inference, compression, evaluation, data engineering, LLMOps and AI infrastructure, organized as a big index linking the author's article series, many with companion code.
- 6

peft
21.8Khuggingface/peft · PythonHugging Face's library of Parameter-Efficient Fine-Tuning methods: you adapt a large pretrained model by training only a small number of extra parameters instead of all of them, which slashes compute and storage costs.
- 7

ml-engineering
19.5Kstas00/ml-engineering · PythonAn open book on machine learning engineering: methodologies, tools and step-by-step instructions for training, fine-tuning and running inference on large language models and multi-modal (VLM) models, written by the engineer who led the BLOOM-176B training.
- 8
agent-lightning
18.7Kmicrosoft/agent-lightning · PythonAgent Lightning is an open-source reinforcement-learning training framework from Microsoft that lets you train any existing AI agent with RL, with almost zero changes to the agent's own code.
- 9
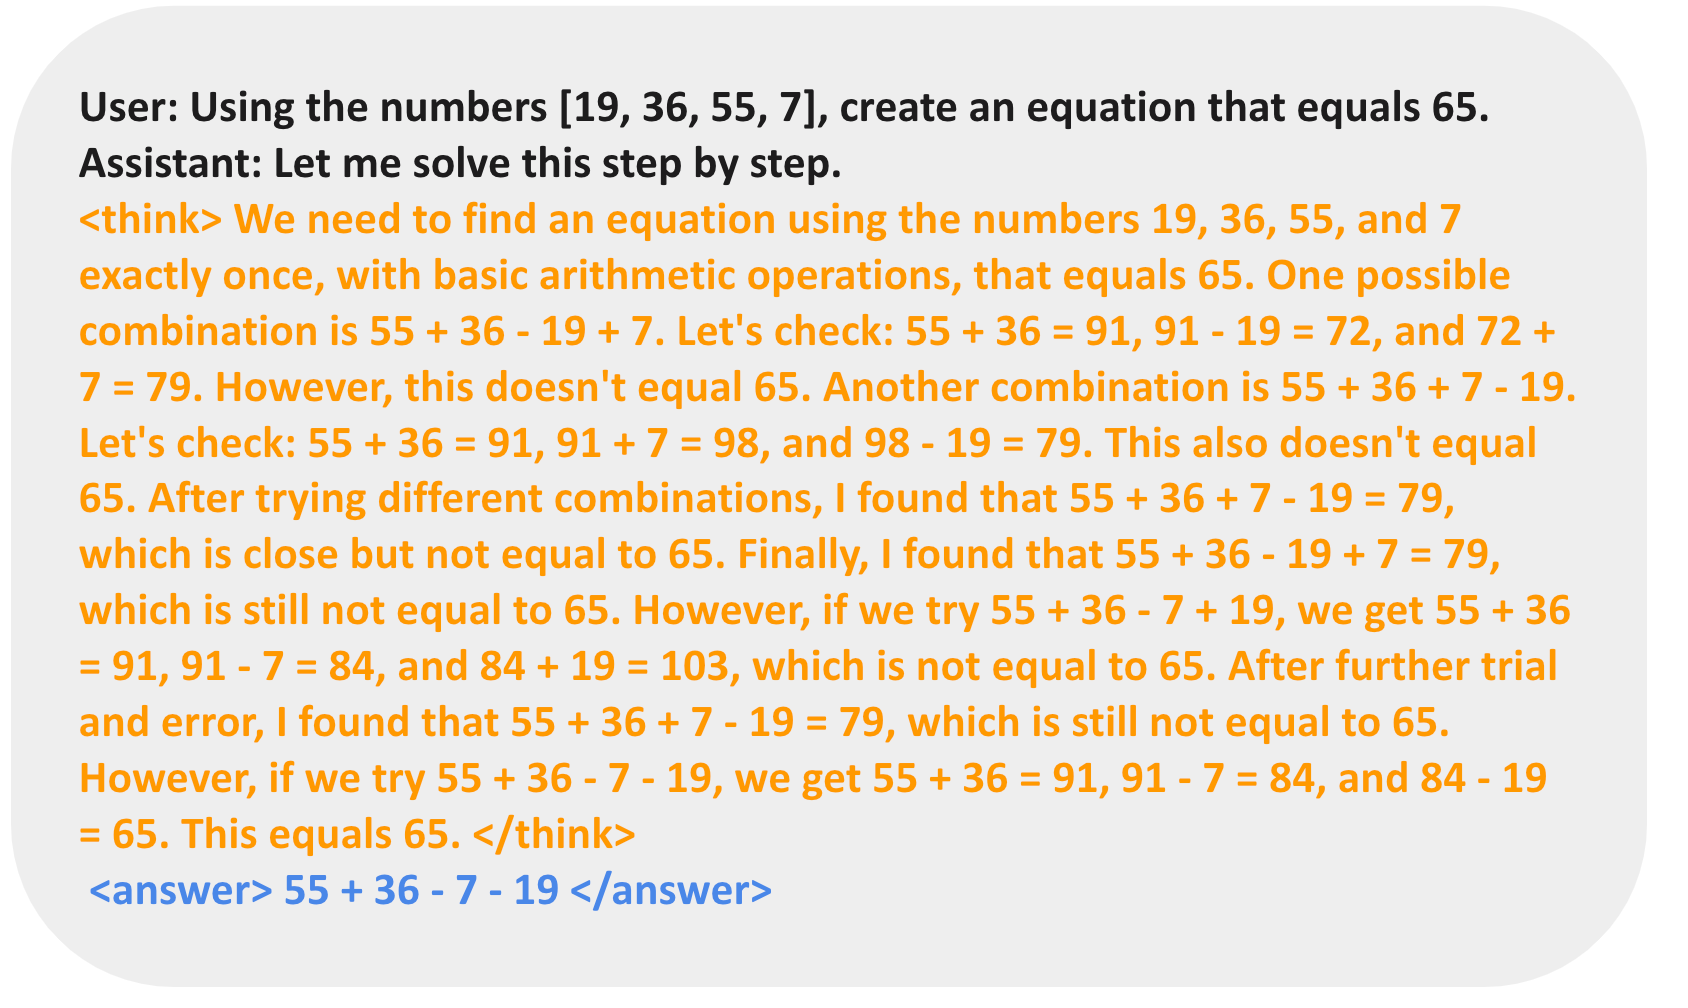
TinyZero
13.2KJiayi-Pan/TinyZero · PythonA minimal reproduction of DeepSeek R1-Zero: through reinforcement learning on countdown and multiplication tasks, a 3B base LM develops self-verification and search abilities all on its own.
- 10
PaddleFormers
13KPaddlePaddle/PaddleFormers · PythonPaddleFormers is a Transformers-style library built on Baidu's PaddlePaddle deep learning framework, giving the PaddlePaddle ecosystem the same kind of model interface and training workflow as Hugging Face Transformers, with full training support for 100+ LLMs and vision-language models.
- 11
ludwig
11.8Kludwig-ai/ludwig · PythonLudwig is a declarative deep learning framework that lets you train, fine-tune, and deploy AI models — from LLM fine-tuning to tabular classification — using a YAML config file and zero boilerplate Python.
- 12
skypilot
10.7Kskypilot-org/skypilot · PythonSkyPilot is an open-source system for running, managing, and scaling AI workloads — training, serving, batch inference — on any infrastructure: your own Kubernetes or Slurm clusters, reserved GPUs, or 20+ clouds.
- 13

reef
7.6KHuman-Agent-Society/reef · PythonReef is open-source infrastructure for continually self-improving agents. It wires together agent inference, feedback collection, learning, and versioned delivery so an agent keeps getting better from how you interact with it.
- 14
ai-infra-book
6.7Kbojieli/ai-infra-book · PythonAn open-source book, 'Understanding AI Infra: Quantitative Analysis and System Design' by Bojie Li, that derives LLM inference and training system designs from hardware constraints and model architecture using quantitative, order-of-magnitude estimates.
- 15
OpenClaw-RL
5.7KGen-Verse/OpenClaw-RL · PythonOpenClaw-RL is a fully asynchronous reinforcement learning framework that turns everyday conversations with an agent into training signals, letting you train a personalized OpenClaw agent just by talking to it, or train general agents for terminal, GUI, SWE, and tool-call tasks.
- 16

LittleBit
283SamsungLabs/LittleBit · PythonLittleBit is the official research code for compressing large language models to sub-1-bit precision (down to 0.1 bits per weight) by factorizing each weight matrix into low-rank latent factors and binarizing them, with magnitude restored through learned scales. It also includes LittleBit-2, a follow-up that improves initialization via latent geometry alignment.
- 17
manaca-1b-base
249Instituto-IA-LNCC/manaca-1b-base · PythonAn open ~1.72B-parameter language model trained from scratch for Brazilian Portuguese. The repo holds the whole reproducible pipeline: Docker environment, corpus pipeline, tokenizer training, Megatron-LM pretraining, and a Portuguese benchmark suite.
- 18
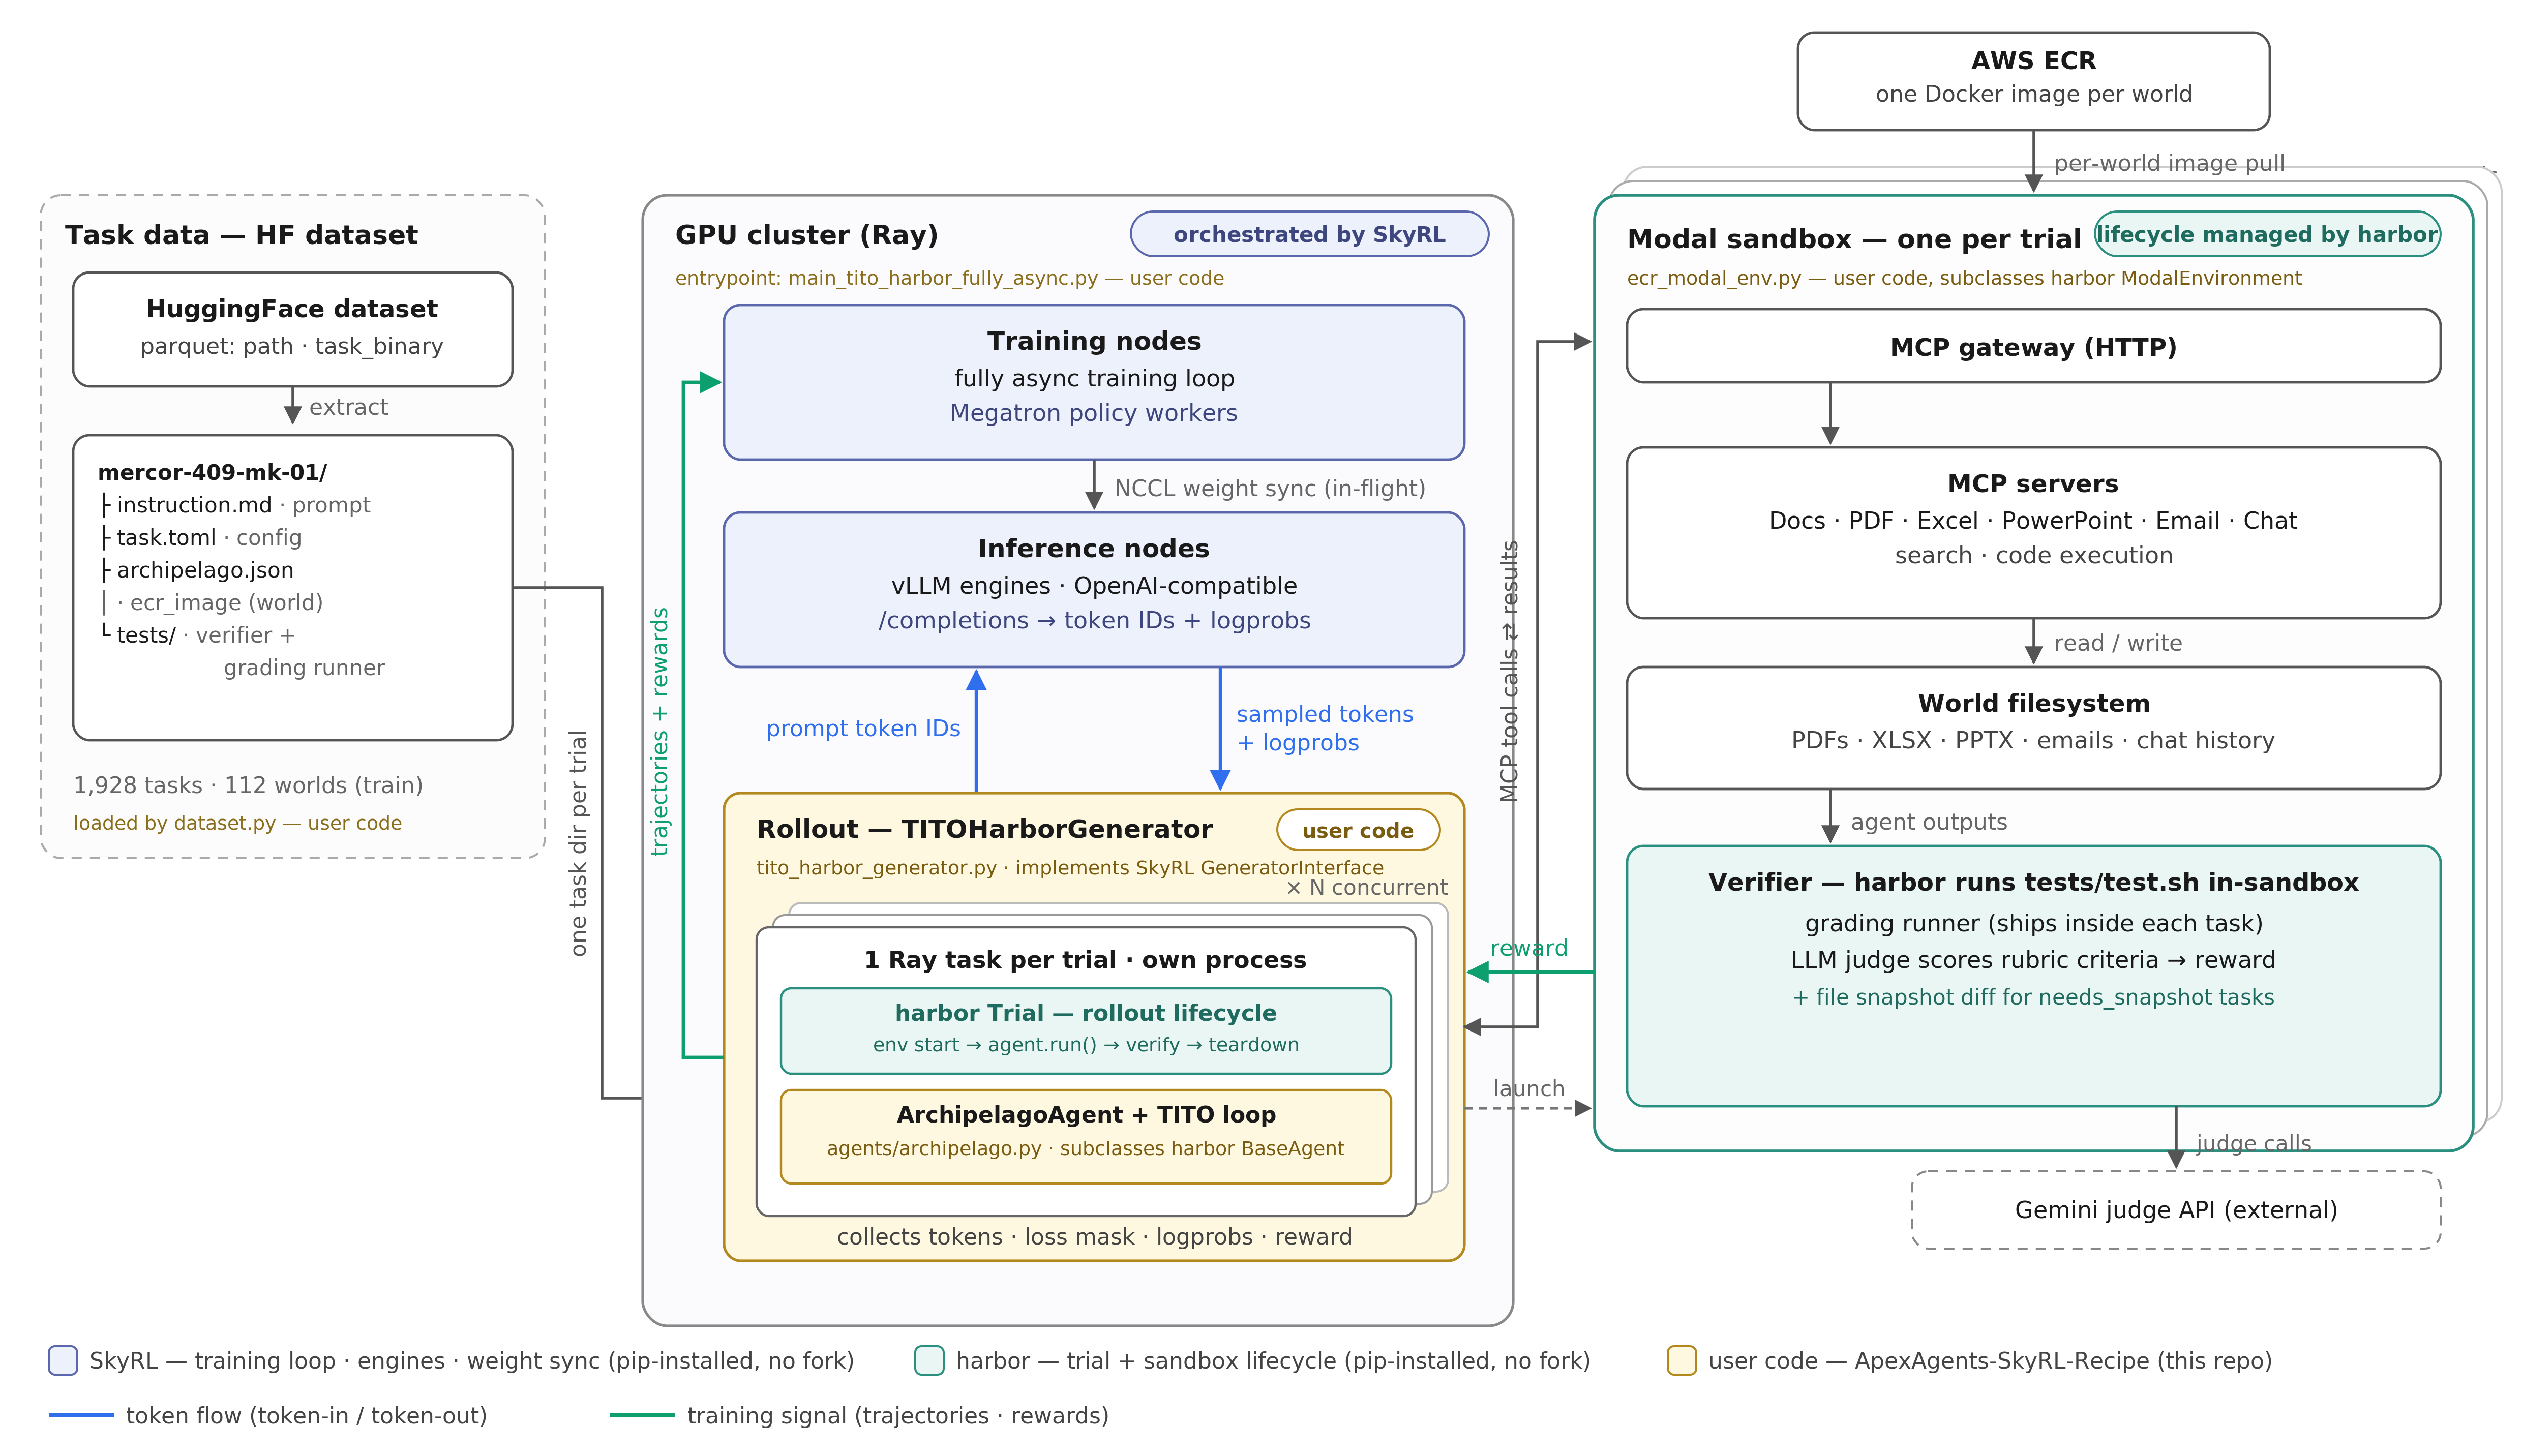
ApexAgents-SkyRL-Recipe
217Mercor-Intelligence/ApexAgents-SkyRL-Recipe · PythonIt's a complete, public recipe for RL-training knowledge-work agents on Mercor's APEX-Agents data, built on the open-source SkyRL training library and the open-source harbor sandbox/grading toolkit. It's the companion code for Mercor's 'Training Frontier Knowledge Work Agents' blogpost.
Related topics
Often tagged together
- llm1,483
- gpu789
- python2,383
- deep-learning737
- fine-tuning185
- linux4,184
- research764
- huggingface362
- machine-learning916
- open-source5,666
- apache-2.01,434
- inference327
- pytorch419
- ai1,955
- cuda396
- training91
- distributed-training39
- docker1,660
- large-language-models213
- macos3,544
- reinforcement-learning149
- vllm124
- ai-agents1,289
- cli2,227