Topics / #foundation-models
Foundation-models projects on GitHub
Large general-purpose foundation models and their training.
As of , the most-starred Foundation-models projects on GitHub are llama (59.6K stars), segment-anything (55K stars) and ColossalAI (41.4K stars). GitHub.Locker tracks 44 Foundation-models repositories with 574.1K stars combined. The fastest-growing on October 18 was Kronos, with +317 stars in a day.
Hot right now
Most stars gained in a day · Oct 18
 +317
Kronos
shiyu-coder/Kronos · ★ 41.3KKronos is an open-source foundation model for financial candlestick (K-line) data, pretrained on data from over 45 global exchanges to produce price/volume forecasts.
 +282
MOSS-Image
OpenMOSS/MOSS-Image · ★ 686MOSS-Image is a 5-billion-parameter text-to-image diffusion transformer (DiT) model built for strong text rendering, JSON-based layout control over where text and objects go, and efficient fine-tuning (including LoRA) on custom tasks.
 +110
YuE
multimodal-art-projection/YuE · ★ 12.1KYuE2 is an open-source music generation model: lyrics plus a style prompt become an editable melody-and-chord plan, then a complete song with vocals and accompaniment. It also does zero-shot covers and agent-driven editing.
 +83
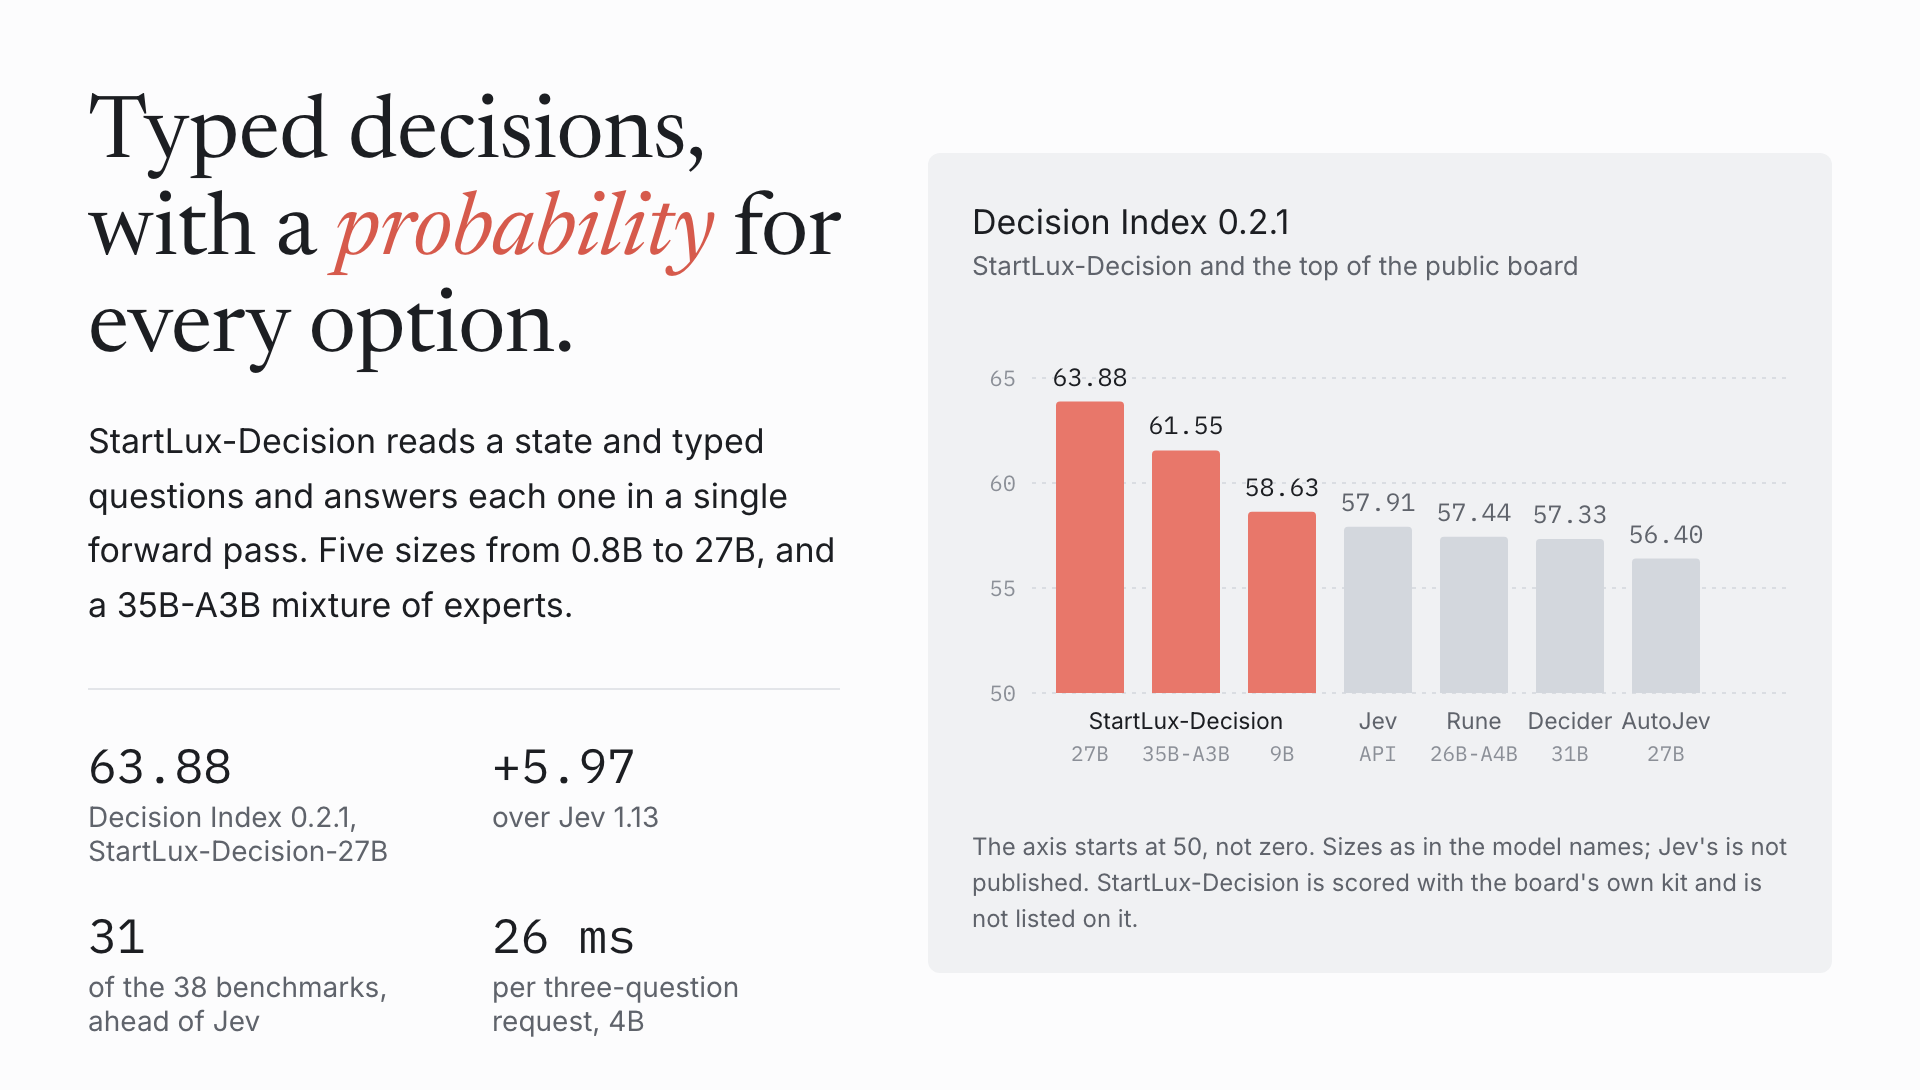
StartLux-Decision
StartLuxLabs/StartLux-Decision · ★ 727StartLux-Decision is a family of typed decision models (five dense sizes from 0.8B to 27B plus a 35B-A3B mixture-of-experts) that answer a question with a probability for each option instead of generating text.
The all-time top
44 projects · by stars
- 59.6K
 #1 · meta-llama/llama
llama
This is Meta's reference inference code for running Llama 2 language models (7B to 70B parameters) locally, letting you load pre-trained or chat fine-tuned weights and generate text completions.
- 55K
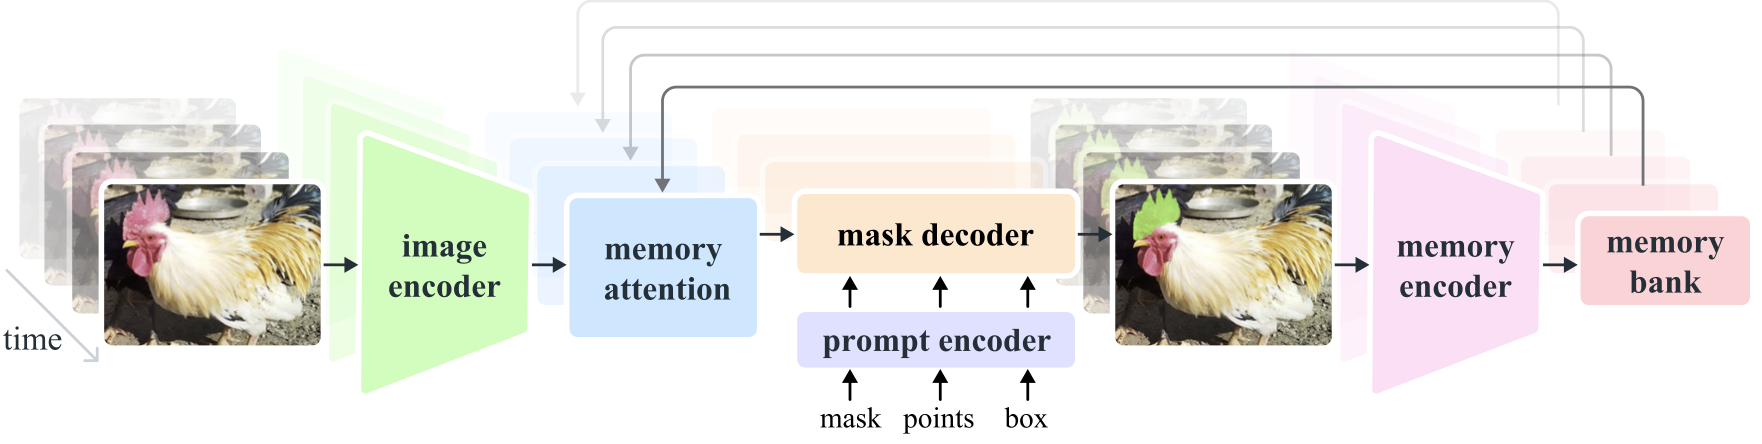 #2 · facebookresearch/segment-anything
segment-anything
This is Meta AI's Segment Anything Model (SAM), a foundation model that produces object masks for images from prompts like points or boxes, or automatically generates masks for every object in an image.
- 41.4K
 #3 · hpcaitech/ColossalAI
ColossalAI
Colossal-AI is an open-source system for training and running large AI models more cheaply, faster and with less hardware, by providing a toolbox of parallelism and memory-optimization techniques.
- 4
Kronos
41.3Kshiyu-coder/Kronos · PythonKronos is an open-source foundation model for financial candlestick (K-line) data, pretrained on data from over 45 global exchanges to produce price/volume forecasts.
- 5
timesfm
34.6Kgoogle-research/timesfm · PythonTimesFM is a pretrained time-series foundation model from Google Research used for time-series forecasting, similar in spirit to a language model but for numerical sequences.
- 6

Qwen3
27.7KQwenLM/Qwen3 · PythonQwen3 is a series of open-weight large language models built by the Qwen team at Alibaba Cloud, released as both dense and Mixture-of-Experts (MoE) models from 0.6B up to 235B-A22B parameters, with switchable 'thinking' and 'non-thinking' reasoning modes.
- 7
TDengine
25.2Ktaosdata/TDengine · CTDengine is an open-source, high-performance, cloud-native, AI-powered time-series database built for IoT, Connected Cars, and Industrial IoT workloads, handling TB-to-PB scale data from billions of sensors.
- 8
LLaVA
25.1Khaotian-liu/LLaVA · PythonLLaVA is an open-source large multimodal chatbot: a vision-language model you can show images to and talk with, built by visual instruction tuning toward GPT-4V-level capabilities (NeurIPS 2023 Oral).
- 9

unilm
22.2Kmicrosoft/unilm · PythonMicrosoft's research hub for large-scale self-supervised pre-training: a family of foundation models spanning NLP, vision, speech, and multimodal tasks across 100+ languages - including BEiT, LayoutLM, Kosmos, MiniLM, TrOCR, and WavLM.
- 10

sam2
20Kfacebookresearch/sam2 · Jupyter NotebookSAM 2 (Segment Anything Model 2) is Meta's foundation model for promptable segmentation of objects in both images and videos, extending the original Segment Anything Model with a streaming memory architecture for real-time video tracking.
- 11
Grounded-Segment-Anything
17.8KIDEA-Research/Grounded-Segment-Anything · Jupyter NotebookGrounded SAM, a research demo project that combines Grounding DINO with Segment Anything to detect and segment any object in an image from a plain text prompt, extended with Stable Diffusion, RAM, Whisper and more.
- 12
Janus
17.8Kdeepseek-ai/Janus · PythonJanus is DeepSeek's family of open multimodal AI models (Janus, Janus-Pro, JanusFlow). One model both understands images and text and generates images from a text prompt.
- 13
Wan2.1
17.2KWan-Video/Wan2.1 · PythonWan2.1 is an open suite of large-scale video generative models: it turns text or images into videos, and also covers video editing, text-to-image and video-to-audio tasks.
- 14
YuE
12.1Kmultimodal-art-projection/YuE · PythonYuE2 is an open-source music generation model: lyrics plus a style prompt become an editable melody-and-chord plan, then a complete song with vocals and accompaniment. It also does zero-shot covers and agent-driven editing.
- 15
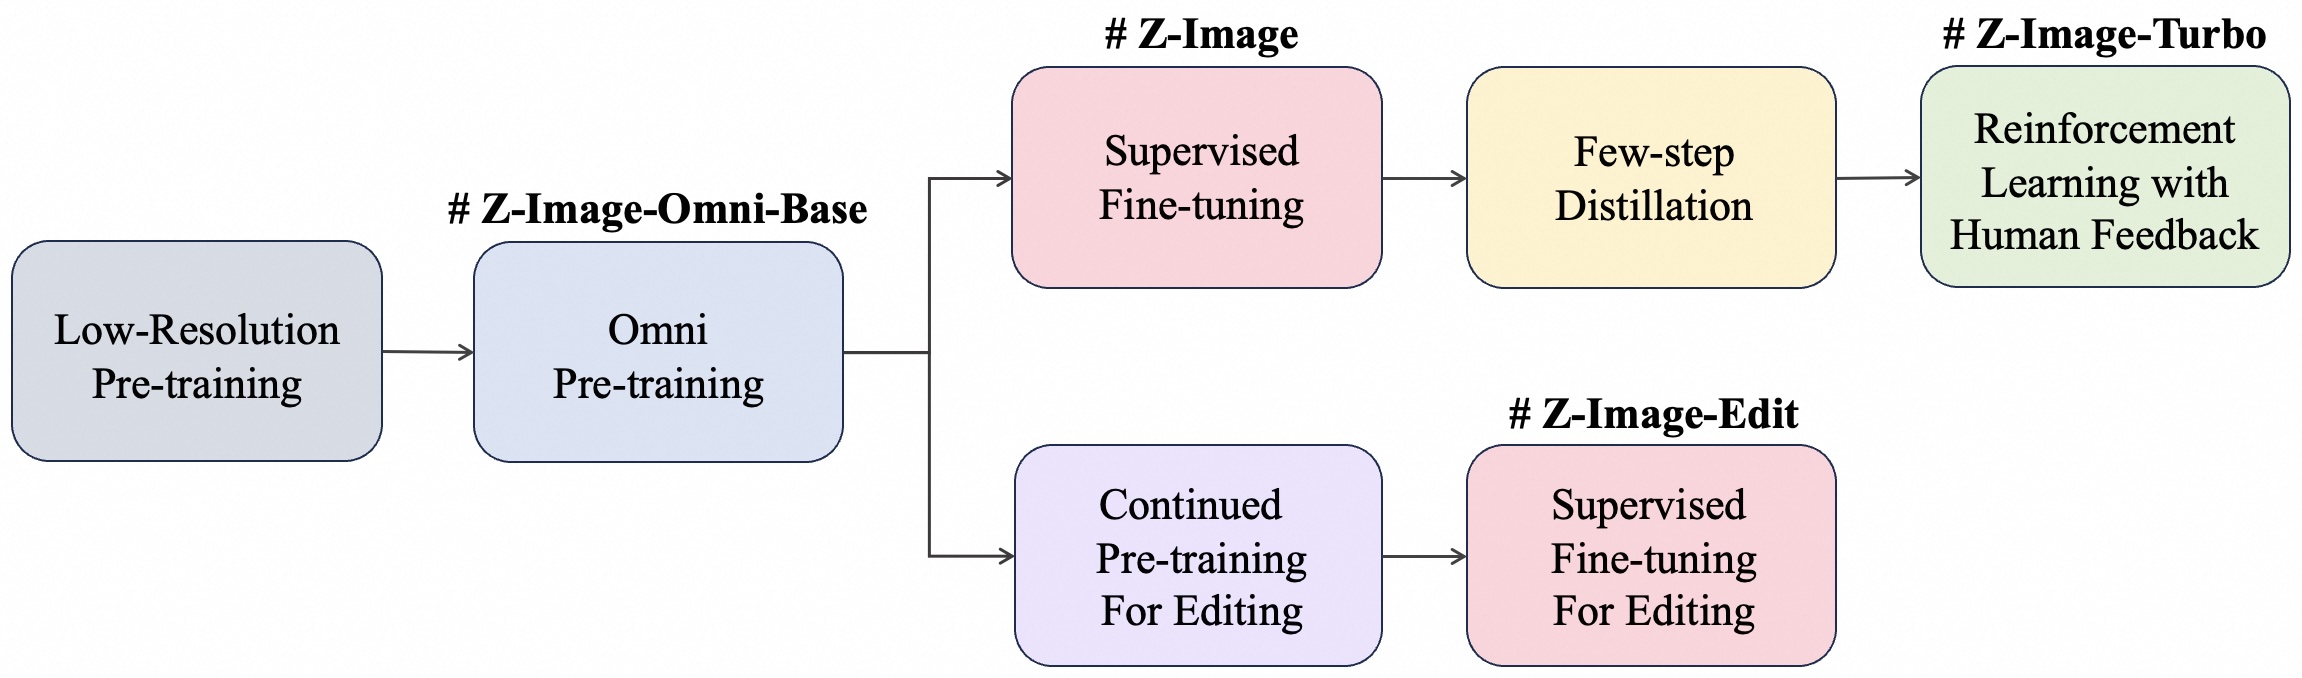
Z-Image
12.1KTongyi-MAI/Z-Image · PythonZ-Image is a family of efficient image generation models with 6B parameters, built around a single-stream diffusion transformer architecture, developed by Alibaba's Tongyi team.
- 16
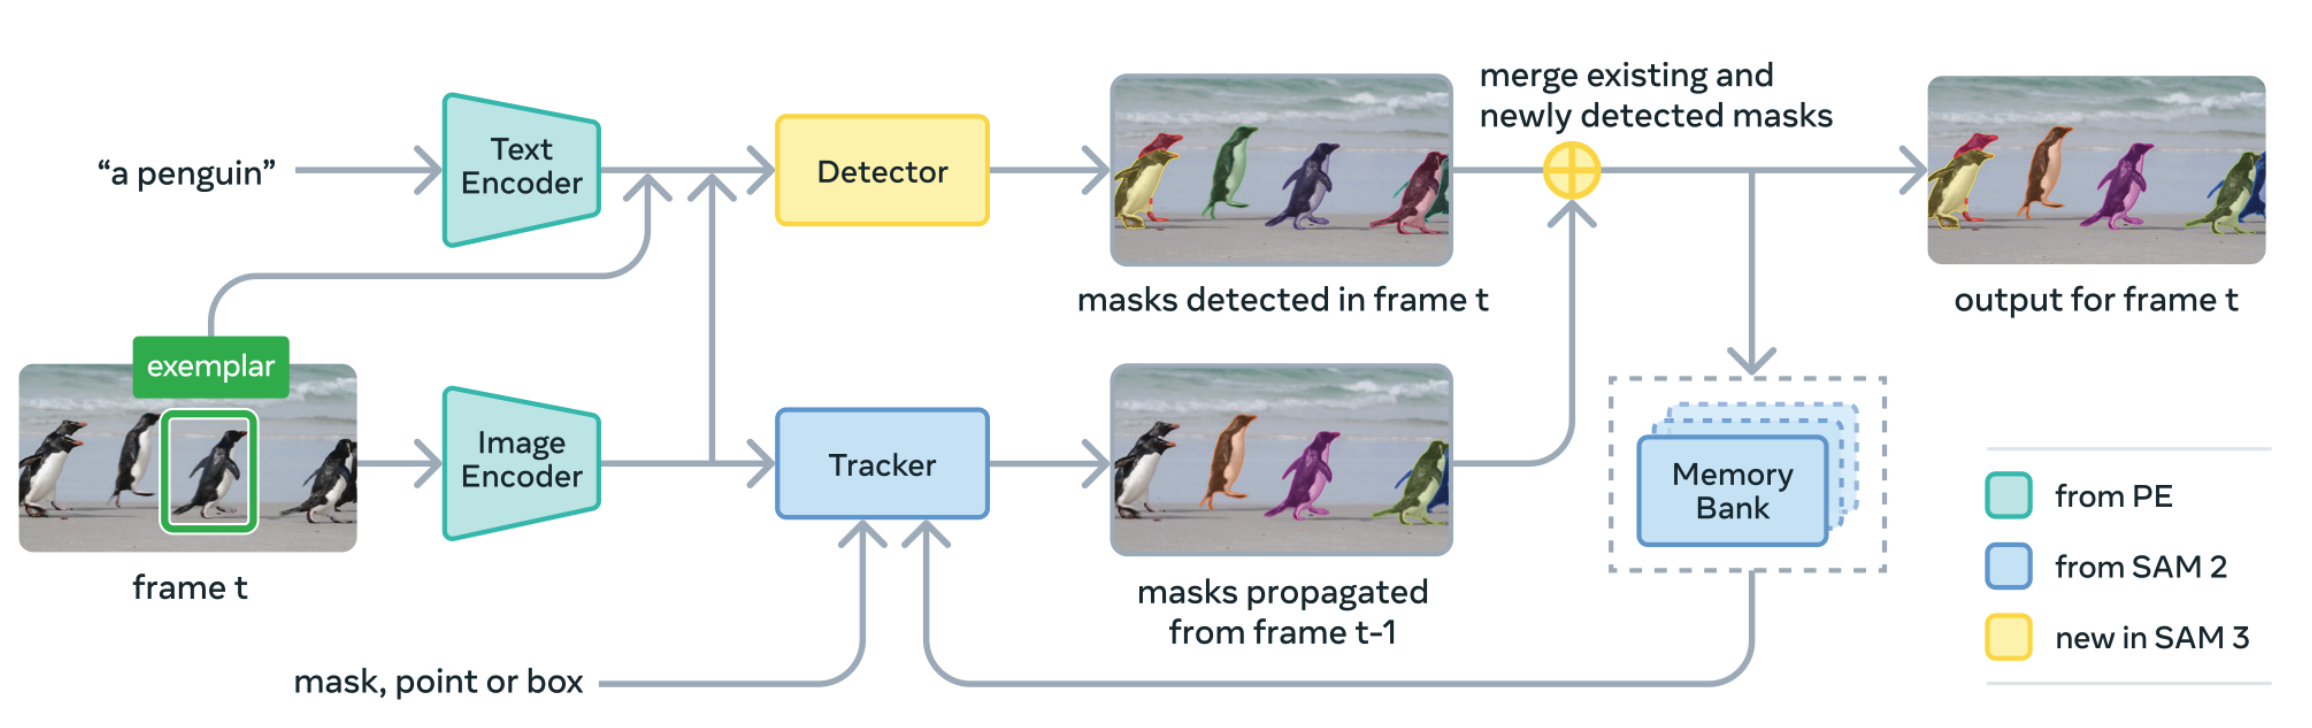
sam3
12Kfacebookresearch/sam3 · PythonSAM 3 is Meta's unified foundation model for promptable segmentation in images and videos. It can detect, segment, and track objects using text prompts or visual prompts like points, boxes, and masks.
- 17

seamless_communication
11.9Kfacebookresearch/seamless_communication · Jupyter NotebookSeamless Communication is Meta's family of foundational AI models for speech and text translation across roughly 100 languages, covering speech-to-speech, speech-to-text, text-to-speech and text-to-text translation plus automatic speech recognition.
- 18
dinov3
11.6Kfacebookresearch/dinov3 · Jupyter NotebookMeta AI Research (FAIR)'s reference PyTorch implementation and model release for DINOv3, a family of vision foundation models that produce high-quality dense features and perform strongly across many vision tasks.
- 19
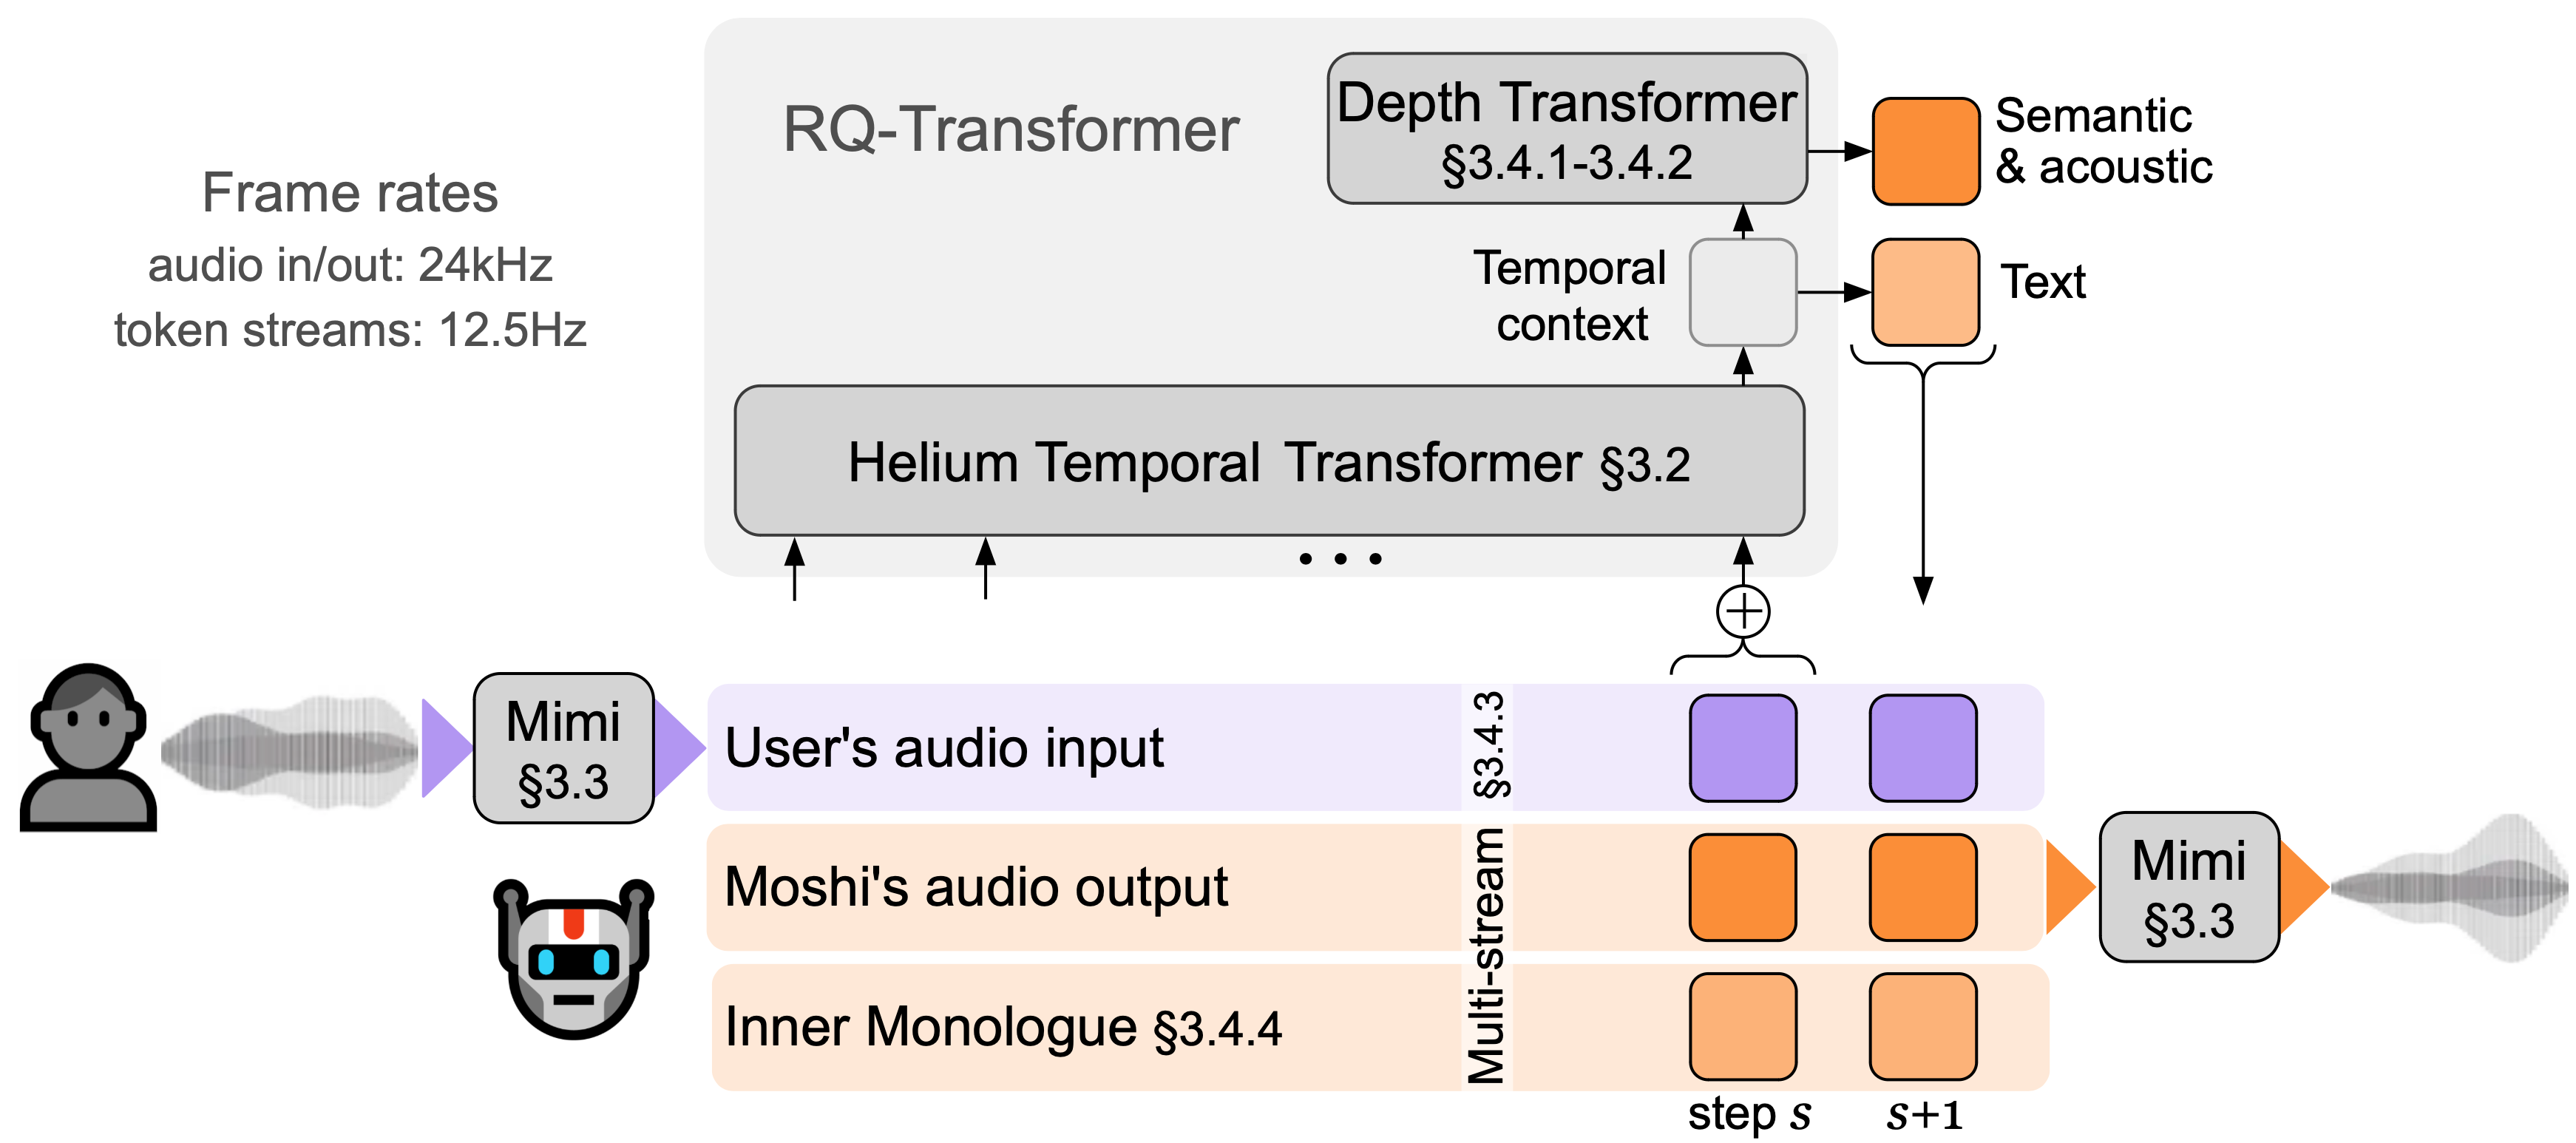
moshi
11.3Kkyutai-labs/moshi · PythonMoshi is a speech-text foundation model and full-duplex spoken dialogue framework, meaning the model can listen and speak at the same time rather than taking turns like typical voice assistants.
- 20

LTX-Video
11.1KLightricks/LTX-Video · PythonLTX-Video is the official repo for Lightricks' DiT-based video generation model, which generates synchronized audio+video, supports text-to-video and image-to-video, keyframe conditioning, video extension, and video-to-video transformations.
- 21
autogluon
10.8Kautogluon/autogluon · PythonAutoGluon is an open-source Python library that automates machine learning: feed it your data and it delivers strong predictive performance in about three lines of code.
- 22

pyod
10Kyzhao062/pyod · PythonPyOD is a Python library for anomaly detection that bundles over 60 detection algorithms into one consistent API, covering tabular, time series, graph, text, image, and audio data.
- 23
LTX-2
9.8KLightricks/LTX-2 · PythonThe official Python package for LTX-2, Lightricks' audio-video foundation model: one DiT-based model that generates video with synchronized audio from text or an image, in several quality/speed modes.
- 24
LongCat-Video
9.2Kmeituan-longcat/LongCat-Video · PythonLongCat-Video is a 13.6B-parameter foundational video generation model that unifies Text-to-Video, Image-to-Video, and Video-Continuation generation in a single architecture, aimed at efficient long-video generation and framed as a first step toward world models.
- 25
Kimi-K3
8.9KMoonshotAI/Kimi-K3Kimi K3 is MoonshotAI's open-weight, native multimodal agentic model — a 2.8T-parameter Mixture-of-Experts system built for frontier-level long-horizon coding, agentic knowledge work, and reasoning.
- 26
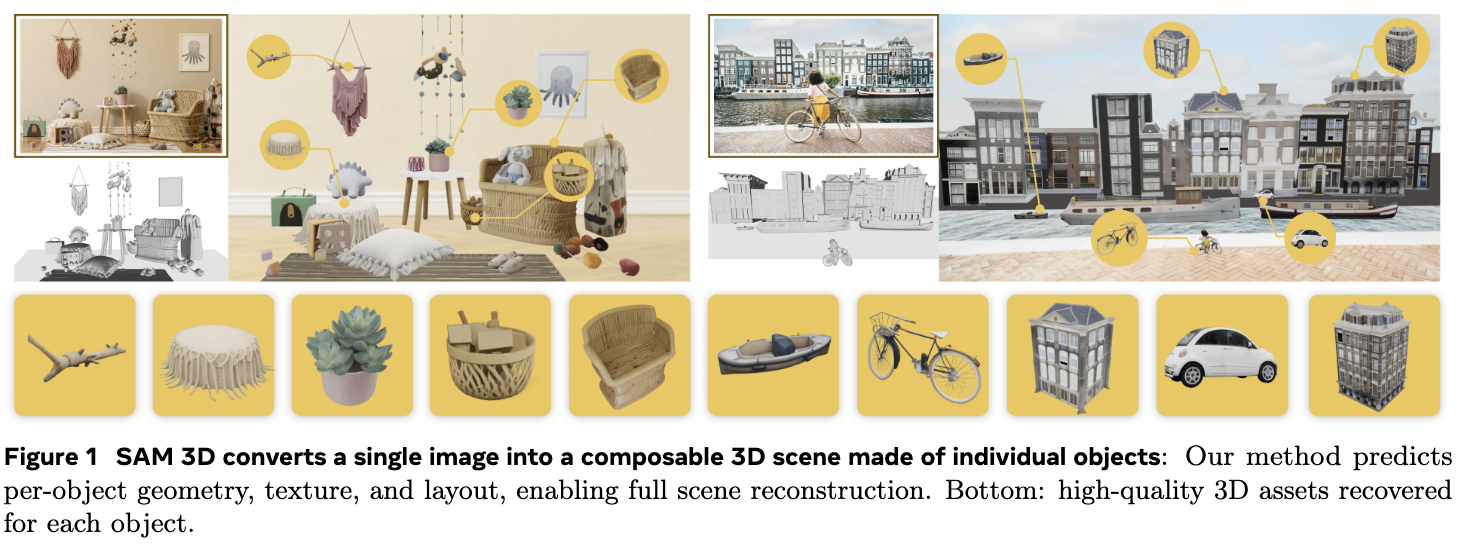
sam-3d-objects
7.5Kfacebookresearch/sam-3d-objects · PythonSAM 3D Objects is a foundation model from Meta that reconstructs full 3D shape geometry, texture, and object layout from a single 2D image, even in cluttered real-world scenes with occlusion.
- 27
opensquilla
7.1KTokenRhythm/opensquilla · PythonOpenSquilla is a token-efficient, microkernel AI agent that uses a local model router to send each conversation turn to the cheapest model that can handle it, while sharing memory, a sandbox, and web search across its CLI, Web UI, and chat-channel interfaces.
- 28

awesome-opensource-ai
4.9Kalvinreal/awesome-opensource-ai · PythonA curated, daily-updated list of truly open-source AI projects, models, tools, and infrastructure.
- 29

GR00T-WholeBodyControl
3.8KNVlabs/GR00T-WholeBodyControl · PythonNVIDIA GR00T Whole-Body Control — a codebase hosting pretrained checkpoints plus training, evaluation, and deployment code for advanced humanoid robot controllers: the Decoupled WBC used in GR00T N1.5/N1.6, the GEAR-SONIC series, and MotionBricks.
- 30
Attention-Residuals
3.5KMoonshotAI/Attention-ResidualsAttnRes (Attention Residuals) is a drop-in replacement for standard residual connections in Transformers, letting each layer use learned, input-dependent attention over all previous layer outputs instead of simple additive accumulation.
- 31
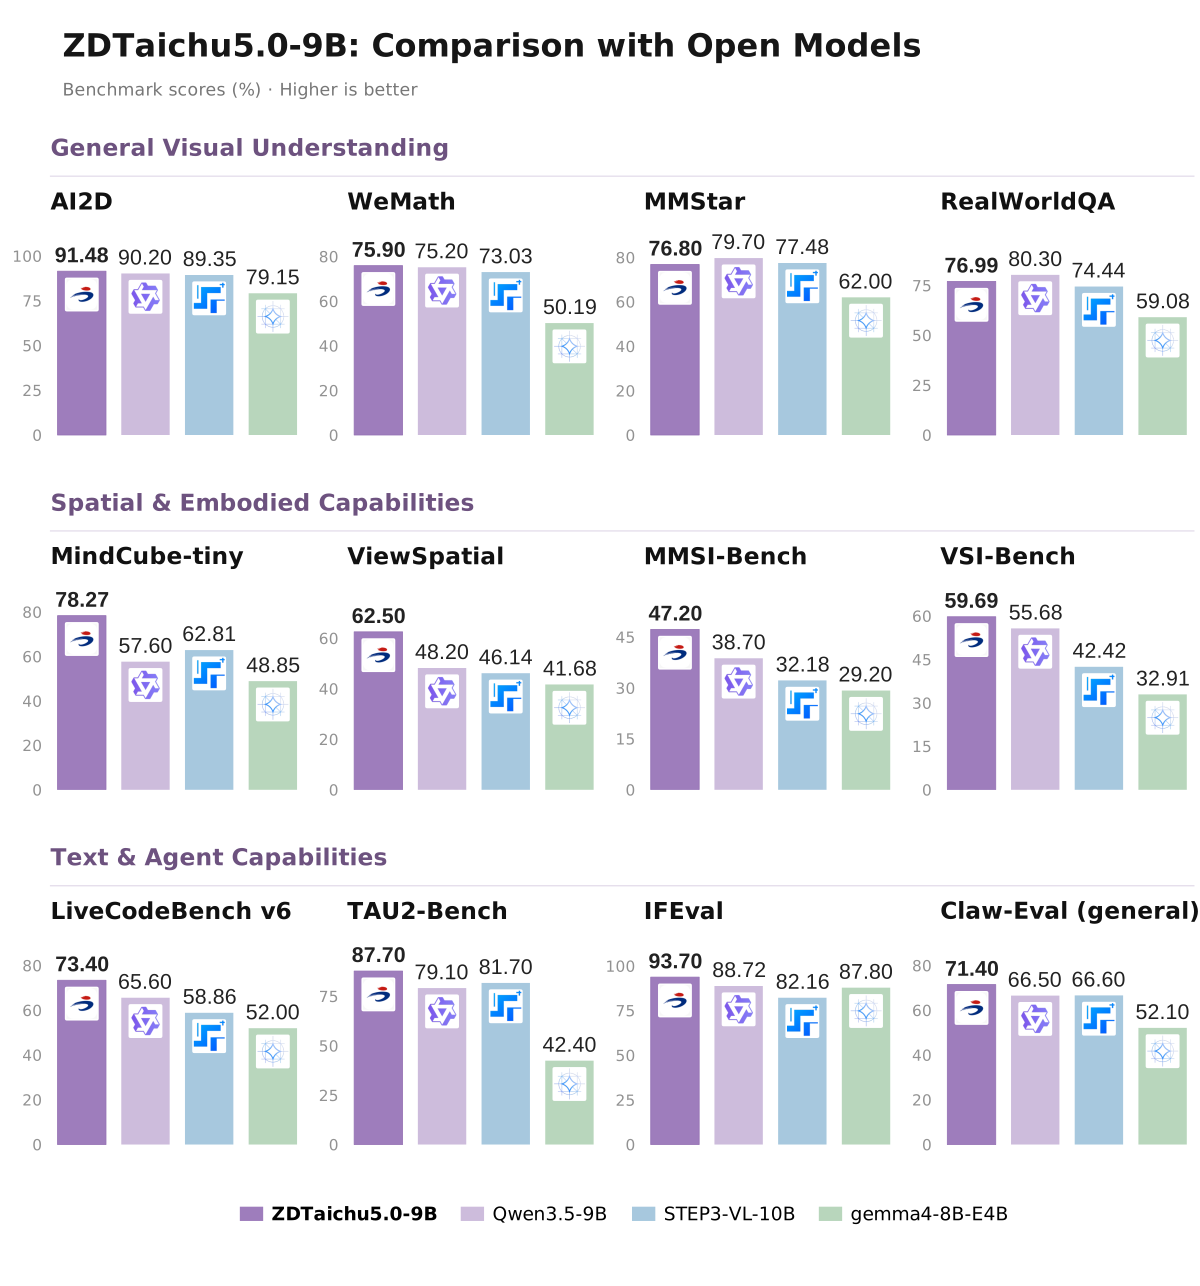
ZDTaichu5.0-9B
3.1KTaichu-AI/ZDTaichu5.0-9B · PythonZDTaichu5.0-9B is a multimodal foundation model that combines a Qwen3.5-9B language backbone with a C-RADIOv4-H vision encoder for general visual understanding, spatial reasoning, embodied-AI research and agentic tool use.
- 32

AuK
1.5KTencent-Hunyuan/AuK · PythonAn open-source 1.5B-parameter foundation model from Tencent Hunyuan for speech generation and editing: zero-shot and instruct TTS, speech editing, enhancement, and source separation — all driven through one natural-language instruction interface.
- 33
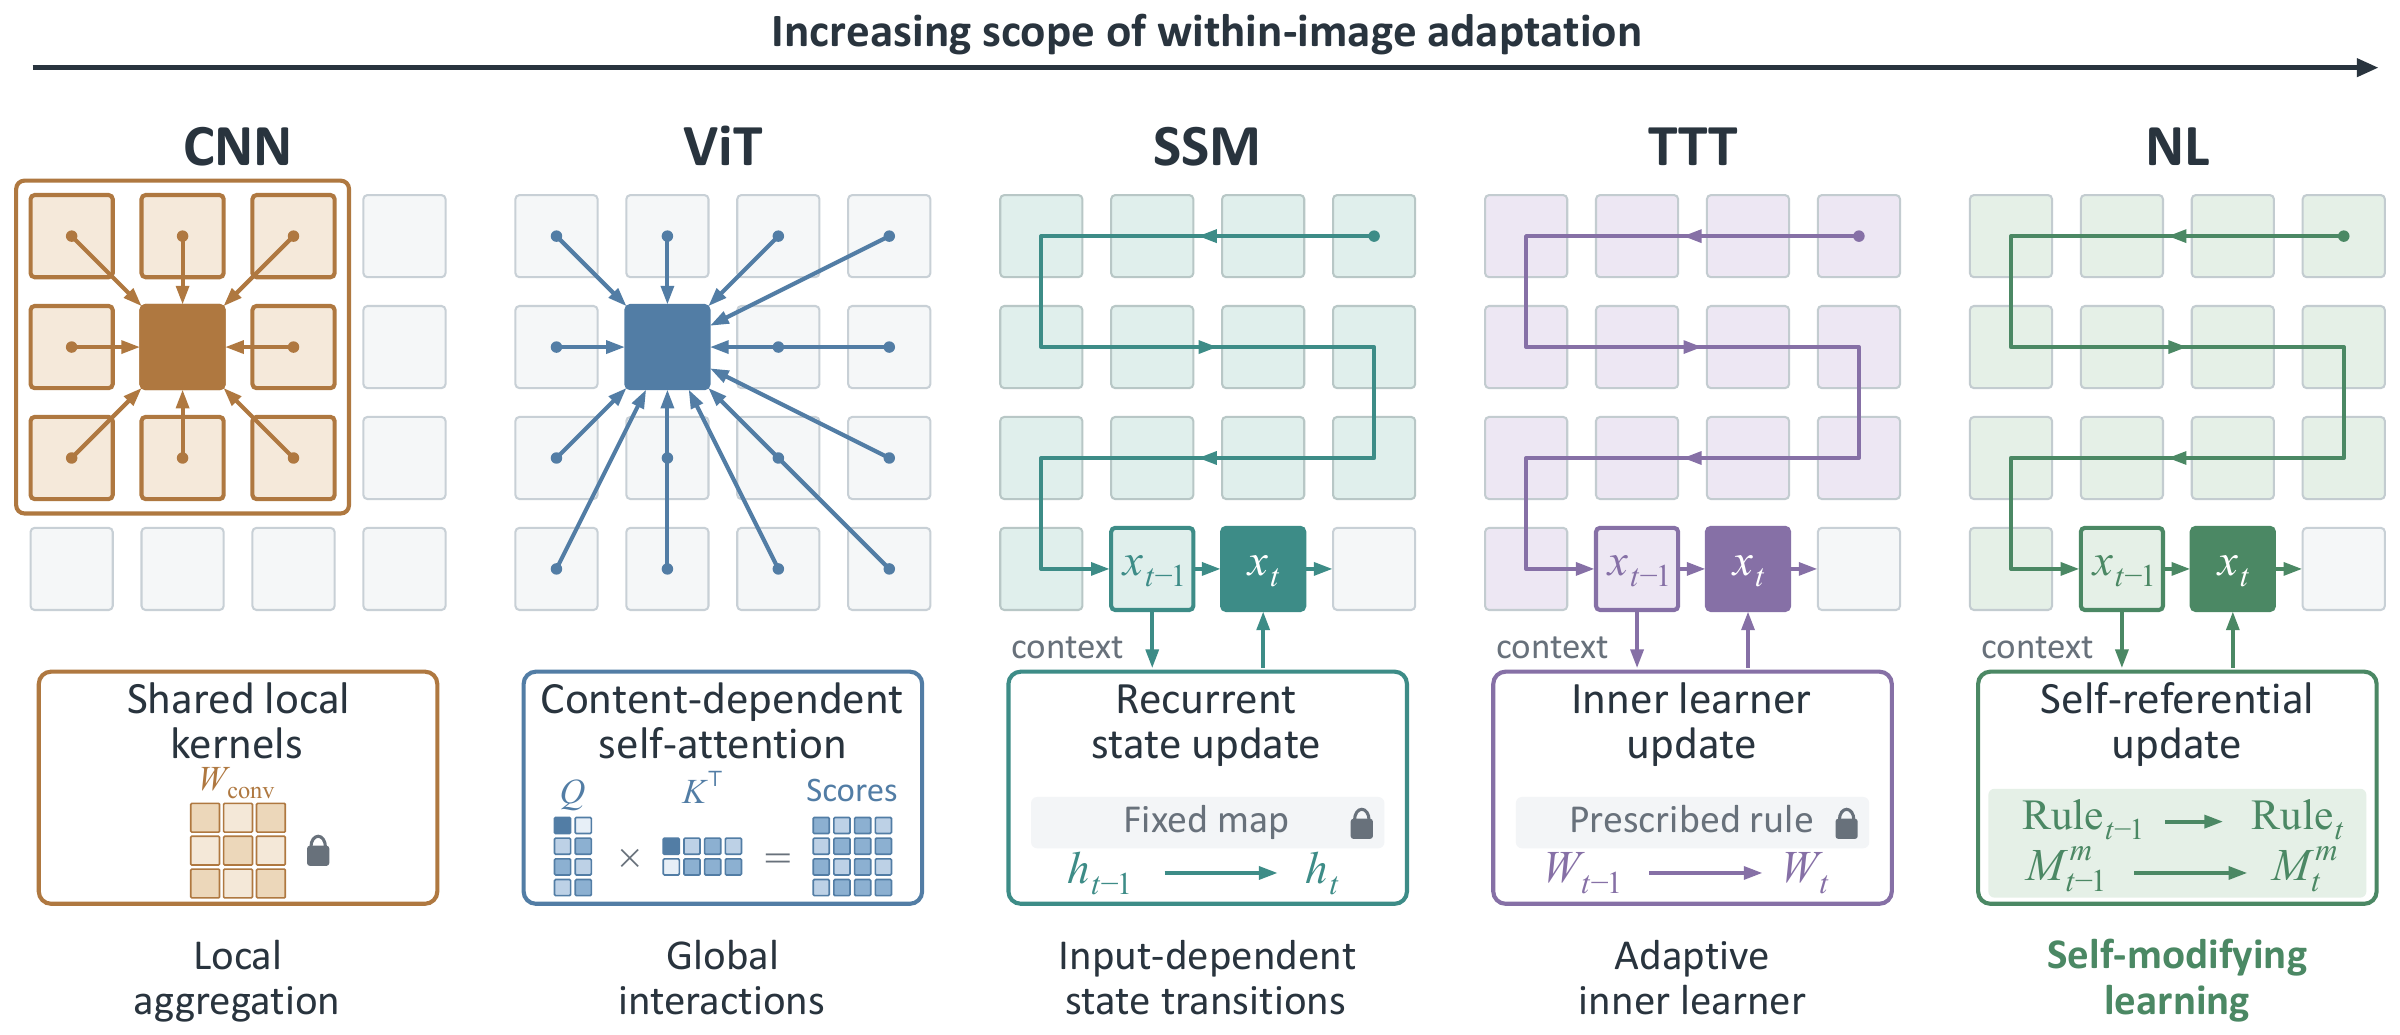
VisionHOPE
1.3KPSRben/VisionHOPE · PythonVisionHOPE is the official PyTorch implementation of a visual backbone built on self-referential nested learning (SRNL), supporting ImageNet-1K classification, COCO detection/instance segmentation, and ADE20K semantic segmentation.
- 34
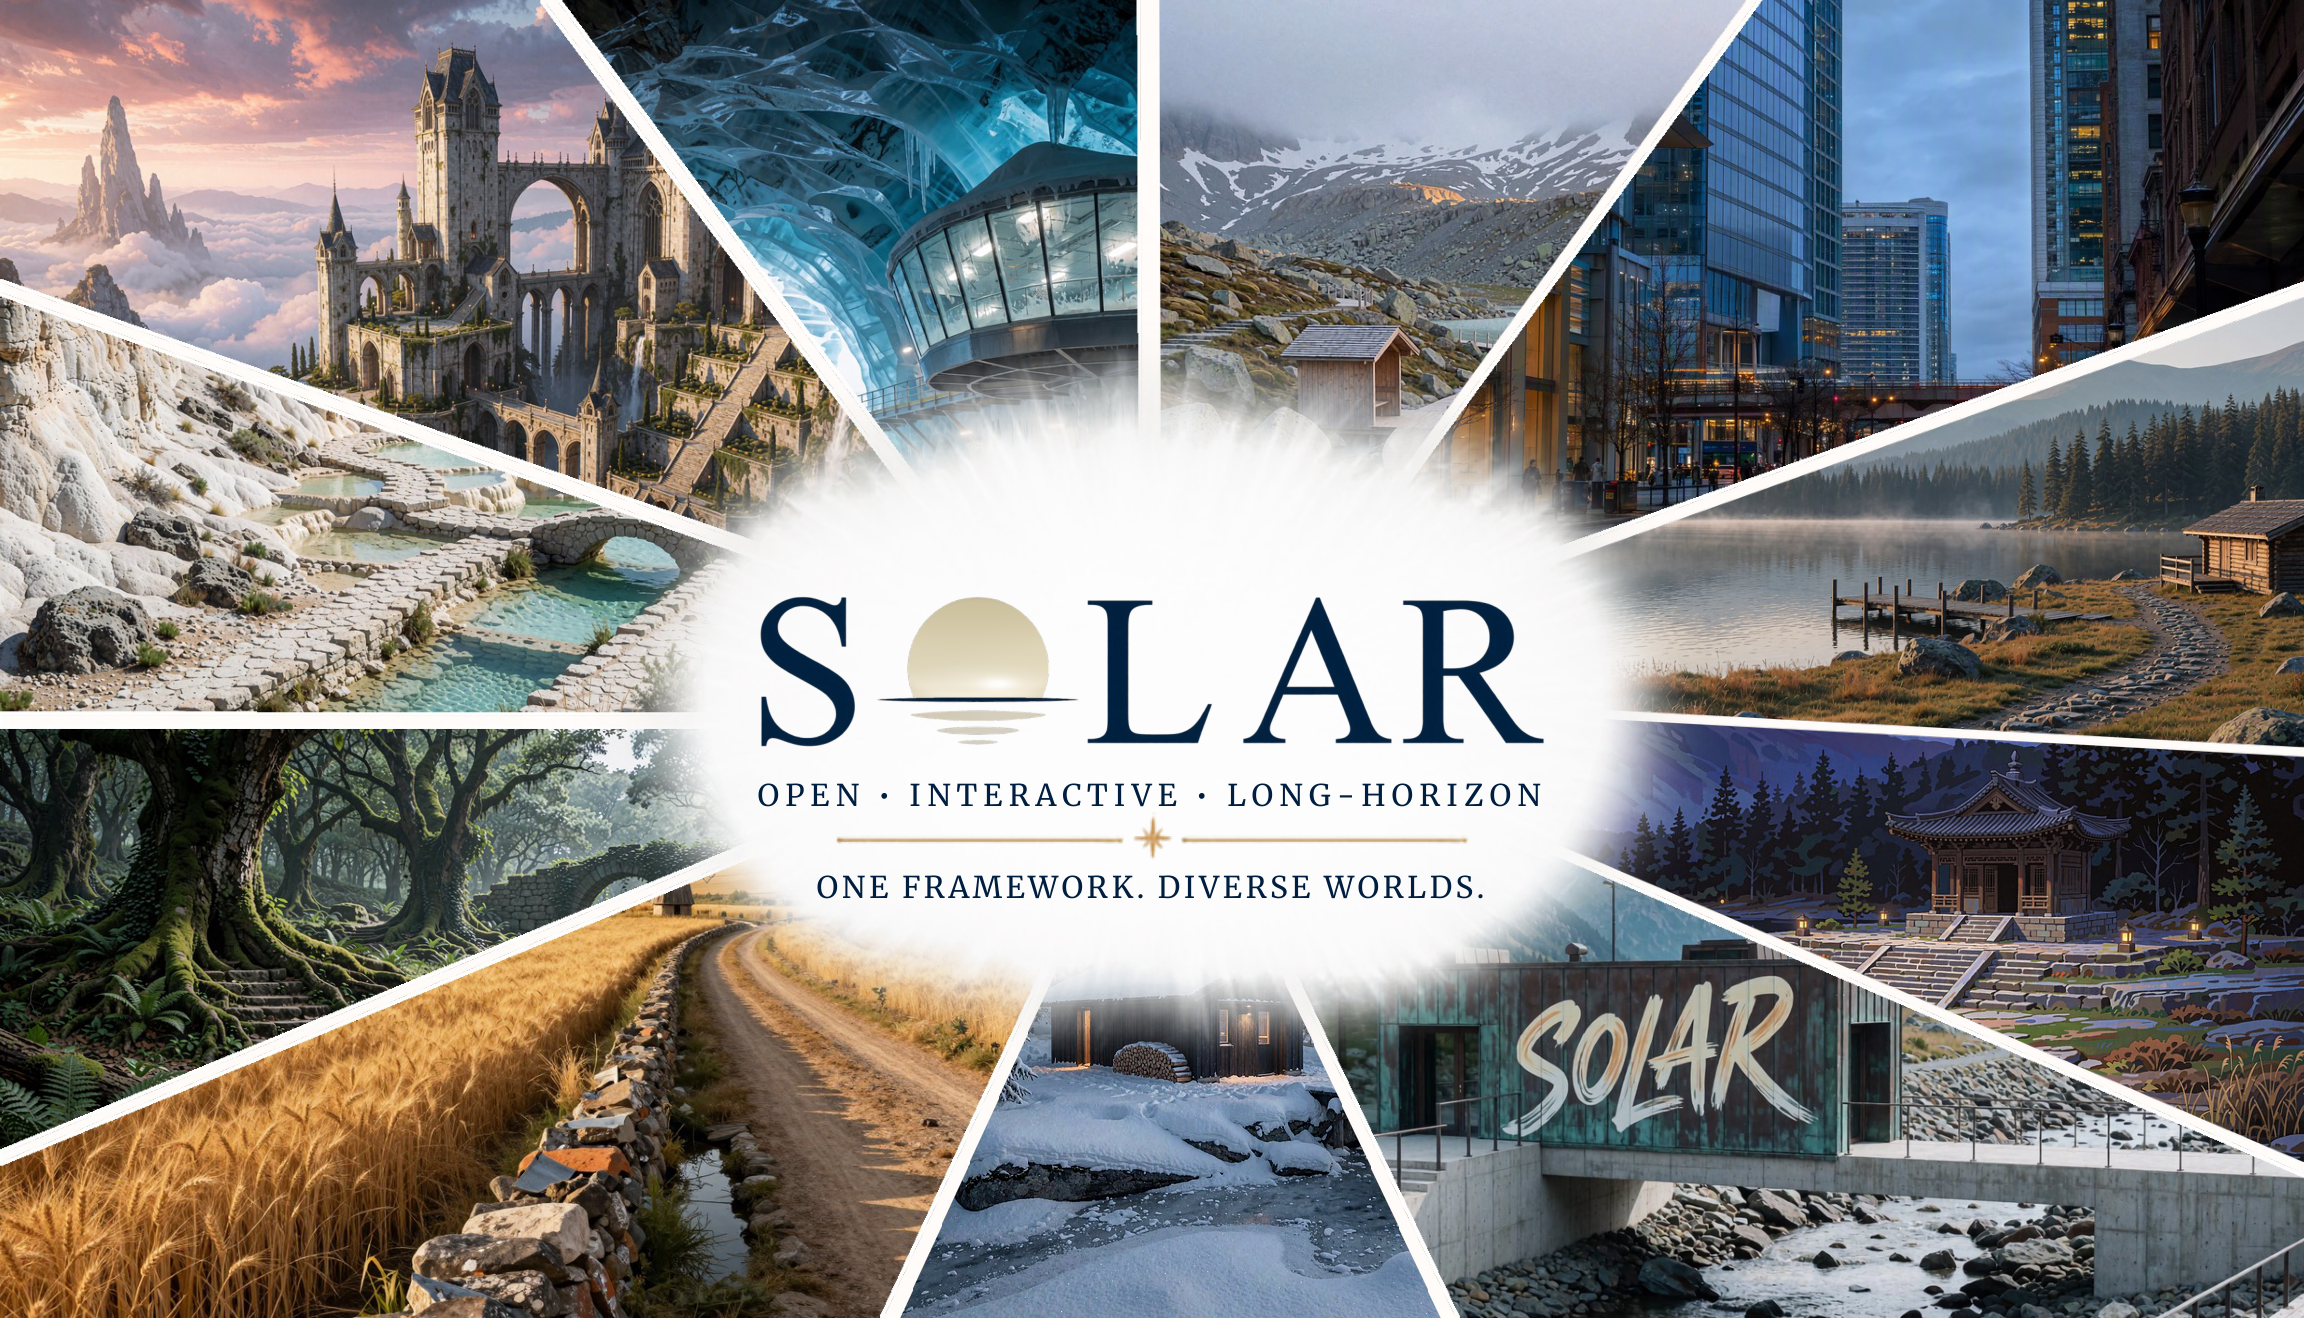
SolarWM
778Junchao-cs/SolarWM · PythonSolarWM is a fully open foundation for building interactive video world models, covering data preparation, scalable multi-backbone training, and long-horizon inference.
- 35
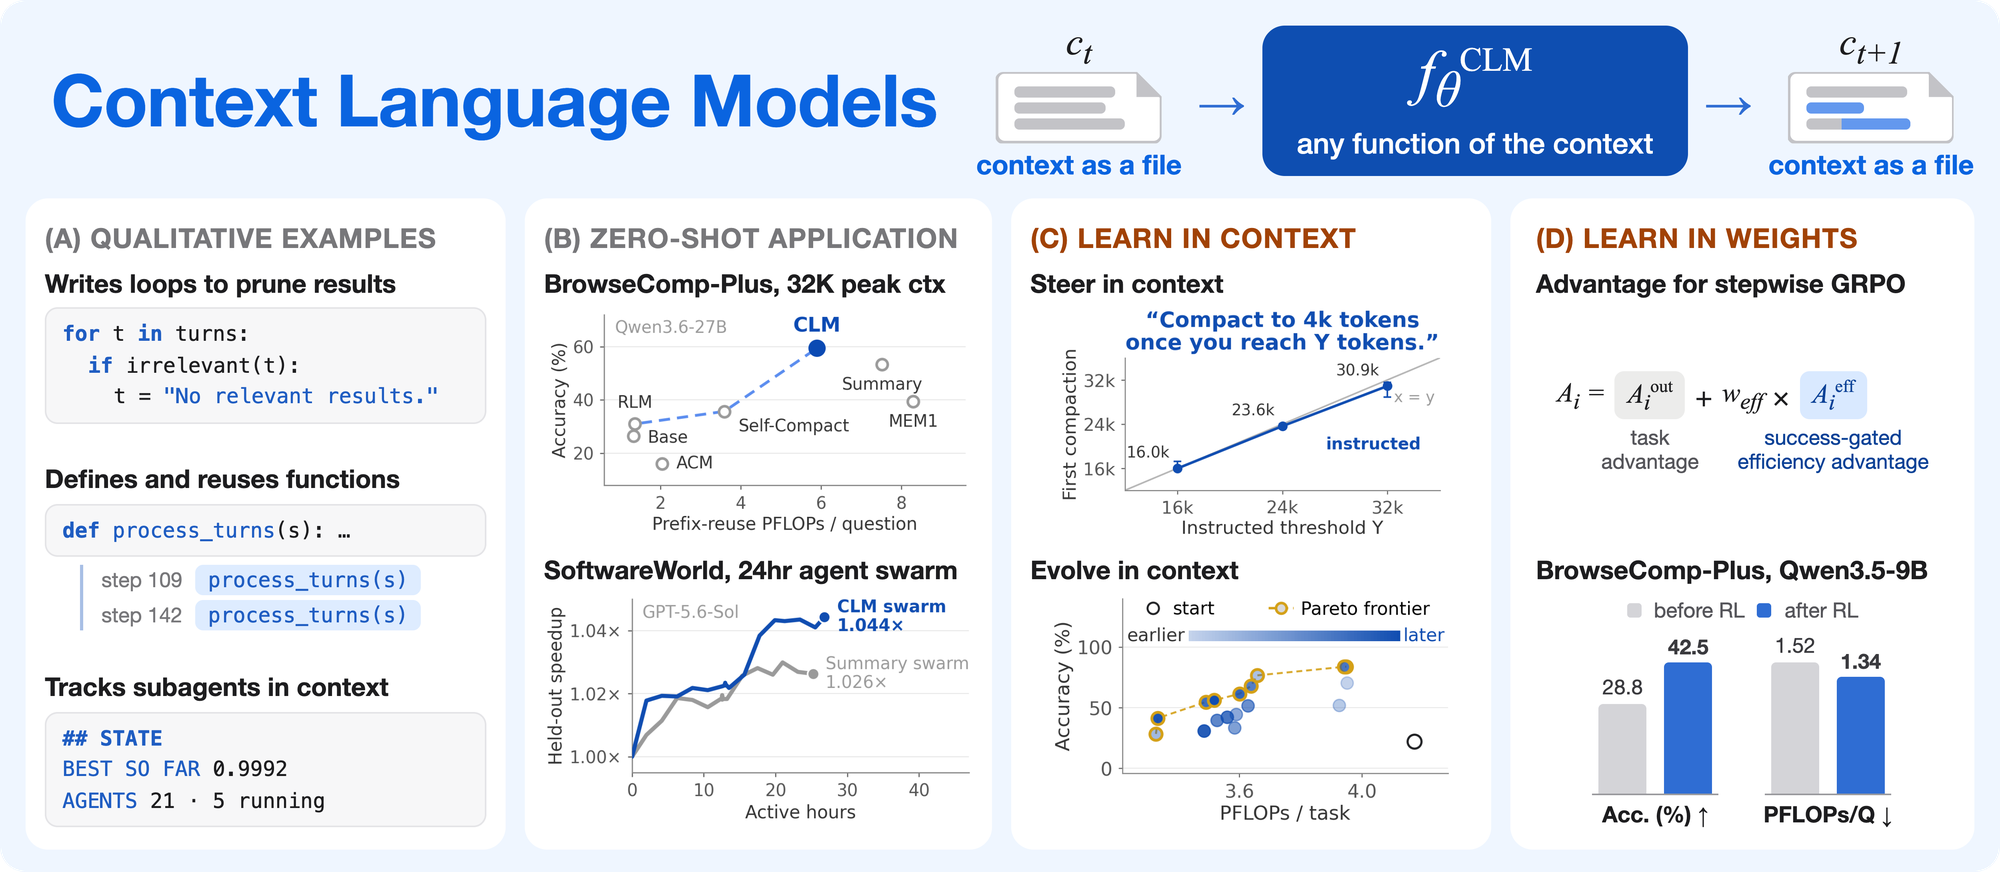
context-language-models
736facebookresearch/context-language-models · PythonThis is the official code release for 'Context Language Models (CLMs)', research from University of Washington, Meta Superintelligence Labs, MIT and Trillium Labs. CLMs are language models that natively manage their own context by treating it as a file they can freely edit, which naturally extends to multi-agent setups where each agent's context is its own file.
- 36
StartLux-Decision
727StartLuxLabs/StartLux-Decision · PythonStartLux-Decision is a family of typed decision models (five dense sizes from 0.8B to 27B plus a 35B-A3B mixture-of-experts) that answer a question with a probability for each option instead of generating text.
- 37
MOSS-Image
686OpenMOSS/MOSS-Image · PythonMOSS-Image is a 5-billion-parameter text-to-image diffusion transformer (DiT) model built for strong text rendering, JSON-based layout control over where text and objects go, and efficient fine-tuning (including LoRA) on custom tasks.
- 38
Qwen-Drive-1.0
517QwenLM/Qwen-Drive-1.0 · PythonQwen-Drive-1.0 is a vision-language foundation model for autonomous driving, built on the Qwen3.5-4B VLM and extended with 3D perception, visual question answering, and motion planning in one unified model.
- 39
LongCat-Next
477meituan-longcat/LongCat-Next · PythonLongCat-Next is a native multimodal foundation model from Meituan that processes text, vision, and audio under a single autoregressive objective using discrete tokens, built on the LongCat-Flash-Lite MoE backbone (A3B).
- 40
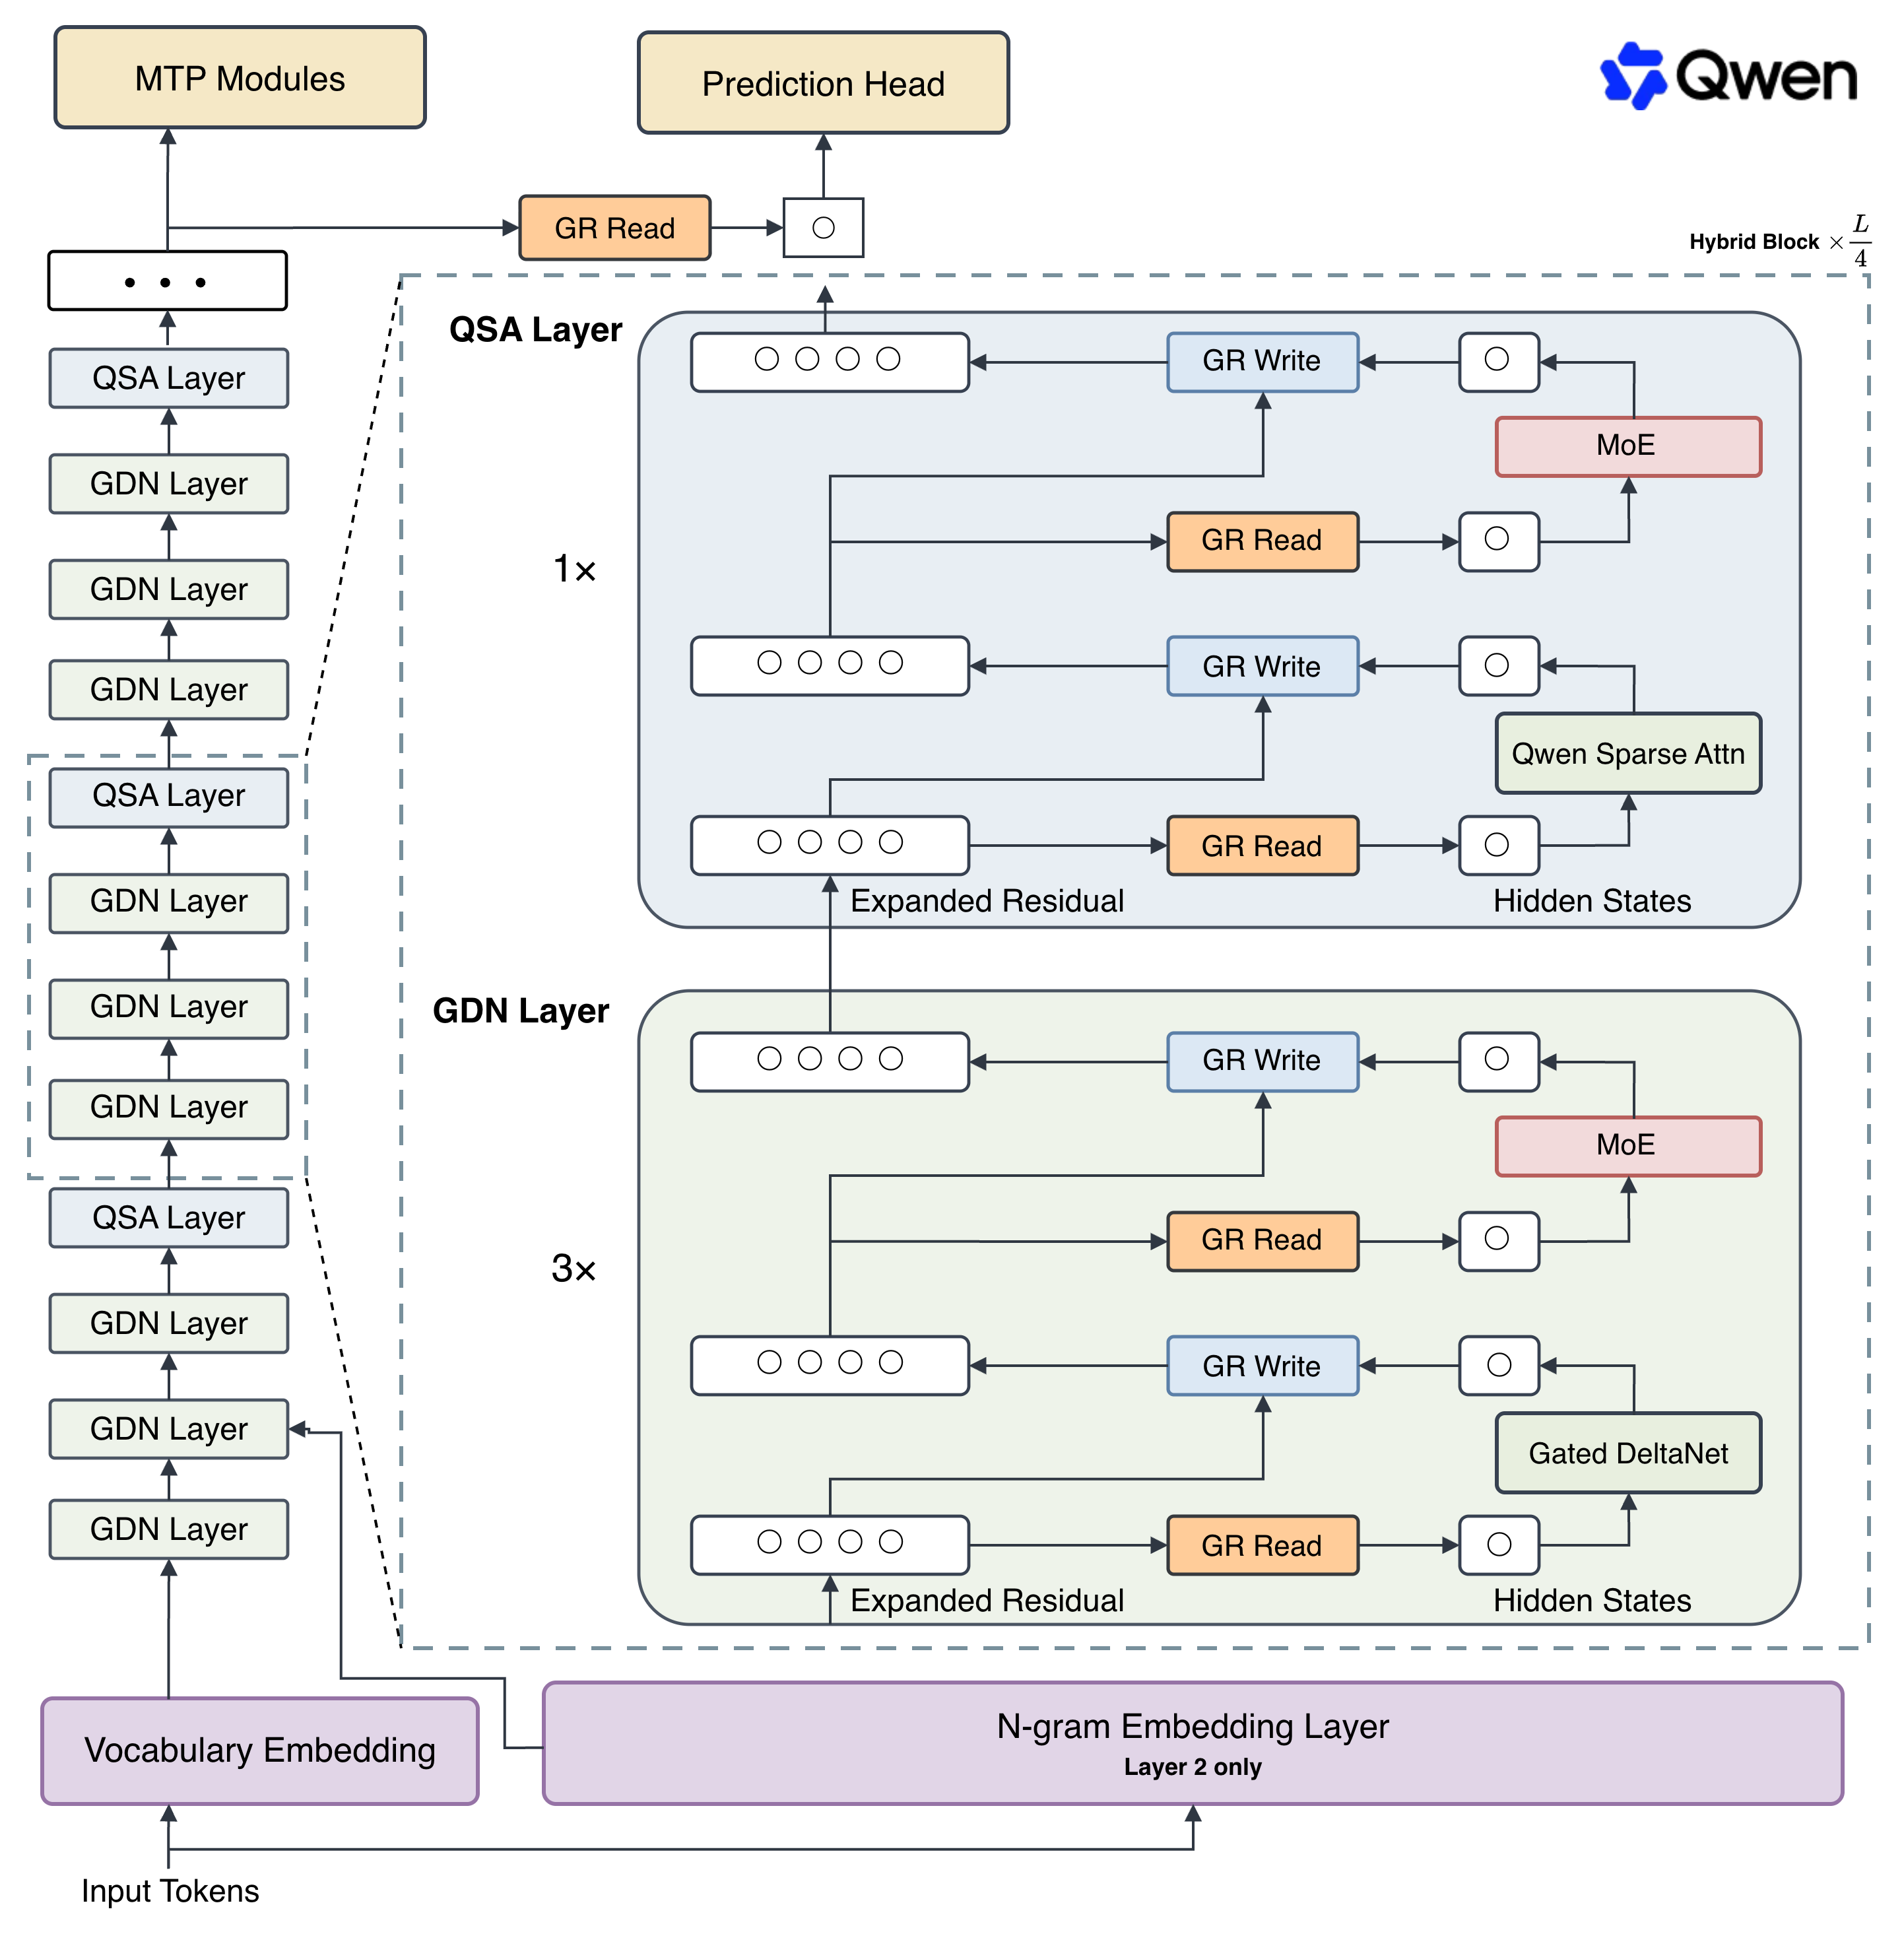
Qwen3.8-Flash-Next
434QwenLM/Qwen3.8-Flash-NextQwen3.8-Flash-Next is an open-weight multimodal Mixture-of-Experts foundation model from Alibaba's Qwen Team, also serving as an early preview of the architecture Alibaba plans to use for the upcoming Qwen4 model family.
- 41
EasyWAM
403OpenMOSS/EasyWAM · PythonEasyWAM is a unified research codebase for training, fine-tuning, and evaluating World Action Models (WAMs) — models that jointly predict future video and robot actions for embodied-AI and robotics research.
- 42
Hy4-preview
396Tencent-Hunyuan/Hy4-preview · PythonHy4 preview is Tencent Hunyuan's newest open-source large language model, a 770B-parameter Mixture-of-Experts model (49B active per token) built for coding, office/data analysis, game development, and scientific research tasks.
- 43
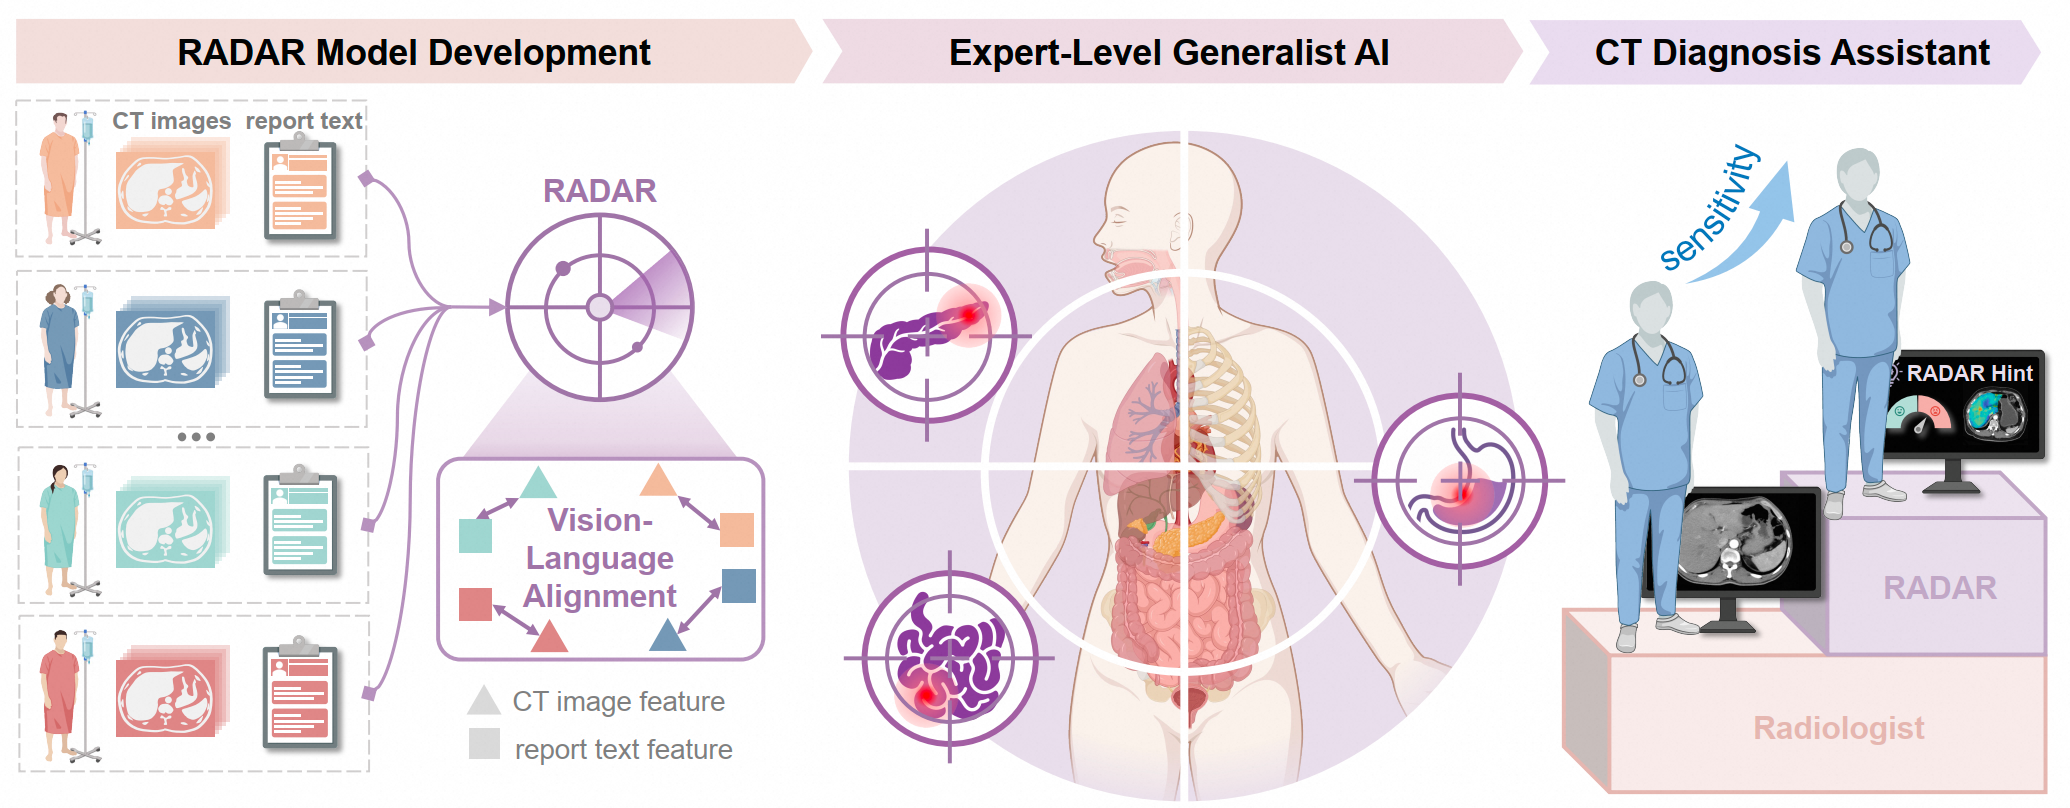
damo-radar
207alibaba-damo-academy/damo-radar · PythonRADAR is a generalist vision-language AI model for abdominal CT diagnosis, trained on over 400,000 contrast-enhanced abdominal CT exams with 15 million anatomy-aware image-text pairs derived directly from clinical reports.
- 44

timeseries-atlas
133dreamers-laboratory/timeseries-atlas · PythonA curated map of modern time-series forecasting architectures, from DLinear to foundation models like Chronos-2, each in its own directory with a short README and, for some, a runnable PyTorch implementation.
Related topics
Often tagged together
- python2,425
- deep-learning746
- machine-learning930
- gpu809
- research779
- huggingface367
- pytorch421
- ai1,993
- transformer214
- linux4,248
- open-source5,749
- benchmark444
- cuda401
- computer-vision393
- apache-2.01,452
- llm1,516
- multimodal190
- inference331
- generative-ai353
- fine-tuning188
- large-language-models218
- macos3,608
- nvidia339
- academic-research220