Topics / #gradio
Gradio projects on GitHub
Quick web UIs for demoing machine learning models with Gradio.
As of , the most-starred Gradio projects on GitHub are stable-diffusion-webui (165.1K stars), textgen (47.7K stars) and gradio (43.8K stars). GitHub.Locker tracks 63 Gradio repositories with 1.2M stars combined. The fastest-growing on October 18 was MOSS-Image, with +282 stars in a day.
Hot right now
Most stars gained in a day · Oct 18
 +282
MOSS-Image
OpenMOSS/MOSS-Image · ★ 686MOSS-Image is a 5-billion-parameter text-to-image diffusion transformer (DiT) model built for strong text rendering, JSON-based layout control over where text and objects go, and efficient fine-tuning (including LoRA) on custom tasks.
 +128
voice-pro
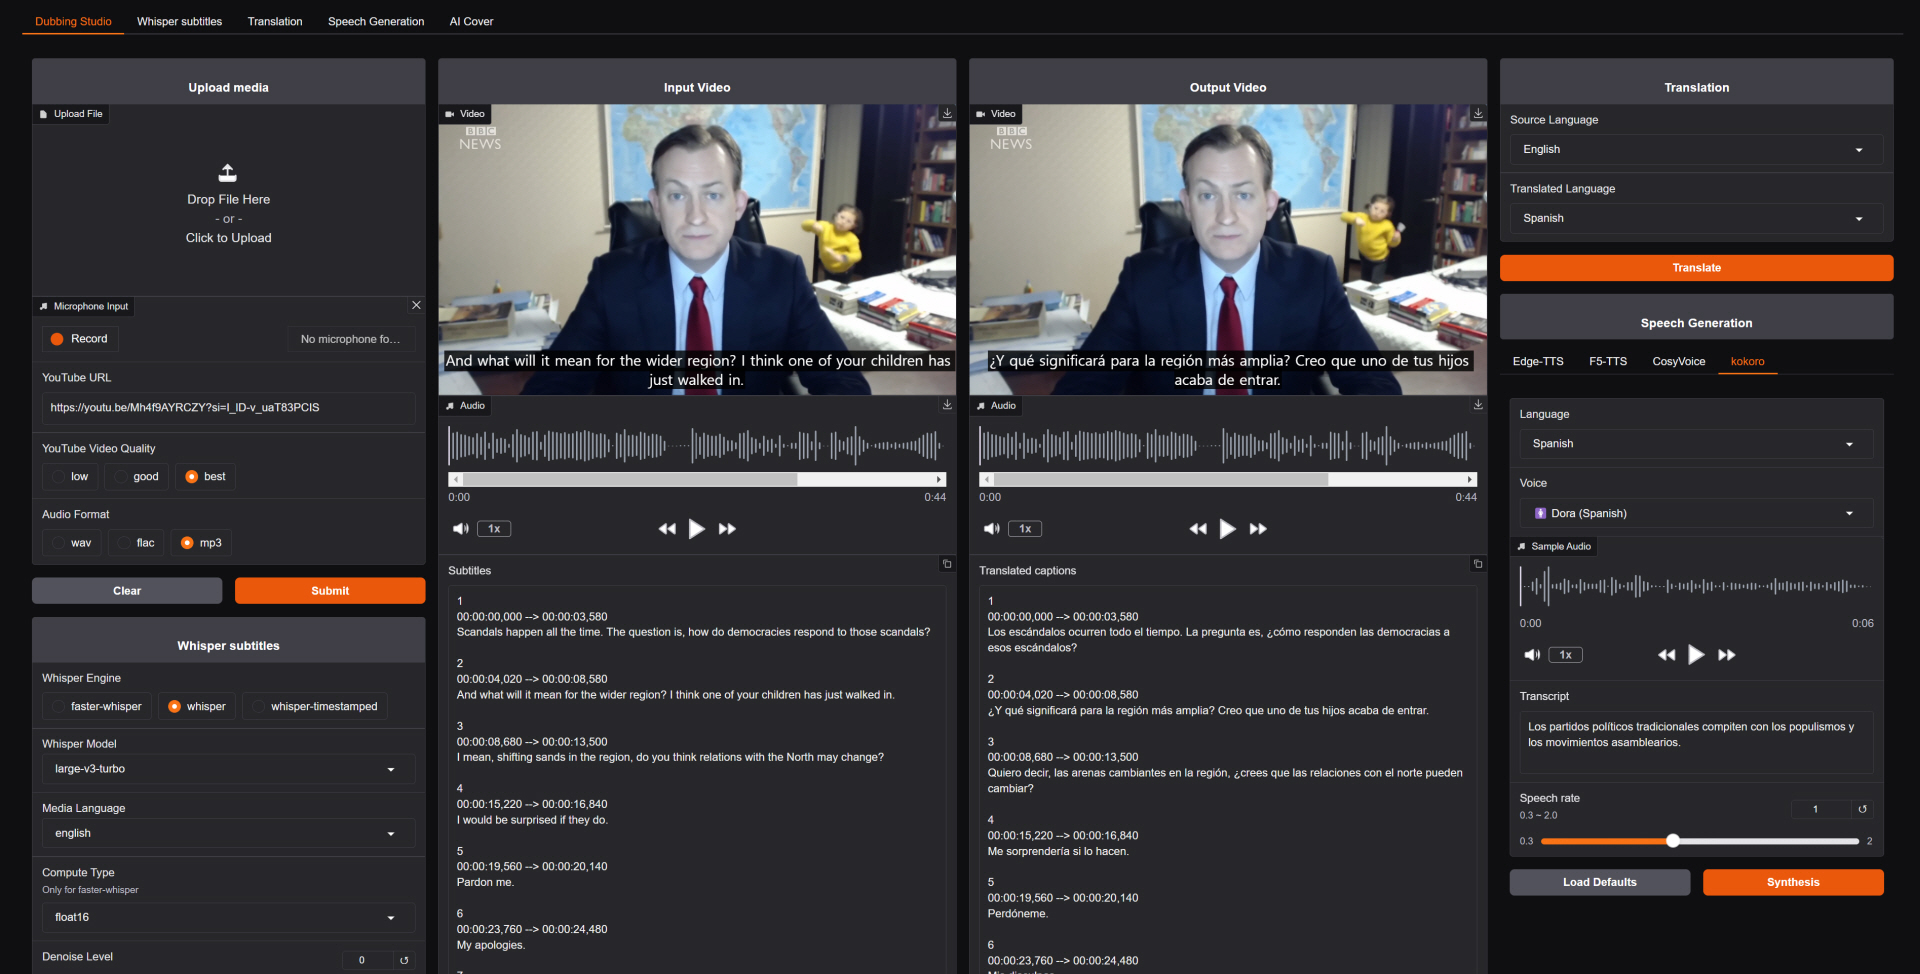
abus-aikorea/voice-pro · ★ 13.2KVoice-Pro is a free, open-source AI web app (built with Gradio) that combines speech recognition, zero-shot voice cloning, text-to-speech, YouTube downloading, vocal isolation, and multilingual translation into one tool for creators and researchers.
 +95
WanGP
deepbeepmeep/WanGP · ★ 10.7KWanGP is a one-stop open source app for running top generative AI models for video, image, and audio/TTS generation, built specifically to work on modest consumer GPUs (the 'GPU Poor').
 +66
PaperBanana
dwzhu-pku/PaperBanana · ★ 7.2KPaperBanana is an open-source framework that turns raw scientific content into publication-quality diagrams and plots, acting like a creative team of five specialized agents: Retriever, Planner, Stylist, Visualizer and Critic.
The all-time top
63 projects · by stars
- 165.1K
 #1 · AUTOMATIC1111/stable-diffusion-webui
stable-diffusion-webui
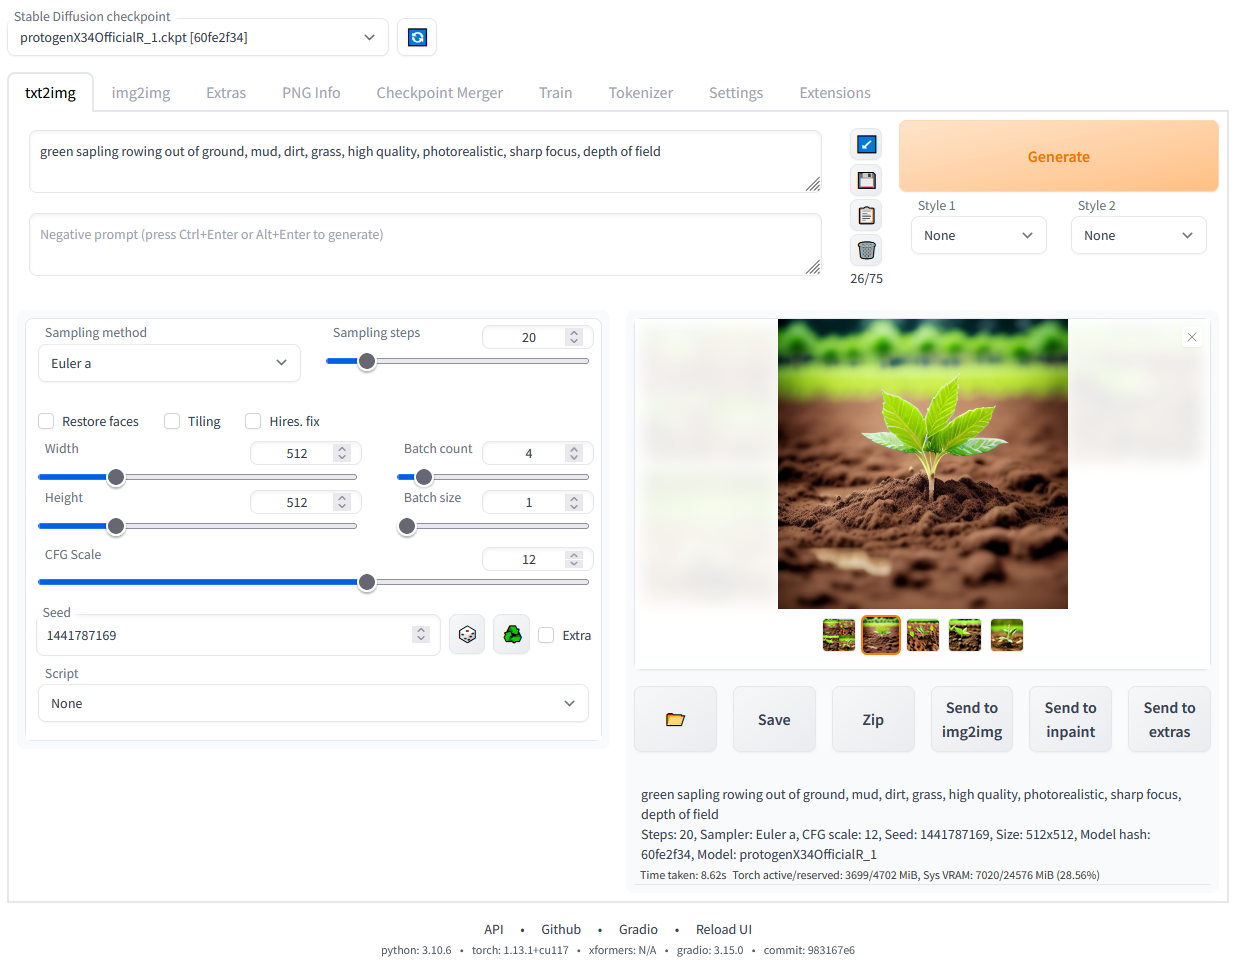
A browser-based interface for Stable Diffusion, built with the Gradio library, letting you generate and edit AI images (txt2img, img2img, inpainting, outpainting and more) on your own machine.
- 47.7K
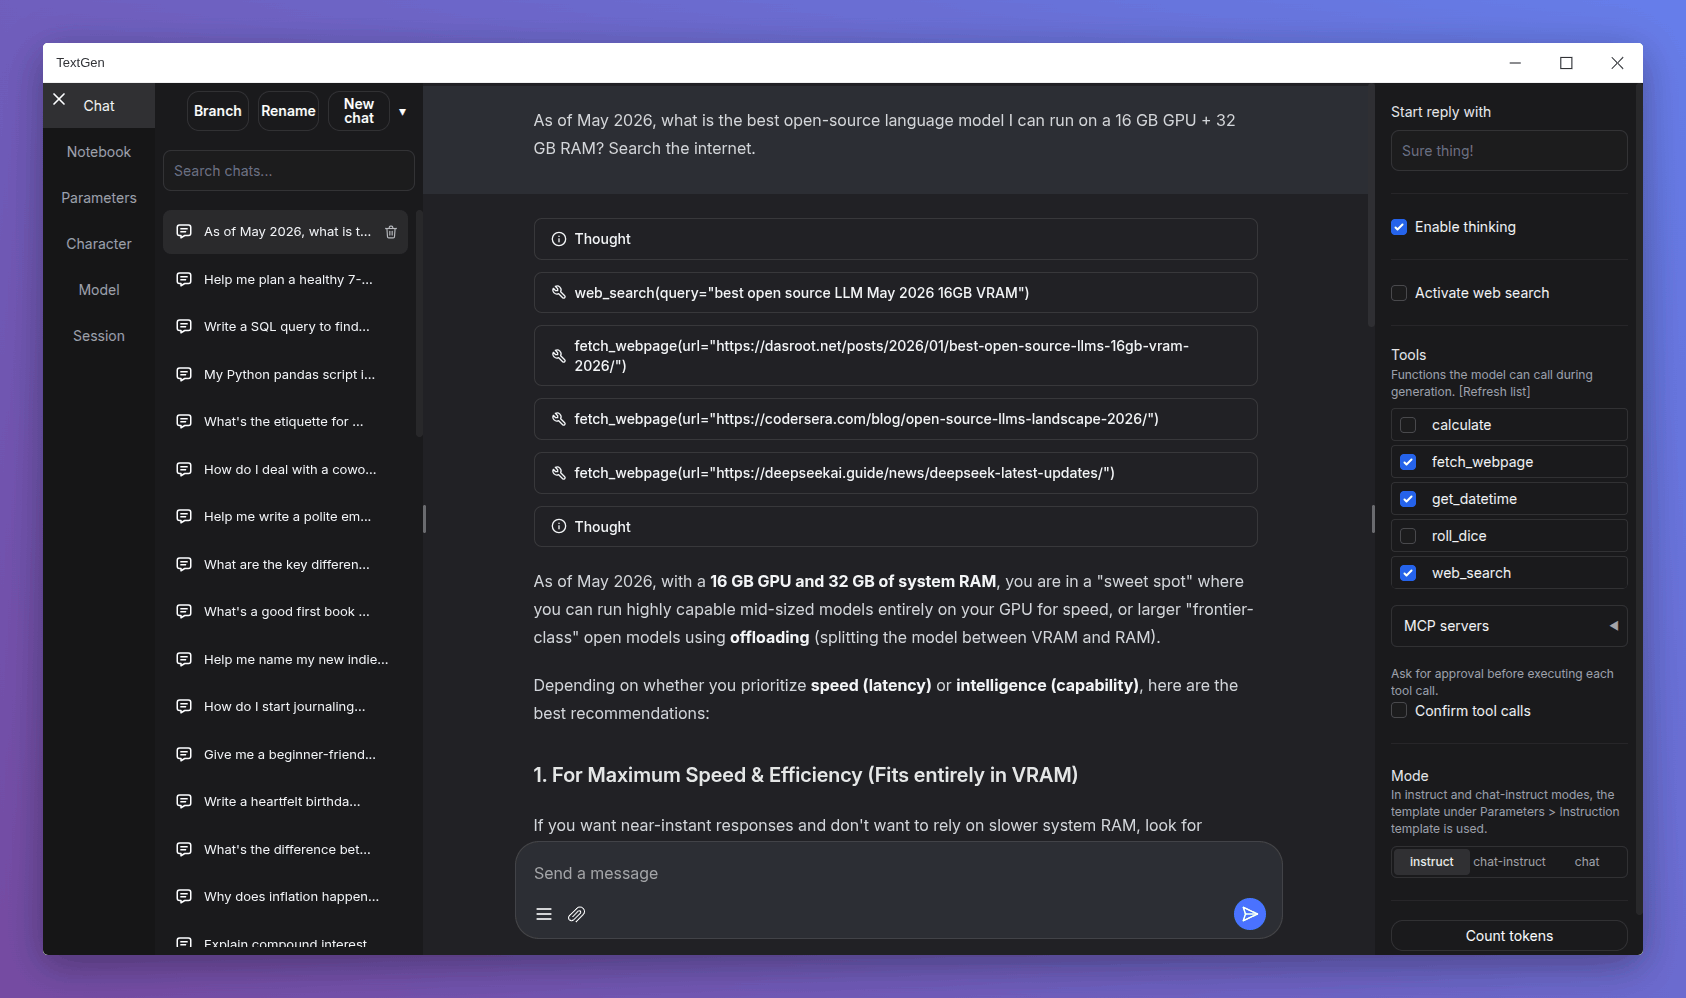 #2 · oobabooga/textgen
textgen
TextGen is an open-source desktop app for running local LLMs with text, vision, tool-calling, and an OpenAI/Anthropic-compatible API, built to be 100% private with no telemetry.
- 43.8K
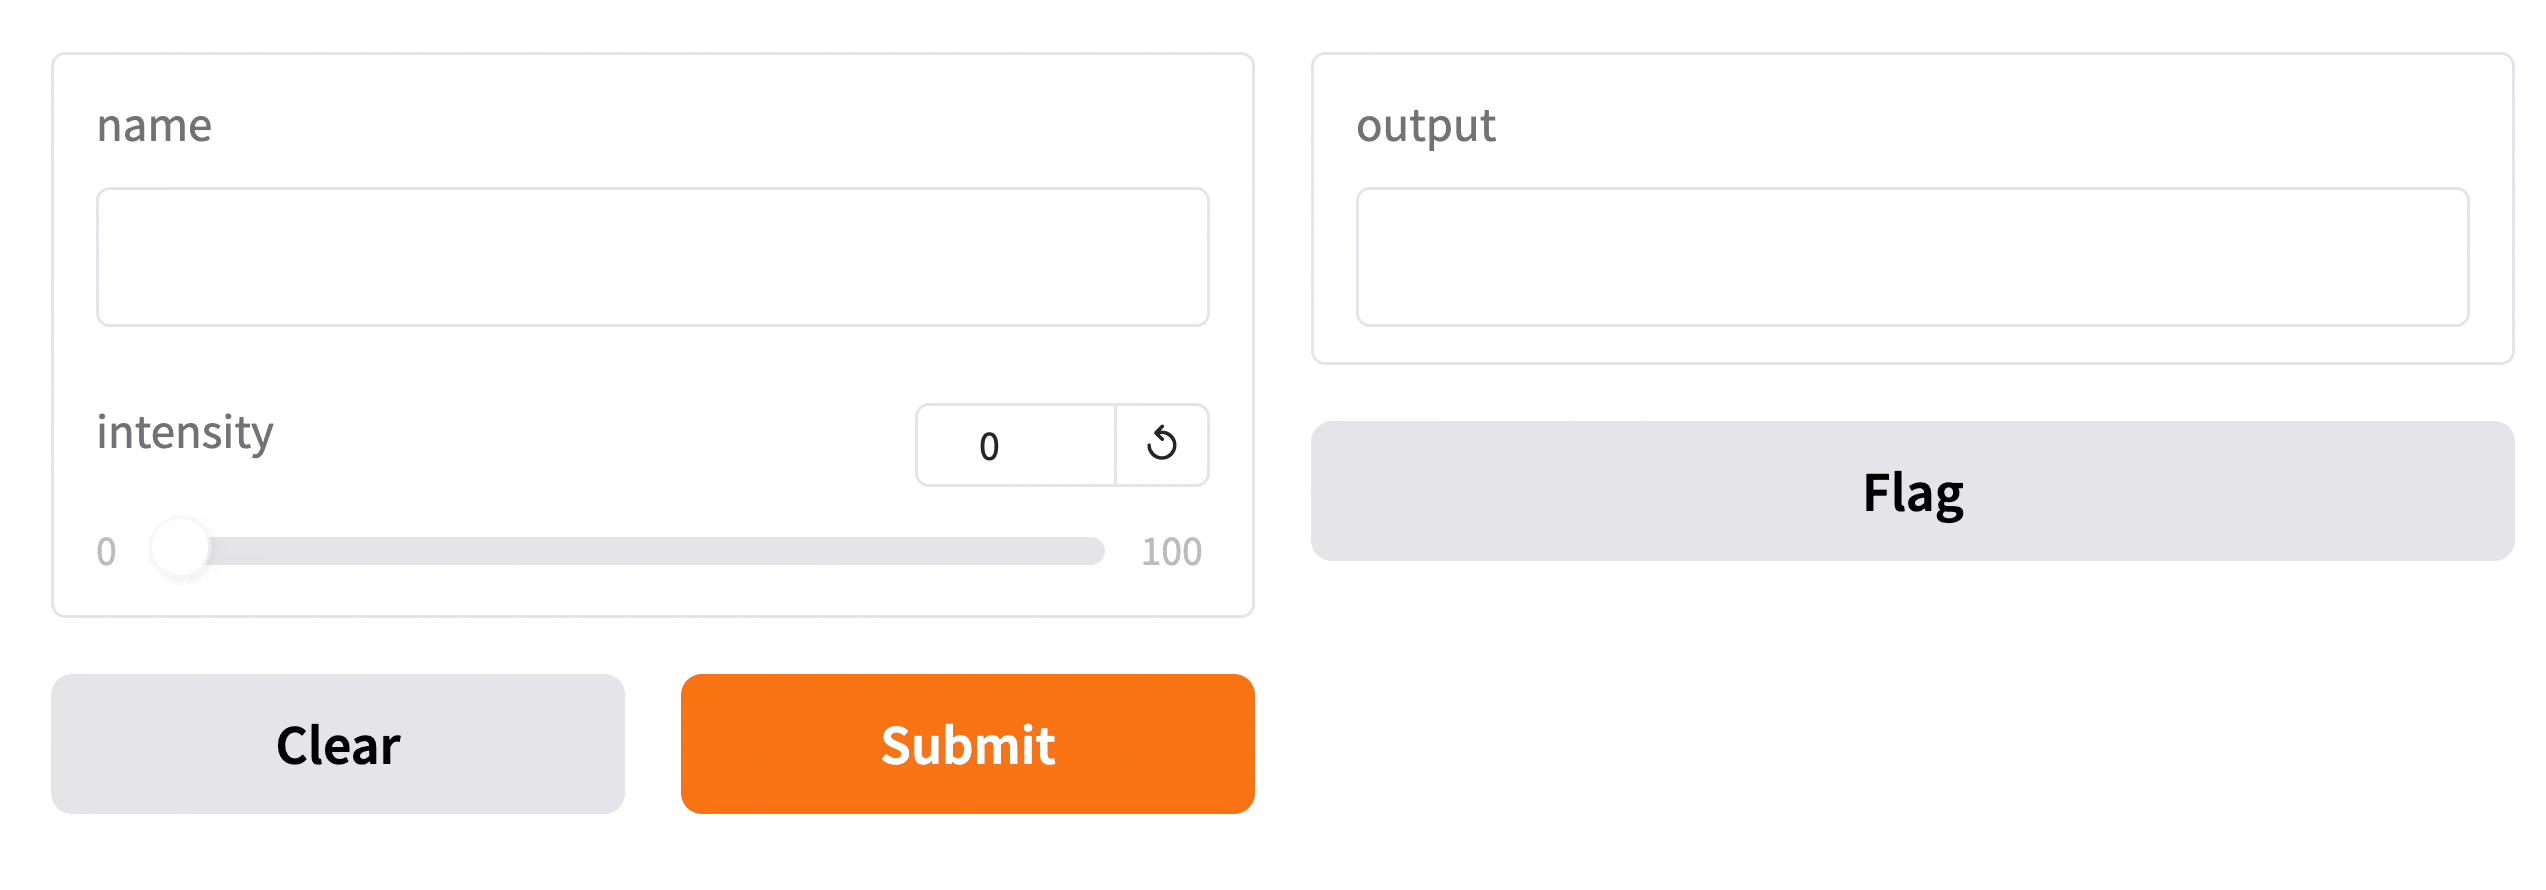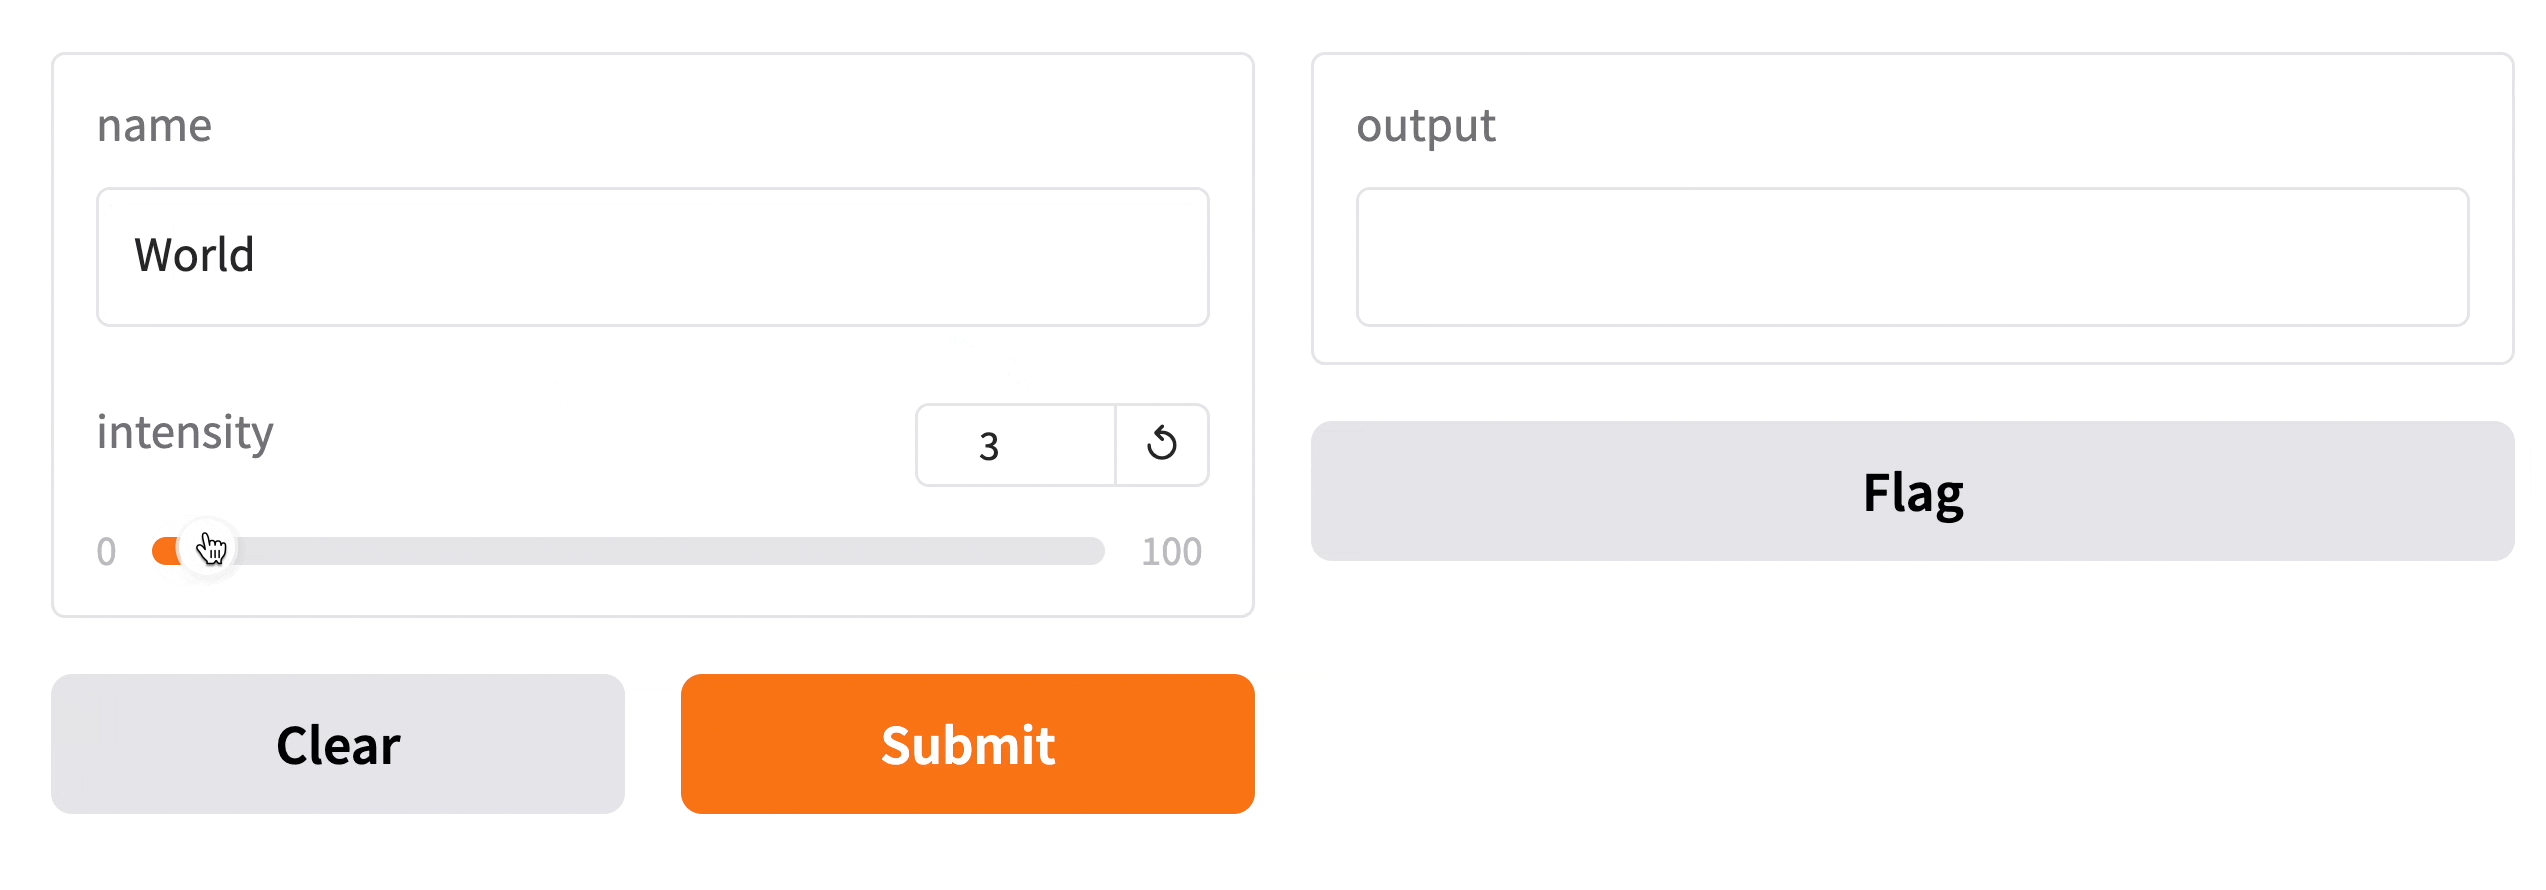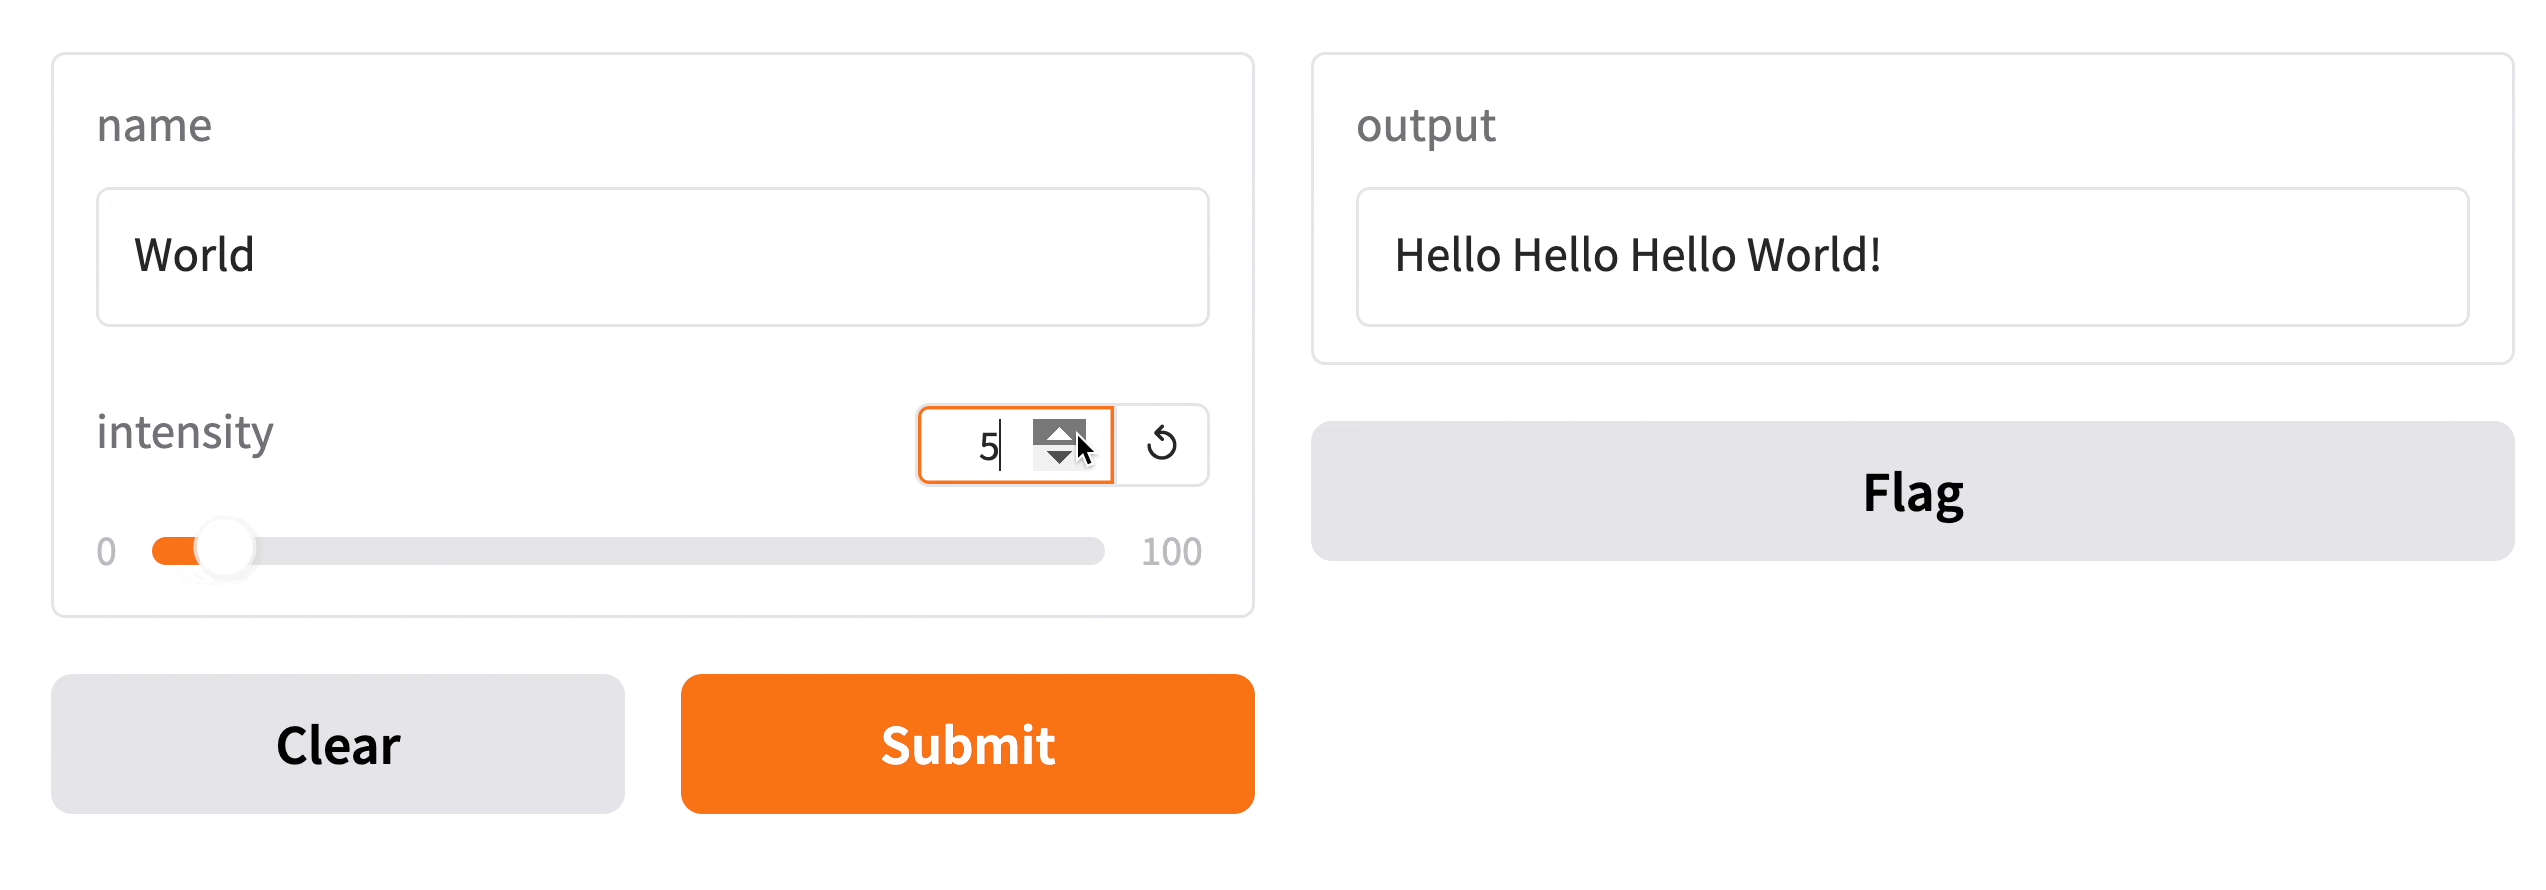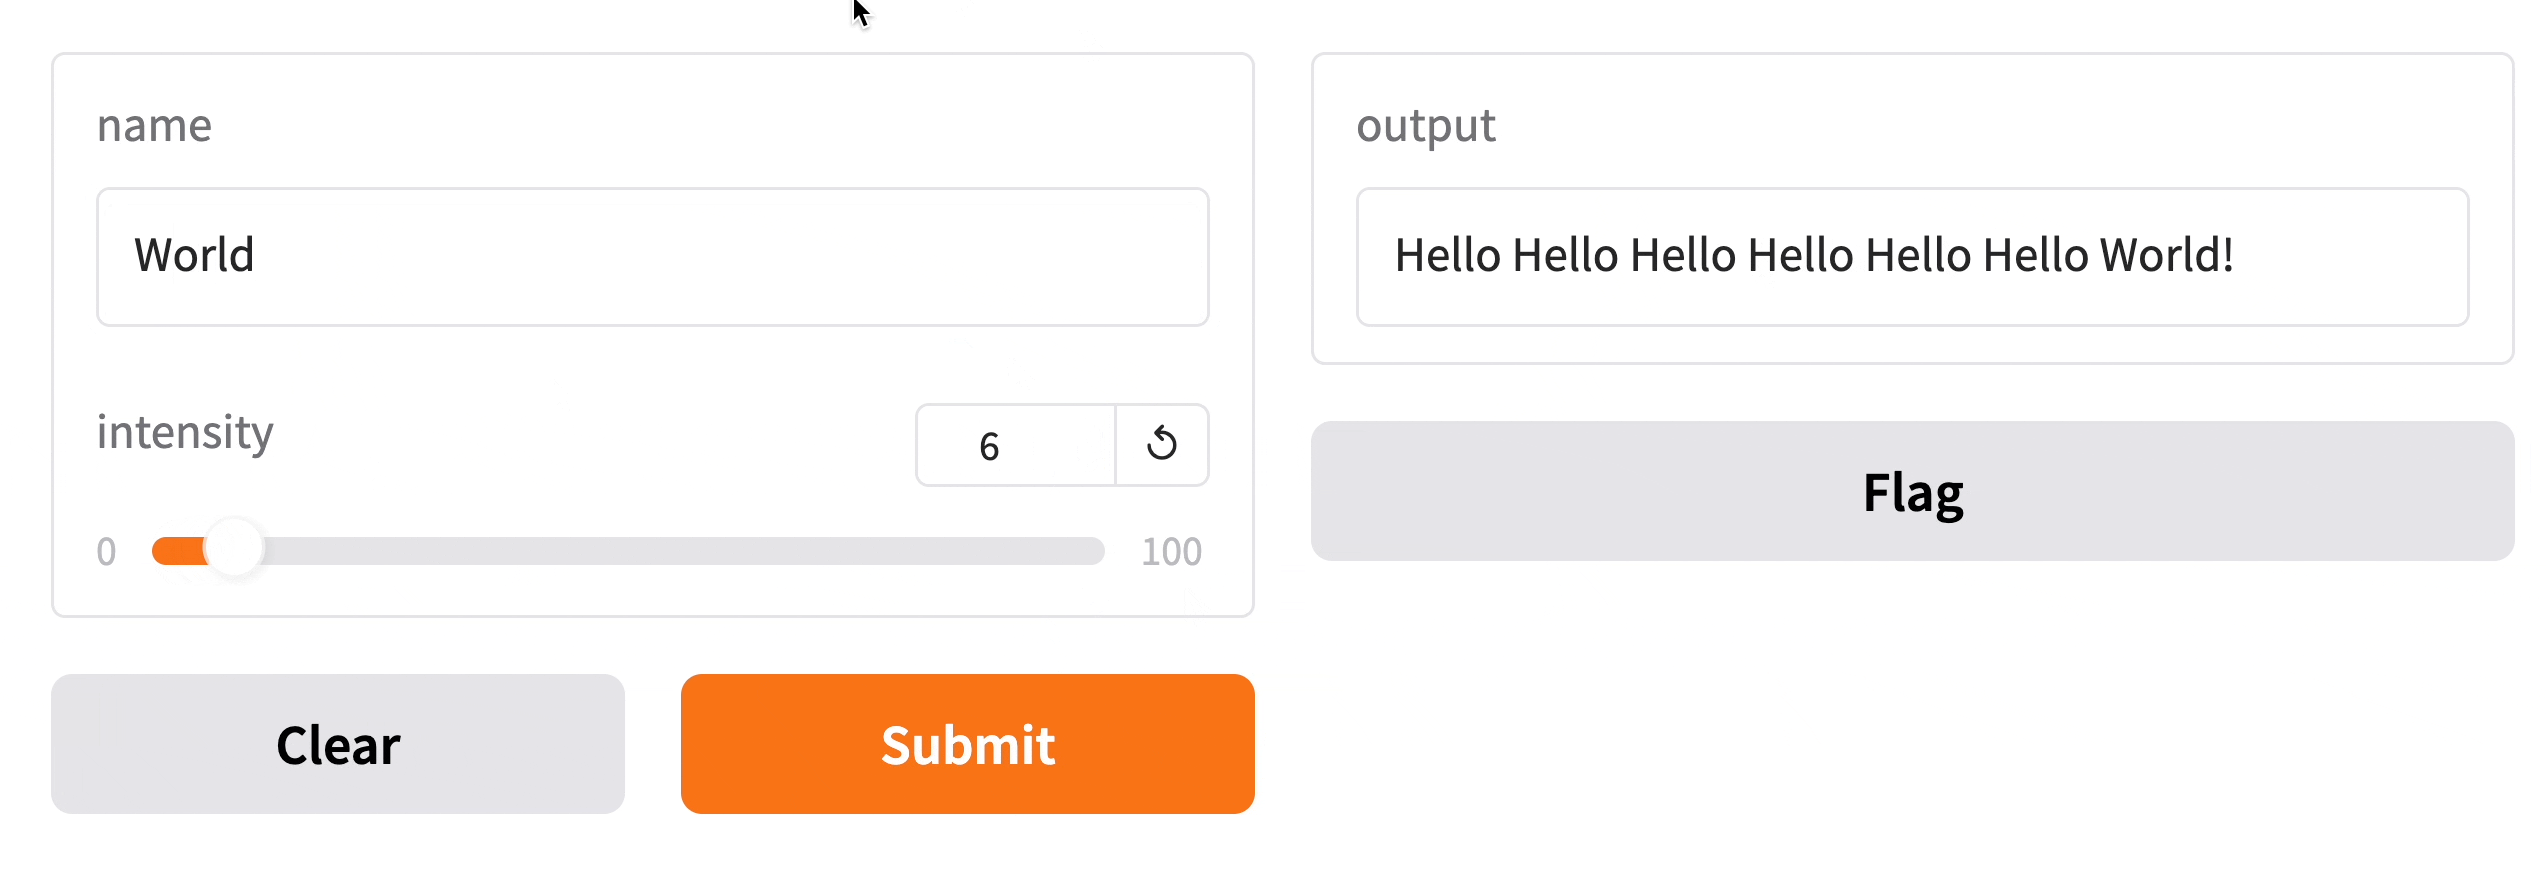 #3 · gradio-app/gradio
gradio
Gradio is an open-source Python package that turns machine learning models, APIs, or any arbitrary Python function into a shareable demo or web app in just a few lines of Python.
- 4
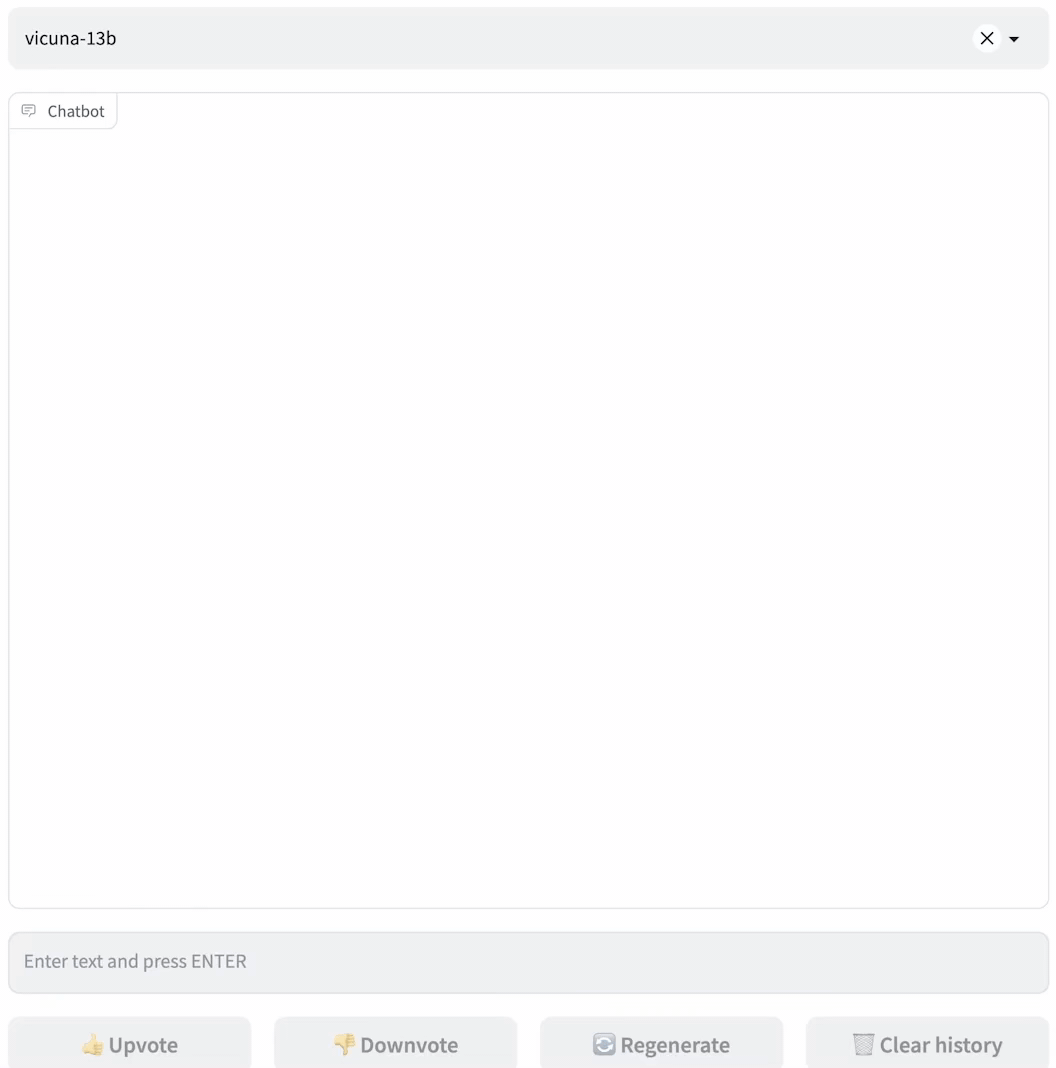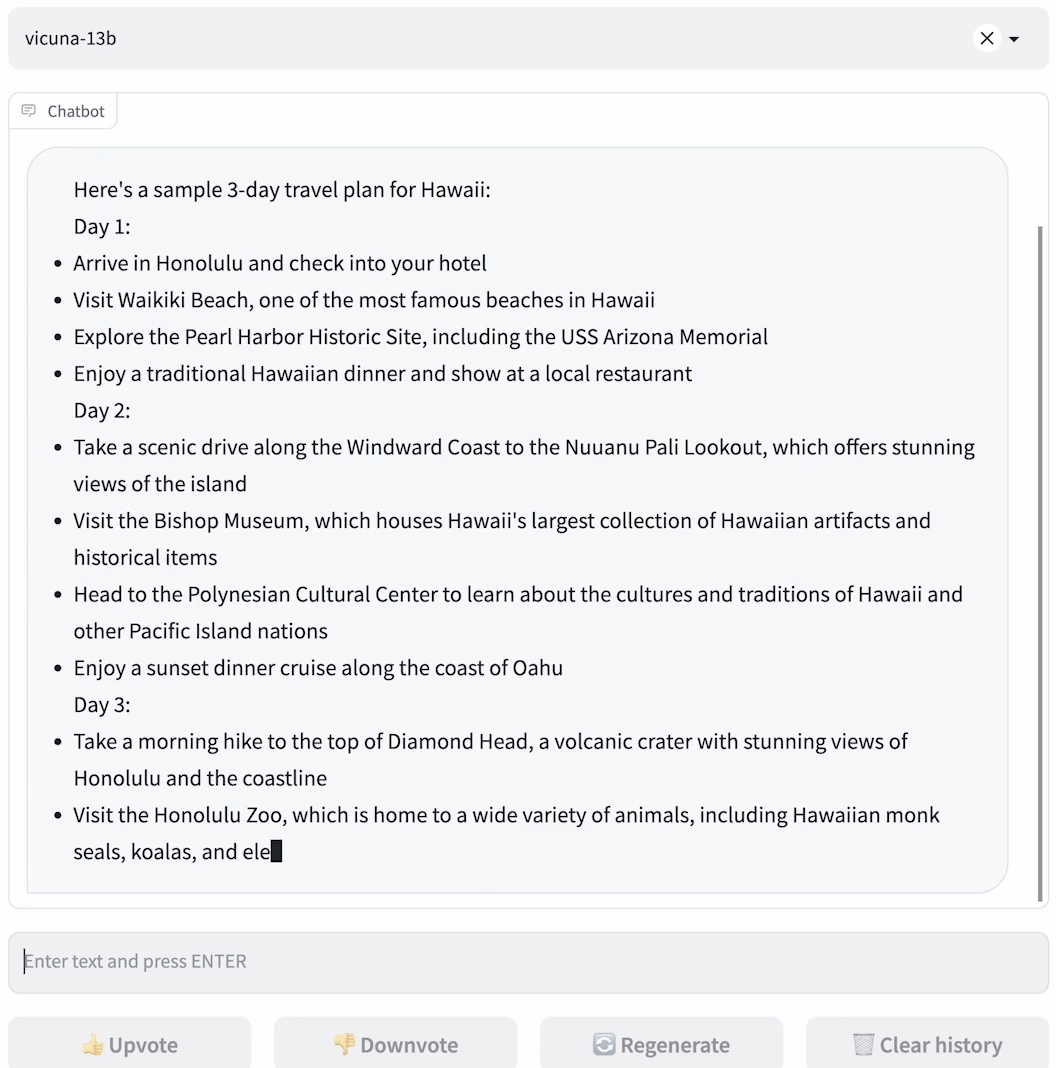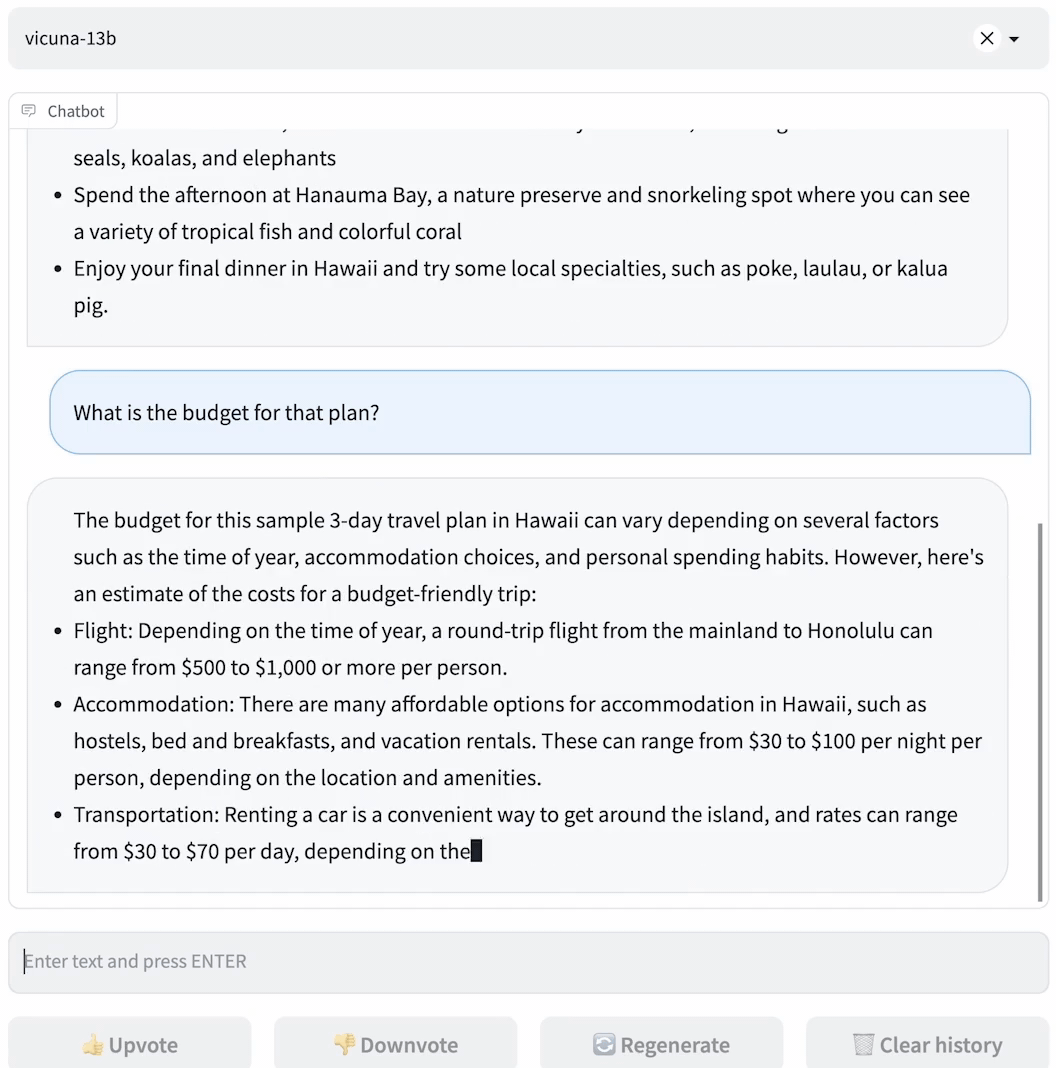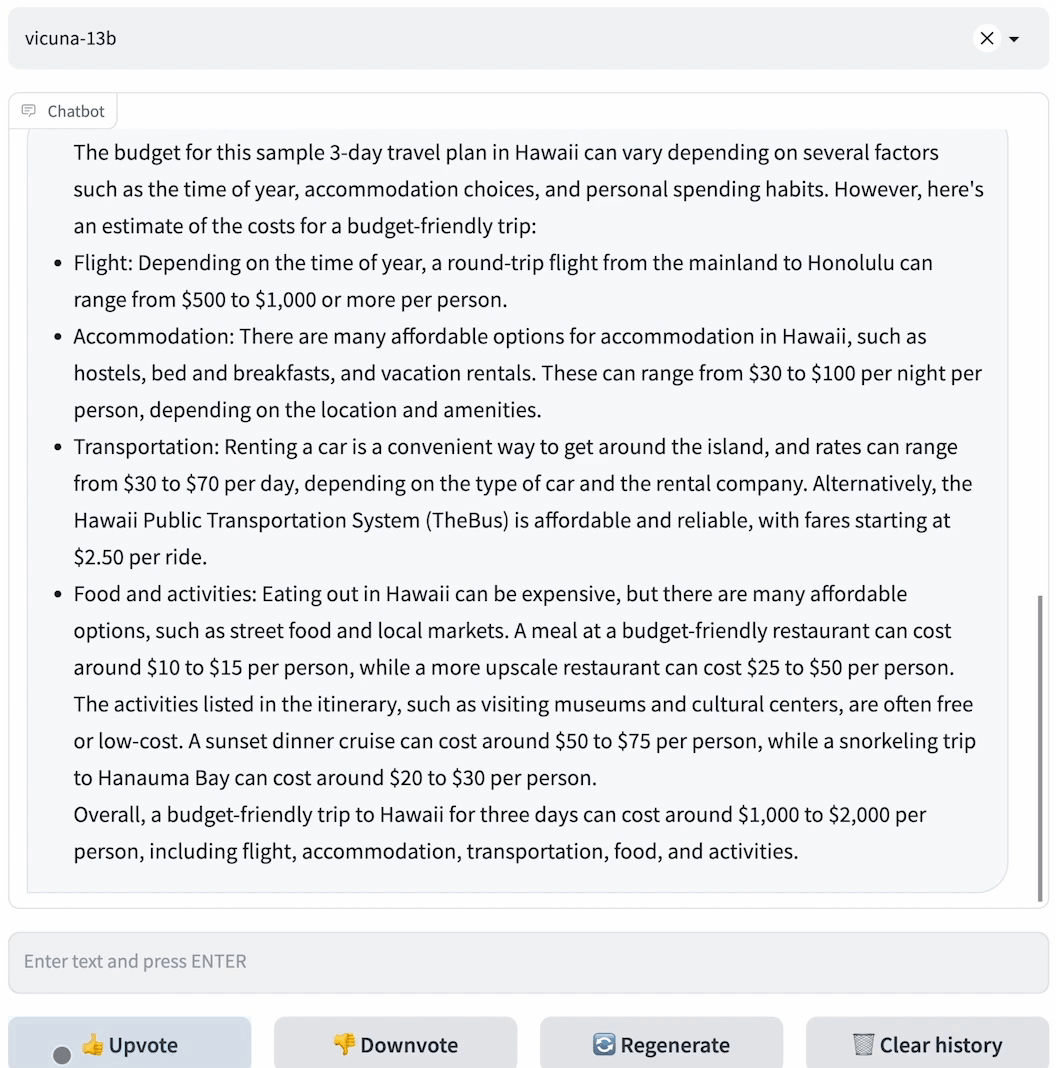
FastChat
39.5Klm-sys/FastChat · PythonFastChat is an open platform for training, serving, and evaluating large language model based chatbots. It is the release repo for Vicuna and powers Chatbot Arena (lmarena.ai), which has served over 10 million chat requests for 70+ LLMs.
- 5
Retrieval-based-Voice-Conversion-WebUI
38.8KRVC-Project/Retrieval-based-Voice-Conversion-WebUI · PythonRVC WebUI is a web-based tool for training and running voice conversion (voice-changing) models, letting you clone a target voice's timbre using as little as about 10 minutes of audio.
- 6
GFPGAN
37.7KTencentARC/GFPGAN · PythonGFPGAN is a practical algorithm for real-world blind face restoration: it rebuilds degraded or low-quality faces in photos using rich priors from a pretrained face GAN like StyleGAN2.
- 7
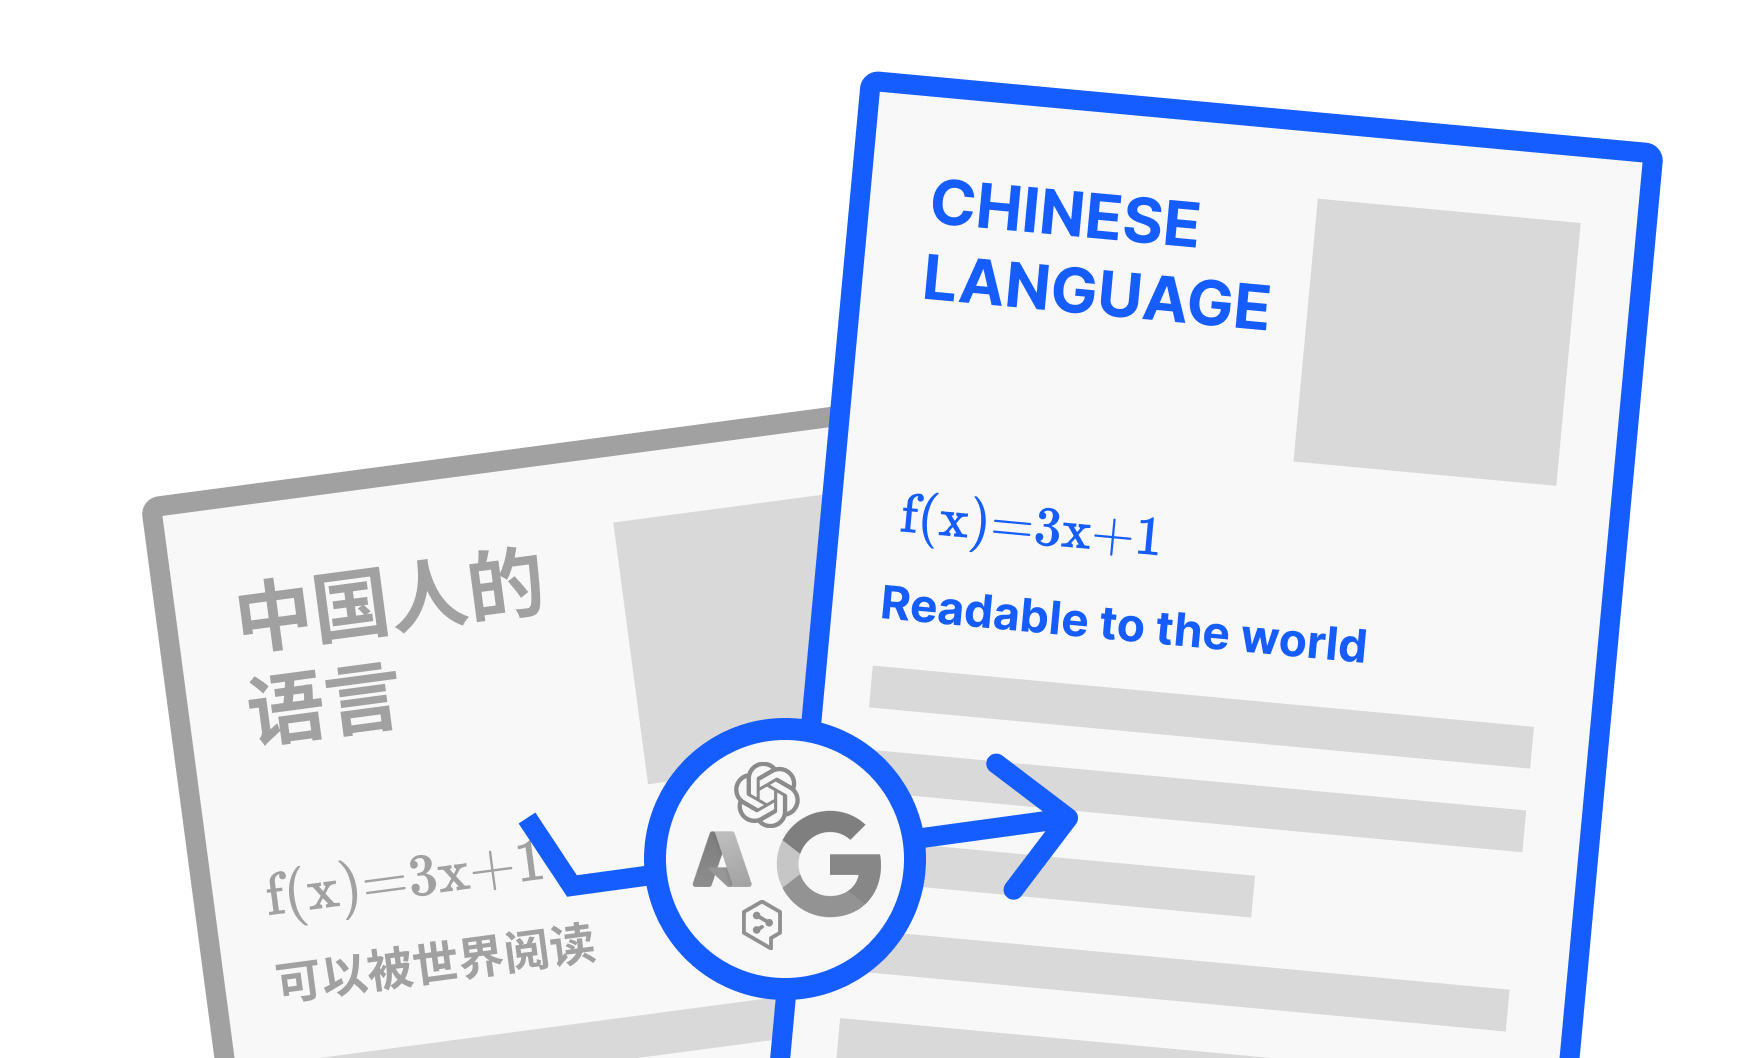
PDFMathTranslate
37.7KPDFMathTranslate/PDFMathTranslate · PythonIt translates scientific PDF papers into other languages while preserving the original layout - formulas, charts, table of contents and annotations stay in place. It was accepted as a demo at EMNLP 2025.
- 8
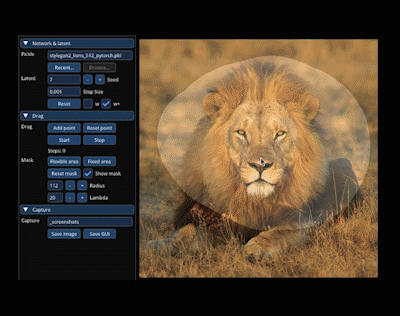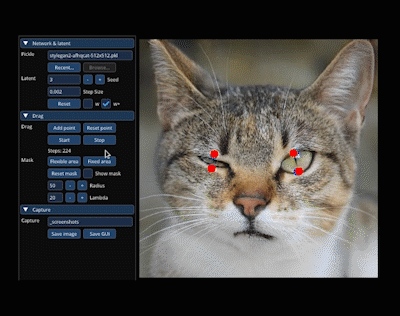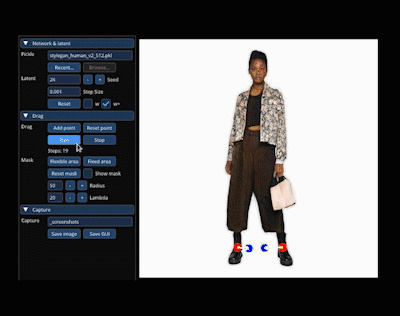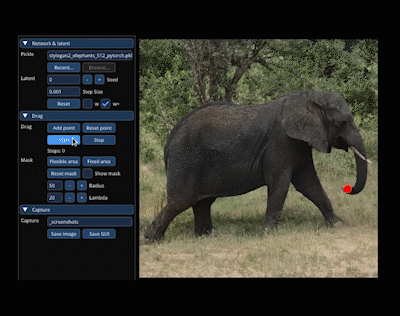
DragGAN
35.7KXingangPan/DragGAN · PythonDragGAN is the official implementation of the SIGGRAPH 2023 paper that lets you interactively drag points on a GAN-generated image to move or reshape objects within it.
- 9
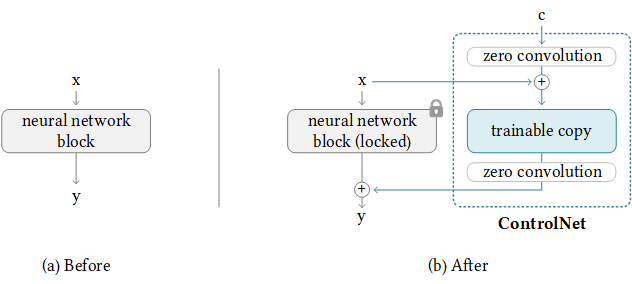
ControlNet
34.1Klllyasviel/ControlNet · PythonControlNet is a neural network structure that adds extra conditions to diffusion models like Stable Diffusion: instead of a text prompt alone, you steer generation with an edge map, depth map, pose skeleton or scribble. This repo is the official implementation.
- 10
Open-Sora
29.9Khpcaitech/Open-Sora · PythonOpen-Sora is an open-source initiative for efficiently producing high-quality video: it releases video generation models together with the tools, checkpoints and all training details.
- 11
OmniParser
25.5Kmicrosoft/OmniParser · Jupyter NotebookOmniParser parses GUI screenshots into structured, labeled elements (icons, text, interactable regions) so a vision model like GPT-4V can accurately decide what to click or type on a screen.
- 12
LLaVA
25.1Khaotian-liu/LLaVA · PythonLLaVA is an open-source large multimodal chatbot: a vision-language model you can show images to and talk with, built by visual instruction tuning toward GPT-4V-level capabilities (NeurIPS 2023 Oral).
- 13
llm-cookbook
24.8Kdatawhalechina/llm-cookbook · Jupyter NotebookA developer-oriented LLM starter handbook: a Chinese adaptation of Andrew Ng's LLM course series, translated and re-run for Chinese developers, covering prompt engineering through RAG development and model fine-tuning.
- 14
index-tts
24.6Kindex-tts/index-tts · PythonIndexTTS is a zero-shot text-to-speech system that clones a voice from a single reference audio clip. The latest version, IndexTTS-2.5, supports Chinese, English, Japanese, Spanish and Arabic with fine-grained emotion, speed and pronunciation control.
- 15
HivisionIDPhotos
21.6KZeyi-Lin/HivisionIDPhotos · PythonAn open-source AI tool for making ID photos: it cuts the person out of an ordinary snapshot with matting models and generates standard ID photos in various sizes with the right background color.
- 16
ebook2audiobook
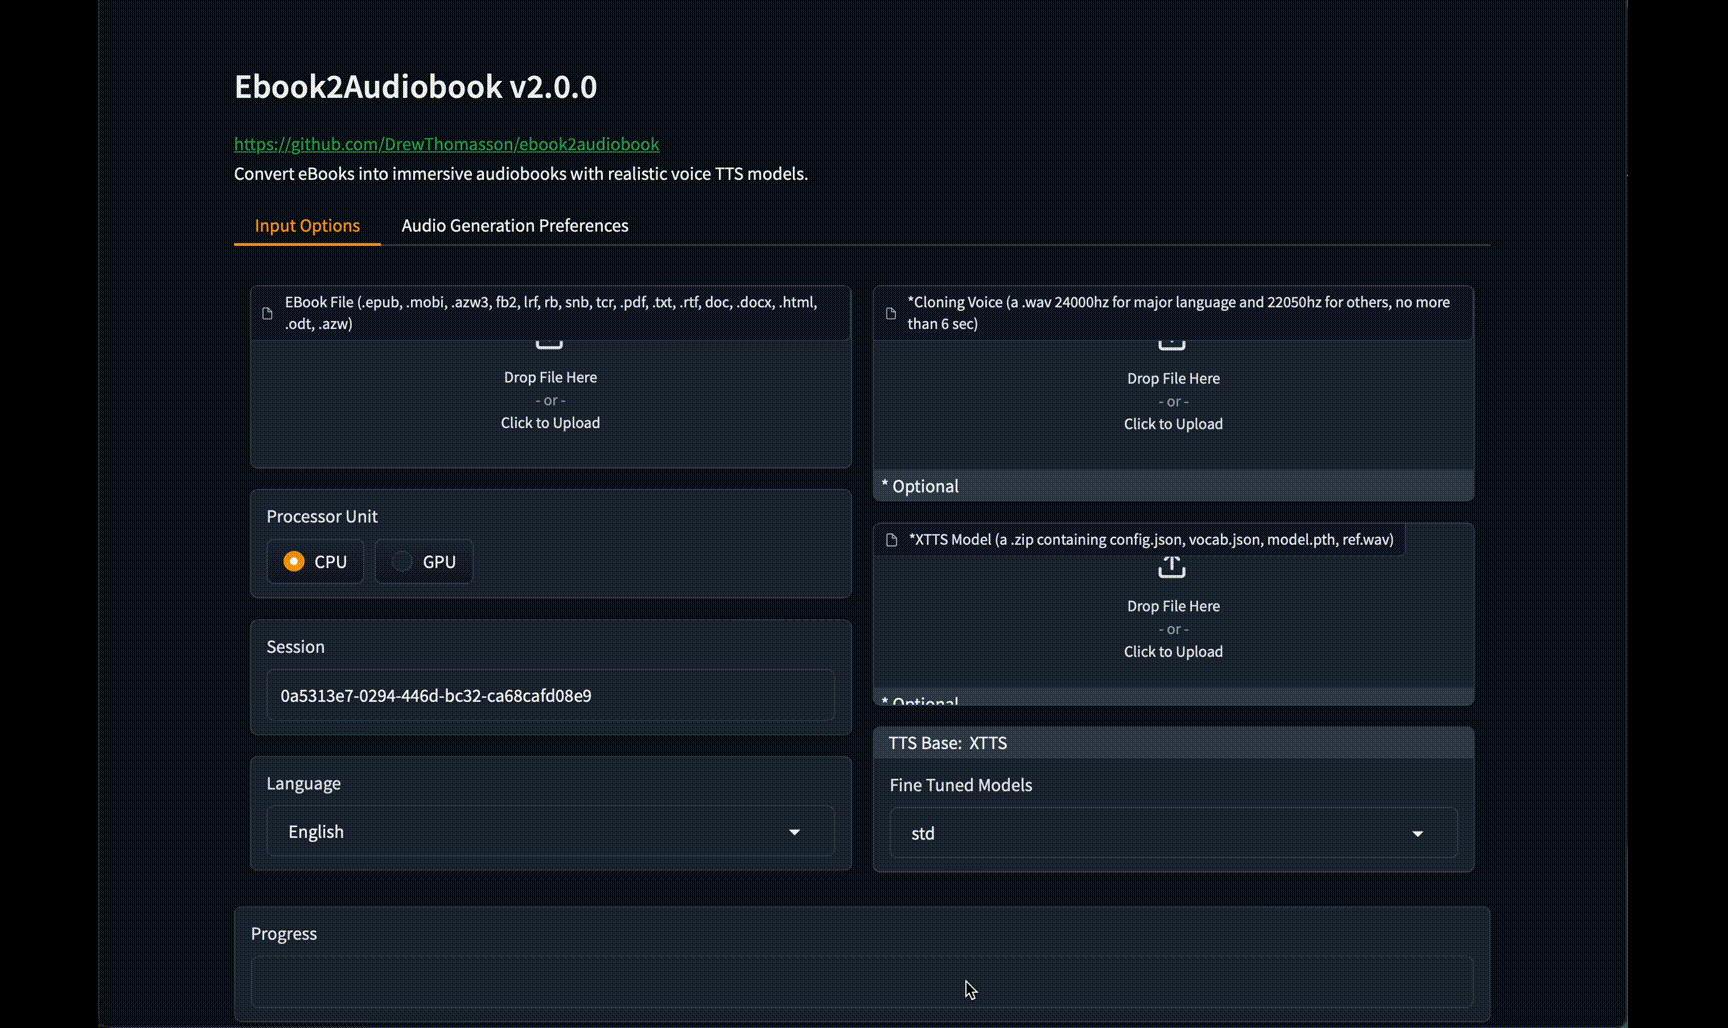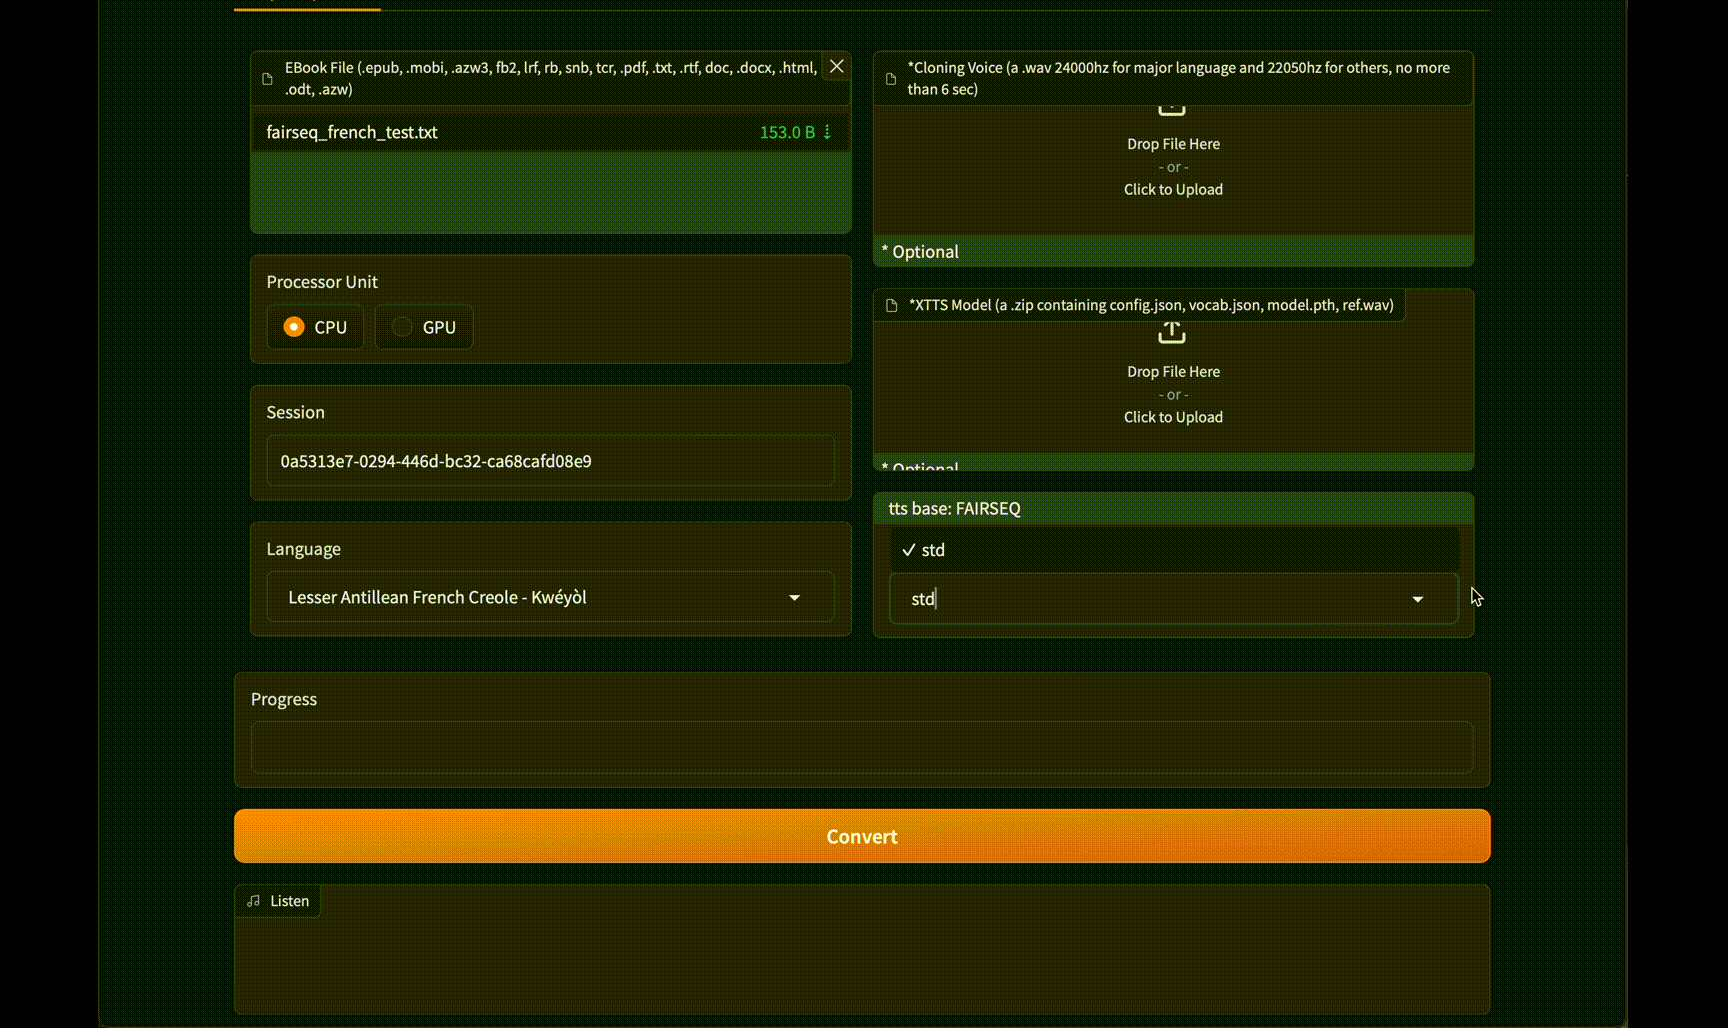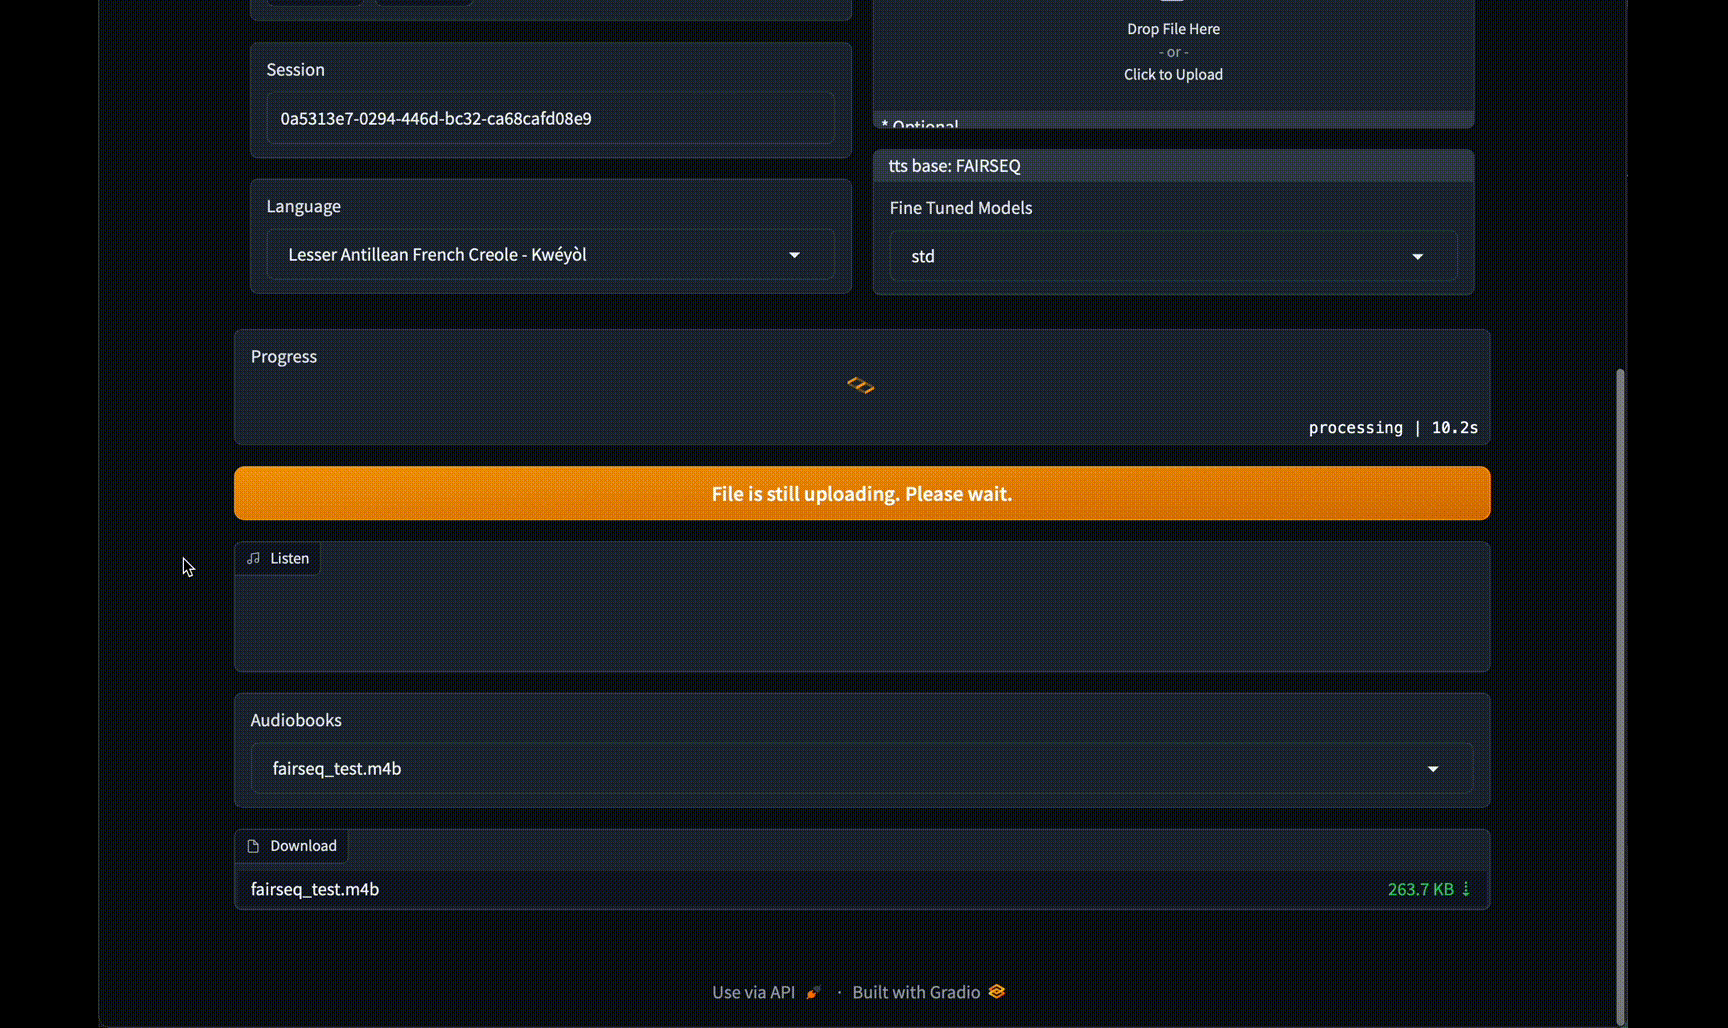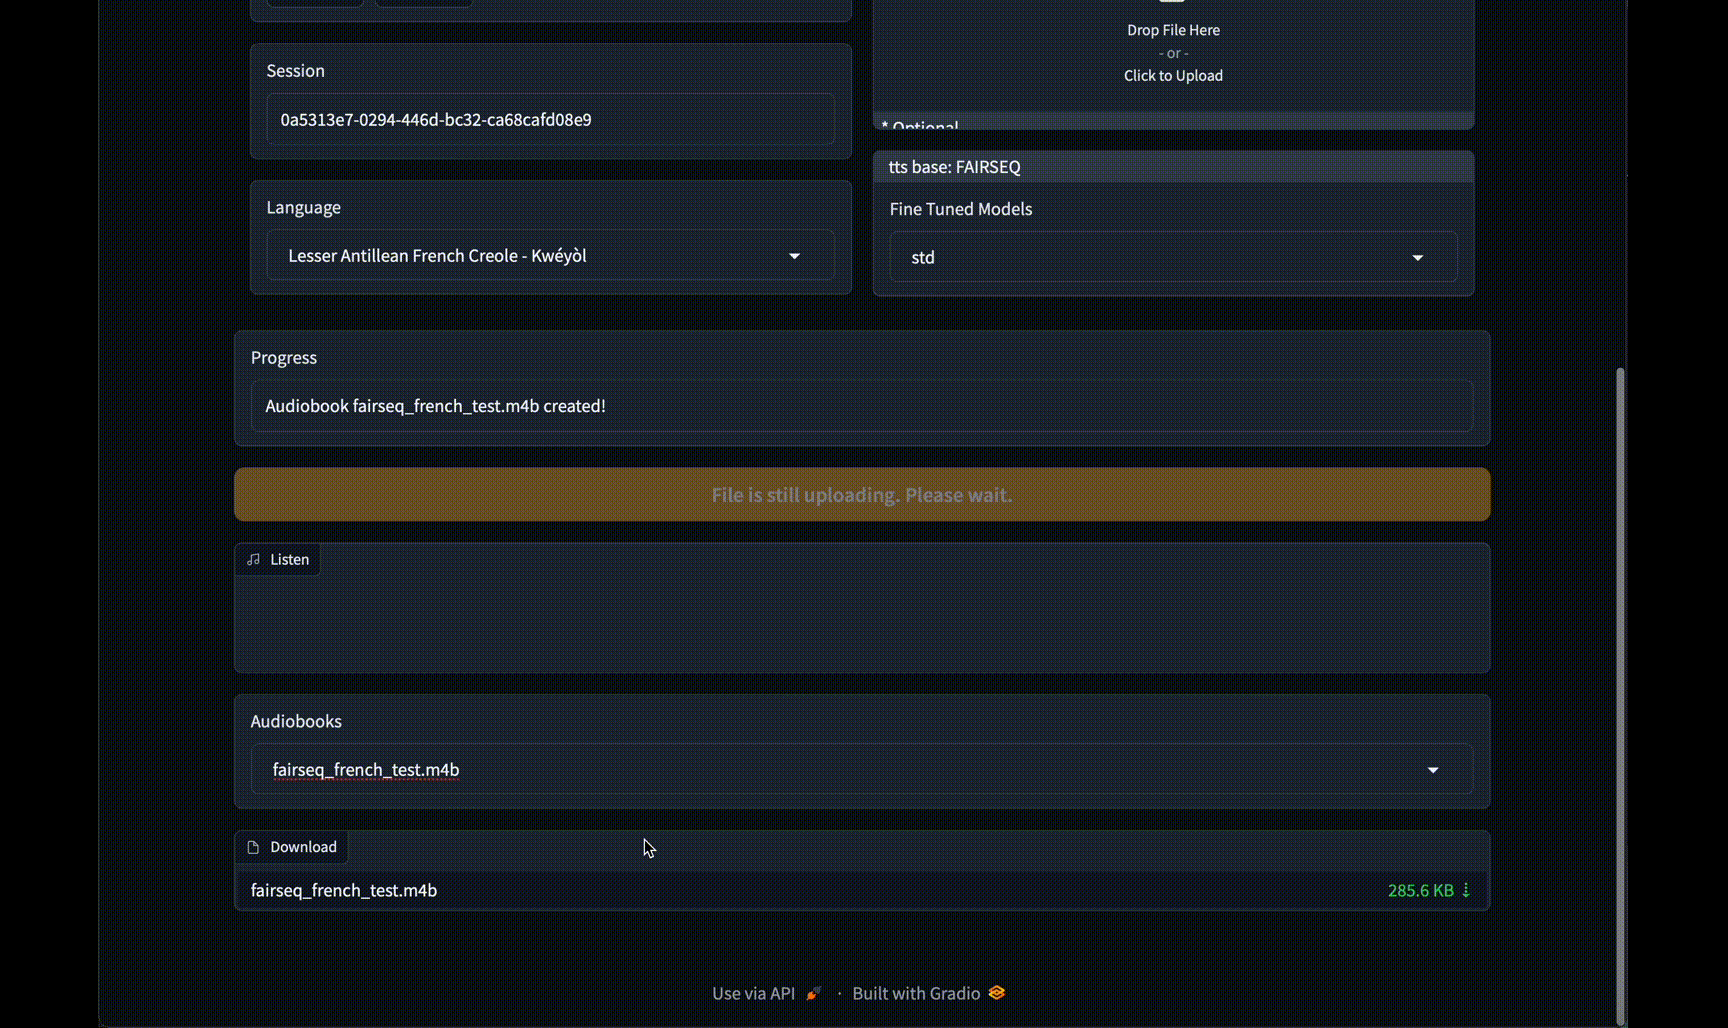
20.4KDrewThomasson/ebook2audiobook · PythonA converter that turns DRM-free e-books into audiobooks with chapters and metadata, using TTS engines with optional voice cloning, in 1158+ languages. It runs locally on modest hardware or in Docker.
- 17
pyvideotrans
19.4Kjianchang512/pyvideotrans · PythonAn open-source video translation and dubbing tool: it converts a video from one language to another through a one-click pipeline of speech recognition, subtitle translation, TTS dubbing, and video synthesis.
- 18

LivePortrait
19.3KKlingAIResearch/LivePortrait · PythonLivePortrait animates a still portrait photo using a driving video — the official PyTorch implementation of the paper 'Efficient Portrait Animation with Stitching and Retargeting Control' by Kuaishou Technology. It works on humans as well as cats and dogs.
- 19

alpaca-lora
18.9Ktloen/alpaca-lora · Jupyter NotebookAlpaca-LoRA reproduces the Stanford Alpaca results by instruct-tuning LLaMA with low-rank adaptation (LoRA). It ships the training code, inference scripts, and the resulting LoRA weights, producing an Instruct model of similar quality to text-davinci-003.
- 20

SkillOpt
18.5Kmicrosoft/SkillOpt · PythonA text-space optimizer that trains reusable natural-language skills for frozen LLM agents without touching model weights. The trained skill ships as a compact markdown file (typically 300–2,000 tokens) that adds zero inference-time model calls at deployment.
- 21
Grounded-Segment-Anything
17.8KIDEA-Research/Grounded-Segment-Anything · Jupyter NotebookGrounded SAM, a research demo project that combines Grounding DINO with Segment Anything to detect and segment any object in an image from a plain text prompt, extended with Stable Diffusion, RAM, Whisper and more.
- 22
Janus
17.8Kdeepseek-ai/Janus · PythonJanus is DeepSeek's family of open multimodal AI models (Janus, Janus-Pro, JanusFlow). One model both understands images and text and generates images from a text prompt.
- 23
Wan2.1
17.2KWan-Video/Wan2.1 · PythonWan2.1 is an open suite of large-scale video generative models: it turns text or images into videos, and also covers video editing, text-to-image and video-to-audio tasks.
- 24

Qwen-Agent
17.2KQwenLM/Qwen-Agent · PythonQwen-Agent is a framework for building LLM applications on top of Qwen models, using their instruction following, tool use, planning and memory capabilities. It ships with example apps such as a Browser Assistant and Code Interpreter, and it is the backend that powers Qwen Chat.
- 25
web-ui
16.6Kbrowser-use/web-ui · PythonA Gradio web UI for the browser-use library: give a task to an AI agent and watch it drive a real browser. It supports many LLMs — OpenAI, Anthropic, Google, Azure OpenAI, DeepSeek, Ollama and more.
- 26

stable-diffusion-webui-colab
15.9Kcamenduru/stable-diffusion-webui-colab · Jupyter NotebookA set of ready-made Google Colab notebooks that install and run the Stable Diffusion WebUI in the cloud — one notebook per popular model, from SD 1.5 to waifu-diffusion and style fine-tunes.
- 27
ms-swift
15.9Kmodelscope/ms-swift · Pythonms-swift is the ModelScope community's fine-tuning and deployment framework for LLMs and multimodal models, covering training, inference, evaluation, quantization and deployment in one pipeline.
- 28
ChatGLM2-6B
15.5Kzai-org/ChatGLM2-6B · PythonChatGLM2-6B is an open bilingual (Chinese-English) conversational language model with 6 billion parameters, the second generation of ChatGLM-6B from Zhipu AI (Z.ai).
- 29

F5-TTS
15.4KSWivid/F5-TTS · PythonF5-TTS is a text-to-speech system that generates fluent, faithful speech using flow matching with a Diffusion Transformer (ConvNeXt V2 backbone), and it supports cloning a speaker's voice from a short reference clip.
- 30
ChuanhuChatGPT
15.3KGaiZhenbiao/ChuanhuChatGPT · PythonChuanhuChatGPT is a web-based GUI for ChatGPT and many other LLMs, adding extras like agents, file-based Q&A, local model deployment, web search, and GPT fine-tuning on top of a Gradio interface.
- 31
Hunyuan3D-2
15.2KTencent-Hunyuan/Hunyuan3D-2 · PythonHunyuan3D 2.0 is a large-scale 3D generation system from Tencent that turns a single image (or text) into a high-resolution textured 3D mesh, using a two-stage pipeline: a shape diffusion model (Hunyuan3D-DiT) followed by a texture synthesis model (Hunyuan3D-Paint).
- 32
OmniVoice
14.8Kk2-fsa/OmniVoice · PythonOmniVoice is a zero-shot text-to-speech model that supports over 600 languages, built on a diffusion language model-style architecture, with voice cloning and voice design capabilities.
- 33
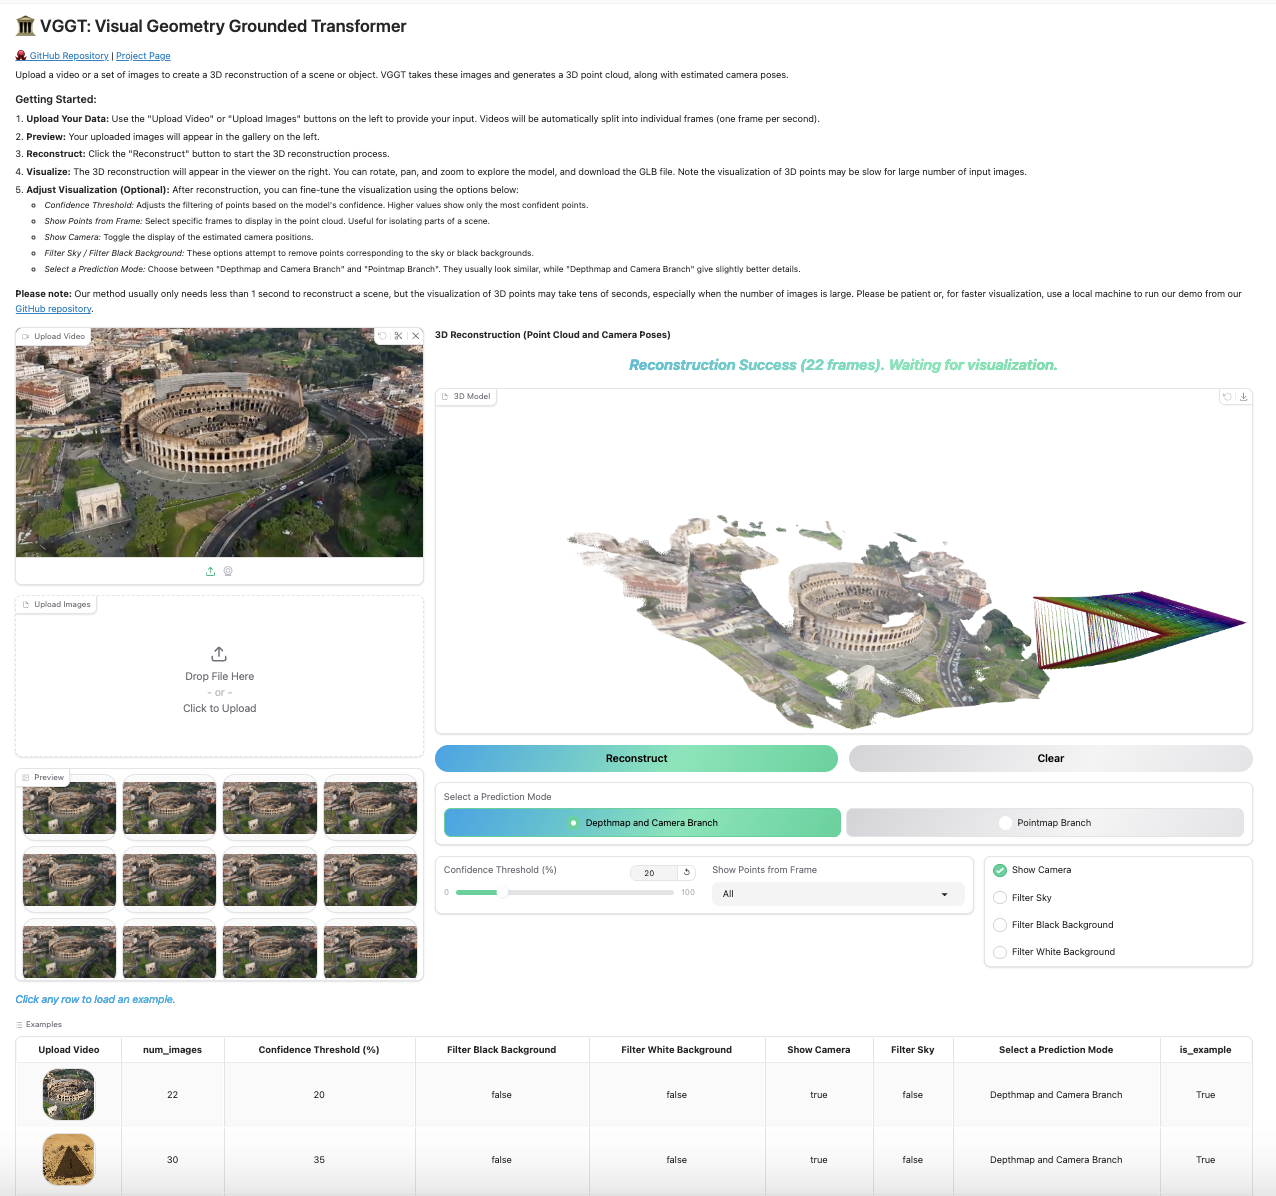
vggt
14.5Kfacebookresearch/vggt · PythonVGGT (Visual Geometry Grounded Transformer) is a feed-forward neural network that directly infers a scene's 3D attributes - camera intrinsics/extrinsics, depth maps, point maps, and 3D point tracks - from one, a few, or hundreds of images, in seconds. It won the CVPR 2025 Best Paper Award.
- 34
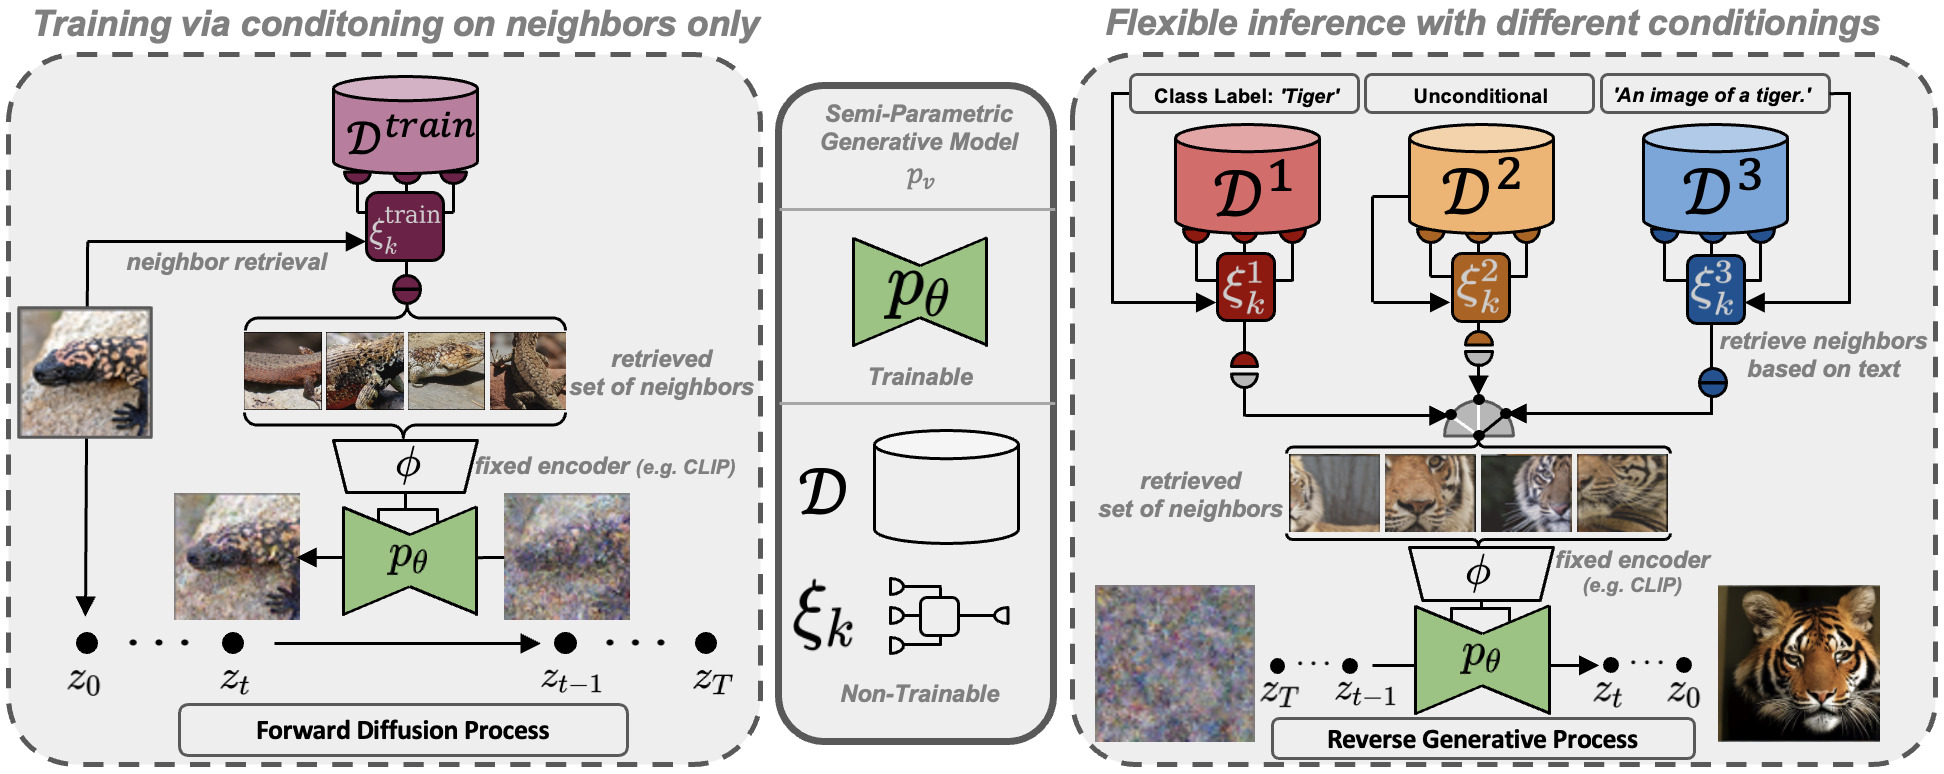
latent-diffusion
14.2KCompVis/latent-diffusion · Jupyter NotebookThis is the official research codebase for the paper 'High-Resolution Image Synthesis with Latent Diffusion Models' by CompVis, which introduced Latent Diffusion Models (LDMs) - diffusion models trained in a compressed latent space instead of raw pixel space for efficient, high-resolution image synthesis.
- 35

SadTalker
14.1KOpenTalker/SadTalker · PythonSadTalker generates a realistic talking-head video from a single portrait photo and an audio clip, using a CVPR 2023 method that learns 3D motion coefficients for audio-driven face animation.
- 36
TRELLIS
14Kmicrosoft/TRELLIS · PythonMicrosoft's large 3D asset generation model: feed it a text or image prompt and it generates high-quality 3D assets as Radiance Fields, 3D Gaussians, or meshes. It is the official code for a CVPR'25 Spotlight paper.
- 37
ACE-Step-1.5
13.8Kace-step/ACE-Step-1.5 · PythonACE-Step 1.5 is an open-source local music generation model that turns text prompts (and optional reference audio) into full songs, aiming for quality on par with commercial tools like Suno.
- 38
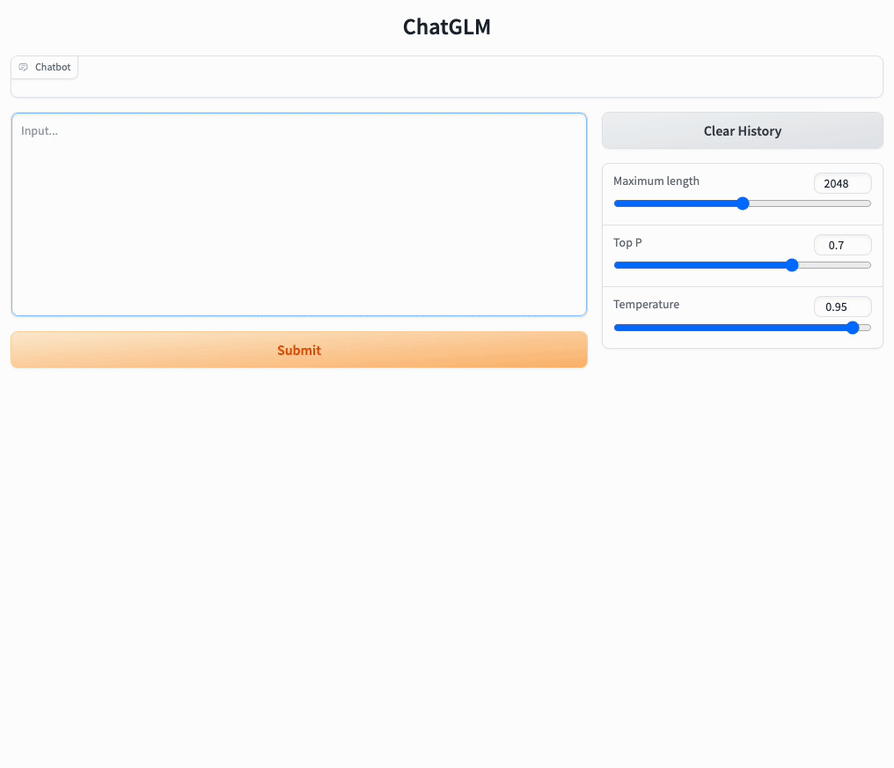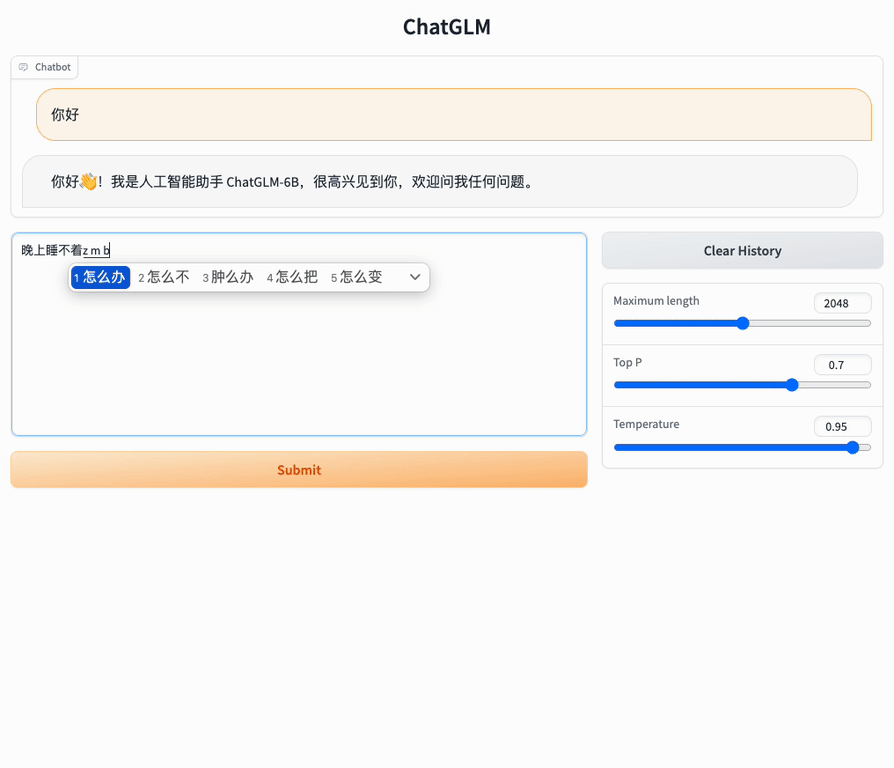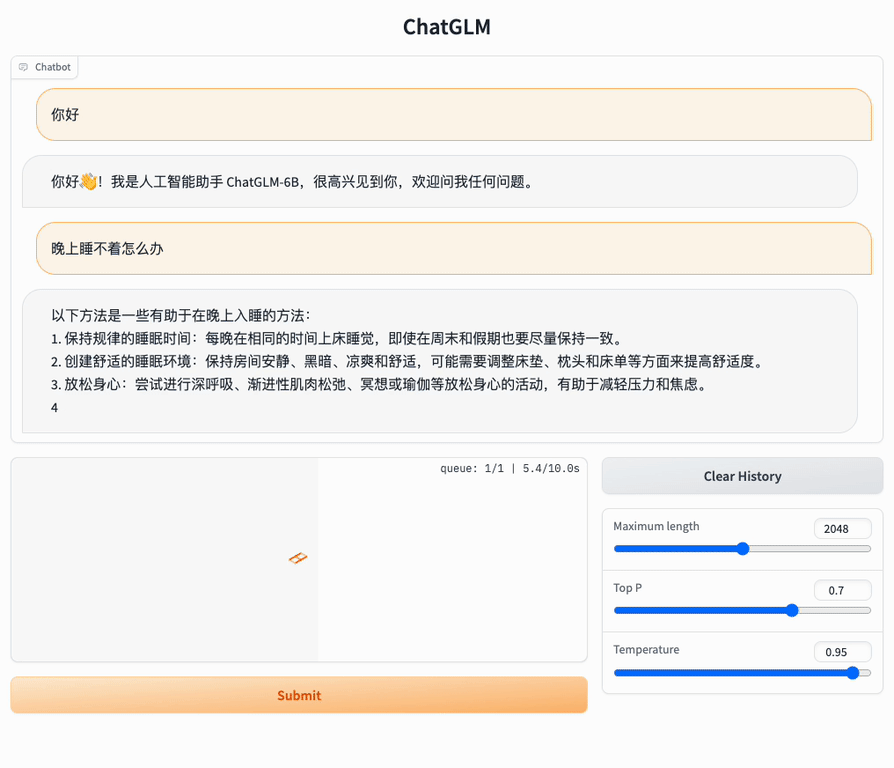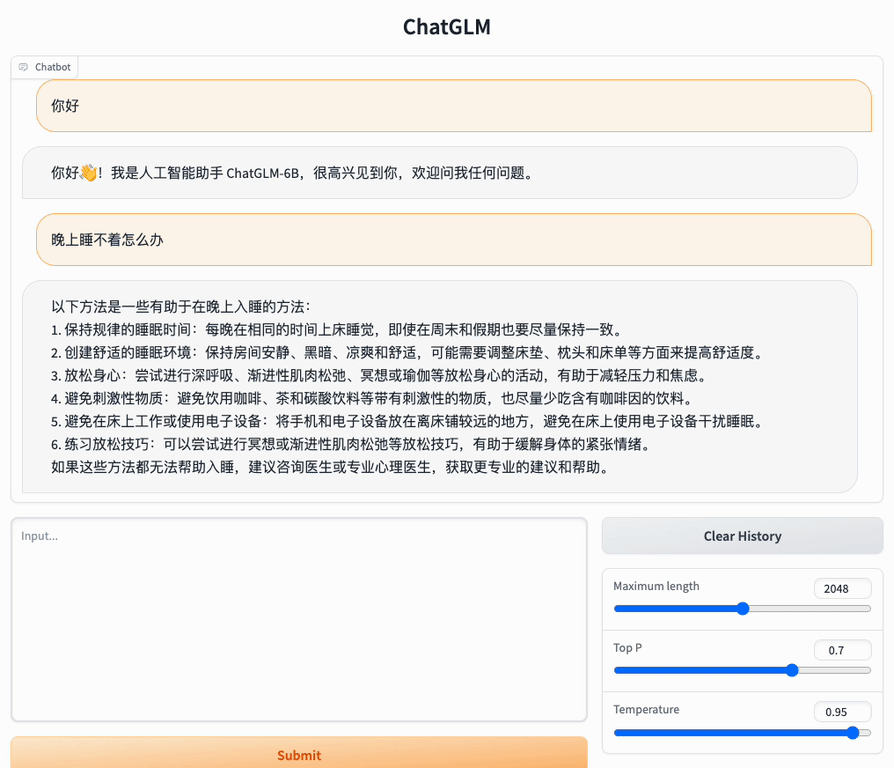
ChatGLM3
13.6Kzai-org/ChatGLM3 · PythonChatGLM3 is a series of open bilingual (Chinese-English) chat large language models released jointly by Zhipu AI and Tsinghua University's KEG Lab, including a 6B-parameter chat model, its base model, and 32K/128K long-context variants.
- 39
voice-pro
13.2Kabus-aikorea/voice-pro · PythonVoice-Pro is a free, open-source AI web app (built with Gradio) that combines speech recognition, zero-shot voice cloning, text-to-speech, YouTube downloading, vocal isolation, and multilingual translation into one tool for creators and researchers.
- 40

stable-diffusion-webui-forge
13.1Klllyasviel/stable-diffusion-webui-forge · PythonStable Diffusion WebUI Forge is a platform built on top of Stable Diffusion WebUI (using Gradio) that adds GPU memory management and performance improvements for running Stable Diffusion image generation locally.
- 41
MOSS
12.3KOpenMOSS/MOSS · PythonMOSS is an open-source, tool-augmented bilingual (Chinese-English) conversational language model built by Fudan University's OpenMOSS team, released with model weights, training data, and deployment/finetuning code.
- 42
AnimateDiff
12.3Kguoyww/AnimateDiff · PythonAnimateDiff is the official implementation of a research method that turns personalized text-to-image Stable Diffusion models into animation (text-to-video) generators without any extra fine-tuning of those models.
- 43
InstantID
12KinstantX-research/InstantID · PythonInstantID is a tuning-free method for identity-preserving image generation: a single reference photo of a face plus a text prompt is enough to create new images that keep the person's likeness, in seconds.
- 44

h2ogpt
11.9Kh2oai/h2ogpt · Pythonh2oGPT is an open-source private chat application that lets you query and summarize your own documents or just chat with local LLMs, with no data leaving your machine.
- 45
moshi
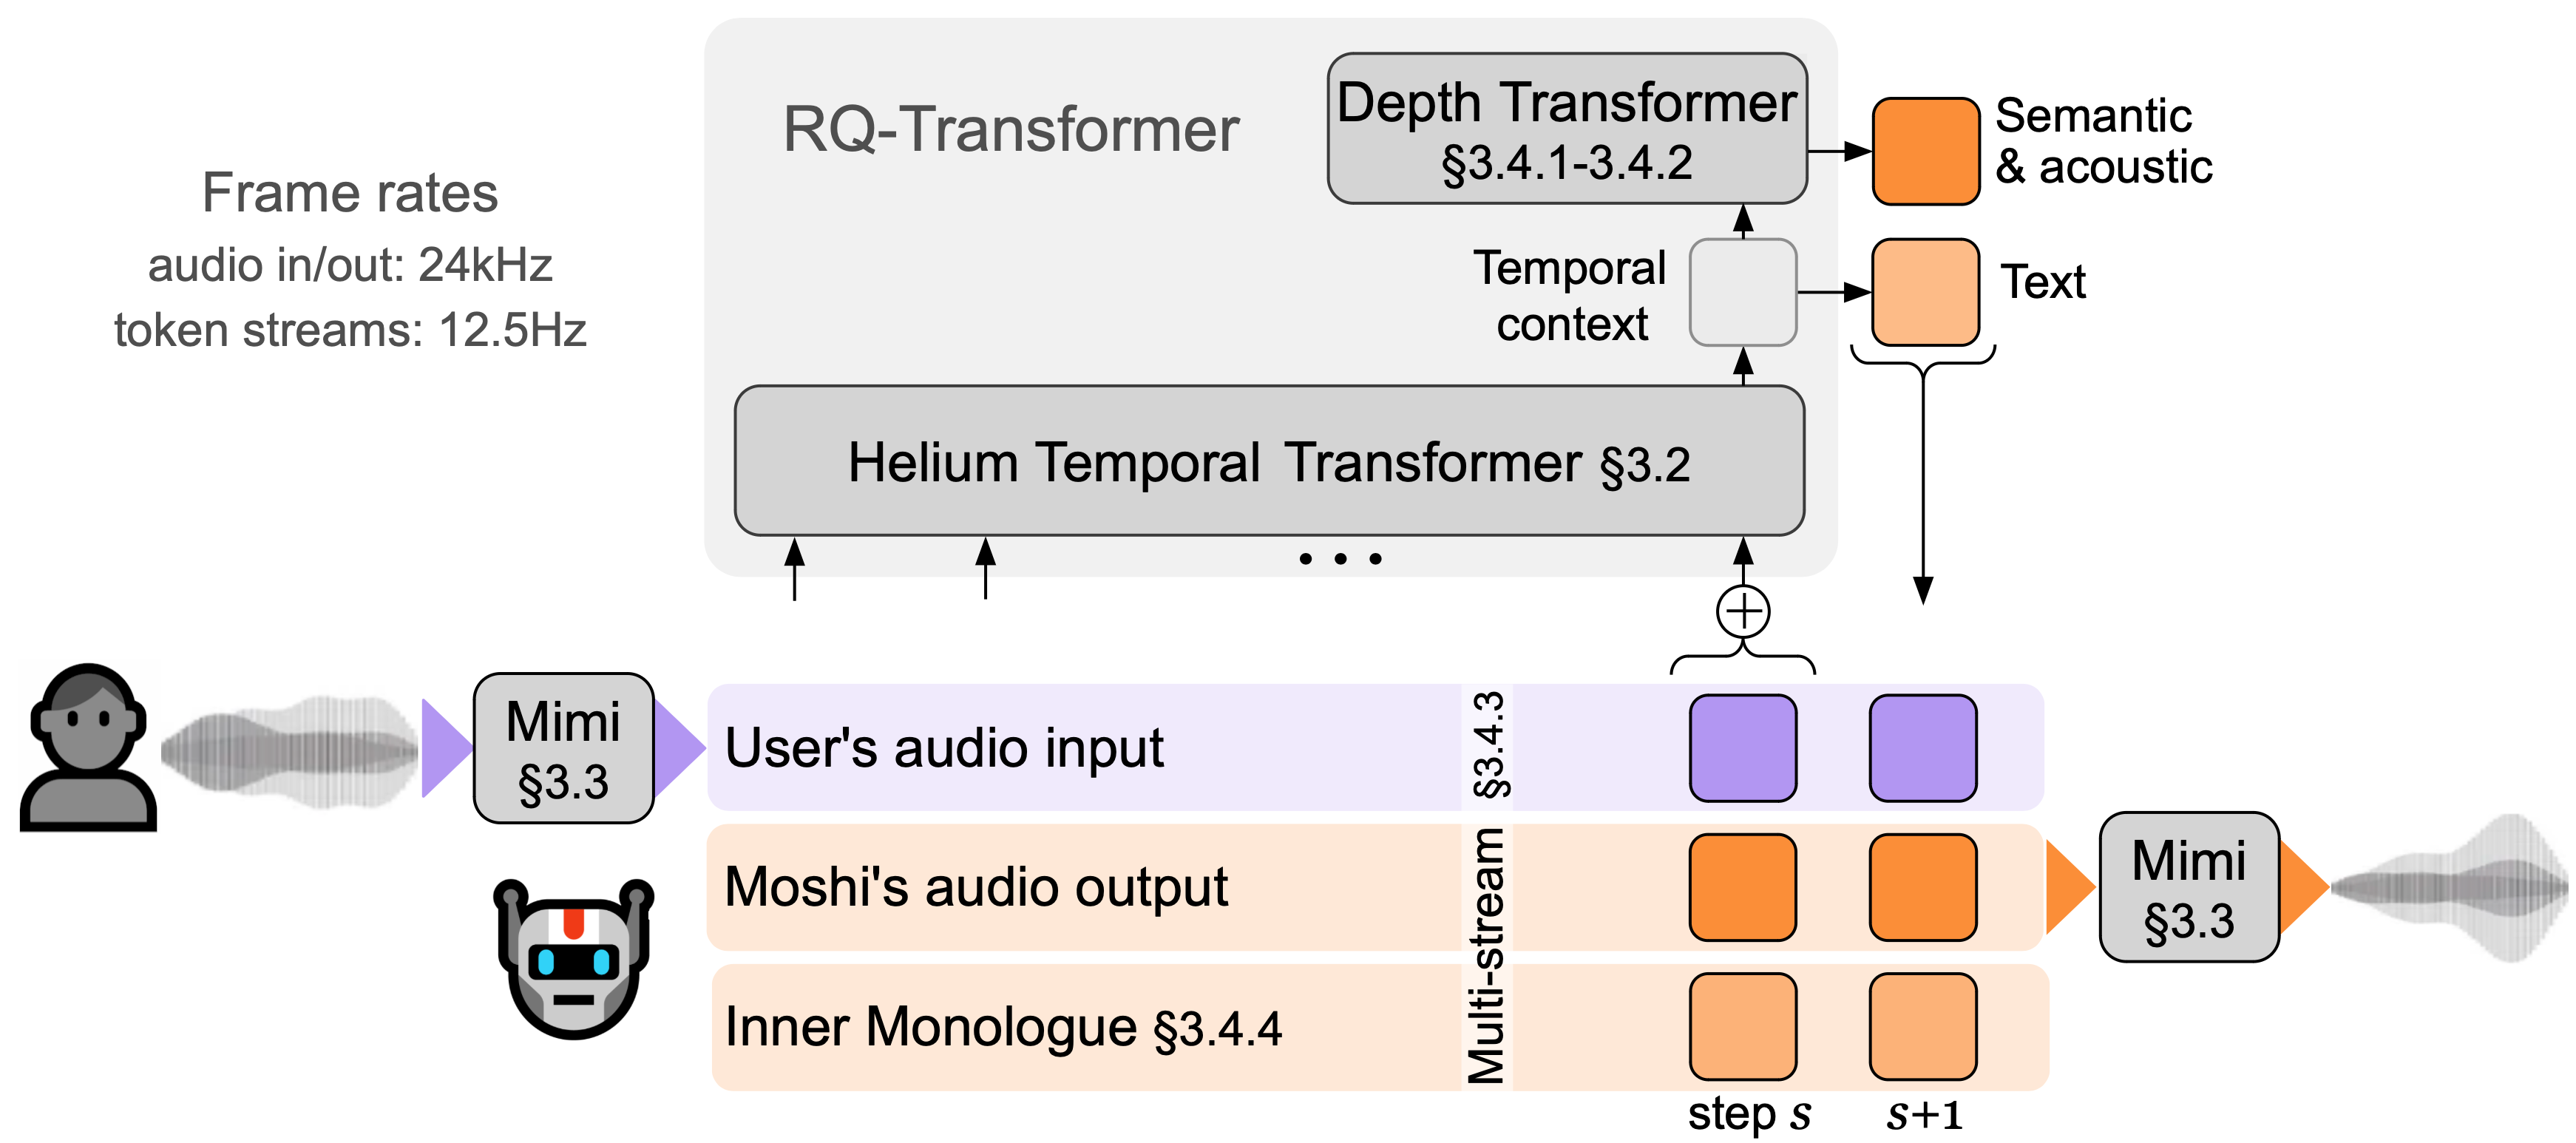
11.3Kkyutai-labs/moshi · PythonMoshi is a speech-text foundation model and full-duplex spoken dialogue framework, meaning the model can listen and speak at the same time rather than taking turns like typical voice assistants.
- 46

skills
11.2Khuggingface/skills · PythonThis repo provides modular 'Agent Skills' — SKILL.md definitions that teach AI coding agents (Claude Code, Codex, Gemini CLI, Cursor) how to do Hugging Face ML tasks like managing models/datasets, training, evaluation, and deploying to Spaces or SageMaker.
- 47
magic-animate
10.9Kmagic-research/magic-animate · PythonThis is the official codebase for 'MagicAnimate' (CVPR 2024), a diffusion-model method that animates a reference human image according to a motion sequence to produce temporally consistent video.
- 48
GroundingDINO
10.7KIDEA-Research/GroundingDINO · PythonAn open-set object detection model from IDEA-Research (ECCV 2024): give it an image plus a text prompt and it finds the objects your words describe. This repo is the official PyTorch implementation with pretrained models.
- 49
WanGP
10.7Kdeepbeepmeep/WanGP · PythonWanGP is a one-stop open source app for running top generative AI models for video, image, and audio/TTS generation, built specifically to work on modest consumer GPUs (the 'GPU Poor').
- 50
PhotoMaker
10.1KTencentARC/PhotoMaker · Jupyter NotebookPhotoMaker is an AI tool from Tencent ARC (CVPR 2024) that generates new images of a specific person: you feed in a few reference photos of the face plus a text prompt, and it renders that identity in new scenes, poses, or styles.
- 51
production-agentic-rag-course
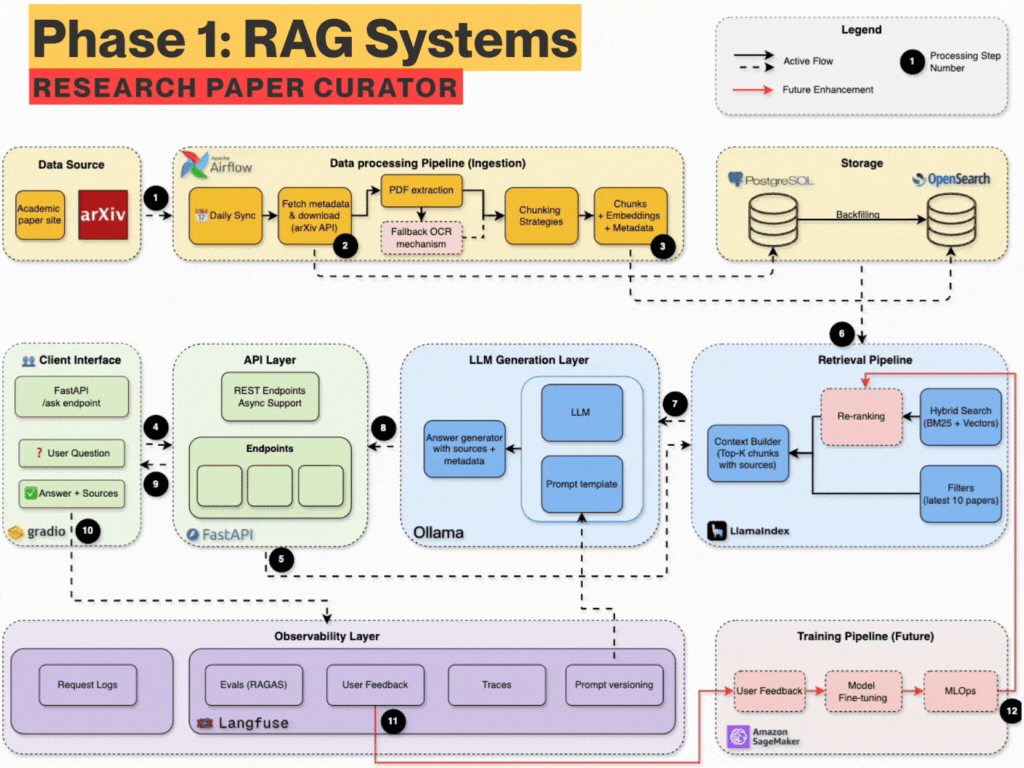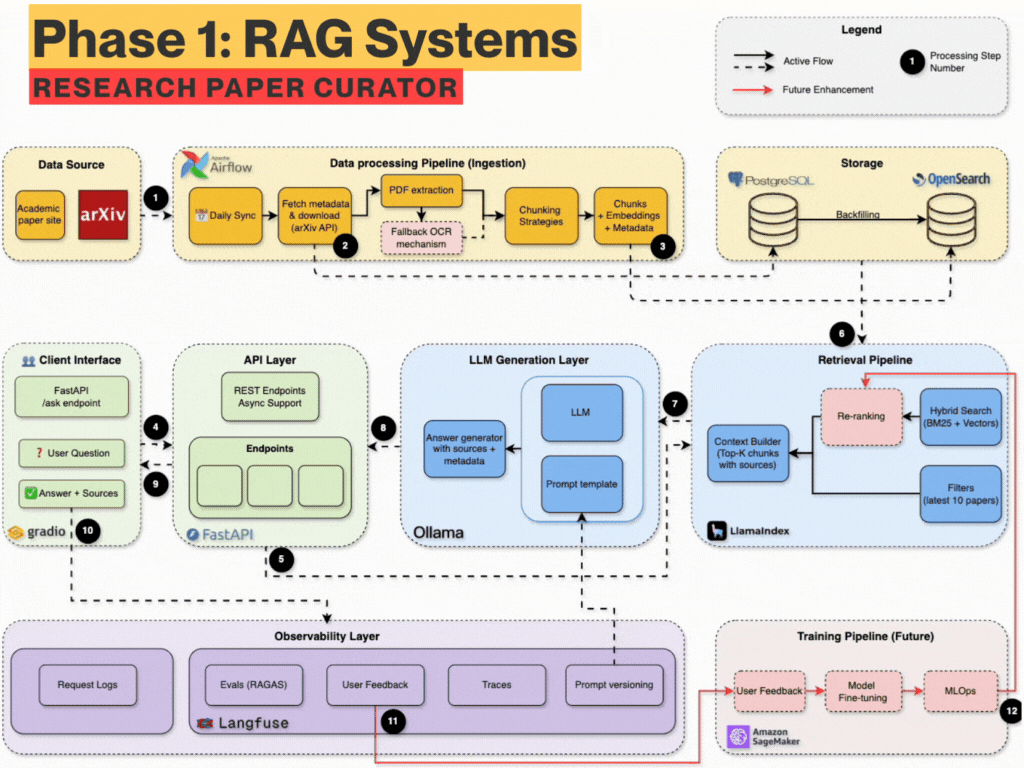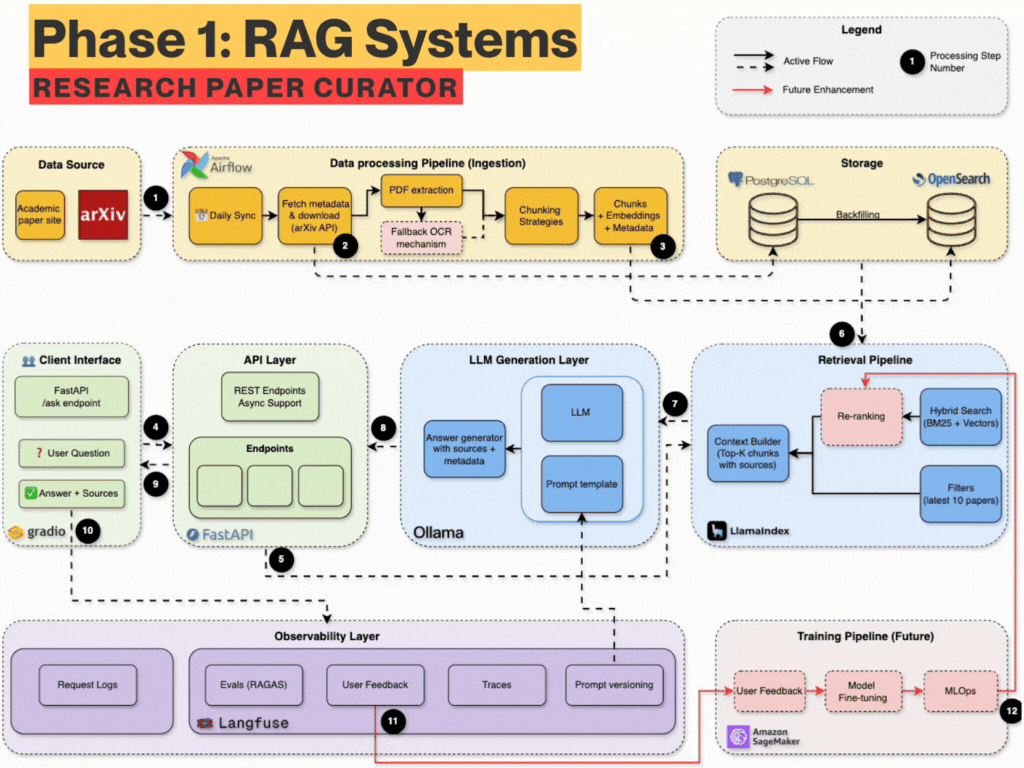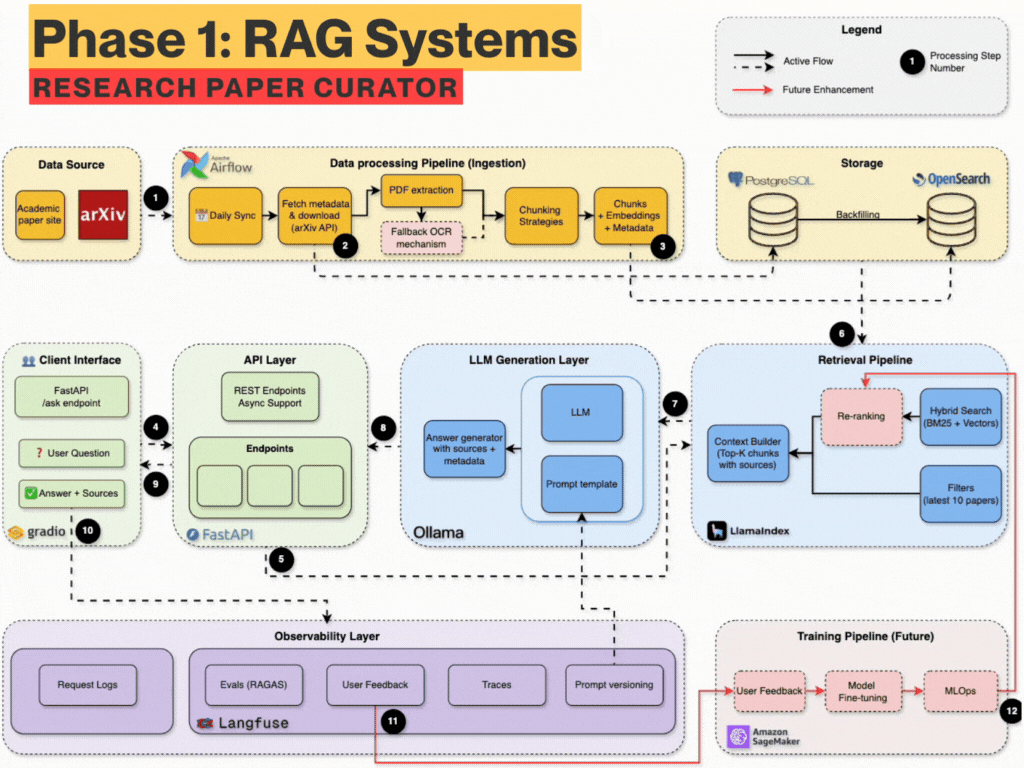
9.8Kjamwithai/production-agentic-rag-course · PythonThis is a hands-on, week-by-week course that teaches you to build 'arXiv Paper Curator', a production-grade Retrieval-Augmented Generation (RAG) system that fetches academic papers, indexes them, and answers research questions about them.
- 52

OBLITERATUS
8.9Kelder-plinius/OBLITERATUS · PythonOBLITERATUS is an open-source toolkit for 'abliteration' — it probes a language model's hidden states to locate the internal directions responsible for refusing prompts, then surgically removes them so the model stops refusing while keeping its core language abilities.
- 53
PaperBanana
7.2Kdwzhu-pku/PaperBanana · PythonPaperBanana is an open-source framework that turns raw scientific content into publication-quality diagrams and plots, acting like a creative team of five specialized agents: Retriever, Planner, Stylist, Visualizer and Critic.
- 54
Depth-Anything-3
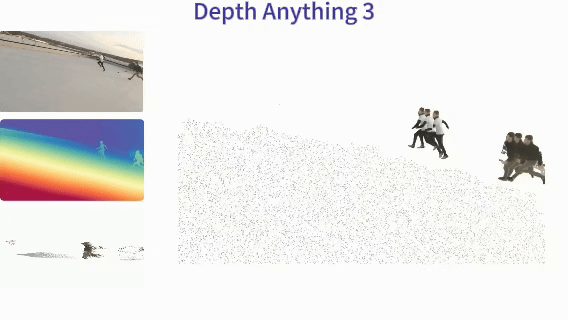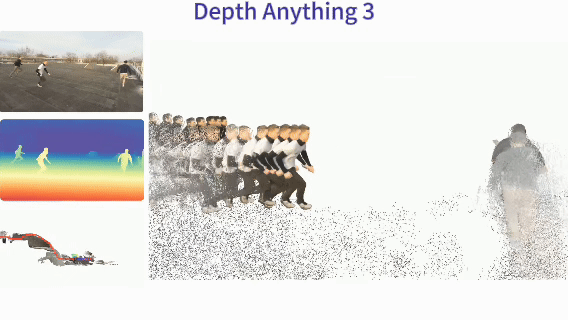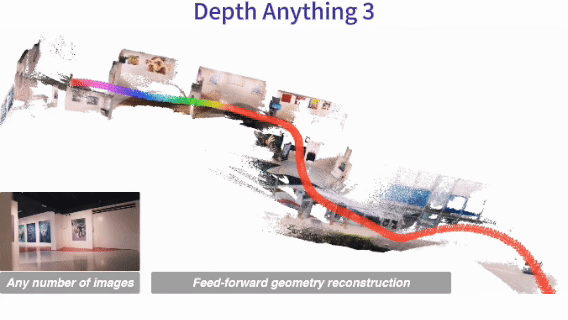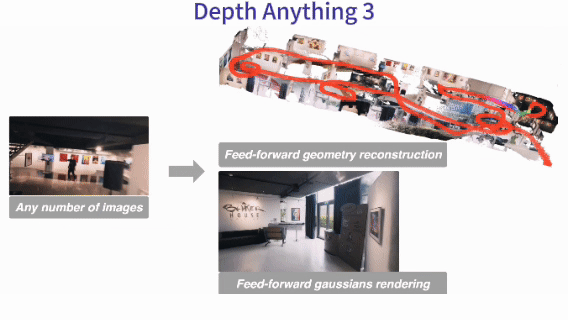
6.5KByteDance-Seed/Depth-Anything-3 · PythonDepth Anything 3 (DA3) is a foundation model from ByteDance Seed that predicts spatially consistent geometry — depth, camera poses, even 3D Gaussians — from arbitrary visual inputs, with or without known camera poses.
- 55

vggt-omega
4.7Kfacebookresearch/vggt-omega · PythonVGGT-Omega is a research model from Visual Geometry Group (Oxford) and Meta AI that reconstructs 3D geometry, camera poses, and depth from a set of images or a video, producing a point cloud and camera predictions.
- 56
agentic-rag-for-dummies
4.3KGiovanniPasq/agentic-rag-for-dummies · Jupyter NotebookIt is a learning project and modular codebase that shows how to build an Agentic RAG (Retrieval-Augmented Generation) system using LangGraph, including conversation memory and human-in-the-loop query clarification.
- 57
FireRedAudio
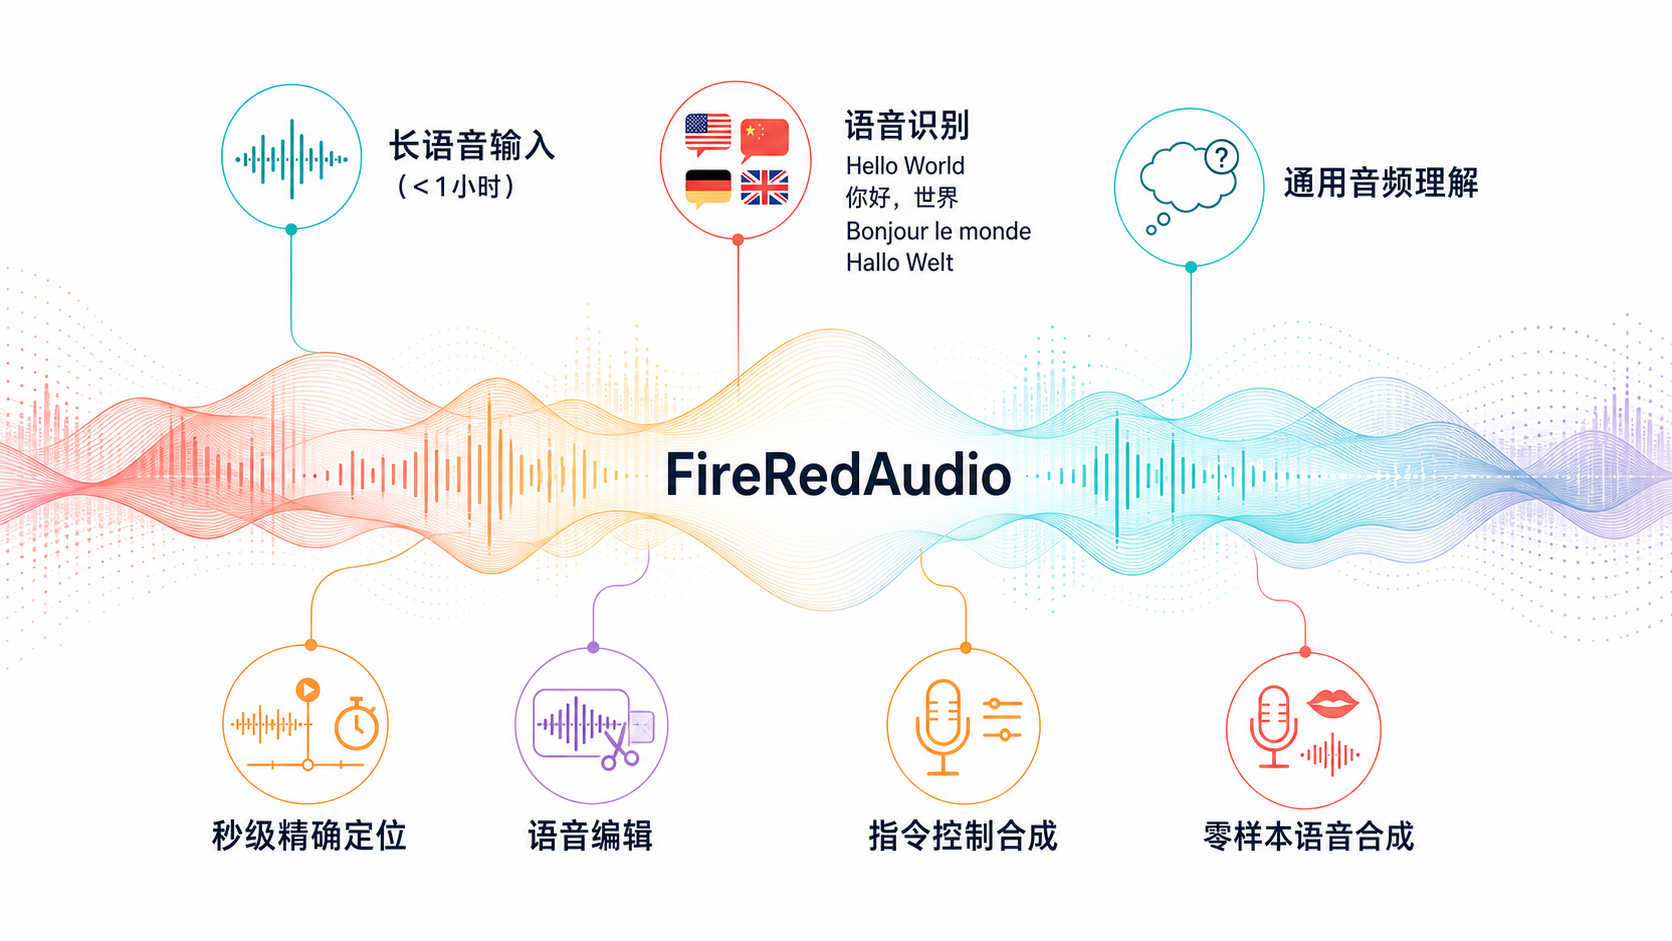
2KFireRedTeam/FireRedAudio · PythonFireRedAudio is a general-purpose audio language model built on a shared 9B-parameter LLM that can transcribe speech (ASR), understand audio, do zero-shot and instruct text-to-speech, and edit speech, all from one model.
- 58
FireRedTTS3
1.8KFireRedTeam/FireRedTTS3 · PythonFireRedTTS3 is a unified speech generation and editing model: it clones voices across 24 languages and 21 Chinese dialects, can design brand-new voices from a text description, and can edit existing speech (semantic and acoustic) using natural-language instructions.
- 59

AuK
1.5KTencent-Hunyuan/AuK · PythonAn open-source 1.5B-parameter foundation model from Tencent Hunyuan for speech generation and editing: zero-shot and instruct TTS, speech editing, enhancement, and source separation — all driven through one natural-language instruction interface.
- 60
dlss5-visual-enhancer
1.4KMerserk/dlss5-visual-enhancer · C++DLSS 5 Visual Enhancer is a Windows app that applies NVIDIA's DLSS 5 Neural Rendering to images and video, uses DLSS Frame Generation for video frame interpolation, and applies Neural Rendering live during video playback - all through a local web interface.
- 61
MOSS-Image
686OpenMOSS/MOSS-Image · PythonMOSS-Image is a 5-billion-parameter text-to-image diffusion transformer (DiT) model built for strong text rendering, JSON-based layout control over where text and objects go, and efficient fine-tuning (including LoRA) on custom tasks.
- 62
DramaBox
507resemble-ai/DramaBox · PythonDramaBox is Resemble AI's expressive text-to-speech model with voice cloning, fine-tuned on top of Lightricks' LTX-2.3 audio model. The prompt itself controls speaker identity, emotion, delivery style, laughs, sighs, pauses and transitions, and an optional 10-second voice reference clones the target voice timbre.
- 63
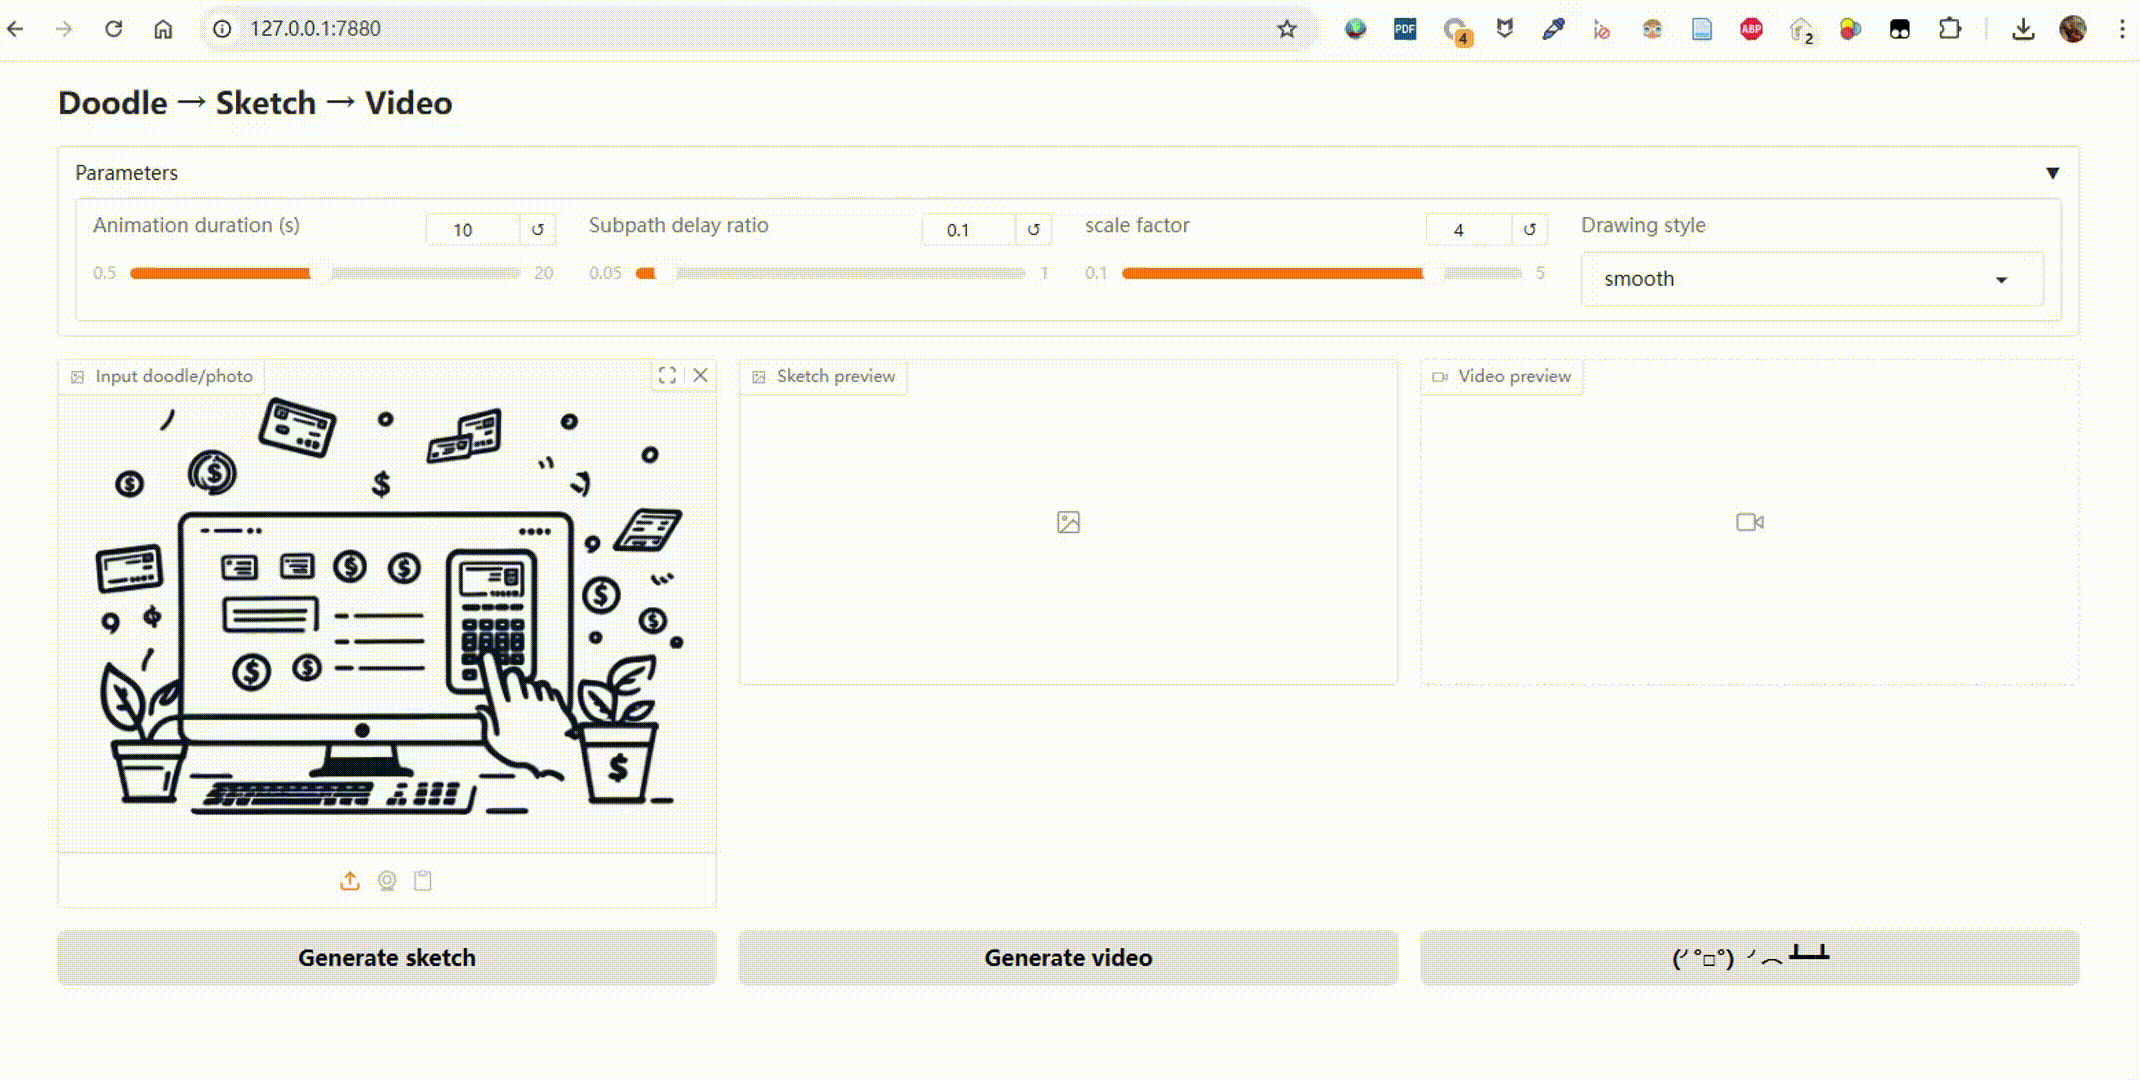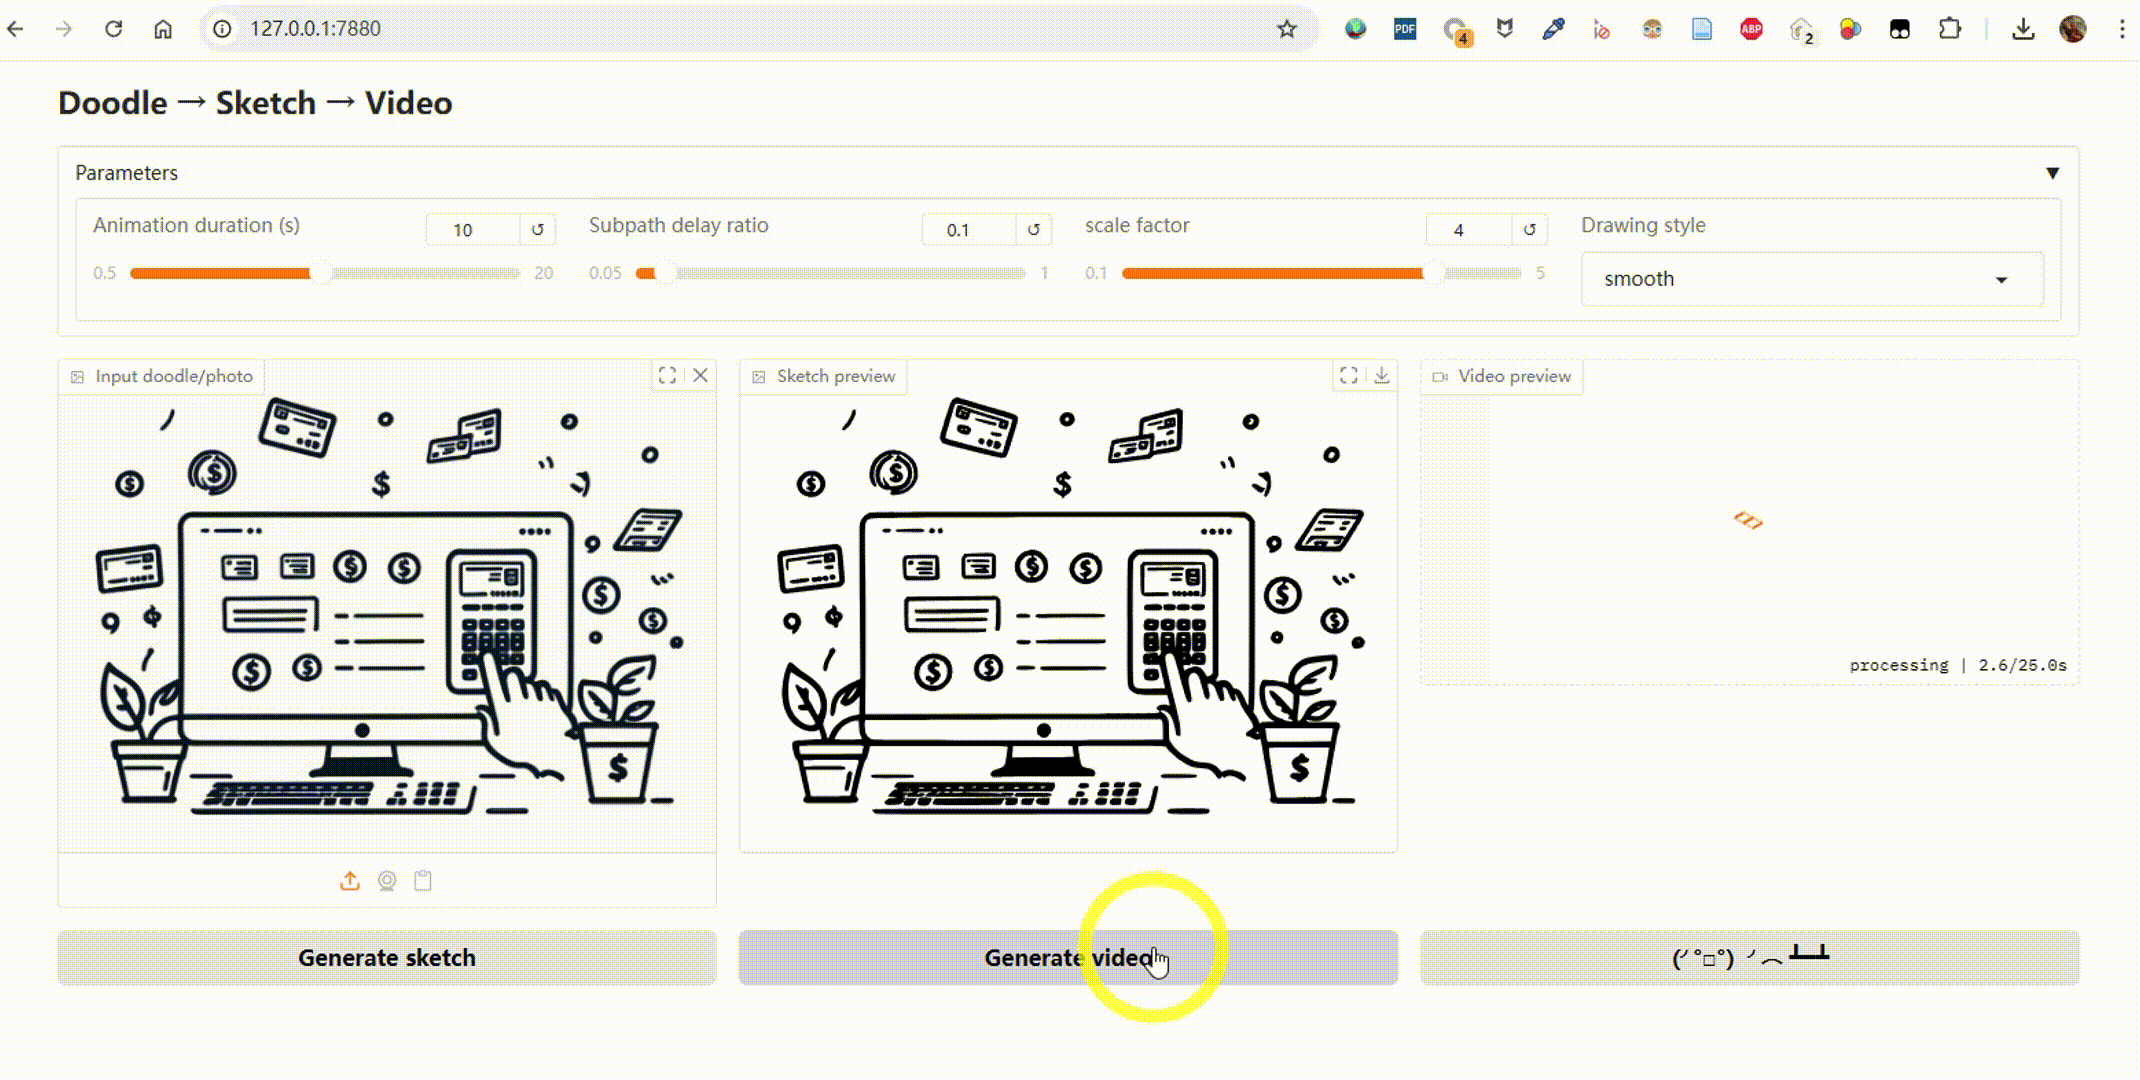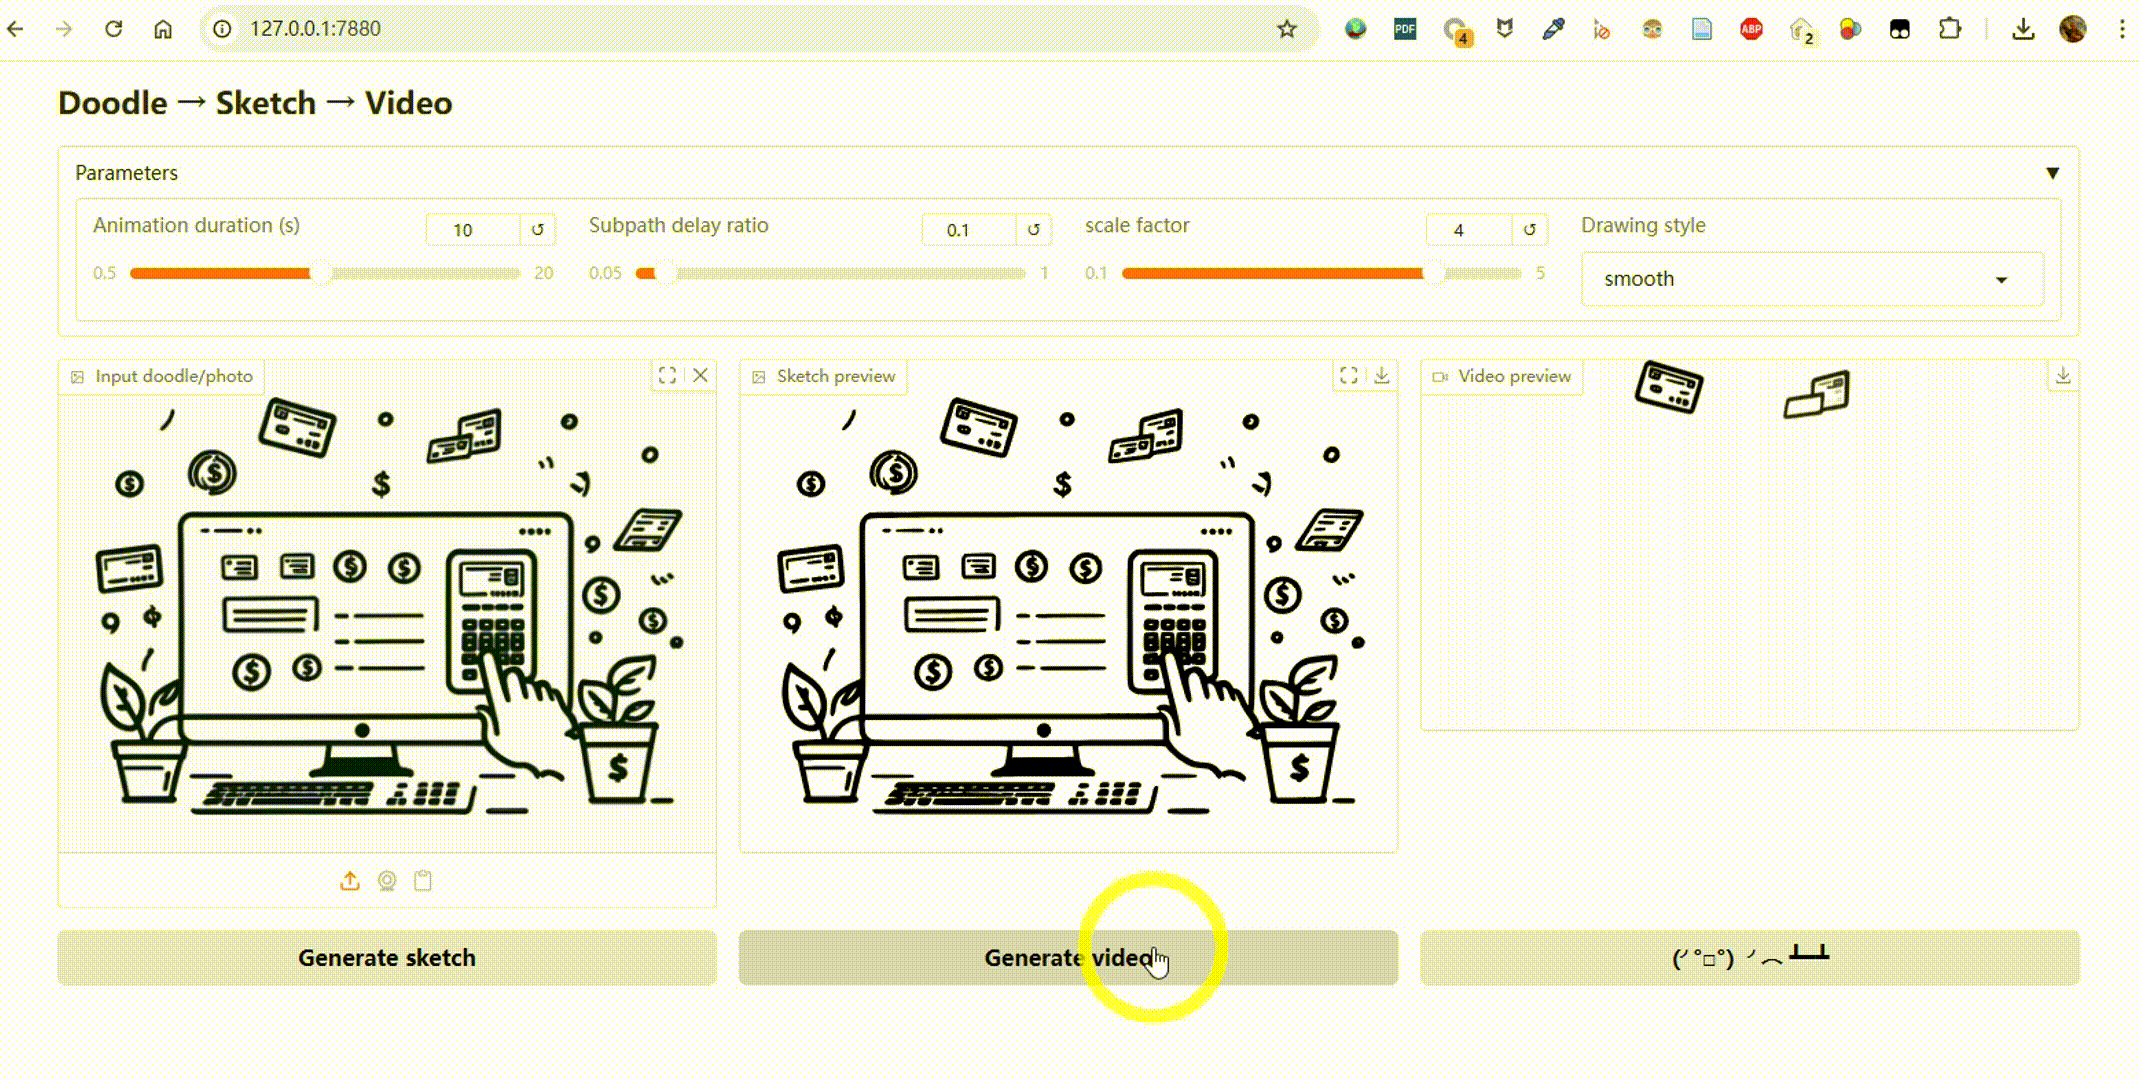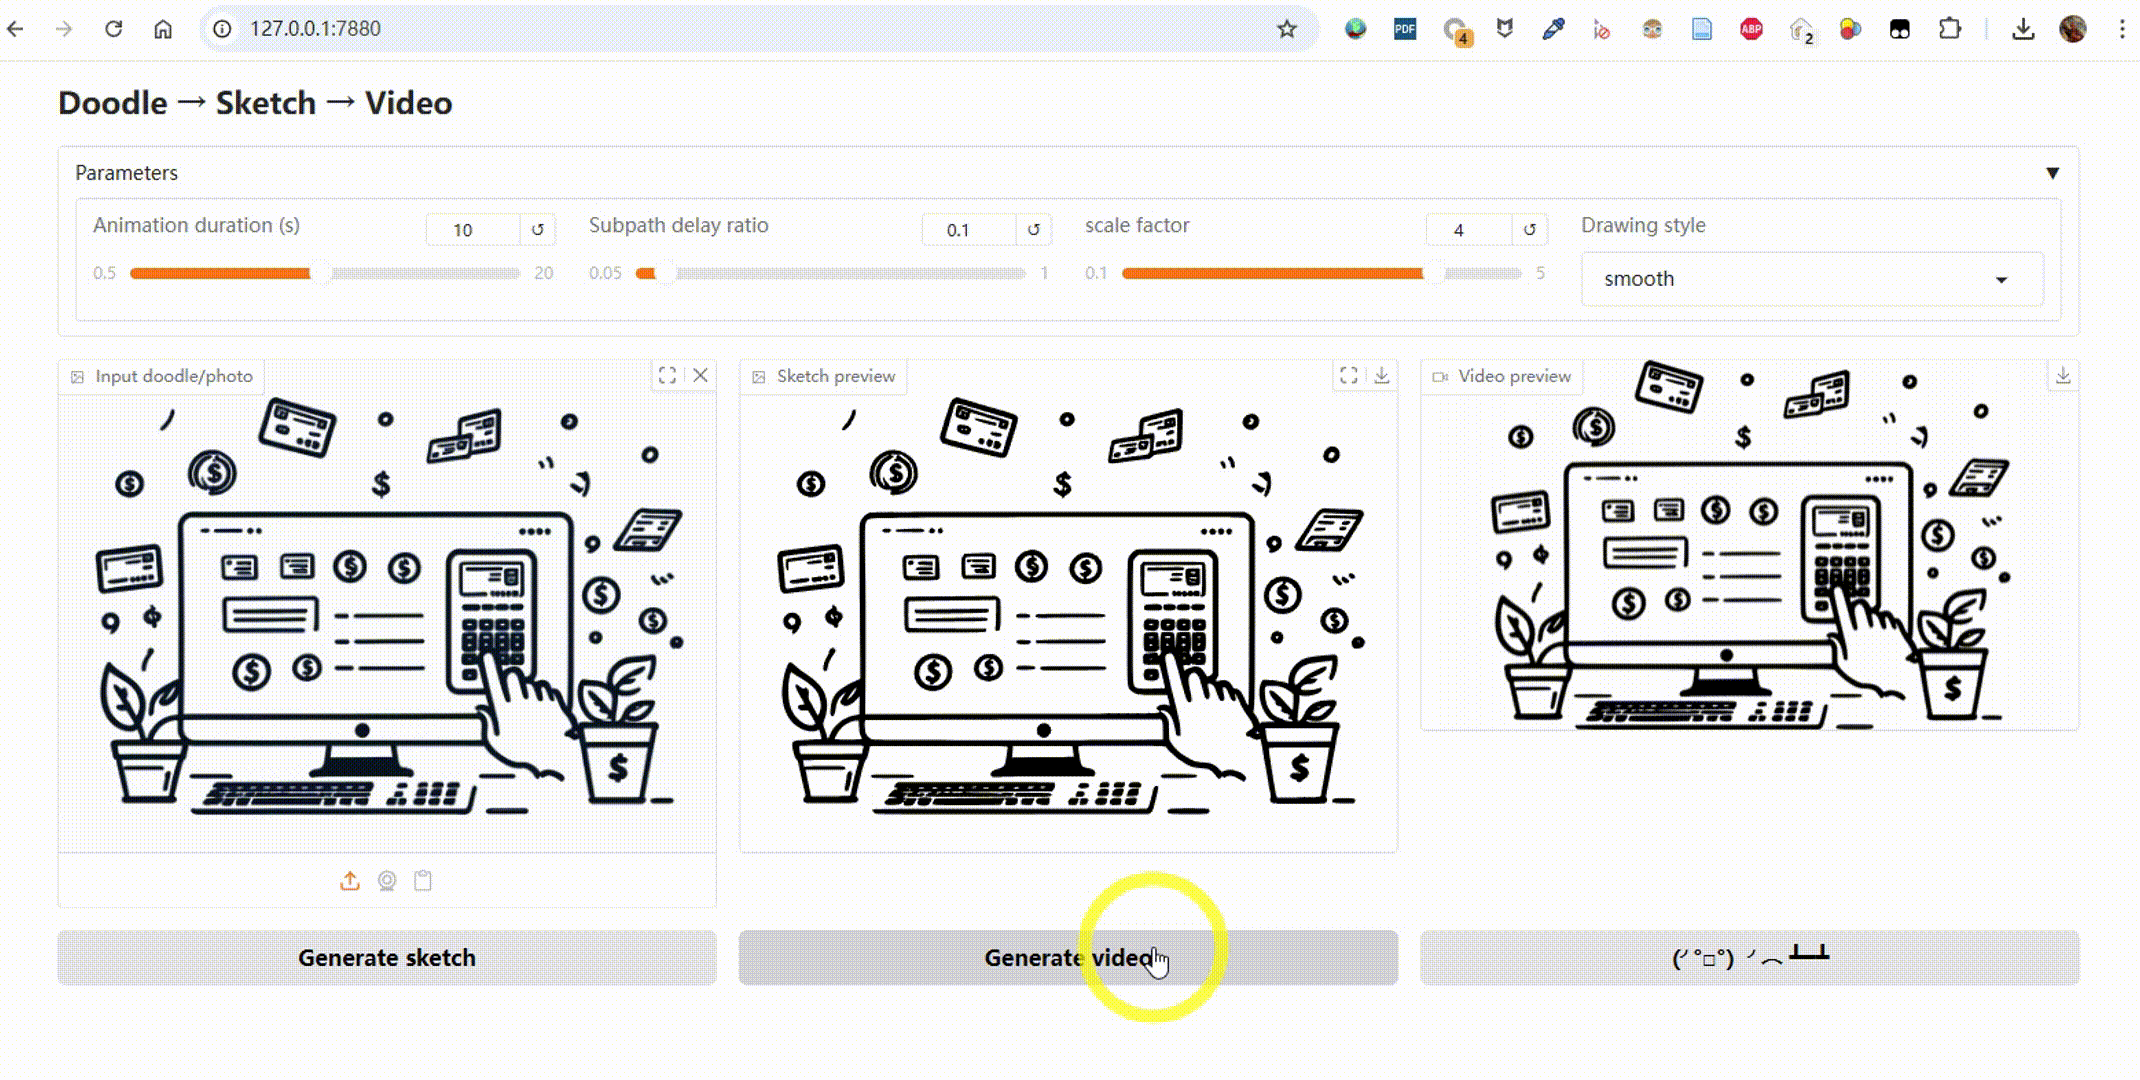
Sketch2Motion
382leeyeel/Sketch2Motion · PythonSketch2Motion converts a photo, doodle, or sketch into an animated drawing-style MP4 video, as if someone were drawing it by hand.
Related topics
Often tagged together