Topics / #vision-transformer
Vision-transformer projects on GitHub
Transformer-based neural architectures adapted for computer vision tasks.
As of , the most-starred Vision-transformer projects on GitHub are mmdetection (33K stars), deep-learning-for-image-processing (26.4K stars) and vit-pytorch (25.6K stars). GitHub.Locker tracks 16 Vision-transformer repositories with 186K stars combined. The fastest-growing on October 16 was modlens, with +24 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +24
modlens
liustack/modlens · ★ 4.3KModLens is a vision plugin for DeepSeek Harness (dsh) that gives text-only coding models like DeepSeek and GLM the ability to see. Paste an image into the chat and it returns structured JSON evidence from OCR, layout, and semantic analysis.
dinov3
facebookresearch/dinov3 · ★ 11.6KMeta AI Research (FAIR)'s reference PyTorch implementation and model release for DINOv3, a family of vision foundation models that produce high-quality dense features and perform strongly across many vision tasks.
 +5
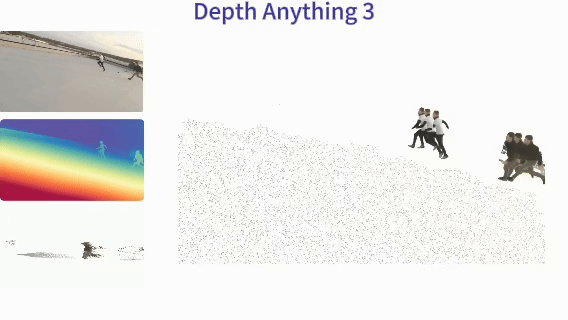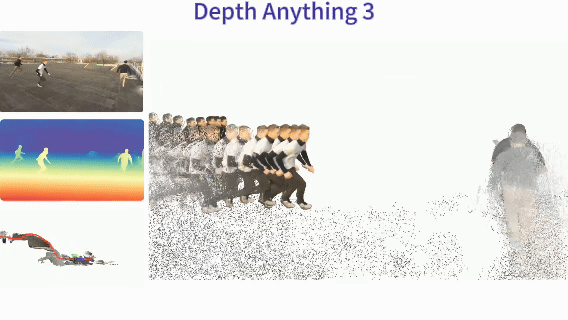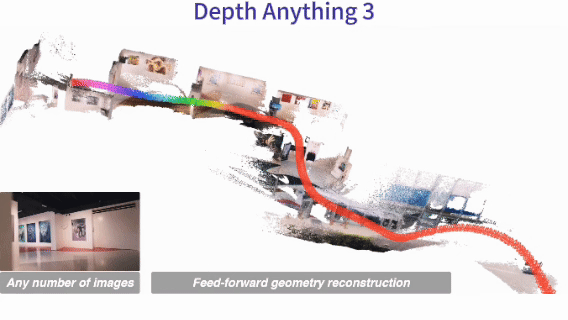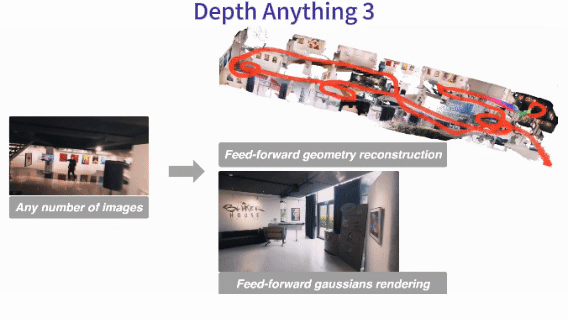
Depth-Anything-3
ByteDance-Seed/Depth-Anything-3 · ★ 6.5KDepth Anything 3 (DA3) is a foundation model from ByteDance Seed that predicts spatially consistent geometry — depth, camera poses, even 3D Gaussians — from arbitrary visual inputs, with or without known camera poses.
 +4
dinov2
facebookresearch/dinov2 · ★ 13.4KDINOv2, a self-supervised visual feature learning method from Meta AI's FAIR team, shipped as PyTorch code and pretrained models. Its features plug into classifiers as simple as linear layers across many vision tasks, with no fine-tuning required.
The all-time top
16 projects · by stars
- 33K
 #1 · open-mmlab/mmdetection
mmdetection
MMDetection is an open source object detection toolbox built on PyTorch, part of the OpenMMLab project, that supports object detection, instance segmentation, panoptic segmentation, and semi-supervised detection.
- 26.4K
 #2 · WZMIAOMIAO/deep-learning-for-image-processing
deep-learning-for-image-processing
A video-based deep learning course that walks through classic computer-vision architectures for image classification, object detection, segmentation and keypoint detection, pairing each network with a lecture and runnable code.
- 25.6K
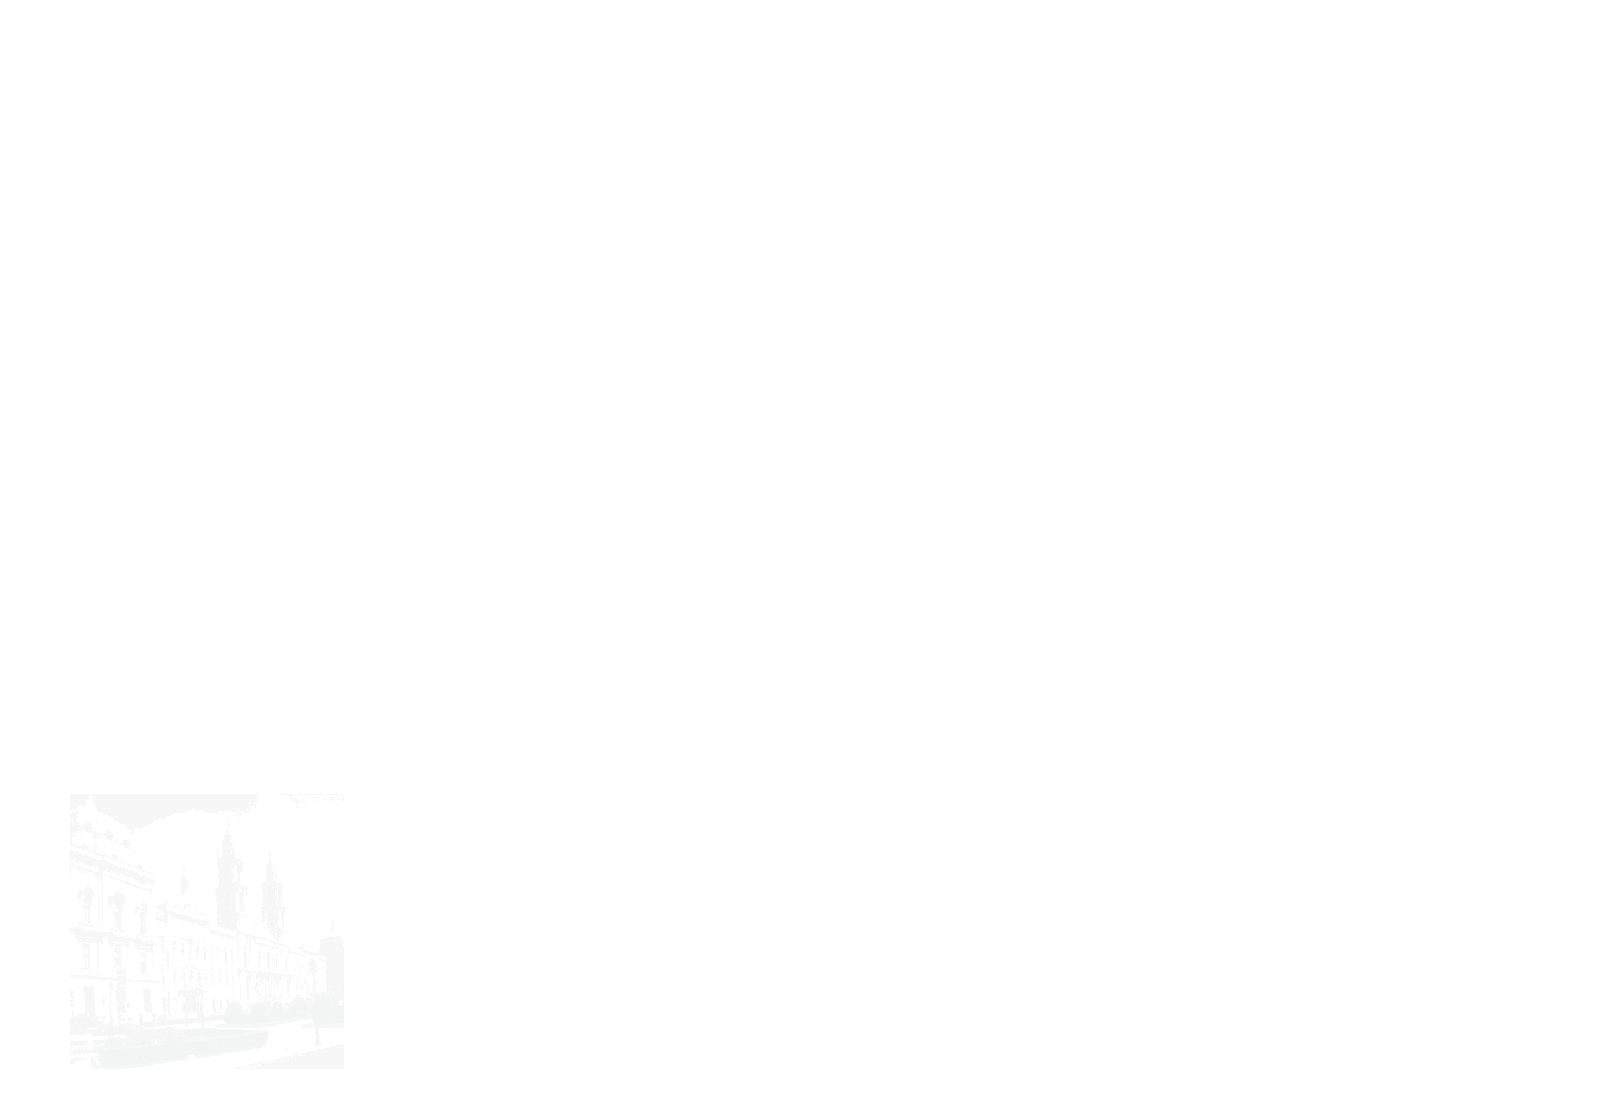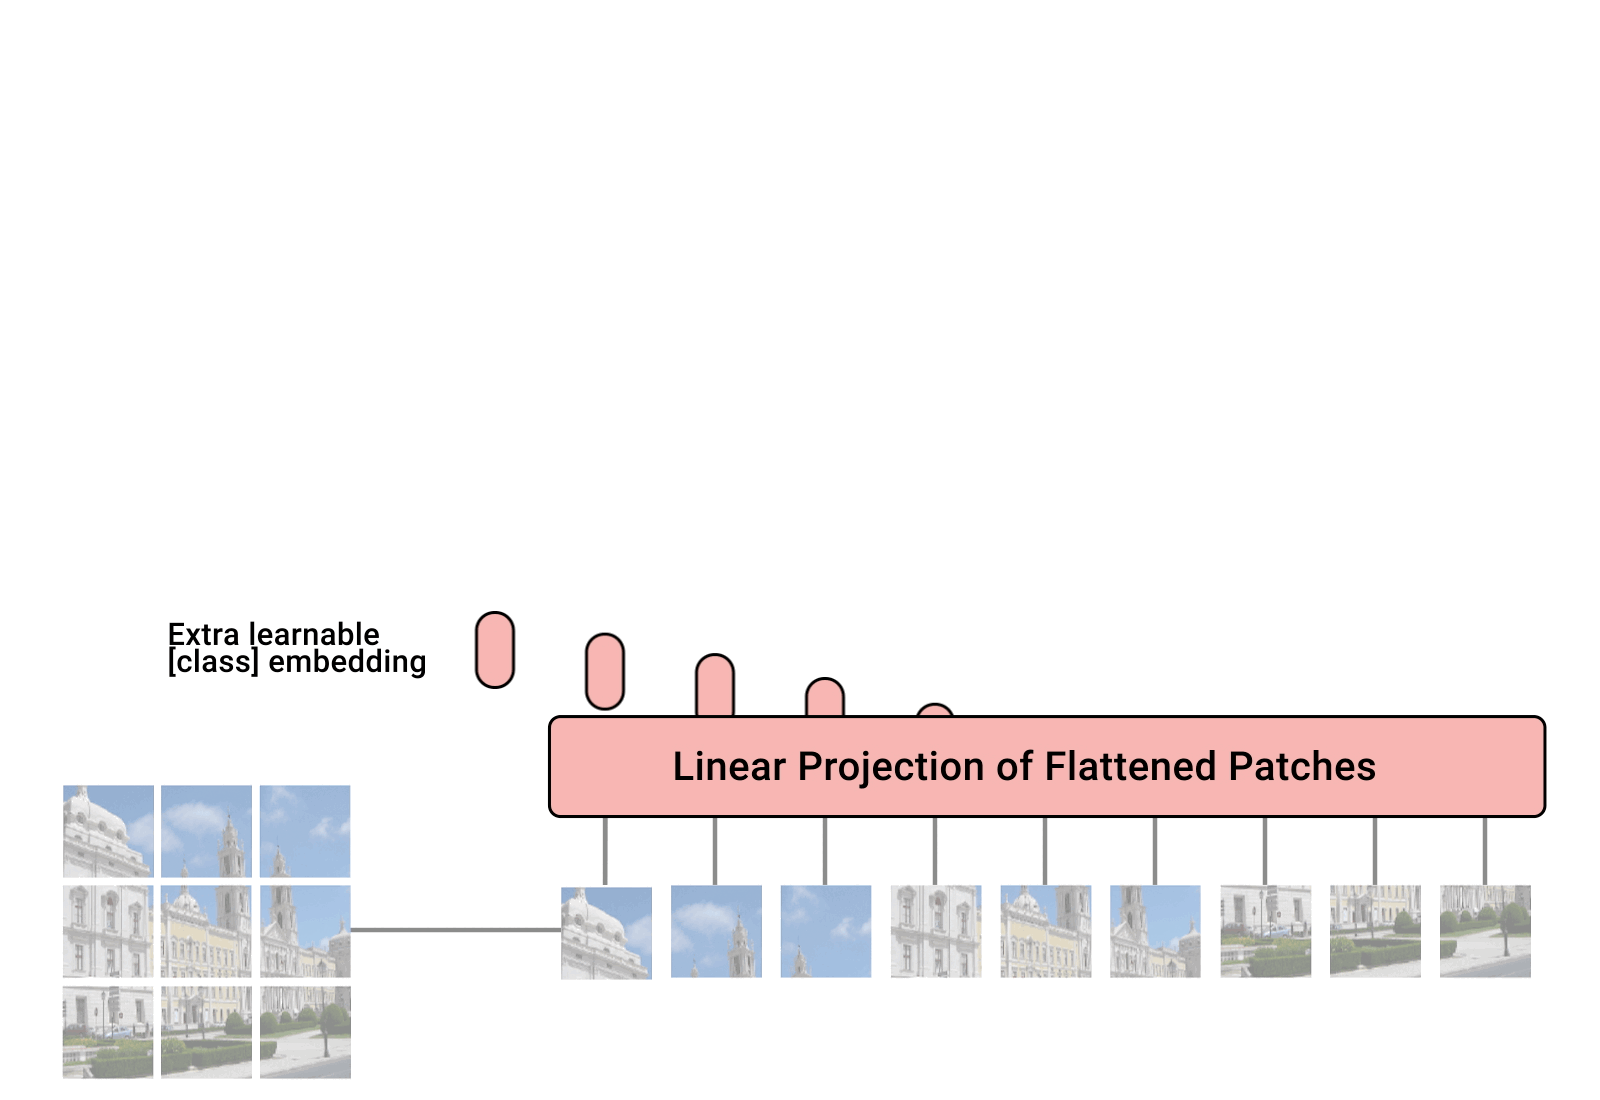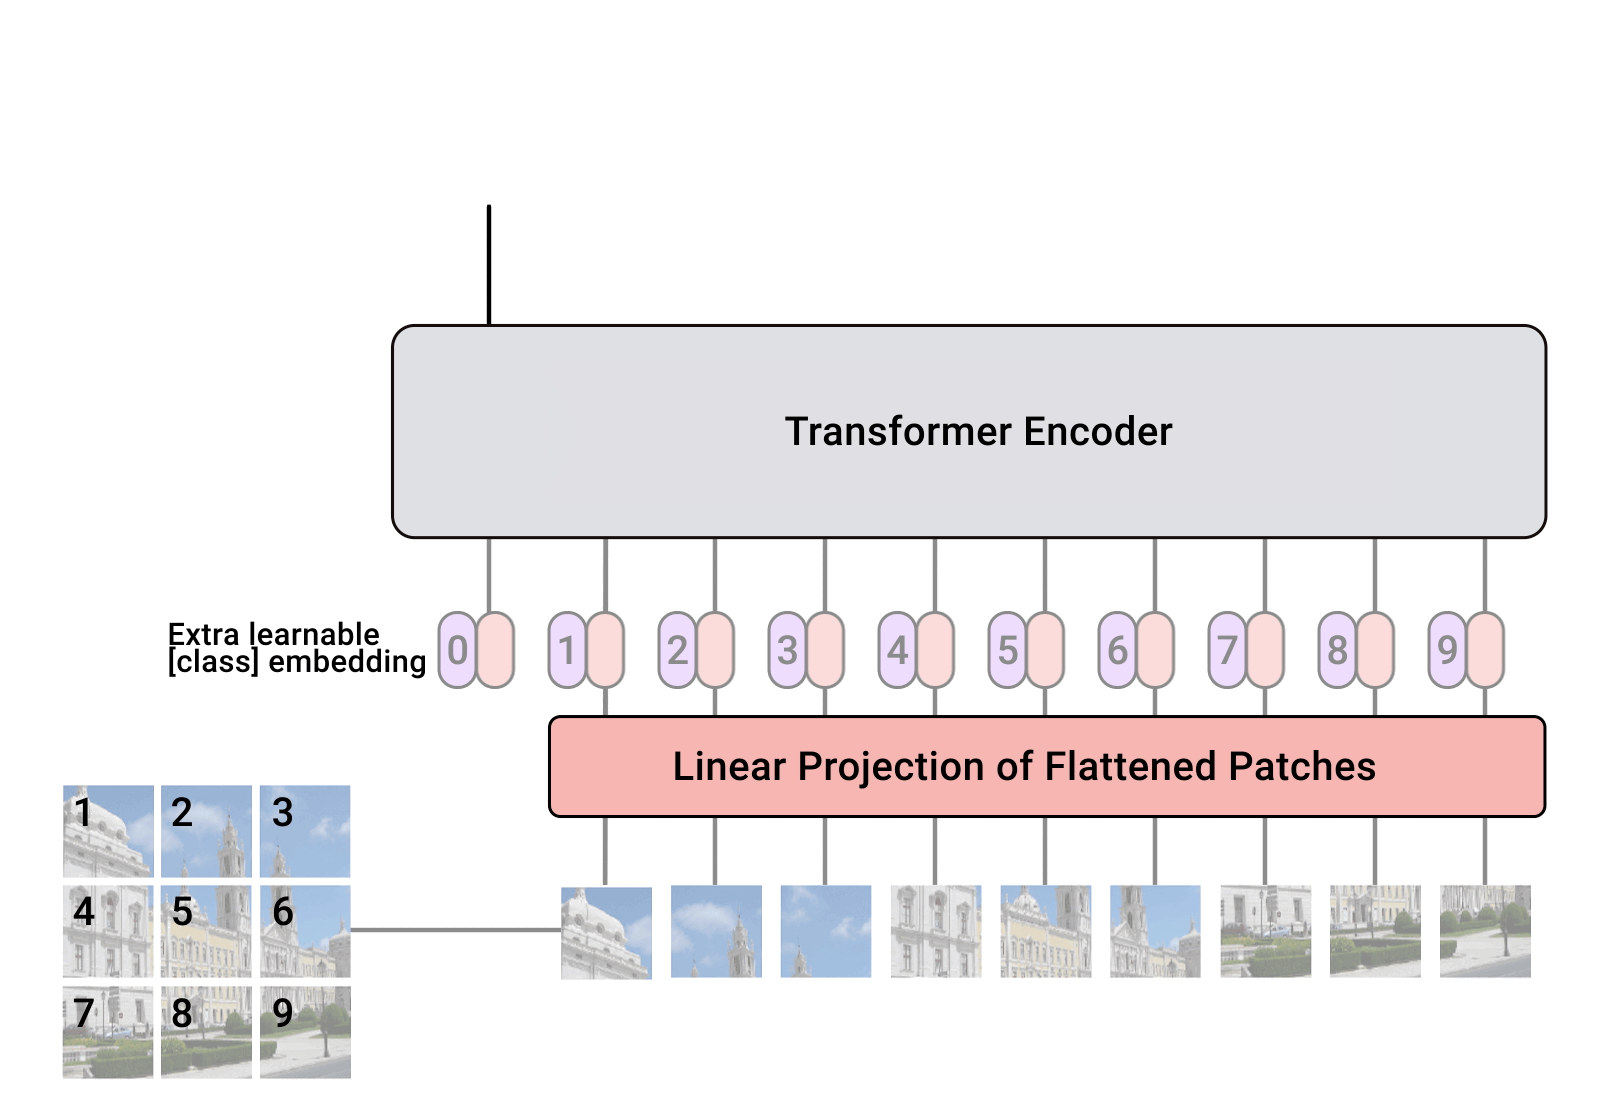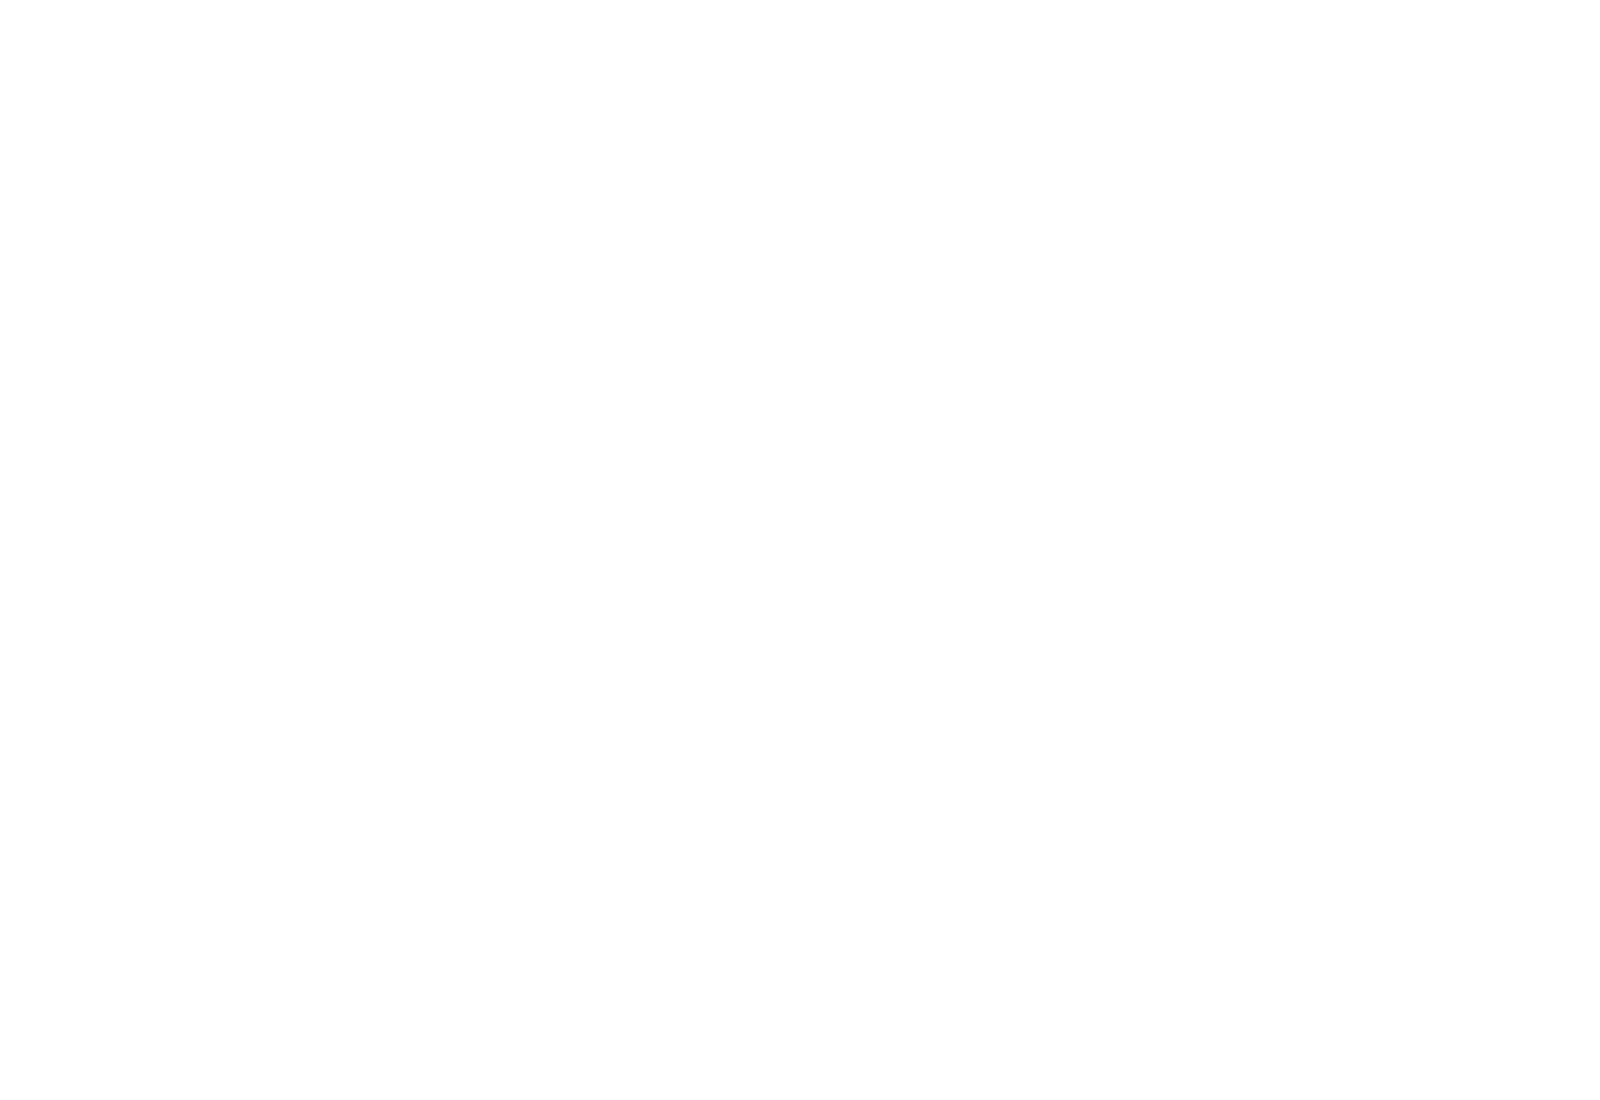 #3 · lucidrains/vit-pytorch
vit-pytorch
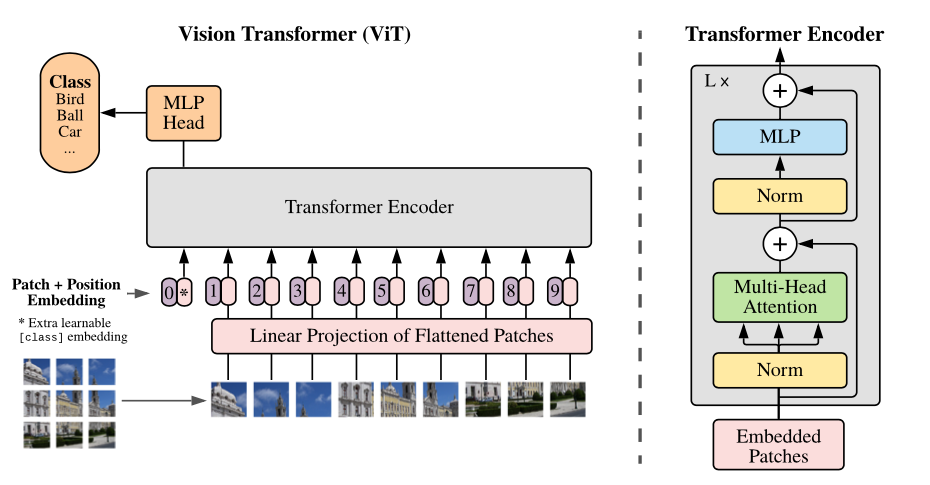
A PyTorch implementation of the Vision Transformer (ViT), an image classification model that reaches SOTA results using just a single transformer encoder instead of convolutions.
- 4

LaTeX-OCR
16.6Klukas-blecher/LaTeX-OCR · PythonA learning-based OCR system: feed it an image of a math formula and it returns the matching LaTeX code.
- 5
Swin-Transformer
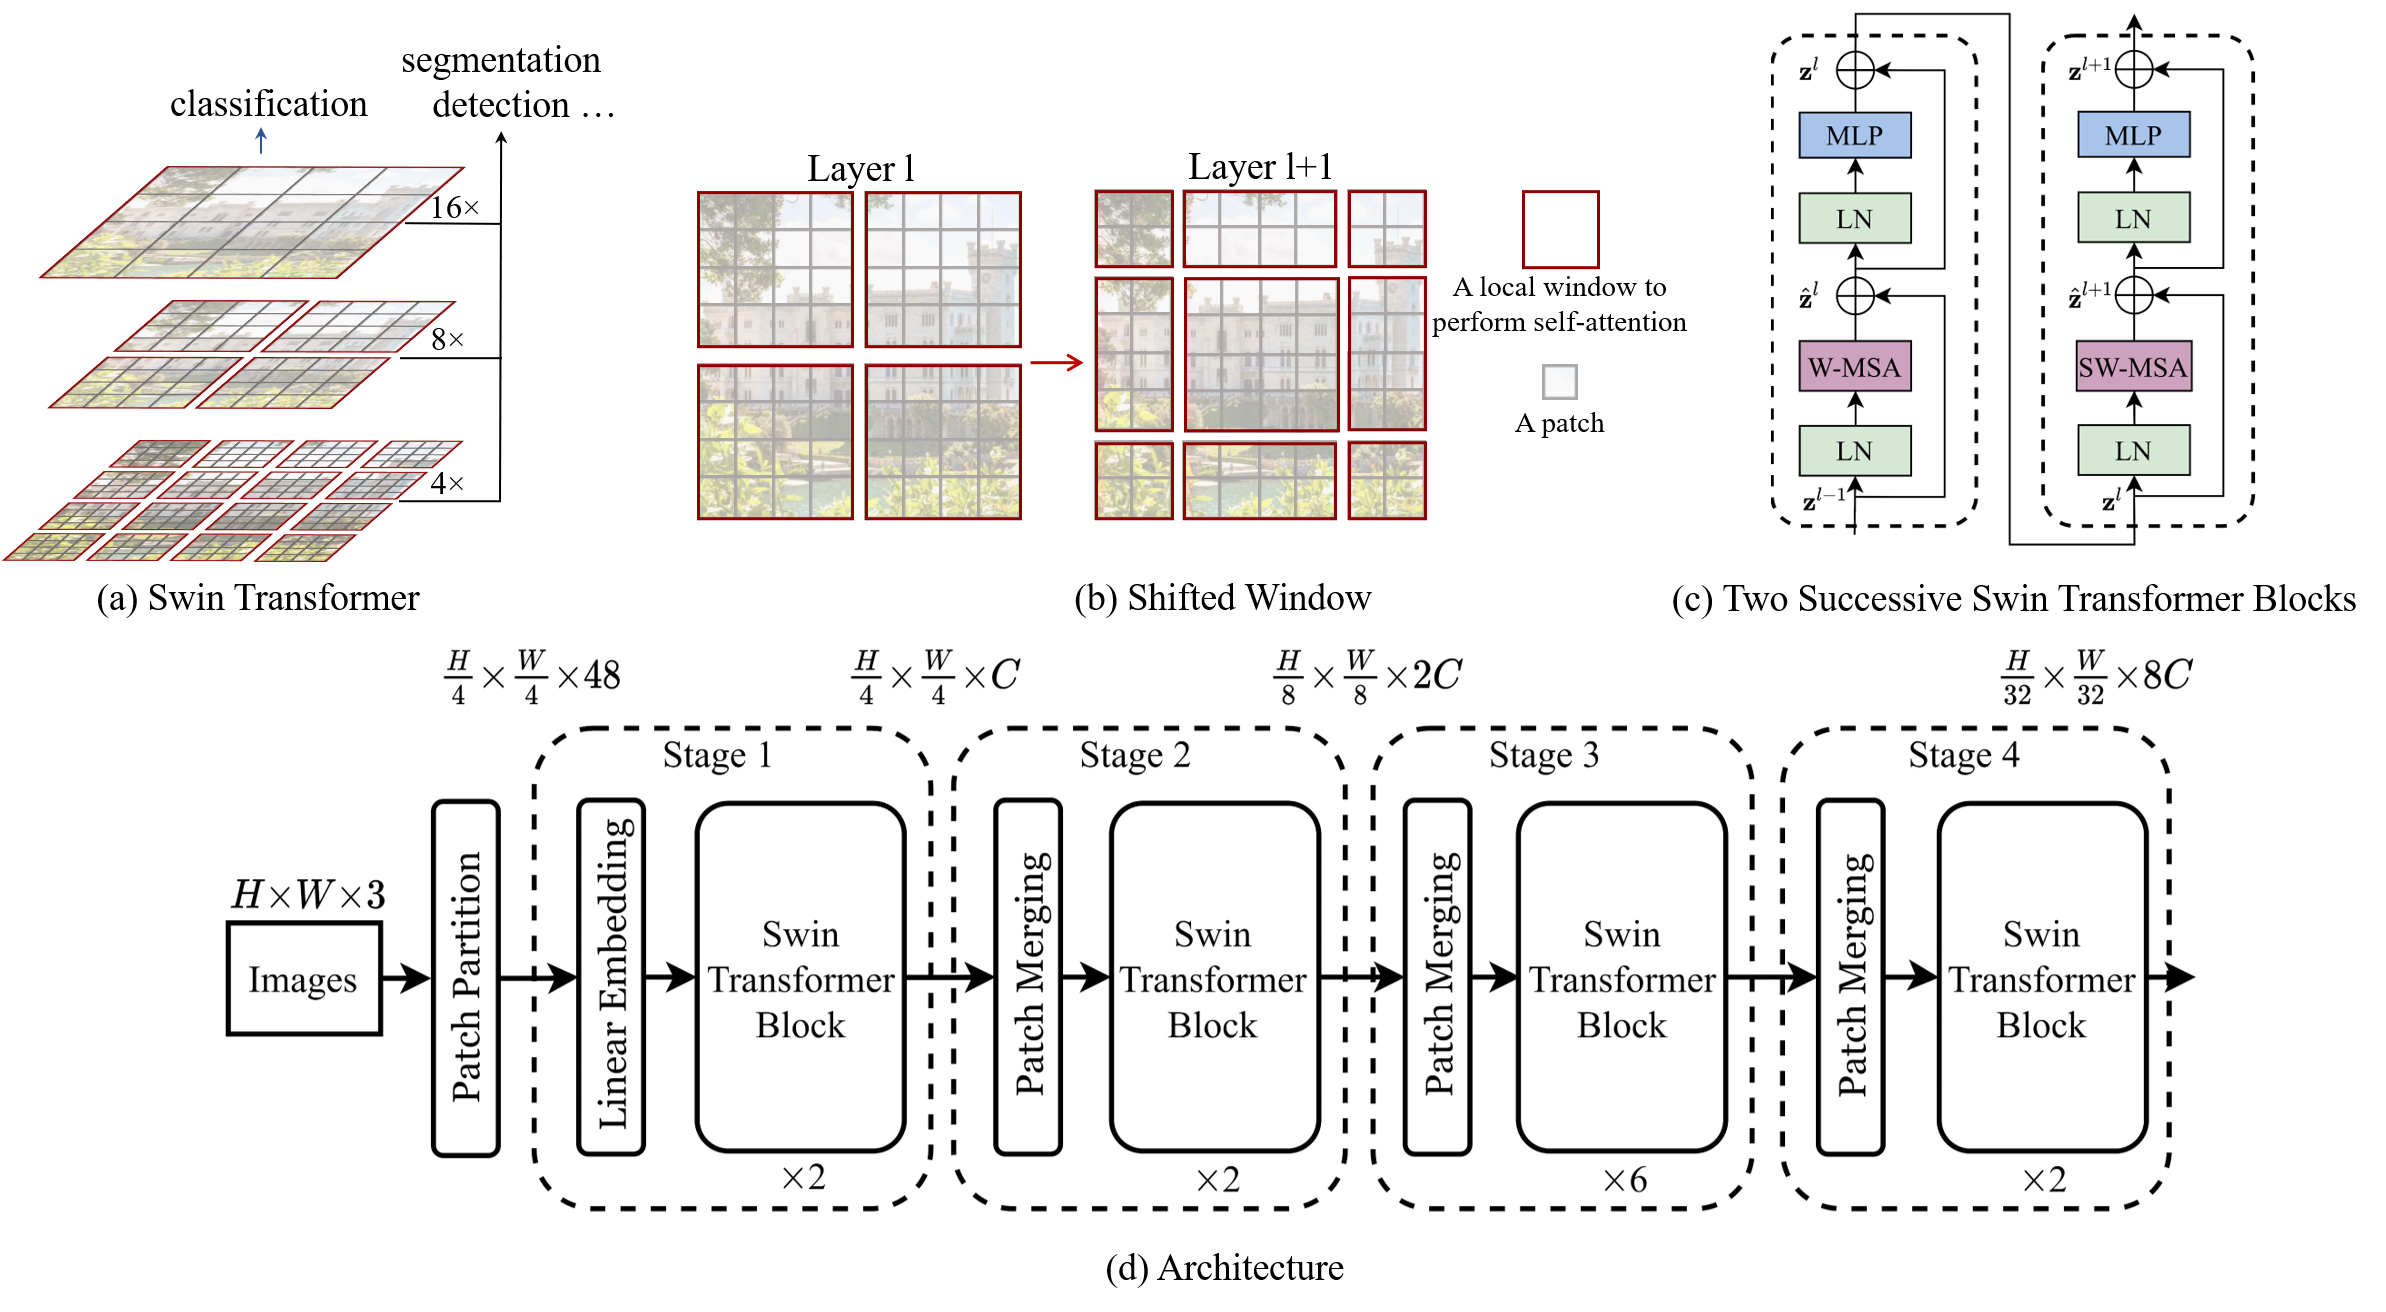
16.1Kmicrosoft/Swin-Transformer · PythonThe official Microsoft implementation of the Swin Transformer paper and its follow-ups: a hierarchical vision Transformer that computes attention with shifted windows and serves as a general-purpose backbone for computer vision tasks.
- 6
dinov2
13.4Kfacebookresearch/dinov2 · Jupyter NotebookDINOv2, a self-supervised visual feature learning method from Meta AI's FAIR team, shipped as PyTorch code and pretrained models. Its features plug into classifiers as simple as linear layers across many vision tasks, with no fine-tuning required.
- 7
vision_transformer
12.7Kgoogle-research/vision_transformer · Jupyter NotebookThis is Google Research's official JAX/Flax code release for Vision Transformer (ViT) and MLP-Mixer image classification models, including pretrained checkpoints and scripts to fine-tune them on your own data.
- 8

Transformers-Tutorials
11.8KNielsRogge/Transformers-Tutorials · Jupyter NotebookA collection of Jupyter notebook demos showing how to use HuggingFace's Transformers library in PyTorch, covering models like BERT, GPT-2, LayoutLM, DETR, Donut and many more.
- 9
dinov3
11.6Kfacebookresearch/dinov3 · Jupyter NotebookMeta AI Research (FAIR)'s reference PyTorch implementation and model release for DINOv3, a family of vision foundation models that produce high-quality dense features and perform strongly across many vision tasks.
- 10
Depth-Anything-3
6.5KByteDance-Seed/Depth-Anything-3 · PythonDepth Anything 3 (DA3) is a foundation model from ByteDance Seed that predicts spatially consistent geometry — depth, camera poses, even 3D Gaussians — from arbitrary visual inputs, with or without known camera poses.
- 11
doctr
6.4Kmindee/doctr · PythondocTR is a Python library for Optical Character Recognition (OCR) that localizes and reads text in documents using deep learning, with PyTorch and TensorFlow2 backends.
- 12
modlens
4.3Kliustack/modlens · TypeScriptModLens is a vision plugin for DeepSeek Harness (dsh) that gives text-only coding models like DeepSeek and GLM the ability to see. Paste an image into the chat and it returns structured JSON evidence from OCR, layout, and semantic analysis.
- 13
OpenDLSS-NR
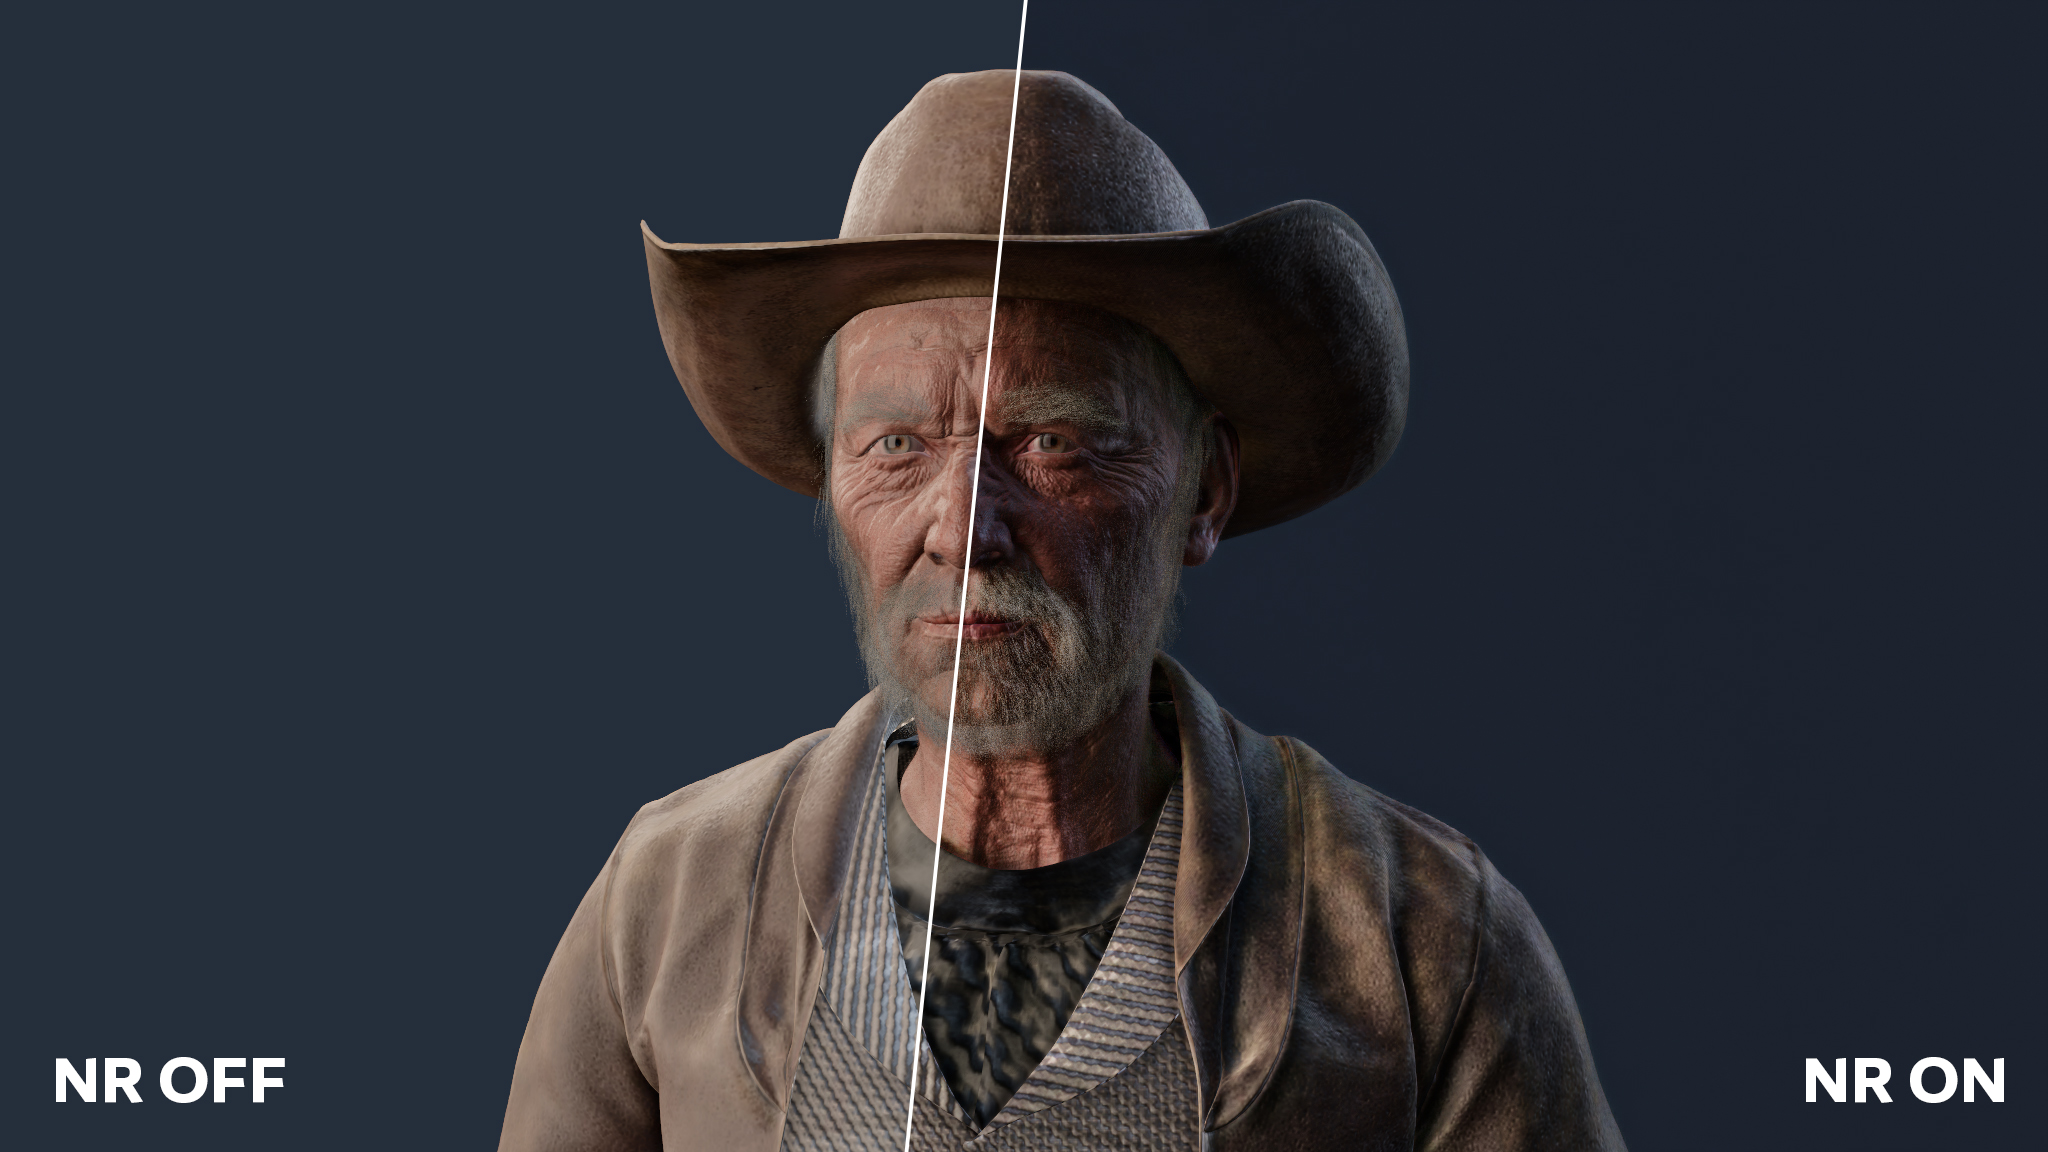
921maanHimself/OpenDLSS-NR · JavaScriptOpenDLSS-NR is a from-scratch Vulkan reimplementation of NVIDIA's DLSS 5 Neural Rendering network, matching the original bit-exactly down to every internal block boundary, not just the final image.
- 14

LeVJEPA
270MLO-lab/LeVJEPA · Jupyter NotebookThe official implementation of LeVJEPA — a self-supervised video encoder trained with LeJEPA's collapse-free objective. Unlike V-JEPA or VideoMAE it needs no EMA target encoder, stop-gradient, predictor, or pixel-reconstruction decoder: just an encoder, a small projector, and one loss hyperparameter.
- 15
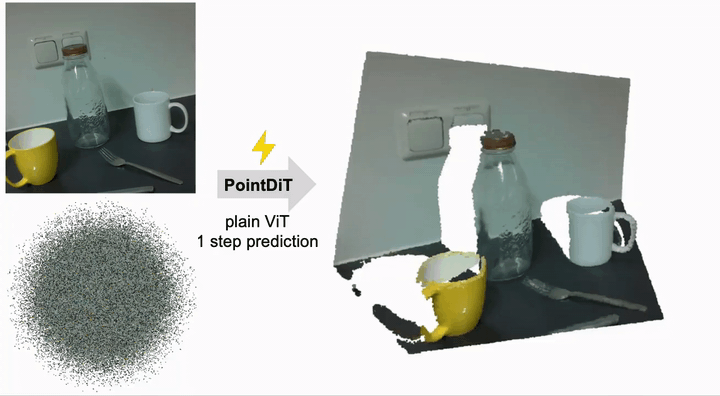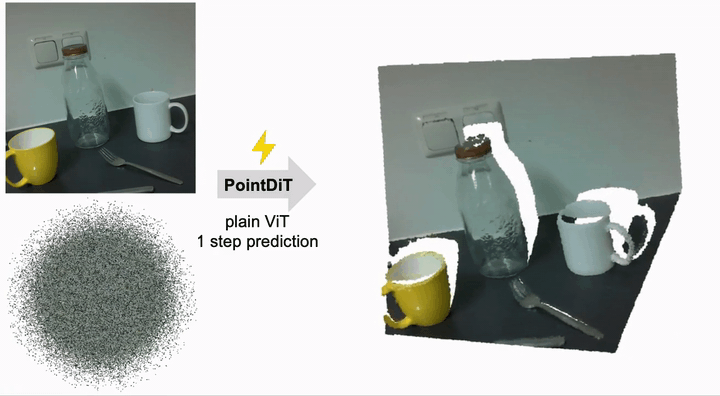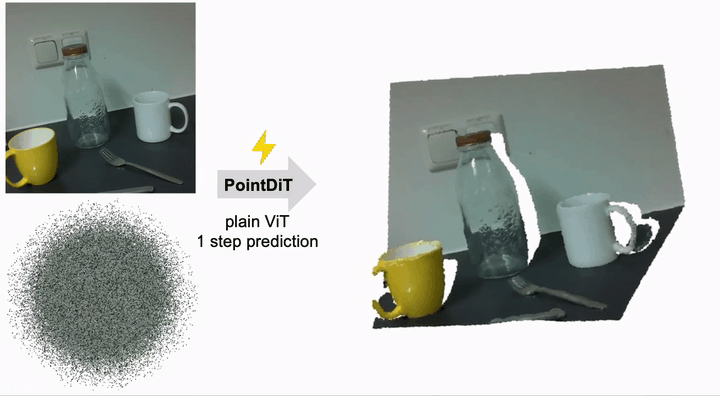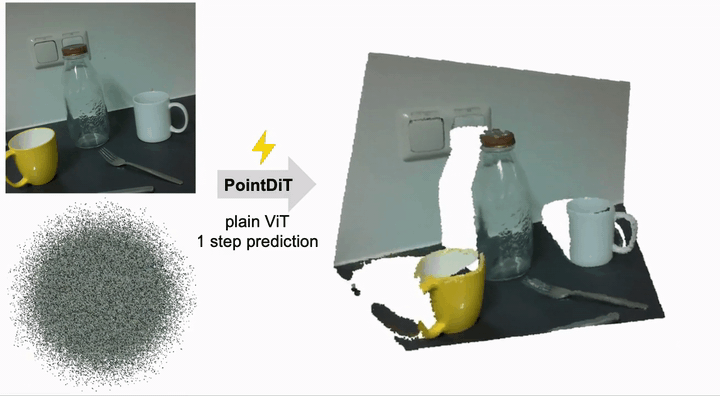
pointdit
233google-research/pointdit · PythonPointDiT is a research codebase for a minimalist pixel-space Diffusion Transformer that estimates 3D geometry (point maps) from a single monocular image.
- 16
High-Angle_Robust_Fast_FaceAlignment
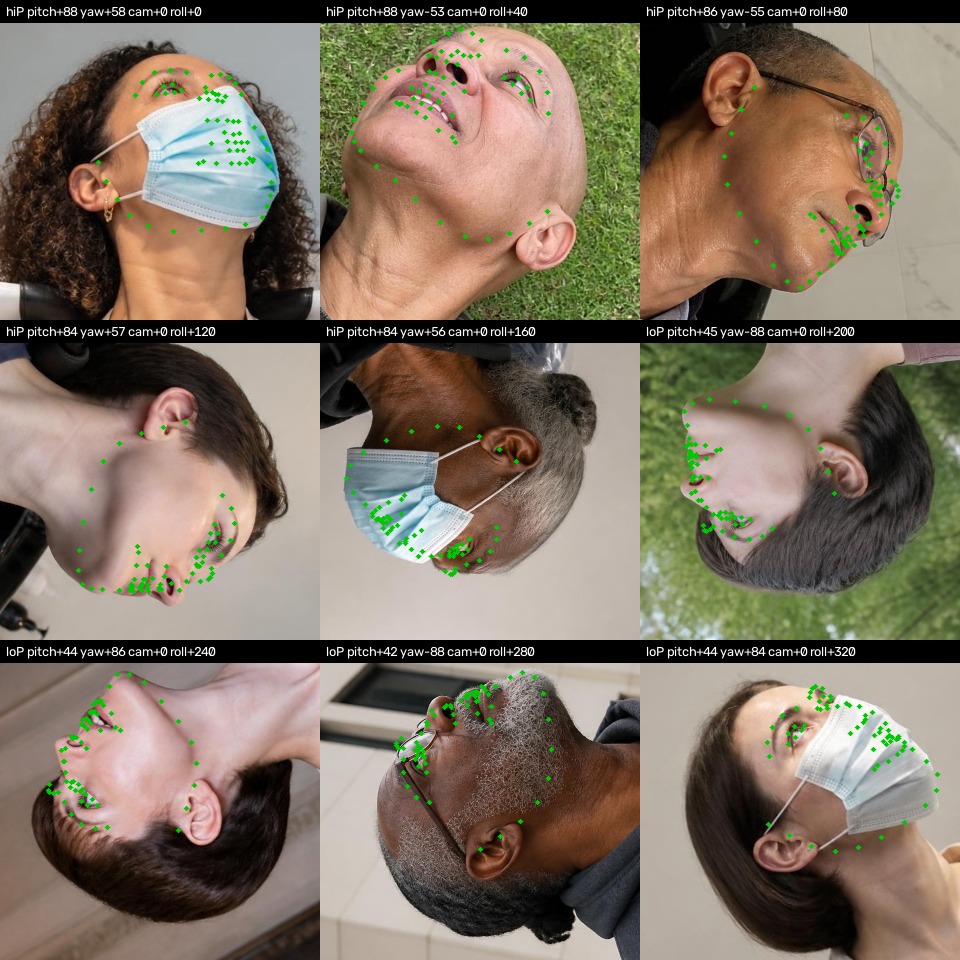
195PINTO0309/High-Angle_Robust_Fast_FaceAlignment · PythonHRFFA is a training, distillation and ONNX deployment pipeline for whole-head face alignment that stays robust at extreme head poses (looking up/down, full 360° roll, profile views) while being light enough for CPU inference.
Related topics
Often tagged together
- computer-vision384
- deep-learning737
- python2,383
- machine-learning916
- pytorch419
- research764
- transformer212
- gpu789
- cuda396
- image-classification47
- apache-2.01,434
- object-detection69
- open-source5,666
- pretrained-models74
- huggingface362
- image-processing242
- jupyter notebook176
- neural-network166
- benchmark431
- embeddings135
- fine-tuning185
- linux4,184
- mit3,312
- nvidia328