Topics / #speculative-decoding
Speculative-decoding projects on GitHub
Inference technique that speeds up language model generation by drafting and verifying tokens in parallel.
As of , the most-starred Speculative-decoding projects on GitHub are vllm (94K stars), Strata (26.4K stars) and ds4 (23.9K stars). GitHub.Locker tracks 40 Speculative-decoding repositories with 259.7K stars combined. The fastest-growing on October 16 was Strata, with +718 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +718
Strata
Niko1221/Strata · ★ 26.4KStrata runs Qwen3.8-Flash-Next, a 125-billion-parameter AI model, on a normal gaming PC with one NVIDIA GPU (12-24GB VRAM) and 64GB of RAM, with a one-click installer for Windows and Linux.
 +79
Soup
MakazhanAlpamys/Soup · ★ 9.2KSoup is a command-line tool for fine-tuning and post-training LLMs from a single YAML config file, automating GPU detection, batching and quantization so you just write a config and run one command.
 +73
vllm
vllm-project/vllm · ★ 94KvLLM is a library for fast LLM inference and serving, built around PagedAttention for efficient memory management of attention keys and values.
 +58
project-maya
mw00/project-maya · ★ 954Project Maya lets you run GLM-5.3-Flash, a 321-billion-parameter mixture-of-experts AI model, on your own NVIDIA GPU(s) by streaming the model's experts across VRAM, RAM and NVMe SSD as the conversation needs them.
The all-time top
40 projects · by stars
- 94K#1 · vllm-project/vllm
vllm
vLLM is a library for fast LLM inference and serving, built around PagedAttention for efficient memory management of attention keys and values.
- 26.4K#2 · Niko1221/Strata
Strata
Strata runs Qwen3.8-Flash-Next, a 125-billion-parameter AI model, on a normal gaming PC with one NVIDIA GPU (12-24GB VRAM) and 64GB of RAM, with a one-click installer for Windows and Linux.
- 23.9K
 #3 · antirez/ds4
ds4
DwarfStar (ds4) is a small, self-contained local inference engine specialized for running DeepSeek V4 Flash and PRO, plus GLM 5.2/5.3, on consumer hardware like high-memory Macs, NVIDIA GPUs, and AMD Strix Halo systems.
- 4
TensorRT-LLM
14.8KNVIDIA/TensorRT-LLM · PythonTensorRT LLM is NVIDIA's Python framework for defining large language models (and now visual generation models) and compiling them into highly optimized inference engines that run on NVIDIA GPUs, with specialized kernels and Python/C++ runtimes.
- 5
PaddleNLP
13KPaddlePaddle/PaddleNLP · PythonPaddleNLP is a large language model (LLM) and small language model (SLM) development toolkit built on the PaddlePaddle deep learning framework, offering efficient training, lossless compression, and high-performance inference for large models.
- 6
MiniCPM
11.6KOpenBMB/MiniCPM · Jupyter NotebookMiniCPM is OpenBMB's family of small, open-source LLMs built for on-device and resource-constrained use. The newest release, MiniCPM5-2B, is a dense 2B-parameter model that reaches open-source state-of-the-art for its size class while staying competitive with much larger 4B-class models.
- 7
text-generation-inference
10.9Khuggingface/text-generation-inference · PythonText Generation Inference (TGI) is a toolkit for deploying and serving large language models — a Rust, Python and gRPC server that powers Hugging Chat, the Inference API and Inference Endpoints at Hugging Face.
- 8
Soup
9.2KMakazhanAlpamys/Soup · PythonSoup is a command-line tool for fine-tuning and post-training LLMs from a single YAML config file, automating GPU detection, batching and quantization so you just write a config and run one command.
- 9

GLM-5
7.3Kzai-org/GLM-5GLM-5 is a family of large open-weight language models from Z.ai built for agentic engineering and complex, long-horizon coding tasks, scaling up to 744B parameters with sparse attention for efficient long-context serving.
- 10

DeepSpec
7.2Kdeepseek-ai/DeepSpec · PythonDeepSpec is DeepSeek's full-stack Python codebase for training and evaluating draft models for speculative decoding — the technique where a small draft model accelerates a larger target LLM.
- 11

lectures
6.9Kgpu-mode/lectures · Jupyter NotebookThis is the supplementary material repository for the GPU MODE lectures YouTube channel — a growing collection of notebooks, slides and code from each numbered lecture on GPU and CUDA programming.
- 12
dflash
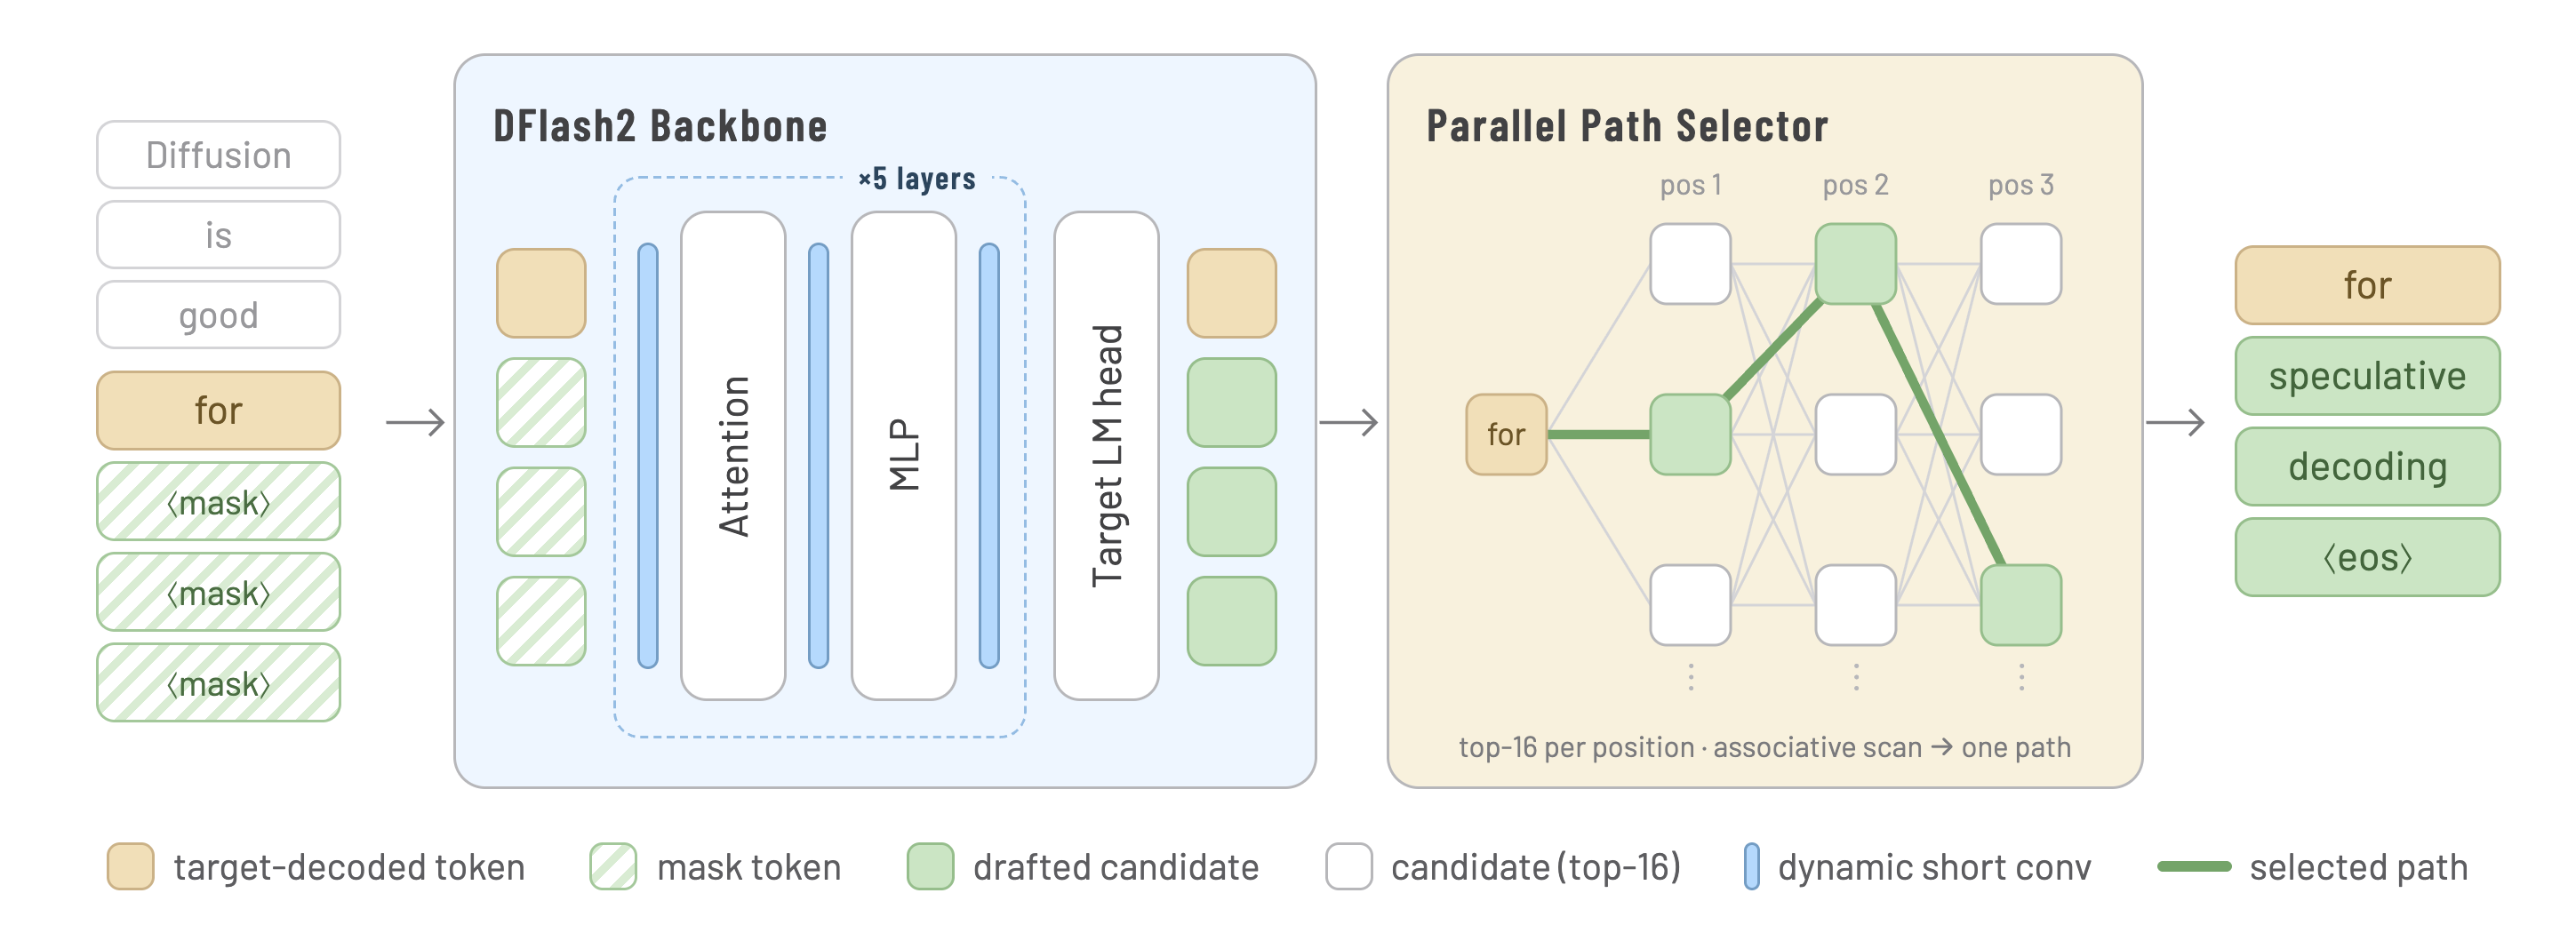
6.2Kz-lab/dflash · PythonDFlash is a lightweight block diffusion model built for speculative decoding, drafting tokens in parallel blocks so a larger target LLM can verify them faster than generating one token at a time.
- 13
Model-Optimizer
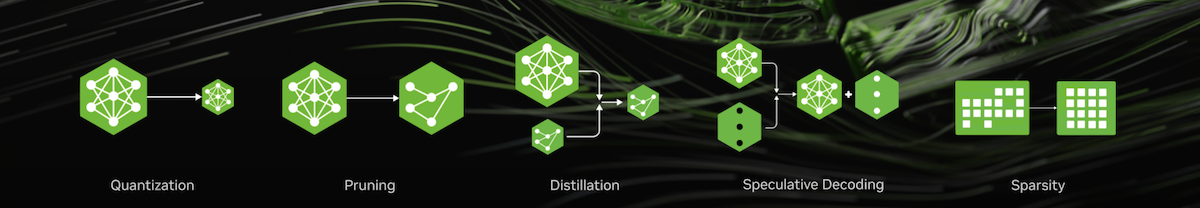
5.3KNVIDIA/Model-Optimizer · PythonNVIDIA Model Optimizer (ModelOpt) is a Python library that bundles state-of-the-art model-compression techniques - quantization, pruning, neural architecture search, distillation, speculative decoding and sparsity - to shrink and speed up deep learning models before deployment.
- 14
Rapid-MLX
4Kraullenchai/Rapid-MLX · PythonRapid-MLX is a local LLM inference server for Apple Silicon Macs, built on MLX, that exposes OpenAI- and Anthropic-compatible APIs and focuses on reliable tool calling for coding agents like Claude Code and Codex CLI.
- 15

HyperQwen
2Ksyv-ai/HyperQwen · PythonHyperQwen is a self-hosted serving setup that runs the Qwen3.8-27B model on a single 24 GB consumer GPU (like an RTX 3090) using vLLM, exposing it through an OpenAI-compatible API.
- 16
mlx-serve
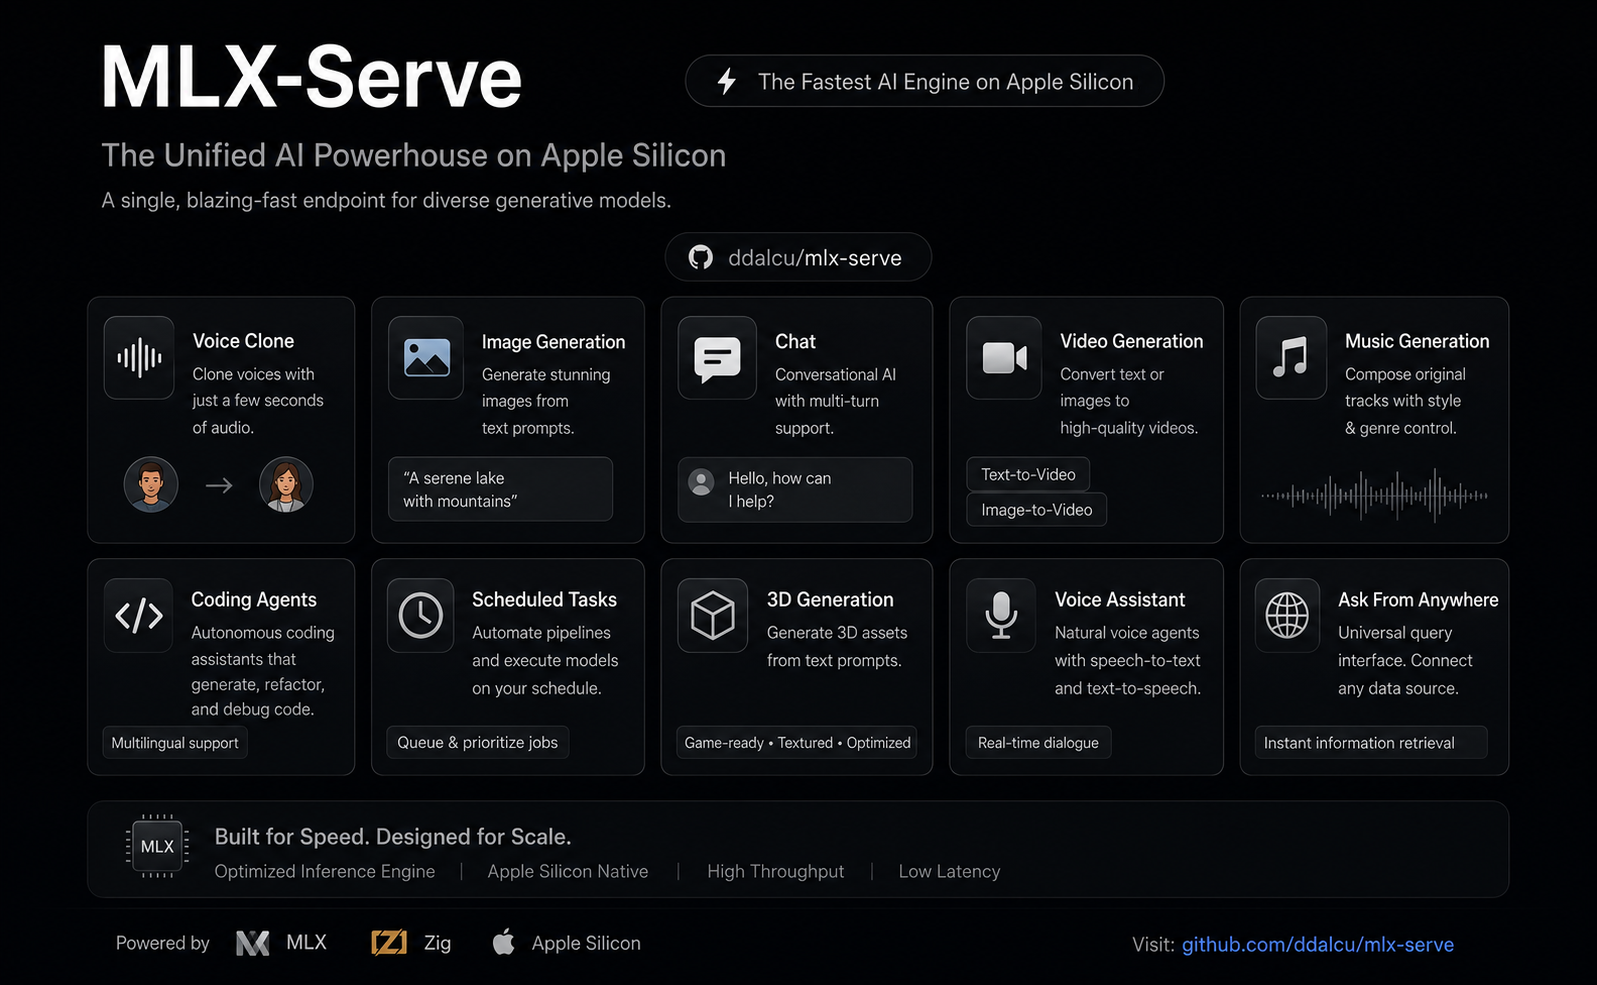
2Kddalcu/mlx-serve · Zigmlx-serve is a native local inference server for Apple Silicon Macs that runs MLX and GGUF language models and exposes OpenAI-, Anthropic-, and Ollama-compatible APIs, plus generates images, video, music, speech, and 3D models, all without Python or a cloud connection.
- 17
ai-engineering-interview-questions-company-wise
1.8Kpallavi-shekhar/ai-engineering-interview-questions-company-wise · MarkdownA free, continuously updated cheat sheet of real interview questions asked in AI Engineering interviews at 35 companies (Anthropic, OpenAI, Google DeepMind, Meta, NVIDIA, Databricks and more), organized company by company with answers linked wherever available.
- 18
zero-to-sglang
1.5Kdatawhalechina/zero-to-sglang · PythonThe official SGLang x Datawhale course on LLM inference: it teaches how inference engines work, has you build a mini-sglang from scratch, and then digs into the real SGLang source code.
- 19

TensorFold
1.4Kashhart/TensorFold · ZigTensorFold is an LLM inference engine that serves open-weight language models through an OpenAI-compatible API, running them on Apple Silicon via MLX or on NVIDIA GPUs via CUDA.
- 20
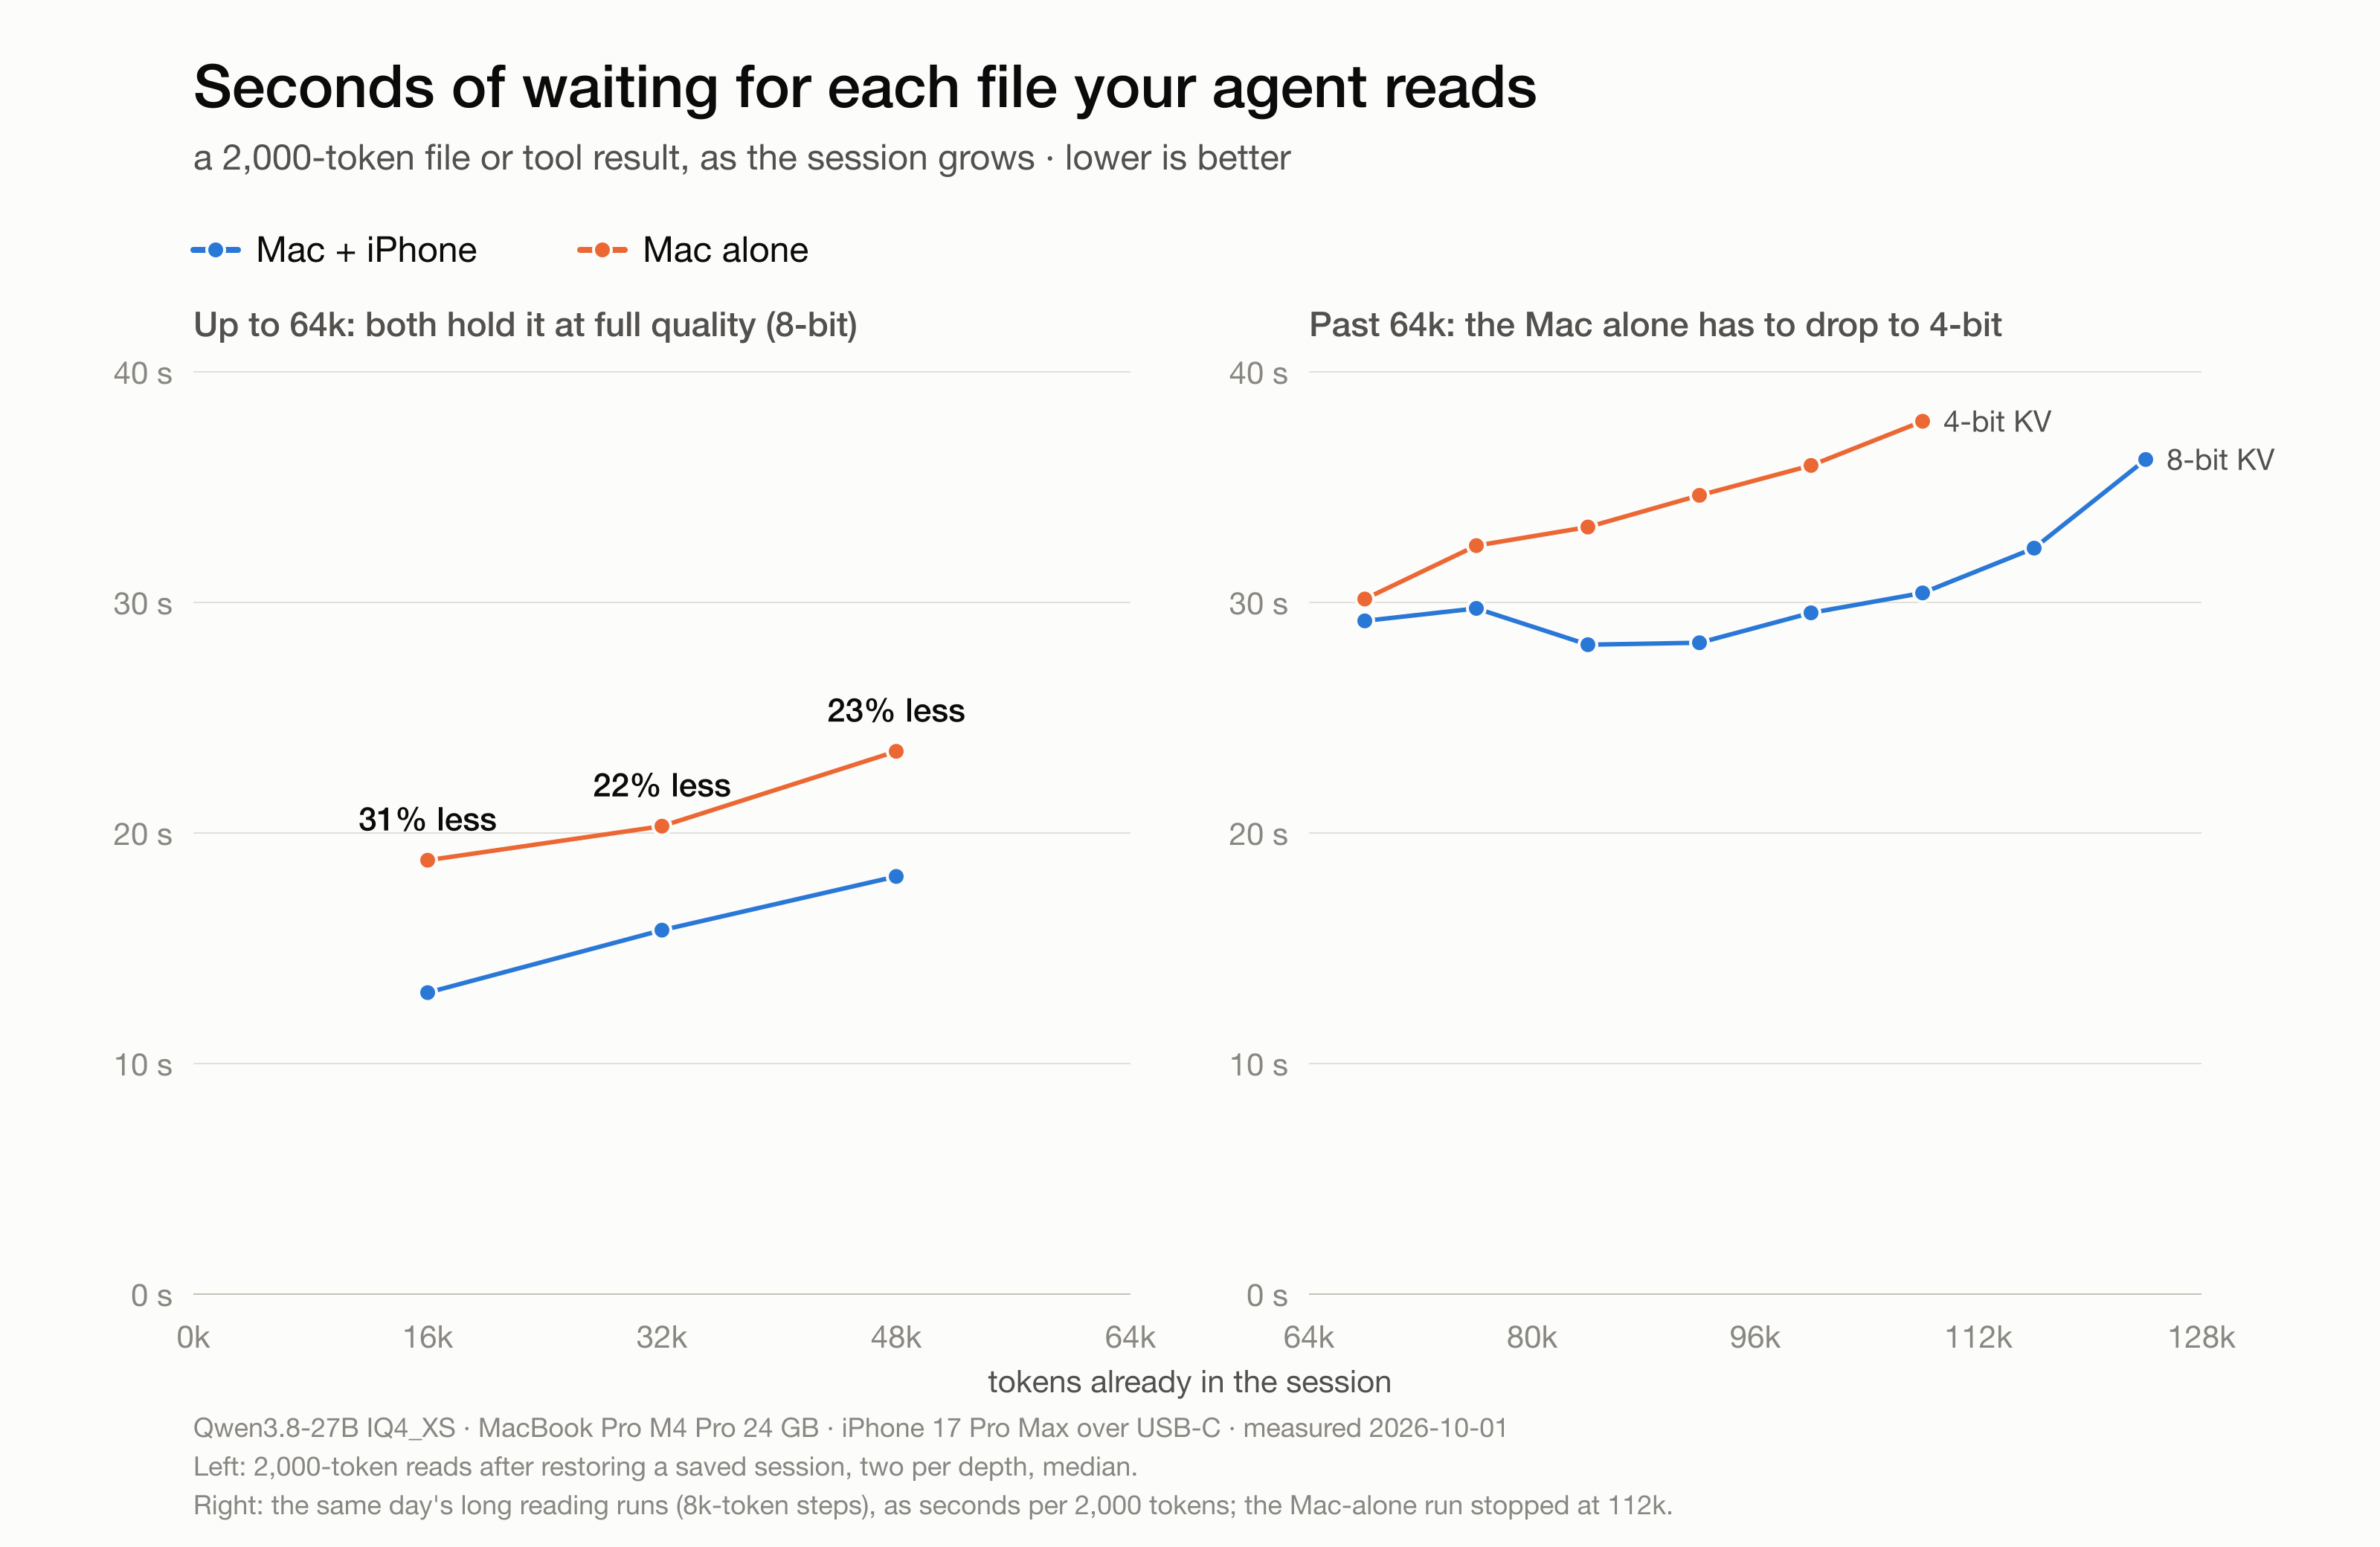
backburner
1KStayLameBro/backburner · PythonBackburner lets a nearby iPhone act as a coprocessor for your Mac so a locally-run 27B LLM (Qwen3.8-27B) reads prompts faster and holds far more context. The phone connects over a 10 Gb/s USB-C cable and offloads part of the model's layers plus storage/attention for old context.
- 21
halogen-flash-server
1Kpeonist-ai/halogen-flash-server · Shellhalogen-flash-server is a purpose-built inference server for running the Qwen3.8-Flash-Next model as fast as possible on AMD's Strix Halo (gfx1151) GPU, exposing an OpenAI-compatible API.
- 22
project-maya
954mw00/project-maya · C++Project Maya lets you run GLM-5.3-Flash, a 321-billion-parameter mixture-of-experts AI model, on your own NVIDIA GPU(s) by streaming the model's experts across VRAM, RAM and NVMe SSD as the conversation needs them.
- 23
gufo
781gufo-org/gufo · C++Gufo is a local inference engine built specifically for AMD Strix Halo hardware (Ryzen AI MAX+ 395 with Radeon 8060S / gfx1151, up to 128 GiB unified memory), serving text, speech, image and video models through an OpenAI-compatible API.
- 24

GLM-5.3-Flash-EXL3-2x-DGX-Sparks
734MiaAI-Lab/GLM-5.3-Flash-EXL3-2x-DGX-Sparks · PythonA deployment recipe and Docker image that serves the GLM-5.3-Flash model as an OpenAI-compatible vLLM endpoint across 2-4 NVIDIA DGX Spark (GB10) kits, using a custom EXL3/TR3 4-bit quantization of the weights.
- 25
ai-system-design
672amitshekhariitbhu/ai-system-design · MarkdownA free, open-source guide that teaches AI System Design step by step: how to combine GPUs, inference servers, caches, vector databases, AI agents, guardrails, and evals into one system that is fast, cheap, reliable, and safe.
- 26

kaggle-tpu-lab
657ARahim3/kaggle-tpu-lab · PythonA recipe that serves frontier-class open LLMs — GLM-5.3-Flash 320B MoE and Qwen3.8-27B bf16 — on Kaggle's free TPU v5e-8, exposing a public OpenAI-compatible (and Anthropic-compatible) endpoint you can plug into coding agents like Claude Code, Codex, opencode, or pi.
- 27
Qwen3.8-Flash-Next-Single-DGX-Spark
609MiaAI-Lab/Qwen3.8-Flash-Next-Single-DGX-Spark · PythonA self-contained recipe for serving the Qwen3.8-Flash-Next-NVFP4 checkpoint from a single NVIDIA DGX Spark machine's unified memory, using vLLM with the PLE table offloaded and memory-mapped.
- 28

pooled
589Nehanth/pooled · JavaScriptSwarmLLM pools the WebGPU power of several devices open in browser tabs to run large open models that no single device could hold on its own, splitting the model into layer slices and passing a small activation vector between devices over WebRTC.
- 29

slotstream
474carloslfu/slotstream · SwiftSlotstream lets you run a 105 GB AI model (Qwen3.8-Flash-Next, a 125B-parameter mixture-of-experts model) on Macs with only 16 to 64 GB of RAM, by streaming most of the model from SSD and caching the busiest experts in memory.
- 30

qwen3.8-Flash-DGX
453blazux/qwen3.8-Flash-DGX · PythonA recipe (scripts plus a patched Docker image) for serving the ~176B-parameter Qwen3.8-Flash-Next model with vLLM on a single NVIDIA DGX Spark (GB10). It solves the problem that the 126 GiB NVFP4 checkpoint doesn't fit next to a usable KV cache in the Spark's 128 GB unified memory, by streaming a 48 GiB lookup table from NVMe via mmap instead of keeping it resident.
- 31
jeeves
425PostHog/jeeves · PythonJeeves is a reasoning-enhanced 'Jev-like' decision model built on Qwen3.5-9B with LoRA. It thinks through a reasoning chain before giving calibrated yes/no, multiple-choice, or rating answers, and ships with a diffusion drafter for faster inference.
- 32
DeepSeek-v4-Flash-One-DGX-Spark
346MiaAI-Lab/DeepSeek-v4-Flash-One-DGX-Spark · PythonA single-node Docker launcher that serves the DeepSeek V4 Flash 0731 model (EXL3 3.0bpw quantization) with DSpark speculative decoding, tuned to run entirely on one NVIDIA DGX Spark machine.
- 33
llm-inference-engineering
344amitshekhariitbhu/llm-inference-engineering · MarkdownA free, continuously growing blog series that teaches LLM inference engineering step by step, covering KV cache, PagedAttention, continuous batching, speculative decoding, and serving engines like vLLM, SGLang, TensorRT-LLM, and GGUF.
- 34

GLM-5.3-Flash-NVFP4-DFlash2-2x-DGX-Spark
236tonyd2wild/GLM-5.3-Flash-NVFP4-DFlash2-2x-DGX-Spark · PythonA deployment recipe and set of patched Docker images for serving GLM-5.3-Flash (320B total / 18B active MoE) as an OpenAI-compatible API across two NVIDIA DGX Spark nodes, using vLLM tensor-parallel 2, NVFP4 quantization, and DFlash2 speculative decoding.
- 35
Qwen3.8-27B-DFlash2-EXL3-5.0bpw
232MiaAI-Lab/Qwen3.8-27B-DFlash2-EXL3-5.0bpw · PythonA deployment kit for serving Qwen3.8-27B (quantized to EXL3 3.5bpw) through an OpenAI-compatible server, using speculative decoding to speed up generation. It bundles the launcher, server, and config; the model weights live on Hugging Face and inference runs on the team's exllamav3 fork.
- 36

dgx-spark-qwen38
227hasso5703/dgx-spark-qwen38 · PythonA one-command installer that sets up a hardened, boot-persistent SGLang serving stack for the Qwen3.8 model family on a single NVIDIA DGX Spark (GB10), reaching 50 tok/s greedy median and up to 1M context on the 27B NVFP4 config, with a 176B Flash-Next MoE model also fitting on one box.
- 37

twinspark
176raullenchai/twinspark · ShellThis is a production-grade deployment recipe for running DeepSeek-V4-Flash-0731 (a 284B-parameter MoE model) across two networked NVIDIA DGX Spark machines, using a self-healing 2-node vLLM cluster tuned for speculative decoding.
- 38

v100-skinny
172dnv2003/v100-skinny · Pythonv100-skinny provides hand-written NVFP4 (W4A16) and FP8 (W8A16) CUDA kernels that let four Tesla V100-SXM2-16GB GPUs run Qwen3.8-27B's published mixed NVFP4/FP8 weights directly, serving the model through an OpenAI-compatible API.
- 39
tpu-megakernels
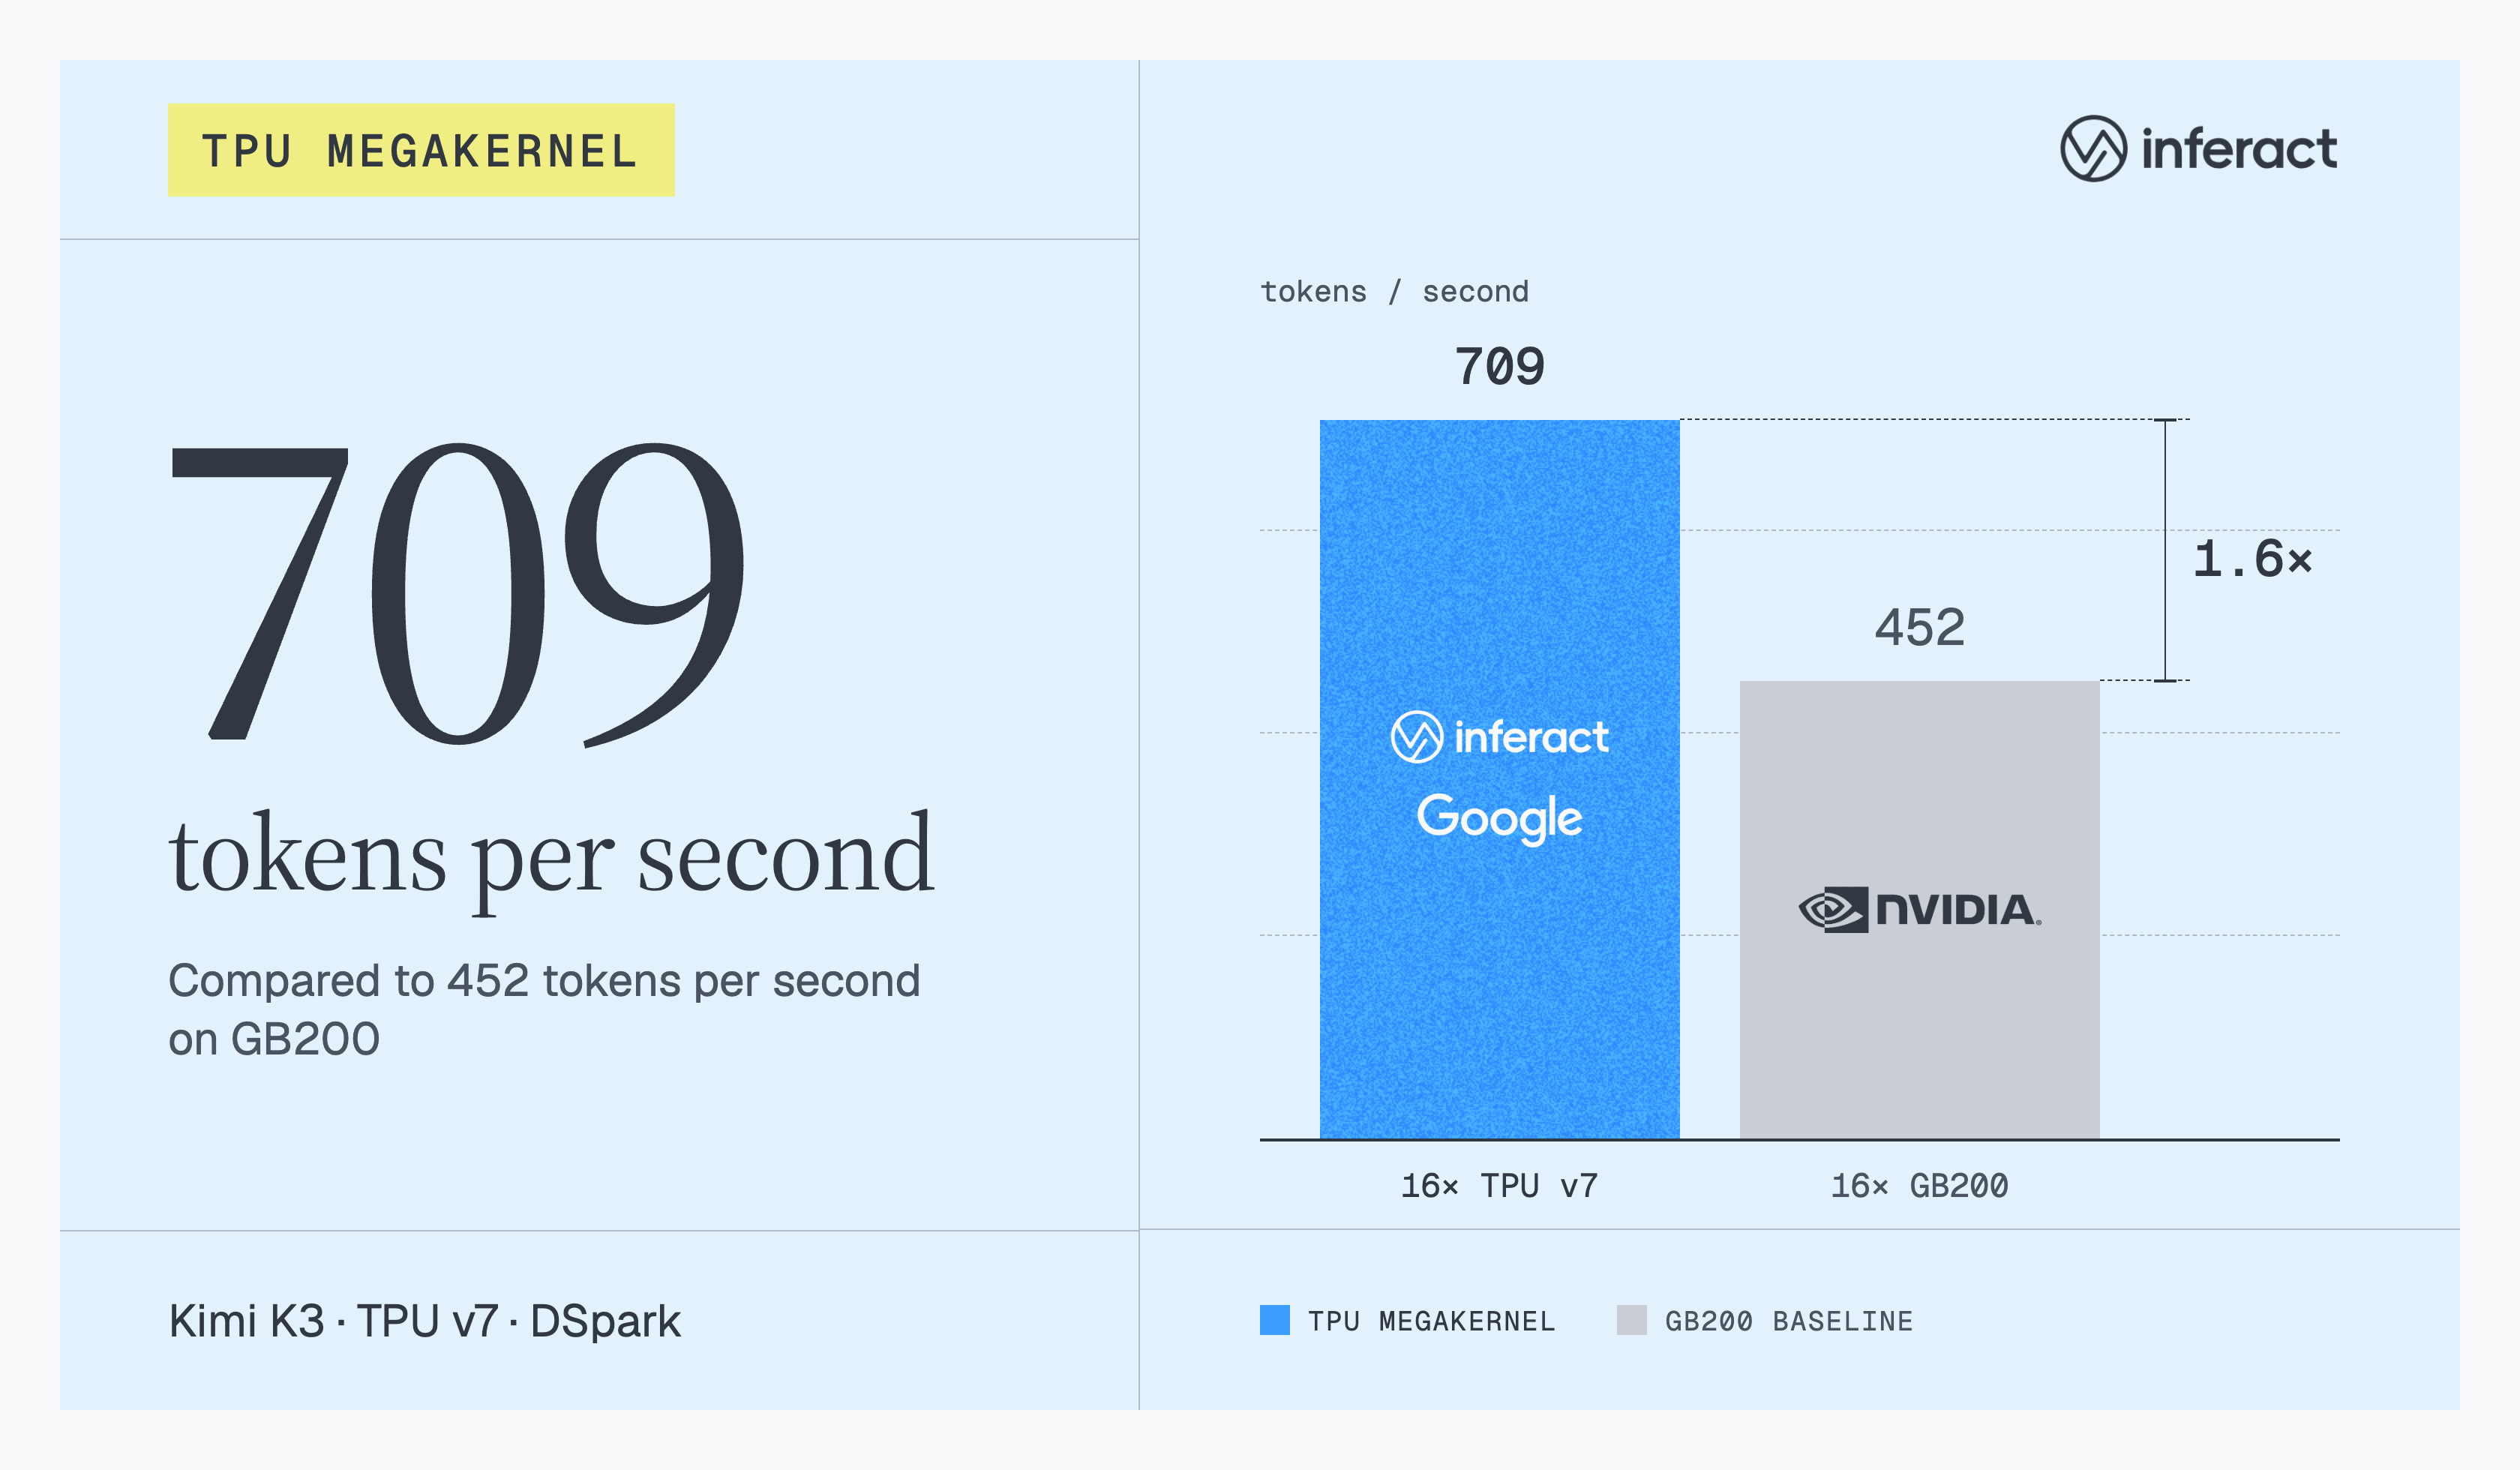
162Inferact/tpu-megakernels · PythonA companion research repo with fused 'megakernel' decode implementations for two models on Google TPUs: Kimi K3 with DSpark speculative decoding, and Qwen3.8-27B with DFlash2 speculative decoding, written to accompany the blog post '700 TPS on Kimi K3: A Case for TPU Megakernels'.
- 40
DMI
65ProjectDMX/DMI · PythonDMI is a decoupled, asynchronous observability stack that gives real-time access to a running LLM's internal state — residual streams, attention patterns, MLP outputs, KV-cache slices, logits — during inference or training, with minimal overhead.
Related topics
Often tagged together
- llm1,483
- gpu789
- llm-inference119
- quantization183
- inference327
- python2,383
- cuda396
- linux4,184
- benchmark431
- nvidia328
- self-hosted1,929
- local-llm218
- large-language-models213
- openai-compatible211
- server1,459
- open-source5,666
- vllm124
- huggingface362
- llm-serving29
- model-serving46
- qwen154
- ai1,955
- deep-learning737
- inference-engine45