Topics / #edge-ai
Edge AI projects on GitHub
Running machine learning inference on edge and embedded hardware.
As of , the most-starred Edge AI projects on GitHub are BitNet (41.2K stars), mediapipe (37.3K stars) and qdrant (35.1K stars). GitHub.Locker tracks 50 Edge AI repositories with 452.7K stars combined. The fastest-growing on October 18 was FractalWorkspace, with +983 stars in a day.
Hot right now
Most stars gained in a day · Oct 18
 +983
FractalWorkspace
AhmadHassan-BTed/FractalWorkspace · ★ 1.2KFractal is a distributed computing ecosystem for federated learning that harvests spare compute from mobile edge devices while keeping raw user data on-device. It pairs a Python-based central orchestrator with a native Android client that trains models locally and only sends back weight checkpoints.
 +966
FractalWorkspace
Fractal-Compute-Orchestrations/FractalWorkspace · ★ 1.2KFractal is a distributed computing ecosystem that harvests compute from edge devices (like Android phones) to run federated learning and large foundation model inference, while keeping raw user data on-device.
 +946
FractalCore
Fractal-Compute-Orchestrations/FractalCore · ★ 1.1KFractalCore is the central backend orchestrator for the Fractal decentralized compute ecosystem. It coordinates federated learning tasks across Android edge nodes, manages multi-tenant TFLOPs budgets, and runs FedAvg weight aggregation to build a global model.
 +944
FractalAndroid
Fractal-Compute-Orchestrations/FractalAndroid · ★ 1.1KFractalAndroid is an Android client that turns a phone into a privacy-preserving edge compute node for the Fractal distributed intelligence network, running on-device federated learning (TFLite) training in coordination with a central server called FractalCore.
The all-time top
50 projects · by stars
- 41.2K
 #1 · microsoft/BitNet
BitNet
bitnet.cpp is Microsoft's official inference framework for 1-bit (ternary, 1.58-bit) large language models like BitNet b1.58, letting them run fast on CPUs and GPUs.
- 37.3K
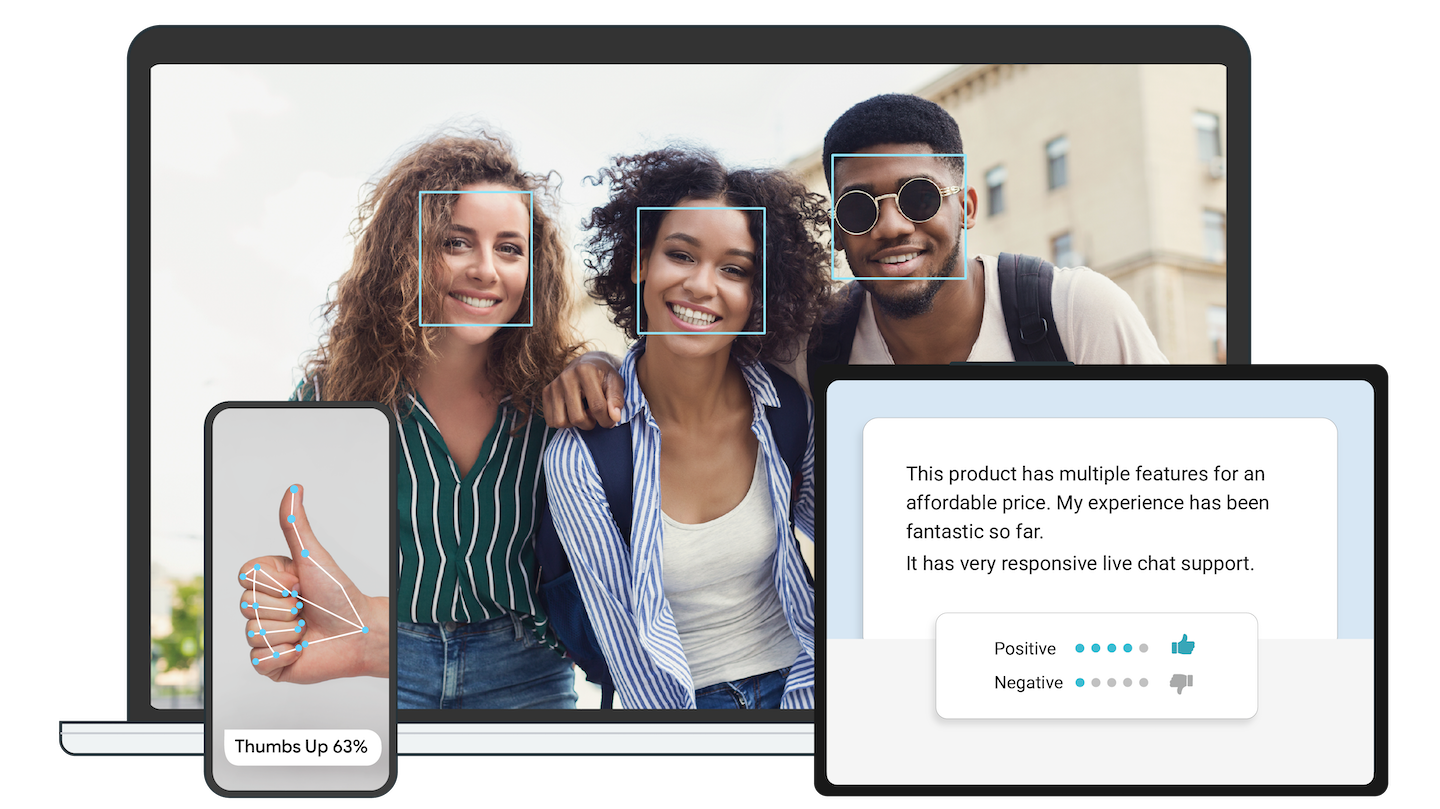 #2 · google-ai-edge/mediapipe
mediapipe
Google's open-source, cross-platform toolkit for on-device machine learning in live and streaming media: ready-made libraries and pre-trained models you plug straight into your own app.
- 35.1K
 #3 · qdrant/qdrant
qdrant
Qdrant is a high-performance vector similarity search engine and vector database written in Rust, built to store, search, and manage 'points' (vectors plus a JSON payload) for AI applications like semantic search, recommendations, and RAG.
- 4

cs249r_book
29.1Kharvard-edge/cs249r_book · PythonAn open textbook and full curriculum on Machine Learning Systems — AI engineering — from Harvard's CS249r course: four volumes covering foundations, scaling, agentic AI, and physical AI, plus labs, projects, and instructor materials.
- 5

MiniCPM-V
26.9KOpenBMB/MiniCPM-V · PythonA family of pocket-sized multimodal AI models from OpenBMB (MiniCPM-V and MiniCPM-o) built to run on local devices, even phones — understanding images, video and text, and in the o-series also speech.
- 6

ncnn
24KTencent/ncnn · C++ncnn is a high-performance neural network inference framework built by Tencent and optimized for mobile, embedded, and desktop deployment. It is used in Tencent apps like QQ, Qzone, and WeChat to run deep learning models on-device.
- 7
nats-server
20.9Knats-io/nats-server · GoThis is the NATS server — the high-performance core of NATS.io, a messaging system for connecting digital systems, services and devices. It's a CNCF project.
- 8
Qwen3-VL
20.1KQwenLM/Qwen3-VL · Jupyter NotebookQwen3-VL is a family of multimodal vision-language models built by the Qwen team at Alibaba Cloud, combining strong text understanding with deep visual perception, reasoning, and agent capabilities.
- 9
MNN
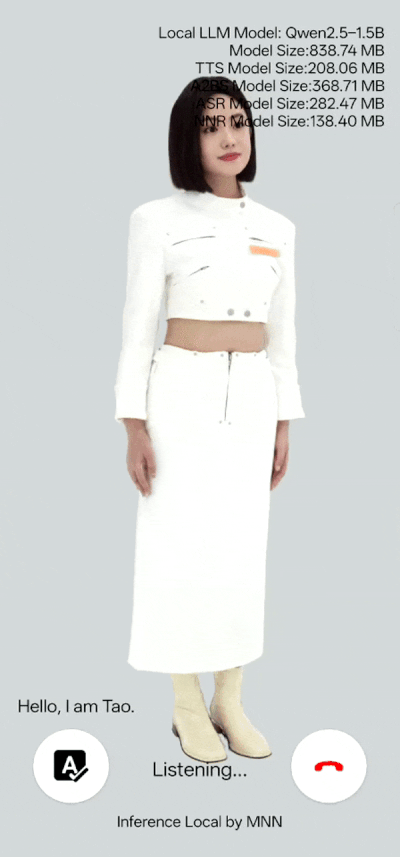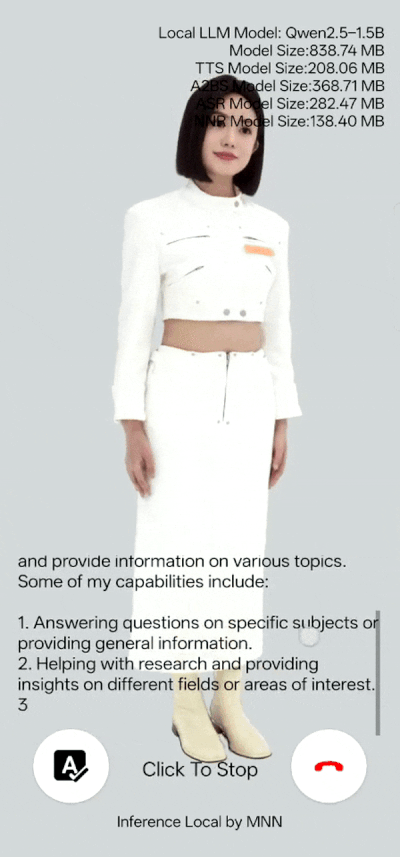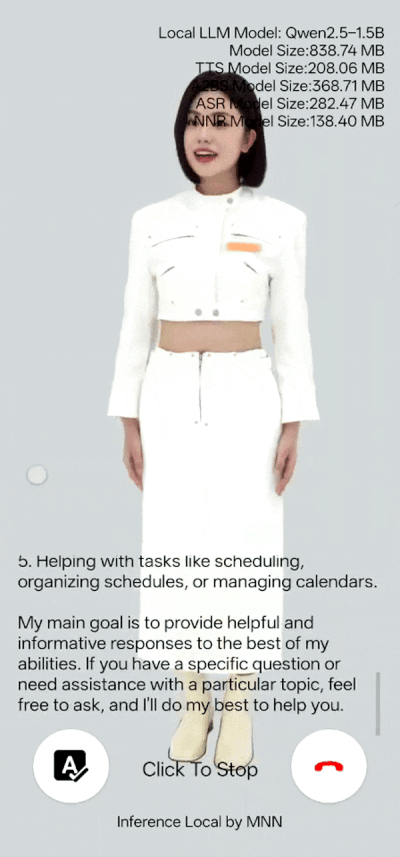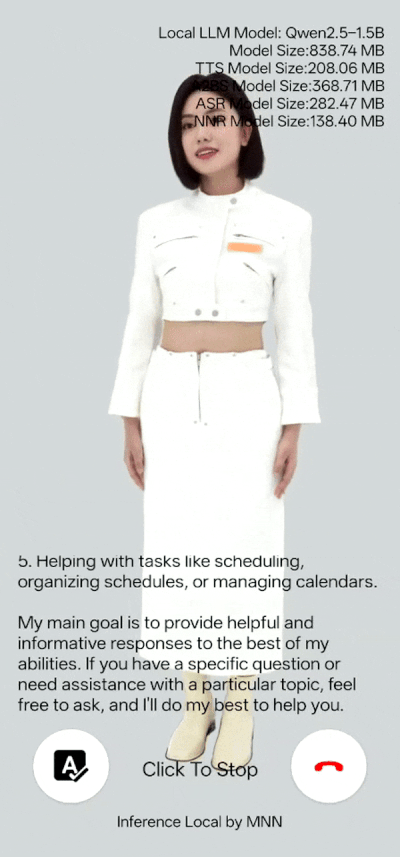
16.2Kalibaba/MNN · C++MNN is a lightweight, high-performance deep learning inference (and training) engine built by Alibaba, used to run models like LLMs, diffusion models, and CNNs efficiently on mobile, embedded, and edge devices.
- 10
KittenTTS
16.2KKittenML/KittenTTS · PythonKitten TTS is an open-source, lightweight text-to-speech library built on ONNX that converts text into natural-sounding speech using tiny 15M-80M parameter models, running entirely on CPU.
- 11

sherpa-onnx
15.4Kk2-fsa/sherpa-onnx · C++sherpa-onnx is an offline toolkit for speech-to-text, text-to-speech, speaker diarization, speaker identification/verification, spoken language identification, audio tagging, VAD, speech enhancement, keyword spotting and source separation, built on next-gen Kaldi and ONNX Runtime, with no internet connection required.
- 12
FreeToken
14.6KFlashML-org/FreeToken · PythonFreeToken is an edge-native Mixture-of-Experts (MoE) serving engine built to run frontier-scale open-weight models, including 290B+ parameter models, on consumer hardware like gaming PCs.
- 13
needle
14.1Kcactus-compute/needle · PythonNeedle 2 is an open 45M-parameter model for tool calling, device use and structured extraction that ships as a single 14MB binary and runs a full session in about 28MB of RAM. This repo is its Python package for inference, LoRA fine-tuning and export.
- 14
MiniCPM
11.6KOpenBMB/MiniCPM · Jupyter NotebookMiniCPM is OpenBMB's family of small, open-source LLMs built for on-device and resource-constrained use. The newest release, MiniCPM5-2B, is a dense 2B-parameter model that reaches open-source state-of-the-art for its size class while staying competitive with much larger 4B-class models.
- 15
moonshine
11.3Kmoonshine-ai/moonshine · C++Moonshine Voice is an open source AI toolkit for building real-time voice agents and interfaces, covering speech-to-text, intent recognition, and text-to-speech.
- 16

WasmEdge
10.8KWasmEdge/WasmEdge · C++WasmEdge is a lightweight, high-performance, extensible WebAssembly runtime built for cloud-native, edge, and decentralized applications, powering serverless apps, microservices, smart contracts, and IoT devices.
- 17

yolov3
10.6Kultralytics/yolov3 · PythonUltralytics' PyTorch implementation of the YOLOv3 real-time object detector, packaging three model variants - YOLOv3, YOLOv3-SPP and YOLOv3-tiny - with training, validation, inference and multi-format export tooling.
- 18
silero-vad
10.5Ksnakers4/silero-vad · PythonSilero VAD is a pre-trained, enterprise-grade Voice Activity Detector: a compact model that tells you which parts of an audio stream contain speech.
- 19
runanywhere-sdks
10.3KRunanywhereAI/runanywhere-sdks · C++A toolkit of eight SDKs over one C++ core that runs AI fully on-device — LLM chat, vision, speech, voice agents, RAG, and image generation — on phones, browsers, and desktops. Everything is private by default and works offline.
- 20
moondream
10.1Km87-labs/moondream · PythonMoondream is a tiny, open-source vision language model that understands images — captioning, visual question answering, and object detection — while being small enough to run almost anywhere.
- 21

ANE
7.3Kmaderix/ANE · Objective-CANE is a research project that trains neural networks directly on Apple's Neural Engine using reverse-engineered private APIs, instead of CoreML's inference-only path.
- 22
laya-mlx
7Kmizorewww/laya-mlx · PythonLaya-MLX is a native MLX runtime that runs the open-weight Laya typed decision models locally on Apple Silicon, returning structured answers like a choice, a rubric score, or a probability in milliseconds instead of generating text.
- 23
turbo-fieldfare
6.9Kdrumih/turbo-fieldfare · SwiftTurboFieldfare is a custom Swift and Metal runtime that runs the instruction-tuned Gemma 4 26B-A4B model on Apple Silicon Macs using only about 2 GB of RAM, even on 8 GB machines, by streaming only the experts needed for each token from SSD instead of loading the full 14.3 GB model.
- 24
mimiclaw
5.8Kmemovai/mimiclaw · CMimiClaw turns a $5 ESP32-S3 microcontroller into a personal AI assistant you talk to through Telegram, complete with local memory and tool-calling, running entirely on a tiny chip with no Linux, no Node.js, and no server involved.
- 25

Edge0
5.7KEdge0-AI/Edge0 · PythonEdge0 is an open-source streaming MoE (Mixture-of-Experts) inference framework that lets you run large MoE models, like a 35B-parameter model, using only about 2.5-2.9 GB of active RAM by streaming expert weights from SSD and predicting routing one step ahead.
- 26
Model-Optimizer
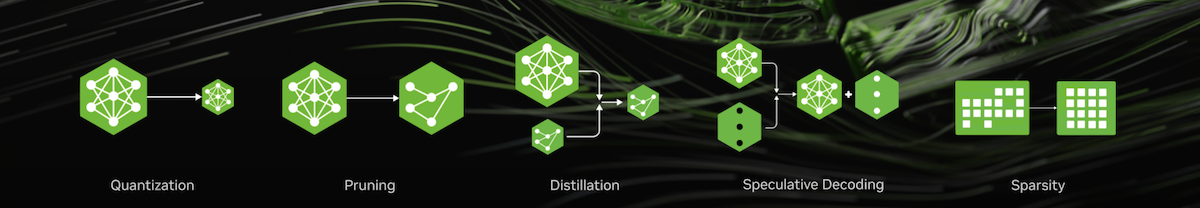
5.4KNVIDIA/Model-Optimizer · PythonNVIDIA Model Optimizer (ModelOpt) is a Python library that bundles state-of-the-art model-compression techniques - quantization, pruning, neural architecture search, distillation, speculative decoding and sparsity - to shrink and speed up deep learning models before deployment.
- 27
esp32-ai
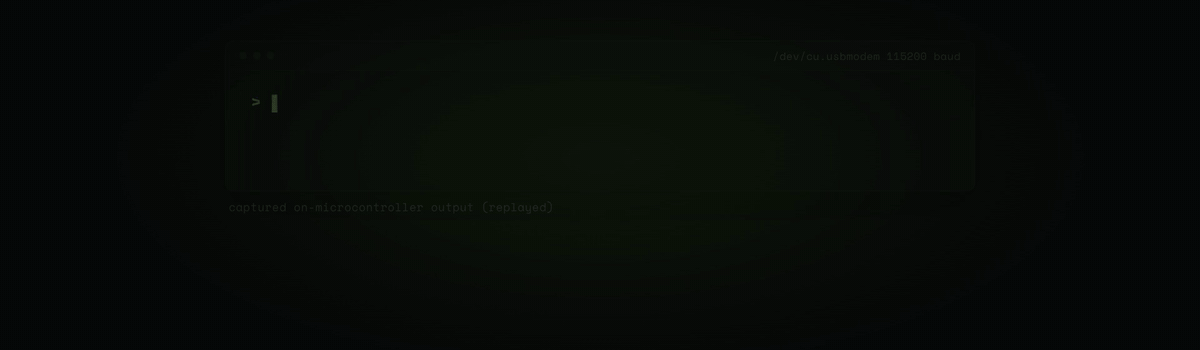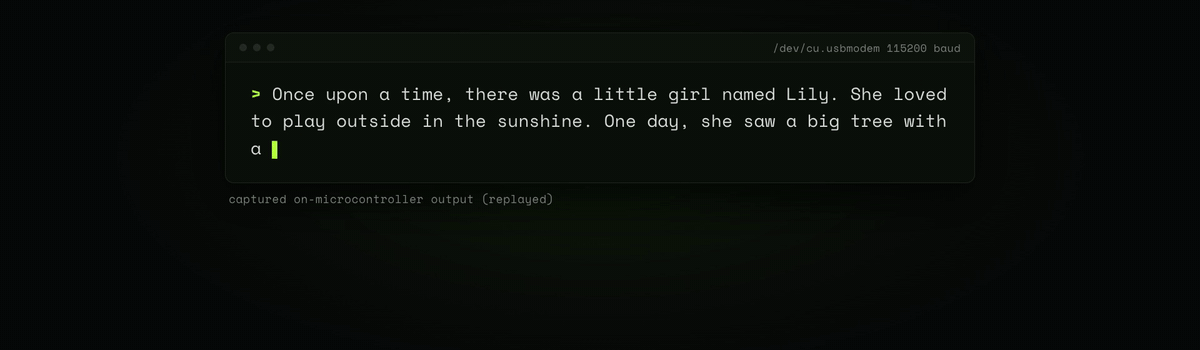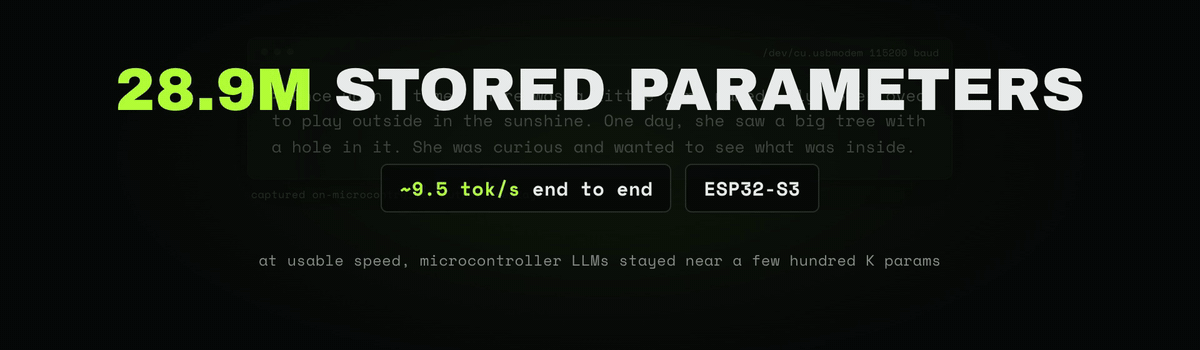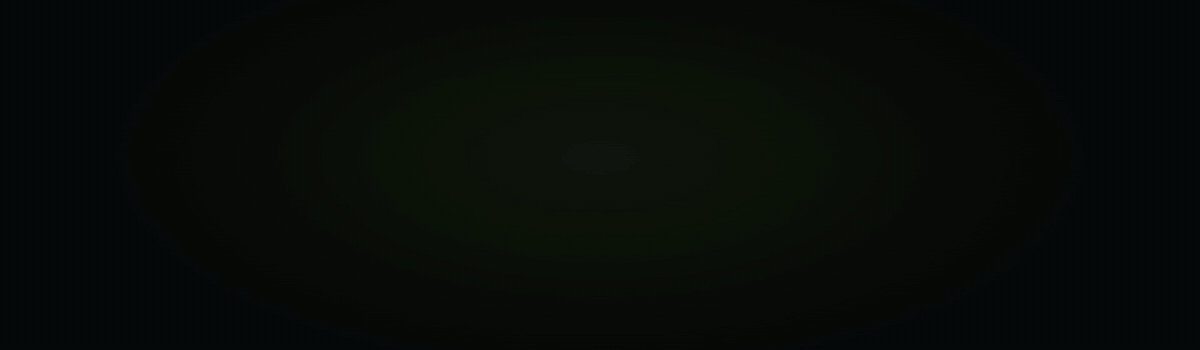
4.6KslvDev/esp32-ai · PythonA 28.9 million parameter language model that runs text generation entirely on an ESP32-S3 microcontroller, with the generated text shown on a small screen wired to the chip.
- 28
MOSS-TTS-Nano
4.5KOpenMOSS/MOSS-TTS-Nano · PythonMOSS-TTS-Nano is an open-source, 100M-parameter multilingual text-to-speech model from MOSI.AI and OpenMOSS that supports voice cloning, 48kHz stereo output, and real-time generation directly on CPU.
- 29
uzu
2.4Ktrymirai/uzu · Rustuzu is a high-performance inference engine for AI models that lets you run LLMs directly inside your app with zero latency, full data privacy, and no per-request inference costs.
- 30
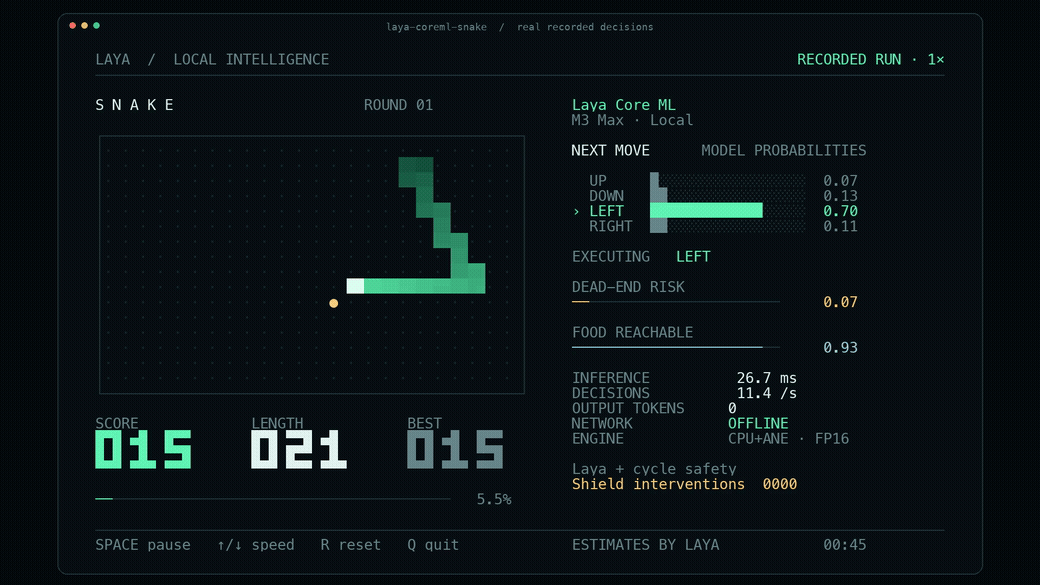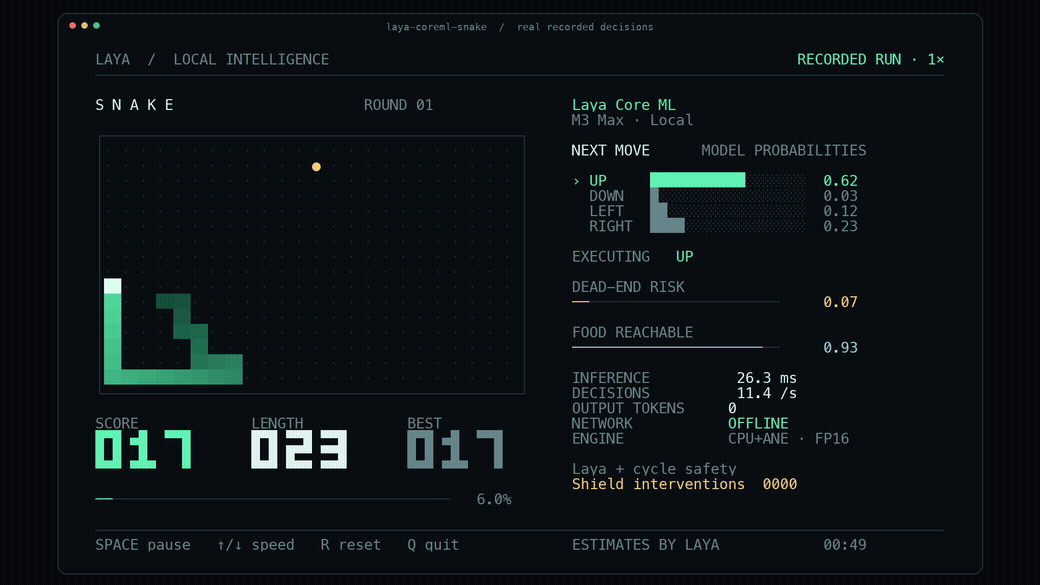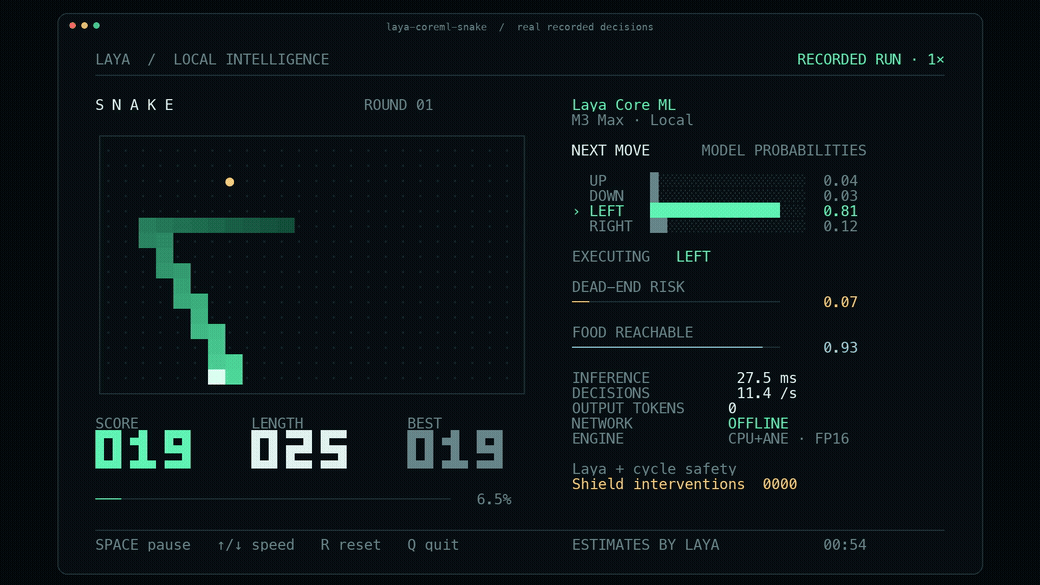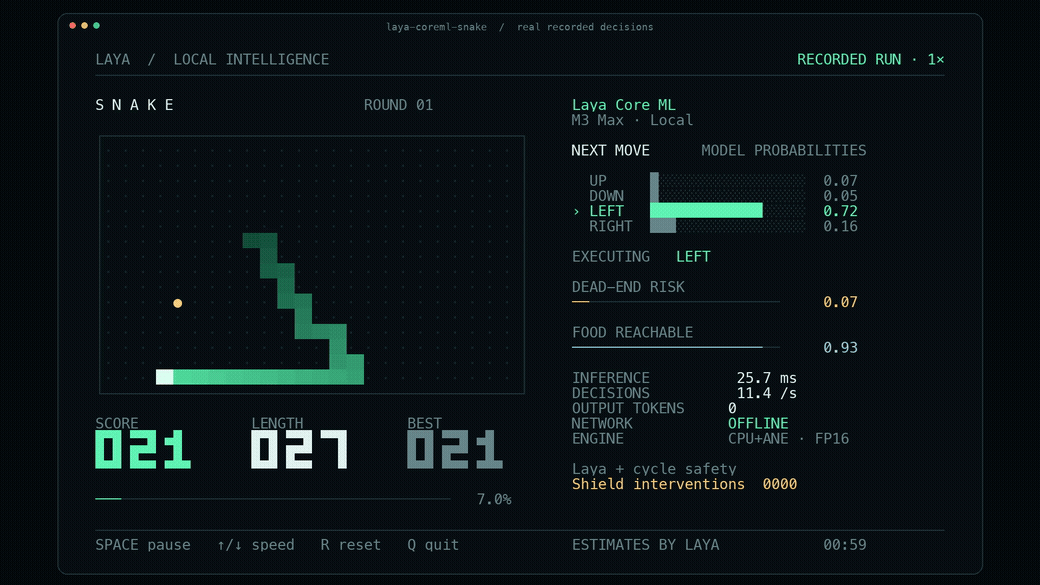
laya-coreml
1.6Kmizorewww/laya-coreml · PythonIt's an open-weight Python port of Laya that answers typed questions — pick an option, an ordinal score, or yes/no — locally on Apple Silicon through Core ML and the Neural Engine, generating zero text tokens.
- 31
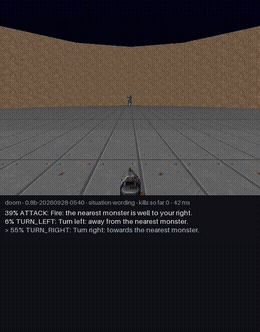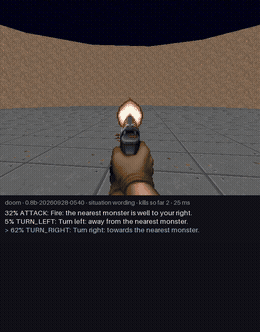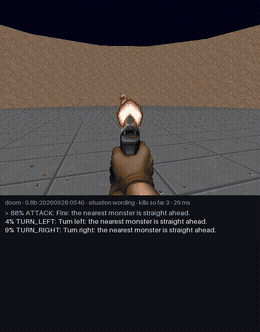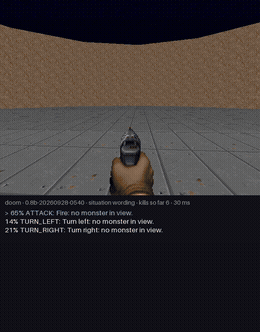
jeff
1.5Kfirelex/jeff · PythonJeff is a family of small (0.8B-2B parameter) open-weight models fine-tuned from Qwen3.5 and Gemma 4 that act as fast 'System 1' decision-makers: you describe a situation and a list of options in plain text, and Jeff returns a calibrated probability for each option from a single forward pass, with no generated text to parse.
- 32
jev
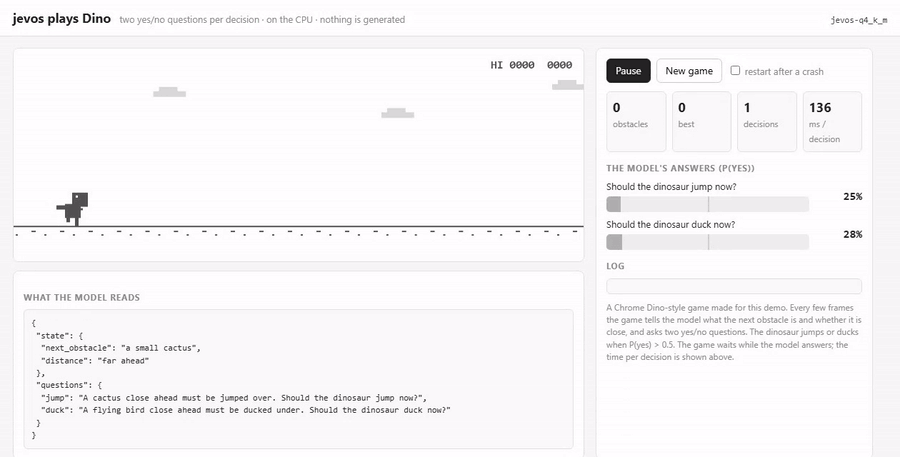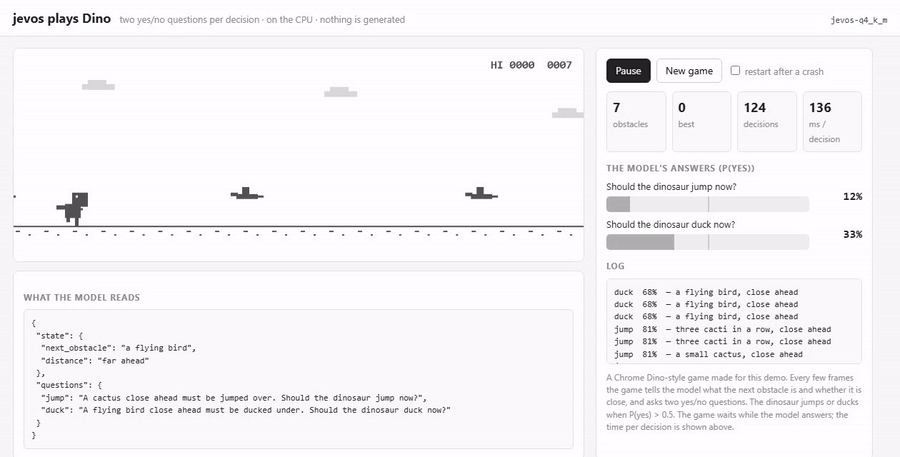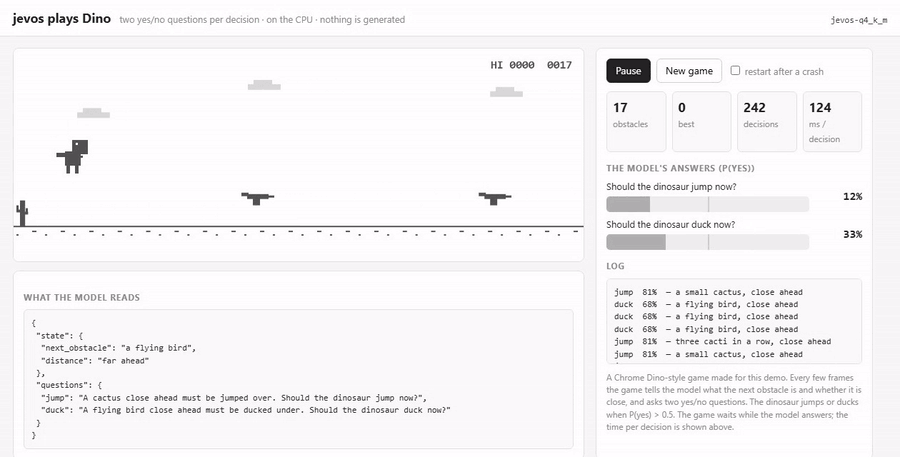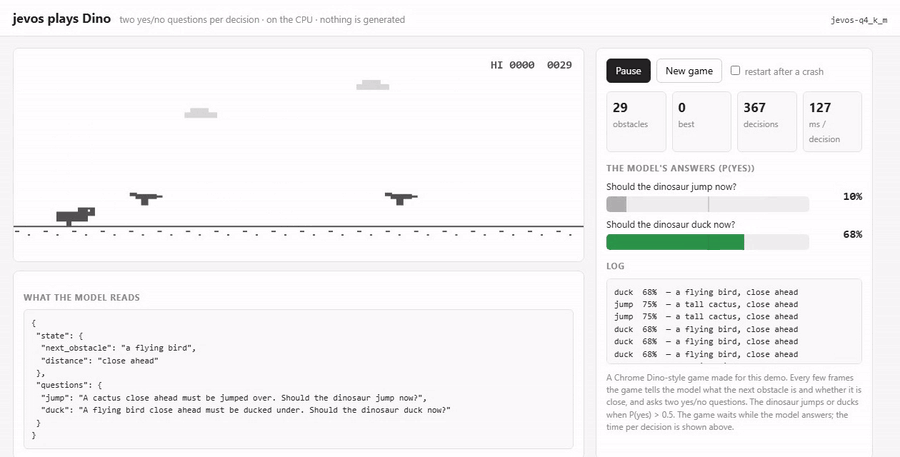
1.4Kfeder-cr/jev · C++jevos-1b is a free, open-source yes/no decision engine that runs locally on your laptop's CPU, returning the probability that the answer is 'yes' for a given text plus question in about 50-220 ms, as a self-hosted alternative to the cloud-based Jev service.
- 33
speech-swift
1.2Ksoniqo/speech-swift · SwiftSpeech Swift is a collection of on-device AI speech models for Apple Silicon — speech recognition (ASR), text-to-speech, speech-to-speech, voice activity detection, and speaker diarization — built as Swift packages powered by MLX and CoreML.
- 34
FractalWorkspace
1.2KFractal-Compute-Orchestrations/FractalWorkspace · PythonFractal is a distributed computing ecosystem that harvests compute from edge devices (like Android phones) to run federated learning and large foundation model inference, while keeping raw user data on-device.
- 35
cpu-performance-engineering
1.2Kusamahz/cpu-performance-engineering · PythonA curated reading path for CPU performance engineering: it walks you from what one instruction does on a modern core to serving ML inference on CPUs, ordered so each piece makes the next one legible.
- 36
FractalWorkspace
1.2KAhmadHassan-BTed/FractalWorkspace · PythonFractal is a distributed computing ecosystem for federated learning that harvests spare compute from mobile edge devices while keeping raw user data on-device. It pairs a Python-based central orchestrator with a native Android client that trains models locally and only sends back weight checkpoints.
- 37
FractalCore
1.1KFractal-Compute-Orchestrations/FractalCore · PythonFractalCore is the central backend orchestrator for the Fractal decentralized compute ecosystem. It coordinates federated learning tasks across Android edge nodes, manages multi-tenant TFLOPs budgets, and runs FedAvg weight aggregation to build a global model.
- 38
FractalAndroid
1.1KFractal-Compute-Orchestrations/FractalAndroid · KotlinFractalAndroid is an Android client that turns a phone into a privacy-preserving edge compute node for the Fractal distributed intelligence network, running on-device federated learning (TFLite) training in coordination with a central server called FractalCore.
- 39

MasterAgent
1.1KOpenSparX/MasterAgent · C++MasterAgent (OAK) is an embeddable, local-first C++17 agent runtime: it turns input into validated tool execution, running deterministic skills before falling back to model inference. It targets on-device AI agents for use cases like automotive and embedded/Qualcomm NPU hardware, with zero cloud dependency by default.
- 40
backburner
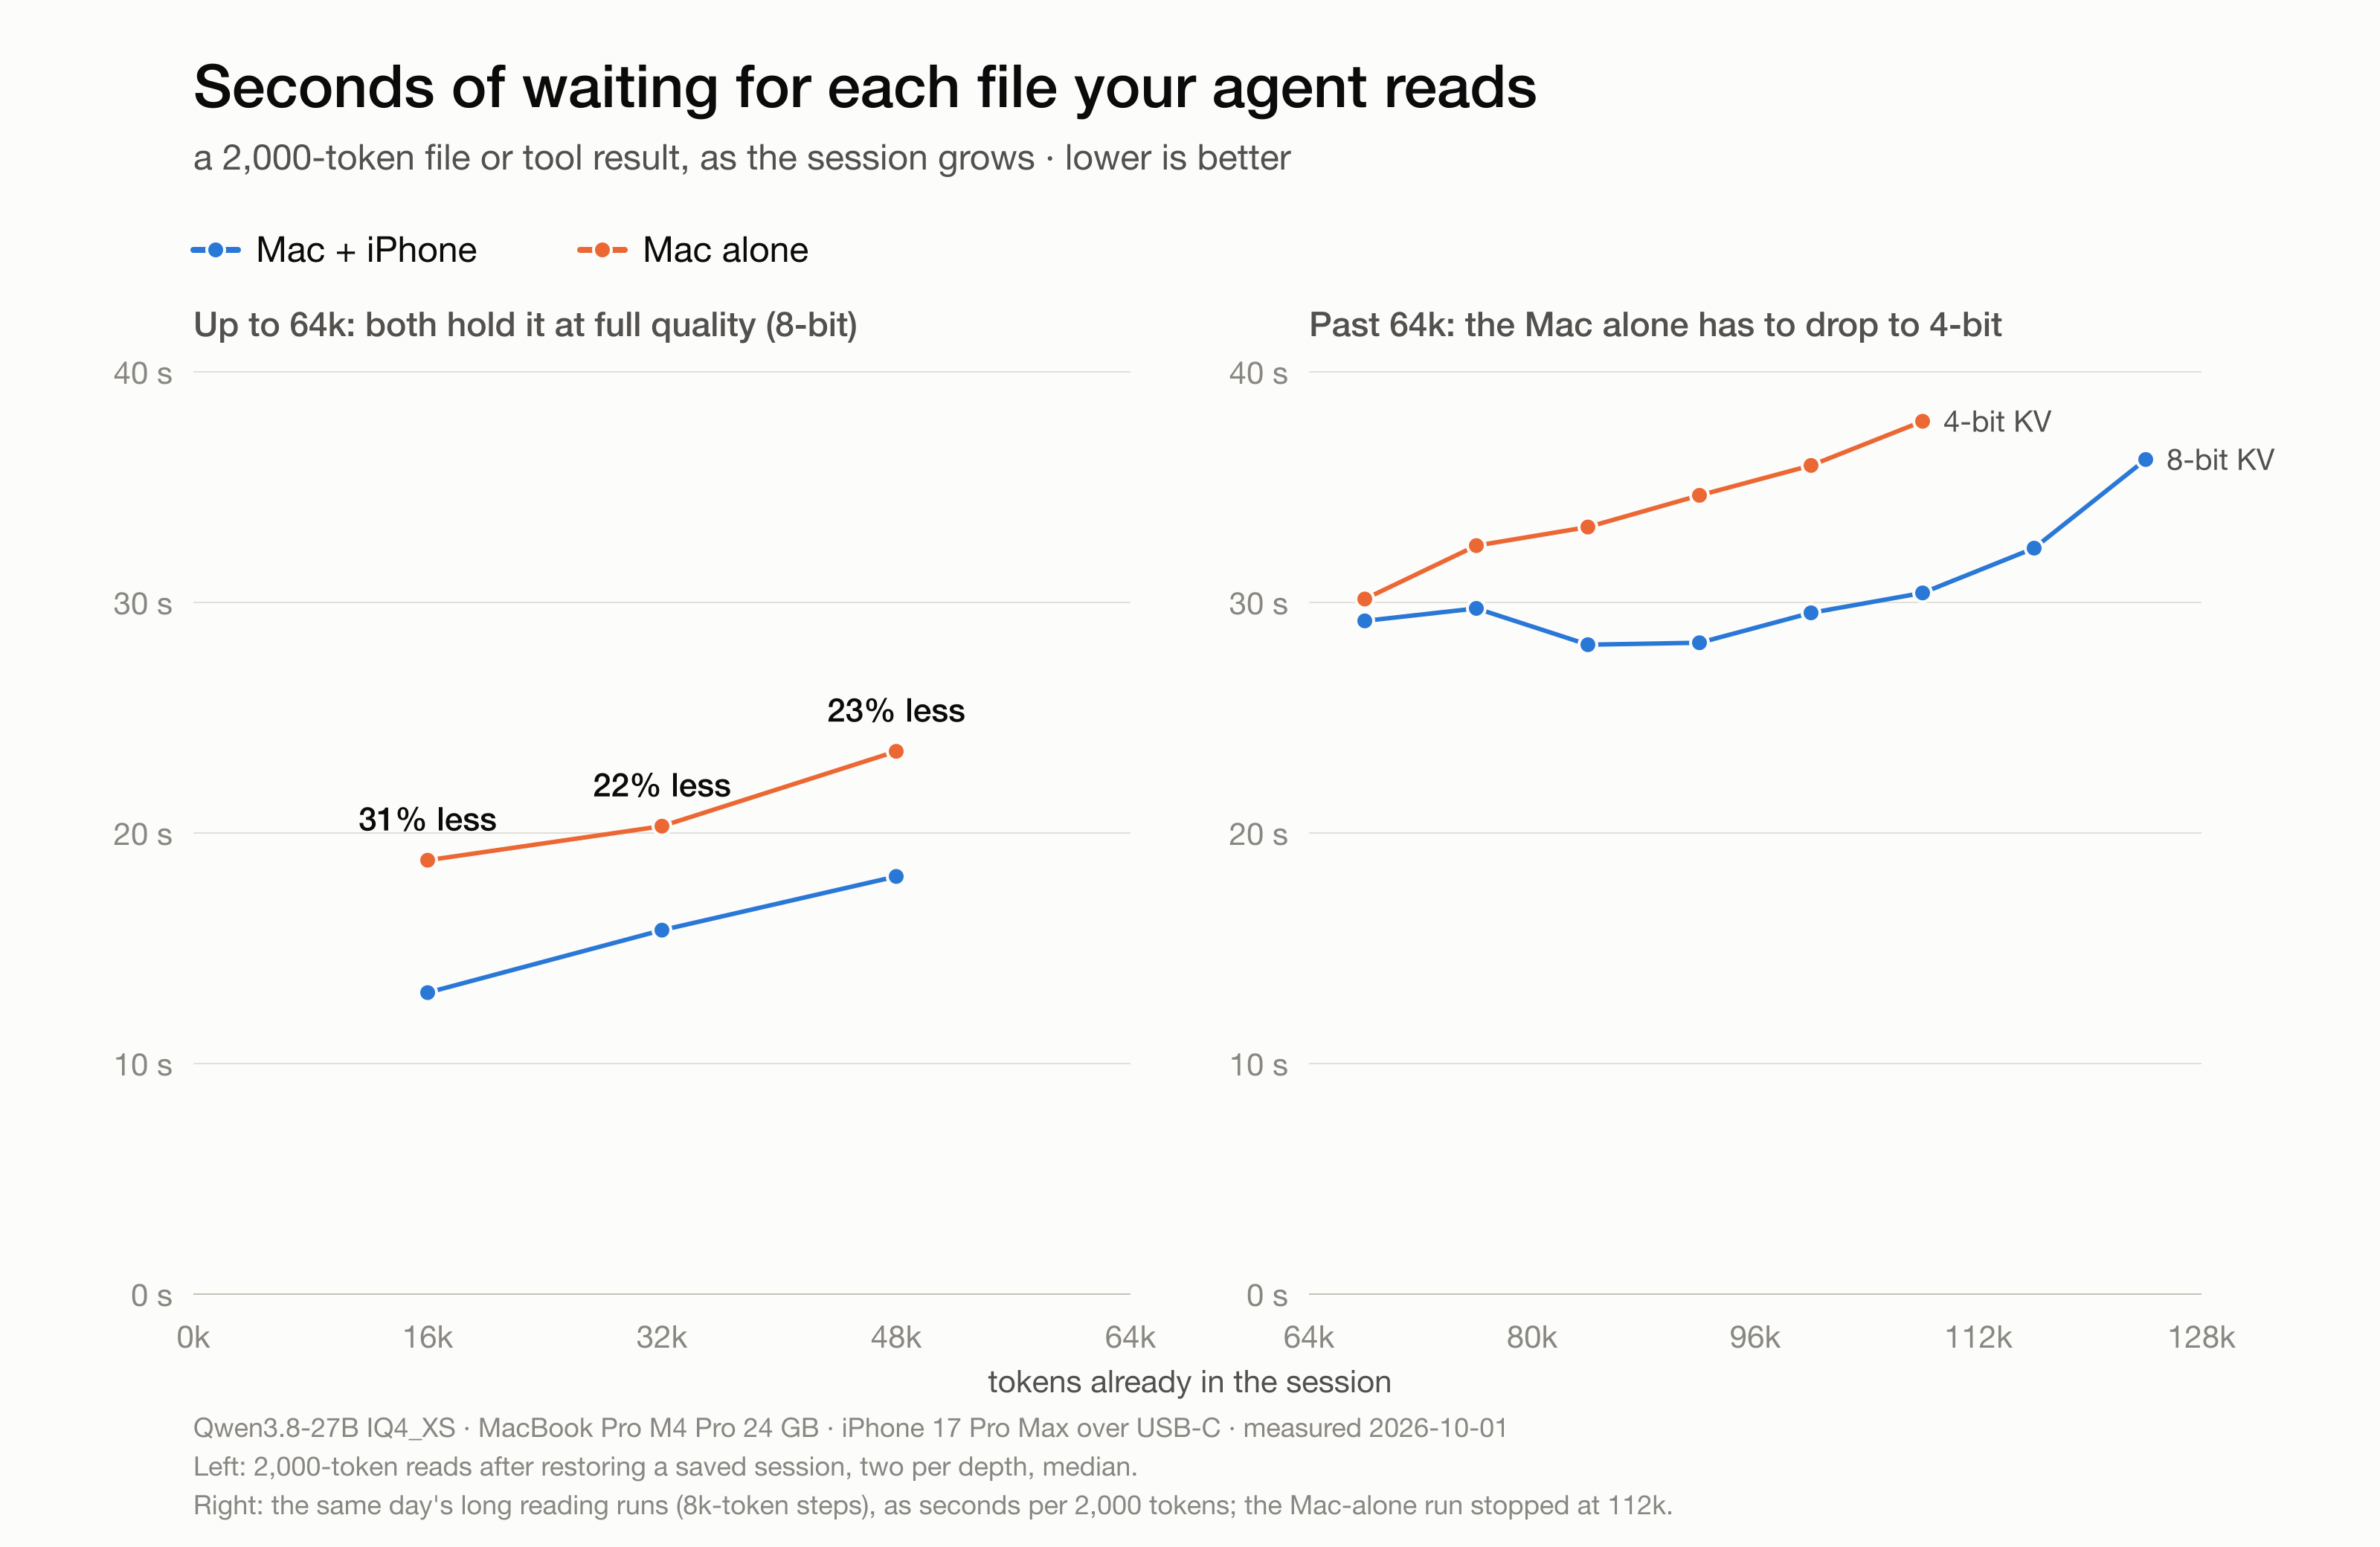
1KStayLameBro/backburner · PythonBackburner lets a nearby iPhone act as a coprocessor for your Mac so a locally-run 27B LLM (Qwen3.8-27B) reads prompts faster and holds far more context. The phone connects over a 10 Gb/s USB-C cable and offloads part of the model's layers plus storage/attention for old context.
- 41
openTPU
773FeSens/openTPU · VerilogopenTPU is an open-source AI accelerator whose hardware design, instruction set, simulator, compiler and profiler were all built by AI agents, and it runs real LLMs like Qwen3 and LFM2.5 on an FPGA PCIe card.
- 42

intrinsic-core
584intrinsic-ai/intrinsic-core · C++Intrinsic Core is an open, local runtime, SDK and hardware-agnostic real-time control framework for industrial robotics. It provides foundational building blocks for AI-enabled robot applications, from simulation and 6-DoF perception down to hardware execution.
- 43
apex-inference-chip
581SigmanticAI/apex-inference-chip · PythonAPEX is an open, verification-first hardware design for LLM inference: one transformer decoder layer written in real RTL that runs Qwen2.5-0.5B on an FPGA, with every circuit block checked bit-exact against a software golden model.
- 44

Real-Time-Person-Elderly-Fall-Detection-System
276AwaisShah75/Real-Time-Person-Elderly-Fall-Detection-System · PythonIt's an edge AI computer vision system that detects falls in real time, especially for elderly people, even when partially hidden behind furniture, while avoiding false alarms from normal activities like sitting or sleeping.
- 45
coyopedal
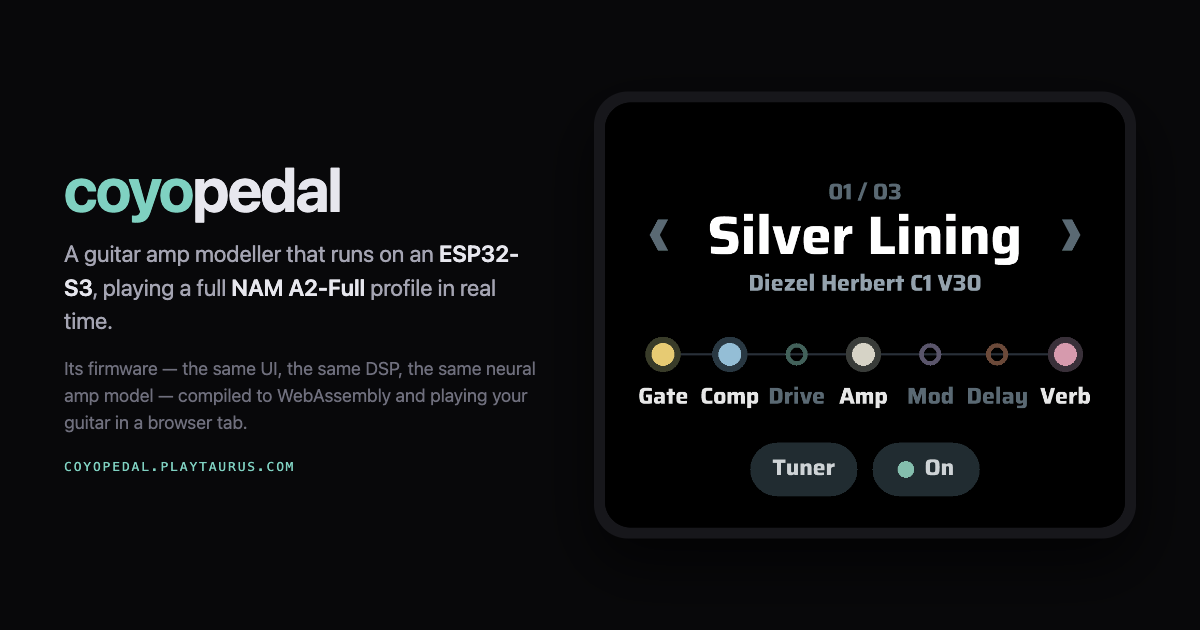
261dashersw/coyopedal · C++CoyoPedal is a standalone guitar amp and effects pedal built on the ESP32-S3 that runs full-size Neural Amp Modeler (NAM) A2 captures in real time, with a touchscreen UI and a browser build compiled to WebAssembly.
- 46
ESP32s3-LLM-Cluster
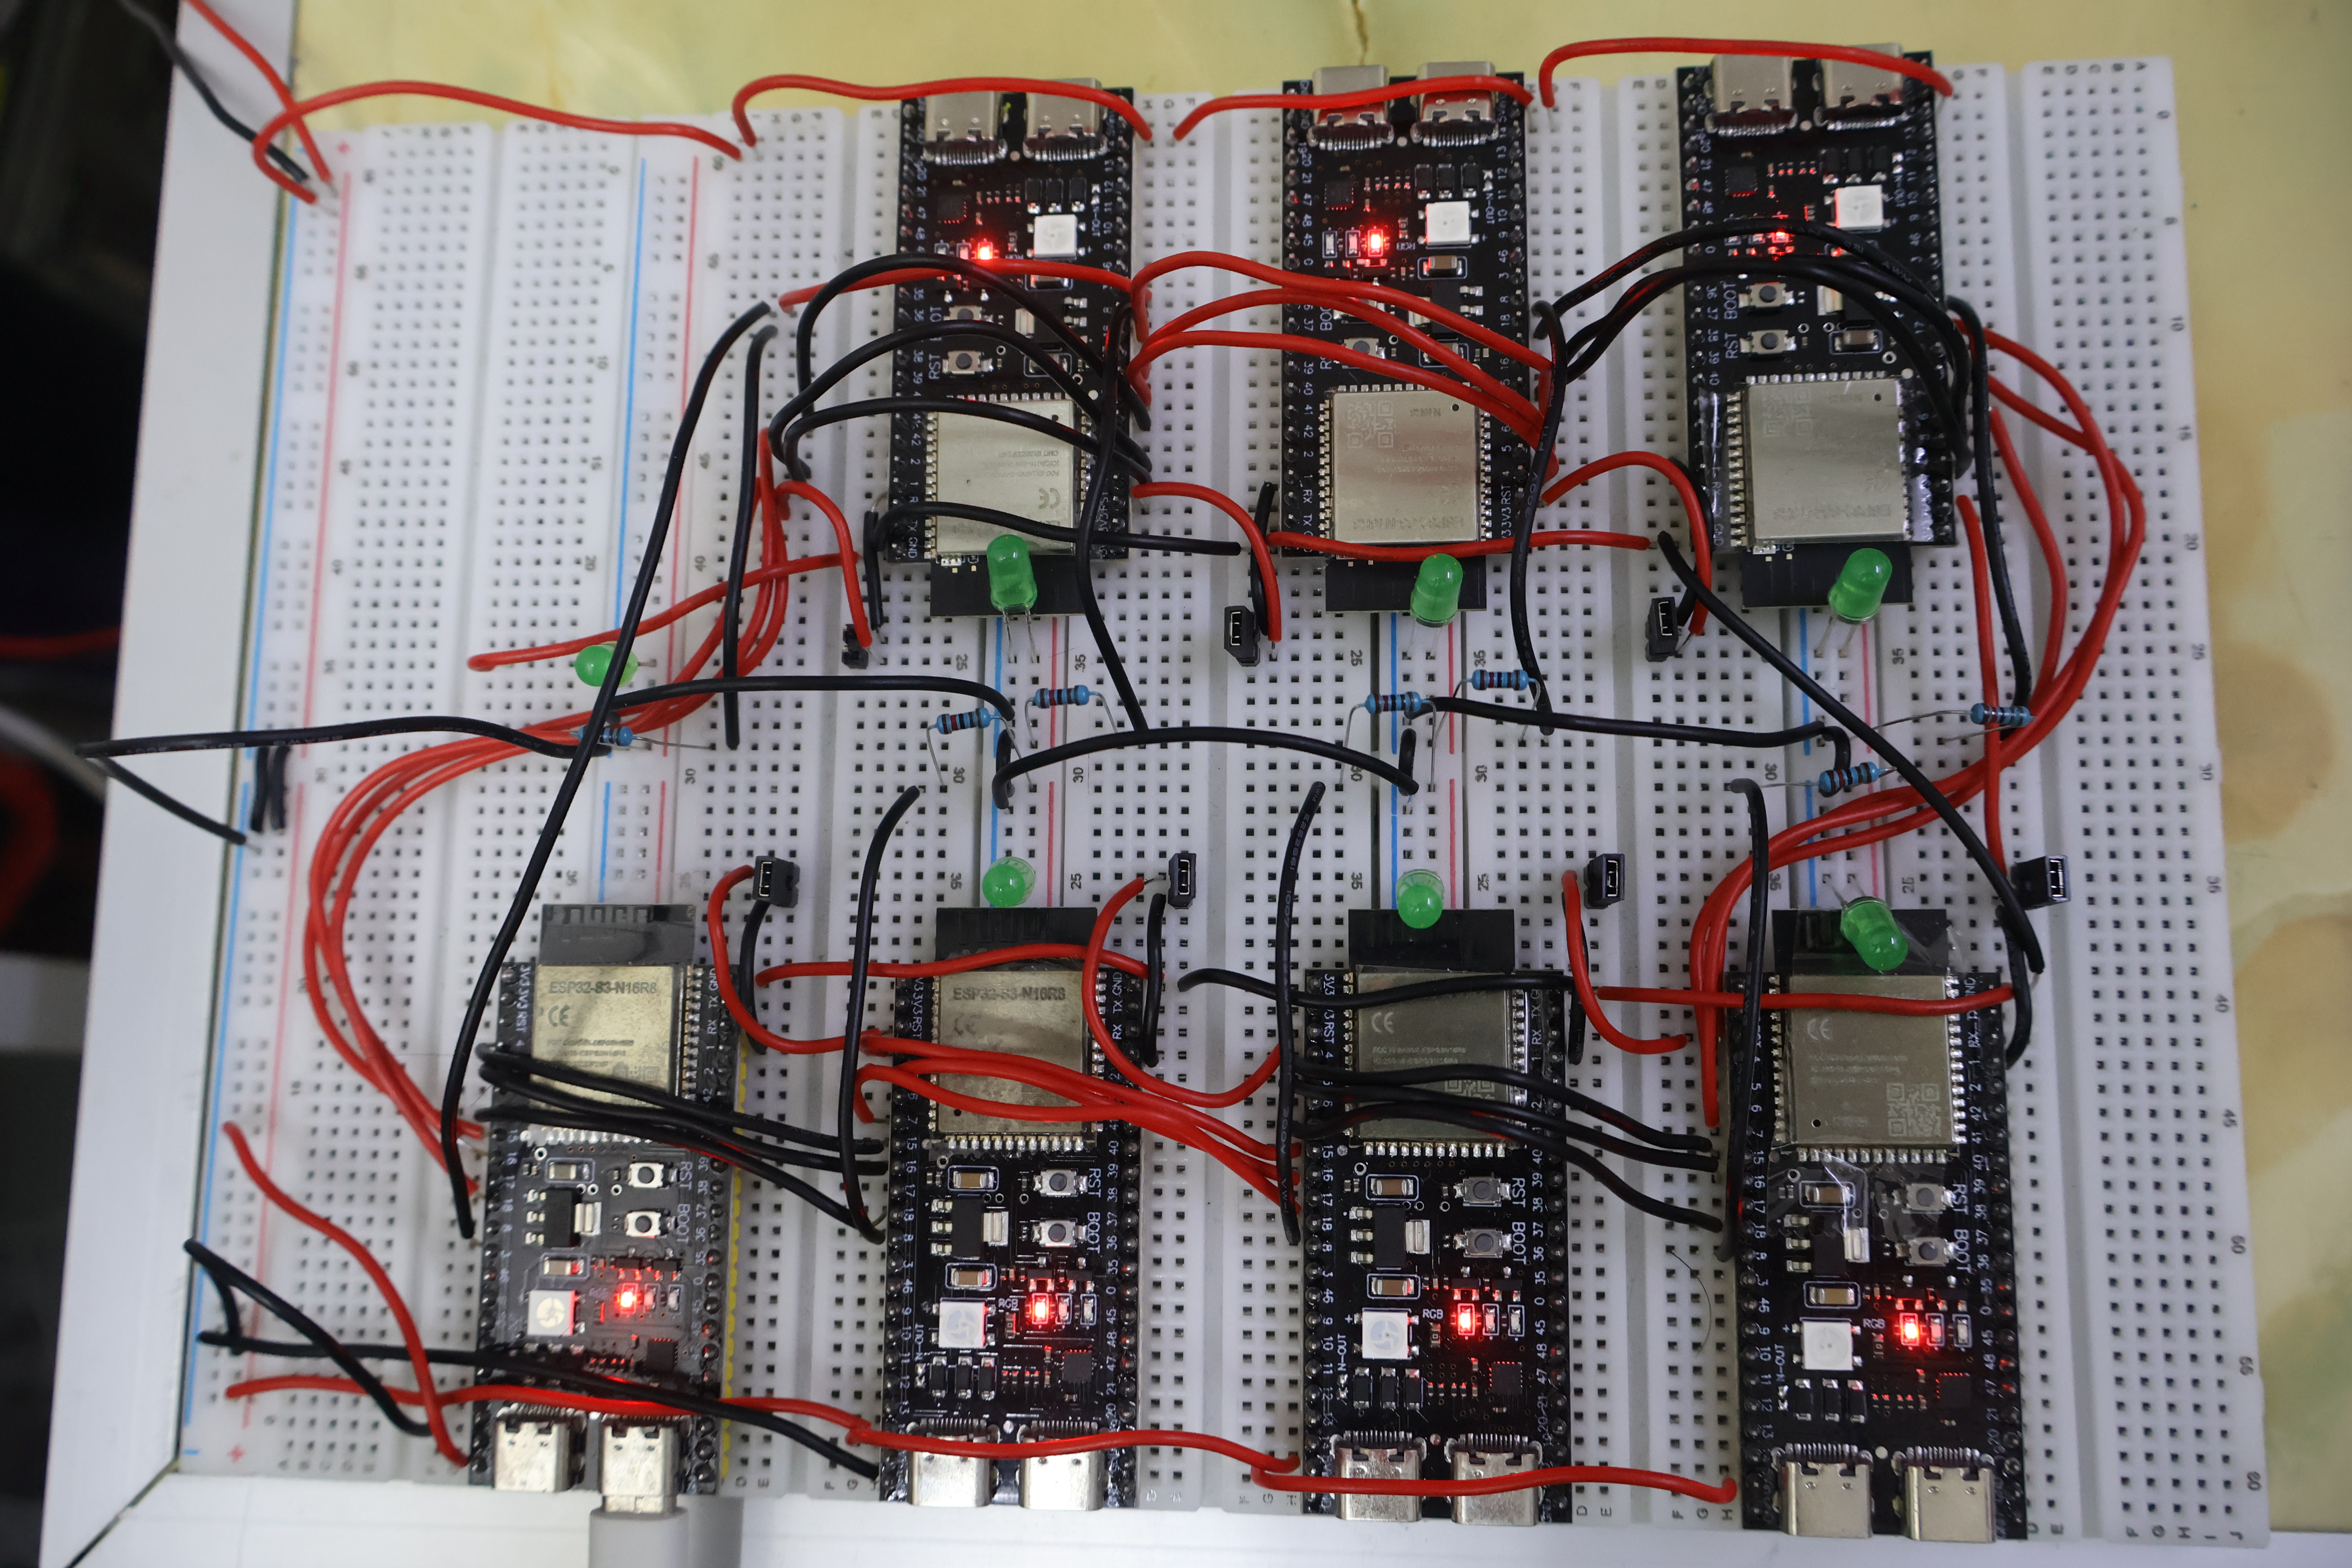
243Low-Zi-Hong/ESP32s3-LLM-Cluster · C++This project is a distributed inference engine that runs a 0.5B-parameter LLM, quantized to 1.58-bit (BitNet) ternary weights, split across a cluster of 7 ESP32-S3 microcontrollers connected via SPI.
- 47
InstinctFlash
200General-Instinct/InstinctFlash · PythonInstinctFlash is a high-performance serving runtime for robotics foundation models - it loads checkpoints like GR00T, Cosmos3, pi0.5, LingBot-VA/VLA and DreamZero, applies acceleration (FP8, fused Triton kernels, caching) and serves them over Python or WebSocket, reporting up to 33.78x speedup on Jetson Thor.
- 48
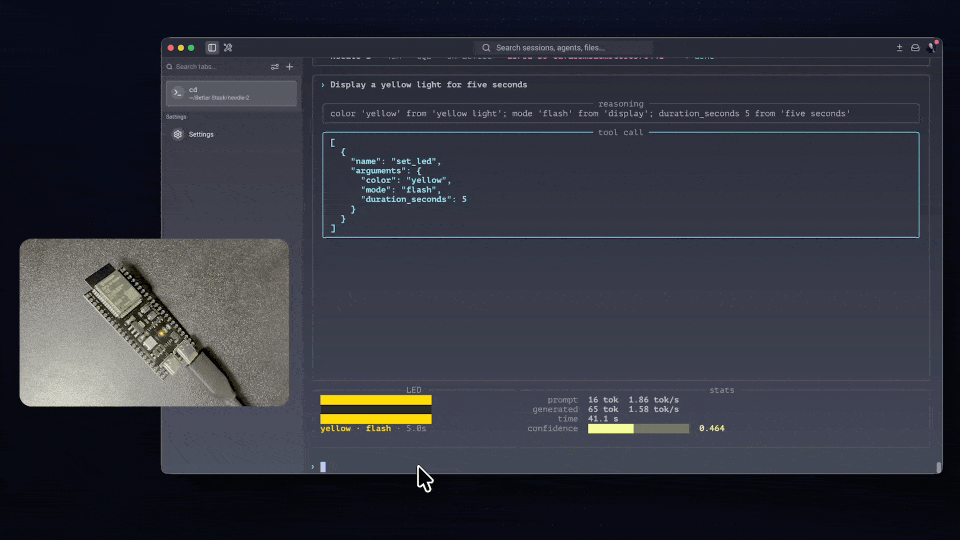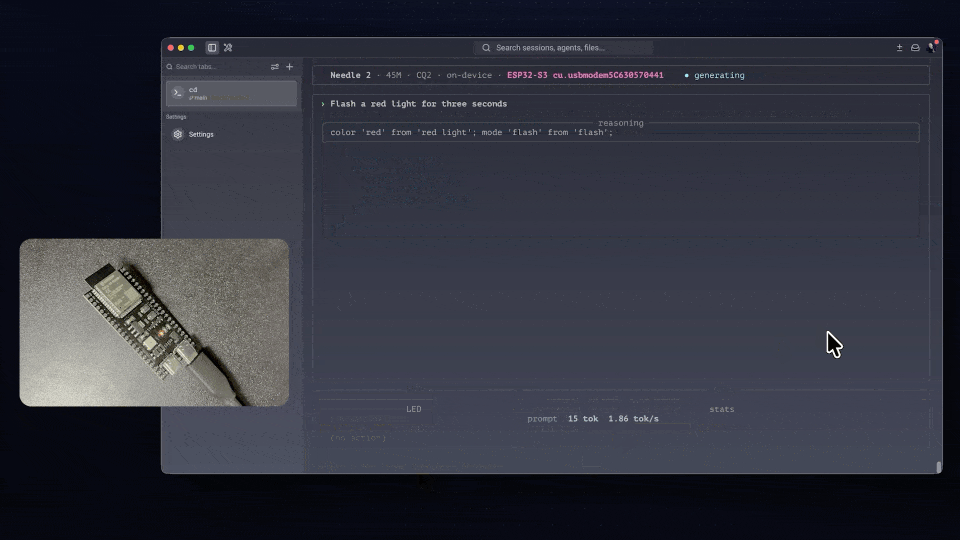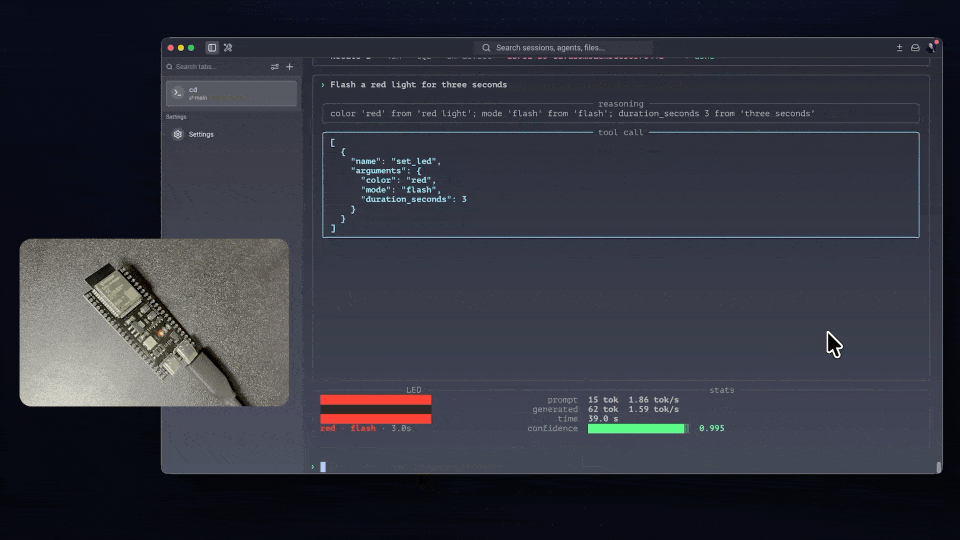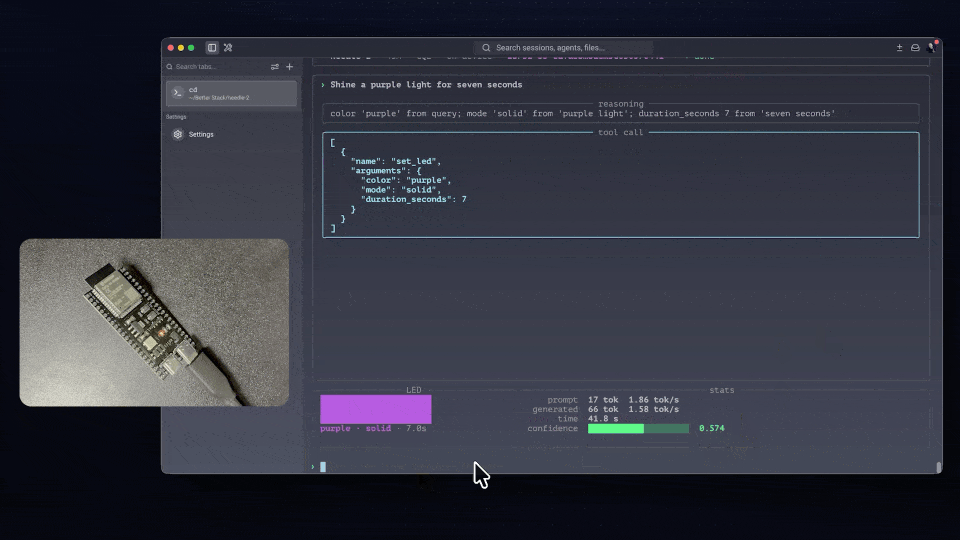
needle-2-esp32
199andrisgauracs/needle-2-esp32 · CIt is a C firmware that runs Cactus's Needle 2, a 45-million-parameter language model, entirely offline on an ESP32-S3 microcontroller, turning plain-English requests into guaranteed-valid JSON tool calls.
- 49
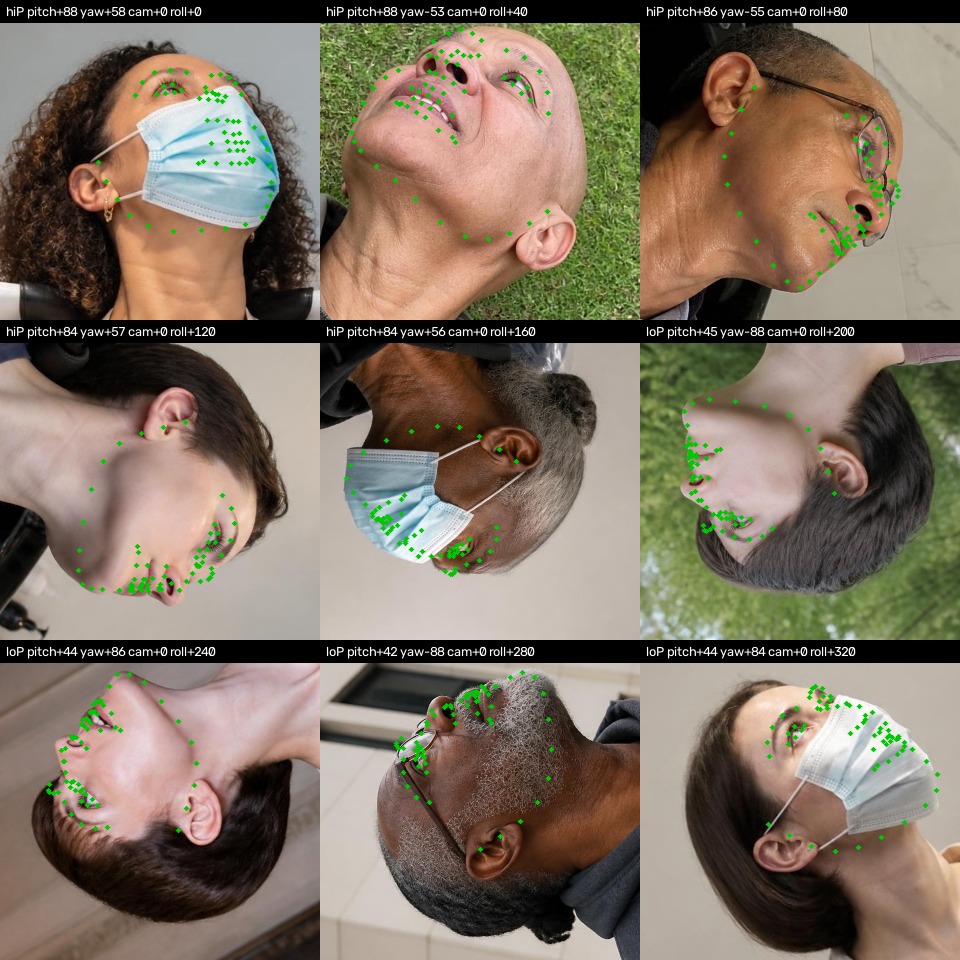
High-Angle_Robust_Fast_FaceAlignment
197PINTO0309/High-Angle_Robust_Fast_FaceAlignment · PythonHRFFA is a training, distillation and ONNX deployment pipeline for whole-head face alignment that stays robust at extreme head poses (looking up/down, full 360° roll, profile views) while being light enough for CPU inference.
- 50
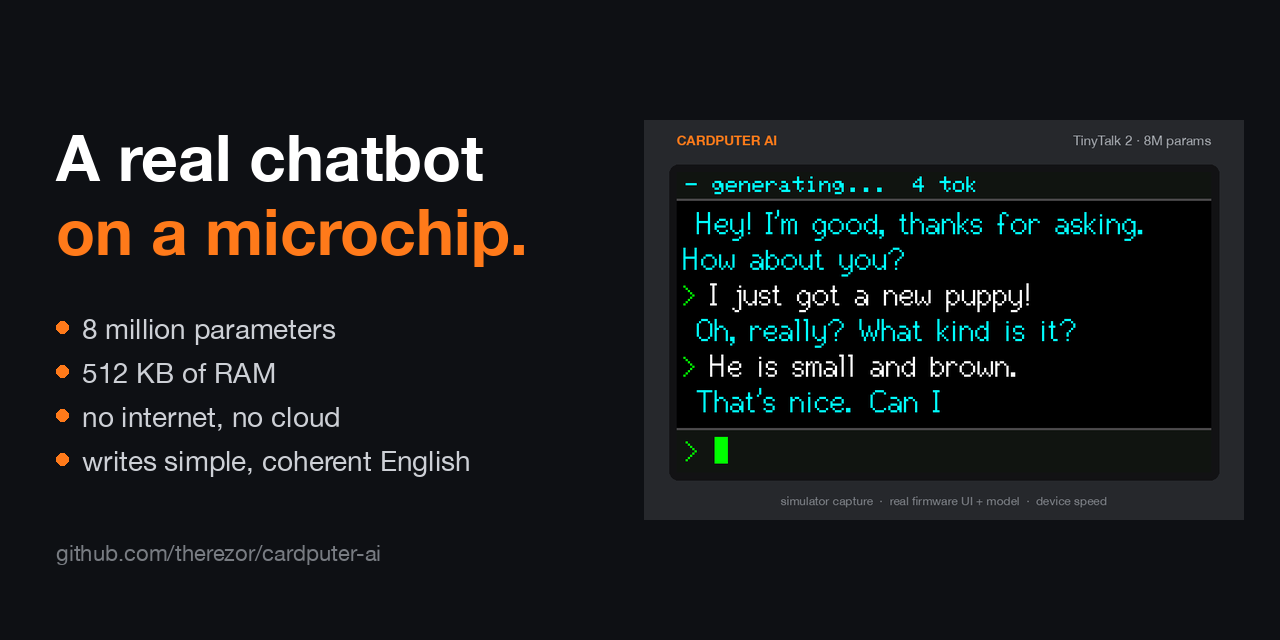
cardputer-ai
119therezor/cardputer-ai · C++Cardputer AI is a tiny offline chatbot that runs entirely on the M5Stack Cardputer / Cardputer ADV handheld, powered by an 8-million-parameter language model baked directly into the firmware.
Related topics
Often tagged together