Topics / #audio-generation
Audio-generation projects on GitHub
AI models that generate speech, music, and sound effects from text or audio prompts.
As of , the most-starred Audio-generation projects on GitHub are ComfyUI (138.6K stars), ppt-master (63.6K stars) and LocalAI (49.6K stars). GitHub.Locker tracks 52 Audio-generation repositories with 727.2K stars combined. The fastest-growing on October 18 was ComfyUI, with +835 stars in a day.
Hot right now
Most stars gained in a day · Oct 18
ComfyUI
Comfy-Org/ComfyUI · ★ 138.6KComfyUI is a node-based graph interface for building and running diffusion model workflows: image, video, 3D, and audio generation, editing, and more, all without writing code.
 +370
ppt-master
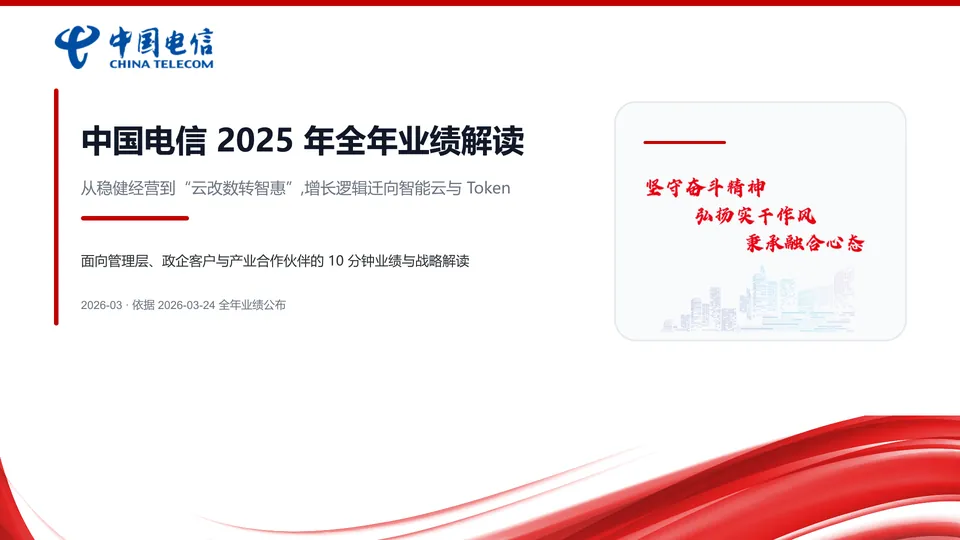
hugohe3/ppt-master · ★ 63.6KPPT Master is an AI workflow that turns documents or a topic into a real, natively editable PowerPoint deck - with native shapes, transitions, animations, data-backed charts and tables, audio narration from speaker notes, and support for your own .pptx templates.
 +263
earshot
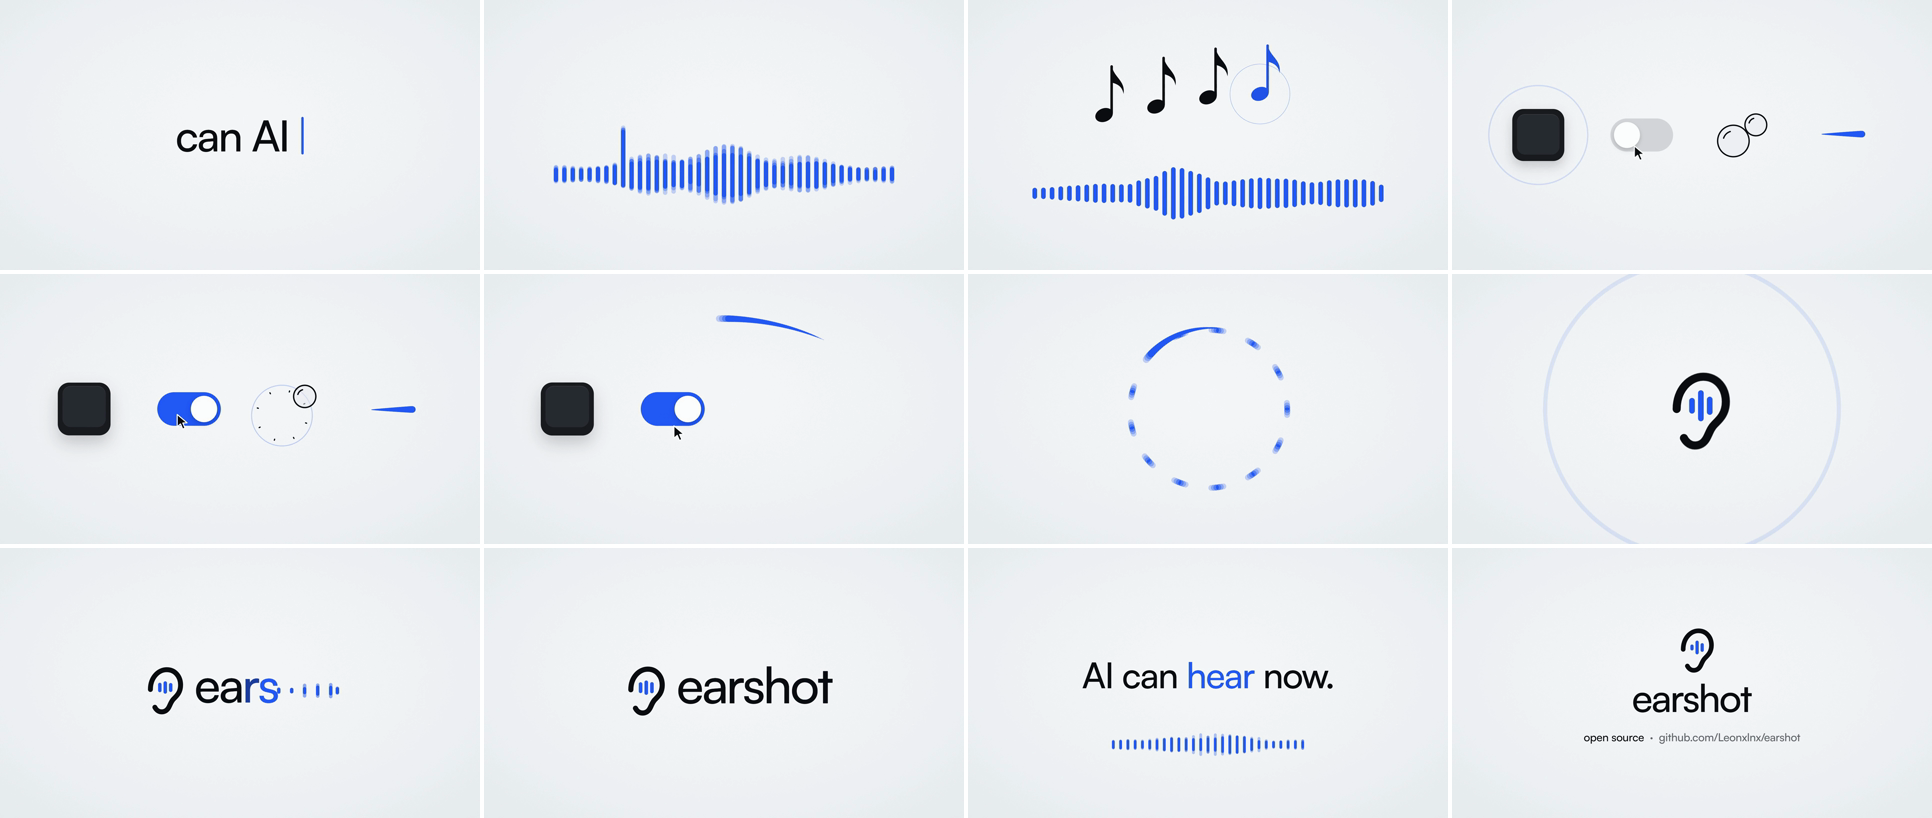
Leonxlnx/earshot · ★ 799Earshot gives AI coding agents the ability to hear and reason about sound: it can describe what a file sounds like, judge how well audio matches a description, find the best moments in a recording, tell real recordings from code-synthesized ones, and critique a video's sound design against professional launch films.
 +215
mg-styles-15
Vincentwei1021/mg-styles-15 · ★ 1.2KA collection of 15 ten-second motion-design films, each in a different visual style, all made by Claude Opus 5.5 writing code from a single text prompt. The repo publishes every film along with its style notes, full prompt and complete source code.
The all-time top
52 projects · by stars
- 138.6K
#1 · Comfy-Org/ComfyUI
ComfyUI
ComfyUI is a node-based graph interface for building and running diffusion model workflows: image, video, 3D, and audio generation, editing, and more, all without writing code.
- 63.6K#2 · hugohe3/ppt-master
ppt-master
PPT Master is an AI workflow that turns documents or a topic into a real, natively editable PowerPoint deck - with native shapes, transitions, animations, data-backed charts and tables, audio narration from speaker notes, and support for your own .pptx templates.
- 49.6K
 #3 · mudler/LocalAI
LocalAI
LocalAI is an open-source, self-hosted AI engine that lets you run LLMs, vision, voice, image and video models on your own hardware, including CPU-only setups, through an OpenAI/Anthropic/ElevenLabs-compatible API.
- 4
ChatTTS
39.9K2noise/ChatTTS · PythonChatTTS is an open-source text-to-speech model built for conversational speech — the natural-sounding voice layer for things like LLM assistants — speaking English and Chinese.
- 5
bark
39.3Ksuno-ai/bark · Jupyter NotebookBark is a transformer-based text-to-audio model from Suno that generates realistic, multilingual speech plus music, background noise, and sound effects from text prompts.
- 6
OpenVoice
38Kmyshell-ai/OpenVoice · PythonOpenVoice is an audio foundation model for instant voice cloning, built by MIT and MyShell; it clones a reference speaker's tone color and generates speech in multiple languages and accents.
- 7
diffusers
34.8Khuggingface/diffusers · PythonDiffusers is Hugging Face's Python library for state-of-the-art pretrained diffusion models that generate images, audio, and even 3D molecule structures, all in PyTorch.
- 8
CosyVoice
24KQwenAudio/CosyVoice · PythonCosyVoice is Alibaba's open-source, LLM-based text-to-speech system. It generates natural speech in 9 languages plus 18+ Chinese dialects, supports zero-shot voice cloning, and ships inference, training and deployment code.
- 9

audiocraft
23.7Kfacebookresearch/audiocraft · Jupyter NotebookAudioCraft is a PyTorch library for deep learning research on audio generation, built around generative models like MusicGen (text-to-music) and AudioGen (text-to-sound), plus the EnCodec neural audio codec.
- 10
ebook2audiobook
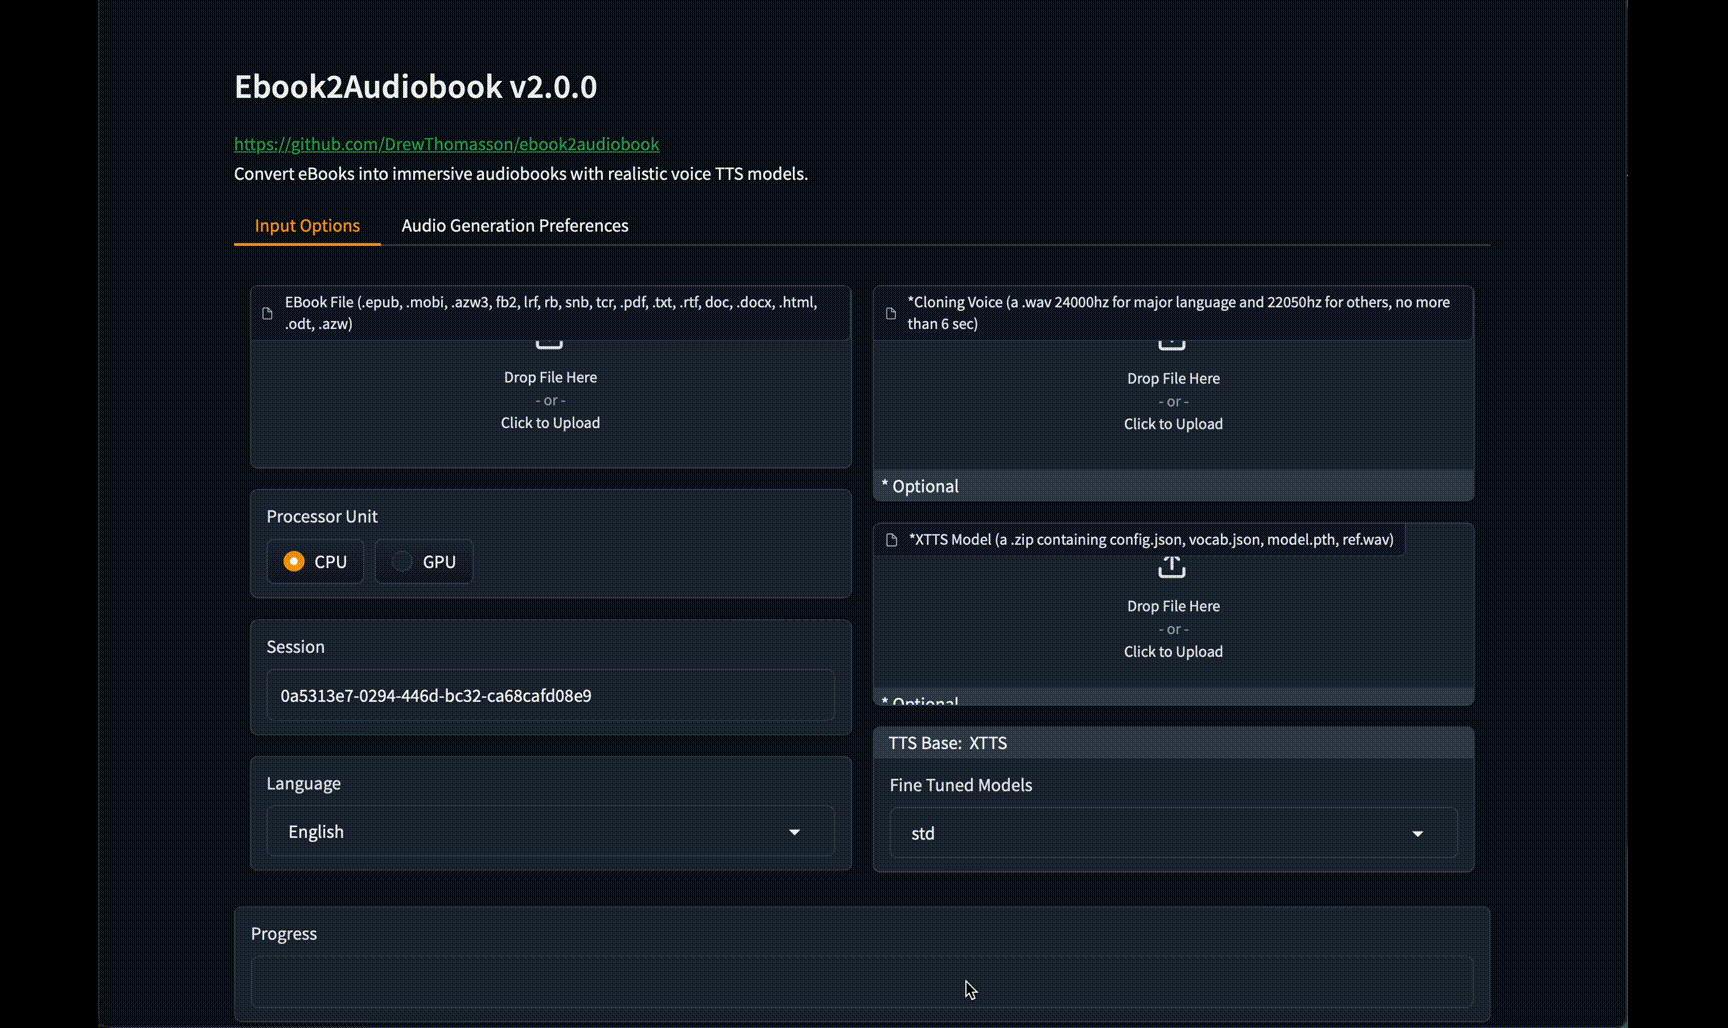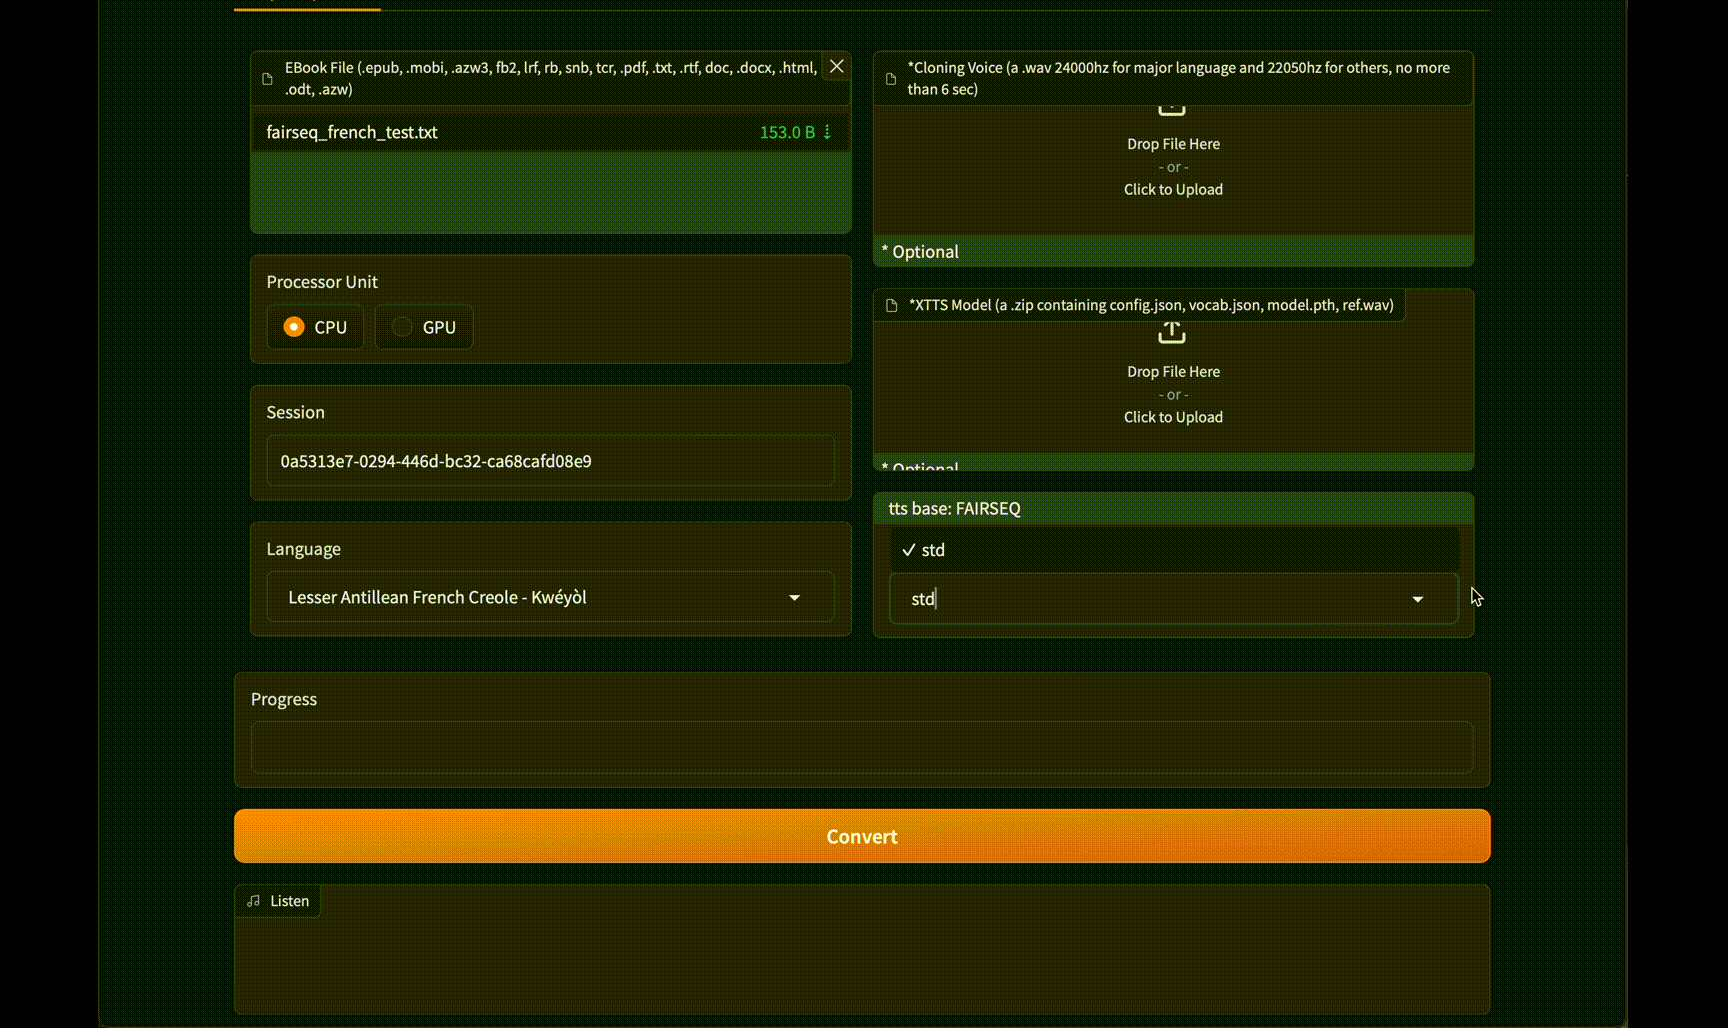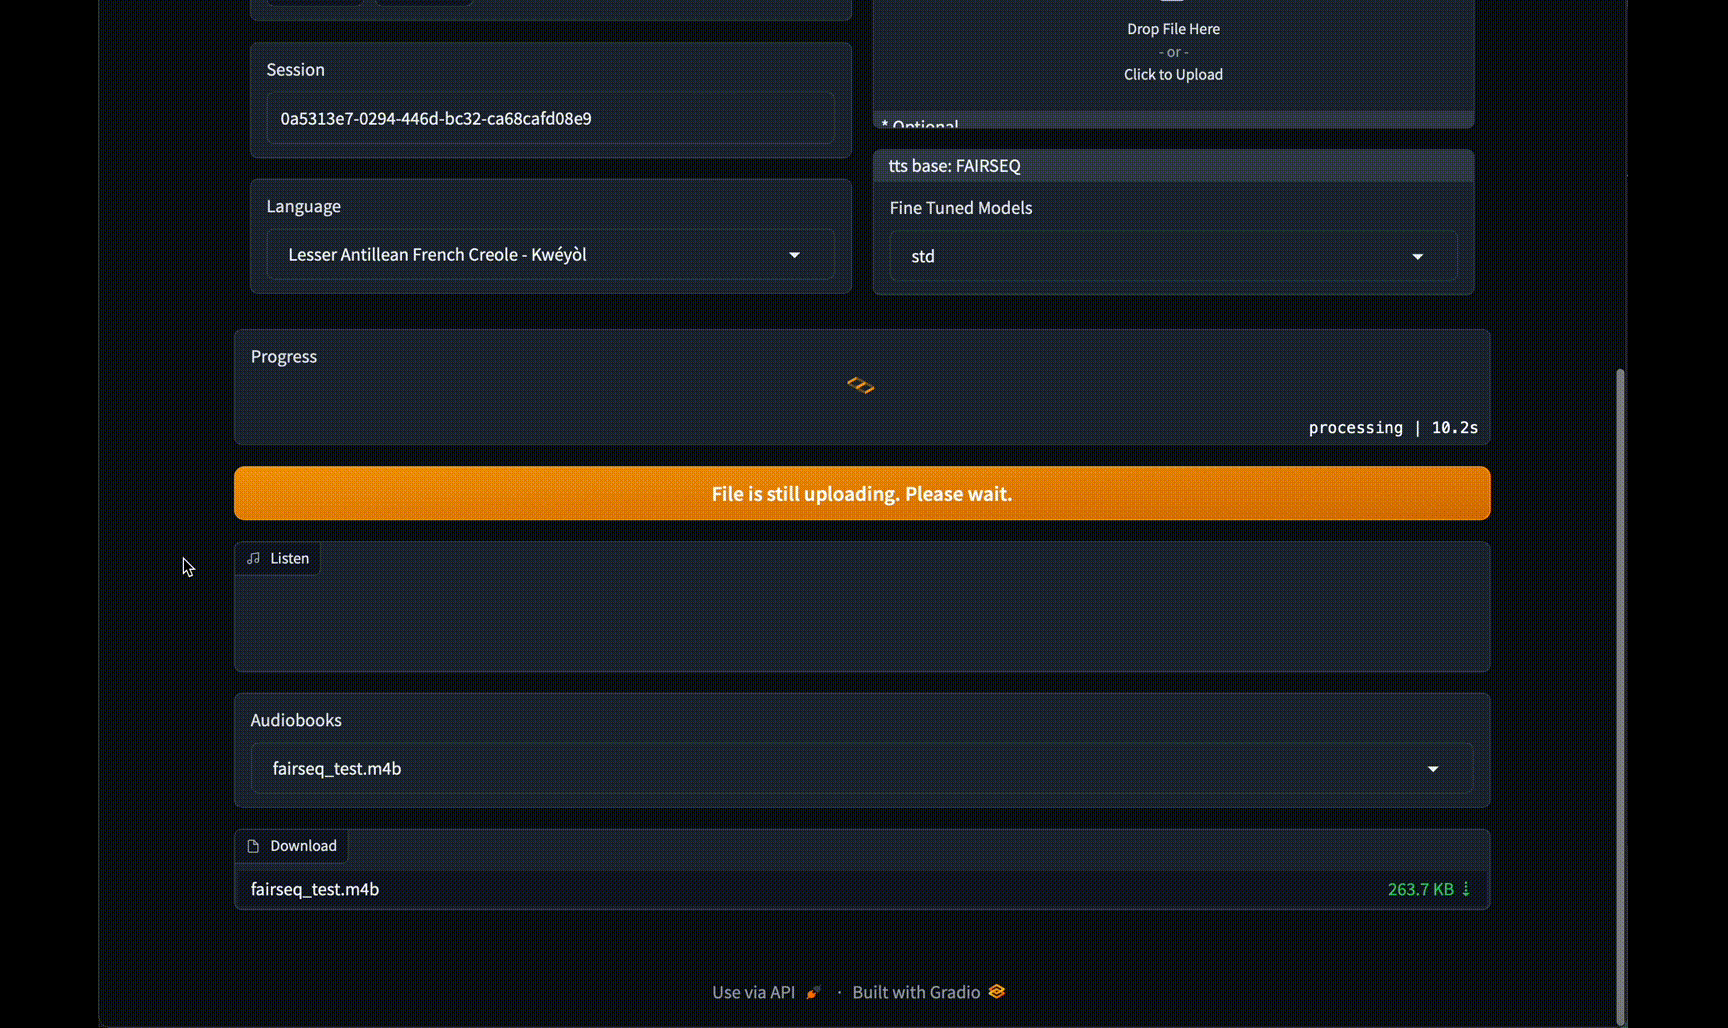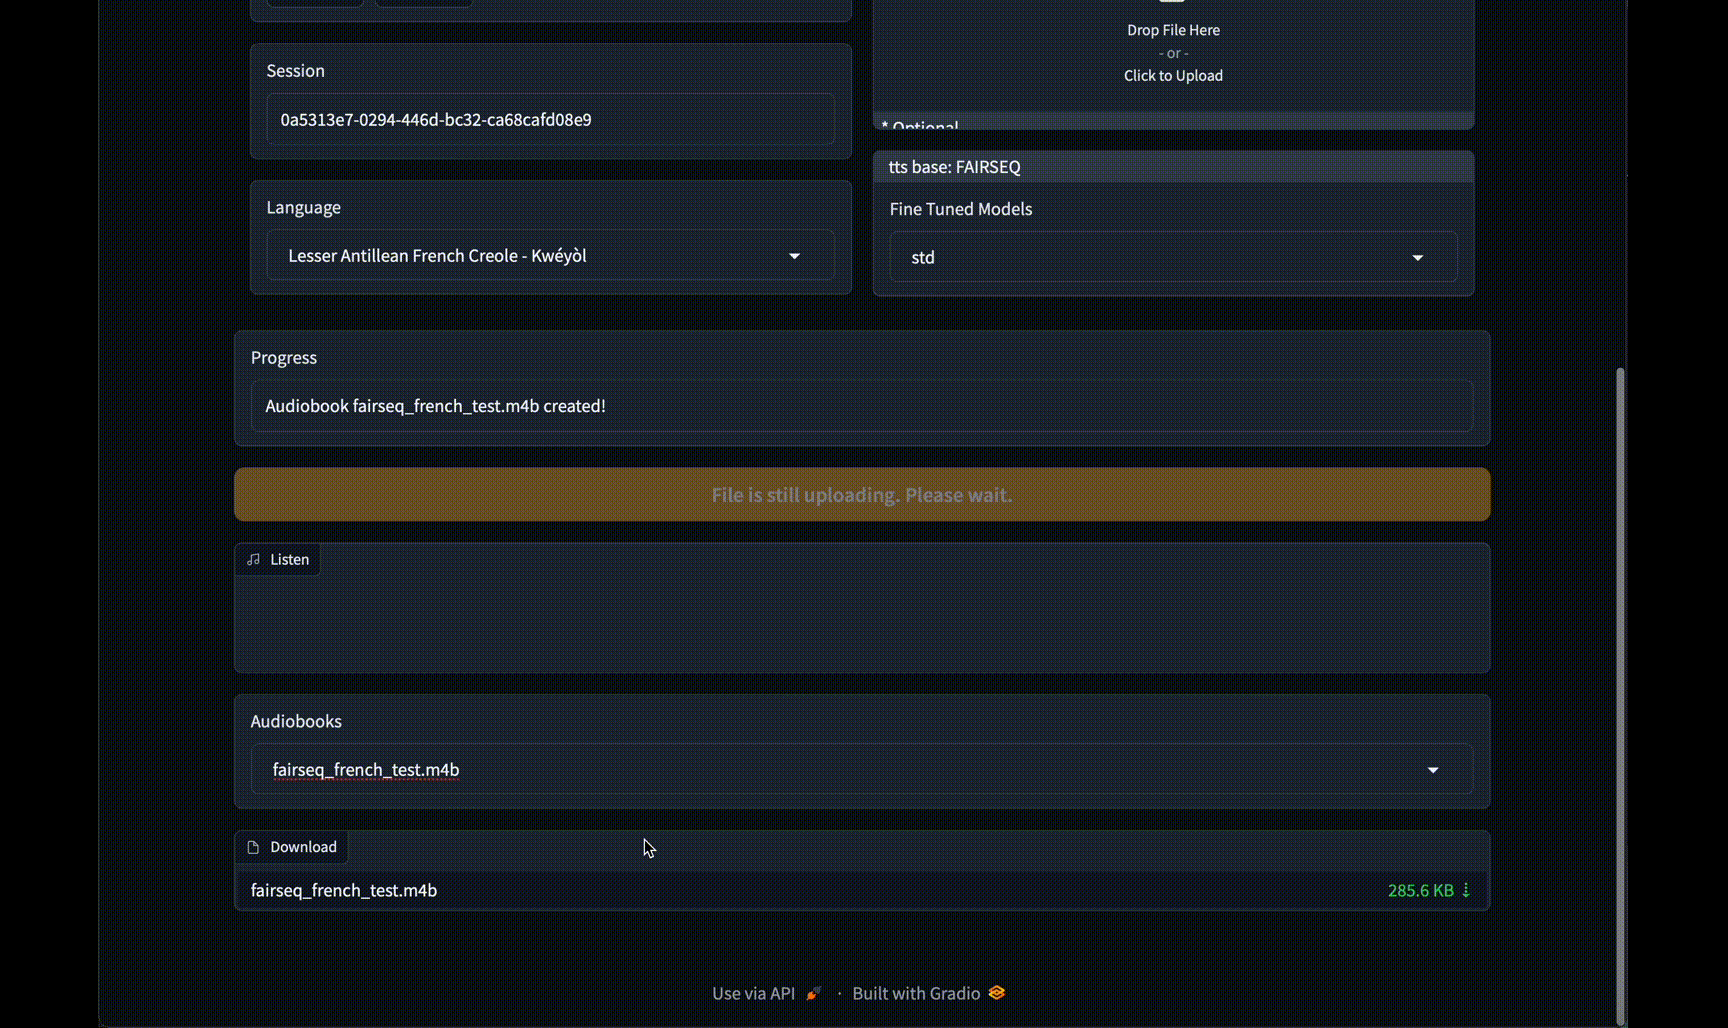
20.4KDrewThomasson/ebook2audiobook · PythonA converter that turns DRM-free e-books into audiobooks with chapters and metadata, using TTS engines with optional voice cloning, in 1158+ languages. It runs locally on modest hardware or in Docker.
- 11
magenta
19.8Kmagenta/magenta · PythonA Google Brain research project on machine learning for creativity: deep learning and reinforcement learning models that generate songs, audio, images, and drawings, plus smart tools for artists and musicians.
- 12

dia
19.4Knari-labs/dia · PythonDia is a 1.6B-parameter open-weights text-to-speech model from Nari Labs that generates ultra-realistic multi-speaker dialogue from a transcript in a single pass.
- 13
Wan2.1
17.2KWan-Video/Wan2.1 · PythonWan2.1 is an open suite of large-scale video generative models: it turns text or images into videos, and also covers video editing, text-to-image and video-to-audio tasks.
- 14

csm
14.7KSesameAILabs/csm · PythonCSM (Conversational Speech Model) is a speech generation model from Sesame that turns text and audio input into spoken audio by producing RVQ audio codes, using a Llama backbone plus a smaller audio decoder.
- 15
ACE-Step-1.5
13.8Kace-step/ACE-Step-1.5 · PythonACE-Step 1.5 is an open-source local music generation model that turns text prompts (and optional reference audio) into full songs, aiming for quality on par with commercial tools like Suno.
- 16
DiffSynth-Studio
13.3Kmodelscope/DiffSynth-Studio · PythonDiffSynth-Studio is an open-source Diffusion model engine built and maintained by the ModelScope Community, covering image, video, and audio generation plus image quality metrics, with support for both inference and training.
- 17

awesome-generative-ai
12.7Ksteven2358/awesome-generative-aiA curated list of modern Generative AI projects and services, covering text, coding, agents, image, video, audio, and more.
- 18
ai-toolkit
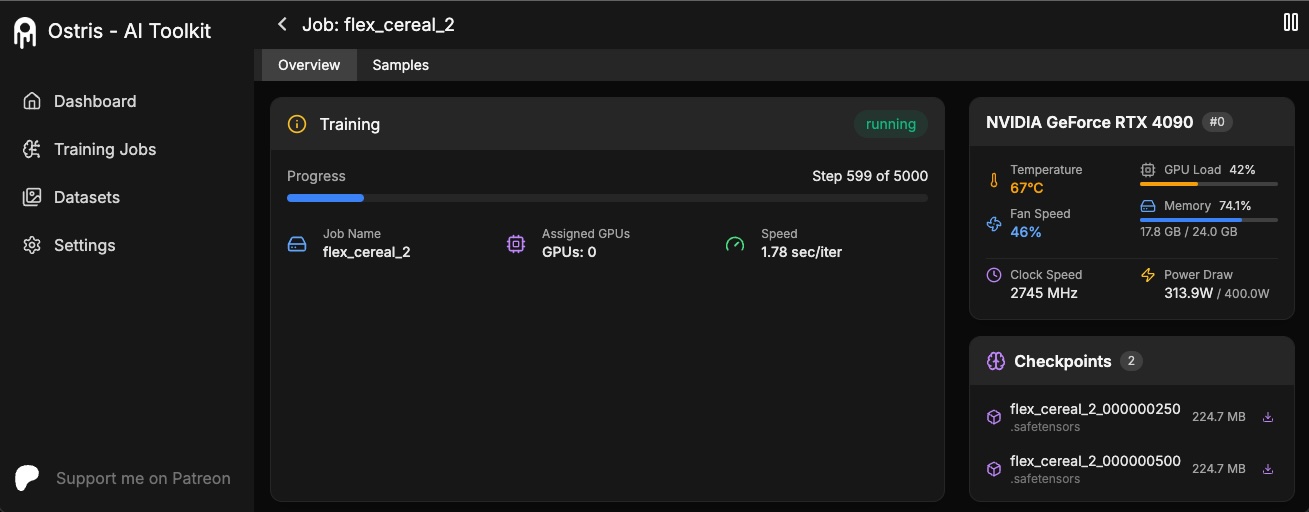
12.4Kostris/ai-toolkit · PythonAI Toolkit is an all-in-one training suite for finetuning diffusion models, covering image, video, and audio generation models, with support for the latest models like FLUX, Qwen-Image, Wan 2.1/2.2, and Ace-Step on consumer GPUs.
- 19
YuE
12.3Kmultimodal-art-projection/YuE · PythonYuE2 is an open-source music generation model: lyrics plus a style prompt become an editable melody-and-chord plan, then a complete song with vocals and accompaniment. It also does zero-shot covers and agent-driven editing.
- 20
image-blaster
11.5Kneilsonnn/image-blaster · TypeScriptimage-blaster is a skillset for Claude that turns a single image into a 3D environment, complete with meshes and sound effects, by orchestrating Claude skills alongside the World Labs and FAL APIs.
- 21

WanGP
10.7Kdeepbeepmeep/WanGP · PythonWanGP is a one-stop open source app for running top generative AI models for video, image, and audio/TTS generation, built specifically to work on modest consumer GPUs (the 'GPU Poor').
- 22
Amphion
10.3Kopen-mmlab/Amphion · PythonAn open-source toolkit for audio, music, and speech generation. It is built to support reproducible research and help junior researchers and engineers get started in the field.
- 23

TTS
10.2Kmozilla/TTS · Jupyter NotebookAn open-source deep learning library for text-to-speech: pretrained models, vocoders, a speaker encoder and dataset tools, already used in 20+ languages for products and research.
- 24

AudioGPT
10.2KAIGC-Audio/AudioGPT · PythonAudioGPT is an open-source research system for understanding and generating speech, music, sound, and talking heads — pretrained foundation models wrapped behind prompt-driven audio tasks.
- 25
MiniMax-H3
10.1KMiniMax-AI/MiniMax-H3 · PythonMiniMax H3 is a general-purpose omni-modal generative system: it reads mixed text, image, video and audio input and generates video with native stereo audio, up to 2K resolution and 15 seconds per clip.
- 26
LTX-2
9.8KLightricks/LTX-2 · PythonThe official Python package for LTX-2, Lightricks' audio-video foundation model: one DiT-based model that generates video with synchronized audio from text or an image, in several quality/speed modes.
- 27
universal-modder
8.4Krehan-remade/universal-modder · PythonUniversal Modder gives Claude Code (and other AI coding agents) a set of Agent Skills, a CLI called 'um', and a fal MCP server so the agent can find, reverse-engineer, and mod almost any PC game you own, then generate art, 3D, audio, test the mod in-game, and record a showcase video.
- 28
vllm-omni
7.2Kvllm-project/vllm-omni · PythonvLLM-Omni is an inference and serving framework that extends vLLM beyond text-only LLMs to omni-modality models, handling text, image, audio, video, and action outputs.
- 29

LuxTTS
5.5Kysharma3501/LuxTTS · PythonLuxTTS is a lightweight text-to-speech model built on the ZipVoice architecture, designed for high-quality voice cloning and fast speech generation.
- 30
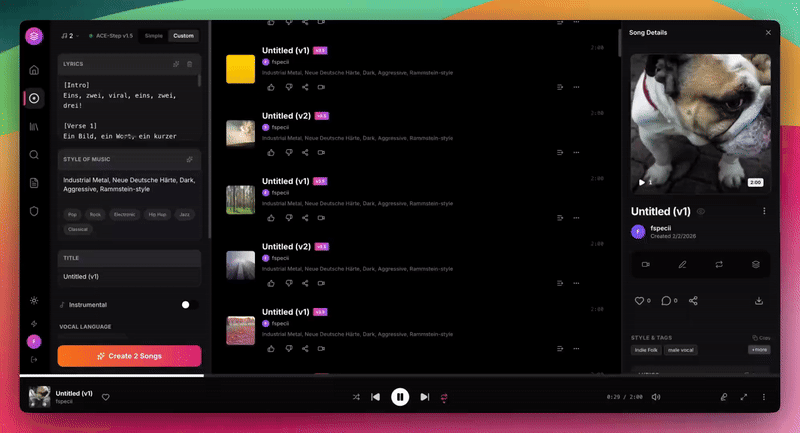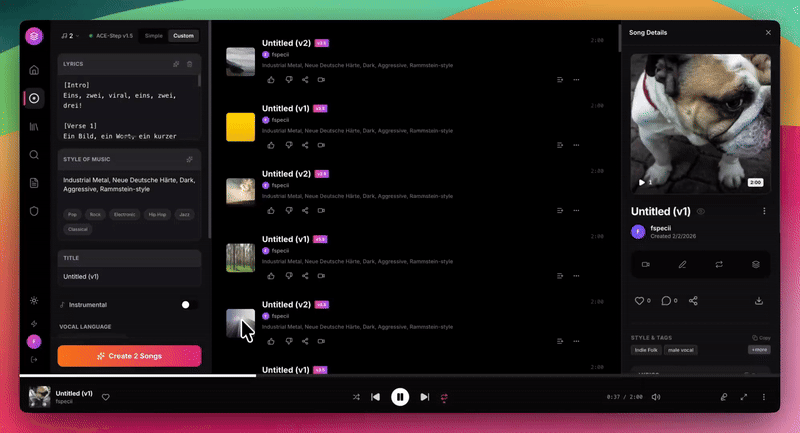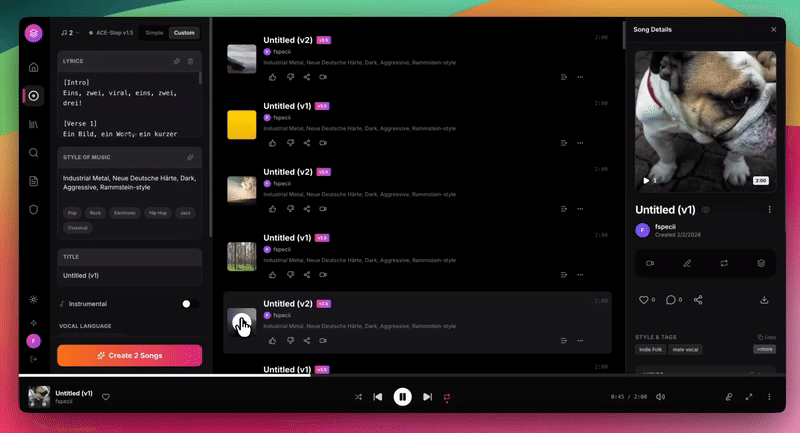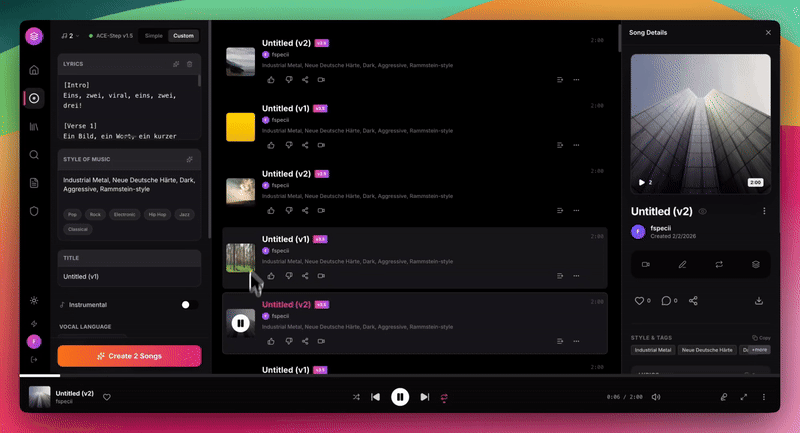
ace-step-ui
5.1Kfspecii/ace-step-ui · JavaScriptACE-Step UI is a free, open-source, locally-run web interface for the ACE-Step 1.5 AI music generation model, letting you create full songs with vocals or instrumentals without paying for Suno or Udio.
- 31
Easel
3.9KZJU-REAL/Easel · PythonEasel is an open-source content workbench built around an AI agent that discovers trends, plans topics, creates text/image/audio/video content, publishes it to Chinese social platforms, and learns from performance data to improve future content.
- 32
lanshu-create-ai-presenter-video
2.7Kcclank/lanshu-create-ai-presenter-video · HTMLThis is a Codex Skill that turns a topic or script plus an authorized photo of a person into a full AI presenter video: it writes the script, generates voiceover, creates the character, syncs lips, adds subtitles and keyword animations, edits, renders and runs quality checks.
- 33

threejs-game-skills
2.5Kmajidmanzarpour/threejs-game-skills · PythonA set of nine self-contained skill packages (SKILL.md files) that teach Codex and Claude Code how to build playable, polished Three.js browser games end-to-end, including gameplay, AAA-style graphics, UI, QA, and optional AI-generated 3D, image, and audio assets.
- 34
Drift
2KCutWire-Studios/Drift · C++Drift is a free, open-source desktop video editor from CutWire Studios, built with Qt 6 and FFmpeg, for cutting clips, adding effects, captions, stickers and music, then exporting without subscriptions, watermarks, or accounts.
- 35
mg-styles-15
1.2KVincentwei1021/mg-styles-15 · PythonA collection of 15 ten-second motion-design films, each in a different visual style, all made by Claude Opus 5.5 writing code from a single text prompt. The repo publishes every film along with its style notes, full prompt and complete source code.
- 36
skills
1.1Kscenario-labs/skills · PythonAgent Skills that teach AI coding agents (Claude Code, Cursor, Codex, Copilot, and 70+ others) to create production-ready images, video, audio, textures, skyboxes and 3D assets through the Scenario MCP server, for games and other creative work.
- 37
MiniMax-Music3
966MiniMax-AI/MiniMax-Music3MiniMax Music 3 is a music generation model that creates complete songs up to five minutes long from lyrics and a music description, producing 32 kHz 16-bit stereo WAV audio with coherent structure and expressive vocals.
- 38
guizang-product-video-skill
828op7418/guizang-product-video-skill · PythonA Claude Code / Codex agent skill that turns a product's own codebase into a polished update or promo video: it writes the script, reuses the product's real UI components for the shots, animates them with code, and composes an original soundtrack and sound effects, then renders an MP4 plus an editable video project.
- 39
earshot
799Leonxlnx/earshot · PythonEarshot gives AI coding agents the ability to hear and reason about sound: it can describe what a file sounds like, judge how well audio matches a description, find the best moments in a recording, tell real recordings from code-synthesized ones, and critique a video's sound design against professional launch films.
- 40
Colab-notebooks
559TeamAIQ/Colab-notebooks · Jupyter NotebookA curated collection of free, ready-to-run Google Colab and Kaggle notebooks, each wrapping a different AI tool for text-to-speech, voice cloning, image generation, video generation, or music generation.
- 41
DramaBox
507resemble-ai/DramaBox · PythonDramaBox is Resemble AI's expressive text-to-speech model with voice cloning, fine-tuned on top of Lightricks' LTX-2.3 audio model. The prompt itself controls speaker identity, emotion, delivery style, laughs, sighs, pauses and transitions, and an optional 10-second voice reference clones the target voice timbre.
- 42

ComfyUI-MiniMaxH3Mod
468Luisacaotica/ComfyUI-MiniMaxH3Mod · PythonA ComfyUI custom node pack that adds 'RefMod' reference adapters for the MiniMax H3 model. It compresses reference images, videos or audio into small reusable .safetensors files that can be loaded and applied to influence generation without any training of the H3 model.
- 43
awesome-minimax-h3-integration
446MiniMax-AI/awesome-minimax-h3-integrationA community-maintained index of checkpoints, tools, and workflows for MiniMax H3, a video generation model that produces clips with native stereo audio from text, image, video, and audio inputs.
- 44
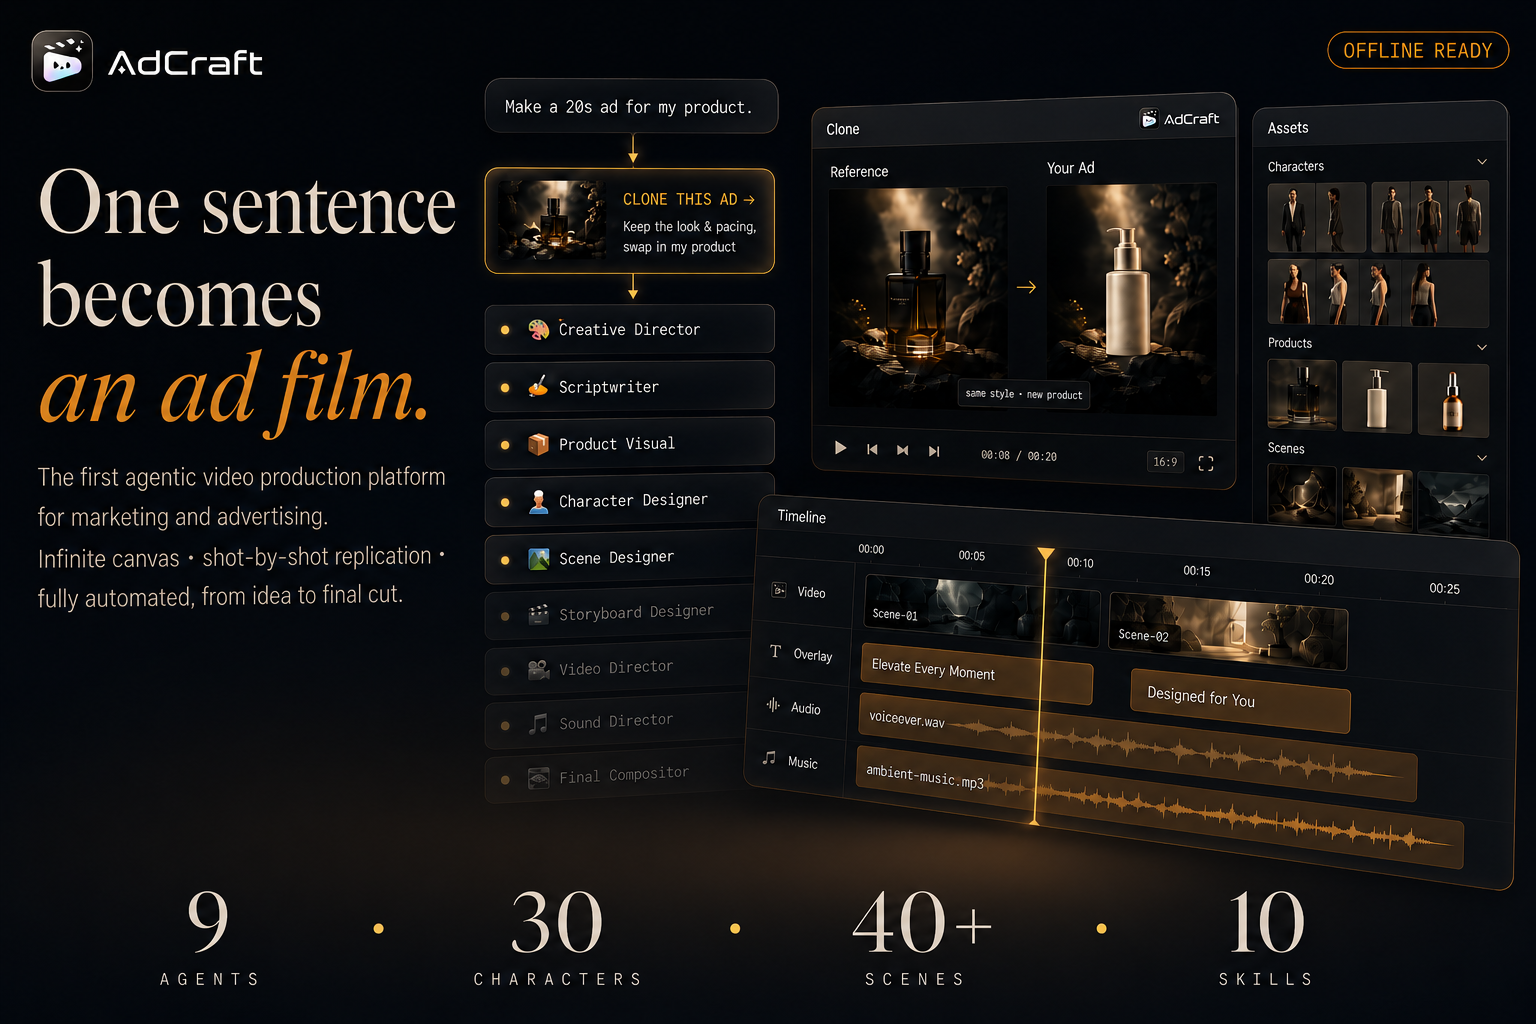
AdCraft
439GML-MMGroup/AdCraft · PythonAdCraft is an agentic AI video production platform for making advertising videos end-to-end, from a vague idea to a finished ad, orchestrated by a team of specialized AI agents on an editable infinite canvas.
- 45
framefields
420gatewai-dev/framefields · TypeScriptFramefields is a TypeScript npm package for code-first video: you write a composition in code (layers, 3D, typography, audio, charts) and it renders it natively on GPU via WebGPU/Dawn into an MP4, with no desktop creative suite needed.
- 46
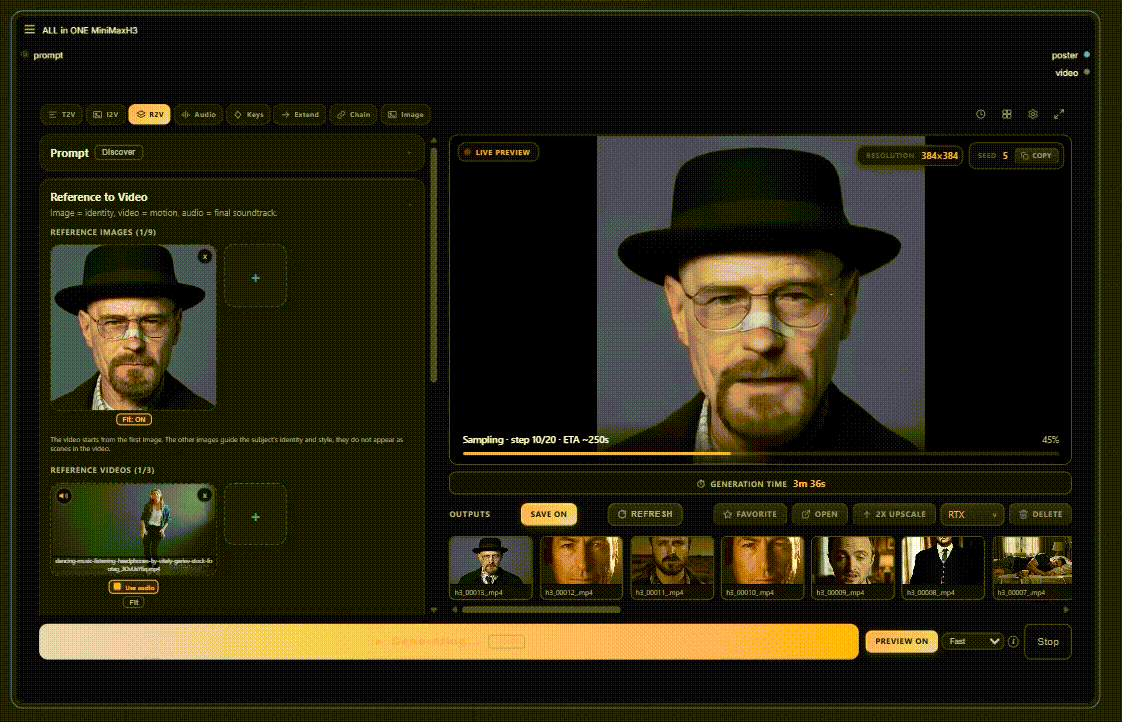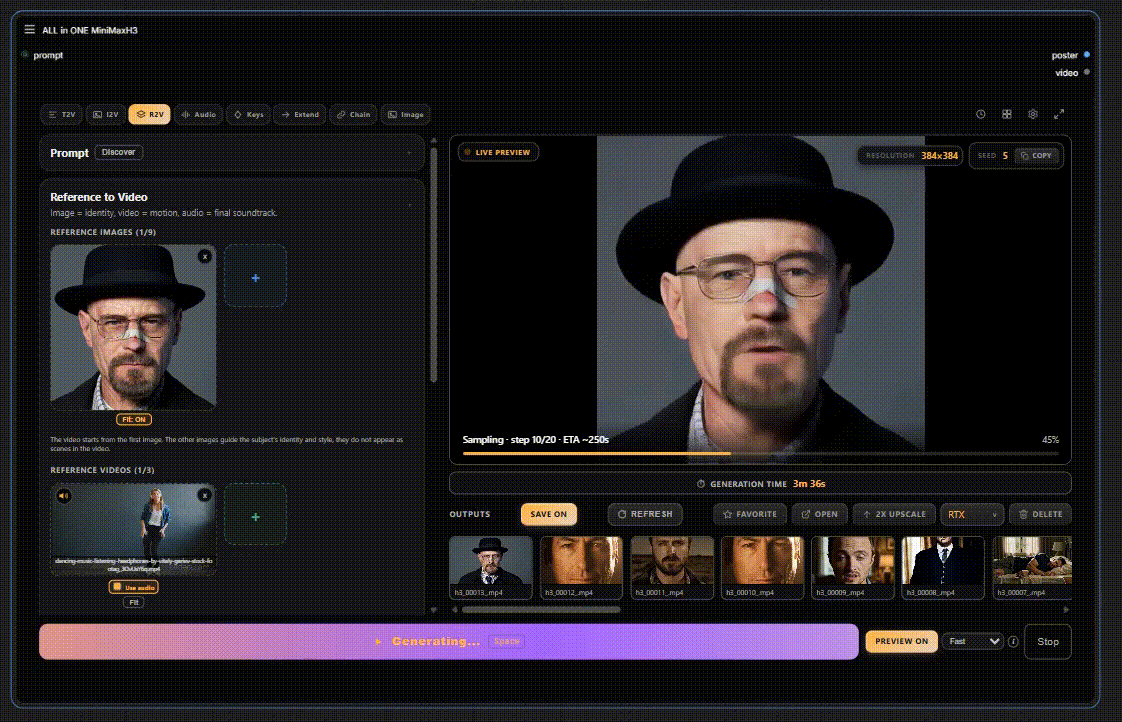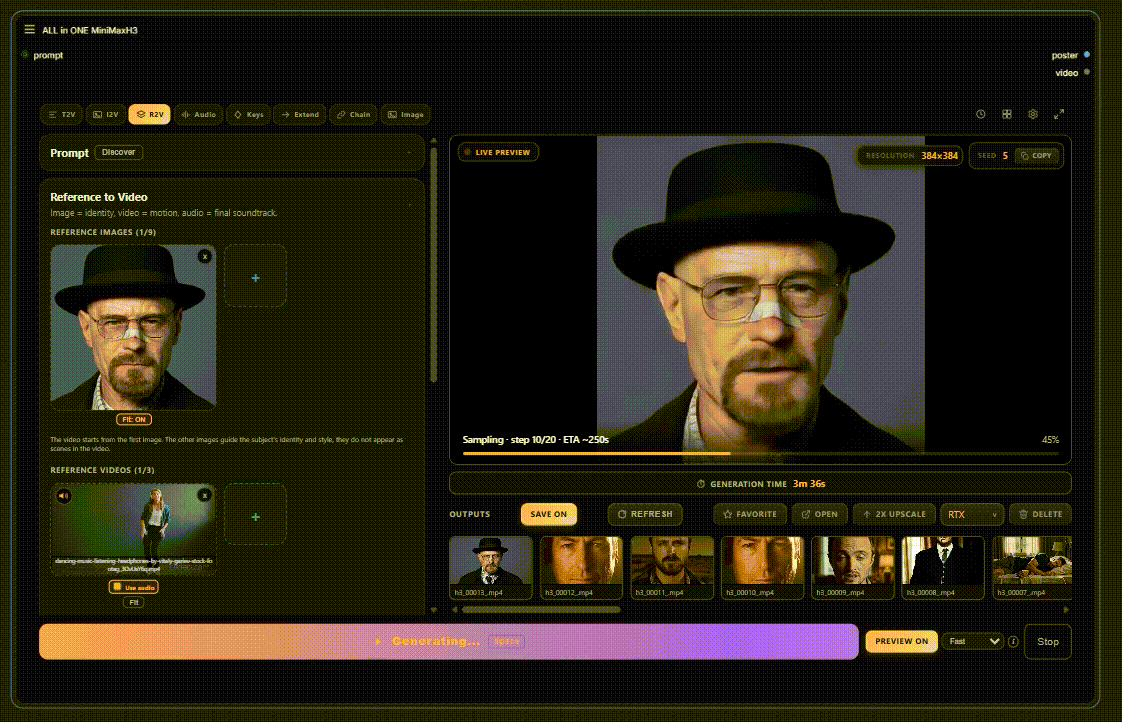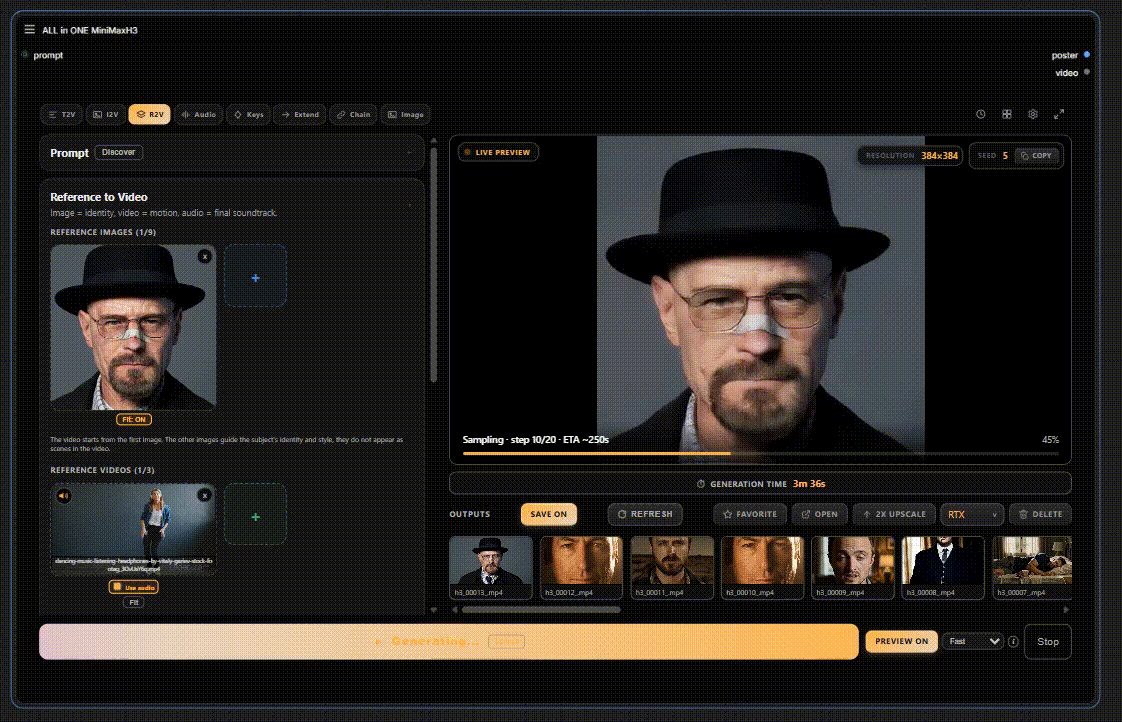
ComfyUI-ALLinONE-MinimaxH3
355LeonQ8/ComfyUI-ALLinONE-MinimaxH3 · JavaScriptA single custom node for ComfyUI that packs the whole MiniMax H3 video pipeline into one node — pick a mode, drop in your prompt or references, and hit Generate.
- 47

seedance-2.0-api
329apiframe-ai/seedance-2.0-apiThis repo contains example scripts for calling ByteDance's Seedance 2.0 video generation model through the Apiframe API, covering text-to-video, image-to-video, and reference-to-video generation.
- 48
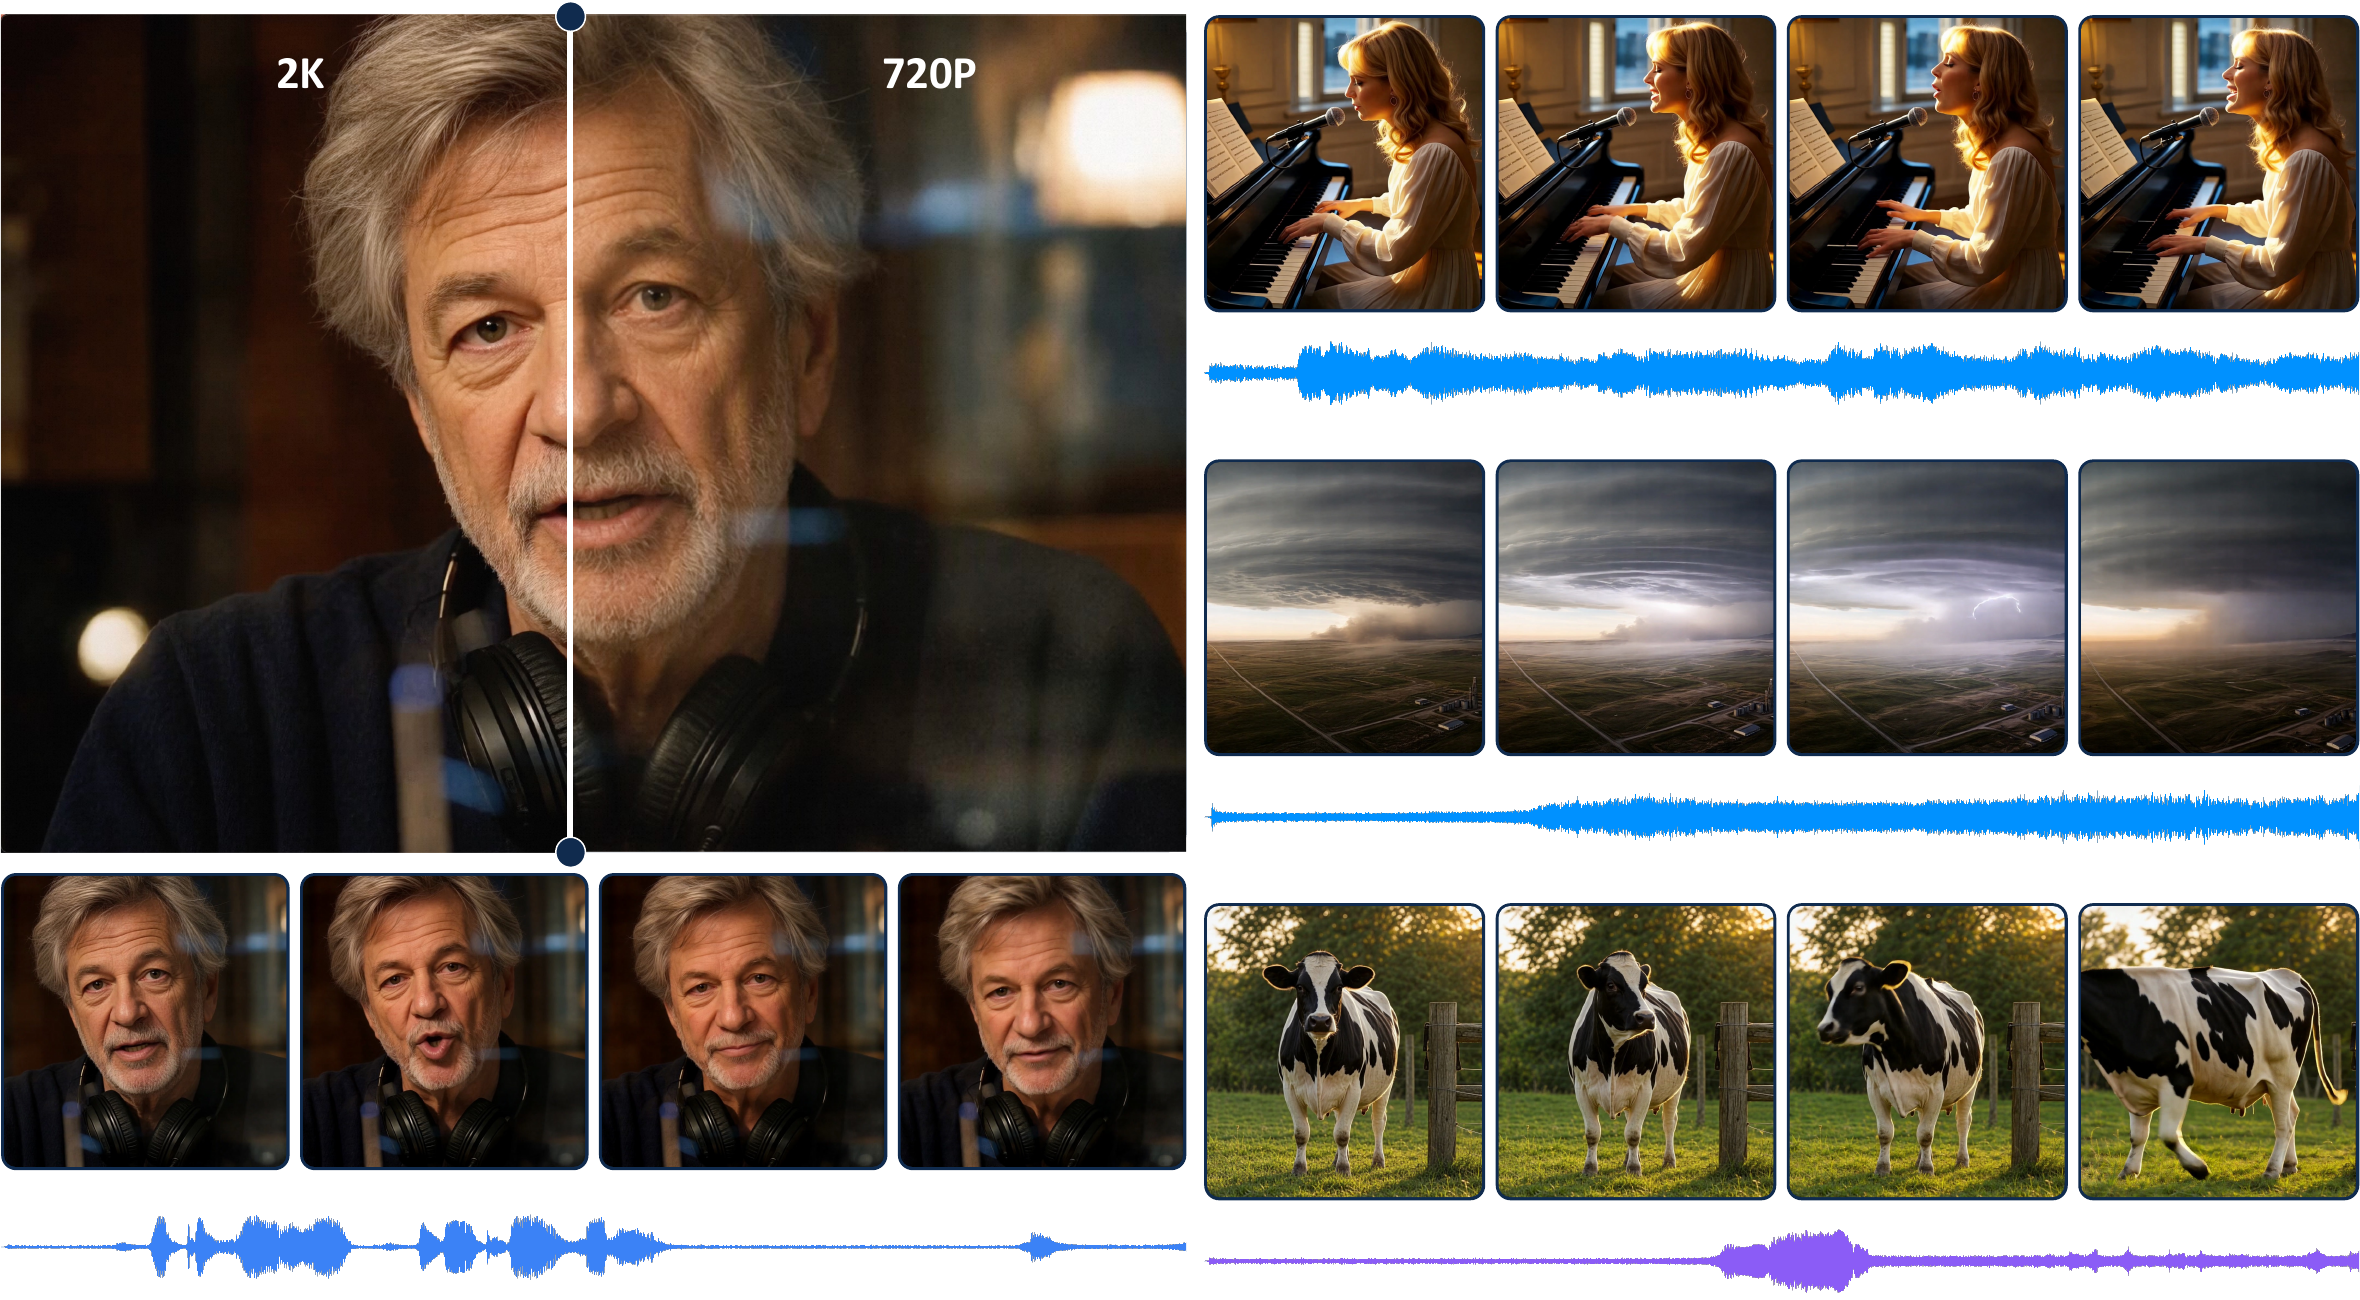
DreamX-Creator
312AMAP-ML/DreamX-Creator · PythonDreamX-Creator is an open-source research framework for native joint audio-video generation: it produces video and a synchronized audio track together, refined up to 2K resolution.
- 49
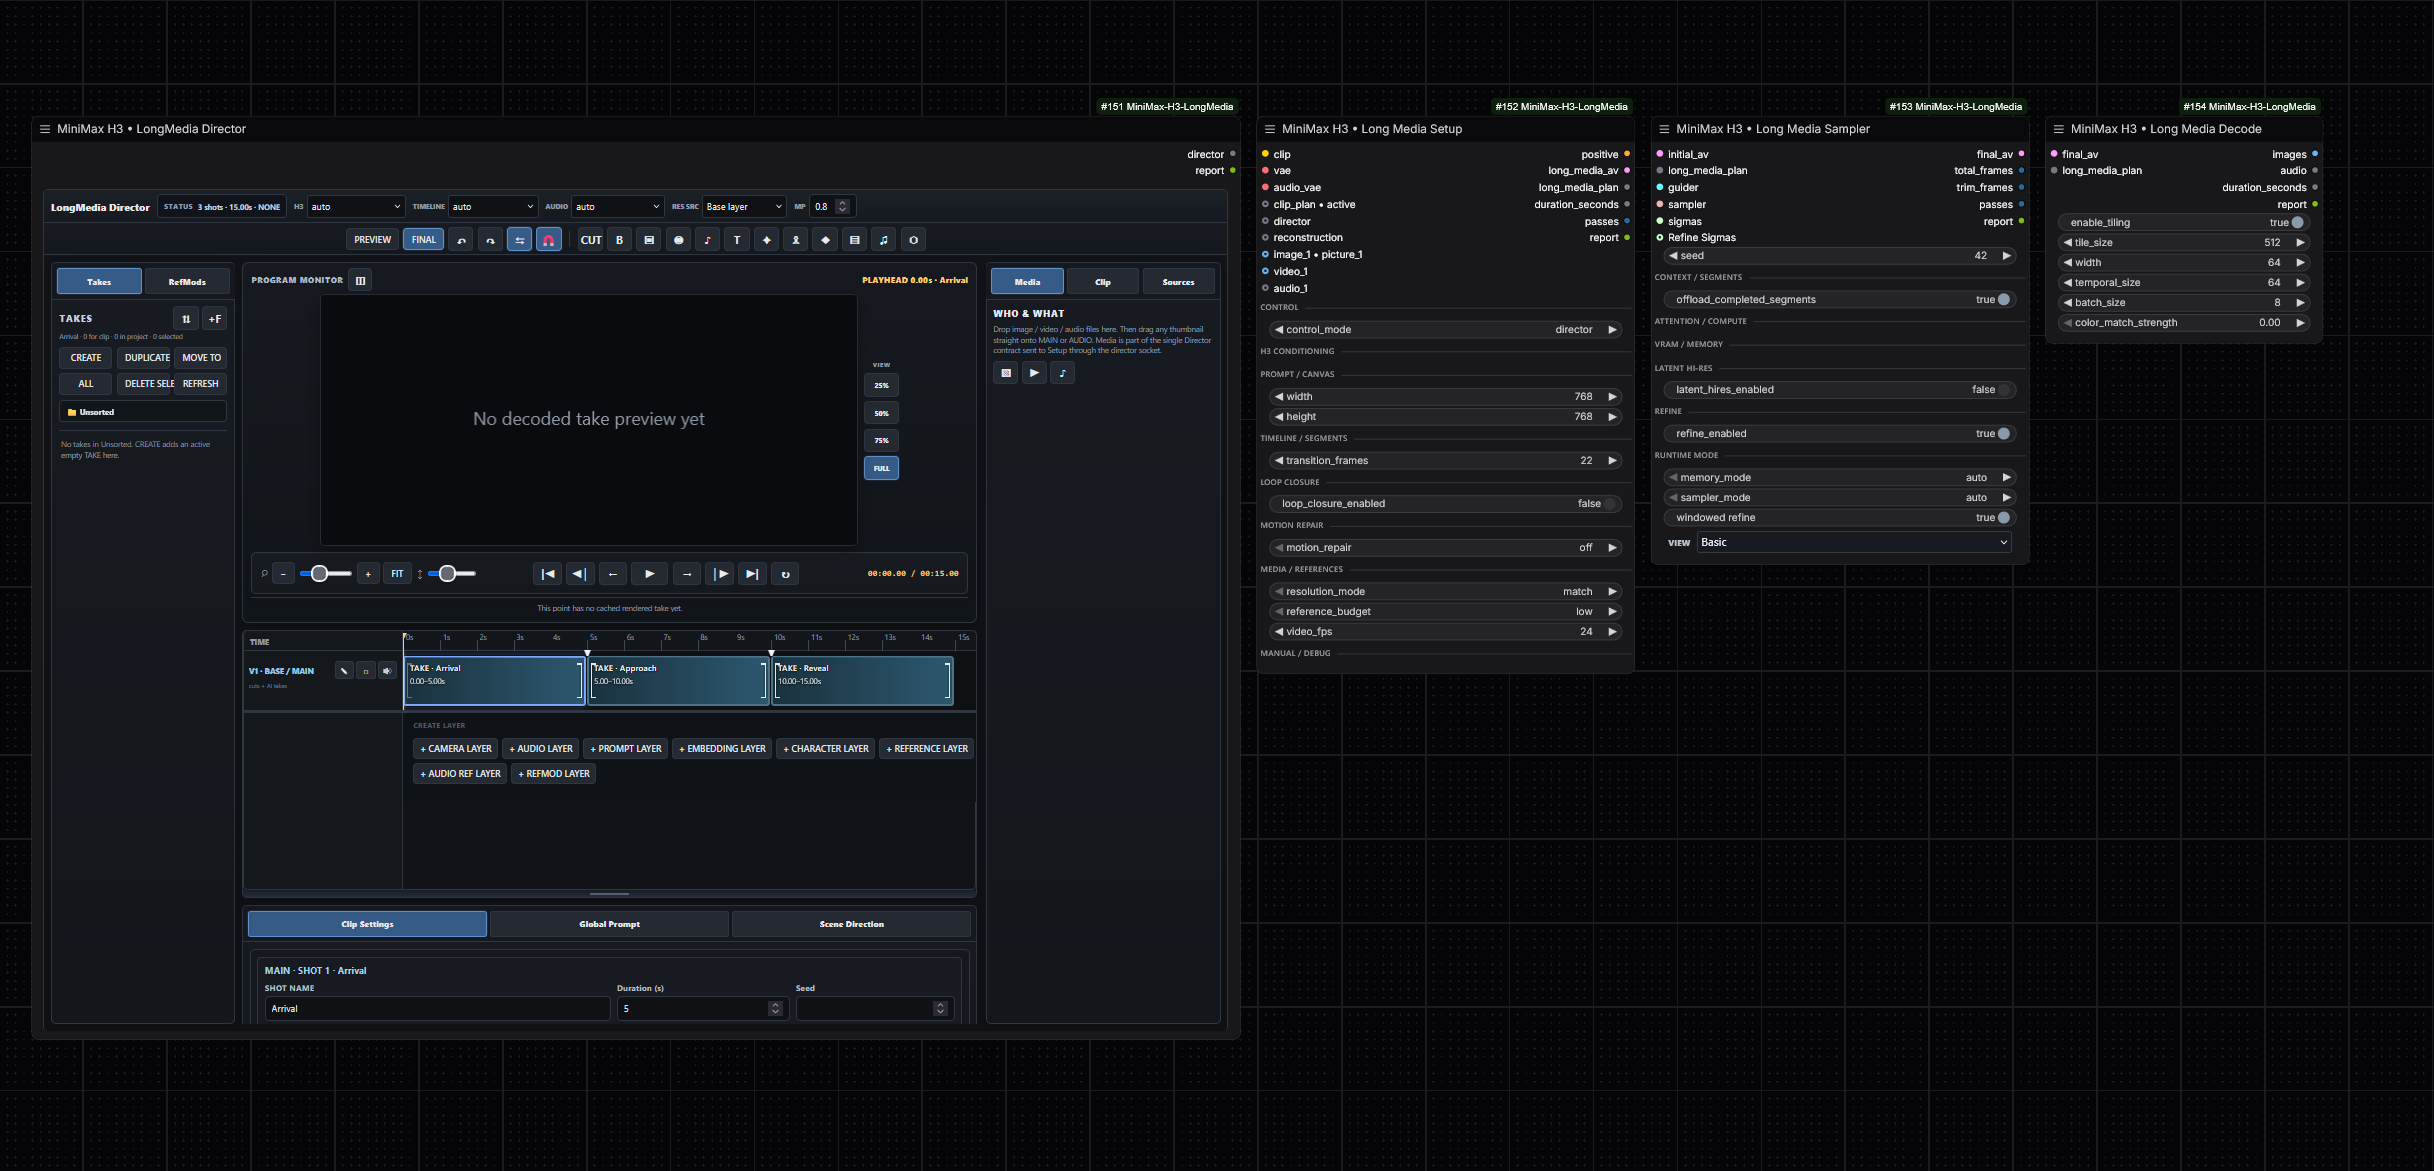
ComfyUI-MiniMax-H3-LongMedia
297vizart-vj/ComfyUI-MiniMax-H3-LongMedia · PythonA set of production-oriented custom nodes for ComfyUI that run MiniMax H3 for long-form video and audio generation: reference editing, MultiClip planning, camera direction, fixed segmentation, lip-sync and redubbing, latent hi-res refinement, and low-VRAM-safe execution.
- 50

infinite-livestream
240reactor-team/infinite-livestream · PythonAn end-to-end, chat-driven, never-ending AI video broadcast: viewers type !prompt in Twitch or YouTube chat, an LLM expands the idea into a styled scene, the FastH3 model renders it as a 768p clip with synced audio, and it goes out continuously over RTMP.
- 51
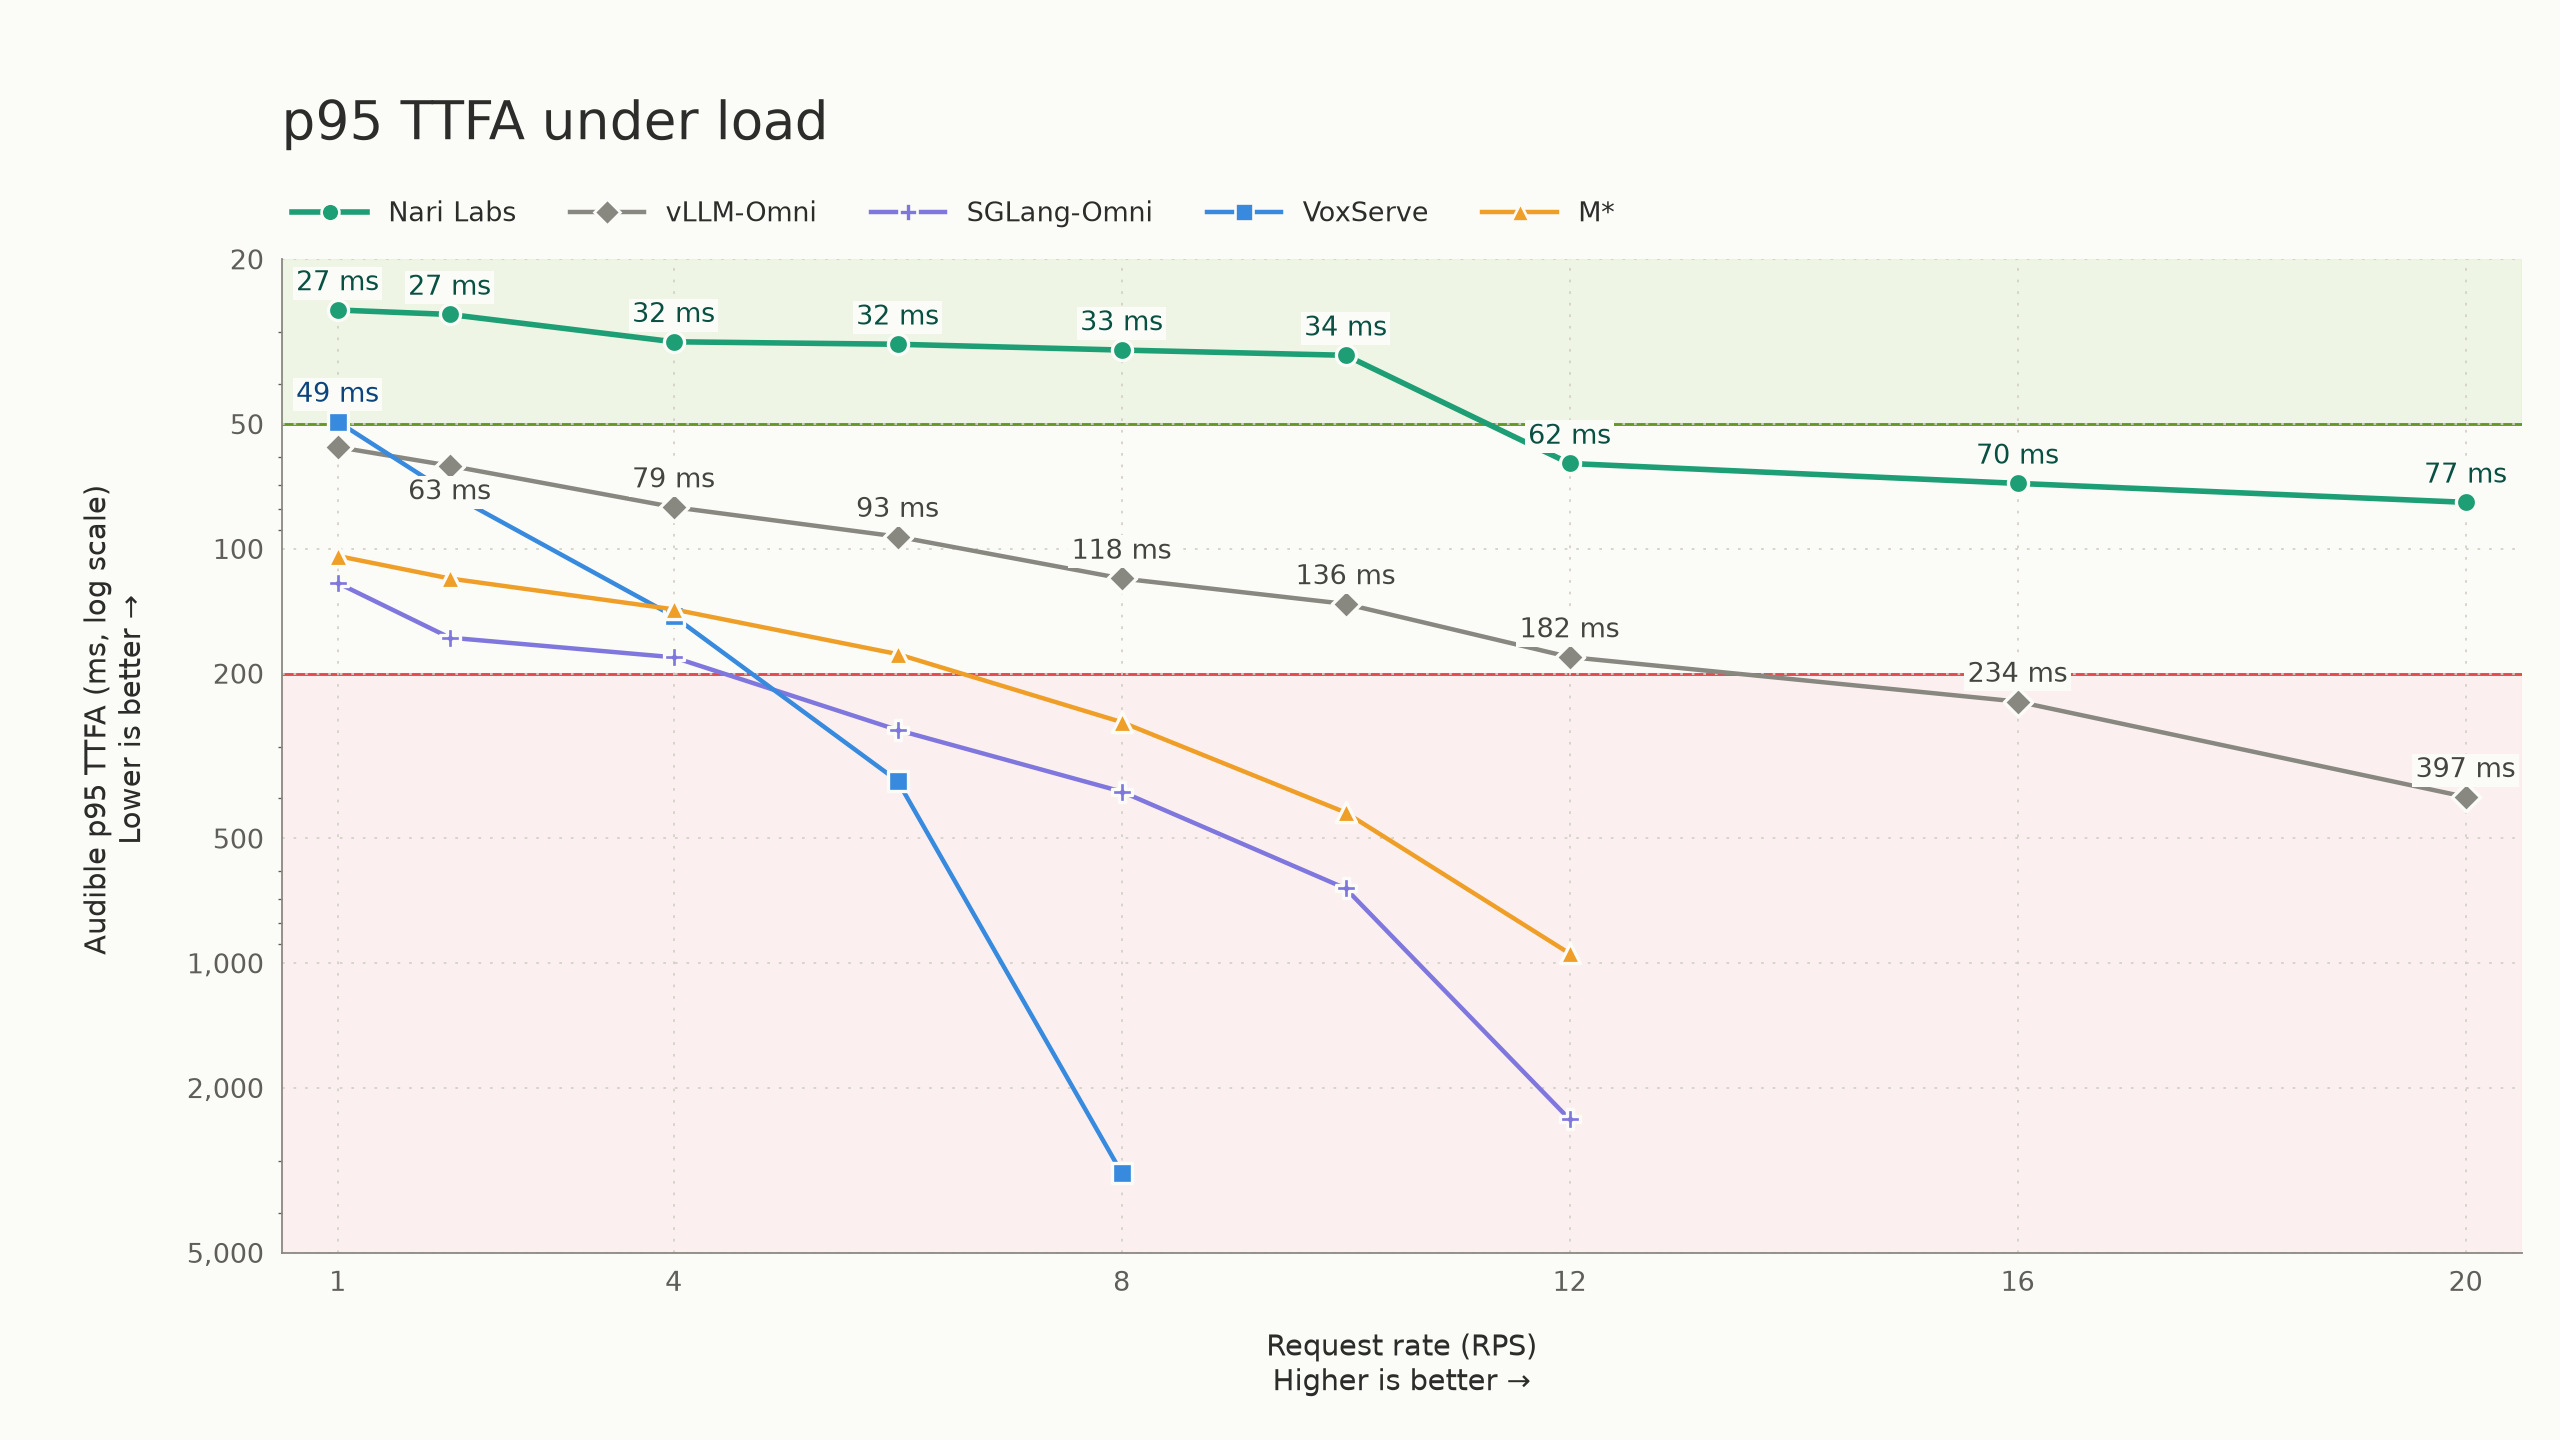
nari-qwen3-tts
187nari-labs/nari-qwen3-tts · PythonNari Qwen3-TTS is a high-performance serving implementation of the Qwen3-TTS 1.7B CustomVoice model, built to run on a single NVIDIA H100 and exposed as an API with streaming and non-streaming speech generation.
- 52

hyperflow
146Video-Rebirth/hyperflow · PythonAn 8-step LoRA adapter for MiniMax-H3, a video+audio generation model, trained by data-free flow self-distillation. This repository holds the loader and example scripts that run it on the diffusers Modular Pipeline.
Related topics
Often tagged together