Topics / #long-context
Long-context projects on GitHub
Handling very long inputs and documents in language models.
As of , the most-starred Long-context projects on GitHub are Qwen (21.9K stars), DeepResearch (20.1K stars) and llama-cookbook (18.6K stars). GitHub.Locker tracks 16 Long-context repositories with 124.7K stars combined. The fastest-growing on October 16 was billion-context, with +144 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +144
billion-context
ranxianglei/billion-context · ★ 1.5Kbillion-context is a context-compression proxy that sits between any coding agent and its model API, rewriting Anthropic/OpenAI streams so a 100K context window is enough and a single session can run for months across billions of tokens.
 +27
fast-jev-compaction
tamaratran/fast-jev-compaction · ★ 7.7KA Claude Code plugin, also usable as an npm library, that replaces context compaction's summary with Jev decisions: every tool call and result is scored in fast requests, stale ones are dropped or truncated, and everything kept stays verbatim.
 +13
MiniCPM
OpenBMB/MiniCPM · ★ 11.6KMiniCPM is OpenBMB's family of small, open-source LLMs built for on-device and resource-constrained use. The newest release, MiniCPM5-2B, is a dense 2B-parameter model that reaches open-source state-of-the-art for its size class while staying competitive with much larger 4B-class models.
 +12
kaggle-tpu-lab
ARahim3/kaggle-tpu-lab · ★ 657A recipe that serves frontier-class open LLMs — GLM-5.3-Flash 320B MoE and Qwen3.8-27B bf16 — on Kaggle's free TPU v5e-8, exposing a public OpenAI-compatible (and Anthropic-compatible) endpoint you can plug into coding agents like Claude Code, Codex, opencode, or pi.
The all-time top
16 projects · by stars
- 21.9K
 #1 · QwenLM/Qwen
Qwen
The official repo of Qwen (通义千问, Tongyi Qianwen) — Alibaba Cloud's family of chat and pretrained large language models, released in sizes from 1.8B up to 72B parameters on Hugging Face and ModelScope.
- 20.1K
 #2 · Alibaba-NLP/DeepResearch
DeepResearch
Tongyi DeepResearch — an open-source agentic LLM from Alibaba's Tongyi Lab, built for long-horizon, deep information-seeking on the web. This repo ships the model weights plus Python inference and benchmark evaluation scripts.
- 18.6K
 #3 · meta-llama/llama-cookbook
llama-cookbook
The Llama Cookbook — Meta's official collection of recipes for building with the Llama model family: inference, fine-tuning, RAG and end-to-end use cases, mostly written as Jupyter notebooks.
- 4
Qwen3-Coder
16.8KQwenLM/Qwen3-Coder · PythonQwen3-Coder is the code-focused branch of the Qwen3 large language model family from the Qwen team — open-weight models built for coding and agentic tasks, available in several sizes.
- 5
MiniCPM
11.6KOpenBMB/MiniCPM · Jupyter NotebookMiniCPM is OpenBMB's family of small, open-source LLMs built for on-device and resource-constrained use. The newest release, MiniCPM5-2B, is a dense 2B-parameter model that reaches open-source state-of-the-art for its size class while staying competitive with much larger 4B-class models.
- 6
fast-jev-compaction
7.7Ktamaratran/fast-jev-compaction · TypeScriptA Claude Code plugin, also usable as an npm library, that replaces context compaction's summary with Jev decisions: every tool call and result is scored in fast requests, stale ones are dropped or truncated, and everything kept stays verbatim.
- 7

GLM-5
7.3Kzai-org/GLM-5GLM-5 is a family of large open-weight language models from Z.ai built for agentic engineering and complex, long-horizon coding tasks, scaling up to 744B parameters with sparse attention for efficient long-context serving.
- 8

turboquant_plus
7KTheTom/turboquant_plus · PythonTurboQuant+ is the research home for TurboQuant (ICLR 2026), a KV cache compression method for transformer LLMs. It shrinks the KV cache 3.8-6.4x using PolarQuant plus Walsh-Hadamard rotation, and this repo holds the Python reference implementation, validation papers and benchmark data.
- 9
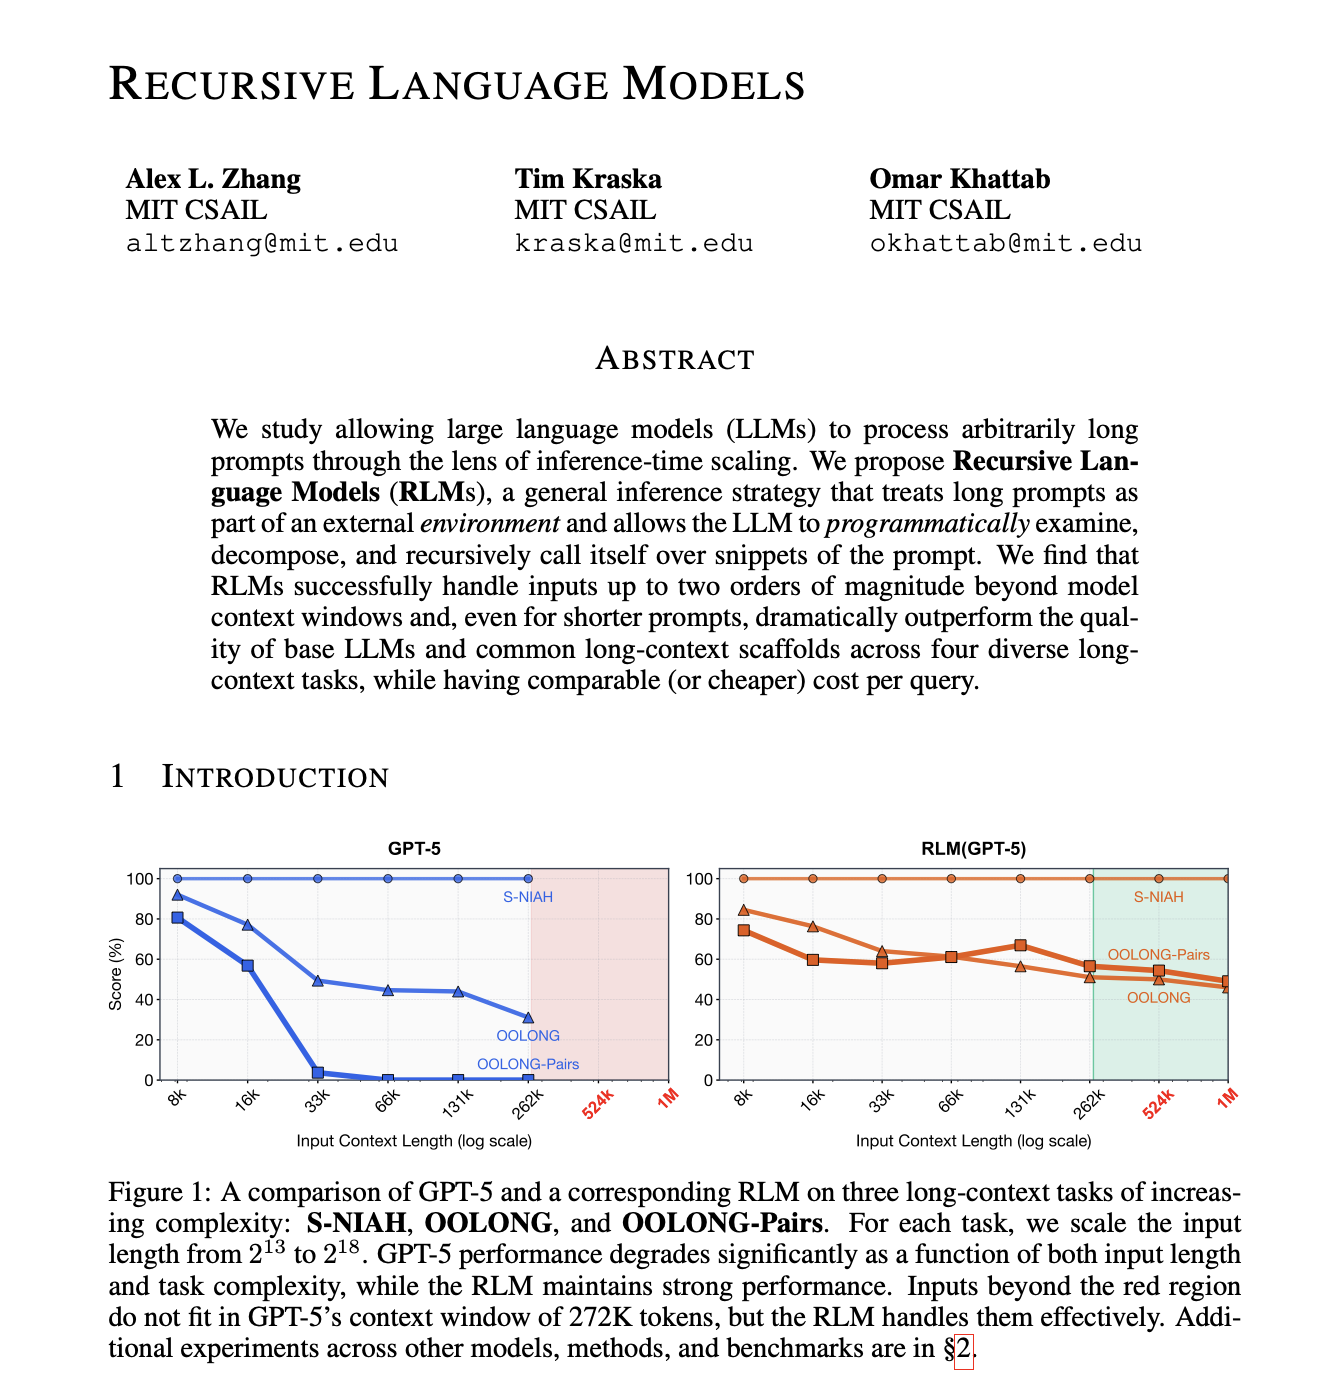
rlm
5.7Kalexzhang13/rlm · PythonRLM is an inference library implementing Recursive Language Models, a paradigm where an LLM offloads its context into a REPL environment and recursively calls itself (or sub-LLMs) to examine, decompose, and reason over near-infinite-length inputs.
- 10
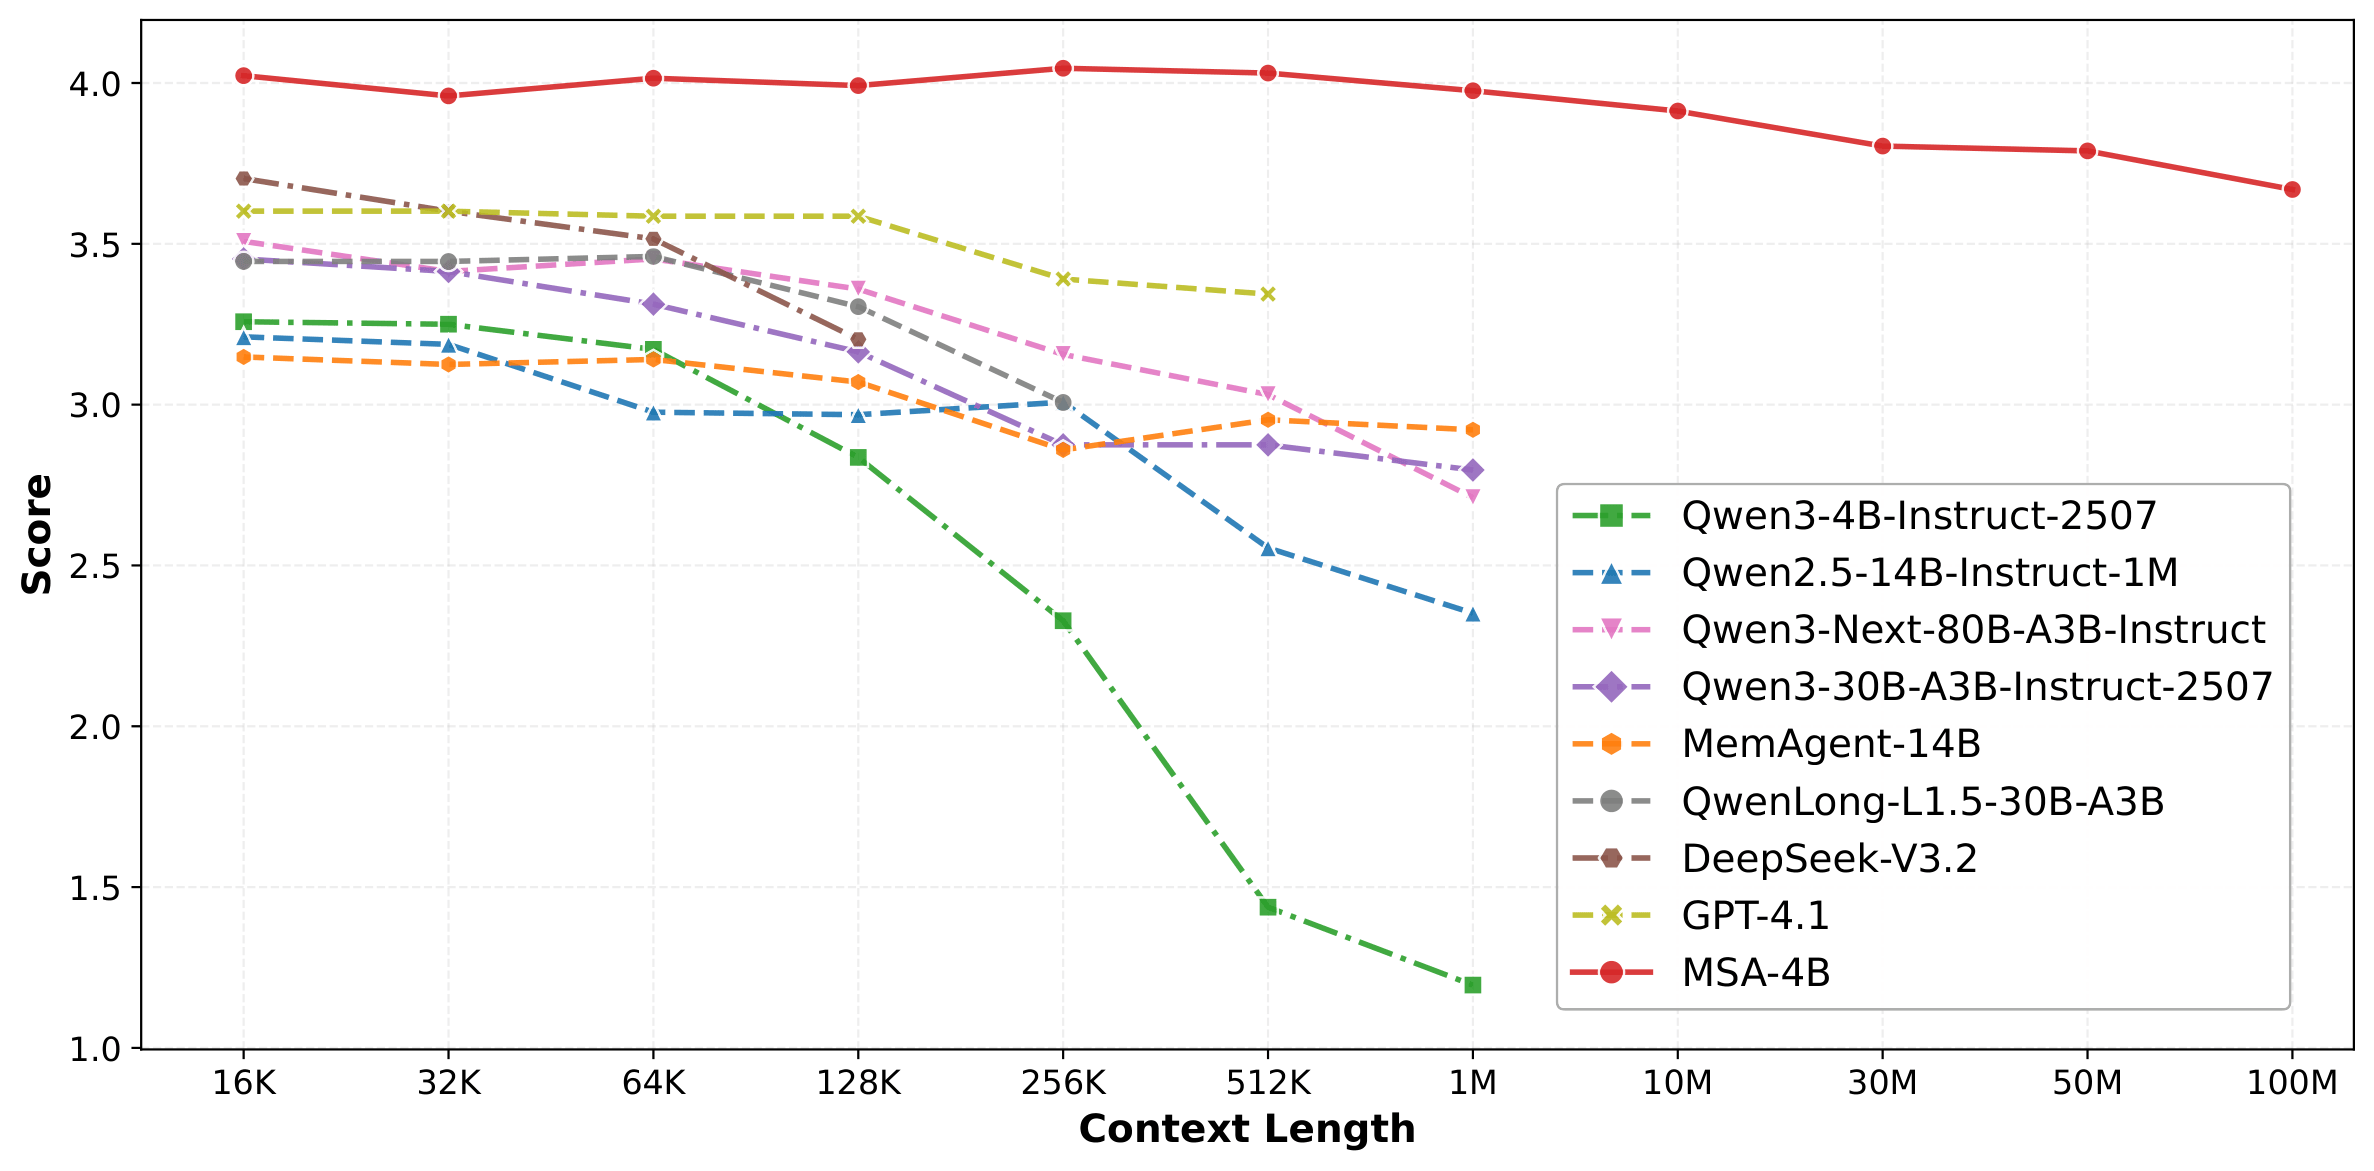
MSA
3.5KEverMind-AI/MSA · PythonMSA (Memory Sparse Attention) is an end-to-end trainable, scalable latent-memory framework that lets LLMs handle context windows up to 100M tokens, replacing RAG or fixed-size RNN-style memory with a differentiable sparse-attention memory bank.
- 11
billion-context
1.5Kranxianglei/billion-context · TypeScriptbillion-context is a context-compression proxy that sits between any coding agent and its model API, rewriting Anthropic/OpenAI streams so a 100K context window is enough and a single session can run for months across billions of tokens.
- 12
halogen-flash-server
1Kpeonist-ai/halogen-flash-server · Shellhalogen-flash-server is a purpose-built inference server for running the Qwen3.8-Flash-Next model as fast as possible on AMD's Strix Halo (gfx1151) GPU, exposing an OpenAI-compatible API.
- 13
kaggle-tpu-lab
657ARahim3/kaggle-tpu-lab · PythonA recipe that serves frontier-class open LLMs — GLM-5.3-Flash 320B MoE and Qwen3.8-27B bf16 — on Kaggle's free TPU v5e-8, exposing a public OpenAI-compatible (and Anthropic-compatible) endpoint you can plug into coding agents like Claude Code, Codex, opencode, or pi.
- 14

GLiClass
563Knowledgator/GLiClass · PythonGLiClass is an efficient zero-shot model for sequence classification, inspired by GLiNER: give it a text and a list of candidate labels, and it classifies the text with accuracy comparable to cross-encoders.
- 15
Hy4-preview
395Tencent-Hunyuan/Hy4-preview · PythonHy4 preview is Tencent Hunyuan's newest open-source large language model, a 770B-parameter Mixture-of-Experts model (49B active per token) built for coding, office/data analysis, game development, and scientific research tasks.
- 16
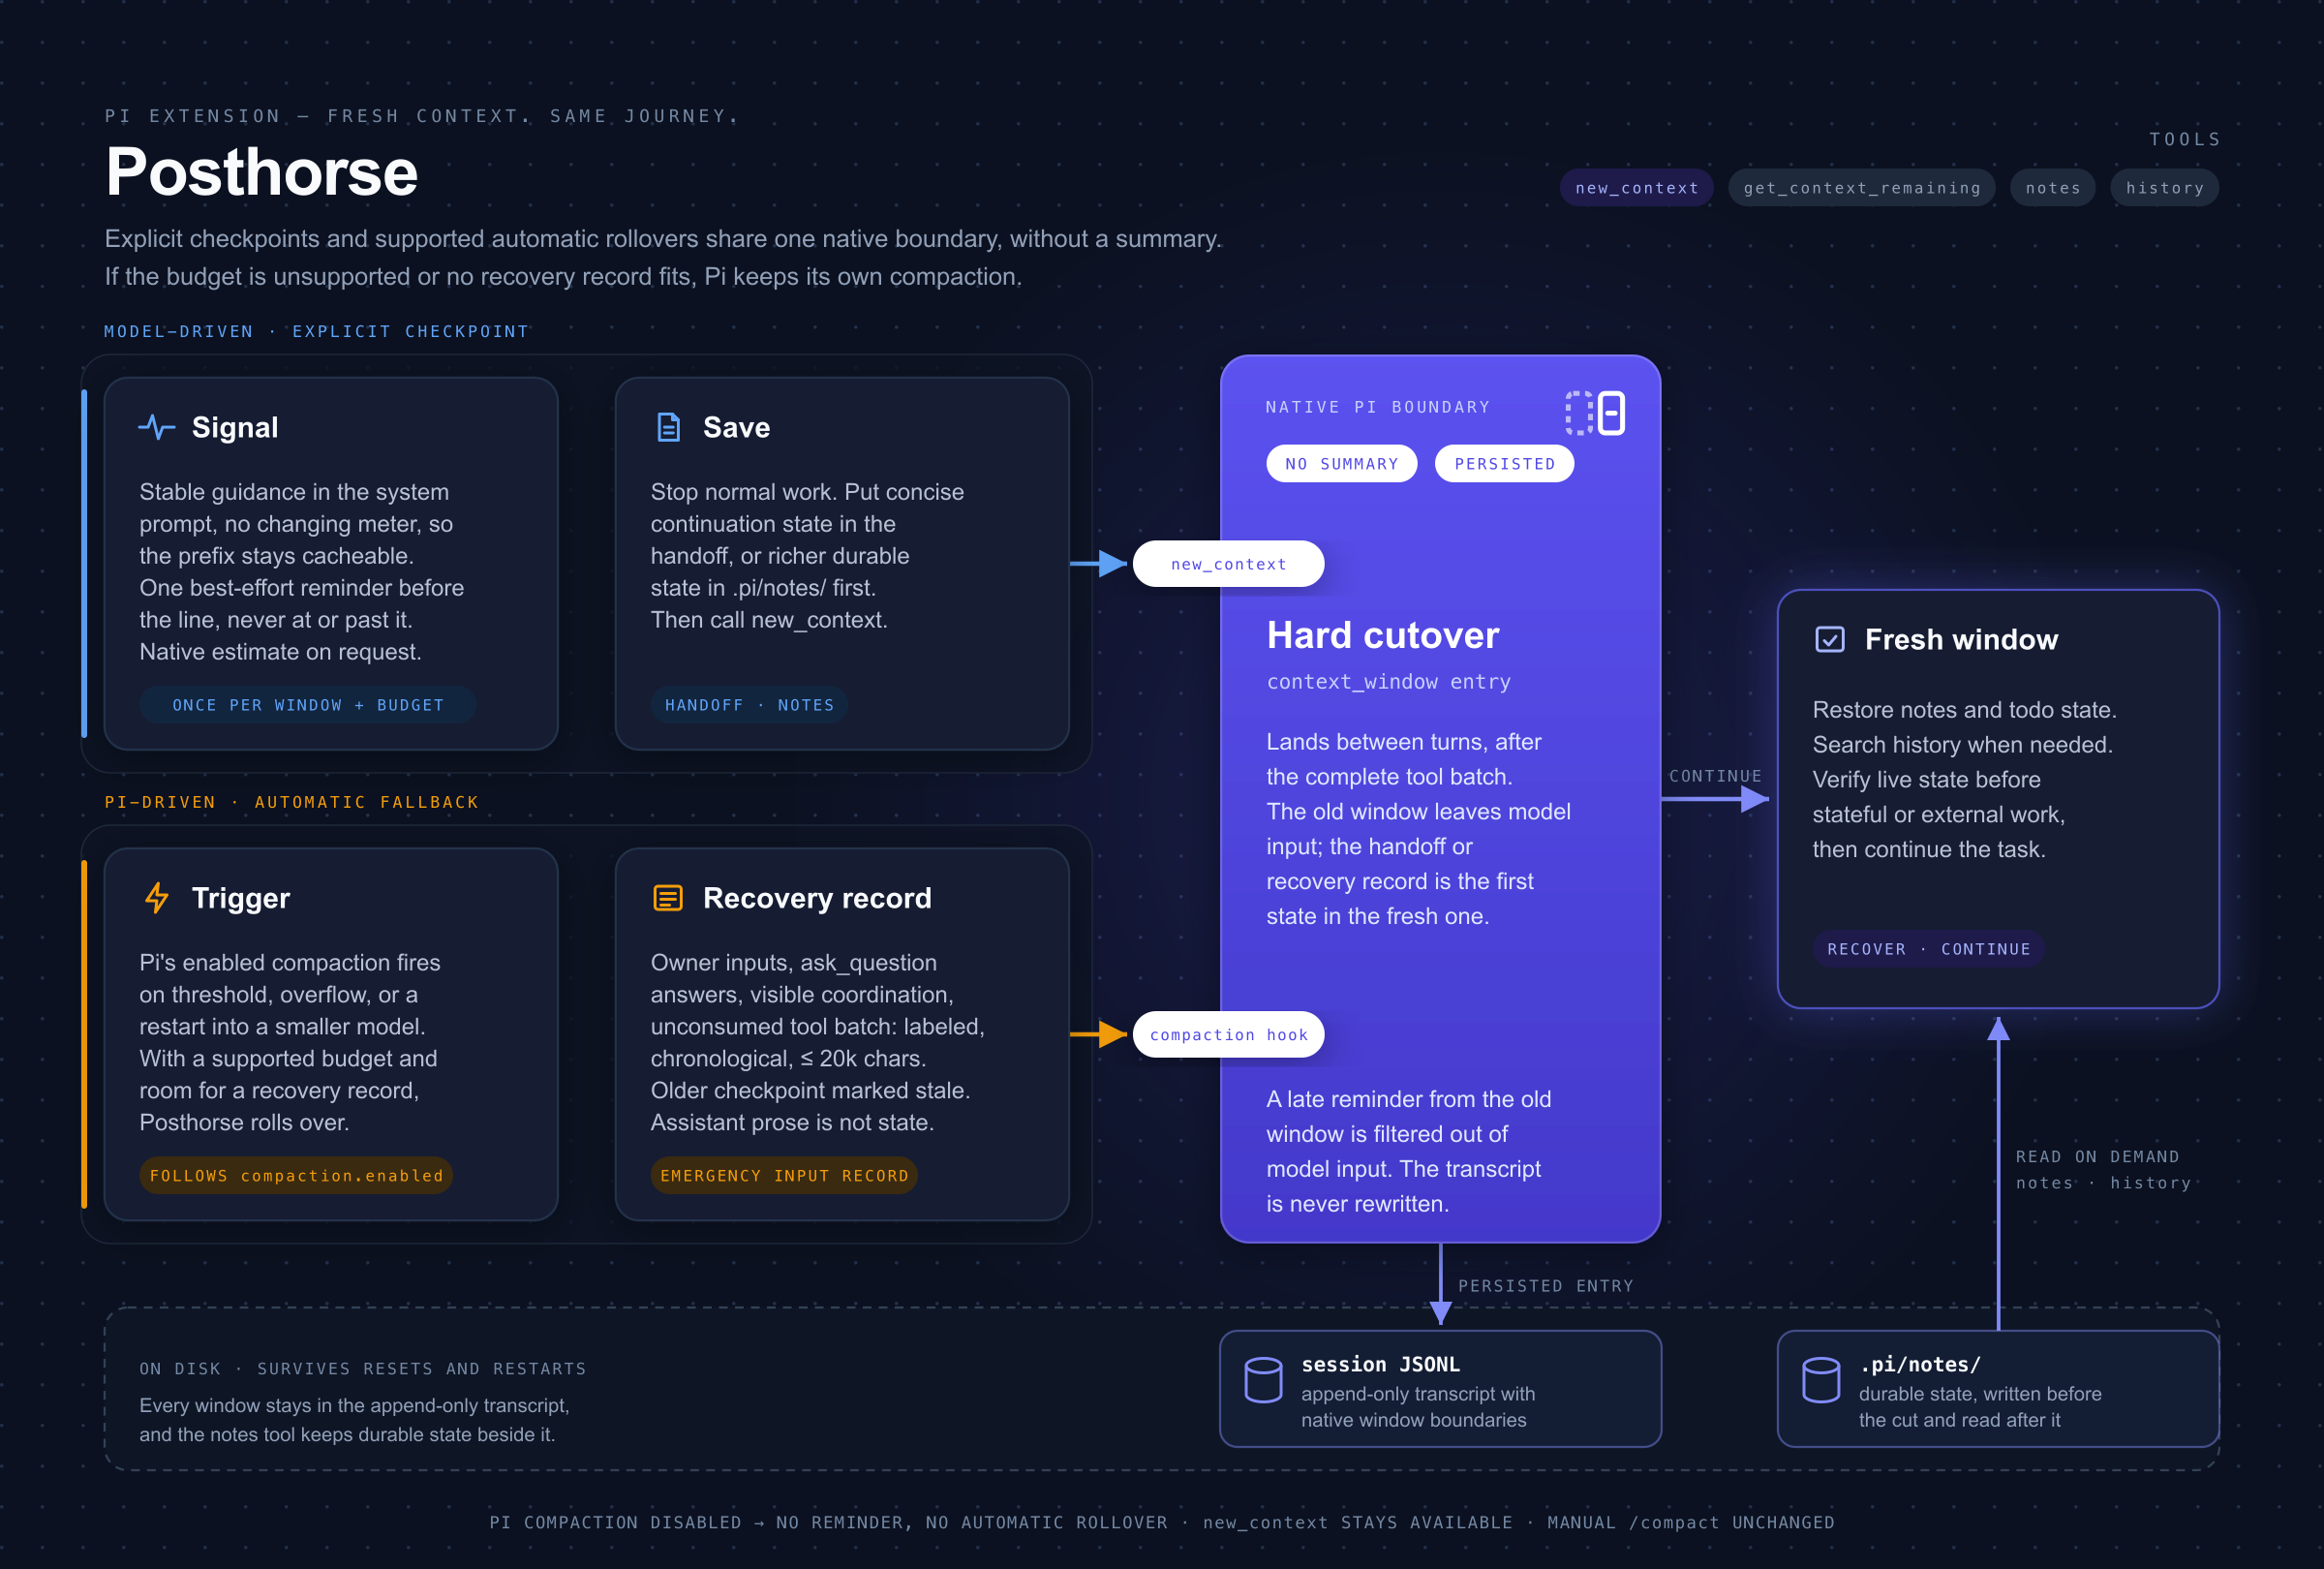
pi-posthorse
272fitchmultz/pi-posthorse · TypeScriptPosthorse is an extension for the Pi coding agent (specifically the fitchmultz/pi fork) that handles context window rollovers without summarization: when a session nears its limit it starts a fresh window with a durable handoff and a fully recoverable transcript instead of compressing the history into a summary.
Related topics
Often tagged together