Topics / #dgx-spark
Dgx-spark projects on GitHub
Projects for running local AI models on NVIDIA DGX Spark compact systems.
As of , the most-starred Dgx-spark projects on GitHub are ds4 (24K stars), carrel (312 stars) and dgx-spark-qwen38 (231 stars). GitHub.Locker tracks 5 Dgx-spark repositories with 24.8K stars combined. The fastest-growing on October 19 was ds4, with +31 stars in a day.
Hot right now
Most stars gained in a day · Oct 19
 +31
ds4
antirez/ds4 · ★ 24KDwarfStar (ds4) is a small, self-contained local inference engine specialized for running DeepSeek V4 Flash and PRO, plus GLM 5.2/5.3, on consumer hardware like high-memory Macs, NVIDIA GPUs, and AMD Strix Halo systems.
 +1
dgx-spark-qwen38
hasso5703/dgx-spark-qwen38 · ★ 231A one-command installer that sets up a hardened, boot-persistent SGLang serving stack for the Qwen3.8 model family on a single NVIDIA DGX Spark (GB10), reaching 50 tok/s greedy median and up to 1M context on the 27B NVFP4 config, with a 176B Flash-Next MoE model also fitting on one box.
The all-time top
5 projects · by stars
- 24K#1 · antirez/ds4
ds4
DwarfStar (ds4) is a small, self-contained local inference engine specialized for running DeepSeek V4 Flash and PRO, plus GLM 5.2/5.3, on consumer hardware like high-memory Macs, NVIDIA GPUs, and AMD Strix Halo systems.
- 312
 #2 · FengZhenfei/carrel
carrel
Carrel is a self-hosted knowledge base for AI agents. It automates document parsing, indexing, and retrieval, with optional knowledge graphs, so an agent can pull source passages, images, and facts from your documents and answer from them.
- 231#3 · hasso5703/dgx-spark-qwen38
dgx-spark-qwen38
A one-command installer that sets up a hardened, boot-persistent SGLang serving stack for the Qwen3.8 model family on a single NVIDIA DGX Spark (GB10), reaching 50 tok/s greedy median and up to 1M context on the 27B NVFP4 config, with a 176B Flash-Next MoE model also fitting on one box.
- 4

twinspark
176raullenchai/twinspark · ShellThis is a production-grade deployment recipe for running DeepSeek-V4-Flash-0731 (a 284B-parameter MoE model) across two networked NVIDIA DGX Spark machines, using a self-healing 2-node vLLM cluster tuned for speculative decoding.
- 5
pd-bridge
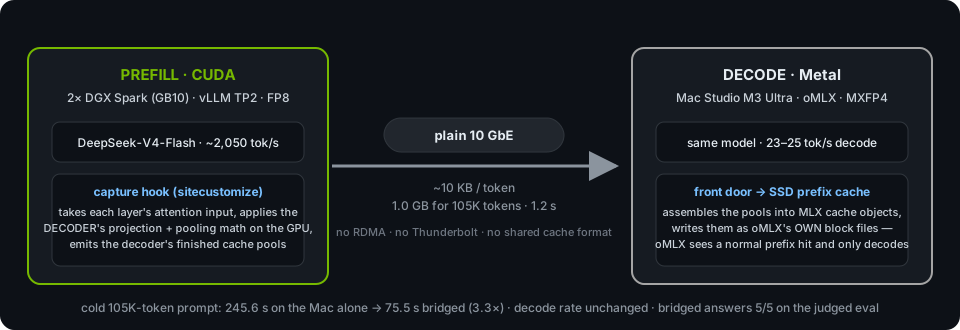
151chadhurley25075-png/pd-bridge · Pythonpd-bridge serves one DeepSeek-V4-Flash request across two machines: prefill runs on NVIDIA DGX Sparks (CUDA/vLLM), decode on a Mac Studio (Metal/oMLX), linked by ordinary 10GbE Ethernet.
Related topics
Often tagged together
- gpu816
- nvidia341
- cuda404
- linux4,264
- llm1,524
- llm-inference121
- mit3,399
- self-hosted1,984
- deepseek314
- docker1,684
- local-llm225
- python2,447
- quantization191
- server1,470
- speculative-decoding42
- vllm128
- ai2,001
- ai-agents1,331
- apple-silicon240
- benchmark447
- distributed-systems277
- gpu-acceleration156
- inference332
- inference-engine48