Topics / #nvfp4
Nvfp4 projects on GitHub
Four bit floating point quantization for GPU inference.
As of , the most-starred Nvfp4 projects on GitHub are ZDTaichu5.0-9B (3.1K stars), TypeLLM (960 stars) and GLM-5.3-Flash-EXL3-2x-DGX-Sparks (736 stars). GitHub.Locker tracks 6 Nvfp4 repositories with 5.4K stars combined. The fastest-growing on October 18 was GLM-5.3-Flash-EXL3-2x-DGX-Sparks, with +1 stars in a day.
Hot right now
Most stars gained in a day · Oct 18
 +1
GLM-5.3-Flash-EXL3-2x-DGX-Sparks
MiaAI-Lab/GLM-5.3-Flash-EXL3-2x-DGX-Sparks · ★ 736A deployment recipe and Docker image that serves the GLM-5.3-Flash model as an OpenAI-compatible vLLM endpoint across 2-4 NVIDIA DGX Spark (GB10) kits, using a custom EXL3/TR3 4-bit quantization of the weights.
 +1
dgx-spark-qwen38
hasso5703/dgx-spark-qwen38 · ★ 230A one-command installer that sets up a hardened, boot-persistent SGLang serving stack for the Qwen3.8 model family on a single NVIDIA DGX Spark (GB10), reaching 50 tok/s greedy median and up to 1M context on the 27B NVFP4 config, with a 176B Flash-Next MoE model also fitting on one box.
 +1
v100-skinny
dnv2003/v100-skinny · ★ 175v100-skinny provides hand-written NVFP4 (W4A16) and FP8 (W8A16) CUDA kernels that let four Tesla V100-SXM2-16GB GPUs run Qwen3.8-27B's published mixed NVFP4/FP8 weights directly, serving the model through an OpenAI-compatible API.
The all-time top
6 projects · by stars
- 3.1K
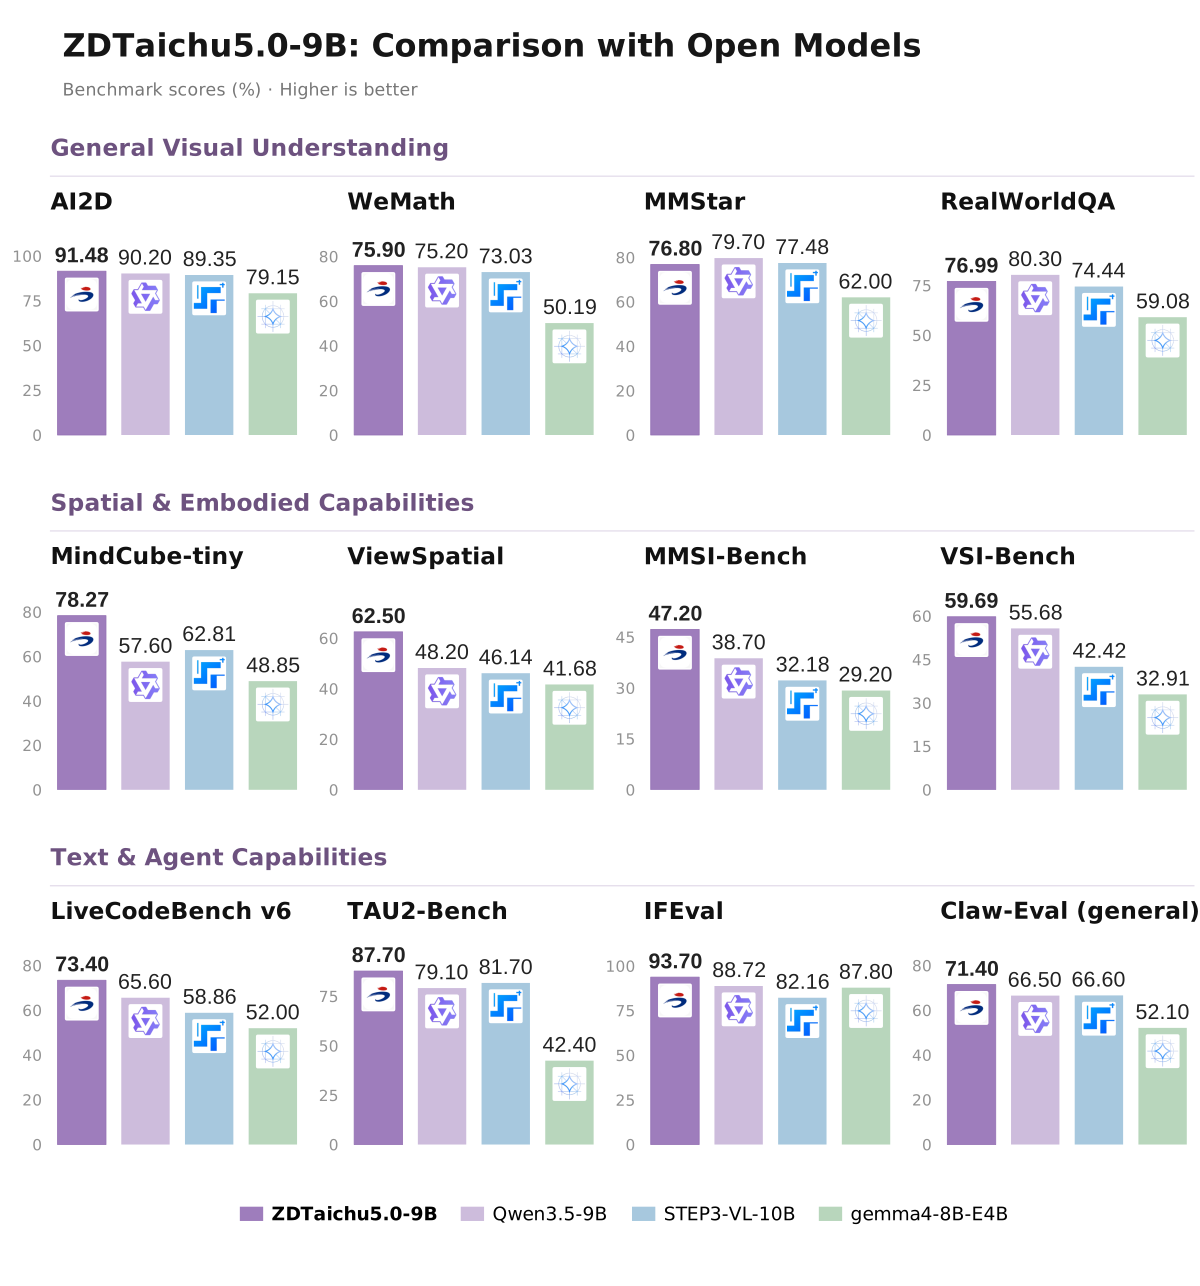 #1 · Taichu-AI/ZDTaichu5.0-9B
ZDTaichu5.0-9B
ZDTaichu5.0-9B is a multimodal foundation model that combines a Qwen3.5-9B language backbone with a C-RADIOv4-H vision encoder for general visual understanding, spatial reasoning, embodied-AI research and agentic tool use.
- 960
#2 · TypeLLM/TypeLLM
TypeLLM
TypeLLM adds type-safe, schema-guaranteed output generation to existing open autoregressive LLMs, without changing their weights or architecture, letting models still think freely while returning typed JSON Schema-constrained answers.
- 736#3 · MiaAI-Lab/GLM-5.3-Flash-EXL3-2x-DGX-Sparks
GLM-5.3-Flash-EXL3-2x-DGX-Sparks
A deployment recipe and Docker image that serves the GLM-5.3-Flash model as an OpenAI-compatible vLLM endpoint across 2-4 NVIDIA DGX Spark (GB10) kits, using a custom EXL3/TR3 4-bit quantization of the weights.
- 4
Qwen3.8-27B-DFlash2-EXL3-5.0bpw
232MiaAI-Lab/Qwen3.8-27B-DFlash2-EXL3-5.0bpw · PythonA deployment kit for serving Qwen3.8-27B (quantized to EXL3 3.5bpw) through an OpenAI-compatible server, using speculative decoding to speed up generation. It bundles the launcher, server, and config; the model weights live on Hugging Face and inference runs on the team's exllamav3 fork.
- 5
dgx-spark-qwen38
230hasso5703/dgx-spark-qwen38 · PythonA one-command installer that sets up a hardened, boot-persistent SGLang serving stack for the Qwen3.8 model family on a single NVIDIA DGX Spark (GB10), reaching 50 tok/s greedy median and up to 1M context on the 27B NVFP4 config, with a 176B Flash-Next MoE model also fitting on one box.
- 6
v100-skinny
175dnv2003/v100-skinny · Pythonv100-skinny provides hand-written NVFP4 (W4A16) and FP8 (W8A16) CUDA kernels that let four Tesla V100-SXM2-16GB GPUs run Qwen3.8-27B's published mixed NVFP4/FP8 weights directly, serving the model through an OpenAI-compatible API.
Related topics
Often tagged together
- benchmark444
- cuda401
- gpu809
- llm1,516
- llm-inference120
- nvidia339
- python2,425
- quantization190
- model-serving49
- openai-compatible219
- self-hosted1,978
- ai1,993
- inference331
- linux4,248
- local-llm224
- qwen156
- server1,469
- speculative-decoding41
- docker1,684
- inference-engine47
- large-language-models218
- machine-learning930
- vllm128
- apache-2.01,452