Topics / #benchmarking
Benchmarking projects on GitHub
Measuring and comparing performance through repeatable benchmarks.
As of , the most-starred Benchmarking projects on GitHub are gpt-engineer (55K stars), wrk (40.4K stars) and tinygrad (33.8K stars). GitHub.Locker tracks 28 Benchmarking repositories with 315.2K stars combined. The fastest-growing on October 17 was StartLux-Decision, with +86 stars in a day.
Hot right now
Most stars gained in a day · Oct 17
 +86
StartLux-Decision
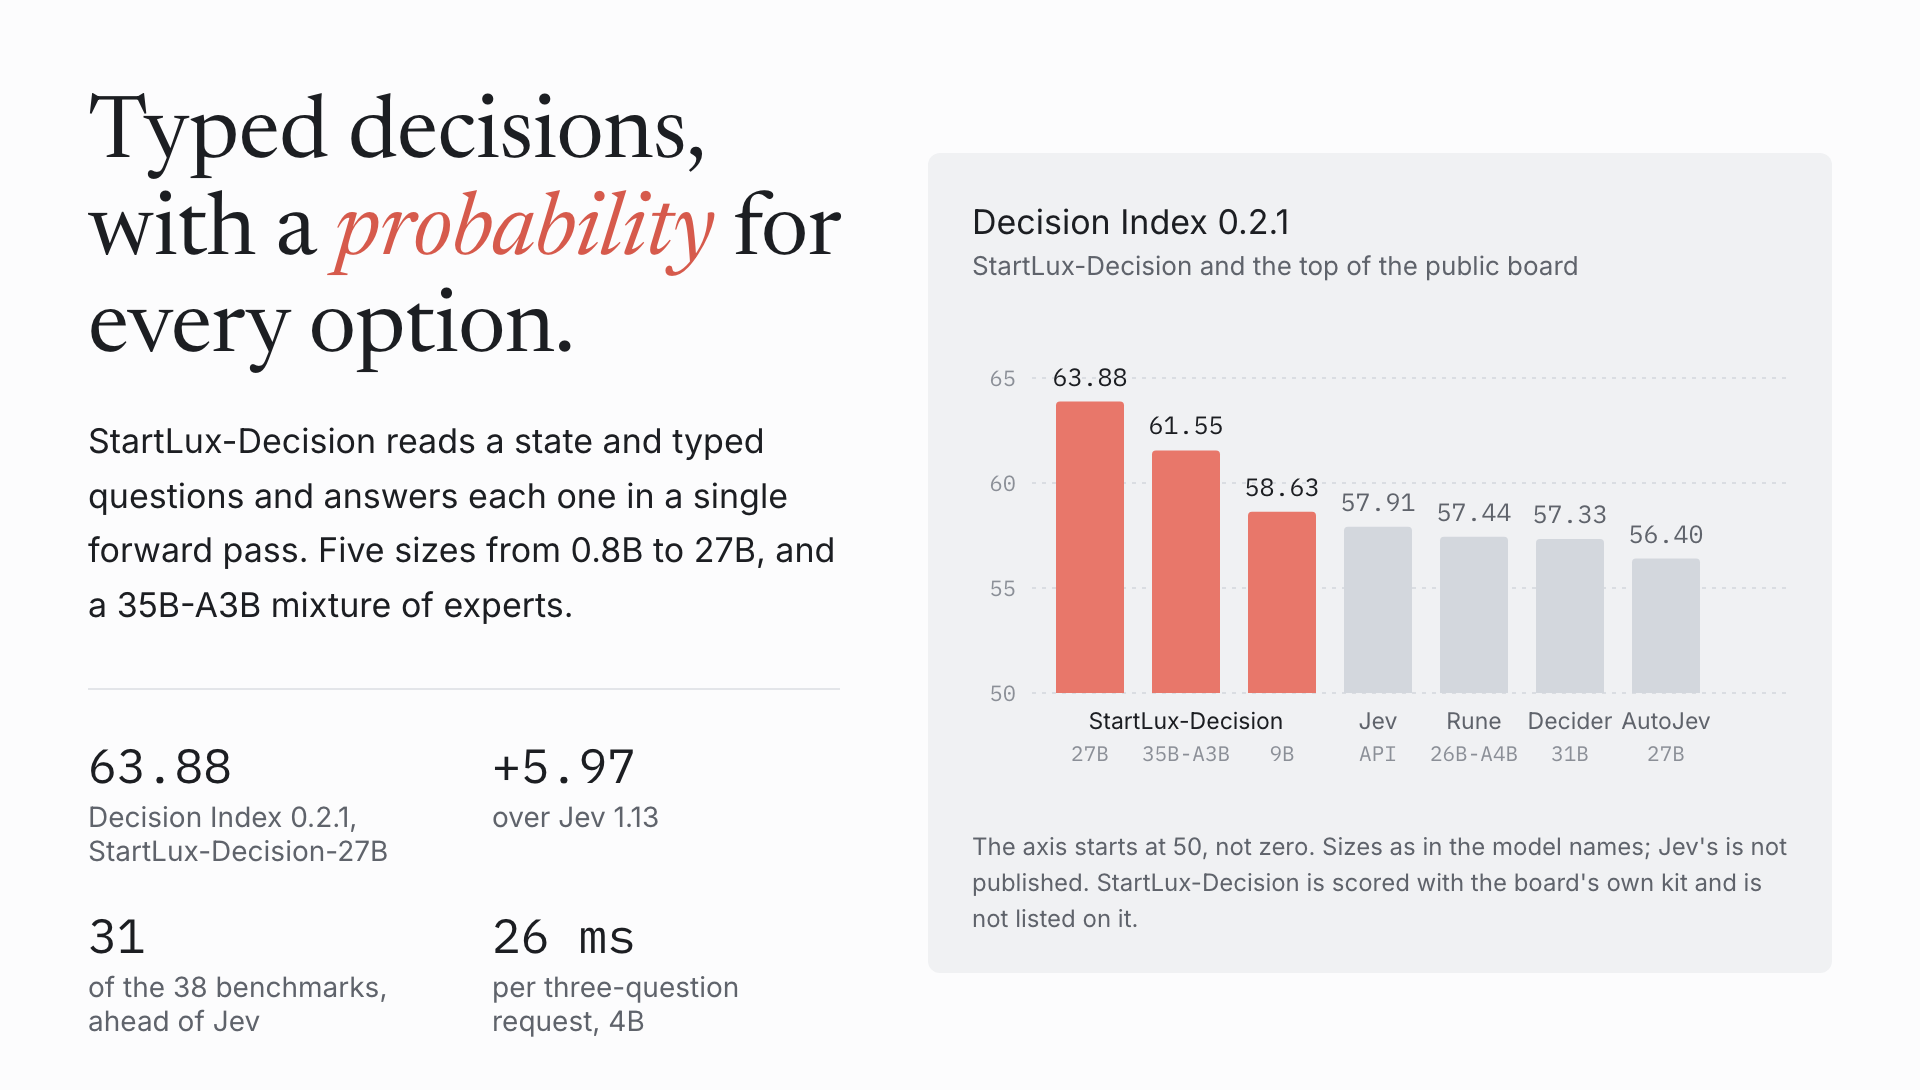
StartLuxLabs/StartLux-Decision · ★ 648StartLux-Decision is a family of typed decision models (five dense sizes from 0.8B to 27B plus a 35B-A3B mixture-of-experts) that answer a question with a probability for each option instead of generating text.
 +33
tubatools
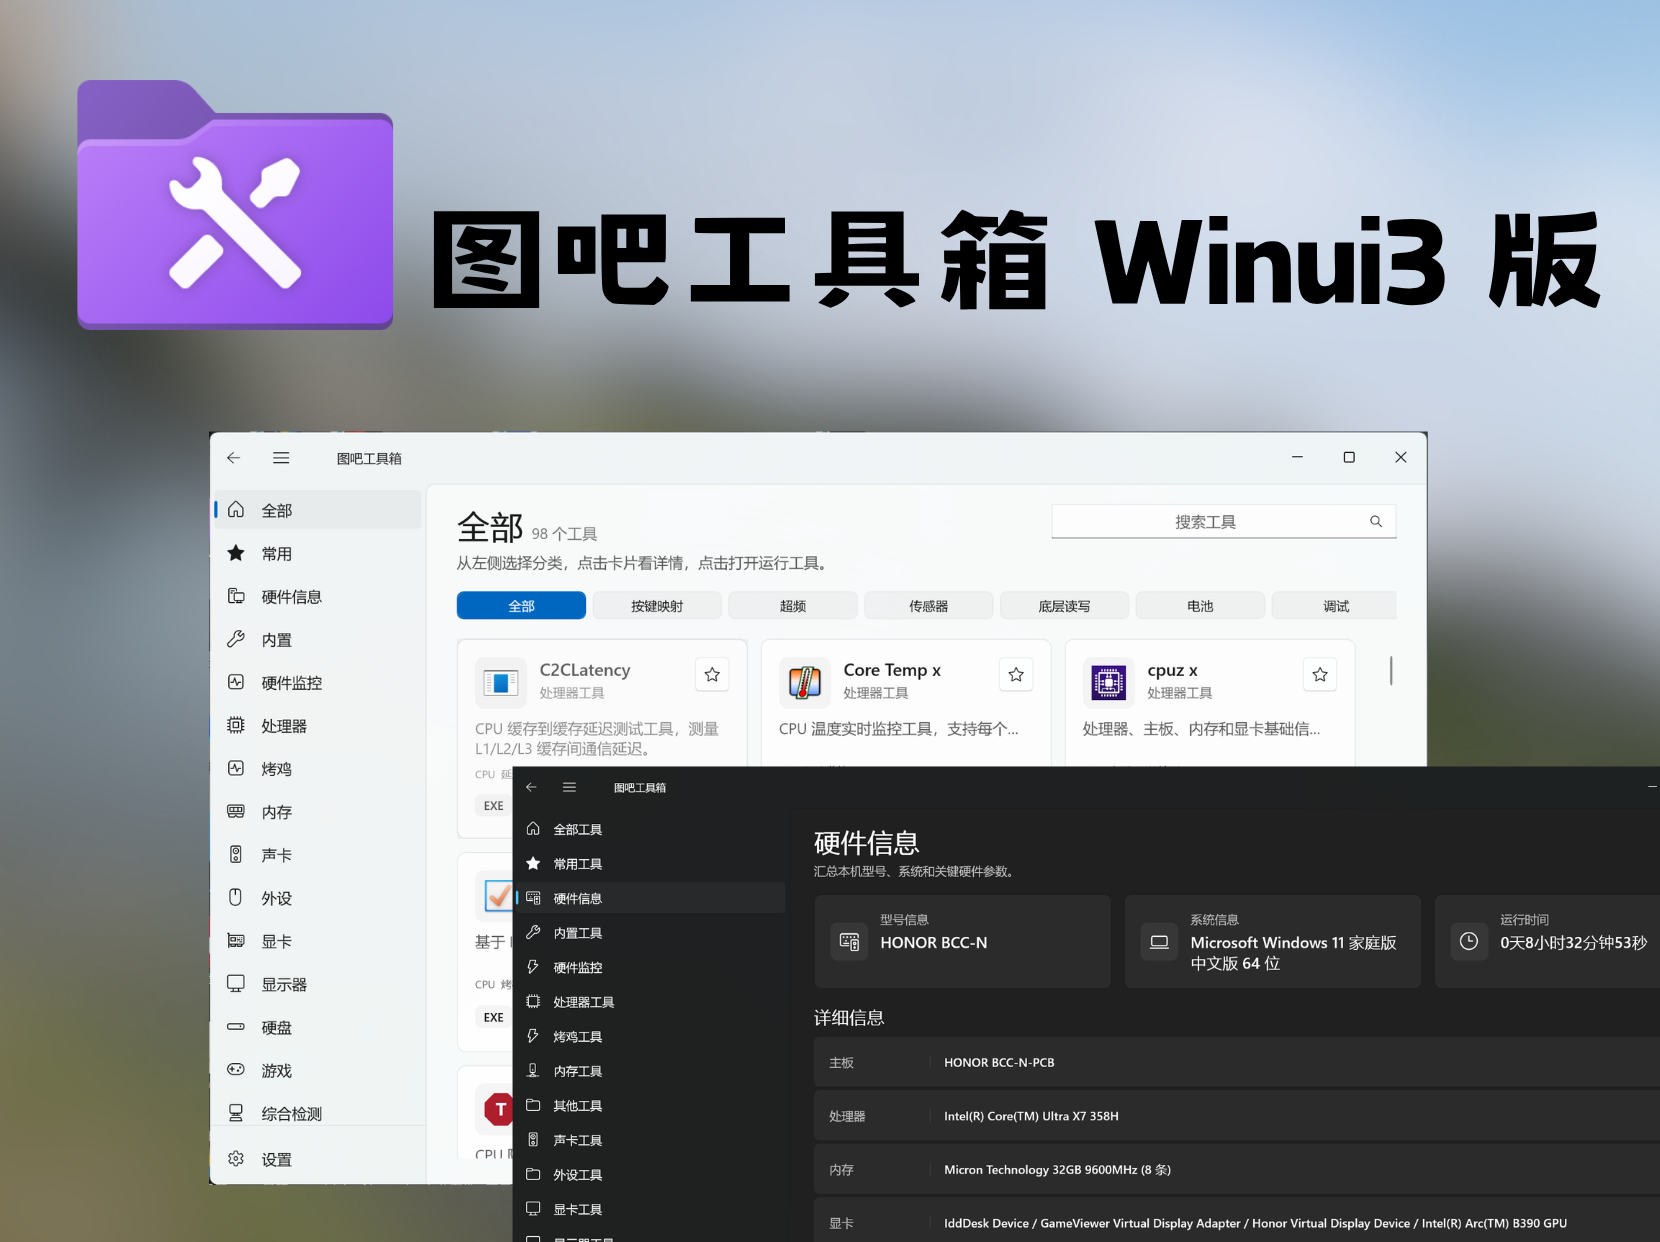
luolangaga/tubatools · ★ 5.5KTubaTools (图吧工具箱CE) is a community-driven, open-source Windows toolbox rebuilt from scratch on WinUI 3 and .NET 10, bundling 45 built-in utilities plus one-click launchers for 82 third-party tools for hardware diagnostics, cleaning, benchmarking and more.
 +16
BibaYanji
Bibapcs/BibaYanji · ★ 957BibaYanji (笔吧验机) is a Windows desktop tool for checking a new or secondhand PC against its order spec: it auto-collects CPU, GPU, RAM, disk, network card, screen and battery info so you can verify them item by item and mark the machine as passed, plus it bundles keyboard, dead-pixel, camera/mic/speaker, stress-test and disk-benchmark checks.
 +13
systeminformer
winsiderss/systeminformer · ★ 16.3KSystem Informer is a free, powerful multi-purpose tool for Windows that helps you monitor system resources, debug software and detect malware.
The all-time top
28 projects · by stars
- 55K
#1 · AntonOsika/gpt-engineer
gpt-engineer
gpt-engineer is a CLI tool where you describe the software you want in a plain-text 'prompt' file, and an AI (OpenAI, Azure OpenAI, or Anthropic models) writes and executes the code for you; you can also ask it to implement improvements to existing code.
- 40.4K
 #2 · wg/wrk
wrk
wrk is a modern HTTP benchmarking tool that generates significant load against a server using a single multi-core machine, measuring latency and throughput.
- 33.8K
 #3 · tinygrad/tinygrad
tinygrad
tinygrad is an end-to-end deep learning stack: a tensor library with autograd, an IR and compiler that fuse and lower kernels, JIT execution, plus nn, optim and datasets for real training.
- 4

locust
28.2Klocustio/locust · PythonLocust is an open source performance/load testing tool for HTTP and other protocols — you define your tests in regular Python code and run them from the command line or a web-based UI.
- 5

vegeta
25.2Ktsenart/vegeta · GoVegeta is a versatile HTTP load testing tool that drills HTTP services with a constant request rate — its tagline: It's over 9000! It works as both a CLI and a Go library and avoids Coordinated Omission.
- 6
nowinandroid
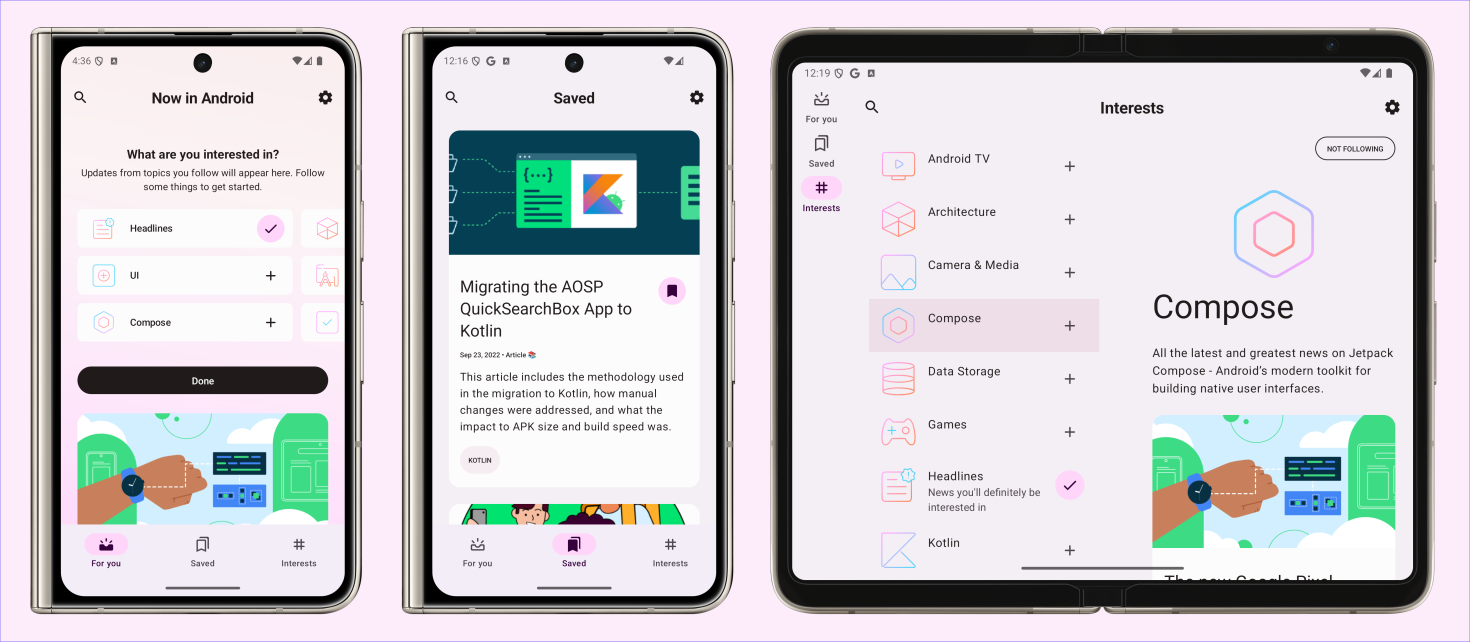
21.9Kandroid/nowinandroid · KotlinNow in Android is a fully functional Android app built entirely with Kotlin and Jetpack Compose. It doubles as an official reference for Android design and development best practices and, as a running app, delivers news updates about Android development.
- 7

vitest
17.3Kvitest-dev/vitest · TypeScriptVitest is a next-generation testing framework for JavaScript and TypeScript, powered by Vite. It runs unit and component tests using your existing Vite setup.
- 8
systeminformer
16.3Kwinsiderss/systeminformer · CSystem Informer is a free, powerful multi-purpose tool for Windows that helps you monitor system resources, debug software and detect malware.
- 9
liteparse
12.9Krun-llama/liteparse · RustLiteParse is a standalone open-source PDF parser focused on fast, lightweight parsing: it extracts spatial text with bounding boxes and outputs Markdown, JSON, or Text, all running locally with no cloud or LLM calls.
- 10

concurrentqueue
12.5Kcameron314/concurrentqueue · C++moodycamel::ConcurrentQueue is an industrial-strength, lock-free multi-producer multi-consumer queue for C++11.
- 11

BenchmarkDotNet
11.5Kdotnet/BenchmarkDotNet · C#BenchmarkDotNet is a .NET library that turns ordinary methods into reliable, repeatable performance benchmarks and reports detailed statistics about the results.
- 12
benchmark
10.5Kgoogle/benchmark · C++Google Benchmark is a C++ library for writing microbenchmarks of code snippets, similar to how you'd write unit tests.
- 13

conc
10.4Ksourcegraph/conc · Goconc is a Go library — a 'toolbelt' for structured concurrency that makes common concurrent patterns in Go easier and safer than raw goroutines and sync primitives.
- 14
tubatools
5.5Kluolangaga/tubatools · C#TubaTools (图吧工具箱CE) is a community-driven, open-source Windows toolbox rebuilt from scratch on WinUI 3 and .NET 10, bundling 45 built-in utilities plus one-click launchers for 82 third-party tools for hardware diagnostics, cleaning, benchmarking and more.
- 15

coost
4.2Kidealvin/coost · C++coost (aka co) is a lightweight, high-performance, easy-to-use C++ base library whose stated goal is to make C++ programming simple and enjoyable.
- 16
laya-coreml
1.6Kmizorewww/laya-coreml · PythonIt's an open-weight Python port of Laya that answers typed questions — pick an option, an ordinal score, or yes/no — locally on Apple Silicon through Core ML and the Neural Engine, generating zero text tokens.
- 17
jeff
1.5Kfirelex/jeff · PythonJeff is a family of small (0.8B-2B parameter) open-weight models fine-tuned from Qwen3.5 and Gemma 4 that act as fast 'System 1' decision-makers: you describe a situation and a list of options in plain text, and Jeff returns a calibrated probability for each option from a single forward pass, with no generated text to parse.
- 18
livenerf
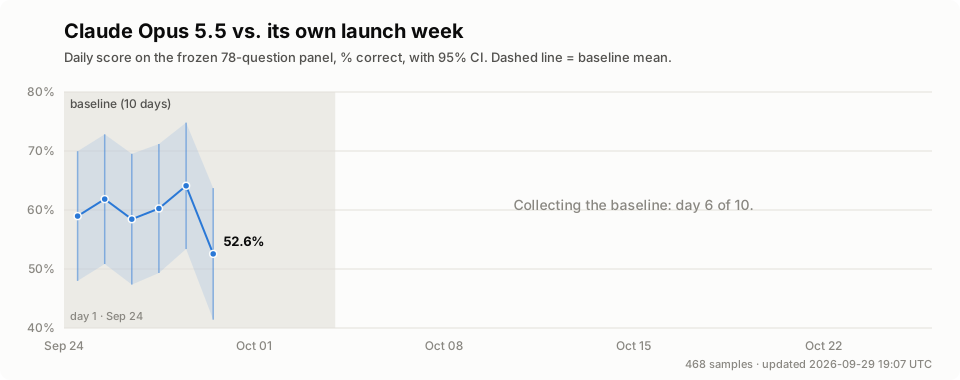
1.5Kninjahawk/livenerf · Pythonlivenerf is a long-running, append-only benchmark that checks whether a frontier Claude model quietly gets worse after it ships, by comparing daily performance against a locked day-0 baseline.
- 19
BibaYanji
957Bibapcs/BibaYanji · CBibaYanji (笔吧验机) is a Windows desktop tool for checking a new or secondhand PC against its order spec: it auto-collects CPU, GPU, RAM, disk, network card, screen and battery info so you can verify them item by item and mark the machine as passed, plus it bundles keyboard, dead-pixel, camera/mic/speaker, stress-test and disk-benchmark checks.
- 20
GVS5H
750slee-persis/GVS5H · PythonGVS5H is the code and experiment data for a research paper introducing 'ledger-based zero-shot self-orchestration': fresh instances of one model decompose a coding problem and coordinate through a shared filesystem holding a plan, notes and the current solution, letting several cheap open models match or approach the accuracy of a much larger proprietary model.
- 21
StartLux-Decision
648StartLuxLabs/StartLux-Decision · PythonStartLux-Decision is a family of typed decision models (five dense sizes from 0.8B to 27B plus a 35B-A3B mixture-of-experts) that answer a question with a probability for each option instead of generating text.
- 22
goose
610aardappel/goose · C++Goose is a memory-safe systems programming language with no heap allocator, garbage collector, or lifetime annotations. In its own benchmarks it runs faster than C++ and safe Rust while using less memory.
- 23
ParseBench
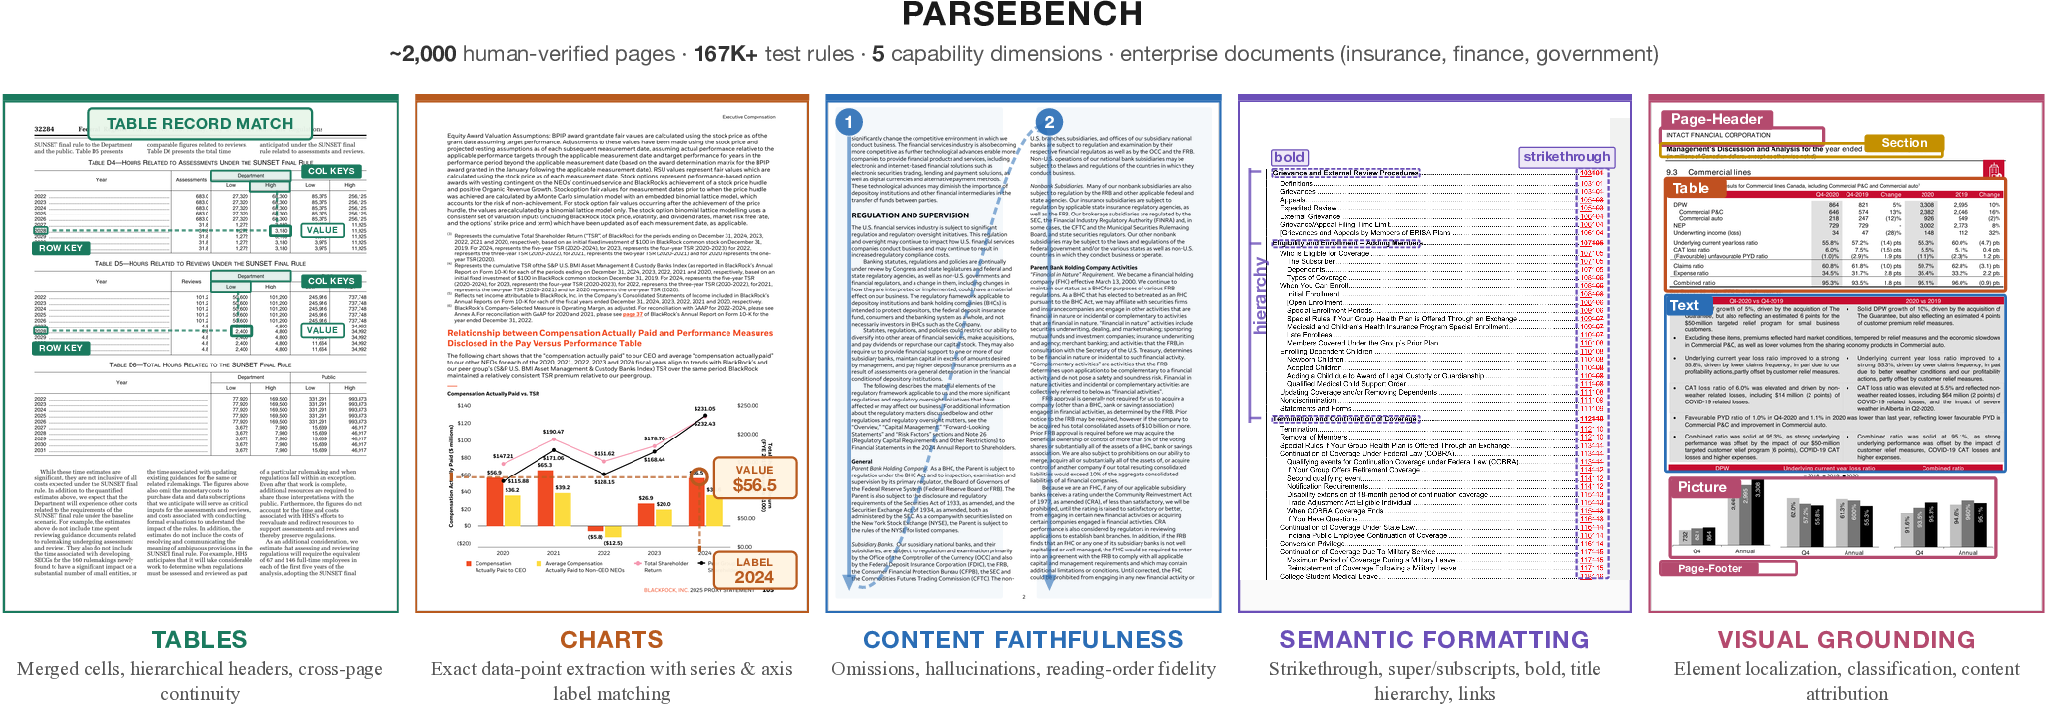
603run-llama/ParseBench · PythonParseBench is a benchmark that measures how well document parsing tools (OCR engines, VLMs, commercial parsing APIs) convert PDFs into structured output that AI agents can reliably act on, rather than just text that looks similar to the original.
- 24

qwen38-mtp
363sudoingX/qwen38-mtp · PythonThis repo documents a single llama.cpp server flag that unlocks multi-token-prediction (MTP) speculative decoding for Qwen3.8-27B, giving +33% to +145% faster decode on consumer GPUs. It bundles the exact launch command, a crowdsourced benchmark table across dozens of GPUs, and a probe.py script for measuring the gain yourself.
- 25
eval
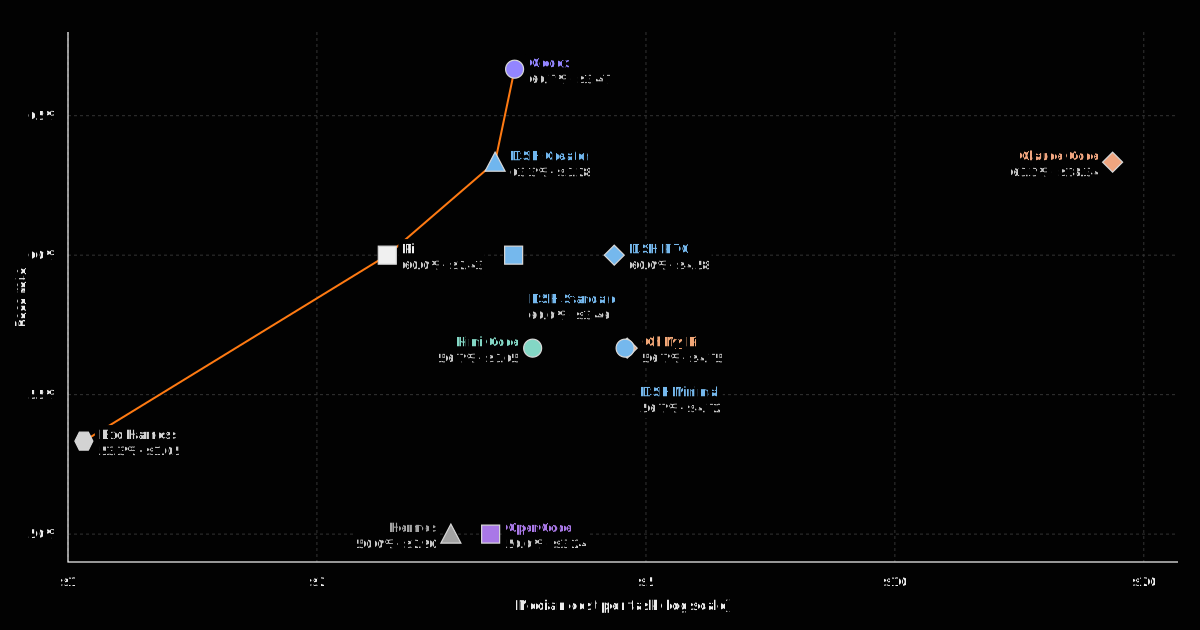
311frontier-harness-eval/eval · JavaScriptFrontierHarness Eval is a public benchmark that ran the same Kimi K3 model through nine coding-agent harnesses (12 configurations) on the same 30 software-engineering tasks, to see how pass rate, cost, cache behavior and speed change when only the harness changes.
- 26
ASI-Bench
301apexin-ai/ASI-Bench · PythonASI-Bench is a benchmark for evaluating AI agents on long-horizon scientific research: it jointly tests general intelligence, innovation, and autonomous execution across 60 project-level tasks in 11 domains.
- 27

m4-sme-exploration
245tzakharko/m4-sme-exploration · CA research project that microbenchmarks the Scalable Matrix Extension (SME) of Apple's M4 chip, measuring peak compute throughput for common matrix and vector operations and memory transfer rates.
- 28

arc-code
143jerber/arc-code · Pythonarc-code is a research harness that lets Claude Code (or Codex) play the ARC-AGI-3 benchmark games through a shell and filesystem, writing its own parsers, simulators and search code for each game instead of relying on built-in ARC-specific tooling.
Related topics
Often tagged together