Topics / #on-device-ai
On device AI projects on GitHub
SDKs for running AI models locally on phones and edge devices.
As of , the most-starred On device AI projects on GitHub are colibri (42.5K stars), khoj (37.7K stars) and mediapipe (37.3K stars). GitHub.Locker tracks 35 On device AI repositories with 326.3K stars combined. The fastest-growing on October 16 was colibri, with +222 stars in a day.
Hot right now
Most stars gained in a day · Oct 16
 +222
colibri
JustVugg/colibri · ★ 42.5KColibri is an open-source engine for running frontier mixture-of-experts (MoE) language models on hardware you already own — written in pure C with zero dependencies.
 +217
Edge0
Edge0-AI/Edge0 · ★ 5.3KEdge0 is an open-source streaming MoE (Mixture-of-Experts) inference framework that lets you run large MoE models, like a 35B-parameter model, using only about 2.5-2.9 GB of active RAM by streaming expert weights from SSD and predicting routing one step ahead.
 +215
DigUp
ARahim3/DigUp · ★ 4.3KDigUp is a free, open-source macOS menu bar app that lets you search the files on your Mac by what's actually in them — photos, PDFs, documents, recordings, videos and code — using Google DeepMind's EmbeddingGemma 2 model running entirely on-device.
 +112
MasterAgent
OpenSparX/MasterAgent · ★ 1KMasterAgent (OAK) is an embeddable, local-first C++17 agent runtime: it turns input into validated tool execution, running deterministic skills before falling back to model inference. It targets on-device AI agents for use cases like automotive and embedded/Qualcomm NPU hardware, with zero cloud dependency by default.
The all-time top
35 projects · by stars
- 42.5K#1 · JustVugg/colibri
colibri
Colibri is an open-source engine for running frontier mixture-of-experts (MoE) language models on hardware you already own — written in pure C with zero dependencies.
- 37.7K
 #2 · khoj-ai/khoj
khoj
Khoj is an open-source personal AI — a 'second brain' that answers your questions from the web and your own documents, runs custom agents for you, and works with any online or local LLM.
- 37.3K
 #3 · google-ai-edge/mediapipe
mediapipe
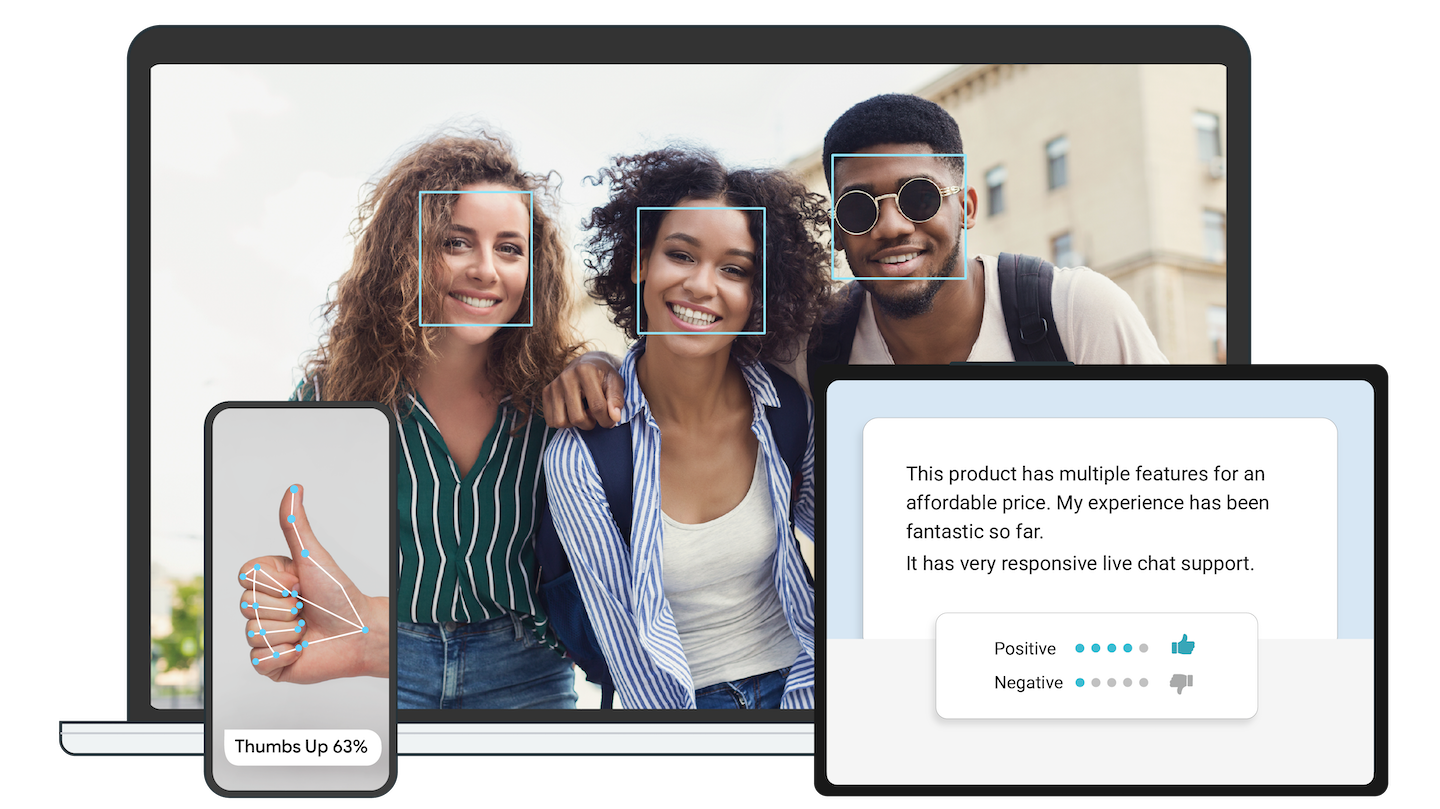
Google's open-source, cross-platform toolkit for on-device machine learning in live and streaming media: ready-made libraries and pre-trained models you plug straight into your own app.
- 4
Handy
34Kcjpais/Handy · RustHandy is a free, open source speech-to-text app: press a keyboard shortcut, speak, and your transcribed words are pasted into whatever app you are typing in. It runs entirely offline on your own computer.
- 5

DeepSpeech
26.8Kmozilla/DeepSpeech · C++Mozilla DeepSpeech is an open-source Speech-To-Text engine — a machine-learning model that turns audio into text on your own hardware.
- 6
gallery
25Kgoogle-ai-edge/gallery · KotlinGoogle AI Edge Gallery is an app that lets you download and run open-source generative AI models, including the Gemma family, directly on your Android phone, iPhone, or Mac — fully offline.
- 7

web-llm
19.3Kmlc-ai/web-llm · TypeScriptWebLLM runs large language models directly in the browser, accelerated by WebGPU — no server involved. It exposes the OpenAI API, so standard OpenAI-style code works against open models running locally.
- 8
needle
14.1Kcactus-compute/needle · PythonNeedle 2 is an open 45M-parameter model for tool calling, device use and structured extraction that ships as a single 14MB binary and runs a full session in about 28MB of RAM. This repo is its Python package for inference, LoRA fine-tuning and export.
- 9
supertonic
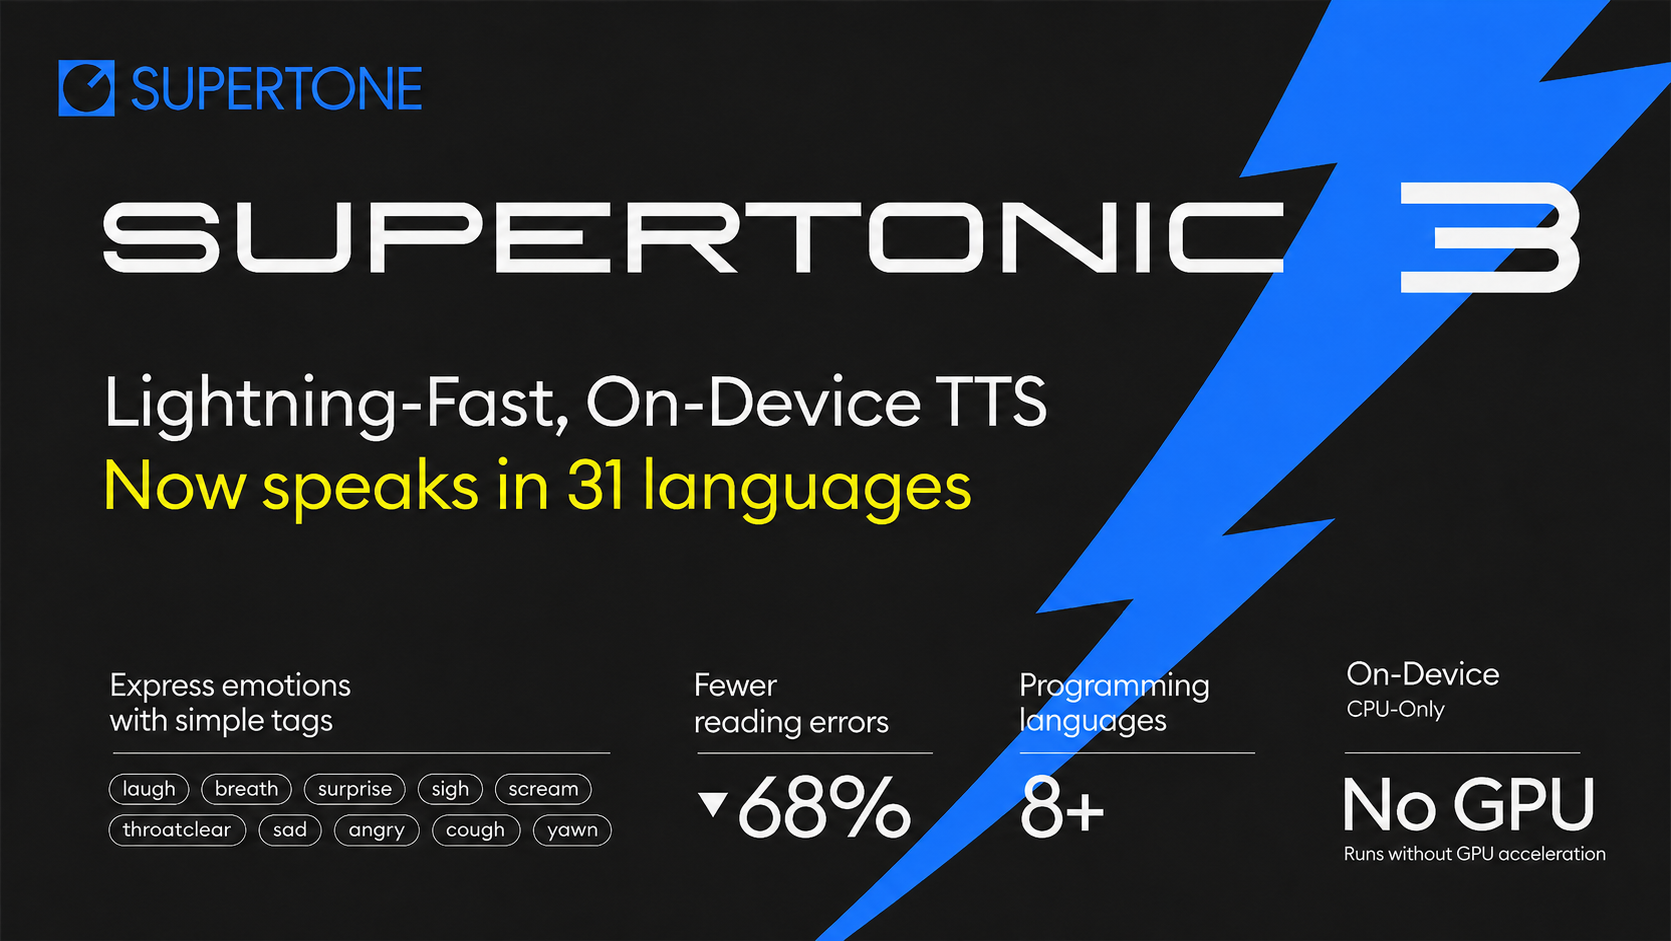
13.8Ksupertone-oss-archive/supertonic · SwiftSupertonic is a lightning-fast, on-device text-to-speech system: it converts text into 44.1kHz 16-bit WAV speech locally via ONNX Runtime — no cloud, no API calls, no GPU. The open-weight model, Supertonic 3, covers 31 languages.
- 10

FluidVoice
12.2Kaltic-dev/FluidVoice · SwiftFluidVoice is an open-source voice-to-text dictation app for macOS that transcribes speech on-device and can enhance the text with AI, acting as a local alternative to Wispr Flow.
- 11
silero-vad
10.5Ksnakers4/silero-vad · PythonSilero VAD is a pre-trained, enterprise-grade Voice Activity Detector: a compact model that tells you which parts of an audio stream contain speech.
- 12
runanywhere-sdks
10.3KRunanywhereAI/runanywhere-sdks · C++A toolkit of eight SDKs over one C++ core that runs AI fully on-device — LLM chat, vision, speech, voice agents, RAG, and image generation — on phones, browsers, and desktops. Everything is private by default and works offline.
- 13
turbo-fieldfare
6.9Kdrumih/turbo-fieldfare · SwiftTurboFieldfare is a custom Swift and Metal runtime that runs the instruction-tuned Gemma 4 26B-A4B model on Apple Silicon Macs using only about 2 GB of RAM, even on 8 GB machines, by streaming only the experts needed for each token from SSD instead of loading the full 14.3 GB model.
- 14
Edge0
5.3KEdge0-AI/Edge0 · PythonEdge0 is an open-source streaming MoE (Mixture-of-Experts) inference framework that lets you run large MoE models, like a 35B-parameter model, using only about 2.5-2.9 GB of active RAM by streaming expert weights from SSD and predicting routing one step ahead.
- 15
esp32-ai
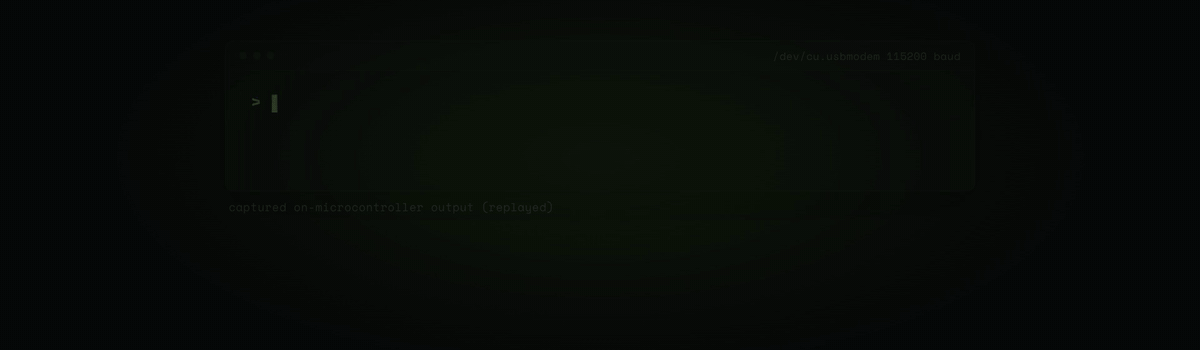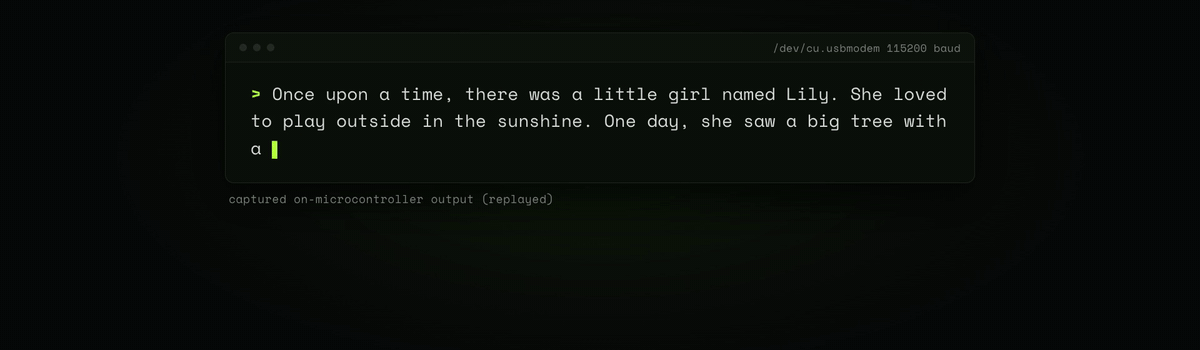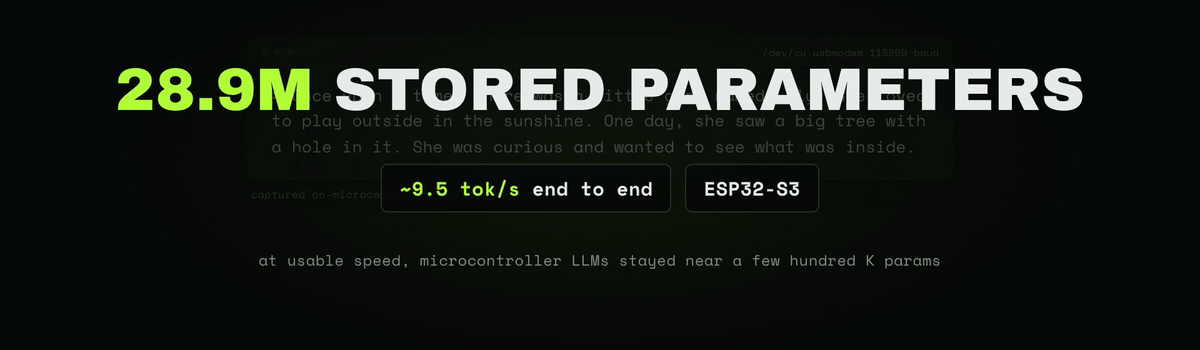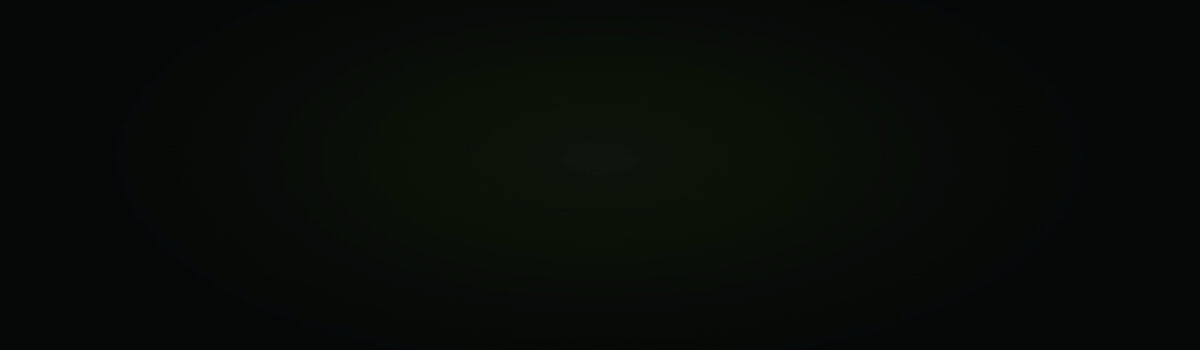
4.5KslvDev/esp32-ai · PythonA 28.9 million parameter language model that runs text generation entirely on an ESP32-S3 microcontroller, with the generated text shown on a small screen wired to the chip.
- 16
DigUp
4.3KARahim3/DigUp · SwiftDigUp is a free, open-source macOS menu bar app that lets you search the files on your Mac by what's actually in them — photos, PDFs, documents, recordings, videos and code — using Google DeepMind's EmbeddingGemma 2 model running entirely on-device.
- 17
EnvoyMesh
3.1Kallenpeng0705/EnvoyMesh · TypeScriptEnvoyMesh is a decentralized peer-to-peer mesh for autonomous AI agents — a private social network you and your agent actually own, with chat, voice, files and AI that negotiates tasks on your behalf. No central server: your devices run the network.
- 18
Open-Source-Face-Recognition-SDK
2.6KFaceplugin-ltd/Open-Source-Face-Recognition-SDK · PythonAn open-source face recognition SDK from Faceplugin that does face detection, landmark extraction, embedding generation and face similarity comparison, all processed on-premise.
- 19
uzu
2.4Ktrymirai/uzu · Rustuzu is a high-performance inference engine for AI models that lets you run LLMs directly inside your app with zero latency, full data privacy, and no per-request inference costs.
- 20
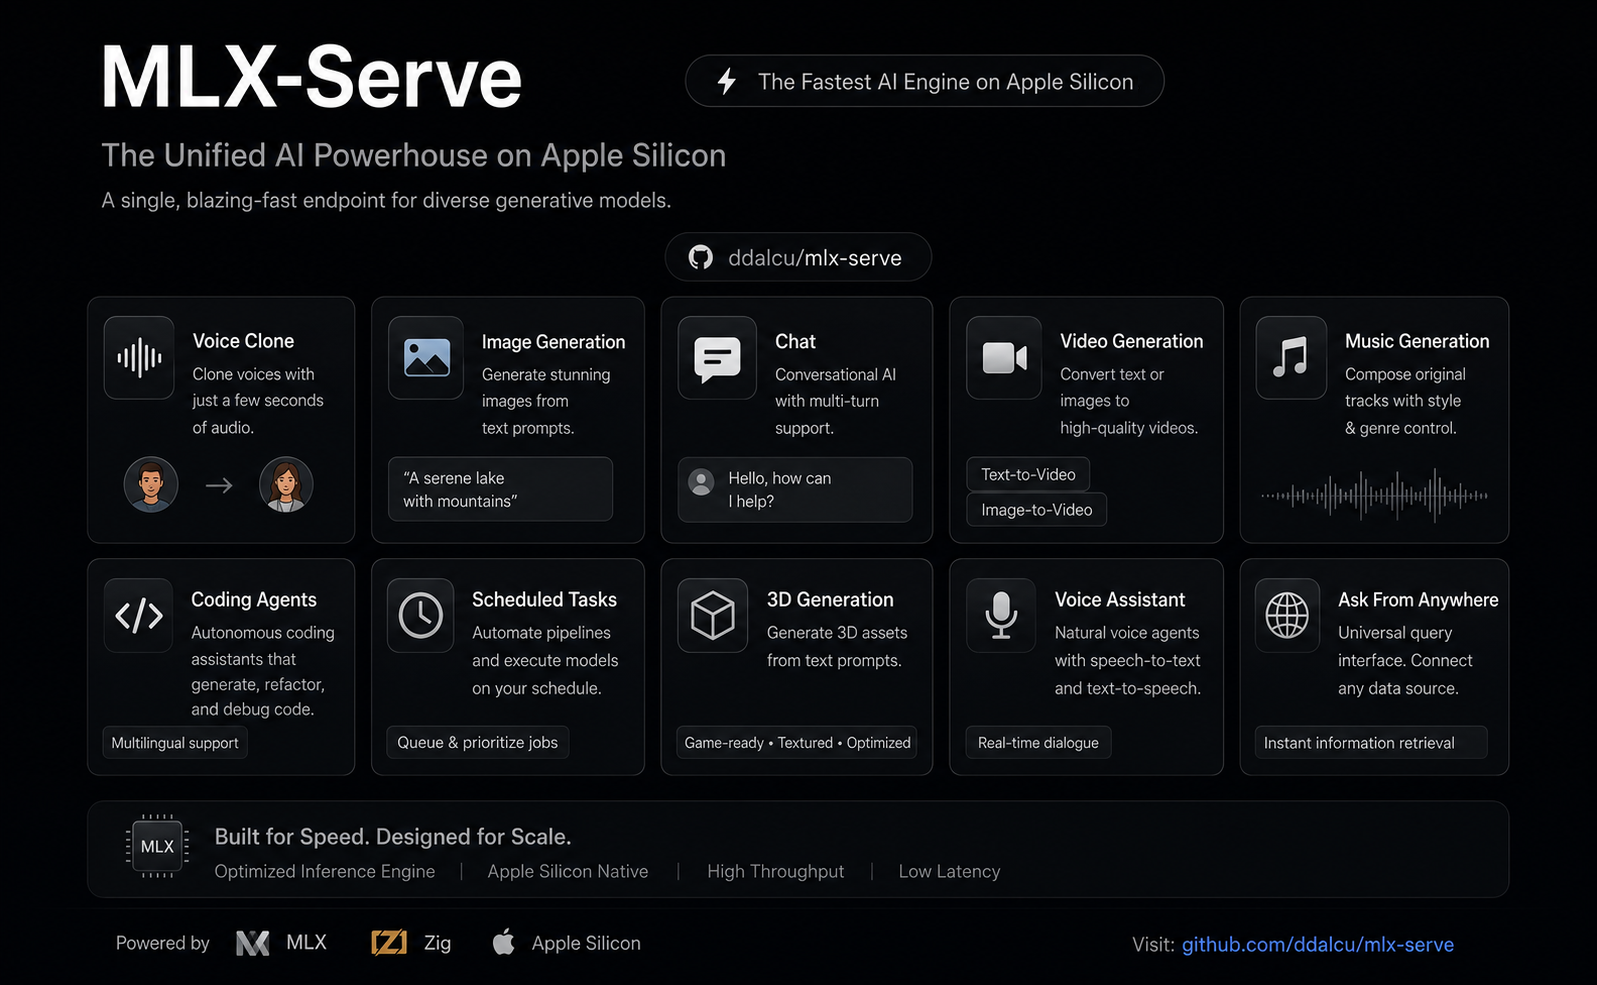
mlx-serve
2Kddalcu/mlx-serve · Zigmlx-serve is a native local inference server for Apple Silicon Macs that runs MLX and GGUF language models and exposes OpenAI-, Anthropic-, and Ollama-compatible APIs, plus generates images, video, music, speech, and 3D models, all without Python or a cloud connection.
- 21
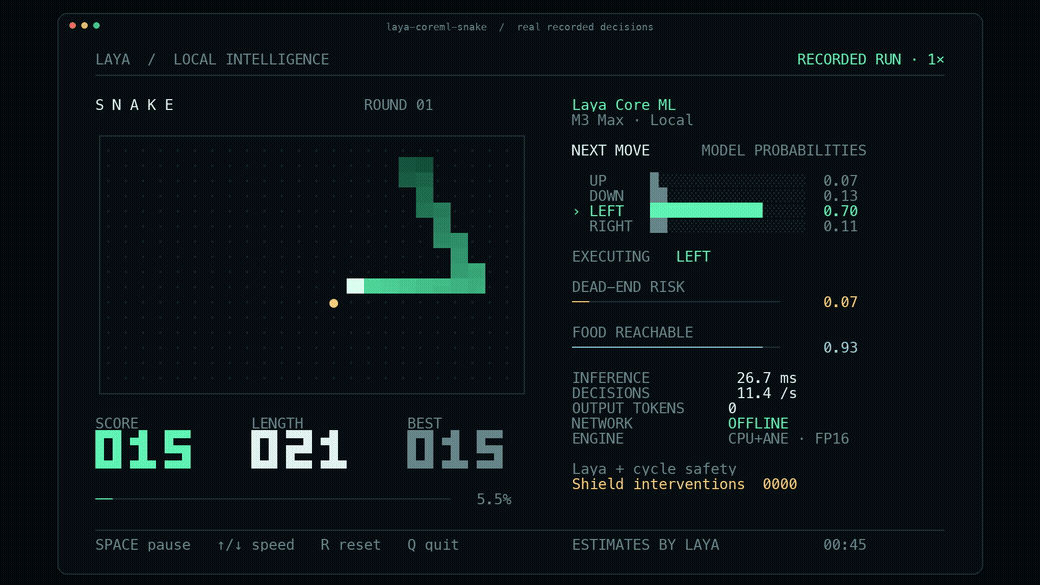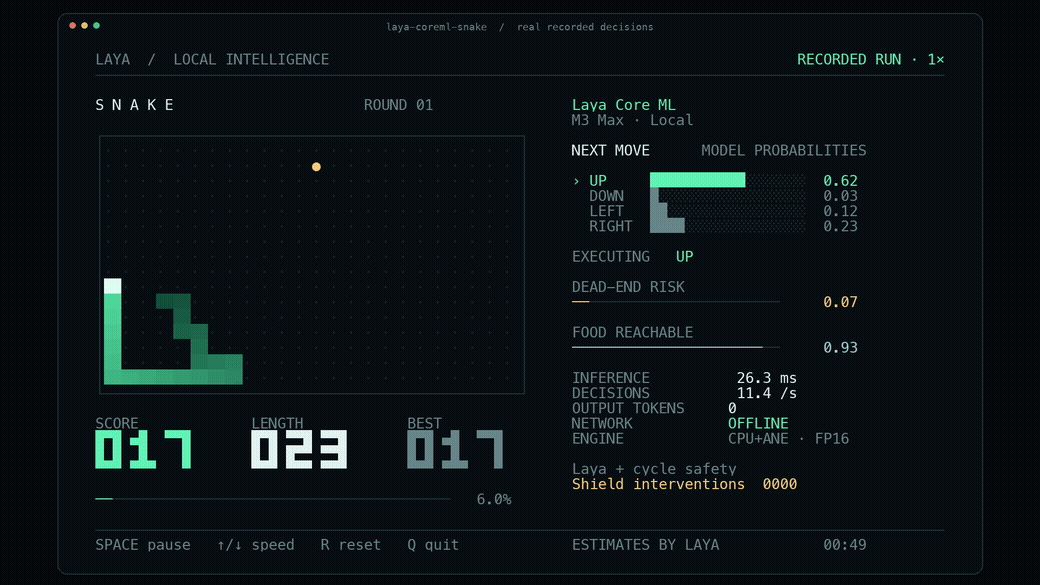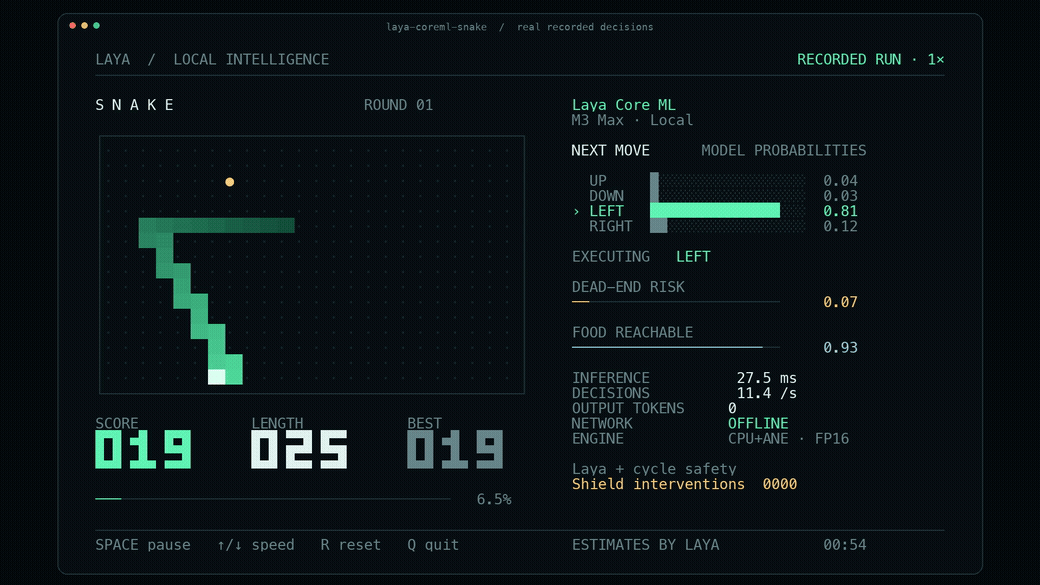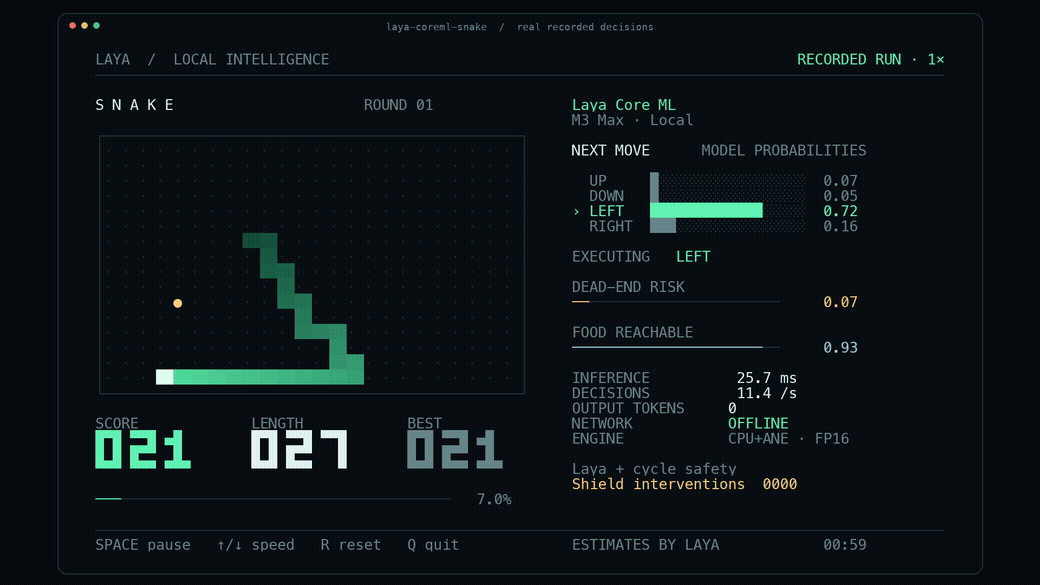
laya-coreml
1.6Kmizorewww/laya-coreml · PythonIt's an open-weight Python port of Laya that answers typed questions — pick an option, an ordinal score, or yes/no — locally on Apple Silicon through Core ML and the Neural Engine, generating zero text tokens.
- 22
nobodywho
1.6Knobodywho-ooo/nobodywho · RustNobodyWho is an open-source inference engine that runs LLMs locally and offline on phones, desktops and even Apple Watch — no API keys, no cloud calls. Under the hood it is powered by llama.cpp and accelerates through the GPU via Vulkan or Metal.
- 23
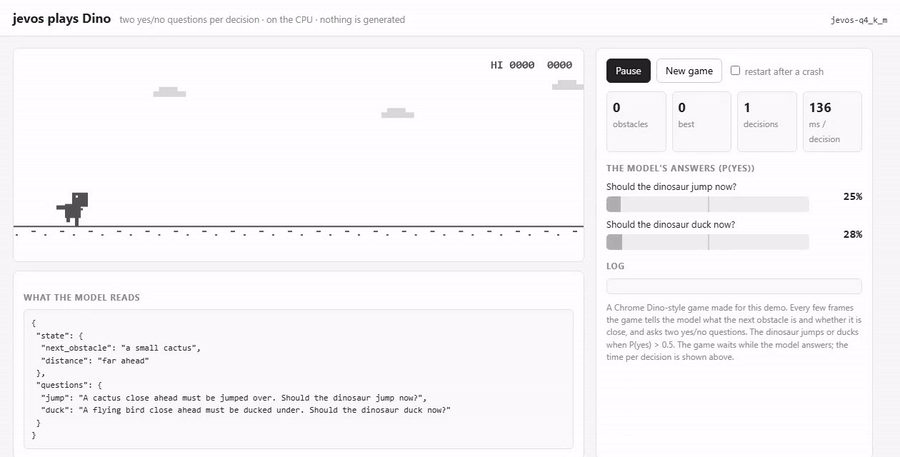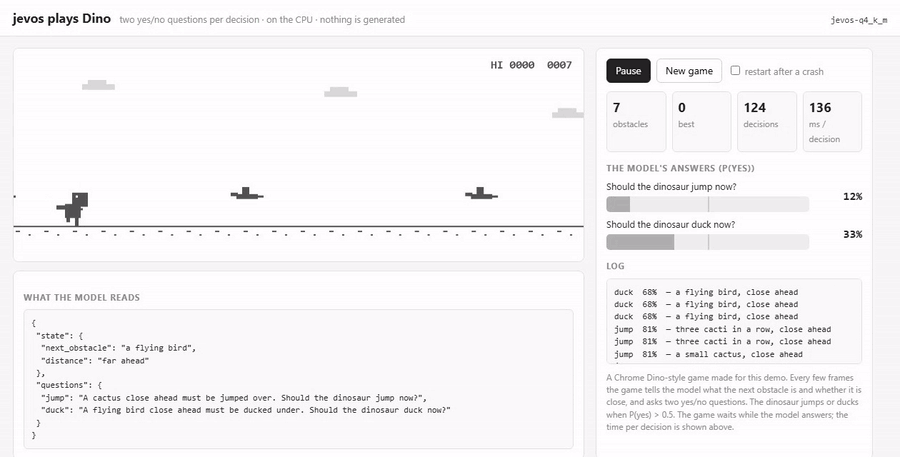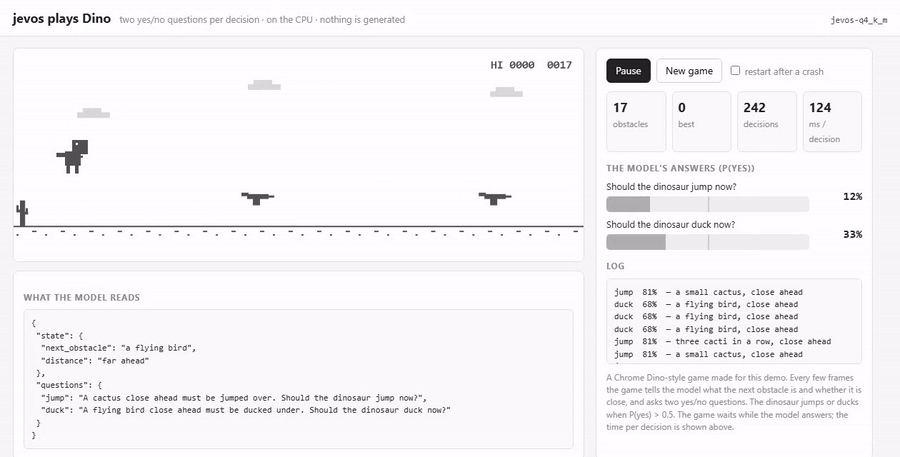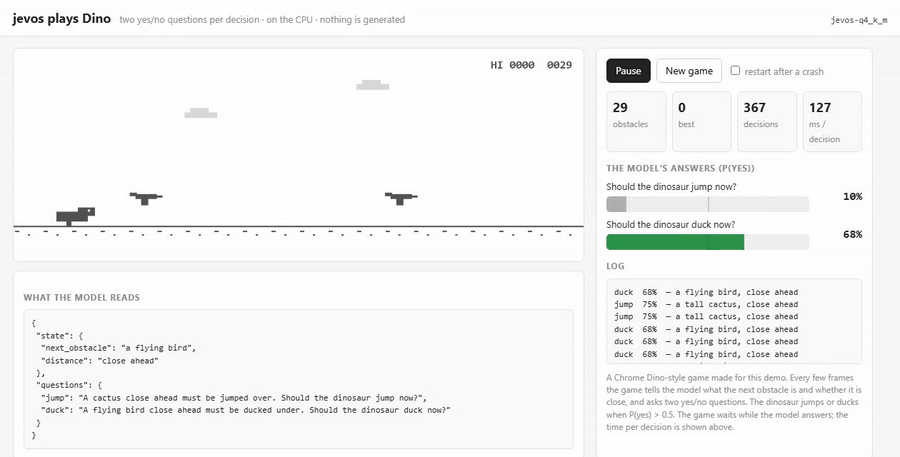
jev
1.3Kfeder-cr/jev · C++jevos-1b is a free, open-source yes/no decision engine that runs locally on your laptop's CPU, returning the probability that the answer is 'yes' for a given text plus question in about 50-220 ms, as a self-hosted alternative to the cloud-based Jev service.
- 24

parrot
1.3Khumanitas-labs/parrot · SwiftParrot is on-device dictation for macOS: hold the fn key, speak, release, and your words appear at the cursor as text.
- 25
MasterAgent
1KOpenSparX/MasterAgent · C++MasterAgent (OAK) is an embeddable, local-first C++17 agent runtime: it turns input into validated tool execution, running deterministic skills before falling back to model inference. It targets on-device AI agents for use cases like automotive and embedded/Qualcomm NPU hardware, with zero cloud dependency by default.
- 26
backburner
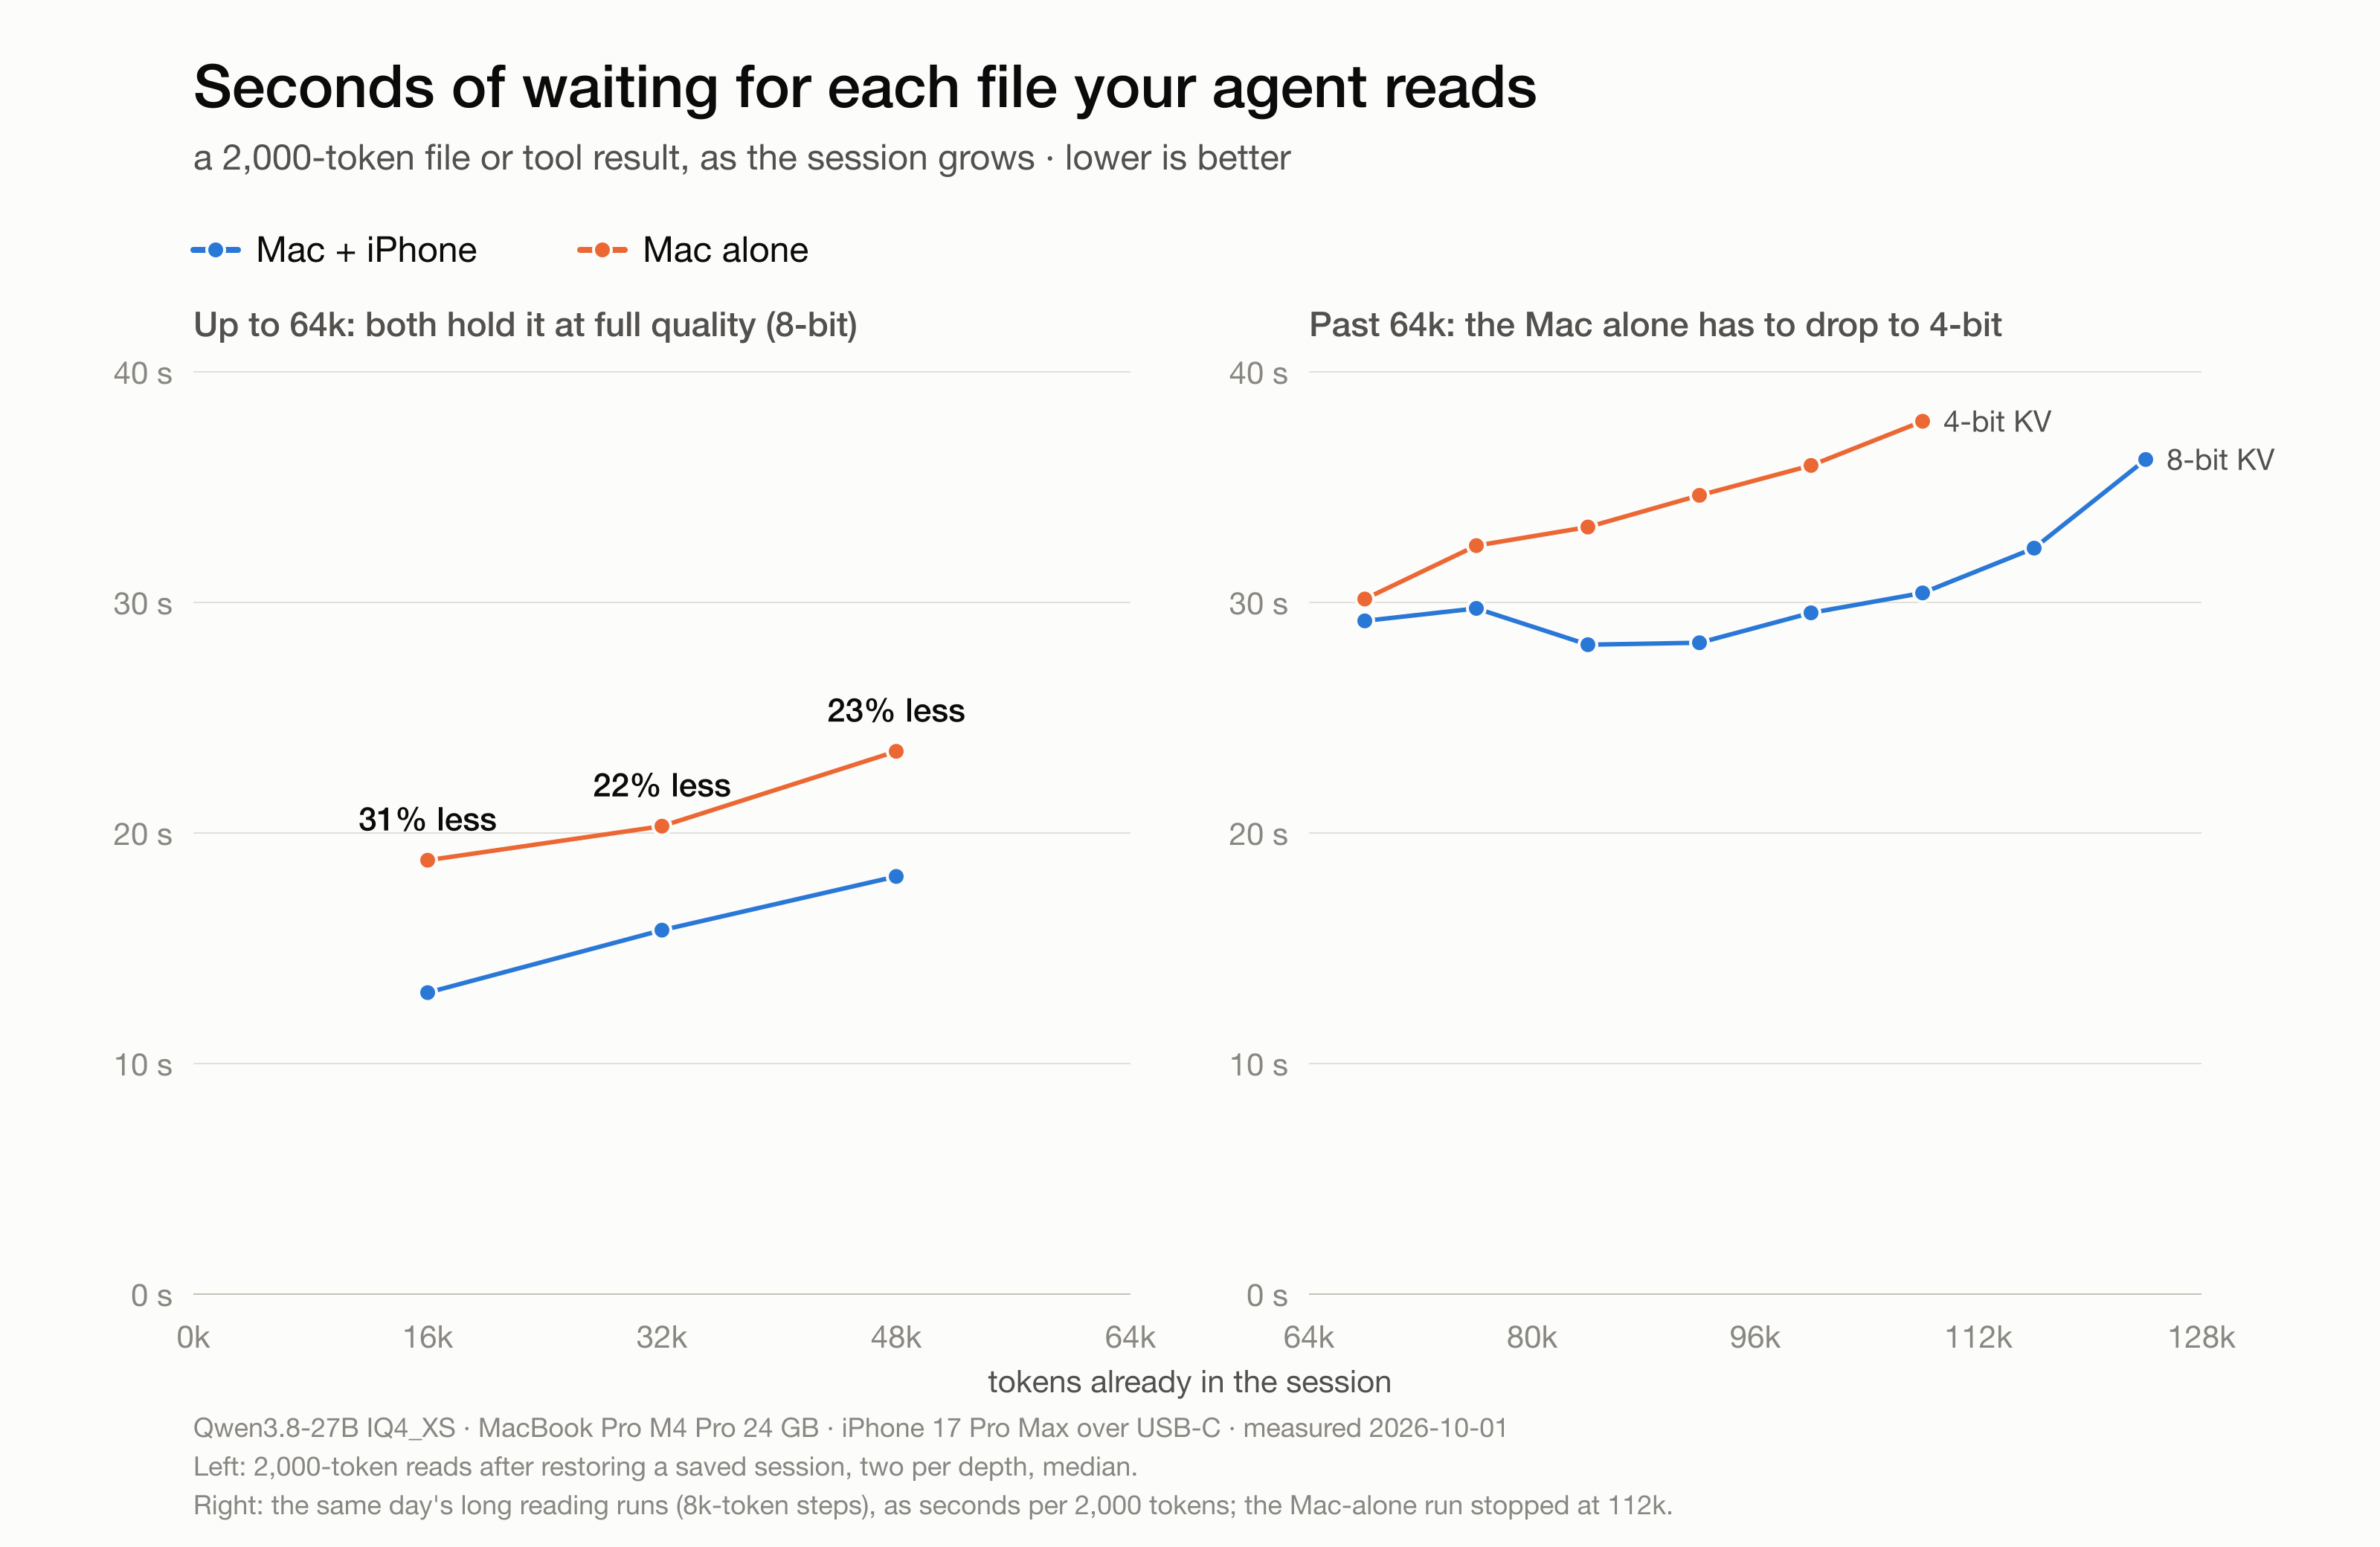
1KStayLameBro/backburner · PythonBackburner lets a nearby iPhone act as a coprocessor for your Mac so a locally-run 27B LLM (Qwen3.8-27B) reads prompts faster and holds far more context. The phone connects over a 10 Gb/s USB-C cable and offloads part of the model's layers plus storage/attention for old context.
- 27

mac-performance-monitor
937Zesty0wl/mac-performance-monitor · SwiftA native macOS performance monitor and recorder that tracks CPU, memory, GPU, network, disk, battery, and sensor readings, letting you compare them against the processes behind them. It works as a menu bar readout, a quiet background recorder, or a window you open when needed.
- 28
souchastnik
725MShverdiakov/souchastnik · KotlinAn Android app (Souchastnik) that tells you what criminal charge you might face in Russia for something you wrote online, and flags mentions of 'foreign agents' or banned social networks.
- 29
apex-inference-chip
581SigmanticAI/apex-inference-chip · PythonAPEX is an open, verification-first hardware design for LLM inference: one transformer decoder layer written in real RTL that runs Qwen2.5-0.5B on an FPGA, with every circuit block checked bit-exact against a software golden model.
- 30
jev-chat-jarvis-mac
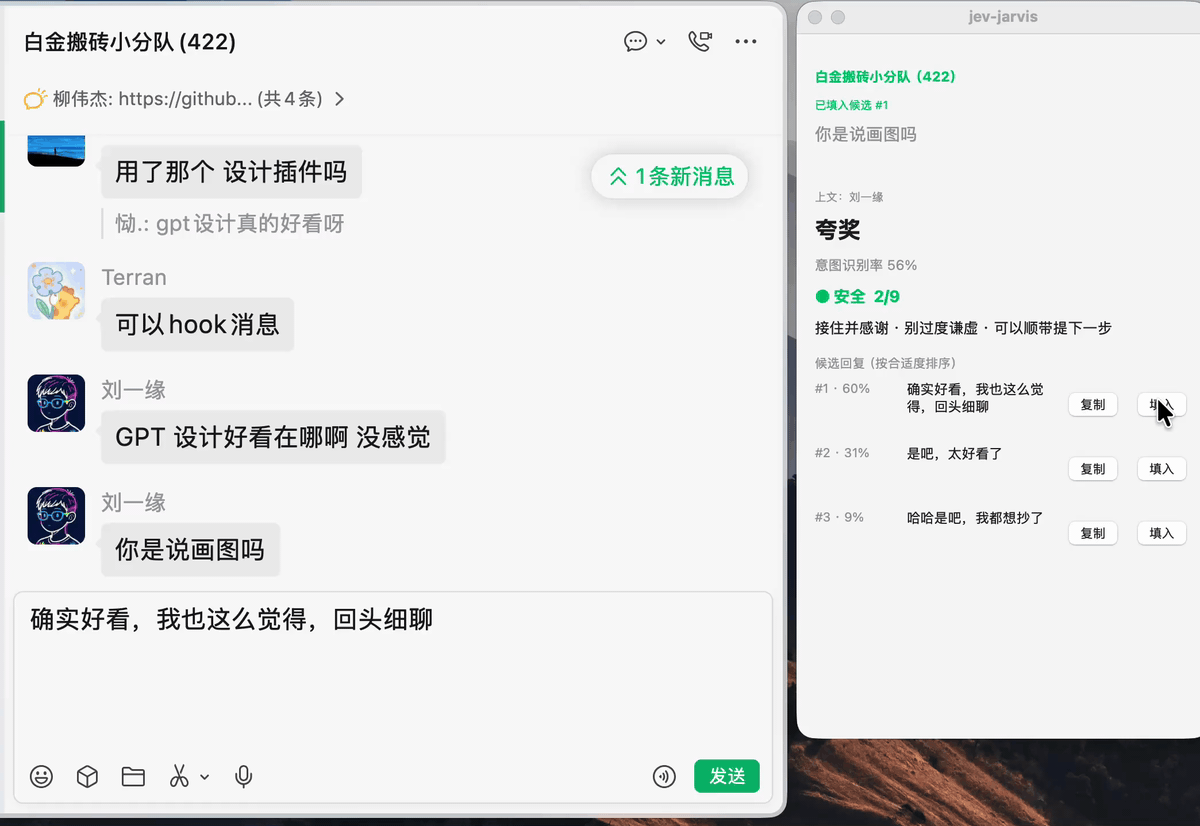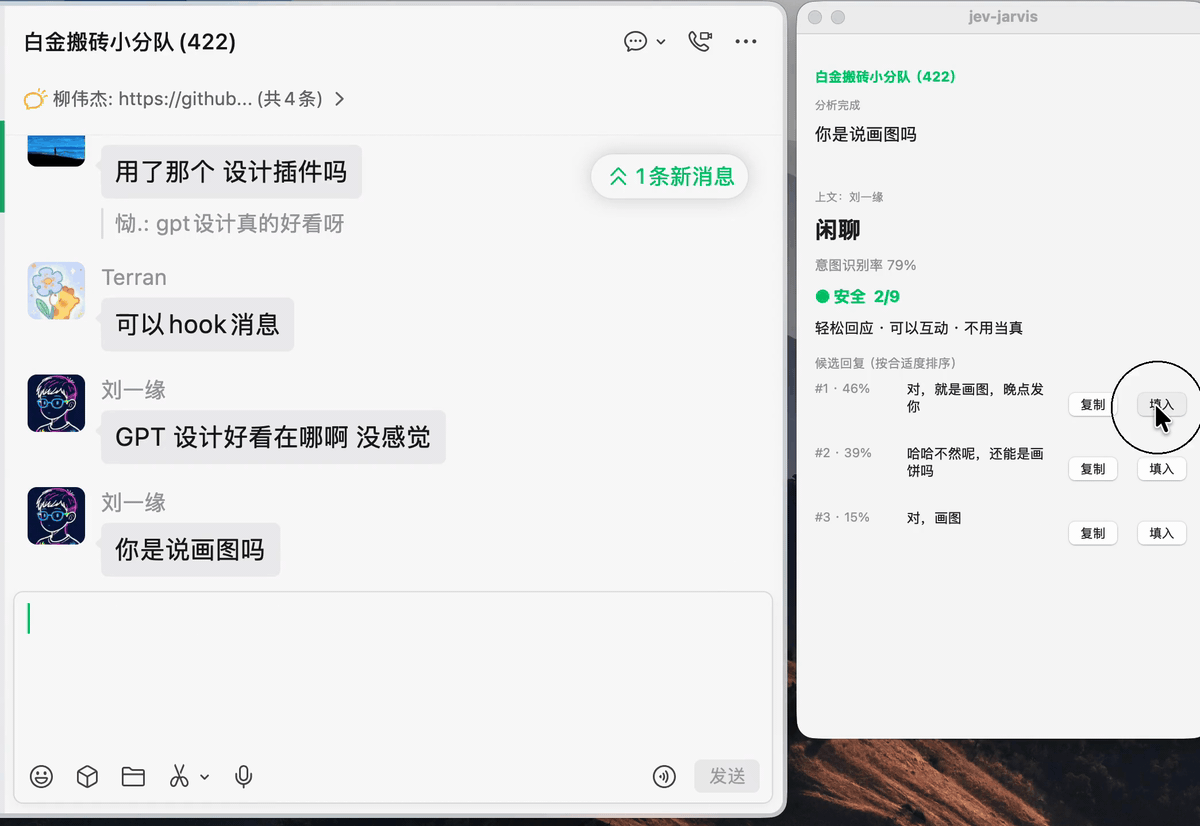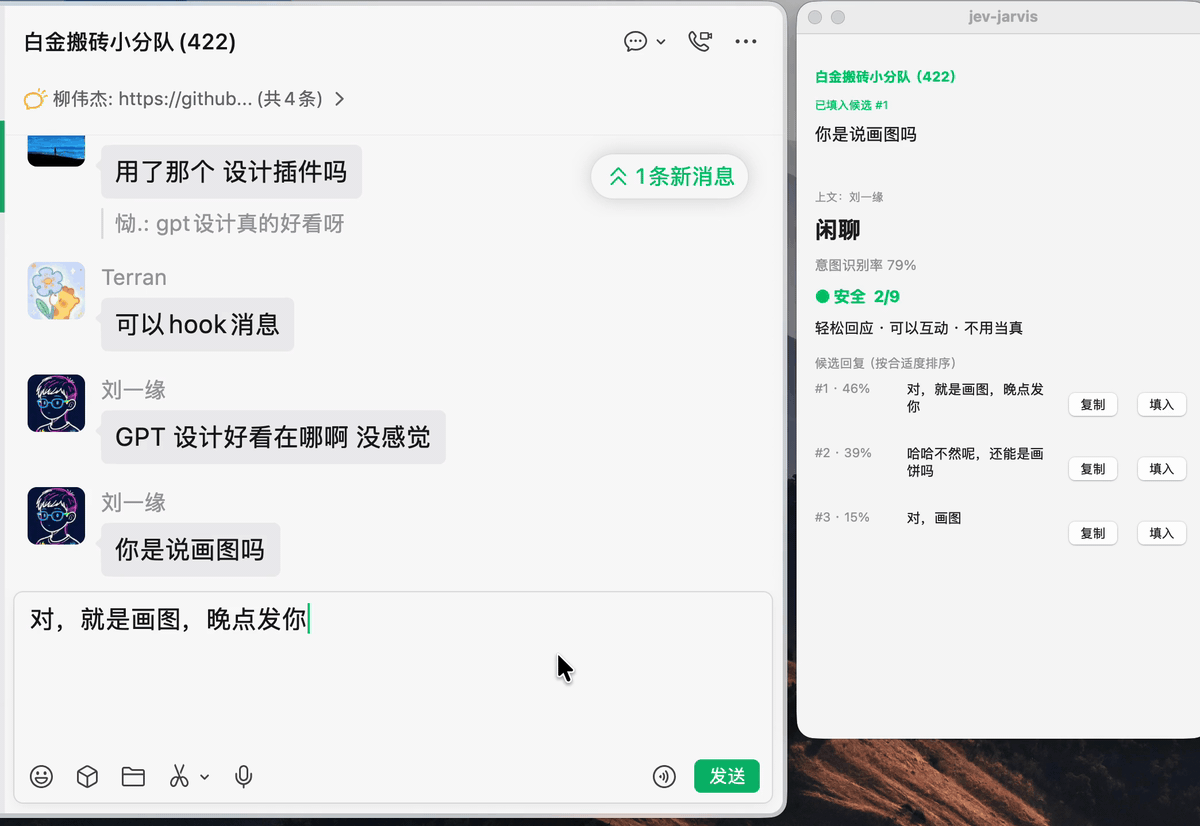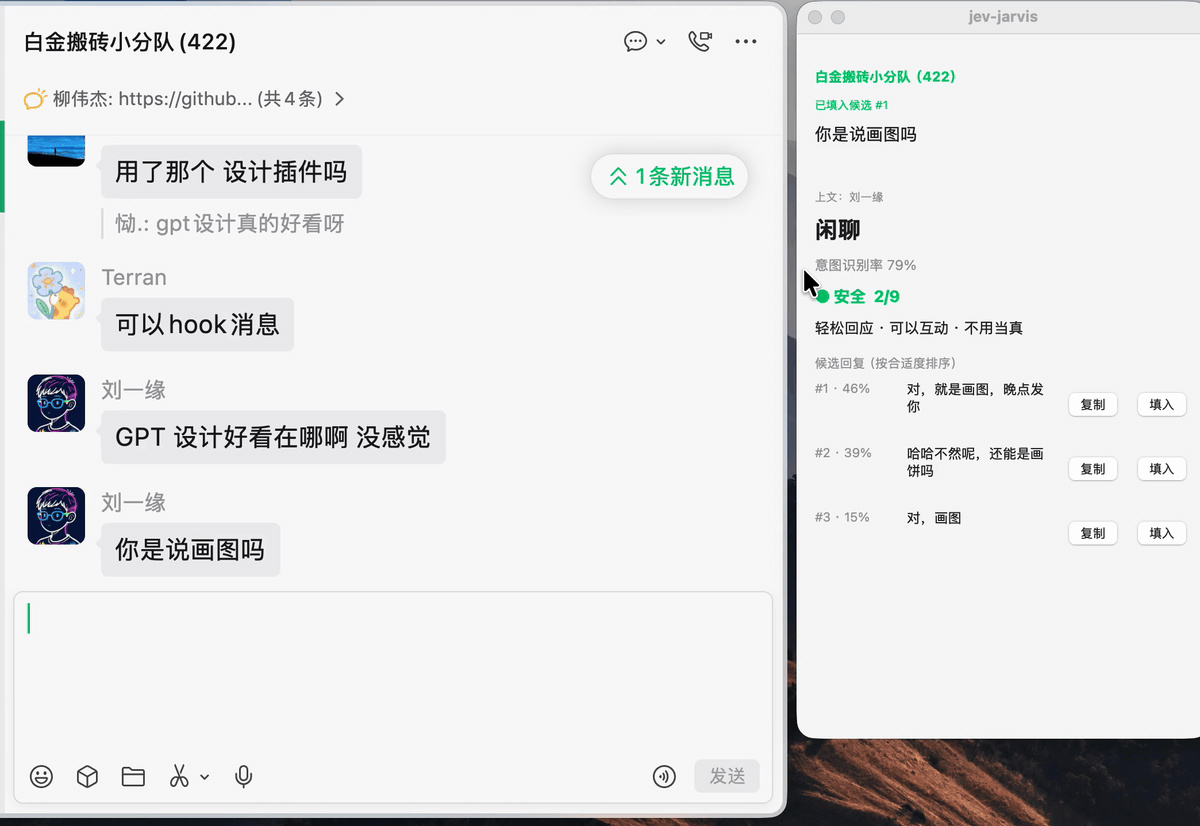
498jev-chat/jev-chat-jarvis-mac · PythonA floating overlay for WeChat on macOS: the moment a message arrives, it shows the sender's likely intent, a 0-9 risk score with a suggested action, and ready-to-use reply candidates.
- 31

slotstream
474carloslfu/slotstream · SwiftSlotstream lets you run a 105 GB AI model (Qwen3.8-Flash-Next, a 125B-parameter mixture-of-experts model) on Macs with only 16 to 64 GB of RAM, by streaming most of the model from SSD and caching the busiest experts in memory.
- 32
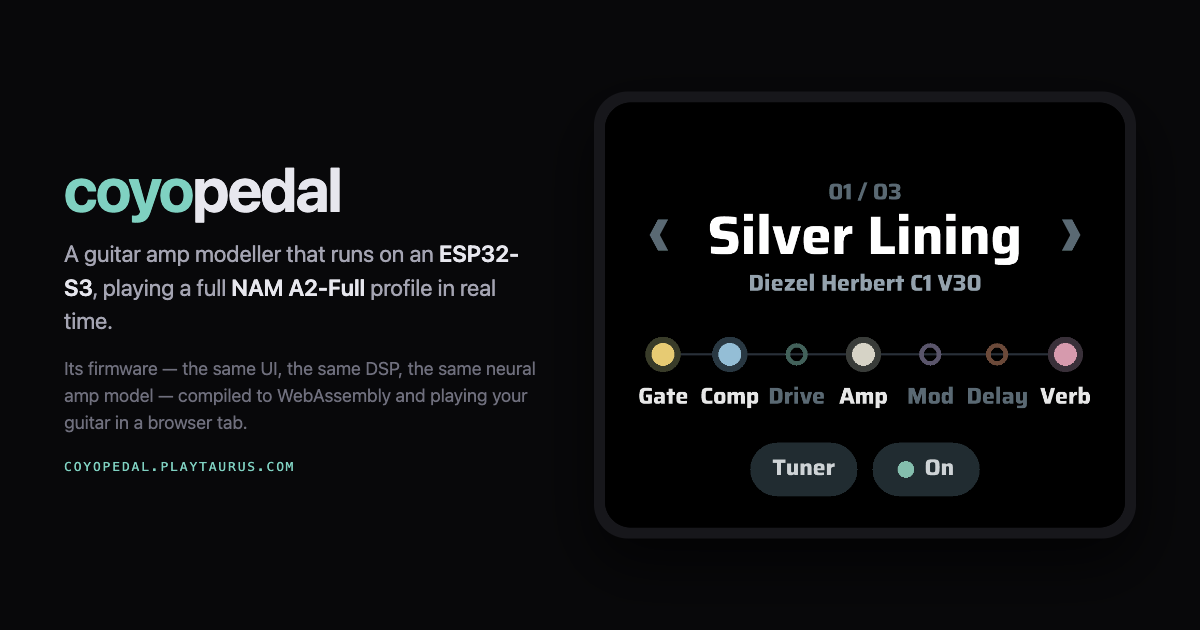
coyopedal
261dashersw/coyopedal · C++CoyoPedal is a standalone guitar amp and effects pedal built on the ESP32-S3 that runs full-size Neural Amp Modeler (NAM) A2 captures in real time, with a touchscreen UI and a browser build compiled to WebAssembly.
- 33
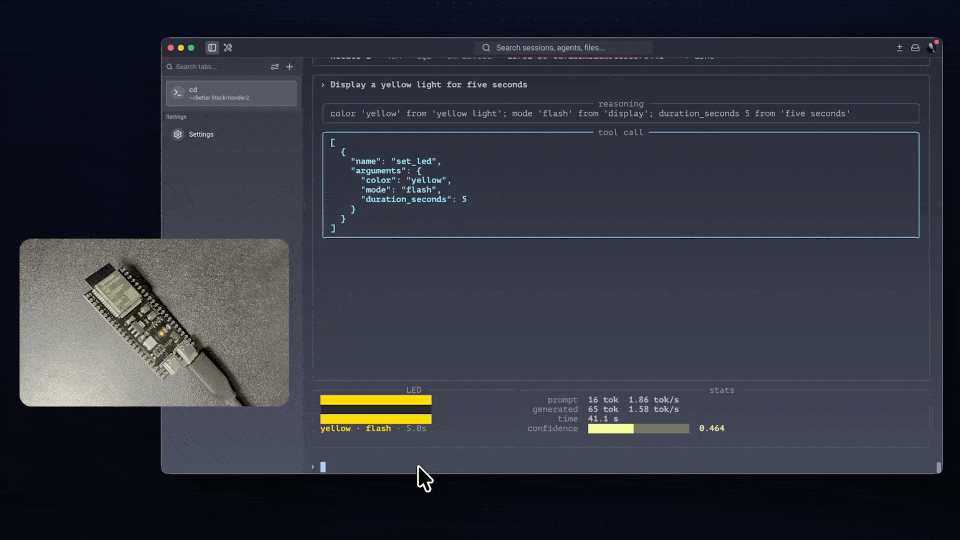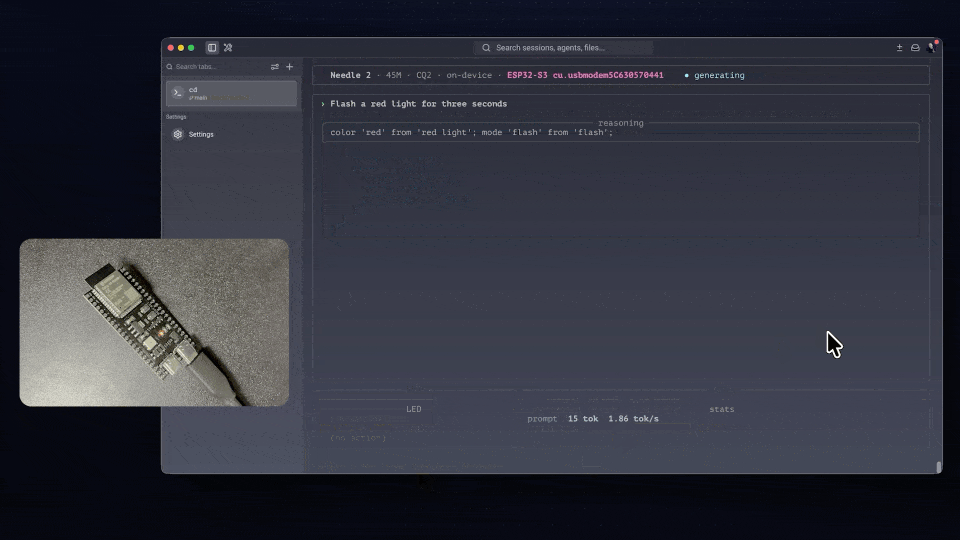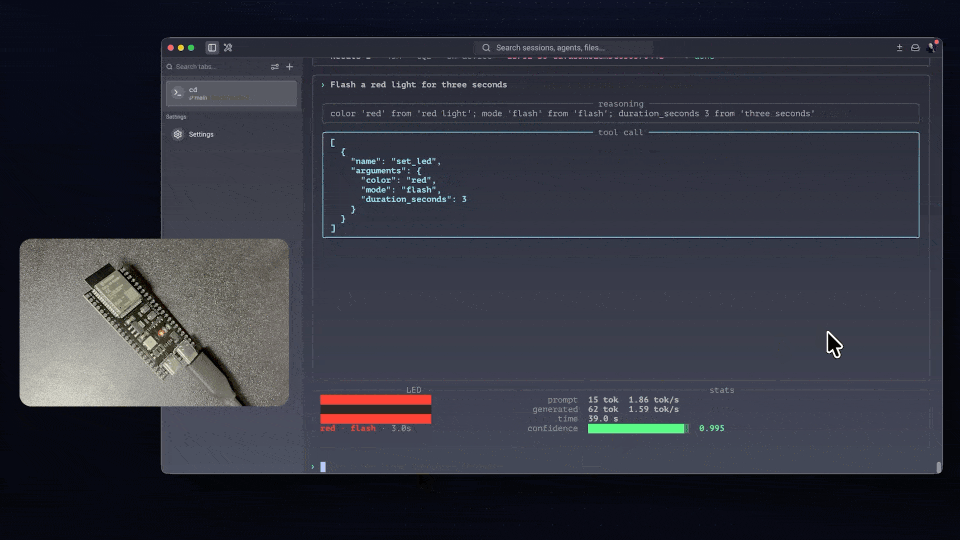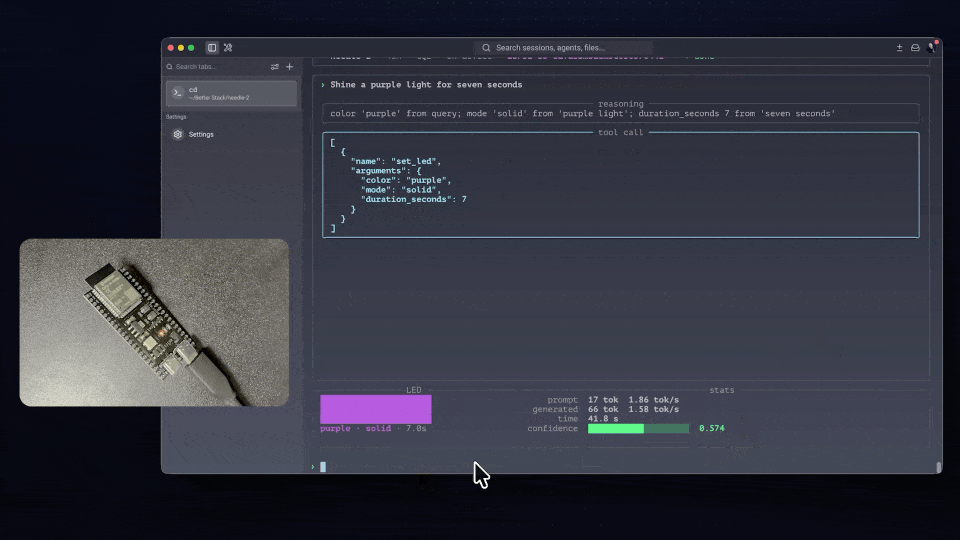
needle-2-esp32
198andrisgauracs/needle-2-esp32 · CIt is a C firmware that runs Cactus's Needle 2, a 45-million-parameter language model, entirely offline on an ESP32-S3 microcontroller, turning plain-English requests into guaranteed-valid JSON tool calls.
- 34
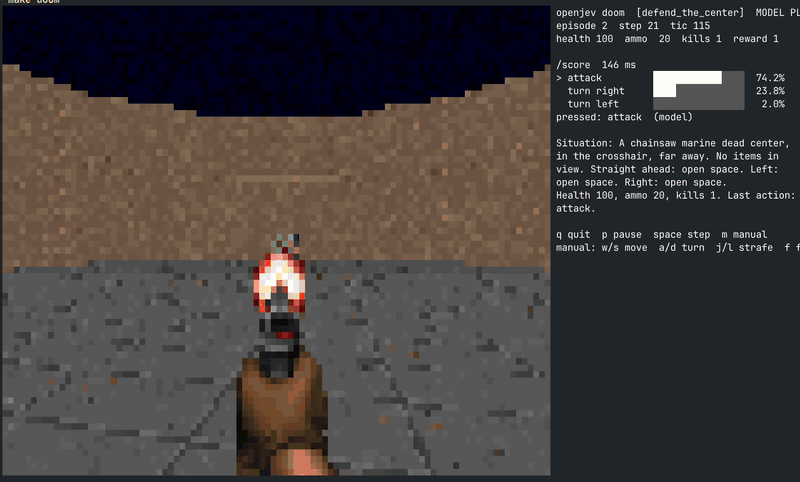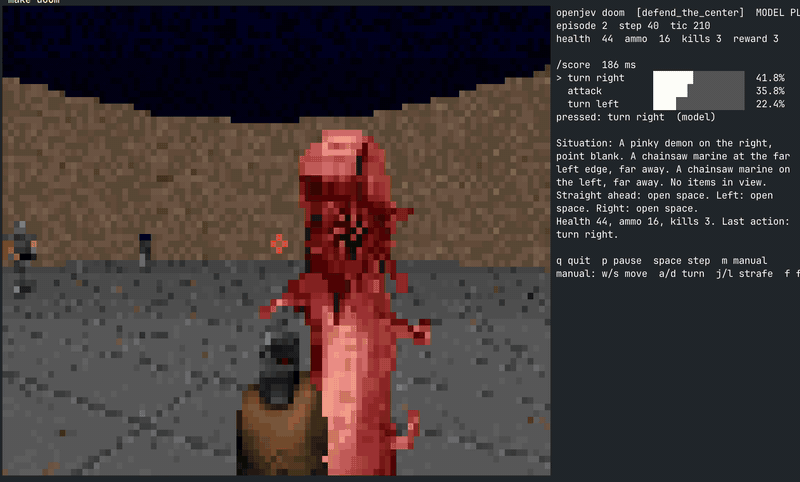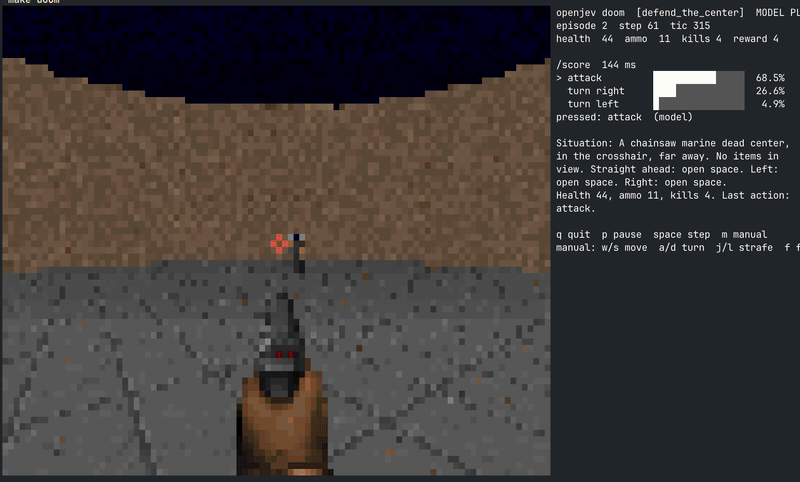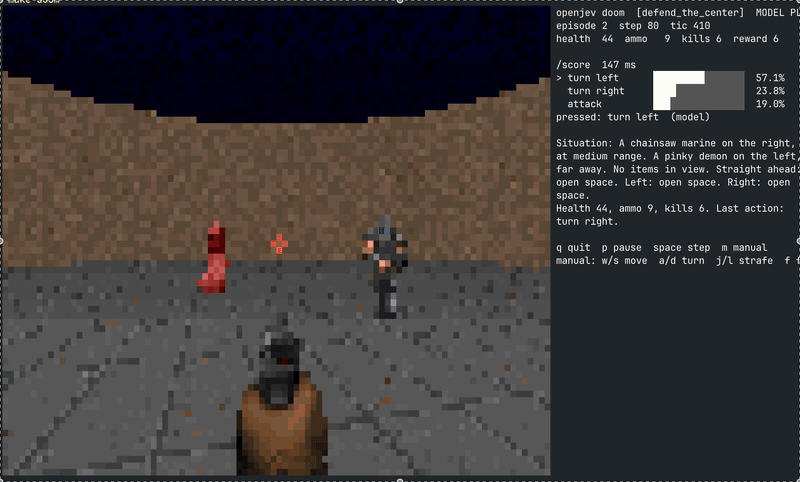
open-jev
134daseinlabs/open-jev · PythonAn open implementation of Jev: a local Gemma 3 4B (via MLX) scores a list of pre-written options against a context in one batched forward pass on Apple silicon — no text generation, just log-probabilities per option.
- 35
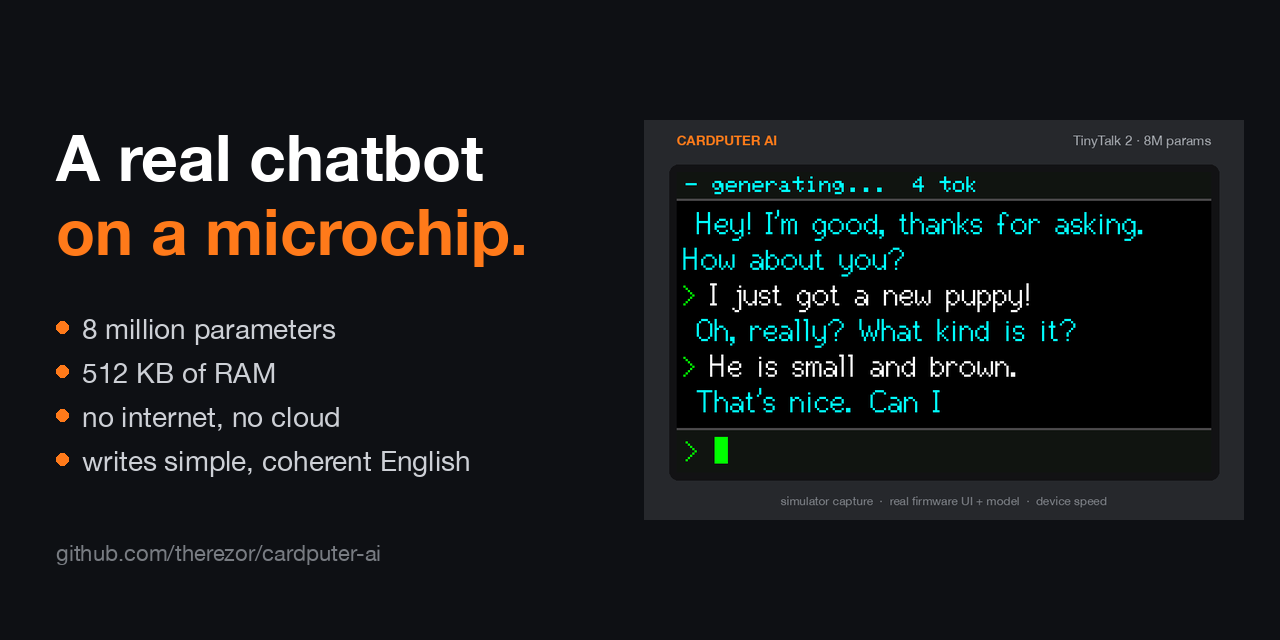
cardputer-ai
118therezor/cardputer-ai · C++Cardputer AI is a tiny offline chatbot that runs entirely on the M5Stack Cardputer / Cardputer ADV handheld, powered by an 8-million-parameter language model baked directly into the firmware.
Related topics
Often tagged together