Topics / #inference-optimization
Inference-optimization projects on GitHub
Engineering LLM inference for lower latency and cost.
As of , the most-starred Inference-optimization projects on GitHub are HyperQwen (2.1K stars), llm-inference-engineering (372 stars) and ComfyUI-H3VAE_TRT (253 stars). GitHub.Locker tracks 6 Inference-optimization repositories with 3.3K stars combined. The fastest-growing on October 18 was HyperQwen, with +41 stars in a day.
Hot right now
Most stars gained in a day · Oct 18
 +41
HyperQwen
syv-ai/HyperQwen · ★ 2.1KHyperQwen is a self-hosted serving setup that runs the Qwen3.8-27B model on a single 24 GB consumer GPU (like an RTX 3090) using vLLM, exposing it through an OpenAI-compatible API.
 +21
llm-inference-engineering
amitshekhariitbhu/llm-inference-engineering · ★ 372A free, continuously growing blog series that teaches LLM inference engineering step by step, covering KV cache, PagedAttention, continuous batching, speculative decoding, and serving engines like vLLM, SGLang, TensorRT-LLM, and GGUF.
 +3
Hyperloom
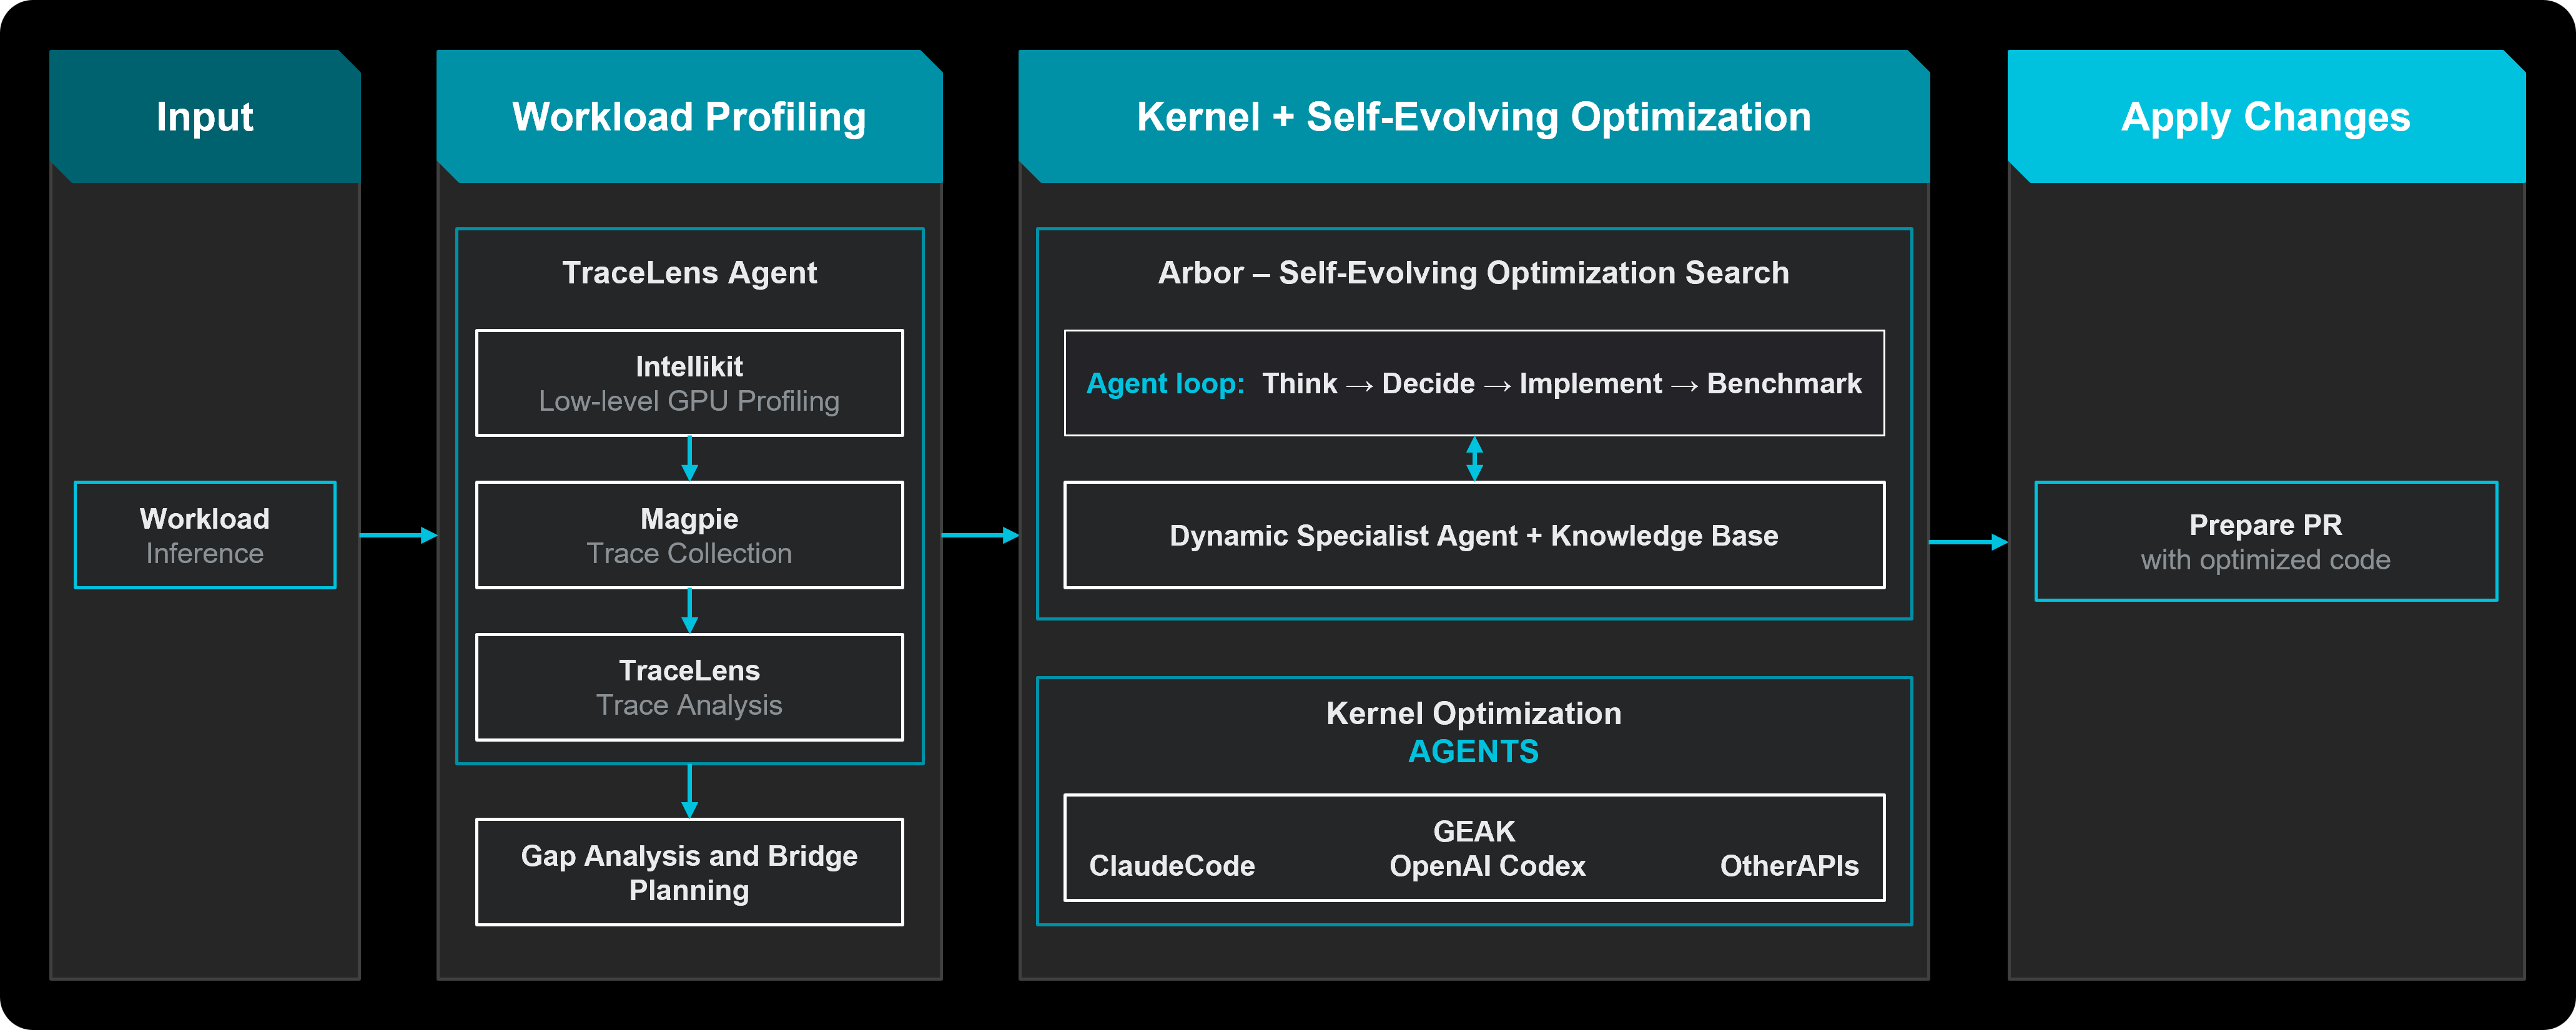
AMD-AGI/Hyperloom · ★ 242A multi-agent harness that autonomously optimizes LLM inference on AMD Instinct GPUs: it profiles your workload, searches framework and GPU-kernel optimizations, validates every candidate end to end, and saves proven results into a recipe knowledge base.
 +1
ComfyUI-H3VAE_TRT
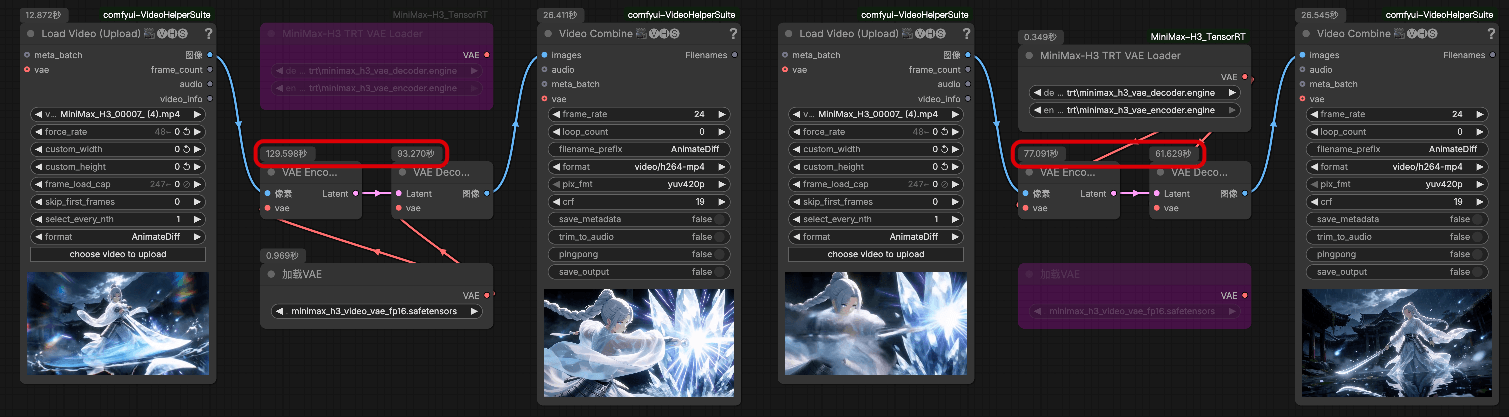
lihaoyun6/ComfyUI-H3VAE_TRT · ★ 253A ComfyUI custom node that runs the MiniMax-H3 VAE as a compiled TensorRT engine instead of the regular one, making it up to 1.7x faster.
The all-time top
6 projects · by stars
- 2.1K#1 · syv-ai/HyperQwen
HyperQwen
HyperQwen is a self-hosted serving setup that runs the Qwen3.8-27B model on a single 24 GB consumer GPU (like an RTX 3090) using vLLM, exposing it through an OpenAI-compatible API.
- 372#2 · amitshekhariitbhu/llm-inference-engineering
llm-inference-engineering
A free, continuously growing blog series that teaches LLM inference engineering step by step, covering KV cache, PagedAttention, continuous batching, speculative decoding, and serving engines like vLLM, SGLang, TensorRT-LLM, and GGUF.
- 253#3 · lihaoyun6/ComfyUI-H3VAE_TRT
ComfyUI-H3VAE_TRT
A ComfyUI custom node that runs the MiniMax-H3 VAE as a compiled TensorRT engine instead of the regular one, making it up to 1.7x faster.
- 4
Hyperloom
242AMD-AGI/Hyperloom · PythonA multi-agent harness that autonomously optimizes LLM inference on AMD Instinct GPUs: it profiles your workload, searches framework and GPU-kernel optimizations, validates every candidate end to end, and saves proven results into a recipe knowledge base.
- 5

dgx-spark-qwen38
230hasso5703/dgx-spark-qwen38 · PythonA one-command installer that sets up a hardened, boot-persistent SGLang serving stack for the Qwen3.8 model family on a single NVIDIA DGX Spark (GB10), reaching 50 tok/s greedy median and up to 1M context on the 27B NVFP4 config, with a 176B Flash-Next MoE model also fitting on one box.
- 6
nari-qwen3-tts
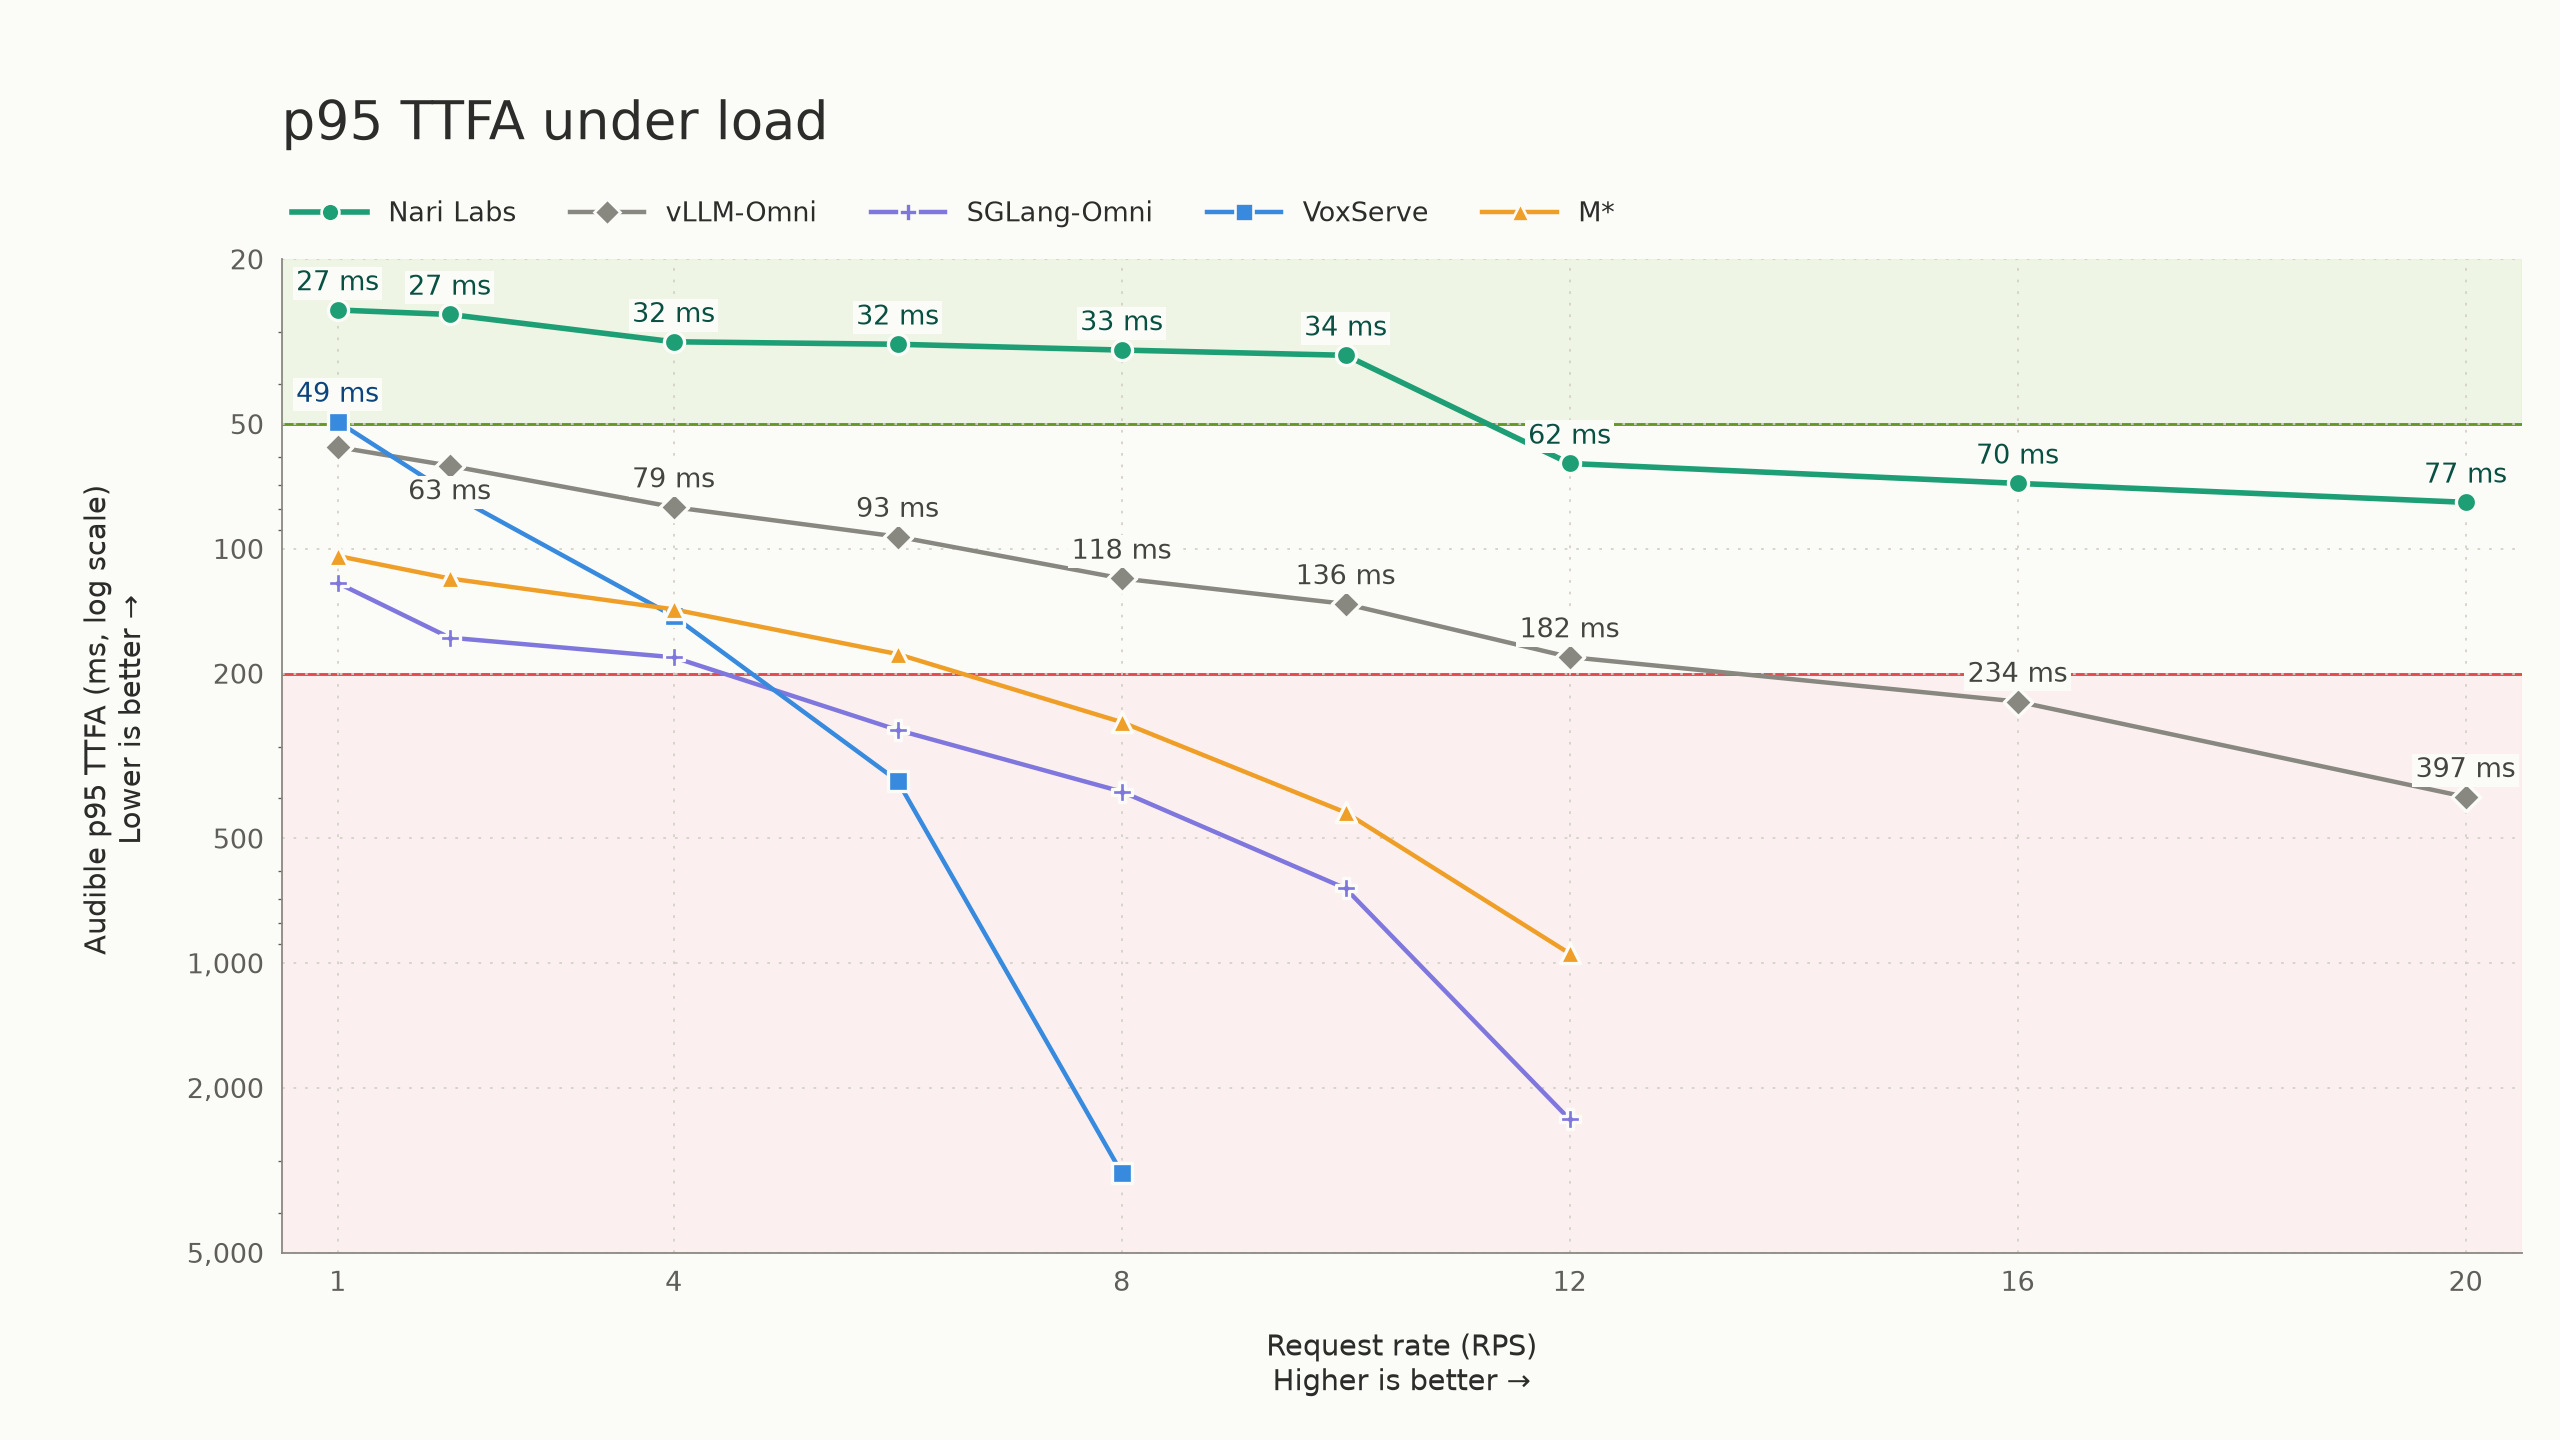
187nari-labs/nari-qwen3-tts · PythonNari Qwen3-TTS is a high-performance serving implementation of the Qwen3-TTS 1.7B CustomVoice model, built to run on a single NVIDIA H100 and exposed as an API with streaming and non-streaming speech generation.
Related topics
Often tagged together
- gpu809
- inference331
- linux4,248
- nvidia339
- python2,425
- quantization190
- ai1,993
- cuda401
- llm-inference120
- model-serving49
- vllm128
- apache-2.01,452
- docker1,684
- large-language-models218
- llm1,516
- llm-serving30
- openai-compatible219
- self-hosted1,978
- sglang26
- speculative-decoding41
- ai-agents1,322
- benchmark444
- inference-engine47
- local-llm224